$$ \newcommand{\AbsoluteConicImageEntry}{B} \newcommand{\AbsoluteConicImageMatrix}{\mathbf{B}} \newcommand{\AbsoluteConicVector}{\mathbf{b}} \newcommand{\AcceleratedEpisodeTime}{T'} \newcommand{\AcceleratedFractionSpeedup}{G} \newcommand{\AccelerationNoiseDensityMatrix}{\mathbf{Q}_c} \newcommand{\AccelerationNoiseSpectralDensity}{q_c} \newcommand{\AccelerationWhiteNoise}{w} \newcommand{\AcceleratorBatchTime}{T_{\text{GPU}}} \newcommand{\AcceleratorConsumptionRate}{R_{\text{accel}}} \newcommand{\AcceleratorCount}{N_{\text{GPU}}} \newcommand{\AcceleratorDataConsumptionRate}{R_{\text{consumption}}} \newcommand{\AcceleratorGain}{G_{\text{accel}}} \newcommand{\AcceleratorHourlyPrice}{R_{\text{GPU/hr}}} \newcommand{\AcceleratorMemoryBandwidth}{\text{BW}_{\text{accelerator}}} \newcommand{\AcceleratorRailVoltage}{V_{\text{rail}}} \newcommand{\AcceleratorSecondsPerQuery}{S_{\text{GPU/query}}} \newcommand{\AcceleratorSupplyCurrent}{i} \newcommand{\AcceleratorTargetQueryRate}{R_{\text{GPU,target}}} \newcommand{\AcceleratorsPerNode}{G_{\text{node}}} \newcommand{\AccelerometerBias}{b_a} \newcommand{\AcceptanceFraction}{\alpha} \newcommand{\AcceptanceIntervalLowerLimit}{L} \newcommand{\AcceptanceIntervalUpperLimit}{U} \newcommand{\AcceptanceProbability}{p_{\text{acc}}} \newcommand{\AcceptedInfluences}{\text{Inf}} \newcommand{\AcceptedInputSet}{\mathcal{A}_{\tau}} \newcommand{\AcceptedLabelCount}{d} \newcommand{\AcceptedOutcomePayoff}{V} \newcommand{\AcceptedSampleCount}{X} \newcommand{\AcceptedTaskMeanCost}{C_{\text{succ}}} \newcommand{\AcceptedTasks}{N_{\text{acc}}} \newcommand{\AcceptingStateSet}{F} \newcommand{\AccessAttemptTime}{t} \newcommand{\AccountQueryDistribution}{p_{\text{user}}} \newcommand{\AccumulatedProcessNoiseCovariance}{\mathbf{Q}_d} \newcommand{\AccumulatedSyncTime}{T_{\text{sync}}} \newcommand{\AccumulatedUpdateTime}{T_{\text{effective}}} \newcommand{\AccumulationStepCount}{k} \newcommand{\AccuracyAfterDeployment}{\text{Accuracy}} \newcommand{\AccuracyDecayRate}{\gamma} \newcommand{\AccuracyPayoffPerQuery}{V} \newcommand{\AchievedBrakingDeceleration}{a} \newcommand{\AchievedKernelBandwidth}{\text{BW}_{\text{effective}}} \newcommand{\AcquisitionEpoch}{t_{\text{acq}}} \newcommand{\ActVariationalObjective}{\mathcal{L}_{\text{ACT}}} \newcommand{\ActionBinCount}{B} \newcommand{\ActionChunk}{\mathbf{A}} \newcommand{\ActionChunkHorizon}{H} \newcommand{\ActionChunkIndex}{k} \newcommand{\ActionDimension}{d_a} \newcommand{\ActionExecutionRate}{f_{\text{exec}}} \newcommand{\ActionFilterCutoffFrequency}{f_{\text{cutoff}}} \newcommand{\ActionLowerBound}{\mathbf{a}_{\min}} \newcommand{\ActionMagnitudeBound}{a_{\max}} \newcommand{\ActionRangeMaximum}{a_{\max}} \newcommand{\ActionRangeMinimum}{a_{\min}} \newcommand{\ActionRecoverableFraction}{\rho_{a}} \newcommand{\ActionResidualVector}{\mathbf{r}} \newcommand{\ActionSpace}{\mathcal{A}} \newcommand{\ActionTokenPrefix}{a_{<j}} \newcommand{\ActionUpperBound}{\mathbf{a}_{\max}} \newcommand{\ActivationCheckpointCount}{n_{\text{ckpt}}} \newcommand{\ActivationFunction}{f} \newcommand{\ActivationInput}{x} \newcommand{\ActivationLipschitzBound}{L_{\phi}} \newcommand{\ActivationMatrix}{\mathbf{A}} \newcommand{\ActivationMemory}{M_{\text{activations}}} \newcommand{\ActivationPayloadSize}{M_{\text{act}}} \newcommand{\ActivationStagingTime}{t_{\text{activate}}} \newcommand{\ActivationVector}{\mathbf{a}} \newcommand{\ActiveContactIndex}{k} \newcommand{\ActiveControlTorque}{\mathbf{u}_{\text{active}}} \newcommand{\ActiveInferencePower}{P_{\text{active}}} \newcommand{\ActiveLeaseCount}{N_{\text{active}}} \newcommand{\ActiveMotionDuration}{T_{\text{motion}}} \newcommand{\ActiveParameterCount}{P_{\text{model}}} \newcommand{\ActivePrefillRequestSet}{\mathcal{P}_{\text{active}}} \newcommand{\ActiveSchemaSet}{\mathcal{S}} \newcommand{\ActiveTargetTokenCount}{N_{\text{active}}} \newcommand{\ActorAccelerationBound}{a_{k,\max}} \newcommand{\ActorBodyRadius}{r} \newcommand{\ActorUpdateDelayCount}{d} \newcommand{\ActuatedJointAccelerations}{\ddot{\mathbf{q}}_j} \newcommand{\ActuatedJointBiasForces}{\mathbf{h}_j} \newcommand{\ActuatedJointCoordinates}{\mathbf{q}_j} \newcommand{\ActuationSelectionBaseBlock}{\mathbf{S}_b} \newcommand{\ActuationSelectionMatrix}{\mathbf{S}} \newcommand{\ActuatorAxisCount}{N_{\text{axes}}} \newcommand{\ActuatorBiasEffort}{u_{\text{bias}}} \newcommand{\ActuatorCyclePeriod}{t_{\text{cycle}}} \newcommand{\ActuatorDutyCycle}{D_{\text{cycle}}} \newcommand{\ActuatorEffort}{u} \newcommand{\ActuatorOffTime}{t_{\text{off}}} \newcommand{\ActuatorOnTime}{t_{\text{on}}} \newcommand{\ActuatorResponseTime}{T_{\text{act}}} \newcommand{\ActuatorTorqueLowerBound}{\mathbf{u}_{\min}} \newcommand{\ActuatorTorqueUpperBound}{\mathbf{u}_{\max}} \newcommand{\AdamFirstMoment}{m} \newcommand{\AdamMomentDecayRate}{\beta} \newcommand{\AdamSecondMoment}{v} \newcommand{\AdaptationEnergyAllowance}{E_{\text{slack}}} \newcommand{\AdaptationInvestmentCost}{C_{\text{invest}}} \newcommand{\AdaptationLatencyIncrease}{\Delta L_{\text{lat,fg}}^{\text{wc}}} \newcommand{\AdaptationModule}{g_{\psi}} \newcommand{\AdaptationPeakMemory}{M_{\text{peak}}} \newcommand{\AdaptationPowerIncrement}{P_{\text{update}}} \newcommand{\AdaptationWindowEnergy}{E_{\text{update}}} \newcommand{\AdaptedHiddenActivation}{\mathbf{h}'} \newcommand{\AdaptedTaskCost}{C_{\text{task, adapt}}} \newcommand{\AdapterActivationFunction}{\sigma} \newcommand{\AdapterDownProjectionMatrix}{\mathbf{A}} \newcommand{\AdapterIndex}{k} \newcommand{\AdapterInitializationStandardDeviation}{\sigma} \newcommand{\AdapterRank}{r} \newcommand{\AdapterScalingFactor}{\gamma} \newcommand{\AdapterUpProjectionMatrix}{\mathbf{B}} \newcommand{\AdjacentNeighboringDataset}{X'} \newcommand{\AdjacentQueryResult}{v'} \newcommand{\AdmissibleBacklogCount}{n} \newcommand{\AdmissibleControlSet}{\mathcal{U}_{\text{adm}}} \newcommand{\AdmissibleDisturbanceSet}{\mathcal{W}} \newcommand{\AdmissionCheckCount}{n_{\text{chk}}} \newcommand{\AdmissionCheckIndex}{i} \newcommand{\AdmissionDecisionEvent}{e_{\text{auth}}} \newcommand{\AdmissionInclusivePrebrakeDelay}{T_{\text{true}}} \newcommand{\AdmissionRouteYield}{Y} \newcommand{\AdmittedAttemptCap}{N} \newcommand{\AdmittedCommand}{u} \newcommand{\AdmittedContactForce}{F^*} \newcommand{\AdmittedControlCommand}{\mathbf{u}} \newcommand{\AdmittedSpeedCommand}{v^*} \newcommand{\AdmittedTargetPosition}{\hat{\mathbf{p}}_{\text{target}}} \newcommand{\AdmittedWorkUnitCount}{m} \newcommand{\AdvantageStabilizer}{\epsilon_{\text{stab}}} \newcommand{\AdversarialDisturbance}{\mathbf{d}} \newcommand{\AdversarialExample}{x_{\text{adv}}} \newcommand{\AdversarialInputLength}{n} \newcommand{\AdversarialPenaltyWeight}{\lambda_{\text{adv}}} \newcommand{\AdversarialPerturbation}{\boldsymbol{\delta}_{\text{adv}}} \newcommand{\AdversarialPerturbationBudget}{\epsilon_{\text{adv}}} \newcommand{\AdversaryLoss}{\mathcal{L}_{\text{adv}}} \newcommand{\AffordanceFrame}{\mathcal{F}_{\text{affordance}}} \newcommand{\AffordanceSuccessEstimate}{V_{\text{policy}}} \newcommand{\AgeBlindTravel}{\Delta x_{\text{blind}}} \newcommand{\AgeCheckInstant}{t_{\text{curr}}} \newcommand{\AggregateSlotWork}{W} \newcommand{\AggregatedRecoveryDataset}{\mathcal{D}} \newcommand{\AggregatedSurrogateLoss}{\epsilon_N} \newcommand{\AggregationLearnedPolicy}{\hat{\pi}} \newcommand{\AggregationLearnerStateDistribution}{d_{\hat{\pi}_i}} \newcommand{\AggregationRoundCount}{N} \newcommand{\AggregationRoundIndex}{i} \newcommand{\AggregationRoundTrajectorySet}{\mathcal{T}} \newcommand{\AiStandaloneSensitivity}{S_{\text{AI}}} \newcommand{\AisleTravelSpeed}{v_{\text{aisle}}} \newcommand{\AisleWidth}{w} \newcommand{\AlertCheckCount}{N_{\text{tests}}} \newcommand{\AlertFalsePositiveRate}{\alpha_{\text{fp}}} \newcommand{\AlgorithmTaxonomyAxis}{\mathsf{Algorithm}} \newcommand{\AliasedVibrationFrequency}{f_{\text{alias}}} \newcommand{\AliasingHarmonicIndex}{k} \newcommand{\AllGatherCompletionTime}{T_{\text{allgather}}} \newcommand{\AllOnesVector}{\mathbf{1}} \newcommand{\AllReduceCompletionTime}{T_{\text{allreduce}}} \newcommand{\AllReduceMinimumBandwidthTime}{T_{\text{bandwidth}}^{\text{min}}} \newcommand{\AllRunsPassEstimate}{\widehat{r}} \newcommand{\AllToAllCompletionTime}{T_{\text{alltoall}}} \newcommand{\AllToAllExchangeTime}{T} \newcommand{\AllocatedBlockCount}{N_{\text{blocks}}} \newcommand{\AllocatedHazardRate}{\lambda_{\text{alloc}}} \newcommand{\AllocatedWallTime}{T_{\text{wall}}} \newcommand{\AllowableRailDroop}{\Delta V_{\text{droop, max}}} \newcommand{\AllowableRailExcursion}{\Delta V_{\max}} \newcommand{\AllowableWindingTemperatureRise}{\Delta T_{\max}} \newcommand{\AllowedTokenSet}{\mathcal{V}_{\text{allow}}} \newcommand{\AllowedViolationFraction}{V^{\text{allow}}} \newcommand{\AlphabetByte}{b} \newcommand{\AlternateModelInput}{x'} \newcommand{\AmbientDimension}{D} \newcommand{\AmbientTemperature}{T_{\text{amb}}} \newcommand{\AmortizedTurnCost}{\bar{C}_{\text{turn}}} \newcommand{\AngularAcceleration}{\boldsymbol{\alpha}} \newcommand{\AngularClearance}{\theta_{\text{clear}}} \newcommand{\AngularClearanceRate}{\dot{\theta}_{\text{clear}}} \newcommand{\AngularFrequency}{\omega} \newcommand{\AngularSpeed}{\omega} \newcommand{\AngularVelocity}{\boldsymbol{\omega}} \newcommand{\AngularVelocityDerivative}{\dot{\boldsymbol{\omega}}} \newcommand{\AnnualQueryVolume}{Q_{\text{annual}}} \newcommand{\AnonymitySetSize}{k_{\text{anon}}} \newcommand{\AntiWindupTrackingTimeConstant}{T_t} \newcommand{\AntialiasingFilterVariance}{s} \newcommand{\ApiAccount}{u} \newcommand{\ApparentContrast}{C} \newcommand{\AppearanceRealityGap}{\Delta_{\text{vis}}} \newcommand{\AppliedForce}{F} \newcommand{\AppliedLoadCycleCount}{n} \newcommand{\ApproachChannelCount}{K_a} \newcommand{\ApproachDirection}{\hat{\mathbf{a}}_{\text{approach}}} \newcommand{\ApproachPosition}{x} \newcommand{\ApproachPredicate}{P_{\text{approach}}} \newcommand{\ApproachSpeed}{v_{\text{app}}} \newcommand{\ApprovalCatchFraction}{q} \newcommand{\ApprovalHeldTrajectories}{N_{\text{held}}} \newcommand{\ApproximatingDistribution}{q} \newcommand{\ArbitrationFieldBitCount}{B_{\text{arb},i}} \newcommand{\ArcObstacleDistance}{d_{\text{arc}}} \newcommand{\ArchitectureResourceCost}{C} \newcommand{\ArchitectureSearchSpace}{\mathcal{A}} \newcommand{\ArcsineEffectSize}{h} \newcommand{\ArgumentLegConfidence}{r} \newcommand{\ArgumentLegCount}{m} \newcommand{\ArithmeticIntensity}{I} \newcommand{\ArmStoppingDeceleration}{a_{\text{arm}}} \newcommand{\ArmSuccessProbability}{p} \newcommand{\ArmingSettleDuration}{t_{\text{settle}}} \newcommand{\ArrivalOffsetTravel}{\Delta x} \newcommand{\ArrivalRate}{\lambda_{\text{arr}}} \newcommand{\ArrivalStampOffset}{\Delta t_{\text{recv}}} \newcommand{\ArrivalTimestamp}{t_{\text{recv}}} \newcommand{\ArtifactVersion}{v} \newcommand{\AssessedContactForceLimit}{F_{\text{limit}}} \newcommand{\AssignedJobGpu}{g} \newcommand{\AssociationCostEntry}{c} \newcommand{\AssuranceClaim}{C} \newcommand{\AsymptoticTightBound}{\Theta} \newcommand{\AtmosphericExtinctionCoefficient}{\beta_{\text{atm}}} \newcommand{\AttackStepsPgd}{K_{\text{PGD}}} \newcommand{\AttackedTrialCount}{n} \newcommand{\AttainableComputeRate}{R_{\text{attain}}} \newcommand{\AttemptCleanupCost}{C_{\text{cleanup}}} \newcommand{\AttemptCost}{C_{\text{attempt}}} \newcommand{\AttemptCycleDuration}{t_{\text{cyc}}} \newcommand{\AttemptDuration}{t_{\text{att}}} \newcommand{\AttemptGenerationTime}{T_{\text{gen}}} \newcommand{\AttemptPassProbability}{p} \newcommand{\AttemptRuntimeOverheadCost}{C_{\text{runtime}}} \newcommand{\AttemptVerificationCost}{C_{\text{verify}}} \newcommand{\AttentionHeadCount}{N_{\text{heads}}} \newcommand{\AttentionHeadDimension}{d_{\text{head}}} \newcommand{\AttentionHeadOutput}{\mathbf{O}} \newcommand{\AttentionKeyMatrix}{\mathbf{K}} \newcommand{\AttentionOutputMatrix}{\mathbf{O}} \newcommand{\AttentionOutputProjectionMatrix}{\mathbf{W}_{O}} \newcommand{\AttentionQueryMatrix}{\mathbf{Q}} \newcommand{\AttentionScoreEntry}{S_{ij}} \newcommand{\AttentionScoreMatrix}{\mathbf{S}} \newcommand{\AttentionScoreRow}{\mathbf{S}_{i, \cdot}} \newcommand{\AttentionScoreSummand}{S_{ik}} \newcommand{\AttentionScoreTile}{\mathbf{S}_{ij}} \newcommand{\AttentionValuesMatrix}{\mathbf{V}} \newcommand{\AttentionValuesProjectionMatrix}{\mathbf{W}_{V}} \newcommand{\AttentionValuesSourceMatrix}{\mathbf{X}_{V}} \newcommand{\AttentionValuesVector}{\mathbf{v}} \newcommand{\AttentionWeightEntry}{A_{ij}} \newcommand{\AttentionWeightMatrix}{\mathbf{A}} \newcommand{\AttentionWeightVector}{\mathbf{a}} \newcommand{\AttitudeError}{\theta_{\text{att}}} \newcommand{\AttributionFeatureCount}{n_{\text{feat}}} \newcommand{\AuditGroupRecordCount}{n_{\text{records}}} \newcommand{\AuthorityExposureLevel}{A} \newcommand{\AutocorrelationLagIndex}{k} \newcommand{\AutoencoderReconstructionError}{\mathcal{L}_{\text{rec}}} \newcommand{\AutomatedResetTime}{t_{\text{reset,auto}}} \newcommand{\AutomatonStateSet}{Q} \newcommand{\AutomatonTransitionFunction}{\delta} \newcommand{\AutonomousExecutionComputeCost}{C_{\text{compute}}} \newcommand{\AutoscalingDecisionTime}{T_{\text{decide}}} \newcommand{\AutoscalingDetectionTime}{T_{\text{detect}}} \newcommand{\AutoscalingResponseTime}{T_{\text{response}}} \newcommand{\AvailabilityObjective}{S_{\text{availability}}} \newcommand{\AvailableBrakingDistance}{D_{\text{avail}}} \newcommand{\AvailableDeceleration}{a} \newcommand{\AvailableObservations}{\mathcal{O}_{\text{avail}}} \newcommand{\AverageCopperLossPower}{\bar{P}_{\text{loss}}} \newcommand{\AverageOnlineRegret}{\gamma_N} \newcommand{\AveragePower}{P_{\text{avg}}} \newcommand{\AverageStateVisitationDistribution}{\bar{d}} \newcommand{\AxiBurstLength}{A_{\text{len}}} \newcommand{\AxisGridPointCount}{N} \newcommand{\AzimuthAngle}{\theta_{\text{az}}} \newcommand{\BackEmfVoltage}{e_{\text{bemf}}} \newcommand{\BacklashAngle}{\theta_{\text{backlash}}} \newcommand{\BackwardEulerEigenvalue}{\lambda_{\text{BE}}} \newcommand{\BackwardEulerTransitionMatrix}{\mathbf{A}_{\text{BE}}} \newcommand{\BackwardPassTime}{T_{\text{backward}}} \newcommand{\BackwardReachableTube}{\mathcal{R}} \newcommand{\BalanceDivergenceTime}{\tau_{\text{fall}}} \newcommand{\BallRadius}{r} \newcommand{\BallVolume}{V_D} \newcommand{\Bandwidth}{\text{BW}} \newcommand{\BankConflictPenalty}{\Delta t_{\text{conflict}}} \newcommand{\BarrierConstraintBound}{b_{\text{cbf}}} \newcommand{\BarrierConstraintCount}{K_b} \newcommand{\BarrierConstraintNormal}{\mathbf{a}_{\text{cbf}}} \newcommand{\BarrierFunction}{h} \newcommand{\BarrierFunctionRate}{\dot{h}} \newcommand{\BarrierHalfSpaceControlSet}{\mathcal{U}_{\text{safe}}} \newcommand{\BarrierMargin}{\delta} \newcommand{\BarrierNormalizationScale}{h_{\text{scale}}} \newcommand{\BarrierProjectionLagrangian}{L_{\text{Lag}}} \newcommand{\BarrierProjectionMultiplier}{\lambda} \newcommand{\BarrierRelativeDegree}{r} \newcommand{\BaseAbscissaVelocity}{\dot{x}} \newcommand{\BaseAccelerationCommand}{a} \newcommand{\BaseBatchSize}{B_{\text{base}}} \newcommand{\BaseCameraRotation}{\mathbf{R}_{\text{base}}^{\text{cam}}} \newcommand{\BaseCameraTransform}{\mathbf{T}_{\text{base}}^{\text{cam}}} \newcommand{\BaseCameraTranslation}{\mathbf{t}_{\text{base}}^{\text{cam}}} \newcommand{\BaseFlangeTransform}{\mathbf{T}_{\text{base}}^{\text{flange}}} \newcommand{\BaseForwardSpeed}{v} \newcommand{\BaseFramePoint}{\mathbf{p}_{\text{base}}} \newcommand{\BaseHeadingRate}{\dot{\theta}_{\text{head}}} \newcommand{\BaseJointInertiaCoupling}{\mathbf{M}_{bj}} \newcommand{\BaseLateralPosition}{y_{\text{base}}} \newcommand{\BaseLateralVelocity}{\dot{y}} \newcommand{\BaseLayerCount}{N_{L,0}} \newcommand{\BaseLearningRate}{\eta_{\text{base}}} \newcommand{\BaseLongitudinalPosition}{x_{\text{base}}} \newcommand{\BaseLongitudinalVelocity}{\dot{x}} \newcommand{\BaseOdometrySpeed}{v} \newcommand{\BaseOrdinateVelocity}{\dot{y}} \newcommand{\BasePosition}{\mathbf{p}_{\text{base}}} \newcommand{\BasePromptLength}{S_{\text{base}}} \newcommand{\BaseStoppingDistance}{d_{\text{base}}} \newcommand{\BaseToCameraTransform}{\mathbf{T}_{\text{cam} \leftarrow \text{base}}} \newcommand{\BaseTrainingComputeCost}{C_{\text{compute}}} \newcommand{\BaseTrajectoryTokenCount}{N_{\text{base}}} \newcommand{\BaseTravelDistance}{d} \newcommand{\BaseTravelSpeed}{v_{\text{base}}} \newcommand{\BaseWidthMultiplier}{w_{\text{mult},0}} \newcommand{\BaseWristTransform}{\mathbf{T}_{\text{base} \leftarrow \text{wrist}}} \newcommand{\BaseYawRateBias}{\omega_{\text{bias}}} \newcommand{\BaselineAcceptanceEstimate}{\hat{p}_{\text{base}}} \newcommand{\BaselineControllerAction}{\mathbf{a}_t^{\text{base}}} \newcommand{\BaselineConversionRate}{p_0} \newcommand{\BaselineFeatureMean}{\mu_{\text{base}}} \newcommand{\BaselineFeatureStandardDeviation}{\sigma_{\text{base}}} \newcommand{\BaselineIntervalLowerLimit}{l_{\text{base}}} \newcommand{\BaselineIntervalUpperLimit}{u_{\text{base}}} \newcommand{\BaselineLowerLimitDistance}{\delta^-_{\text{base}}} \newcommand{\BaselineOnlyAcceptedTaskCount}{b} \newcommand{\BaselineOnlyCorrectCount}{n_{\text{base}}} \newcommand{\BaselinePolicyAcceptanceProbability}{p_{X}} \newcommand{\BaselinePolicyCost}{C_{X}} \newcommand{\BaselineStateDistribution}{d^{\pi_{\text{base}}}} \newcommand{\BaselineTaskCost}{C_{\text{task, base}}} \newcommand{\BaselineToolCallDistribution}{p_{b}} \newcommand{\BaselineTrackingError}{e_{\text{track}}} \newcommand{\BaselineTrainingDuration}{T_{\text{hours}}} \newcommand{\BaselineTrajectoryGoodput}{\mathcal{G}_{b}} \newcommand{\BaselineUpperLimitDistance}{\delta^+_{\text{base}}} \newcommand{\BatchArrivalRate}{\lambda_{\text{batch}}} \newcommand{\BatchAxisLabel}{b} \newcommand{\BatchBufferMemory}{M_{\text{batch}}} \newcommand{\BatchCostPerAcceptedTask}{C_{\text{eff,batch}}} \newcommand{\BatchDataVolume}{D_{\text{vol}}^{(\text{batch})}} \newcommand{\BatchExampleIndex}{n} \newcommand{\BatchFetchTime}{T_{\text{fetch}}} \newcommand{\BatchFillArrivalCount}{k} \newcommand{\BatchFixedOverheadTime}{T_{\text{fixed}}} \newcommand{\BatchFlushStartTime}{t_{\text{start}}} \newcommand{\BatchFormationDelay}{L_{\text{lat,form}}} \newcommand{\BatchIndex}{k} \newcommand{\BatchLabelComponent}{y_{ij}} \newcommand{\BatchLatencyEnvelope}{L_{\text{lat,envelope}}} \newcommand{\BatchLoss}{\mathcal{L}_{\text{batch}}} \newcommand{\BatchMaxOutputLength}{S_{\text{max}}} \newcommand{\BatchMaximumDeviationMultiple}{k} \newcommand{\BatchMeanOutputLength}{\bar{S}} \newcommand{\BatchNormMean}{\mu_{\mathcal{B}}} \newcommand{\BatchNormOutput}{y} \newcommand{\BatchNormRunningMean}{\boldsymbol{\mu}_{\mathcal{B}}} \newcommand{\BatchNormRunningStandardDeviation}{\boldsymbol{\sigma}_{\mathcal{B}}} \newcommand{\BatchNormStandardDeviation}{\sigma_{\mathcal{B}}} \newcommand{\BatchOperations}{O_{\text{batch}}} \newcommand{\BatchPredictedProbability}{\hat{y}_{ij}} \newcommand{\BatchProcessingTime}{T_{\text{process}}} \newcommand{\BatchRolloutCount}{N_{\text{batch}}} \newcommand{\BatchScalingFactor}{k} \newcommand{\BatchServiceTime}{T_{\text{svc}}} \newcommand{\BatchSize}{B} \newcommand{\BatchTransferTime}{T_{\text{transfer}}} \newcommand{\BatchedDecodeStepTime}{t_{\text{step}}} \newcommand{\BatchedEventIndex}{i} \newcommand{\BatchedRequestLatency}{L_{\text{lat,batch}}} \newcommand{\BatchingLatencyBudget}{L_{\text{lat,budget}}} \newcommand{\BatchingQueueWait}{L_{\text{lat,wait}}} \newcommand{\BatchingWindow}{T_{\text{window}}} \newcommand{\BatteryCellResistance}{R_{\text{cell}}} \newcommand{\BeamDivergenceAngle}{\delta\theta_{\text{div}}} \newcommand{\BeamWidth}{W} \newcommand{\BearingRay}{\mathbf{r}} \newcommand{\BeatFrequency}{f_b} \newcommand{\BehaviorCloningHorizon}{S} \newcommand{\BehaviorCloningLoss}{\mathcal{L}_{\text{BC}}} \newcommand{\BehaviorDistribution}{b} \newcommand{\BehaviorPolicyVersion}{\text{ver}_b} \newcommand{\BeliefErrorBound}{E} \newcommand{\BeliefInvalidationHorizon}{T_{\text{inv}}} \newcommand{\BeliefState}{b} \newcommand{\BellmanBackupTarget}{y} \newcommand{\BellmanErrorLoss}{\mathcal{L}_{\text{Bellman}}} \newcommand{\BelowThresholdIndicator}{\mathbf{1}_{\{|(\mathbf{W}_{\text{sparse}})_{ij}| \leq \delta_{\text{prune}}\}}} \newcommand{\BestEffortWireBitCount}{B_{\text{BE,wire}}} \newcommand{\BetterArmSuccessProbability}{p_{\text{high}}} \newcommand{\BetweenTaskStandardDeviation}{\sigma_{\text{task}}} \newcommand{\BevPillarFeature}{\mathbf{V}_{\text{BEV}}} \newcommand{\BevPillarXIndex}{X} \newcommand{\BevPillarYIndex}{Y} \newcommand{\BiasFeedbackFactor}{\alpha_{\text{fb}}} \newcommand{\BiasVector}{\mathbf{b}} \newcommand{\BilledAllocationTime}{T_{\text{total}}} \newcommand{\BinaryActivationVector}{\mathbf{a}} \newcommand{\BinaryClassifier}{h} \newcommand{\BinaryWeightVector}{\mathbf{w}} \newcommand{\BinomialSuccessCount}{X} \newcommand{\BipedTiltAcceleration}{\ddot{\theta}_{\text{tilt}}} \newcommand{\BisectionBandwidth}{\text{BW}_{\text{bisect}}} \newcommand{\BitFlippedFloatNumber}{x_{\text{corrupt}}} \newcommand{\BitTime}{T_{\text{bit}}} \newcommand{\BlackoutClockConversionError}{\Delta t_{\text{one-sigma scenario}}} \newcommand{\BlendDeadline}{t_{\text{blend}}} \newcommand{\BlendedCommandJerk}{j_{\text{cmd}}} \newcommand{\BlendedControlCommand}{\mathbf{u}_{\text{blend}}} \newcommand{\BlendedInputTokenPrice}{c_{\text{in}}} \newcommand{\BlendingTransitionWindow}{\tau_{\text{blend}}} \newcommand{\BlindTravelDistance}{d_{\text{blind}}} \newcommand{\BlockCheckTime}{T_{\text{ver}}} \newcommand{\BlockCoordinateX}{b_x} \newcommand{\BlockCoordinateY}{b_y} \newcommand{\BlockCoordinateZ}{b_z} \newcommand{\BlockEdgeVoxelCount}{n_{\text{blk}}} \newcommand{\BlockMaximum}{M} \newcommand{\BlockMaximumLevel}{z} \newcommand{\BlockMaximumLimitDistribution}{G} \newcommand{\BlockMaximumNormalizingScale}{a} \newcommand{\BlockMaximumNormalizingShift}{b} \newcommand{\BlockMetadataSize}{s_{\text{meta}}} \newcommand{\BlockQuantizationScale}{s_b} \newcommand{\BlockRangeMaximum}{x_{\max,i}} \newcommand{\BlockRangeMinimum}{x_{\min,i}} \newcommand{\BlockSampleCount}{n} \newcommand{\BlockedWorkerCount}{N_{\text{blocked}}} \newcommand{\BlockingCallTimeout}{T_{\text{out}}} \newcommand{\BlockingTaskIndex}{k} \newcommand{\BodyAcceleration}{\dot{v}} \newcommand{\BodyDisplacement}{x} \newcommand{\BodyEndEffectorTransform}{\mathbf{T}_{BE}} \newcommand{\BodyFramePoint}{\mathbf{p}_{\text{body}}} \newcommand{\BodyFramePointCovariance}{\boldsymbol{\Sigma}_{\text{body}}} \newcommand{\BodyLidarTransform}{\mathbf{T}_{bl}} \newcommand{\BodyReferenceFrame}{\mathcal{F}_B} \newcommand{\BodyRegionMass}{m_H} \newcommand{\BodySpeed}{v} \newcommand{\BoltzmannConstant}{k_B} \newcommand{\BoltzmannStateEnergy}{E} \newcommand{\BoltzmannTemperature}{T} \newcommand{\BootstrapQuantileFunction}{Q} \newcommand{\BootstrapReplicateCount}{B_{\text{boot}}} \newcommand{\BootstrapReplicateIndex}{r} \newcommand{\BottomedOutContactStiffness}{k_{\infty}} \newcommand{\BouligandContingentCone}{T_{\mathcal{C}}} \newcommand{\BoundaryConditionVector}{\mathbf{b}} \newcommand{\BoundaryLayerTime}{t_{\text{fast}}} \newcommand{\BoundedRegimeTimestamp}{t_{\text{bounded}}} \newcommand{\BoxMaximumHorizontalCoordinate}{x_{\text{max}}} \newcommand{\BoxMaximumVerticalCoordinate}{y_{\text{max}}} \newcommand{\BoxMinimumHorizontalCoordinate}{x_{\text{min}}} \newcommand{\BoxMinimumVerticalCoordinate}{y_{\text{min}}} \newcommand{\BrakeChopperResistance}{R_{\text{brake}}} \newcommand{\BrakeCommandForce}{F_{\text{cmd}}} \newcommand{\BrakeResistorPulseEnergy}{E_{\text{pulse}}} \newcommand{\BrakingDistance}{d_{\text{brake}}} \newcommand{\BrakingForce}{F_{\text{brake}}} \newcommand{\BrakingOnsetContactForce}{F_{\text{cmd}}} \newcommand{\BrakingWork}{W_{\text{brake}}} \newcommand{\BreadthCriticalPathLatency}{T^{\text{breadth}}} \newcommand{\BreadthPeakKvCacheMemory}{M_{\text{KV}}^{\text{breadth}}} \newcommand{\BreakEvenAcceptanceProbability}{p'} \newcommand{\BreakEvenBrakingDeceleration}{a} \newcommand{\BreakEvenParseFailureRate}{p_{\text{break}}} \newcommand{\BreakEvenTaskCount}{N^*} \newcommand{\BreakEvenUtilization}{u^*} \newcommand{\BreakerCooldownInterval}{T_{\text{cool}}} \newcommand{\BreakerFailureFraction}{r} \newcommand{\BreakerMinimumSampleCount}{n_{\min}} \newcommand{\BreakerOutcomeIndex}{i} \newcommand{\BreakerOutcomeWindow}{W} \newcommand{\BreakerTripThreshold}{r_{\text{trip}}} \newcommand{\BridgeTraceResistance}{R_{\text{trace}}} \newcommand{\BroadcastColumnElement}{A} \newcommand{\BroadcastColumnTensor}{\mathbf{A}} \newcommand{\BroadcastCompletionTime}{T_{\text{broadcast}}} \newcommand{\BroadcastRowElement}{b} \newcommand{\BroadcastRowTensor}{\mathbf{B}} \newcommand{\BroadcastTableSize}{s_{\text{table}}} \newcommand{\BspLearningRate}{\eta_{\text{BSP}}} \newcommand{\BsplineBasisFunction}{B} \newcommand{\BudgetEvaluationTime}{\tau} \newcommand{\BudgetFreeBalance}{F} \newcommand{\BudgetNodeIndex}{k} \newcommand{\BudgetReservedFunds}{R} \newcommand{\BudgetSettledCharges}{E} \newcommand{\BudgetedAcceptanceProbability}{q_{\pi}} \newcommand{\BufferDependencyEdgeSet}{E} \newcommand{\BufferDependencyGraph}{G} \newcommand{\BufferDependencyVertexSet}{V} \newcommand{\BufferIndex}{i} \newcommand{\BulkDecouplingCapacitance}{C_{\text{bulk}}} \newcommand{\BumplessTransferBlend}{\alpha} \newcommand{\BumplessTransferBlendAcceleration}{\ddot{\alpha}} \newcommand{\BumplessTransferBlendRate}{\dot{\alpha}} \newcommand{\BumplessTransferBlendSlope}{\alpha'} \newcommand{\BumplessTransferProgress}{\hat{t}} \newcommand{\BumplessTransferStartInstant}{t_{\text{start}}} \newcommand{\BurstArrivalCount}{N_{\text{burst}}} \newcommand{\BurstSurvivalTime}{t_{\text{limit}}} \newcommand{\BusBitRate}{R_{\text{bit}}} \newcommand{\BusCapacitorEnergy}{E_C} \newcommand{\BusCapacitorVoltage}{V_C} \newcommand{\BusSerializationTime}{t_{\text{bus}}} \newcommand{\ButterflyAllReduceTime}{T_{\text{butterfly}}} \newcommand{\ByteAlphabet}{\Sigma} \newcommand{\ByteString}{u} \newcommand{\ByzantineClientCount}{f} \newcommand{\ByzantineFaultCount}{f} \newcommand{\CableFlexCycleCount}{n_{\text{cable}}} \newcommand{\CableRatedFatigueLife}{L_{\text{cable}}} \newcommand{\CacheMissStallFraction}{f} \newcommand{\CachedInputTokenCount}{n_{\text{cache}}} \newcommand{\CachedInputTokenPrice}{c_{\text{cache}}} \newcommand{\CalibratedAcceptanceEstimate}{\hat{p}} \newcommand{\CalibrationBinCount}{N_{\text{bins}}} \newcommand{\CalibrationBinExampleSet}{B_m} \newcommand{\CalibrationBinIndex}{m} \newcommand{\CalibrationConstraintMatrix}{\mathbf{V}} \newcommand{\CalibrationDataDistribution}{p_{\text{cal}}} \newcommand{\CalibrationDataset}{\mathcal{C}_{\text{cal}}} \newcommand{\CalibrationExampleCount}{n_{\text{cal}}} \newcommand{\CalibrationModelPoint}{\mathbf{M}} \newcommand{\CalibrationPoseIndex}{k} \newcommand{\CalibrationRotationAxisCount}{N} \newcommand{\CalibrationSceneIndex}{j} \newcommand{\CalibrationTemperature}{T_{\text{cal}}} \newcommand{\CalibrationViewCount}{N} \newcommand{\CallLatency}{T_{\text{call}}} \newcommand{\CallPostprocessingTime}{T_{\text{post}}} \newcommand{\CallPreparationTime}{T_{\text{prep}}} \newcommand{\CallTailProbability}{p_{\text{tail}}} \newcommand{\CallUsefulWorkTime}{W} \newcommand{\CameraCenterArcPosition}{x_{\text{rot}}} \newcommand{\CameraExtrinsicRotation}{\mathbf{R}_{bc}} \newcommand{\CameraExtrinsicTransform}{\mathbf{T}_{bc}} \newcommand{\CameraExtrinsicTranslation}{\mathbf{p}_{bc}} \newcommand{\CameraFrameDepth}{Z_c} \newcommand{\CameraFrameHorizontalCoordinate}{X_c} \newcommand{\CameraFramePeriod}{T_{\text{sample}}} \newcommand{\CameraFramePoint}{\mathbf{p}_c} \newcommand{\CameraFramePointCovariance}{\boldsymbol{\Sigma}_c} \newcommand{\CameraFrameVerticalCoordinate}{Y_c} \newcommand{\CameraIdentifierEmbedding}{\mathbf{e}_{\text{cam}}} \newcommand{\CameraImage}{\mathbf{I}} \newcommand{\CameraImuTimeOffset}{\Delta t_{\text{imu}}} \newcommand{\CameraIntrinsicCalibrationMatrix}{\mathbf{K}} \newcommand{\CameraIntrinsicInverseTranspose}{\mathbf{K}^{-\top}} \newcommand{\CameraLateralStandardDeviation}{\sigma_{x_c}} \newcommand{\CameraMountTiltAngle}{\theta_{\text{ext}}} \newcommand{\CameraObjectTransform}{\mathbf{T}_{\text{camera}}^{\text{object}}} \newcommand{\CameraOpticalCenter}{\mathbf{o}} \newcommand{\CameraReferenceFrame}{\mathcal{F}_{\text{cam}}} \newcommand{\CameraRotationColumn}{\mathbf{r}} \newcommand{\CameraSampleTimestamp}{t_{\text{cam}}} \newcommand{\CameraSkewCoefficient}{\gamma} \newcommand{\CameraTargetTransform}{\mathbf{T}_{\text{cam}}^{\text{target}}} \newcommand{\CameraToWorldRotation}{\mathbf{R}_{WC}} \newcommand{\CameraToWorldTransform}{\mathbf{T}_{WC}} \newcommand{\CameraToWorldTranslation}{\mathbf{t}_{WC}} \newcommand{\CampaignActiveTime}{T_{\text{active}}} \newcommand{\CanHighLineVoltage}{V_{\text{CANH}}} \newcommand{\CanLowLineVoltage}{V_{\text{CANL}}} \newcommand{\CanaryAllocationFraction}{\rho} \newcommand{\CanaryInterventionRate}{\lambda_{\text{canary}}} \newcommand{\CanaryLabelDelay}{t_{\text{label}}} \newcommand{\CanarySpeedBound}{v_{\text{canary}}} \newcommand{\CanaryStageDuration}{T_{\text{stage}}} \newcommand{\CanaryTrafficFraction}{p_{\text{stage}}} \newcommand{\CandidateAcceptanceEstimate}{\hat{p}_{\text{cand}}} \newcommand{\CandidateActionVector}{\hat{\mathbf{a}}} \newcommand{\CandidateArchitecture}{a} \newcommand{\CandidateAvailabilityEstimate}{\widehat{q}} \newcommand{\CandidateAvailabilityProbability}{q} \newcommand{\CandidateCheckingCost}{v} \newcommand{\CandidateClientCount}{K_{\text{candidates}}} \newcommand{\CandidateControlCommand}{\mathbf{u}^{\text{cand}}} \newcommand{\CandidateControlCommandDerivative}{\dot{\mathbf{u}}^{\text{cand}}} \newcommand{\CandidateDefectRate}{\epsilon} \newcommand{\CandidateGenerationCost}{g} \newcommand{\CandidateIndex}{i} \newcommand{\CandidateIntervalLowerLimit}{l_{\text{cand}}} \newcommand{\CandidateIntervalUpperLimit}{u_{\text{cand}}} \newcommand{\CandidateLowerLimitDistance}{\delta^-_{\text{cand}}} \newcommand{\CandidateOnlyAcceptedTaskCount}{c} \newcommand{\CandidatePolicyAcceptanceProbability}{p_{Y}} \newcommand{\CandidatePolicyAction}{\mathbf{a}_t^{\text{cand}}} \newcommand{\CandidatePolicyCost}{C_{Y}} \newcommand{\CandidatePoolSize}{N} \newcommand{\CandidateProposal}{p} \newcommand{\CandidateRoutingPolicy}{Y} \newcommand{\CandidateScoreVector}{\mathbf{c}} \newcommand{\CandidateScoringCost}{c_{\text{infer}}} \newcommand{\CandidateScoringError}{\epsilon} \newcommand{\CandidateSkill}{a} \newcommand{\CandidateSpeedCommand}{v_{\text{cand}}} \newcommand{\CandidateTailCompletionTime}{\widehat{T}_{c,0.99}} \newcommand{\CandidateToolCallDistribution}{p_{c}} \newcommand{\CandidateTrackingErrorStandardDeviation}{\sigma_{\text{track}}} \newcommand{\CandidateTrajectoryGoodput}{\mathcal{G}_{c}} \newcommand{\CandidateUpperLimitDistance}{\delta^+_{\text{cand}}} \newcommand{\CandidateUtility}{U} \newcommand{\CandidateUtilityMean}{\mu} \newcommand{\CandidateUtilityStandardDeviation}{\sigma_{U}} \newcommand{\CandidateViolationCount}{V_{c}} \newcommand{\CandidateWinCount}{j} \newcommand{\CapabilityGrant}{\Gamma} \newcommand{\CaptureAgeEmbedding}{\mathbf{e}_{\Delta t}} \newcommand{\CaptureSampleIndex}{t_0} \newcommand{\CaptureSampleKalmanGain}{\mathbf{G}_{t_0}} \newcommand{\CaptureSampleMeasurementMatrix}{\mathbf{H}_{t_0}} \newcommand{\CaptureSamplePredictedCovariance}{\mathbf{P}_{t_0|t_0-1}} \newcommand{\CaptureSamplePredictedEstimate}{\hat{\mathbf{x}}_{t_0|t_0-1}} \newcommand{\CaptureSampleUpdatedCovariance}{\mathbf{P}_{t_0|t_0}} \newcommand{\CaptureSampleUpdatedEstimate}{\hat{\mathbf{x}}_{t_0|t_0}} \newcommand{\CaptureTimestamp}{t_{\text{capture}}} \newcommand{\CapturedSensorObservation}{\mathbf{z}_{t_0}} \newcommand{\CartesianAcceleration}{\ddot{\mathbf{p}}} \newcommand{\CartesianPosition}{\mathbf{p}} \newcommand{\CartesianXCoordinate}{x} \newcommand{\CartesianYCoordinate}{y} \newcommand{\CartesianZCoordinate}{z} \newcommand{\CascadeEscalationProbability}{p_{\text{escalate}}} \newcommand{\CascadeGateCost}{g} \newcommand{\CascadeGateDuration}{v} \newcommand{\CascadeInferenceEnergy}{E_{\text{cascade}}} \newcommand{\CascadeTaskCost}{C_{\text{cascade}}} \newcommand{\CascadeTaskDuration}{T_{\text{cascade}}} \newcommand{\CascadeTierCost}{c^{\text{tier}}} \newcommand{\CascadeTierDuration}{t} \newcommand{\CascadeTierIndex}{j} \newcommand{\CascadedBarrierCertificate}{\psi} \newcommand{\CascadedBarrierClassKFunction}{\alpha} \newcommand{\CascadedBarrierDerivative}{\dot{\psi}} \newcommand{\CaseAmbientThermalResistance}{R_{\text{th,case-amb}}} \newcommand{\CaseTemperature}{T_{\text{case}}} \newcommand{\CaseThermalCapacitance}{C_{\text{case}}} \newcommand{\CaseThermalTimeConstant}{\tau_{\text{th,case}}} \newcommand{\CatalogDefinitionTokens}{S_{\text{catalog}}} \newcommand{\CatalogStagingCallCount}{N} \newcommand{\CategoryRecordCount}{n} \newcommand{\CausalInterventionMask}{\mathcal{M}} \newcommand{\CausalMediator}{M} \newcommand{\CausalTokenPosition}{s} \newcommand{\CbsRuntimeBudget}{Q} \newcommand{\CellOccupancyProbability}{p} \newcommand{\CenterCount}{k} \newcommand{\CentralizedTrainingEnergy}{E_{\text{centralized}}} \newcommand{\CentroidalAngularMomentum}{\mathbf{h}_{\text{ang}}} \newcommand{\CentroidalAngularMomentumDerivative}{\dot{\mathbf{h}}_{\text{ang}}} \newcommand{\CentroidalLinearMomentum}{\mathbf{h}_{\text{lin}}} \newcommand{\CentroidalLinearMomentumDerivative}{\dot{\mathbf{h}}_{\text{lin}}} \newcommand{\CentroidalMomentum}{\mathbf{h}_G} \newcommand{\CentroidalMomentumMatrix}{\mathbf{A}_G} \newcommand{\CentroidalMomentumMatrixDerivative}{\dot{\mathbf{A}}_G} \newcommand{\CentroidalMomentumRate}{\dot{\mathbf{h}}_G} \newcommand{\CertifiedCommandWindow}{\mathbf{u}^*_{t:t+H-1}} \newcommand{\CertifiedControlAction}{\mathbf{u}^*} \newcommand{\CertifiedRadius}{R} \newcommand{\ChainRuleInput}{x} \newcommand{\ChainRuleIntermediate}{u} \newcommand{\ChainRuleOutput}{v} \newcommand{\ChainedOperationCount}{n_{\text{ops}}} \newcommand{\ChanceAnnotatorAgreement}{p_e} \newcommand{\ChannelAuthorityState}{S} \newcommand{\ChannelCommand}{u} \newcommand{\ChannelStoredEnergy}{E_{\text{channel}}} \newcommand{\CharacteristicPolynomial}{p} \newcommand{\CharacteristicPolynomialCoefficient}{c} \newcommand{\ChassisThermalResistance}{R_{\text{th,chassis}}} \newcommand{\CheapConfigurationAttemptCost}{c_{\text{small}}} \newcommand{\CheapConfigurationPassProbability}{p_{\text{small}}} \newcommand{\CheckIntervalStepCount}{m} \newcommand{\CheckPassProbability}{p^{\text{chk}}} \newcommand{\CheckSlotTime}{T} \newcommand{\CheckedSignal}{x} \newcommand{\CheckedSignalLimit}{L_{\text{limit}}} \newcommand{\CheckpointAttemptDuration}{T_{\text{att}}} \newcommand{\CheckpointExtraPauseTime}{T_{\text{pause}}} \newcommand{\CheckpointInterval}{T_{\text{ckpt}}} \newcommand{\CheckpointLoadTime}{T_{\text{load}}} \newcommand{\CheckpointLogPosition}{j_{\text{ckpt}}} \newcommand{\CheckpointOrdinalIndex}{m} \newcommand{\CheckpointOverheadFraction}{f_{\text{ckpt}}} \newcommand{\CheckpointOverheadRatio}{w} \newcommand{\CheckpointRecoveryOverheadTime}{T_{\text{overhead}}} \newcommand{\CheckpointRestoreTime}{T_{\text{restore}}} \newcommand{\CheckpointStride}{k} \newcommand{\CheckpointSuffixReadTime}{T_{\text{read}}} \newcommand{\CheckpointWasteFraction}{W} \newcommand{\CheckpointWriteTime}{T_{\text{write}}} \newcommand{\ChildBatchSize}{n_{\text{batch}}} \newcommand{\ChildBudgetAllocation}{C_{\max,C}} \newcommand{\ChildCapabilityGrant}{\Gamma_{\text{child}}} \newcommand{\ChildFreeBalance}{F_{C}} \newcommand{\ChildPruningProbability}{p_{\text{prune}}} \newcommand{\ChildReservedFunds}{R_{C}} \newcommand{\ChildSettledCharges}{E_{C}} \newcommand{\ChinchillaIrreducibleLoss}{E} \newcommand{\ChirpDuration}{T_c} \newcommand{\ChirpSlope}{S} \newcommand{\ChopperClampVoltage}{V_{\text{clamp}}} \newcommand{\ChopperTurnOffVoltage}{V_{\text{clamp,off}}} \newcommand{\ChopperTurnOnVoltage}{V_{\text{clamp,on}}} \newcommand{\ChunkActionDimension}{d_{\text{chunk}}} \newcommand{\ChunkEnsemblingWeight}{w} \newcommand{\ChunkExecutionHorizon}{H_{\text{exec}}} \newcommand{\ChunkImitationLoss}{\mathcal{L}_{\text{chunk}}} \newcommand{\ChunkLease}{T_{\text{lease}}} \newcommand{\ChunkReactionLatency}{T_{\text{reaction}}} \newcommand{\ChunkRenewalPeriod}{T_{\text{chunk}}} \newcommand{\ChunkRenewalRate}{f_{\text{replan}}} \newcommand{\ChunkStepIndex}{i} \newcommand{\ClampedControlCommand}{\mathbf{u}_{\text{clip}}} \newcommand{\ClassCount}{K} \newcommand{\ClassIndex}{j} \newcommand{\ClassKFunction}{\kappa} \newcommand{\ClassKFunctionSet}{\mathcal{K}} \newcommand{\ClassProbabilityVector}{\mathbf{p}} \newcommand{\ClassificationThreshold}{\gamma_{\text{cls}}} \newcommand{\CleanLabelSampleCount}{D_{\text{clean}}} \newcommand{\CleanTrainingDataset}{\mathcal{S}} \newcommand{\CleanupGraphEdgeSet}{E} \newcommand{\CleanupGraphVertexSet}{V} \newcommand{\ClearDistance}{D_{\text{clear}}} \newcommand{\ClearanceAcceleration}{\ddot{D}_{\text{clear}}} \newcommand{\ClearanceAllowance}{C} \newcommand{\ClearanceExhaustionTime}{t_{\text{impact}}} \newcommand{\ClearanceInset}{C_{\text{inset}}} \newcommand{\ClearanceQueryTime}{t_{\text{query}}} \newcommand{\ClearanceRate}{\dot{D}_{\text{clear}}} \newcommand{\ClearanceSpeedClamp}{v_{\text{clamp}}} \newcommand{\ClearanceTimeBudget}{T_{\text{total}}} \newcommand{\ClfClassKFunction}{\alpha_V} \newcommand{\ClfDescentControlSet}{\mathcal{U}_{\text{CLF}}} \newcommand{\ClientIndex}{k} \newcommand{\ClientLocalDataset}{\mathcal{D}} \newcommand{\ClientLocalTrainingEnergy}{E_{\text{client}}} \newcommand{\ClientObjectiveWeight}{w} \newcommand{\ClientSampleCount}{n} \newcommand{\ClientUpdateUploadEnergy}{E_{\text{upload}}} \newcommand{\ClippedSurrogateObjective}{\mathcal{M}} \newcommand{\ClippingRangeLowerBound}{\alpha} \newcommand{\ClippingRangeUpperBound}{\beta} \newcommand{\ClockConversionBound}{\epsilon_{\text{sync}}} \newcommand{\ClockConversionIntercept}{b_{\text{clk}}} \newcommand{\ClockConversionSlope}{a} \newcommand{\ClockFrequency}{f} \newcommand{\ClockOffset}{\theta_{\text{offset}}} \newcommand{\ClockPeriod}{T_{\text{clk}}} \newcommand{\ClockSynchronizationSkew}{\delta_{\text{skew}}} \newcommand{\ClosedLoopTrajectoryDensity}{p_{\text{cl}}} \newcommand{\ClosingSpeedBound}{v_{\text{close}}} \newcommand{\CloudInferenceEnergy}{E_{\text{cloud}}} \newcommand{\CloudOffloadEnergy}{E_{\text{transmit}}} \newcommand{\CloudTrainingRunEnergy}{E_{\text{cloud,train}}} \newcommand{\ClusterCount}{k} \newcommand{\ClusterHeadroom}{N} \newcommand{\ClusterNodeCount}{N_{\text{nodes}}} \newcommand{\ClusterPower}{P_{\text{cluster}}} \newcommand{\CoarseCellCount}{C} \newcommand{\CodecDecodeTime}{T_{\text{decode}}} \newcommand{\CodecEncodeTime}{T_{\text{encode}}} \newcommand{\CodecOverheadTime}{T_{\text{overhead}}} \newcommand{\CognitivePolicyAction}{\mathbf{a}} \newcommand{\CoherencyCoefficient}{\kappa_{\text{coh}}} \newcommand{\ColdCopperLossPower}{P_0} \newcommand{\ColdResetCycleTime}{T_{\text{cycle,cold}}} \newcommand{\CollaborativeContactForce}{F_{\text{contact}}} \newcommand{\CollectedPhotocharge}{Q} \newcommand{\CollectionCohortCost}{C_{\text{cohort}}} \newcommand{\CollectionStateVisitationDistribution}{p^{\pi_{\text{col}}}} \newcommand{\CollectiveCallStartupLatency}{\alpha_{\text{eff}}} \newcommand{\CollectivePayloadSize}{M} \newcommand{\CollectiveTensorSize}{M_{\text{coll}}} \newcommand{\CollisionHullCount}{N_{\text{hulls}}} \newcommand{\CollocationDefect}{\Delta} \newcommand{\ColumnAccessLatency}{t_{\text{CL}}} \newcommand{\ColumnModeComponentVector}{\mathbf{b}_s} \newcommand{\ColumnModeFactorMatrix}{\mathbf{B}} \newcommand{\ColumnModeFactorSlice}{\mathbf{b}} \newcommand{\ColumnParallelWeightMatrix}{\mathbf{A}} \newcommand{\CombinedBatch}{B_{\text{total}}} \newcommand{\CombinedPlanValidationAllowance}{t_{\text{validate}}} \newcommand{\CommandComponentCount}{N_c} \newcommand{\CommandRateCeiling}{r} \newcommand{\CommandTransportTime}{T_{\text{bus}}} \newcommand{\CommandedActuatorEffort}{u_{\text{cmd}}} \newcommand{\CommandedApproachAcceleration}{a_{\text{cmd}}} \newcommand{\CommandedJointConfiguration}{\mathbf{q}_{\text{cmd}}} \newcommand{\CommandedJointCount}{N_j} \newcommand{\CommandedJointTorque}{\tau} \newcommand{\CommandedJointTorqueSlew}{\dot{\tau}} \newcommand{\CommandedTrackedPosition}{r_{\text{cmd}}} \newcommand{\CommandedTractiveForce}{F_{\text{cmd}}} \newcommand{\CommitBatchRecordCount}{N_{\text{batch}}} \newcommand{\CommitmentInstant}{t_{\text{commit}}} \newcommand{\CommitmentPathPosition}{q_{c}} \newcommand{\CommonPositionShift}{\Delta} \newcommand{\CommunicationComputeRatio}{\rho} \newcommand{\CommunicationIntensity}{\text{CI}} \newcommand{\CommunicationSlowdownFactor}{r} \newcommand{\CommunicationTime}{T_{\text{comm}}} \newcommand{\CommunicationTimeFraction}{f} \newcommand{\CompactedContextLength}{S_{\text{comp}}} \newcommand{\CompactionBoundaryCount}{k} \newcommand{\CompactionBoundaryIndex}{i} \newcommand{\CompactionCycleTurnCount}{n_{\text{cycle}}} \newcommand{\CompactionCycleTurnIndex}{i} \newcommand{\CompactionLossProbability}{\rho} \newcommand{\CompactionPassCost}{C_{\text{comp}}} \newcommand{\CompactionPathCost}{C_{\text{compact}}} \newcommand{\CompactionPaybackCallCount}{N_{\min}} \newcommand{\CompactionPerCallSaving}{s} \newcommand{\CompactionTargetLength}{S_{\text{low}}} \newcommand{\CompactionTriggerLength}{S_{\text{high}}} \newcommand{\CompactionUpfrontCost}{U} \newcommand{\ComparedPeriodAccuracy}{a} \newcommand{\ComparisonArmTrialCount}{n_{\text{arm}}} \newcommand{\ComparisonContext}{c} \newcommand{\ComparisonSampleEmpiricalCdf}{G_{m}} \newcommand{\ComparisonSampleSize}{m} \newcommand{\ComparisonTrajectory}{z} \newcommand{\ComparisonTrajectoryDerivative}{\dot{z}} \newcommand{\CompensatedEnvironmentState}{\sigma_0'} \newcommand{\CompensationPostcondition}{\phi} \newcommand{\CompensationPostconditionSet}{\Phi} \newcommand{\CompetingKeyCount}{n} \newcommand{\CompetingKeyLogit}{z} \newcommand{\CompilationBreakevenCount}{N_{\text{breakeven}}} \newcommand{\CompilationTime}{T_{\text{compile}}} \newcommand{\CompiledExecutionTime}{T_{\text{compiled}}} \newcommand{\CompilerBackendCount}{N_{\text{backend}}} \newcommand{\CompilerFrontendCount}{M} \newcommand{\ComplementarityNormalForce}{\lambda_n} \newcommand{\CompletedRequestCount}{N} \newcommand{\CompletedRoundIndex}{r} \newcommand{\CompletionCriteria}{\mathcal{K}_{\text{comp}}} \newcommand{\CompletionDeadline}{T_{\text{deadline}}} \newcommand{\CompletionOffset}{c} \newcommand{\CompliantElementPreload}{F_{\text{preload}}} \newcommand{\CompliantElementStiffness}{k_{\text{spring}}} \newcommand{\ComponentAvailability}{A_{\text{component}}} \newcommand{\ComponentFailureRate}{\lambda} \newcommand{\ComponentHazardRate}{h} \newcommand{\ComponentMttf}{\text{MTTF}_{\text{component}}} \newcommand{\ComponentReliability}{R_{\text{single}}} \newcommand{\ComposedChainTransform}{\mathbf{T}_{AC}} \newcommand{\ComposedFunctionInput}{x} \newcommand{\ComposedFunctionOutput}{y} \newcommand{\ComposedMechanismCount}{k} \newcommand{\CompoundScalingCoefficient}{\phi} \newcommand{\CompressedCommunicationTime}{T_{\text{compressed}}} \newcommand{\CompressedGradientUpdate}{\mathbf{v}} \newcommand{\CompressedGradientUpdateElement}{v} \newcommand{\CompressedOnlyCorrectCount}{n_{\text{comp}}} \newcommand{\CompressionRatio}{r_{\text{comp}}} \newcommand{\ComputationalGraph}{G} \newcommand{\ComputeBudgetConstraint}{g} \newcommand{\ComputeChipPower}{P_{\text{chip}}} \newcommand{\ComputeConstrainedLagrangian}{\mathcal{L}_{\text{Lagrange}}} \newcommand{\ComputeConstraintMultiplier}{\lambda} \newcommand{\ComputeDemandVolume}{Q} \newcommand{\ComputeLimitedSampleRate}{R_{\text{compute}}} \newcommand{\ComputeOptimalTokenCount}{D_{\text{opt}}} \newcommand{\ComputeUnitCost}{P} \newcommand{\ConcordantTaskCount}{n} \newcommand{\ConcurrentTrajectories}{N_{\text{traj}}} \newcommand{\ConditionalDamageProbability}{p} \newcommand{\ConditionalDistribution}{p(y \mid x)} \newcommand{\ConditionalFlowMap}{\psi} \newcommand{\ConditionalVelocityField}{v} \newcommand{\ConditioningTokenPrefix}{x} \newcommand{\ConductorCurrent}{I} \newcommand{\ConeLimitStepSize}{\tau} \newcommand{\ConfidenceCalibrationDataset}{\mathcal{D}_{\text{cal}}} \newcommand{\ConfidenceCriticalQuantile}{z_{\alpha/2}} \newcommand{\ConfidenceLevel}{C} \newcommand{\ConfidentialityLabel}{\kappa} \newcommand{\ConfigurationSpace}{\mathcal{C}} \newcommand{\ConfirmationHitCount}{M} \newcommand{\ConfirmationWindowCount}{N_{\text{conf}}} \newcommand{\ConfluentVandermondeMatrix}{\mathbf{M}} \newcommand{\ConformalMiscoverageRate}{\epsilon} \newcommand{\ConformalPredictionSet}{\mathcal{C}} \newcommand{\ConformalQuantileRank}{k_{\epsilon}} \newcommand{\ConformalScoreQuantile}{\widehat{q}_{1-\epsilon}} \newcommand{\ConservativePenaltyWeight}{\alpha_{\text{CQL}}} \newcommand{\ConservativeSamplingDistribution}{\mu} \newcommand{\ConsoleCommunicationTime}{T_{\text{comm}}} \newcommand{\ConsolidationOverheadTime}{T_{\text{overhead}}} \newcommand{\ConsolidationStride}{c} \newcommand{\ConstantDivisorGrpoObjective}{\widehat{\mathcal{J}}_{\text{const}}} \newcommand{\ConstantHazardRate}{\lambda} \newcommand{\ConstrainedCallLatency}{T_{\text{constrained}}} \newcommand{\ConstrainedDecodingAutomaton}{\mathcal{D}} \newcommand{\ConstrainedParameterVector}{\mathbf{w}} \newcommand{\ConstrainedTestEnvelope}{\mathcal{S}} \newcommand{\ConstraintLagrangeMultiplier}{\lambda} \newcommand{\ConstraintRetentionFraction}{\eta_{\mathcal{C}}} \newcommand{\ContactApproachSpeed}{v_{\text{approach}}} \newcommand{\ContactCount}{N_c} \newcommand{\ContactDeformationDuration}{\Delta t_{\text{def}}} \newcommand{\ContactDirectionSpeed}{v_c} \newcommand{\ContactDirectionVelocity}{\dot{x}} \newcommand{\ContactDriftAcceleration}{a_{\text{drift}}} \newcommand{\ContactForce}{F_{\text{contact}}} \newcommand{\ContactForceBarrierFunction}{h_{\text{force}}} \newcommand{\ContactForceCap}{F_{\text{cap}}} \newcommand{\ContactForceCeiling}{F_{\max}} \newcommand{\ContactForceLimit}{F_{\text{limit}}} \newcommand{\ContactForceMagnitude}{F} \newcommand{\ContactForceRegularizationWeight}{w_f} \newcommand{\ContactForceRiseTime}{t_{\text{rise}}} \newcommand{\ContactGapAcceleration}{\ddot{\phi}} \newcommand{\ContactGapFunction}{\phi} \newcommand{\ContactGapVelocity}{\dot{\phi}} \newcommand{\ContactImpulse}{I} \newcommand{\ContactJacobianBaseBlock}{\mathbf{J}_{k,b}} \newcommand{\ContactJacobianJointBlock}{\mathbf{J}_{k,j}} \newcommand{\ContactLoopResponseTime}{T_c} \newcommand{\ContactNaturalTimescale}{T_{\text{contact}}} \newcommand{\ContactNormal}{\hat{\mathbf{n}}} \newcommand{\ContactNormalDeflection}{x} \newcommand{\ContactNormalJacobian}{\mathbf{J}_n} \newcommand{\ContactNormalJacobianDerivative}{\dot{\mathbf{J}}_n} \newcommand{\ContactNormalPosition}{x} \newcommand{\ContactNormalVelocity}{v_n} \newcommand{\ContactPatchRegion}{\mathcal{A}} \newcommand{\ContactPointForce}{\mathbf{f}} \newcommand{\ContactPointIndex}{i} \newcommand{\ContactPointJacobian}{\mathbf{J}_{\text{c}}} \newcommand{\ContactPointJacobianDerivative}{\dot{\mathbf{J}}_{\text{c}}} \newcommand{\ContactPointOffset}{\mathbf{r}} \newcommand{\ContactPointPosition}{x} \newcommand{\ContactPointTorque}{\boldsymbol{\tau}} \newcommand{\ContactReactionForce}{F} \newcommand{\ContactResponseLatency}{t_{\text{resp}}} \newcommand{\ContactStiffness}{k_{\text{contact}}} \newcommand{\ContactTorqueCeiling}{\tau_{\max}} \newcommand{\ContactTripwireForce}{F_{\text{trip}}} \newcommand{\ContactWrench}{\mathbf{w}} \newcommand{\ContactWrenchCeiling}{\mathbf{w}_{\max}} \newcommand{\ContactWrenchEnvelope}{\mathbf{w}_{\text{contact}}} \newcommand{\ContactWrenchTransform}{\mathbf{X}_k^*} \newcommand{\ContactYieldDeadline}{t_{\text{yield}}} \newcommand{\ContainerInnerRadius}{R} \newcommand{\ContainmentForceCeiling}{F_{\max}} \newcommand{\ContendingApplicationCount}{N} \newcommand{\ContentionCoefficient}{\sigma_{\text{cont}}} \newcommand{\ContextChunkTokenCount}{n} \newcommand{\ContextHiddenRepresentation}{\mathbf{h}_{\text{context}}} \newcommand{\ContextParallelDegree}{c} \newcommand{\ContextParallelRankIndex}{i} \newcommand{\ContextSaveTime}{t_{\text{context\_save}}} \newcommand{\ContextWindow}{S_{\max}} \newcommand{\ContinuationCount}{K} \newcommand{\ContinuationIndex}{i} \newcommand{\ContinuationReturnStandardDeviation}{\sigma} \newcommand{\ContinuityCorrectedCrossProduct}{A} \newcommand{\ContinuousActionComponent}{a} \newcommand{\ContinuousActionSpace}{\mathcal{A}} \newcommand{\ContinuousActionVector}{\mathbf{a}} \newcommand{\ContinuousCurrent}{I_{\text{cont}}} \newcommand{\ContinuousFactorialFunction}{\Gamma} \newcommand{\ContinuousMeasurementNoiseIntensity}{\mathbf{R}_{\text{cont}}} \newcommand{\ContinuousMotionModel}{\mathbf{f}} \newcommand{\ContinuousOutcome}{\mathbf{x}} \newcommand{\ContinuousRandomVariable}{\mathbf{X}} \newcommand{\ContinuousStateTransitionMatrix}{\boldsymbol{\Phi}} \newcommand{\ContinuousTorque}{\tau_{\text{cont}}} \newcommand{\ContractedBarrierFunction}{h_{\text{contracted}}} \newcommand{\ControlAffineDriftField}{\mathbf{f}} \newcommand{\ControlAffineInputField}{\mathbf{g}} \newcommand{\ControlCommand}{\mathbf{u}} \newcommand{\ControlCommandSpace}{\mathcal{U}} \newcommand{\ControlConversionRate}{\hat{p}_A} \newcommand{\ControlCycleIndex}{i} \newcommand{\ControlInput}{\mathbf{u}} \newcommand{\ControlInputDimension}{m} \newcommand{\ControlInputLowerLimit}{\mathbf{u}_{\min}} \newcommand{\ControlInputSet}{\mathcal{U}} \newcommand{\ControlInputUpperLimit}{\mathbf{u}_{\max}} \newcommand{\ControlInputWindow}{\mathbf{u}_{[t, t+\Delta t]}} \newcommand{\ControlSampleIndex}{k} \newcommand{\ControlSampleSize}{m_A} \newcommand{\ControlSetpointPeriod}{\Delta t_{\text{ctrl}}} \newcommand{\ControlStepIndex}{t} \newcommand{\ControlTaskIndex}{i} \newcommand{\ControllabilityMatrix}{\mathbf{C}_{\text{ctrb}}} \newcommand{\ControlledStopCommand}{\mathbf{u}_{\text{stop}}} \newcommand{\ControllerReactionDelay}{T_{\text{react}}} \newcommand{\ConversationTurnIndex}{i} \newcommand{\ConverterLockoutVoltage}{V_{\text{uvlo}}} \newcommand{\ConveyorSpeed}{v_{\text{conv}}} \newcommand{\ConveyorSpeedBound}{v_{\text{conv}}} \newcommand{\ConvolutionActivation}{H} \newcommand{\ConvolutionTimeInstant}{t'} \newcommand{\CookedTokenKeyVector}{\mathbf{k}_{\text{cooked}}} \newcommand{\CookedTokenQueryVector}{\mathbf{q}_{\text{cooked}}} \newcommand{\CoolantHeatLoad}{P_{\text{thermal}}} \newcommand{\CoolantMassFlowRate}{\dot{m}} \newcommand{\CoolantTemperature}{T} \newcommand{\CoolingEnergy}{E_{\text{cooling}}} \newcommand{\CoordinateFrameEmbedding}{\mathbf{e}_{\text{frame}}} \newcommand{\CoordinationLatency}{L_{\text{lat,coordination}}} \newcommand{\CoordinationOverhead}{h} \newcommand{\CopperIronThermalResistance}{R_{\text{th,cu-iron}}} \newcommand{\CopperReferenceTemperature}{T_0} \newcommand{\CopperTemperatureCoefficient}{\alpha_{\text{Cu}}} \newcommand{\CopperThermalCapacitance}{C_{\text{cu}}} \newcommand{\CopperThermalTimeConstant}{\tau_{\text{th,cu}}} \newcommand{\CoreAmbientThermalResistance}{R_{\text{th,ca}}} \newcommand{\CoreRailVoltageDroop}{\Delta V_{\text{droop}}} \newcommand{\CoreThermalCapacitance}{C_{\text{core}}} \newcommand{\CoresetBudget}{K} \newcommand{\CoriolisCentrifugalMatrix}{\mathbf{C}} \newcommand{\CorrectCandidateTrialPassProbability}{p_{g}} \newcommand{\CorrectClassIndex}{c} \newcommand{\CorrectClassLogit}{z_{c}} \newcommand{\CorrectClassProbability}{\hat{y}_{c}} \newcommand{\CorrectnessReward}{R_{\text{corr}}} \newcommand{\CorrelationCoefficient}{\rho} \newcommand{\CorruptedAttentionScoreMatrix}{\mathbf{S}_{\text{corrupt}}} \newcommand{\CorruptedModelWeight}{w'} \newcommand{\CostAnomalyScore}{Z} \newcommand{\CostBudgetUsedFraction}{\rho_C} \newcommand{\CostCeiling}{C_{\max}} \newcommand{\CostPerAcceptedTask}{C_{\text{eff}}} \newcommand{\CostPerEmittedArtifact}{C_{\text{emit}}} \newcommand{\CostToGo}{C} \newcommand{\CoulombFrictionCoefficient}{\mu} \newcommand{\CoulombFrictionForce}{F_{\text{friction}}} \newcommand{\CountedFailureIndicator}{e} \newcommand{\CovariateDriftBound}{\mathcal{O}(S^2 \epsilon)} \newcommand{\CoverageFactor}{k} \newcommand{\CpuEnergy}{E_{\text{CPU}}} \newcommand{\CredibleBrakingDeceleration}{a_{\text{brake}}} \newcommand{\CreditWindowCapacity}{N_{\text{win}}} \newcommand{\CriticActionReturnEstimate}{Q_{\phi}} \newcommand{\CriticApproximationError}{\epsilon} \newcommand{\CriticModel}{M_{\text{value}}} \newcommand{\CriticParameters}{\phi} \newcommand{\CriticReturnEstimate}{V_{\phi}} \newcommand{\CriticalBatchSize}{B^{*}} \newcommand{\CriticalConstraint}{c} \newcommand{\CriticalPathDuration}{T_{\text{crit}}} \newcommand{\CriticalSectionIndex}{s} \newcommand{\CriticalSectionWcet}{C^{\text{cs}}} \newcommand{\CriticalTrackingErrorBound}{\epsilon_{\text{crit}}} \newcommand{\CriticalTransitDistance}{d_{\text{crit}}} \newcommand{\CrossEntropyLevelThreshold}{\gamma} \newcommand{\CrossEntropyLoss}{\mathcal{L}_{\text{CE}}} \newcommand{\CrossoverFrequency}{\omega_c} \newcommand{\CruiseSpeed}{v_{c}} \newcommand{\CumulativeArrivals}{A} \newcommand{\CumulativeCompletions}{C} \newcommand{\CumulativeIncidentCount}{N} \newcommand{\CumulativeLogLikelihoodRatio}{\Lambda} \newcommand{\CumulativeScheduleStepIndex}{s} \newcommand{\CumulativeTransmittance}{T} \newcommand{\CumulativeWorkCost}{C} \newcommand{\CurrentBinProportion}{A} \newcommand{\CurrentDistribution}{P_t} \newcommand{\CurrentFeatureMean}{\mu_{\text{curr}}} \newcommand{\CurrentFeatureStandardDeviation}{\sigma_{\text{curr}}} \newcommand{\CurrentLayerWidth}{n_{\ell}} \newcommand{\CurrentModelParameters}{\theta_{\text{old}}} \newcommand{\CurrentMonotonicTime}{t_{\text{now,mono}}} \newcommand{\CurrentNodeIndex}{j} \newcommand{\CurrentPeriodCost}{C_{\text{current}}} \newcommand{\CurrentStateDigest}{h_{\text{state},t}} \newcommand{\CurrentStateEstimate}{\hat{\mathbf{x}}_{t_{\text{current}}}} \newcommand{\CurrentTime}{t_{\text{now}}} \newcommand{\CurrentWallClockTime}{t_{\text{current}}} \newcommand{\CutCrossingDataVolume}{V_{\text{cut}}} \newcommand{\CvaeEncoderParameters}{\phi} \newcommand{\CvaeRecognitionEncoder}{q_\phi} \newcommand{\CycleAveragePowerCeiling}{\bar{P}_{\max}} \newcommand{\CycleGuardTime}{t_{\text{guard}}} \newcommand{\CylinderForce}{F_{\text{cyl}}} \newcommand{\DailyAccountQueryCount}{q_{\text{daily}}} \newcommand{\DailyQueryVolume}{Q_{\text{day}}} \newcommand{\DamageEventCount}{N_{\text{damage}}} \newcommand{\DamageProbabilityTolerance}{\epsilon} \newcommand{\DamageProbabilityUpperBound}{p_U} \newcommand{\DamagingOutcomeIndicator}{Y} \newcommand{\DampedLeastSquaresPseudoinverse}{\mathbf{J}_{\lambda}^\dagger} \newcommand{\DampedStepConfiguration}{\mathbf{q}_\lambda} \newcommand{\DampingRatio}{\zeta} \newcommand{\DataAcquisitionCost}{C_{\text{acquire}}} \newcommand{\DataDebtGrowthRate}{r} \newcommand{\DataEgressCost}{C_{\text{egress}}} \newcommand{\DataFieldBitCount}{B_{\text{data},i}} \newcommand{\DataInformationContent}{\mathcal{I}} \newcommand{\DataLabelingCost}{C_{\text{label}}} \newcommand{\DataLoaderWorkerCount}{W} \newcommand{\DataMovementEnergyFraction}{q} \newcommand{\DataParallelDegree}{N_{\text{DP}}} \newcommand{\DataPhaseBitRate}{R_{\text{data}}} \newcommand{\DataPipelineProcessingCost}{C_{\text{process}}} \newcommand{\DataProcessingCost}{C_{\text{process}}} \newcommand{\DataScaleCoefficient}{B} \newcommand{\DataScalingExponent}{\beta} \newcommand{\DataScalingLossFactor}{D^{-\beta}} \newcommand{\DataStallFraction}{f_{\text{stall}}} \newcommand{\DataStorageCost}{C_{\text{store}}} \newcommand{\DataSupplyRate}{R_{\text{data}}} \newcommand{\DataTaxonomyAxis}{\mathsf{Data}} \newcommand{\DataVolume}{D_{\text{vol}}} \newcommand{\DatasetQuery}{f} \newcommand{\DatasetQueryResult}{v} \newcommand{\DatasetShardCount}{K_{\text{shards}}} \newcommand{\DatasetSize}{D} \newcommand{\DatasetTransferTime}{T} \newcommand{\DcBusBulkCapacitance}{C_{\text{bus}}} \newcommand{\DcBusOvervoltageThreshold}{V_{\text{max\_safe}}} \newcommand{\DcBusVoltage}{V_{\text{bus}}} \newcommand{\DcRailVoltage}{V_{\text{rail}}} \newcommand{\DeadTimeCycleCount}{N_{\text{dtg}}} \newcommand{\DeadTimeDqVoltageError}{\Delta V_{d,q}} \newcommand{\DeadTimeSafetyMargin}{t_{\text{margin}}} \newcommand{\DeadTimeTickPeriod}{T_{\text{dtg}}} \newcommand{\DeadTimeVoltageError}{\Delta V_{\text{phase}}} \newcommand{\DeadlineInstant}{t_{\text{deadline}}} \newcommand{\DebiasingTotalLoss}{\mathcal{L}_{\text{total}}} \newcommand{\DebounceFrameCount}{N} \newcommand{\DecisionProcessState}{s} \newcommand{\DecisionScore}{s_{\text{dec}}} \newcommand{\DecisionStepIndex}{k} \newcommand{\DecodeArithmeticIntensity}{I_{\text{decode}}} \newcommand{\DecodeBatchSize}{B_{\text{dec}}} \newcommand{\DecodeInterval}{T_{\text{decode}}} \newcommand{\DecodeRequestSet}{\mathcal{D}} \newcommand{\DecodeTokenTimeFloor}{T_{\text{token}}} \newcommand{\DecoderEvaluationCount}{N_{\text{eval}}} \newcommand{\DecoderPassTime}{t_{\text{pass}}} \newcommand{\DecodingConstraintState}{q} \newcommand{\DecomposedTensor}{\mathcal{Y}} \newcommand{\DecomposedTensorEntry}{y_{ijt}} \newcommand{\DecouplingCapacitance}{C} \newcommand{\DecouplingDriftVector}{\mathbf{b}} \newcommand{\DecouplingMatrix}{\mathbf{E}} \newcommand{\DecouplingMatrixElement}{E} \newcommand{\DedicatedHourlyFixedCost}{C_{\text{fixed}}} \newcommand{\DedicatedVariableTokenCost}{c_{\text{ded}}} \newcommand{\DefectiveActionProbability}{p_{\text{bad}}} \newcommand{\DefinitionSerializedSize}{S} \newcommand{\DeflectionComplianceAllowance}{\delta_{\text{deflect}}} \newcommand{\DegradedFrictionCoefficient}{\mu_{\text{fault}}} \newcommand{\DegradedStepTime}{T_{\text{slow}}} \newcommand{\DelassusOperator}{\mathbf{A}_{\text{Delassus}}} \newcommand{\DelayPhaseLag}{\Delta \phi} \newcommand{\DelayTravelDistance}{d_{\text{delay}}} \newcommand{\DelayWindowIntegrationTime}{\sigma} \newcommand{\DelayedObservation}{\mathbf{y}_{t_0}} \newcommand{\DelegatedAllocationAmount}{b} \newcommand{\DelegationTokenMultiple}{r} \newcommand{\DeliveredActuatorTorque}{\tau_{\text{act}}} \newcommand{\DeliveredCapacityFraction}{u} \newcommand{\DemandCap}{x_{\max}} \newcommand{\DemandPriceElasticity}{\epsilon_{\text{elast}}} \newcommand{\DemandThreshold}{x} \newcommand{\DemonstratedTargetA}{\mathbf{y}_A} \newcommand{\DemonstratedTargetB}{\mathbf{y}_B} \newcommand{\DemonstrationActionDistribution}{p} \newcommand{\DemonstrationActionLabel}{\mathbf{a}} \newcommand{\DemonstrationArchiveActionDistribution}{p_{\text{demo}}} \newcommand{\DemonstrationChunkDistribution}{p_{\text{data}}} \newcommand{\DemonstrationDataset}{\mathcal{D}_{\text{demo}}} \newcommand{\DemonstrationRetentionRate}{R} \newcommand{\DemonstratorAction}{\mathbf{a}^{*}} \newcommand{\DemonstratorActionComponent}{a} \newcommand{\DenseEvaluationEnergy}{E_{\text{eval}}} \newcommand{\DenseEvaluationRate}{f_{\text{eval}}} \newcommand{\DenseVoxelGridMemory}{M_{\text{dense}}} \newcommand{\DepartmentQuotaLimit}{Q_{\text{department}}} \newcommand{\DependencyGraphEdgeSet}{E} \newcommand{\DependencyGraphVertex}{v} \newcommand{\DependencyGraphVertexSet}{V} \newcommand{\DepletedBusVoltage}{V_{\text{low}}} \newcommand{\DeploymentAge}{t} \newcommand{\DeploymentDistribution}{p_{\text{deploy}}} \newcommand{\DeploymentDuration}{T_{\text{deployment}}} \newcommand{\DepthBinCount}{D} \newcommand{\DepthBinDistribution}{\boldsymbol{\alpha}_{u, v}} \newcommand{\DepthBinIndex}{k} \newcommand{\DepthBinLogits}{\mathbf{d}_{u, v}} \newcommand{\DepthBinProbability}{\alpha_{u, v}} \newcommand{\DepthCalibrationScale}{s} \newcommand{\DepthCalibrationShift}{t} \newcommand{\DepthCriticalPathLatency}{T^{\text{depth}}} \newcommand{\DepthFrameRate}{f_{\text{cam}}} \newcommand{\DepthHypothesis}{d} \newcommand{\DepthModeComponentVector}{\mathbf{c}_s} \newcommand{\DepthModeFactorMatrix}{\mathbf{C}} \newcommand{\DepthModeFactorSlice}{\mathbf{c}} \newcommand{\DepthRayCount}{N_{\text{rays}}} \newcommand{\DepthScalingRatio}{\alpha} \newcommand{\DepthStandardDeviation}{\sigma_z} \newcommand{\DerivativeControlEffort}{\mathbf{u}_{d}} \newcommand{\DerivativeFilterTimeConstant}{T_{f}} \newcommand{\DerivativeGainMatrix}{\mathbf{K}_{d}} \newcommand{\DerivativeOperator}{d} \newcommand{\DerivativeSplineControlPoint}{\mathbf{v}} \newcommand{\DerivedMemoryEntry}{c} \newcommand{\DerivedRecord}{y} \newcommand{\DesignLatencyQuantile}{Q_{1-\epsilon}} \newcommand{\DesiredContactPosition}{x_{\text{des}}} \newcommand{\DesiredContactVelocity}{\dot{x}_{\text{des}}} \newcommand{\DesiredTaskAcceleration}{\ddot{\mathbf{x}}_d} \newcommand{\DesiredTaskPosition}{\mathbf{x}_d} \newcommand{\DesiredTaskSpaceAcceleration}{\ddot{\mathbf{x}}^{\text{des}}} \newcommand{\DesiredTaskVelocity}{\dot{\mathbf{x}}_d} \newcommand{\DestinationRankIndex}{j} \newcommand{\DetectionCount}{n_{\text{det}}} \newcommand{\DetectionInterval}{t_{\text{detect}}} \newcommand{\DetectionMeasurementNoiseCovariance}{\boldsymbol{\Sigma}_{\text{meas},j}} \newcommand{\DetectionRangeShortfall}{\Delta d_{\text{detect}}} \newcommand{\DetectionTimestamp}{t_{\text{det}}} \newcommand{\DetectorMissProbability}{p_{\text{miss}}} \newcommand{\DeterministicPolicy}{\mu_{\theta}} \newcommand{\DevelopmentIterationCount}{N_{\text{dev}}} \newcommand{\DeviationDisadvantage}{u} \newcommand{\DeviceCount}{N} \newcommand{\DeviceEnergy}{E_{\text{device}}} \newcommand{\DeviceHardwareTime}{T_{\text{hw}}} \newcommand{\DeviceMemoryCapacity}{M_{\text{device}}} \newcommand{\DevicePower}{P_{\text{device}}} \newcommand{\DeviceRequestCapacity}{Q_{\text{req,max}}} \newcommand{\DeviceSilentCorruptionProbability}{p} \newcommand{\DiagnosticCoverage}{C_{\text{diag}}} \newcommand{\DictionaryCoefficientMatrix}{\mathbf{C}} \newcommand{\DifferentiabilityClass}{C} \newcommand{\DifferentialEntropy}{h} \newcommand{\DiffusionCumulativeSchedule}{\bar{\alpha}} \newcommand{\DiffusionGaussianNoise}{\boldsymbol{\epsilon}} \newcommand{\DiffusionMatchingLoss}{\mathcal{L}_{\text{diff}}} \newcommand{\DiffusionNoiseVariance}{\beta} \newcommand{\DiffusionStepCount}{N} \newcommand{\DiffusionStepIndex}{k} \newcommand{\DiffusionStepRetention}{\alpha} \newcommand{\DiffusionTimeCoordinate}{t_{\text{diff}}} \newcommand{\DirectAxisCurrent}{i_d} \newcommand{\DirectAxisInductance}{L_d} \newcommand{\DirectAxisVoltage}{v_d} \newcommand{\DirectionalCosineMatrix}{\mathbf{R}} \newcommand{\DirectionalDerivativeStep}{\epsilon} \newcommand{\DisadvantagedGroupClassificationThreshold}{\gamma_{\text{cls},g=\text{B}}} \newcommand{\DiscordantPairCount}{n_{\text{disc}}} \newcommand{\DiscordantPairFraction}{\psi} \newcommand{\DiscountFactor}{\gamma} \newcommand{\DiscountedReturn}{G} \newcommand{\DiscountedReturnStepOffset}{j} \newcommand{\DiscountedStateVisitationDistribution}{d} \newcommand{\DiscreteLqrFeedbackGain}{\mathbf{K}_{\text{lqr},d}} \newcommand{\DiscreteLqrQuadraticObjective}{J_d} \newcommand{\DiscreteOutcome}{x} \newcommand{\DiscretePlantDynamics}{f} \newcommand{\DiscreteRandomVariable}{X} \newcommand{\DiscreteSampleIndex}{k} \newcommand{\DiscreteStateSpaceInputMatrix}{\mathbf{B}_{d}} \newcommand{\DiscreteStateSpaceSystemMatrix}{\mathbf{A}_{d}} \newcommand{\DiscretizationBinCount}{n_{\text{bin}}} \newcommand{\DisengagedTakeoverResponseTime}{T_{\Sigma,2}} \newcommand{\DiskBandwidth}{\text{BW}_{\text{disk}}} \newcommand{\DisparityStandardDeviation}{\sigma_d} \newcommand{\DispatchAdmissionCeiling}{\Delta_{\text{da,max}}} \newcommand{\DispatchAdmissionInterval}{\Delta_{\text{da}}} \newcommand{\DispatchObservationAge}{t_{\text{age}}} \newcommand{\DispatchedOperationCount}{N_{\text{ops}}} \newcommand{\DisplayPipelineLatency}{t_{\text{disp}}} \newcommand{\DispreferredReferenceRelativeScore}{\Delta_l} \newcommand{\DispreferredTrajectory}{\tau_l} \newcommand{\DistanceEstimateStandardDeviation}{\sigma} \newcommand{\DistanceMeasurement}{z} \newcommand{\DistanceNormOrder}{p} \newcommand{\DistanceQueryPoint}{\mathbf{y}} \newcommand{\DistillationClassProbability}{p^{(T_{\text{distill}})}} \newcommand{\DistillationLoss}{\mathcal{L}_{\text{distill}}} \newcommand{\DistillationLossWeight}{\gamma_{\text{KD}}} \newcommand{\DistillationTemperature}{T_{\text{distill}}} \newcommand{\DistortedImageAbscissa}{x_d} \newcommand{\DistortedImageOrdinate}{y_d} \newcommand{\DistributedStepTime}{T_{\text{step}}} \newcommand{\DisturbanceAccelerationBound}{a_{\text{dist}}} \newcommand{\DisturbanceBasisCoefficient}{\psi} \newcommand{\DisturbanceBasisCount}{K} \newcommand{\DisturbanceBasisFunction}{B} \newcommand{\DisturbanceBudget}{\Delta_{w}} \newcommand{\DisturbanceDimension}{p} \newcommand{\DisturbanceForceBound}{d_{\max}} \newcommand{\DisturbanceParameterSet}{\Psi} \newcommand{\DisturbanceParameterVector}{\boldsymbol{\psi}} \newcommand{\DisturbanceTrajectory}{w_{\text{dist}}} \newcommand{\DivergenceInstant}{t_{\text{div}}} \newcommand{\DivergenceMeasure}{\mathcal{D}} \newcommand{\DivergenceTolerance}{\delta_{\text{tol}}} \newcommand{\DmaQueueTime}{t_{\text{DMA}}} \newcommand{\DocumentPayloadFraction}{q} \newcommand{\DomainRandomizationDistribution}{\mathcal{D}_{\text{DR}}} \newcommand{\DomainRandomizationObjective}{J_{\text{DR}}} \newcommand{\DominantComponentEnergy}{E_{\text{dominant}}} \newcommand{\DominantShare}{d} \newcommand{\DoorOpenReward}{r_{\text{open}}} \newcommand{\DoubleIntegratorPosition}{p} \newcommand{\DoubleIntegratorPositionDerivative}{\dot{p}} \newcommand{\DoubleIntegratorVelocity}{v} \newcommand{\DoubleIntegratorVelocityDerivative}{\dot{v}} \newcommand{\DoubleTreeAllReduceTime}{T_{\text{double-tree}}} \newcommand{\DownstreamStageLatency}{Y} \newcommand{\DpoLoss}{\mathcal{L}_{\text{DPO}}} \newcommand{\DraftAcceptanceRate}{\alpha} \newcommand{\DraftCandidateToken}{\tilde{x}} \newcommand{\DraftModelDistribution}{q_{\phi}} \newcommand{\DraftPositionAcceptanceProbability}{\alpha_{\text{spec}, j}} \newcommand{\DraftSamplingDistribution}{q} \newcommand{\DraftTokenAcceptanceProbability}{\alpha_{\text{acc}}} \newcommand{\DraftTokenCostRatio}{\beta} \newcommand{\DraftTokenCount}{\gamma} \newcommand{\DraftedToken}{T} \newcommand{\DragonflyGlobalChannelCount}{h} \newcommand{\DragonflyGroupRouterCount}{a} \newcommand{\DragonflyTerminalPortCount}{p} \newcommand{\DrainSourceVoltage}{V_{\text{ds}}} \newcommand{\DriftElapsedTime}{t_{\text{drift}}} \newcommand{\DriftImpactTime}{t_{\text{impact}}} \newcommand{\DriftLieDerivativeOperator}{L_{\mathbf{f}}} \newcommand{\DriftSpeedBound}{v_{\text{drift}}} \newcommand{\DriftTestSampleSize}{n} \newcommand{\DriftVelocityBound}{v_{\text{drift}}} \newcommand{\DriveBrakingForceCeiling}{F} \newcommand{\DriveBrakingTorqueCeiling}{\tau} \newcommand{\DrivenWheelLoadFraction}{\phi_{\text{drive}}} \newcommand{\DriverInterruptLatency}{t_{\text{driver\_irq}}} \newcommand{\DrivetrainAntiresonanceFrequency}{f_{\text{anti}}} \newcommand{\DrivetrainResonanceFrequency}{f_{\text{res}}} \newcommand{\DroopedSupplyVoltage}{V_{\text{droop}}} \newcommand{\DropletDiameter}{d_{\text{droplet}}} \newcommand{\DropoutProbability}{p_{\text{drop}}} \newcommand{\DualNumberInfinitesimal}{\epsilon} \newcommand{\DuplicateEffectProbability}{p_{\text{dup}}} \newcommand{\DurableAcknowledgmentTime}{t_{\text{ack}}} \newcommand{\DurableStoreWriteBandwidth}{\text{BW}_{\text{store}}} \newcommand{\DutyCyclePeriod}{T_{\text{period}}} \newcommand{\DynamicPower}{P_{\text{dynamic}}} \newcommand{\DynamicReachableSet}{\mathcal{R}} \newcommand{\DynamicsRealityGap}{\Delta_{\text{dyn}}} \newcommand{\EagerExecutionTime}{T_{\text{eager}}} \newcommand{\EarlierBaseFlangeTransform}{\mathbf{T}_{\text{base}, k}^{\text{flange}}} \newcommand{\EarlierCameraTargetTransform}{\mathbf{T}_{\text{cam}, k}^{\text{target}}} \newcommand{\EarlierControlStepIndex}{t'} \newcommand{\EarlierWorkerCount}{k} \newcommand{\EarliestConflictTime}{t_{\text{conflict}}} \newcommand{\EarthReferenceFrame}{\mathcal{F}_{\text{earth}}} \newcommand{\EchoFactor}{e} \newcommand{\EchoRoundTripTime}{t_{\text{rt}}} \newcommand{\EditGrantRights}{\mathcal{R}_{\Gamma_{\text{edit}}}} \newcommand{\EditPhaseCapabilityGrant}{\Gamma_{\text{edit}}} \newcommand{\EffectiveAdmissionCeiling}{Q_{\text{effective}}} \newcommand{\EffectiveApiOutputTokenPrice}{c_{\text{API}}} \newcommand{\EffectiveBrakingDelay}{T_{\text{eff}}} \newcommand{\EffectiveBranchingFactor}{b_{\text{eff}}} \newcommand{\EffectiveConfidentialityLabel}{\kappa_{\text{eff}}} \newcommand{\EffectiveFleetThroughput}{R_{\text{eff}}} \newcommand{\EffectiveImpactMass}{m_{\text{eff}}} \newcommand{\EffectiveIntegrityProvenance}{\iota_{\text{eff}}} \newcommand{\EffectiveJointInertia}{J_{\text{eff}}} \newcommand{\EffectiveLossResistance}{R_{\text{eff}}} \newcommand{\EffectiveSampleSize}{N_{\text{eff}}} \newcommand{\EffectiveSeriesStiffness}{k_{\text{eff}}} \newcommand{\EffectiveServiceRate}{\mu_{\text{eff}}} \newcommand{\EffectiveSpotTrainingCost}{C_{\text{effective}}} \newcommand{\EffectiveStorageThroughput}{R_{\text{storage,eff}}} \newcommand{\EffectiveWasteFraction}{W_{\text{effective}}} \newcommand{\EfficiencyHw}{\eta_{\text{hw}}} \newcommand{\EgressArrivalRate}{\lambda_{\text{arr}}} \newcommand{\EgressBufferCapacity}{Q_{\text{max}}} \newcommand{\EgressPortUtilization}{\rho_{\text{egress}}} \newcommand{\EgressPrice}{R_{\text{egress/GB}}} \newcommand{\EgressQueueOccupancy}{Q} \newcommand{\EgressServiceRate}{\mu} \newcommand{\ElapsedPlanningPeriods}{n} \newcommand{\ElasticJointTorque}{\mathbf{z}} \newcommand{\ElasticMaximumWorkerCount}{N_{\text{max}}} \newcommand{\ElasticMinimumWorkerCount}{N_{\text{min}}} \newcommand{\ElasticModalFrequencyMatrix}{\boldsymbol{\Omega}} \newcommand{\ElasticPotentialEnergy}{E} \newcommand{\ElasticStrainEnergy}{U_{\text{elastic}}} \newcommand{\ElasticTorqueSecondDerivative}{\ddot{\mathbf{z}}} \newcommand{\ElbowSwivelAngle}{\psi} \newcommand{\ElectricalAngularSpeed}{\omega_e} \newcommand{\ElectricalResistance}{R} \newcommand{\ElectricalRotorAngle}{\theta_e} \newcommand{\ElectricalTimeConstant}{\tau_e} \newcommand{\ElectricityPrice}{R_{\$/\text{kWh}}} \newcommand{\ElementStorageSize}{s_{\text{elem}}} \newcommand{\ElementaryCharge}{q} \newcommand{\ElementaryOperationCount}{W} \newcommand{\ElevationAngle}{\phi} \newcommand{\EligibleCachedPrefixLength}{S_{\text{hit}}} \newcommand{\EligibleTargetPositionSet}{\mathcal{P}_{\text{elig}}} \newcommand{\EligibleVectorCount}{N} \newcommand{\EliteSampleFraction}{\beta} \newcommand{\EmbeddingDimension}{d} \newcommand{\EmbeddingShardCount}{N_{\text{shards}}} \newcommand{\EmergencyStopContact}{S} \newcommand{\EmergencyStopCount}{n_{\text{estop}}} \newcommand{\EmittedArtifactCount}{N_{\text{emit}}} \newcommand{\EmittedTokenCount}{S_{\text{out}}} \newcommand{\EmpiricalBellmanOperator}{\mathcal{B}} \newcommand{\EmpiricalExceedanceFraction}{\hat{\zeta}_{u}} \newcommand{\EmpiricalTimestepAverage}{\hat{\mathbb{E}}} \newcommand{\EmpiricalTransferDiscrepancy}{\hat{\epsilon}_{\text{gap}}} \newcommand{\EmptyByteString}{\epsilon} \newcommand{\EncodedLatentState}{\hat{\mathbf{z}}} \newcommand{\EncoderAngle}{\theta_{\text{enc}}} \newcommand{\EncoderBitCount}{n} \newcommand{\EncoderLatentRepresentation}{\mathbf{z}} \newcommand{\EncoderVelocityEstimate}{\dot{\theta}_{\text{enc}}} \newcommand{\EncoderVelocityNoise}{\sigma_{\dot{\theta}_{\text{enc}}}} \newcommand{\EndEffectorCameraTransform}{\mathbf{T}_{EC}} \newcommand{\EndEffectorFirstAxisPosition}{x} \newcommand{\EndEffectorPitchAngle}{\phi_{\text{pitch}}} \newcommand{\EndEffectorPose}{\mathbf{T}_{WE}} \newcommand{\EndEffectorRollAngle}{\phi_{\text{roll}}} \newcommand{\EndEffectorSecondAxisPosition}{y} \newcommand{\EndEffectorTaskAcceleration}{\ddot{\mathbf{x}}} \newcommand{\EndEffectorTaskPosition}{\mathbf{x}} \newcommand{\EndEffectorTaskVelocity}{\dot{\mathbf{x}}} \newcommand{\EndEffectorThirdAxisPosition}{z} \newcommand{\EndEffectorTwist}{\mathbf{V}_E} \newcommand{\EndEffectorVelocity}{\mathbf{v}_e} \newcommand{\EndEffectorYawAngle}{\phi_{\text{yaw}}} \newcommand{\EndToEndRequestLatency}{L_{\text{lat,total}}} \newcommand{\EnergyCrossoverIntensity}{I_{\text{crossover}}} \newcommand{\EnergyLimitedContactForce}{F_E} \newcommand{\EnergyPerByteMoved}{E_{\text{move}}} \newcommand{\EnergyPerOperation}{E_{\text{compute}}} \newcommand{\EnergyTankBarrierFunction}{h_{\text{energy}}} \newcommand{\EnergyTankLevel}{E_{\text{tank}}} \newcommand{\EnergyTankPower}{\dot{E}_{\text{tank}}} \newcommand{\EnergyTankReserve}{E_{\text{min}}} \newcommand{\EnforcedCommandLabel}{\mathbf{a}_{\text{enf}, t}} \newcommand{\EnforcedCommandTap}{a_{\text{enf}}} \newcommand{\EnforcerComputeTime}{T_{\text{comp}}} \newcommand{\EnforcerDeadline}{T_{\text{deadline,enf}}} \newcommand{\EngineerHourlyCost}{C_{\text{engineer}}} \newcommand{\EngineeringTemperatureCeiling}{T_{\text{ceil}}} \newcommand{\EnsembleSpreadThreshold}{\sigma_{\text{thresh}}} \newcommand{\EnsemblingDecayRate}{m} \newcommand{\EnsemblingWindowLength}{K} \newcommand{\EntityCount}{N_{\text{entities}}} \newcommand{\EntityEmbedding}{\mathbf{e}} \newcommand{\EntropyTemperature}{\alpha} \newcommand{\EnvelopeCallCount}{N} \newcommand{\EnvelopeSetupTime}{T_{\text{setup}}} \newcommand{\EnvironmentCycleTime}{T_{\text{cycle}}} \newcommand{\EnvironmentFixture}{f} \newcommand{\EnvironmentLatentDimension}{d_z} \newcommand{\EnvironmentLatentVector}{\mathbf{z}} \newcommand{\EnvironmentParameters}{e} \newcommand{\EnvironmentResetTime}{T_{r}} \newcommand{\EnvironmentResponseFunction}{g} \newcommand{\EnvironmentRolloutStepCount}{h} \newcommand{\EnvironmentTransitionDistribution}{p} \newcommand{\EpipolarLine}{\mathbf{l}} \newcommand{\EpochCount}{N_{\text{epochs}}} \newcommand{\EpochIndex}{n_{\text{epoch}}} \newcommand{\EquilibriumWindingTemperature}{T_\infty} \newcommand{\EquivalentSeriesStiffness}{k_{\text{eq}}} \newcommand{\ErasureDataFragmentCount}{d} \newcommand{\ErasureParityFragmentCount}{m} \newcommand{\ErroneousPredictionCost}{C_{\text{error}}} \newcommand{\ErrorBudgetConsumption}{B} \newcommand{\ErrorCovarianceDerivative}{\dot{\mathbf{P}}} \newcommand{\ErrorFeedbackResidual}{\mathbf{e}} \newcommand{\ErrorFeedbackResidualElement}{e} \newcommand{\ErrorGrowthRate}{r} \newcommand{\ErrorRecoveryCost}{C_{\text{recovery}}} \newcommand{\EscalationDecision}{d} \newcommand{\EscalationLossMatrix}{\mathbf{L}} \newcommand{\EscalationThresholdProbability}{p_{\text{threshold}}} \newcommand{\EssentialMatrix}{\mathbf{E}} \newcommand{\EstimateEpoch}{t_{\text{est}}} \newcommand{\EstimatedAcceptanceProbability}{\hat{p}} \newcommand{\EstimatedAccuracy}{\hat{p}} \newcommand{\EstimatedCandidateUtility}{\hat{U}} \newcommand{\EstimatedCleanActionChunk}{\hat{\mathbf{A}}} \newcommand{\EstimatedCoriolisMatrix}{\hat{\mathbf{C}}} \newcommand{\EstimatedDamageProbability}{\hat{p}} \newcommand{\EstimatedDivergenceInstant}{\hat{t}_{\text{div}}} \newcommand{\EstimatedForceSensorBias}{\hat{b}} \newcommand{\EstimatedGravitationalTorque}{\hat{\mathbf{g}}} \newcommand{\EstimatedGripContactForce}{\hat{x}} \newcommand{\EstimatedHistoryAdvantage}{\hat{A}} \newcommand{\EstimatedInertiaMatrix}{\hat{\mathbf{M}}} \newcommand{\EstimatedPairedAcceptanceDifference}{\hat{\Delta}} \newcommand{\EstimatedPlantState}{\hat{\mathbf{x}}} \newcommand{\EstimatedPosition}{\hat{\mathbf{p}}} \newcommand{\EstimatedRemainingReturn}{\hat{V}} \newcommand{\EstimatedUtilityStandardDeviation}{s} \newcommand{\EstimatedVelocity}{\hat{\mathbf{v}}} \newcommand{\EstimatedWindingTemperature}{\hat{T}_{\text{wind}}} \newcommand{\EstimationErrorCovariance}{\mathbf{P}} \newcommand{\EstimatorDrawCount}{N} \newcommand{\EstimatorDrawStandardDeviation}{\sigma} \newcommand{\EstimatorState}{\mathbf{x}} \newcommand{\EstimatorStateVector}{\mathbf{x}} \newcommand{\EstimatorStepIndex}{k} \newcommand{\EulerIntegralFirstShape}{a} \newcommand{\EulerIntegralSecondShape}{b} \newcommand{\EulerIntegralVariable}{t} \newcommand{\EvaluatedExceedance}{y} \newcommand{\EvaluationPredicate}{\phi} \newcommand{\EvaluationSampleCount}{N} \newcommand{\EvaluationTrialCount}{N} \newcommand{\EvaluationTrialIndex}{i} \newcommand{\EventContrastThreshold}{C_{\text{th}}} \newcommand{\EventDetectionPower}{P_{\text{detect}}} \newcommand{\EventIndicator}{\mathbf{1}} \newcommand{\EventPacket}{e} \newcommand{\EventPolarity}{p} \newcommand{\EventProcessingEnergy}{E_{\text{event}}} \newcommand{\EvidenceCaptureInstant}{t_{\text{capture}}} \newcommand{\EvidenceEpoch}{t_0} \newcommand{\EvidenceHorizon}{\tau_{\text{ev}}} \newcommand{\EvidenceLowerBound}{\mathcal{L}_{\text{ELBO}}} \newcommand{\EvidenceRecordEvent}{e_{\text{obs}}} \newcommand{\ExactFailureLowerLimit}{p_{L}} \newcommand{\ExactFailureUpperLimit}{p_{U}} \newcommand{\ExampleAveragedBatchLoss}{\mathcal{L}_{\text{example}}} \newcommand{\ExampleIndex}{i} \newcommand{\ExampleLabel}{y} \newcommand{\ExceedanceReturnLevel}{z_\epsilon} \newcommand{\ExceedanceSampleSet}{\mathcal{Y}_u} \newcommand{\ExceedanceThreshold}{u} \newcommand{\ExcessDistributionFunction}{F_{u}} \newcommand{\ExcessForcePenaltyWeight}{\lambda_f} \newcommand{\ExcessSupportUpperEndpoint}{y_{\max}} \newcommand{\ExecutedActionStepCount}{T_a} \newcommand{\ExecutedToolCall}{a} \newcommand{\ExecutedTrialCount}{N_{\text{trial}}} \newcommand{\ExecutionHorizon}{H_{\text{exec}}} \newcommand{\ExecutionNondeterminism}{\xi} \newcommand{\ExecutionSwitchTime}{T_{\text{switch}}} \newcommand{\ExogenousDataDistribution}{\mathcal{D}} \newcommand{\ExpectedCategoryFrequency}{n_i^{\text{exp}}} \newcommand{\ExpectedCheckingTime}{T_{\text{check}}} \newcommand{\ExpectedCostLimit}{\delta} \newcommand{\ExpectedDecisionRisk}{\mathcal{R}} \newcommand{\ExpectedHistoryActionReturn}{Q} \newcommand{\ExpectedIrreversibleLoss}{L_A} \newcommand{\ExpectedNormalMaximum}{m_{N}} \newcommand{\ExpectedQueryDistribution}{p_{\text{expected}}} \newcommand{\ExpectedRemainingReturn}{V} \newcommand{\ExpectedReturnObjective}{J} \newcommand{\ExpectedRunCompletionTime}{T} \newcommand{\ExpectedTaskCostSum}{J} \newcommand{\ExperienceReplayBuffer}{\mathcal{D}} \newcommand{\ExperimentCount}{N_{\text{exp}}} \newcommand{\ExperimentUserIndex}{i} \newcommand{\ExpertCapacityFactor}{C_{\text{cap}}} \newcommand{\ExpertCount}{N_{\text{experts}}} \newcommand{\ExpertDiscountedStateVisitationDistribution}{d^{\pi^*}} \newcommand{\ExpertIndex}{e} \newcommand{\ExpertSelectionProbability}{p_e} \newcommand{\ExpertStateVisitationDistribution}{p^{\pi^*}} \newcommand{\ExpertTokenCount}{B_e} \newcommand{\ExploitCandidateFraction}{p_{\text{exp}}} \newcommand{\ExploitTrajectory}{\tau_{\text{hack}}} \newcommand{\ExploratoryStateVisitationDistribution}{p^{\pi_{\text{expl}}}} \newcommand{\ExponentBitIndex}{k} \newcommand{\ExponentialSeriesArgument}{u} \newcommand{\ExponentialStabilityConstant}{k} \newcommand{\ExposedCommunicationTime}{T_{\text{comm,exposed}}} \newcommand{\ExposedUnitCount}{E_{\text{exposure}}} \newcommand{\ExposureDuration}{t_{\text{exp}}} \newcommand{\ExposureMidpointTime}{t_{\text{mid}}} \newcommand{\ExposureMotionDisplacement}{\Delta x_{\text{motion}}} \newcommand{\ExposureStartTime}{t_{\text{start}}} \newcommand{\ExposureTravelDistance}{\Delta x} \newcommand{\ExtendedClassKInfinityFamily}{\mathcal{K}_\infty} \newcommand{\ExtendedDepthLength}{K_{\text{ext}}} \newcommand{\ExternalContactTorque}{\boldsymbol{\tau}_{\text{ext}}} \newcommand{\ExternalDispatchAction}{a_{\text{ext}}} \newcommand{\ExternalDisturbanceForce}{d} \newcommand{\ExternalDisturbanceLoad}{\mathbf{d}_{\text{ext}}} \newcommand{\ExternalJointTorque}{\tau_{\text{ext}}} \newcommand{\ExternalObjectWrench}{\mathbf{w}_{\text{ext}}} \newcommand{\ExternalWait}{T_{\text{wait}}} \newcommand{\ExternalWrench}{\mathbf{F}_{\text{ext}}} \newcommand{\ExtractionAnomalyClassifier}{f_{\theta}} \newcommand{\ExtractionQueryCount}{n_{\text{queries}}} \newcommand{\ExtrinsicCalibrationCovariance}{\boldsymbol{\Sigma}_{\text{ext}}} \newcommand{\ExtrinsicCovarianceJacobian}{\mathbf{J}_{\text{ext}}} \newcommand{\ExtrinsicLateralError}{\Delta y} \newcommand{\ExtrinsicMisalignmentAngle}{\theta_{\text{ext}}} \newcommand{\EyeInHandCameraMotion}{\mathbf{B}} \newcommand{\EyeInHandFlangeMotion}{\mathbf{A}} \newcommand{\EyeInHandUnknownTransform}{\mathbf{X}} \newcommand{\EyeToHandCameraPose}{\mathbf{B}'} \newcommand{\EyeToHandFlangePose}{\mathbf{A}'} \newcommand{\EyeToHandTargetTransform}{\mathbf{Z}} \newcommand{\EyeToHandUnknownTransform}{\mathbf{X}'} \newcommand{\FacilityEnergy}{E_{\text{facility}}} \newcommand{\FacilityHeatRemovalCapacity}{\dot{Q}_{\text{remove,max}}} \newcommand{\FacilityPower}{P_{\text{facility}}} \newcommand{\FacilityWaterConsumption}{W_{\text{water}}} \newcommand{\FactoredIntermediateActivation}{\mathbf{z}} \newcommand{\FactorizationRank}{k} \newcommand{\FailureDetectionTime}{T_{\text{detect}}} \newcommand{\FailureEventCost}{C_{\text{per-failure}}} \newcommand{\FailureFlagLatency}{\delta_{\text{flag}}} \newcommand{\FailureMarginFunction}{l} \newcommand{\FailureModeOccurrenceCount}{n_{f}} \newcommand{\FailureObservationInterval}{T} \newcommand{\FailureOverheadFraction}{F_{\text{fail}}} \newcommand{\FailureRecoveryTime}{T_{\text{recovery}}} \newcommand{\FailureRegion}{F} \newcommand{\FailureSet}{\mathcal{F}_{\text{fail}}} \newcommand{\FailureUpperConfidenceLimit}{p_{\text{fail, upper}}} \newcommand{\FairShareStabilizingConstant}{\epsilon_{\text{stab}}} \newcommand{\FairnessGapTolerance}{\epsilon_{\text{fair}}} \newcommand{\FakeQuantizedOutput}{x_{\text{fake}}} \newcommand{\FallbackCost}{C_{\text{fallback}}} \newcommand{\FallbackDeadline}{T_{\text{deadline,fallback}}} \newcommand{\FallbackHold}{T_{\text{hold}}} \newcommand{\FalseAcceptHarmCost}{C_{\text{harm}}} \newcommand{\FalseApprovalCount}{N_{\text{fa}}} \newcommand{\FalseApprovalOutcomeCount}{k} \newcommand{\FalseApprovalPropensity}{Q} \newcommand{\FalseApprovalPropensityLevel}{q} \newcommand{\FalseDiscoveryRateTarget}{q} \newcommand{\FalsificationInitialStateSet}{\mathcal{X}_0} \newcommand{\FanoutBackendCount}{m} \newcommand{\FarthestCandidateDistance}{D_{\max}} \newcommand{\FatTreeHostCount}{N_{\text{hosts}}} \newcommand{\FatigueLifeCycleCount}{N} \newcommand{\FaultContainmentLatency}{\Delta t_{\text{bounded}}} \newcommand{\FaultDetectionLatency}{\Delta t_{\text{det}}} \newcommand{\FaultDomainIsolation}{\mathcal{F}} \newcommand{\FaultInjectionDuration}{\Delta t_{\text{duration}}} \newcommand{\FaultStartTimestamp}{t_{\text{fault\_start}}} \newcommand{\FaultTakeoverLatency}{\Delta t_{\text{takeover}}} \newcommand{\FaultTakeoverTimestamp}{t_{\text{takeover}}} \newcommand{\FaultToleranceCost}{C_{\text{ft}}} \newcommand{\FaultToleranceInvestment}{x} \newcommand{\FeasibleOutputTokenRate}{\mu_{\text{out}}} \newcommand{\FeasibleTrajectoryProjection}{\Pi_{\mathcal{K}}} \newcommand{\FeasibleTrajectorySet}{\mathcal{K}} \newcommand{\FeatureCategoryCount}{k} \newcommand{\FeatureCategoryIndex}{i} \newcommand{\FeatureCellVector}{\mathbf{f}_{u, v}} \newcommand{\FeatureChannelCount}{C} \newcommand{\FeatureCount}{N_{\text{features}}} \newcommand{\FeatureFreshnessLatency}{T_{\text{freshness}}} \newcommand{\FeatureMapColumnCoordinate}{x} \newcommand{\FeatureMapGrowthRate}{g} \newcommand{\FeatureMapHeight}{H_{\text{img}}} \newcommand{\FeatureMapRowCoordinate}{y} \newcommand{\FeatureMapWidth}{W_{\text{img}}} \newcommand{\FeatureRecordTime}{t} \newcommand{\FeatureRetentionWindow}{T_{\text{retention}}} \newcommand{\FeatureUpdateInterval}{T_{\text{update}}} \newcommand{\FeatureUpdateLag}{T_{\text{staleness}}} \newcommand{\FeatureUpdateTimestamp}{t_{\text{feat}}} \newcommand{\FeatureViewingDistance}{r} \newcommand{\FederatedRoundCount}{R} \newcommand{\FederatedRoundIndex}{t} \newcommand{\FederatedTrainingEnergy}{E_{\text{federated}}} \newcommand{\FeedForwardOperations}{O_{\text{FFN}}} \newcommand{\FeedForwardWidth}{d_{\text{ff}}} \newcommand{\FeedbackCheckDuration}{t_{\text{check}}} \newcommand{\FeedbackCriticalPathLatency}{T^{\text{feedback}}} \newcommand{\FeedbackIntervalCount}{k} \newcommand{\FeedbackStepIndex}{t} \newcommand{\FeedforwardJointTorque}{\boldsymbol{\tau}_{\text{ff}}} \newcommand{\FeedthroughMatrix}{\mathbf{D}} \newcommand{\FewShotStepCount}{n_{\text{steps}}} \newcommand{\FewShotSupportSet}{\mathcal{D}_{\text{shot}}} \newcommand{\FiberPropagationSpeed}{c_{\text{fiber}}} \newcommand{\FieldbusCycleTime}{T_{\text{cycle}}} \newcommand{\FilmEncounterRate}{\lambda_{\text{film}}} \newcommand{\FilterSolveBudget}{T_{\text{budget}}} \newcommand{\FilterSolveTime}{T_{\text{solve}}} \newcommand{\FilterTapCount}{N} \newcommand{\FilterWeight}{w} \newcommand{\FilteredScreenSpaceCovariance}{\boldsymbol{\Sigma}_{2D}'} \newcommand{\FinalBusVoltage}{V_{\text{final}}} \newcommand{\FinalGeneratorLatentVector}{\mathbf{z}_{m}} \newcommand{\FinalLayerFunction}{f_{N_L}} \newcommand{\FinalLayerWidth}{n_{N_L}} \newcommand{\FinalMiniBatchActivation}{a_{B}} \newcommand{\FinalRecurrentHiddenState}{\mathbf{h}_{S}} \newcommand{\FinalWatchdogToken}{T_{\text{final}}} \newcommand{\FingerNormalForce}{f_n} \newcommand{\FingerTangentialForce}{\mathbf{f}_t} \newcommand{\FinishedWorkerCount}{j} \newcommand{\FiniteChange}{\Delta} \newcommand{\FiniteSampleGeneralizationBound}{\delta_N} \newcommand{\FiniteTimeHorizon}{T} \newcommand{\FirstAdjacentCheckIndex}{a} \newcommand{\FirstAdjacentCheckPassProbability}{p_{a}} \newcommand{\FirstAdjacentCheckSlotTime}{T_{a}} \newcommand{\FirstCatalogDefinitionCount}{n_{\text{def},A}} \newcommand{\FirstCatalogDefinitionSize}{S_{A}} \newcommand{\FirstClassCoverageFloor}{a} \newcommand{\FirstClientMaskedUpdate}{\mathbf{y}_A} \newcommand{\FirstClientModelParameters}{\theta_A} \newcommand{\FirstComparedGroupLabel}{a} \newcommand{\FirstComparedItem}{i} \newcommand{\FirstDiscardedSingularNumber}{\sigma_{r+1}} \newcommand{\FirstErrorStepIndex}{k} \newcommand{\FirstFloatingPointAddend}{a} \newcommand{\FirstGroupClassificationThreshold}{\tau_{\text{thr},a}} \newcommand{\FirstGroupQualifiedFraction}{q_a} \newcommand{\FirstGroupSampleApprovalRate}{\hat{p}_a} \newcommand{\FirstGroupSampleSize}{n_a} \newcommand{\FirstGroupThresholdClassifier}{h_a} \newcommand{\FirstIncidentTime}{t_1} \newcommand{\FirstInputNodePrimal}{v_{1-N}} \newcommand{\FirstJaccardSet}{\mathcal{A}} \newcommand{\FirstMistakeEvent}{\mathcal{E}} \newcommand{\FirstRankComputeTime}{T_{\text{rank}_0}} \newcommand{\FirstRaterCategoryFraction}{p_{y,1}} \newcommand{\FirstRingTraceElement}{a} \newcommand{\FirstSummandStandardDeviation}{\sigma_a} \newcommand{\FirstTwinCriticReturnEstimate}{Q_{\phi_1}} \newcommand{\FittedSensitivity}{\lambda} \newcommand{\FixedClearanceAllowance}{\delta} \newcommand{\FlangeCameraTransform}{\mathbf{T}_{\text{flange}}^{\text{cam}}} \newcommand{\FlangePose}{\mathbf{T}_{\text{flange}}} \newcommand{\FlangeReferenceFrame}{\mathcal{F}_{\text{flange}}} \newcommand{\FlangeTargetTransform}{\mathbf{T}_{\text{flange}}^{\text{target}}} \newcommand{\FlattenedFilterWeights}{\mathbf{w}_{\text{col}}} \newcommand{\FleetCommunicationTaxonomyAxis}{C_2} \newcommand{\FleetComputeTaxonomyAxis}{C_1} \newcommand{\FleetCoordinationTaxonomyAxis}{C_3} \newcommand{\FleetEnergyProductivity}{\rho_{\text{energy}}} \newcommand{\FleetManufacturingDistribution}{\mathcal{M}} \newcommand{\FleetResourceCapacity}{C_{r}} \newcommand{\FleetRobotCount}{N_{\text{fleet}}} \newcommand{\FlippedFloatExponentField}{e'} \newcommand{\FloatEncodedNumber}{x} \newcommand{\FloatExponentField}{e} \newcommand{\FloatMantissaField}{m} \newcommand{\FloatSignBit}{s} \newcommand{\FloatingBaseAccelerations}{\ddot{\mathbf{q}}_b} \newcommand{\FloatingBaseBiasForces}{\mathbf{h}_b} \newcommand{\FloatingBaseInertiaBlock}{\mathbf{M}_{bb}} \newcommand{\FloatingBasePose}{\mathbf{q}_b} \newcommand{\FlopPrice}{c_{\text{FLOP}}} \newcommand{\FlowMatchingLoss}{\mathcal{L}_{\text{FM}}} \newcommand{\FlowProbabilityPath}{\rho} \newcommand{\FlowSampleVector}{\mathbf{y}} \newcommand{\FlowTimeCoordinate}{t} \newcommand{\FocalLength}{f} \newcommand{\FollowerForwardWave}{\mathbf{u}_s} \newcommand{\FollowerJointPositions}{\mathbf{q}_{\text{follower}}} \newcommand{\FollowerMechanicalLatency}{t_{\text{mech}}} \newcommand{\FollowerReturnWave}{\mathbf{w}_s} \newcommand{\ForceGuidedRelay}{K} \newcommand{\ForceReadingInnovation}{\nu} \newcommand{\ForceSensorBias}{b} \newcommand{\ForceSensorReading}{y} \newcommand{\ForegroundLatency}{L_{\text{lat,fg}}} \newcommand{\ForgetDataset}{D_{\text{forget}}} \newcommand{\ForkBoundarySet}{\mathcal{B}_{\text{fork}}} \newcommand{\ForkedTrajectoryTokenCount}{N_{\text{total}}} \newcommand{\FormatComplianceScore}{\Phi} \newcommand{\FormatEfficiency}{\eta_{\text{format}}} \newcommand{\FormatRewardWeight}{\lambda_{\text{fmt}}} \newcommand{\ForwardDiffusionDistribution}{q} \newcommand{\ForwardEulerEigenvalue}{\lambda_{\text{FE}}} \newcommand{\ForwardEulerTransitionMatrix}{\mathbf{A}_{\text{FE}}} \newcommand{\ForwardInvariantSafeSet}{\mathcal{C}} \newcommand{\ForwardKinematicsMap}{\mathbf{FK}} \newcommand{\ForwardOccupancySet}{\mathcal{R}} \newcommand{\ForwardPassTokenCount}{n} \newcommand{\ForwardPosteriorMean}{\tilde{\boldsymbol{\mu}}} \newcommand{\ForwardPosteriorVariance}{\tilde{\beta}} \newcommand{\FourthRingTraceElement}{d} \newcommand{\FrameBitCount}{B_{\text{frame}}} \newcommand{\FrameBlockingTime}{B} \newcommand{\FrameExposureStartTime}{t_{\text{start}}} \newcommand{\FrameIndex}{i} \newcommand{\FramePayloadSize}{B_{\text{payload}}} \newcommand{\FramePeriod}{T} \newcommand{\FrameReadoutTime}{t_{\text{readout}}} \newcommand{\FrameReleaseJitter}{J} \newcommand{\FrameResponseTime}{R} \newcommand{\FrameSerializationTime}{t_{\text{frame},i}} \newcommand{\FrameTransmissionTime}{C} \newcommand{\FrameWireBitCount}{B_{\text{wire},i}} \newcommand{\FreeConfigurationSpace}{\mathcal{C}_{\text{free}}} \newcommand{\FreeCreditCount}{N_{\text{free}}} \newcommand{\FreeSpaceDepth}{d_{\text{free}}} \newcommand{\FreeSpaceLogOddsIncrement}{L_{\text{free}}} \newcommand{\FreeSurfaceTiltAngle}{\theta_{\text{tilt}}} \newcommand{\FreeboardHeight}{h_{f}} \newcommand{\FreshEvidenceTime}{t_{\text{fresh}}} \newcommand{\FreshInputTokenCount}{S_{\text{fresh}}} \newcommand{\FreshnessObjective}{S_{\text{freshness}}} \newcommand{\FrictionCoefficientFloor}{\mu_{\min}} \newcommand{\FrictionPyramidMatrix}{\mathbf{F}} \newcommand{\FrobeniusNorm}{F} \newcommand{\FrozenBackboneFunction}{f} \newcommand{\FrozenFeatureEncoder}{f} \newcommand{\FrustumFeature}{\mathbf{c}_{u, v, k}} \newcommand{\FullBatchLoss}{\mathcal{L}_B} \newcommand{\FullDatasetSize}{D_{\text{total}}} \newcommand{\FullPrecisionWeight}{w} \newcommand{\FullSnapshotWriteVolume}{D_{\text{vol,full}}} \newcommand{\FullSpeedTravelTime}{b} \newcommand{\FunctionInputAdjoint}{\bar{x}} \newcommand{\FunctionInputDimension}{N} \newcommand{\FunctionInputElement}{x} \newcommand{\FunctionInputTangent}{\dot{x}} \newcommand{\FunctionInputVariable}{x} \newcommand{\FunctionInputVector}{\mathbf{x}} \newcommand{\FunctionJacobian}{\mathbf{J}} \newcommand{\FunctionOutputDimension}{M} \newcommand{\FunctionOutputElement}{y} \newcommand{\FunctionOutputVariable}{z} \newcommand{\FunctionOutputVector}{\mathbf{y}} \newcommand{\FunctionSecondInputVariable}{y} \newcommand{\FundamentalMatrix}{\mathbf{F}} \newcommand{\FusedConvolutionBias}{\mathbf{b}_{\text{fused}}} \newcommand{\FusedConvolutionWeight}{\mathbf{W}_{\text{fused}}} \newcommand{\FusedTokenCount}{N_{\text{total}}} \newcommand{\FusionCandidate}{x_{\text{cand}}} \newcommand{\FusionInputList}{\mathcal{L}} \newcommand{\FusionInputRank}{r} \newcommand{\FutureControlTrajectory}{\mathbf{u}_{[t, \infty)}} \newcommand{\FutureTimeInstant}{t'} \newcommand{\GaeAdvantageEstimate}{\widehat{A}^{\text{GAE}}} \newcommand{\GateCurrent}{I_g} \newcommand{\GateDriverSkew}{t_{\text{prop, skew}}} \newcommand{\GatePropagationDelay}{t_{\text{prop}}} \newcommand{\GateSourceCapacitance}{C_{\text{gs}}} \newcommand{\GateSourceCharge}{Q_{\text{gs}}} \newcommand{\GateSourceVoltage}{V_{\text{gs}}} \newcommand{\GaussianCovarianceMatrix}{\boldsymbol{\Sigma}} \newcommand{\GaussianDistribution}{\mathcal{N}} \newcommand{\GaussianFirstAxisScale}{s_{x}} \newcommand{\GaussianMeanVector}{\boldsymbol{\mu}} \newcommand{\GaussianMechanismNoiseVector}{\mathbf{z}} \newcommand{\GaussianMechanismStandardDeviation}{\sigma_{\text{mech}}} \newcommand{\GaussianOpacityLogit}{o} \newcommand{\GaussianPrimitiveCovariance}{\boldsymbol{\Sigma}} \newcommand{\GaussianPrimitiveDensity}{G} \newcommand{\GaussianPrimitiveIndex}{i} \newcommand{\GaussianPrimitiveMean}{\boldsymbol{\mu}} \newcommand{\GaussianPrimitiveOpacity}{\alpha} \newcommand{\GaussianPrimitiveScaleMatrix}{\mathbf{S}} \newcommand{\GaussianSecondAxisScale}{s_{y}} \newcommand{\GaussianStandardDeviation}{\sigma} \newcommand{\GaussianThirdAxisScale}{s_{z}} \newcommand{\GaussianViewDependentColor}{c} \newcommand{\GearFaceWidth}{b} \newcommand{\GearModule}{m} \newcommand{\GearRatedFatigueLife}{L_{\text{gear}}} \newcommand{\GearReductionRatio}{N_{\text{gear}}} \newcommand{\GearTangentialLoad}{W_t} \newcommand{\GearToothBendingStress}{\sigma_b} \newcommand{\GearTorqueReversalCount}{n_{\text{gear}}} \newcommand{\GearboxTransmissionEfficiency}{\eta_{\text{gear}}} \newcommand{\GemmAccumulatorScale}{\beta} \newcommand{\GemmColumnDimension}{N} \newcommand{\GemmInnerDimension}{K} \newcommand{\GemmLeftOperand}{\mathbf{A}} \newcommand{\GemmLeftOperandElement}{A} \newcommand{\GemmLeftOperandEntry}{A_{ik}} \newcommand{\GemmOutputElement}{C} \newcommand{\GemmOutputEntry}{C_{ij}} \newcommand{\GemmOutputMatrix}{\mathbf{C}} \newcommand{\GemmProductScale}{\alpha} \newcommand{\GemmReductionIndex}{k} \newcommand{\GemmRightOperand}{\mathbf{B}} \newcommand{\GemmRightOperandElement}{B} \newcommand{\GemmRightOperandEntry}{B_{kj}} \newcommand{\GemmRowDimension}{M} \newcommand{\GemmTileColumnDimension}{N_{\text{tile}}} \newcommand{\GemmTileInnerDimension}{K_{\text{tile}}} \newcommand{\GemmTileRowDimension}{M_{\text{tile}}} \newcommand{\GemvArithmeticIntensity}{I_{\text{GEMV}}} \newcommand{\GeneralPurposeEnergyProductivity}{\rho_{\text{energy,general}}} \newcommand{\GeneralizedAccelerationLowerBound}{\ddot{\mathbf{q}}_{\min}} \newcommand{\GeneralizedAccelerationUpperBound}{\ddot{\mathbf{q}}_{\max}} \newcommand{\GeneralizedAccelerations}{\ddot{\mathbf{q}}} \newcommand{\GeneralizedBiasForces}{\mathbf{h}} \newcommand{\GeneralizedCoordinateCount}{n} \newcommand{\GeneralizedCoordinates}{\mathbf{q}} \newcommand{\GeneralizedInertiaMatrix}{\mathbf{M}} \newcommand{\GeneralizedParetoDistribution}{H} \newcommand{\GeneralizedParetoLikelihood}{L} \newcommand{\GeneralizedVelocities}{\dot{\mathbf{q}}} \newcommand{\GeneratedResponse}{y} \newcommand{\GeneratedSampleCount}{n} \newcommand{\GeneratedTokenCap}{N_{\text{cap}}} \newcommand{\GenerationStepErrorRate}{\lambda_{\text{error}}} \newcommand{\GenerativeActionModelDistribution}{p_\theta} \newcommand{\GeneratorLatentVector}{\mathbf{z}} \newcommand{\GenericRandomVariable}{X} \newcommand{\GeometricStateRepresentation}{\mathbf{Z}_{\text{geom}}} \newcommand{\GevLocationParameter}{\mu} \newcommand{\GevScaleParameter}{\sigma} \newcommand{\GlobalBatchGradient}{\mathbf{g}_{\text{global}}} \newcommand{\GlobalBatchSize}{B_{\text{global}}} \newcommand{\GlobalDeviationPenalty}{\mathcal{R}} \newcommand{\GlobalModelParameters}{\theta_{\text{global}}} \newcommand{\GoalConfiguration}{\mathbf{q}_{\text{goal}}} \newcommand{\GoalSet}{\mathcal{G}_{\text{goal}}} \newcommand{\GoodputRelativeTolerance}{\epsilon_{\mathcal{G}}} \newcommand{\GpdCumulativeDistribution}{F_{\text{GPD}}} \newcommand{\GpdScaleParameter}{\tilde{\sigma}} \newcommand{\GpuAvailability}{A_{\text{GPU}}} \newcommand{\GpuEnergy}{E_{\text{GPU}}} \newcommand{\GpuFailureRate}{\lambda_{\text{GPU}}} \newcommand{\GpuMttf}{\text{MTTF}_{\text{GPU}}} \newcommand{\GpuTopologicalDistance}{d} \newcommand{\GradientClippingNorm}{C} \newcommand{\GradientCovarianceMatrix}{\Sigma} \newcommand{\GradientElementCount}{d_{\text{grad}}} \newcommand{\GradientMemory}{M_{\text{gradients}}} \newcommand{\GradientPayload}{M_{\text{grad}}} \newcommand{\GradientStaleness}{\tau_{\text{stale}}} \newcommand{\GrantAllowedAccesses}{\mathcal{A}} \newcommand{\GrantCondition}{\phi_{\Gamma}} \newcommand{\GrantExpiryTime}{t_{\text{exp}}} \newcommand{\GrantIssueTime}{T} \newcommand{\GrantRights}{\mathcal{R}_{\Gamma}} \newcommand{\GraphEdgeSet}{E} \newcommand{\GraphNodeIndex}{i} \newcommand{\GraphNodeSet}{V} \newcommand{\GraspContactDisplacement}{\mathbf{d}} \newcommand{\GraspForceCeiling}{f_{\max}} \newcommand{\GraspForceFloor}{f_{\min}} \newcommand{\GraspMap}{\mathbf{G}} \newcommand{\GraspOrientation}{\mathbf{R}_{\text{grasp}}} \newcommand{\GraspPose}{\mathbf{T}_{\text{grasp}}} \newcommand{\GraspPosition}{\mathbf{p}_{\text{grasp}}} \newcommand{\GraspVerticalAcceleration}{a_z} \newcommand{\GravitationalTorqueVector}{\mathbf{g}} \newcommand{\Gravity}{g} \newcommand{\GravityCenterHeight}{h_{\text{cg}}} \newcommand{\GravityVector}{\mathbf{g}_0} \newcommand{\GridFeedCapacity}{P_{\text{grid}}} \newcommand{\GridSideCellCount}{N} \newcommand{\GripContactForce}{x} \newcommand{\GripperContactAngle}{\theta_{\text{contact}}} \newcommand{\GripperOpeningCommand}{a_{\text{gripper}}} \newcommand{\GroundPlaneAbscissa}{x} \newcommand{\GroundPlaneOrdinate}{y} \newcommand{\GroupCommitWaitTime}{L_{\text{lat}, i}} \newcommand{\GroupContrastProbability}{p_{\text{contrast}}} \newcommand{\GroupDisparity}{\Delta_g} \newcommand{\GroupMeanReward}{\mu_{R}} \newcommand{\GroupRelativeAdvantage}{\hat{A}} \newcommand{\GroupRewardStandardDeviation}{\sigma_{R}} \newcommand{\GroupRolloutIndex}{i} \newcommand{\GroupSize}{G} \newcommand{\GrpoSampledObjective}{\widehat{\mathcal{J}}_{\text{GRPO}}} \newcommand{\GuardBandDuration}{t_{\text{guard}}} \newcommand{\GuardedContactPredicate}{P_{\text{contact}}} \newcommand{\GuestImageMemory}{M_{\text{guest}}} \newcommand{\GuestKernelBootTime}{T_{\text{kernel}}} \newcommand{\HalfPrecisionGemvIntensity}{I_{\text{GEMV, 16-bit}}} \newcommand{\HammingDataBitCount}{n} \newcommand{\HandForceCriterion}{F_h} \newcommand{\HandleAffordanceFrame}{\mathcal{F}_{\text{handle}}} \newcommand{\HandoffExceedanceProbability}{\epsilon} \newcommand{\HandoverTimeout}{T_{\text{timeout}}} \newcommand{\HandoverTimeoutCeiling}{T_{\text{config}}} \newcommand{\HandshakeProtocolLatency}{T_{\text{handshake}}} \newcommand{\HardwareCommonCauseRate}{\lambda_{\text{other}}} \newcommand{\HardwareParameterVector}{\boldsymbol{\xi}_{\text{real}}} \newcommand{\HardwareServiceLife}{T_{\text{lifetime}}} \newcommand{\HarmInclusiveTaskCost}{C_{\text{with\ harm}}} \newcommand{\HarmInstant}{t_{\text{harm}}} \newcommand{\HarmLeadTime}{t_{\text{harm}}} \newcommand{\HarmonicDriveTorsionalStiffness}{k_c} \newcommand{\HarmonicPeriodMultiple}{m} \newcommand{\HarnessConnectorResistance}{R_{\text{harness}}} \newcommand{\HashBucketCount}{N_{\text{buckets}}} \newcommand{\HashEntrySize}{s_{\text{entry}}} \newcommand{\HashRingServer}{s} \newcommand{\HashRingServerCount}{N} \newcommand{\HashRingServerSet}{\mathcal{S}_{\text{srv}}} \newcommand{\HashedGridMemory}{M_{\text{hashed}}} \newcommand{\HazardClassIndex}{h} \newcommand{\HazardOnset}{t_{\text{onset}}} \newcommand{\HazardOnsetBound}{t_{\text{bound}}} \newcommand{\HazardousProposalRate}{\lambda_{\text{proposal}, h}} \newcommand{\HazardousWorldState}{s_B} \newcommand{\HeadAxisLabel}{h} \newcommand{\HeadByteAllocation}{M_{\text{head}}} \newcommand{\HeadComponentIndex}{m} \newcommand{\HeadDimensionAxisLabel}{d} \newcommand{\HeadKeyProjectionMatrix}{\mathbf{W}_{K,i}} \newcommand{\HeadQueryProjectionMatrix}{\mathbf{W}_{Q,i}} \newcommand{\HeadSamplingProbability}{\theta} \newcommand{\HeadValuesProjectionMatrix}{\mathbf{W}_{V,i}} \newcommand{\HeadingAngle}{\theta_{\text{head}}} \newcommand{\HeadingCurvature}{\kappa} \newcommand{\HealthyStepTime}{T_{\text{healthy}}} \newcommand{\HeartbeatAge}{\Delta t_{\text{heartbeat}}} \newcommand{\HeartbeatInterval}{H} \newcommand{\HeartbeatReceiptTime}{t_{\text{local}}} \newcommand{\HeartbeatSequenceCounter}{k} \newcommand{\HeartbeatTimestamp}{t^{\text{hb}}} \newcommand{\HeatDissipationPower}{P_{\text{heat}}} \newcommand{\HermiteBasisFunction}{h} \newcommand{\HermiteInterpolationFraction}{\lambda} \newcommand{\HermiteSegmentProgress}{s} \newcommand{\HertzianContactCoefficient}{k_{c}} \newcommand{\HertzianContactStiffness}{k_H} \newcommand{\HiddenActivation}{\mathbf{h}} \newcommand{\HiddenActivationMatrix}{\mathbf{H}} \newcommand{\HiddenDimension}{d} \newcommand{\HiddenUnitOutput}{h} \newcommand{\HighOccupancyBinCount}{m} \newcommand{\HigherPriorityFrames}{hp} \newcommand{\HigherPriorityTasks}{hp} \newcommand{\HighestSignalFrequency}{f_{\max}} \newcommand{\HnswLayerIndex}{L} \newcommand{\HnswLevelDraw}{U} \newcommand{\HnswLevelNormalization}{m_\ell} \newcommand{\HnswMaximumConnectionCount}{M} \newcommand{\HnswSearchBeamWidth}{ef_{\text{search}}} \newcommand{\HoldingTorque}{\tau_{\text{hold}}} \newcommand{\HomogeneousCameraFramePoint}{\tilde{\mathbf{p}}_C} \newcommand{\HomogeneousPixelCoordinates}{\tilde{\mathbf{m}}} \newcommand{\HomogeneousPointCoordinates}{\tilde{\mathbf{p}}} \newcommand{\HomogeneousTransform}{\mathbf{T}_{AB}} \newcommand{\HomogeneousWorldFramePoint}{\tilde{\mathbf{p}}_W} \newcommand{\HomographyColumn}{\mathbf{h}} \newcommand{\HomographyColumnEntry}{h} \newcommand{\HomographyConstraintVector}{\mathbf{v}} \newcommand{\HomographyScaleFactor}{\lambda} \newcommand{\HomomorphicCiphertext}{c} \newcommand{\HomomorphicFunction}{f} \newcommand{\HomomorphicPublicKey}{pk} \newcommand{\HomomorphicSecretKey}{sk} \newcommand{\HorizonStepIndex}{k} \newcommand{\HorizontalFocalLength}{f_x} \newcommand{\HostArrivalTimestamp}{t_{\text{host}}} \newcommand{\HostHeartbeatRate}{f_{\text{heartbeat}}} \newcommand{\HostLinkBandwidth}{\text{BW}_{\text{link}}} \newcommand{\HostPower}{P_{\text{host}}} \newcommand{\HostPreparationTime}{T_{\text{prep}}} \newcommand{\HostRuntimeCount}{N_{\text{host}}} \newcommand{\HostSoftwareTime}{T_{\text{sw}}} \newcommand{\HostTransferBandwidth}{\text{BW}_{\text{host}}} \newcommand{\HotTierHitProbability}{h} \newcommand{\HotTierServiceTime}{T_{\text{hot}}} \newcommand{\HourlyAccountQueryCount}{q_{\text{hourly}}} \newcommand{\HourlyComponentFailureRate}{\lambda_{\text{hour}}} \newcommand{\HuberLossThreshold}{\delta} \newcommand{\HullQueryTime}{t_{\text{query}}} \newcommand{\HullSphereRadius}{r_{\text{hull}}} \newcommand{\HumanCommandRate}{\dot{\mathbf{u}}_{\text{human}}} \newcommand{\HumanControlCommand}{\mathbf{u}_{\text{human}}} \newcommand{\HumanFallbackCost}{C_{h}} \newcommand{\HumanReactionTime}{T_{\text{human}}} \newcommand{\HumanResolutionProbability}{h} \newcommand{\HumanReviewCost}{C_{\text{human}}} \newcommand{\HumanStandaloneSensitivity}{S_{\text{human}}} \newcommand{\HumanWalkingSpeedBound}{v_h} \newcommand{\HybridIterationTime}{T_{\text{step}}} \newcommand{\HydraulicSupplyPressure}{p} \newcommand{\HypothesisIndex}{h} \newcommand{\HypothesisTestFalseNegativeRate}{\beta_{\text{stat}}} \newcommand{\HypothesisTestSignificanceLevel}{\alpha_{\text{sig}}} \newcommand{\HypothesizedAcceptanceProbability}{p} \newcommand{\HypothesizedTrialFailureProbability}{p} \newcommand{\IdealAcceleratorTime}{T_{\text{ideal}}} \newcommand{\IdealMemoryQueueDelay}{t_{\text{queue,ideal}}} \newcommand{\IdempotentAlgebraElement}{x} \newcommand{\IdentityMatrix}{\mathbf{I}} \newcommand{\IllustrativeFunction}{f} \newcommand{\ImageChannelCount}{C} \newcommand{\ImageChannelIndex}{c} \newcommand{\ImageColumnIndex}{w} \newcommand{\ImageEpipole}{\mathbf{e}} \newcommand{\ImageHeight}{H} \newcommand{\ImageRowIndex}{h} \newcommand{\ImageTensorElement}{X} \newcommand{\ImageWidth}{W} \newcommand{\ImaginaryUnit}{j} \newcommand{\ImitationLearnedPolicy}{\hat{\pi}} \newcommand{\ImitationTargetCommand}{\mathbf{u}_{\text{target}}} \newcommand{\ImmediateTaskCostScore}{C} \newcommand{\ImpactInstant}{T} \newcommand{\ImpactRiseTime}{t_{\text{rise}}} \newcommand{\ImpactSpeed}{v_{\text{impact}}} \newcommand{\ImpedanceControlledPosition}{x} \newcommand{\ImpedanceControlledVelocity}{\dot{x}} \newcommand{\ImpedanceEquilibriumPosition}{x_{\text{des}}} \newcommand{\ImpedanceEquilibriumVelocity}{\dot{x}_{\text{des}}} \newcommand{\ImpedanceRestoringForce}{F} \newcommand{\ImplicitPolicyEnergyFunction}{E_\theta} \newcommand{\ImportanceProposalDistribution}{q} \newcommand{\ImportanceSampledFailureProbability}{\hat{p}_F} \newcommand{\ImuSampleTime}{t_{\text{IMU}}} \newcommand{\InContactViableSet}{\mathcal{C}_{\text{contact}}} \newcommand{\IncidenceAngle}{\theta_{\text{inc}}} \newcommand{\IncidentOpticalPower}{P_{\text{opt}}} \newcommand{\IncomingChannelCommand}{u_{\text{new}}} \newcommand{\IncomingCommandDerivative}{\dot{u}_{\text{new}}} \newcommand{\IncorrectCandidateTrialPassProbability}{p_{b}} \newcommand{\IncrementalSnapshotWriteVolume}{D_{\text{vol,delta}}} \newcommand{\IncumbentControlCommand}{\mathbf{u}^{\text{incumbent}}} \newcommand{\IncumbentInterventionRate}{\lambda_{\text{incumbent}}} \newcommand{\IncumbentTrackingErrorStandardDeviation}{\sigma_{\text{incumbent}}} \newcommand{\IndependentAttemptCount}{k} \newcommand{\IndependentEventProbability}{p} \newcommand{\IndependentSampleRate}{f} \newcommand{\IndexGraphNodeSet}{V} \newcommand{\IndexedDocumentCount}{N} \newcommand{\IndicatorFunction}{\mathbb{I}} \newcommand{\InducedGateVoltage}{V_{\text{gs,induced}}} \newcommand{\InductiveVoltage}{v} \newcommand{\InequalityConstraintFunction}{g} \newcommand{\InertiaMatchingRatio}{N^*} \newcommand{\InertiaMatrixDerivative}{\dot{\mathbf{M}}} \newcommand{\InertialIntegrationTime}{T} \newcommand{\InferenceActiveTime}{t_{\text{inference}}} \newcommand{\InferenceCost}{C_{\text{infer}}} \newcommand{\InferenceDutyCycle}{\alpha_{\text{duty}}} \newcommand{\InferenceEnergy}{E_{\text{inf}}} \newcommand{\InferenceLatency}{L_{\text{lat,infer}}} \newcommand{\InferenceLoadSocPower}{P_{\text{load}}} \newcommand{\InflatedHullRadius}{r_{\text{inflated}}} \newcommand{\InflightRolloutReservation}{M_{\text{inflight}}} \newcommand{\InfluenceFunction}{I} \newcommand{\InformationTechnologyEnergy}{E_{\text{IT}}} \newcommand{\InformationTechnologyHeatLoad}{\dot{Q}_{\text{IT}}} \newcommand{\InformationTechnologyPower}{P_{\text{IT}}} \newcommand{\InformativeTaskFraction}{p_{\text{inform}}} \newcommand{\IngestionPricePerSample}{C_{\text{ingest/sample}}} \newcommand{\InitialAccuracy}{\text{Accuracy}_0} \newcommand{\InitialBusVoltage}{V_{\text{initial}}} \newcommand{\InitialPositionStandardDeviation}{\sigma_{p,0}} \newcommand{\InitialPositionVelocityCovariance}{\sigma_{pv,0}} \newcommand{\InitialProposalDistribution}{q_{\boldsymbol{\psi}_0}} \newcommand{\InitialStateDistribution}{\rho_0} \newcommand{\InitialTrackingError}{e_0} \newcommand{\InitialVelocityStandardDeviation}{\sigma_{v,0}} \newcommand{\InitiatedTasks}{N} \newcommand{\InjectionBandwidth}{\text{BW}_{\text{inject}}} \newcommand{\InjectionTriggerEpoch}{t_{\text{inject}}} \newcommand{\InnerChainTransform}{\mathbf{T}_{BC}} \newcommand{\InnerLayerFunction}{g} \newcommand{\InnerProductLeftComponent}{a} \newcommand{\InnerProductLeftVector}{\mathbf{a}} \newcommand{\InnerProductRightComponent}{v} \newcommand{\InnerProductRightVector}{\mathbf{b}} \newcommand{\InnovationBias}{b} \newcommand{\InnovationCovariance}{\mathbf{S}} \newcommand{\InnovationVariance}{S} \newcommand{\InputCaptureTime}{T_{\text{capture}}} \newcommand{\InputChannelCount}{C_{\text{in}}} \newcommand{\InputChannelIndex}{c} \newcommand{\InputColumnLieDerivativeOperator}{L_{\mathbf{g}_j}} \newcommand{\InputConsumerAcceleratorCount}{N_{\text{GPU}}} \newcommand{\InputCoordinateCount}{d} \newcommand{\InputDistribution}{p(x)} \newcommand{\InputEventRate}{r_{\text{event}}} \newcommand{\InputFeatureIndex}{i} \newcommand{\InputFeatureVector}{\mathbf{x}} \newcommand{\InputLieDerivativeOperator}{L_{\mathbf{g}}} \newcommand{\InputNodePrimal}{v_{i-N}} \newcommand{\InputPipelineRate}{R_{\text{pipeline}}} \newcommand{\InputPipelineRatio}{r_{\text{pipe}}} \newcommand{\InputPipelineServiceRate}{r_{\text{pipeline}}} \newcommand{\InputPipelineStageIndex}{j} \newcommand{\InputQuantizationScale}{s_X} \newcommand{\InputResolution}{r} \newcommand{\InputStageServiceRate}{r} \newcommand{\InputTokenPrice}{c_{\text{in}}} \newcommand{\InputTokenSequence}{x_{1:S}} \newcommand{\InputVariableIndex}{m} \newcommand{\InsetAvailableBrakingDistance}{D_{\text{avail}}} \newcommand{\InstanceReplenishTime}{T_{\text{init}}} \newcommand{\InstantaneousPhaseCurrent}{i_{\text{phase}}} \newcommand{\InstantaneousRequestOccupancy}{Q} \newcommand{\IntegerWeightCode}{q} \newcommand{\IntegralControlEffort}{\mathbf{u}_{\text{int}}} \newcommand{\IntegralGainMatrix}{\mathbf{K}_{i}} \newcommand{\IntegratedPixelResponse}{I_{\text{pixel}}} \newcommand{\IntegrationCandidateCommitHash}{h_{\text{candidate}}} \newcommand{\IntegrationDummyTime}{t'} \newcommand{\IntegrationHeadCommitHash}{h_{\text{head}}} \newcommand{\IntegrationPoint}{\mathbf{y}} \newcommand{\IntegrationPointCoordinate}{y} \newcommand{\IntegrationTimeInstant}{s} \newcommand{\IntegratorState}{\mathbf{z}} \newcommand{\IntegratorStateRate}{\dot{\mathbf{z}}} \newcommand{\IntegratorUnwindDelay}{T_{\text{unwind}}} \newcommand{\IntegrityProvenance}{\iota} \newcommand{\IntegrityTrustLabel}{\iota} \newcommand{\IntentAcknowledgmentEvent}{e_{\text{flush}}} \newcommand{\IntentAdministrativeLease}{T_{\text{admin}}} \newcommand{\IntentDemonstrationDataset}{\mathcal{D}_{\text{intent}}} \newcommand{\IntentLease}{\mathcal{I}_{\text{intent}}} \newcommand{\IntentLeaseExpiry}{t_{\text{intent\_exp}}} \newcommand{\IntentProposalPeriod}{T_{\text{period}}} \newcommand{\InterAnnotatorAgreement}{\kappa} \newcommand{\InterFeedInterval}{T_{\text{feed}}} \newcommand{\InterGroupColumnDelay}{t_{\text{CCD\_S}}} \newcommand{\InterKernelGapTime}{T_{\text{gap}}} \newcommand{\InterNodeContextParallelDegree}{c_{\text{inter}}} \newcommand{\InterQueryIntervalDeviation}{\sigma_{\text{inter-query}}} \newcommand{\InterSensorClockSkew}{\Delta t_{\text{skew}}} \newcommand{\InteractionHistory}{h} \newcommand{\InteractionPortForce}{F} \newcommand{\InteractionPortVelocity}{v} \newcommand{\InterarrivalVariationCoefficient}{c_{a}} \newcommand{\InterfaceMaterialThermalResistance}{R_{\text{th,TIM}}} \newcommand{\InterferenceSlowdownFactor}{r_{\text{slow}}} \newcommand{\InterframeSpacingTime}{t_{\text{interframe},i}} \newcommand{\InterleavedPipelineBubbleFraction}{b_{\text{interleaved}}} \newcommand{\IntermediateTensorSize}{M_{\text{tensor}}} \newcommand{\InternalDissipationPower}{g} \newcommand{\IntervalCompletionTime}{T_{\text{total}}} \newcommand{\IntervalMean}{\bar{T}} \newcommand{\IntervalMeanOccupancy}{\bar{Q}} \newcommand{\IntervalNormalQuantile}{z} \newcommand{\IntervalStandardDeviation}{\sigma} \newcommand{\IntervalTransitionMatrix}{\boldsymbol{\Phi}} \newcommand{\IntervalVariationCoefficient}{c} \newcommand{\InterventionDensity}{D_{\text{int}}} \newcommand{\InterventionRate}{\lambda_{\text{int}}} \newcommand{\InterventionWindowDuration}{W} \newcommand{\IntraClusterCorrelation}{\rho_{\text{ICC}}} \newcommand{\IntraGroupColumnDelay}{t_{\text{CCD\_L}}} \newcommand{\IntraNodeContextParallelDegree}{c_{\text{intra}}} \newcommand{\IntrusionDistance}{C} \newcommand{\IntrusionDistanceAllowance}{C} \newcommand{\InvalidatedArtifactNode}{v} \newcommand{\InverseDepth}{\rho} \newcommand{\InverseDepthLandmarkParameters}{\mathbf{y}} \newcommand{\InverseKinematicsDamping}{\lambda} \newcommand{\InverseSensorLogOdds}{L_{\text{sensor}}} \newcommand{\InverterCurrentLimit}{I_{\max}} \newcommand{\InverterDeadTime}{t_{\text{dead}}} \newcommand{\IoTransferTime}{T_{\text{IO}}} \newcommand{\IronCaseThermalResistance}{R_{\text{th,iron-case}}} \newcommand{\IronLawComputeTime}{T_{\text{compute}}} \newcommand{\IronLawMemoryTime}{T_{\text{memory}}} \newcommand{\IronLossPower}{P_{\text{iron}}} \newcommand{\IronThermalCapacitance}{C_{\text{iron}}} \newcommand{\IrreducibleLoss}{C_{\mathcal{L}}} \newcommand{\IsolatedEnforcerExecutionTime}{t_{\text{iso}}} \newcommand{\IsolatedJobRunTime}{T} \newcommand{\IspProcessingTime}{t_{\text{ISP}}} \newcommand{\IsrExecutionTime}{t_{\text{ISR}}} \newcommand{\IterationCost}{C_{\text{iter}}} \newcommand{\IterationTokenBudget}{N_{\text{budget}}} \newcommand{\JaccardSimilarity}{J} \newcommand{\JacobianLeftSingularMatrix}{\mathbf{U}} \newcommand{\JacobianLeftSingularVector}{\mathbf{u}} \newcommand{\JacobianPseudoinverse}{\mathbf{J}^\dagger} \newcommand{\JacobianRightSingularMatrix}{\mathbf{V}} \newcommand{\JacobianRightSingularVector}{\mathbf{v}} \newcommand{\JacobianSingularNumber}{\sigma} \newcommand{\JacobianSingularNumberMatrix}{\boldsymbol{\Sigma}} \newcommand{\JawAperture}{w_{\text{aperture}}} \newcommand{\JensenShannonDivergence}{\mathcal{D}_{\text{JS}}} \newcommand{\JensenShannonMixtureDistribution}{\bar{P}} \newcommand{\JerkLimit}{j_{\max}} \newcommand{\JerkWeightMatrix}{\mathbf{W}_j} \newcommand{\JitterBufferPlayoutDelay}{T_{\text{buf}}} \newcommand{\JobAbsoluteDeadline}{d} \newcommand{\JobAvailability}{A_{\text{all}}} \newcommand{\JobDuration}{T_{\text{job}}} \newcommand{\JobIndex}{j} \newcommand{\JobQueueWaitTime}{W} \newcommand{\JobReleaseTime}{r} \newcommand{\JobRestartTime}{T_{\text{restart}}} \newcommand{\JobSlowdown}{S} \newcommand{\JobStartupTime}{T_{\text{startup}}} \newcommand{\JointAcceleration}{\ddot{q}} \newcommand{\JointAngle}{\theta_{\text{joint}}} \newcommand{\JointAngleLowerLimit}{q_{\min}} \newcommand{\JointAngleUpperLimit}{q_{\max}} \newcommand{\JointAngularAcceleration}{\dot{\omega}} \newcommand{\JointAngularRate}{\omega} \newcommand{\JointAngularSpeed}{\omega} \newcommand{\JointBaseInertiaCoupling}{\mathbf{M}_{jb}} \newcommand{\JointBiasTorque}{\tau_{\text{bias}}} \newcommand{\JointCoordinate}{q} \newcommand{\JointCount}{n} \newcommand{\JointFrictionTorque}{\tau_{\text{fric}}} \newcommand{\JointIndex}{i} \newcommand{\JointJerk}{j_{\text{joint}}} \newcommand{\JointLoadTorque}{\tau_{\text{load}}} \newcommand{\JointOutputImpedance}{Z_{\text{out}}} \newcommand{\JointOutputTorque}{\tau_{\text{out}}} \newcommand{\JointPathCurvature}{\mathbf{q}''} \newcommand{\JointPathTangent}{\mathbf{q}'} \newcommand{\JointPosition}{q} \newcommand{\JointPositionLowerLimit}{\mathbf{q}_{\min}} \newcommand{\JointPositionSetpoint}{\mathbf{q}^*} \newcommand{\JointPositionTarget}{q_{\text{des}}} \newcommand{\JointPositionUpperLimit}{\mathbf{q}_{\max}} \newcommand{\JointReflectedRotorInertia}{J_{m}} \newcommand{\JointSampleTimestamp}{t_{\text{joint}}} \newcommand{\JointTorque}{\boldsymbol{\tau}} \newcommand{\JointTorqueConstant}{K_t} \newcommand{\JointTorqueLimit}{\tau_{\max}} \newcommand{\JointTorqueLimits}{\boldsymbol{\tau}_{\max}} \newcommand{\JointTorqueLowerLimit}{\boldsymbol{\tau}_{\min}} \newcommand{\JointTorqueSlew}{\dot{\boldsymbol{\tau}}} \newcommand{\JointTorqueSlewLimit}{\dot{\boldsymbol{\tau}}_{\max}} \newcommand{\JointTorqueTarget}{\tau_{\text{des}}} \newcommand{\JointTorqueUpperLimit}{\boldsymbol{\tau}_{\max}} \newcommand{\JointTorsionalStiffnessMatrix}{\mathbf{K}} \newcommand{\JointTrackingError}{\mathbf{e}} \newcommand{\JointVelocity}{\dot{q}} \newcommand{\JointVelocityCeiling}{\dot{q}_{\max}} \newcommand{\JointVelocityLimit}{\dot{\mathbf{q}}_{\max}} \newcommand{\JointVelocitySetpoint}{\dot{\mathbf{q}}^*} \newcommand{\JointVelocityTarget}{\dot{q}_{\text{des}}} \newcommand{\JouleanTemperatureRise}{\Delta T} \newcommand{\JunctionAmbientThermalResistance}{R_{\text{th,JA}}} \newcommand{\JunctionCaseThermalResistance}{R_{\text{th,JC}}} \newcommand{\JunctionTemperature}{T_{\text{j}}} \newcommand{\KalmanBucyObserverGain}{\mathbf{L}} \newcommand{\KalmanGain}{\mathbf{G}} \newcommand{\KeepContextPathCost}{C_{\text{keep}}} \newcommand{\KendallMarkovianCode}{M} \newcommand{\KernelActiveTime}{T_{\text{compute}}} \newcommand{\KernelColumnOffset}{n} \newcommand{\KernelExecutionTime}{T_{\text{kernel}}} \newcommand{\KernelHeight}{K_h} \newcommand{\KernelHorizontalLoopOffset}{k_{x}} \newcommand{\KernelRowOffset}{m} \newcommand{\KernelSize}{K} \newcommand{\KernelVerticalLoopOffset}{k_{y}} \newcommand{\KernelWeight}{W} \newcommand{\KernelWidth}{K_w} \newcommand{\KeyAxisLabel}{j} \newcommand{\KeyBufferPosition}{j} \newcommand{\KeyComponent}{k_{jm}} \newcommand{\KeyLeftSingularMatrix}{\mathbf{U}} \newcommand{\KeyLeftSingularVector}{\mathbf{u}} \newcommand{\KeyProjectionMatrix}{\mathbf{W}_{K}} \newcommand{\KeyRightSingularMatrix}{\mathbf{V}} \newcommand{\KeyRightSingularVector}{\mathbf{v}} \newcommand{\KeySingularNumber}{\sigma} \newcommand{\KeySingularSpectrumMatrix}{\boldsymbol{\Sigma}} \newcommand{\KeySourceMatrix}{\mathbf{X}_{K}} \newcommand{\KeySpectrumLength}{q} \newcommand{\KeyVector}{\mathbf{k}} \newcommand{\KineticEnergy}{E_k} \newcommand{\KineticEnergyCeiling}{E_{\max}} \newcommand{\KineticInsetBarrierFunction}{h_{\text{kinetic}}} \newcommand{\KineticInsetBarrierRate}{\dot{h}_{\text{kinetic}}} \newcommand{\KlDivergence}{\mathcal{D}_{\text{KL}}} \newcommand{\KlPenaltyCoefficient}{\beta_{\text{KL}}} \newcommand{\KlSampleStatistic}{d} \newcommand{\KnownComponentStopDistance}{d_{\text{budget}}} \newcommand{\KolmogorovSmirnovCriticalThreshold}{c_{\text{crit}}} \newcommand{\KolmogorovSmirnovStatistic}{\mathcal{D}_{\text{KS}}} \newcommand{\KroneckerIndicator}{\delta} \newcommand{\KrumClientCount}{n} \newcommand{\KrylovSubspace}{\mathcal{K}} \newcommand{\KsCriticalCoefficient}{c} \newcommand{\KvBlockSize}{S_{\text{blk}}} \newcommand{\KvBlockTailWaste}{\Delta_{\text{tail}}} \newcommand{\KvCacheBytesPerToken}{m_{\text{token}}} \newcommand{\KvCacheHandoffTime}{T_{\text{handoff}}} \newcommand{\KvCacheMemory}{M_{\text{KV}}} \newcommand{\KvElementStorageSize}{s_{\text{elem,KV}}} \newcommand{\KvHeadCount}{H_{\text{KV}}} \newcommand{\KvPoolHeadroomFraction}{f_{\text{head}}} \newcommand{\KvPoolMemory}{M_{\text{pool}}} \newcommand{\KvRecomputeTime}{T_{\text{recompute}}} \newcommand{\KvReloadTime}{T_{\text{reload}}} \newcommand{\KvTileCount}{T_c} \newcommand{\KvTileIndex}{j} \newcommand{\KvTileSize}{B_c} \newcommand{\LaSalleInvariantSet}{\Omega} \newcommand{\LabelCategoryIndex}{i} \newcommand{\LabelVector}{\mathbf{y}} \newcommand{\LabeledRecord}{x} \newcommand{\LabeledSampleCount}{D_{\text{labeled}}} \newcommand{\LabelingRoundIndex}{k} \newcommand{\LaggedModelInput}{x_{t-\Delta}} \newcommand{\LaggedStateDigest}{h_{\text{state},t-k}} \newcommand{\LandmarkDepth}{d} \newcommand{\LanguageInstruction}{c_{\text{instr}}} \newcommand{\LanguageSkillPrior}{p_{\text{LLM}}} \newcommand{\LaplaceLikelihoodScale}{b} \newcommand{\LaplaceNoiseSample}{x} \newcommand{\LaplaceNoiseScale}{b} \newcommand{\LaplaceVariable}{s} \newcommand{\LargestDrivenWheelLoadShare}{\varphi} \newcommand{\LargestEigenvalue}{\lambda_{\max}} \newcommand{\LargestInvariantSet}{\mathcal{M}} \newcommand{\LargestSingularNumber}{\sigma_{\max}} \newcommand{\LarsGlobalLearningRate}{\eta_{\text{global}}} \newcommand{\LastCandidateEmbeddingVector}{\mathbf{x}_N} \newcommand{\LastFunctionInputComponent}{x_N} \newcommand{\LastMeasurementTime}{t_{\text{last}}} \newcommand{\LastRankComputeTime}{T_{\text{rank}_{N-1}}} \newcommand{\LatchApproachSpeed}{v_{\text{latch}}} \newcommand{\LatchClearance}{c} \newcommand{\LatchContactForce}{f} \newcommand{\LatchForceLimit}{F_{\text{lim}}} \newcommand{\LatchPlateStiffness}{k_{\text{latch}}} \newcommand{\LatchStallForce}{F} \newcommand{\LatchStrengthFloor}{F_{\text{floor}}} \newcommand{\LateHandoffProbability}{p} \newcommand{\Latency}{L_{\text{lat}}} \newcommand{\LatencyBandwidthCrossoverSize}{n^*} \newcommand{\LatencyBoundedBatchSize}{B_{\text{SLO}}} \newcommand{\LatencyObjective}{S_{\text{latency}}} \newcommand{\LatencyQuantileFunction}{Q_p} \newcommand{\LatencyRewardExponent}{\beta_{\text{lat}}} \newcommand{\LatencySlo}{L_{\text{lat,SLO}}} \newcommand{\LatentActionComponent}{u} \newcommand{\LatentComponentMean}{\mu_{\phi, j}} \newcommand{\LatentComponentStandardDeviation}{\sigma_{\phi, j}} \newcommand{\LatentDimension}{d_z} \newcommand{\LatentGaussianPolicyDensity}{\mu} \newcommand{\LatentKlWeight}{\beta} \newcommand{\LatentPosteriorDistribution}{q} \newcommand{\LatentPosteriorMean}{\boldsymbol{\mu}_\phi} \newcommand{\LatentPosteriorStandardDeviation}{\boldsymbol{\sigma}_\phi} \newcommand{\LatentStateEncoder}{q_\phi} \newcommand{\LatentStyleVariable}{\mathbf{z}} \newcommand{\LatentVariableSpace}{\mathcal{Z}} \newcommand{\LaterBaseFlangeTransform}{\mathbf{T}_{\text{base}, k+1}^{\text{flange}}} \newcommand{\LaterCameraTargetTransform}{\mathbf{T}_{\text{cam}, k+1}^{\text{target}}} \newcommand{\LaterRolloutTurnIndex}{j} \newcommand{\LaterStepIndex}{j} \newcommand{\LateralClearance}{W_{\text{clear}}} \newcommand{\LayerAllReduceTime}{T_{\text{layer comm}}} \newcommand{\LayerBackwardTime}{T_{\text{layer backward}}} \newcommand{\LayerCount}{N_L} \newcommand{\LayerExposedCommunicationTime}{T_{\text{exposed}}} \newcommand{\LayerFunction}{f} \newcommand{\LayerIndex}{\ell} \newcommand{\LayerInputComponent}{x} \newcommand{\LayerInputMatrix}{\mathbf{X}} \newcommand{\LayerInputVector}{\mathbf{x}} \newcommand{\LayerInputWidth}{d_{\text{in}}} \newcommand{\LayerIntermediateStateMemory}{s_{\ell}} \newcommand{\LayerNonlinearity}{\phi} \newcommand{\LayerNormMean}{\mu_{\text{LN}}} \newcommand{\LayerNormStandardDeviation}{\sigma_{\text{LN}}} \newcommand{\LayerOutputMatrix}{\mathbf{Y}} \newcommand{\LayerOutputVector}{\mathbf{y}} \newcommand{\LayerOutputWidth}{d_{\text{out}}} \newcommand{\LayerParameterPayload}{M_{\text{layer}}} \newcommand{\LayerSavedTensorCount}{n_{\text{saved}}} \newcommand{\LayerSelectionIndex}{i} \newcommand{\LayerWeightEntry}{W} \newcommand{\LayerWeights}{\mathbf{w}} \newcommand{\LayerWidth}{n} \newcommand{\LcResonantFrequency}{f_0} \newcommand{\LeaderForwardWave}{\mathbf{u}_m} \newcommand{\LeaderJointPositions}{\mathbf{q}_{\text{leader}}} \newcommand{\LeaderPortEffort}{\mathbf{F}_m} \newcommand{\LeaderPortFlow}{\dot{\mathbf{x}}_m} \newcommand{\LeaderPortPower}{P_m} \newcommand{\LeaderReturnWave}{\mathbf{w}_m} \newcommand{\LeaderWristRollAngle}{\theta_{\text{roll}}} \newcommand{\LeadingSupportDistance}{d_{\text{lead}}} \newcommand{\LeakageCurrent}{I_{\text{leak}}} \newcommand{\LeakagePower}{P_{\text{leakage}}} \newcommand{\LearnedActionProposal}{\hat{\mathbf{a}}_{\text{learned}}} \newcommand{\LearnedNominalTrajectory}{\hat{\mathbf{q}}_{\text{learned}}} \newcommand{\LearnedRemainingReturnEstimate}{\widehat{V}} \newcommand{\LearnedVelocityField}{v_\theta} \newcommand{\LearnerStateDisagreementRate}{\epsilon_\pi} \newcommand{\LearnerStateVisitationDistribution}{p^{\pi}} \newcommand{\LearningCurveSampleCount}{n} \newcommand{\LearningRate}{\eta} \newcommand{\LeaseAdmissionInstant}{t_{\text{adm}}} \newcommand{\LeaseDirtyMemory}{M_{\text{dirty}}} \newcommand{\LeaseExpiryDelaySubtotal}{\tau_{\text{delay,sub}}} \newcommand{\LeaseHoldTime}{T_{\text{hold}}} \newcommand{\LeasePathTravel}{d_{\text{lease}}} \newcommand{\LeaseRefreshInstant}{t_{\text{refresh}}} \newcommand{\LeftEvasionAction}{\mathbf{a}_{\text{left}}} \newcommand{\LeftSingularVectorMatrix}{\mathbf{P}} \newcommand{\LengthPenaltyWeight}{\lambda_{\text{len}}} \newcommand{\LeverArmLength}{r_{\text{arm}}} \newcommand{\LeverArmSweepError}{e_{\text{rot}}} \newcommand{\LewisFormFactor}{Y} \newcommand{\LexicalDocument}{x} \newcommand{\LexicalFrequencySaturation}{k_1} \newcommand{\LexicalLengthNormalization}{b} \newcommand{\LexicalQuery}{Q} \newcommand{\LidarAzimuthAngle}{\theta_{\text{az}}} \newcommand{\LidarBeamDirection}{\mathbf{d}} \newcommand{\LidarElevationAngle}{\phi} \newcommand{\LidarFramePoint}{\mathbf{p}_{\text{lidar}}} \newcommand{\LidarReferenceFrame}{\mathcal{F}_{\text{lidar}}} \newcommand{\LidarScanRate}{f_{\text{scan}}} \newcommand{\LidarSweepPeriod}{T_{\text{sweep}}} \newcommand{\LidarSweepStartTime}{t_{\text{sweep}}} \newcommand{\LieDerivativeAlongControl}{L_{\mathbf{g}} h} \newcommand{\LieDerivativeAlongDrift}{L_{\mathbf{f}} h} \newcommand{\LieDerivativeOrder}{k} \newcommand{\LikelihoodRatioWeight}{w} \newcommand{\LimitMarginFunction}{M} \newcommand{\LinearAcceleration}{\mathbf{a}} \newcommand{\LinearBarrierDecayRate}{\gamma_{\text{cbf}}} \newcommand{\LinearMomentum}{p} \newcommand{\LinearizedVirtualInput}{\mathbf{v}} \newcommand{\LinkAngularAcceleration}{\ddot{\theta}_{\text{link}}} \newcommand{\LinkBandwidth}{\beta} \newcommand{\LinkBitRate}{R_{\text{link}}} \newcommand{\LinkLength}{l} \newcommand{\LinkOutputPosition}{q_{\text{out}}} \newcommand{\LintFalseAcceptFraction}{\phi} \newcommand{\LipschitzConstant}{K} \newcommand{\LiveAutomatonStateSet}{Q_{\text{live}}} \newcommand{\LoadCurrent}{I_{\text{load}}} \newcommand{\LoadInertia}{J_{\text{load}}} \newcommand{\LoadStepCurrentDeficit}{\Delta I_{\text{step}}} \newcommand{\LoadStepDeficitDuration}{\Delta t_{\text{step}}} \newcommand{\LoadedEnforcerExecutionTime}{t_{\text{enf}}} \newcommand{\LoadedJunctionTemperature}{T_{\text{load}}} \newcommand{\LocalBatchSize}{B_{\text{local}}} \newcommand{\LocalEpochCount}{E} \newcommand{\LocalGradient}{\mathbf{g}} \newcommand{\LocalInferenceEnergy}{E_{\text{local}}} \newcommand{\LocalPathTime}{T_{\text{local}}} \newcommand{\LocalRankIndex}{i} \newcommand{\LocalTokenCount}{B_{\text{tok}}} \newcommand{\LocalUpdateCount}{H_{\text{local}}} \newcommand{\LocalityPenaltyFunction}{w} \newcommand{\LocalizationBound}{\delta_{\text{loc}}} \newcommand{\LogFailureRatio}{s_{\text{fail}}} \newcommand{\LogOddsLowerClamp}{L_{\min}} \newcommand{\LogOddsUpperClamp}{L_{\max}} \newcommand{\LogPositionIndex}{j} \newcommand{\LoggedEvent}{e} \newcommand{\LoggedEventPrefix}{\mathbf{e}_{1:j}} \newcommand{\LoggpLongMessageTime}{T_{\text{long}}} \newcommand{\LogisticProbability}{p_{\text{sig}}} \newcommand{\LogitMask}{\mathbf{M}} \newcommand{\LogitMaskEntry}{M} \newcommand{\LogitStorageSize}{s_{\text{logit}}} \newcommand{\LogitVector}{\mathbf{z}} \newcommand{\LogpNetworkLatency}{L_{\text{LogGP}}} \newcommand{\LonePassAdvantage}{\hat{A}_{\text{pass}}} \newcommand{\LongMessageGapPerByte}{G} \newcommand{\LongestInterruptMaskTime}{t_{\text{irq\_disabled,max}}} \newcommand{\LongitudinalFrictionCoefficient}{\mu_x} \newcommand{\LongitudinalSlipRatio}{\lambda} \newcommand{\LongitudinalTractionStiffness}{C_x} \newcommand{\LongitudinalVehicleSpeed}{v_x} \newcommand{\LookaheadStepIndex}{l} \newcommand{\LoopAcceptanceProbability}{p_{\text{loop}}} \newcommand{\LoopGainScalingFactor}{\kappa} \newcommand{\LoopNestDepth}{n_{\text{loops}}} \newcommand{\LoopOrderCount}{N_{\text{order}}} \newcommand{\LoopParallelizationChoiceCount}{\mathcal{P}_{\text{parallel}}} \newcommand{\LoopTurnCost}{C} \newcommand{\LossAdjointSeed}{\bar{\mathcal{L}}} \newcommand{\LossFunction}{\mathcal{L}} \newcommand{\LossGradient}{g} \newcommand{\LossGradientVector}{\mathbf{g}} \newcommand{\LossHessian}{\mathbf{H}} \newcommand{\LossLowerBound}{\mathcal{L}_{\inf}} \newcommand{\LossScaleFactor}{s_{\text{loss}}} \newcommand{\LossTimeDerivative}{\dot{\mathcal{L}}} \newcommand{\LostMotionDeflection}{\delta_{\text{lost}}} \newcommand{\LostSuffixTurnCount}{H_{\text{suffix},i}} \newcommand{\LostWorkReplayTime}{T_{\text{replay}}} \newcommand{\LotSamplingProbability}{q} \newcommand{\LowRankLeftFactor}{\mathbf{U}} \newcommand{\LowRankRightFactor}{\mathbf{V}} \newcommand{\LowerPriorityFrames}{lp} \newcommand{\LowerPriorityTasks}{lp} \newcommand{\LowerRatioClippingWidth}{\epsilon_{\text{low}}} \newcommand{\LqrControlWeightMatrix}{\mathbf{R}_u} \newcommand{\LqrCostToGoMatrix}{\mathbf{P}} \newcommand{\LqrFeedbackGain}{\mathbf{K}_{\text{lqr}}} \newcommand{\LqrQuadraticObjective}{J} \newcommand{\LqrStateWeightMatrix}{\mathbf{Q}_x} \newcommand{\LshBandCount}{L} \newcommand{\LshCandidateProbability}{p_{\text{candidate}}} \newcommand{\LshRowsPerBand}{r} \newcommand{\LyapunovAnalysisDomain}{\mathcal{D}} \newcommand{\LyapunovFunction}{V} \newcommand{\LyapunovFunctionDerivative}{\dot{V}} \newcommand{\LyapunovPositivityMargin}{\epsilon_{\text{pos}}} \newcommand{\LyapunovSublevelSet}{\Omega_c} \newcommand{\MacAccumulator}{\text{acc}} \newcommand{\MachineTaxonomyAxis}{\mathsf{Machine}} \newcommand{\MahalanobisDistance}{d_M} \newcommand{\ManifestTrackIndex}{k} \newcommand{\ManipulatorBaseFrame}{\mathcal{F}_{\text{base}}} \newcommand{\ManipulatorJacobian}{\mathbf{J}} \newcommand{\ManualLease}{T_{\text{lease,man}}} \newcommand{\ManualResetTime}{t_{\text{reset,manual}}} \newcommand{\ManualReviewCost}{C_{\text{manual}}} \newcommand{\ManualReviewFraction}{r_{\text{manual}}} \newcommand{\MapCovarianceJacobian}{\mathbf{J}_{\text{map}}} \newcommand{\MapOdometryTransform}{\mathbf{T}_{\text{map}}^{\text{odom}}} \newcommand{\MapParameterEstimate}{\theta_{\text{MAP}}} \newcommand{\MapPoseCovariance}{\boldsymbol{\Sigma}_{\text{map}}} \newcommand{\MapReferenceFrame}{\mathcal{F}_{\text{map}}} \newcommand{\MappedCommandTap}{a_{\text{cmd}}} \newcommand{\MarginalFalseApprovalProbability}{p} \newcommand{\MarginalRequestServiceTime}{t_{\text{req}}} \newcommand{\MarginalStoppingThreshold}{\epsilon_{\text{stop}}} \newcommand{\MarginalVelocityField}{u} \newcommand{\MarginalizedModelParameters}{\theta'} \newcommand{\MarkovDecisionProcess}{\mathcal{M}} \newcommand{\MaskTokenIndex}{i} \newcommand{\MaskedFinetuningLoss}{\mathcal{L}_{\text{SFT}}} \newcommand{\MaskedImitationDataset}{\mathcal{D}_{\text{train}}} \newcommand{\MaskedImitationLoss}{\mathcal{L}_{\text{imitation}}} \newcommand{\MaskedLogitVector}{\mathbf{z}'} \newcommand{\MaskedTokenLogit}{z'} \newcommand{\Mass}{m} \newcommand{\MassCenterAcceleration}{\ddot{\mathbf{c}}} \newcommand{\MassCenterHeight}{z_c} \newcommand{\MassCenterPosition}{\mathbf{c}} \newcommand{\MasterProcessingTime}{t_{\text{master}}} \newcommand{\MatchingRowCount}{K} \newcommand{\MatrixColumnIndex}{j} \newcommand{\MatrixEigenvalue}{\lambda} \newcommand{\MatrixMultiplyDestination}{\mathbf{D}} \newcommand{\MatrixRowIndex}{i} \newcommand{\MaxBatchSize}{B_{\text{max}}} \newcommand{\MaxBatchingWindow}{T_{\text{max}}} \newcommand{\MaxReceivedTokenCount}{B_{\text{max}}} \newcommand{\MaxResidentContextCount}{B_{\max}} \newcommand{\MaximumActuatorEffort}{u_{\max}} \newcommand{\MaximumBreakerCooldownInterval}{T_{\text{cool}}^{\max}} \newcommand{\MaximumCompletionOffset}{c_{\max}} \newcommand{\MaximumDepthHypothesis}{d_{\max}} \newcommand{\MaximumEntropyObjective}{J} \newcommand{\MaximumLoadCurrentStep}{\Delta I_{\max}} \newcommand{\MaximumLogit}{z_{\max}} \newcommand{\MaximumObservationAge}{t_{\text{age},\max}} \newcommand{\MaximumPlateIndentation}{x_{\max}} \newcommand{\MaximumRetryBackoffInterval}{b_{\max}} \newcommand{\MaximumTurnOffDelay}{t_{\text{off, max}}} \newcommand{\McnemarTestStatistic}{\chi^2} \newcommand{\McuCaptureTime}{t_{\text{MCU,capture}}} \newcommand{\McuDispatchTime}{t_{\text{MCU,dispatch}}} \newcommand{\MealTokenKeyVector}{\mathbf{k}_{\text{meal}}} \newcommand{\MealTokenQueryVector}{\mathbf{q}_{\text{meal}}} \newcommand{\MeanAcceptedDraftLength}{\bar{m}} \newcommand{\MeanAttemptCost}{c} \newcommand{\MeanClusterSize}{m} \newcommand{\MeanContextLength}{\bar{S}} \newcommand{\MeanDeliveryPayloadLength}{L} \newcommand{\MeanDocumentLength}{\overline{|x|}} \newcommand{\MeanHoldTime}{\bar{T}_{\text{hold}}} \newcommand{\MeanLatchContactForce}{\bar{F}} \newcommand{\MeanMessageQueueDelay}{\bar{T}_q} \newcommand{\MeanNeesStatistic}{\bar{\epsilon}} \newcommand{\MeanQueryDistance}{\mu_D} \newcommand{\MeanRolloutLength}{\bar{N}} \newcommand{\MeanSlotOccupancy}{\bar{N}_{\text{slot}}} \newcommand{\MeanSquaredErrorCloningLoss}{\mathcal{L}_{\text{MSE}}} \newcommand{\MeanStoredTokensPerRecord}{\bar{S}} \newcommand{\MeanTargetTokensPerRecord}{\bar{w}} \newcommand{\MeanTimeBetweenFailures}{\text{MTBF}} \newcommand{\MeanTimeToFailure}{\text{MTTF}} \newcommand{\MeanTimeToRepair}{\text{MTTR}} \newcommand{\MeanVerifierServiceTime}{\bar{T}_{\text{svc}}} \newcommand{\MeasuredAxisPosition}{x_{\text{meas}}} \newcommand{\MeasuredContactForce}{\mathbf{F}_{\text{contact}}} \newcommand{\MeasuredJointVelocities}{\dot{\mathbf{q}}_{\text{meas}}} \newcommand{\MeasuredPixelDepth}{Z_{\text{meas}}} \newcommand{\MeasuredResponseTap}{a_{\text{meas}}} \newcommand{\MeasuredSeamAccelerations}{\ddot{\mathbf{q}}_{\text{meas}}} \newcommand{\MeasuredSeamConfiguration}{\mathbf{q}_{\text{meas}}} \newcommand{\MeasuredSeamVelocities}{\dot{\mathbf{q}}_{\text{meas}}} \newcommand{\MeasuredTrackedPosition}{\mathbf{p}_{\text{meas}}} \newcommand{\MeasurementCovariance}{\boldsymbol{\Sigma}_z} \newcommand{\MeasurementDimension}{m} \newcommand{\MeasurementErrorStandardDeviation}{\sigma} \newcommand{\MeasurementFunction}{h} \newcommand{\MeasurementHistory}{\mathbf{y}_{1:k}} \newcommand{\MeasurementInnovation}{\boldsymbol{\nu}} \newcommand{\MeasurementMatrix}{\mathbf{H}} \newcommand{\MeasurementNoiseCovariance}{\boldsymbol{\Sigma}_{\text{meas}}} \newcommand{\MeasurementNoiseVector}{\mathbf{v}_{\text{meas}}} \newcommand{\MeasurementVector}{\mathbf{y}} \newcommand{\MeasurementVectorDerivative}{\dot{\mathbf{y}}} \newcommand{\MeasurementWindowEnd}{t_{\text{end}}} \newcommand{\MechanicalEnergy}{E} \newcommand{\MechanicalEnergyDerivative}{\dot{E}} \newcommand{\MechanicalImpedanceMap}{Z} \newcommand{\MechanicalPlantState}{\mathbf{x}} \newcommand{\MechanicalWork}{W} \newcommand{\MechanismAcceptanceProbability}{p'_{\text{acc}}} \newcommand{\MechanismAttemptCost}{C'_{\text{attempt}}} \newcommand{\MechanismLogMoment}{\alpha_{\mathcal{M}}} \newcommand{\MechanismOutcome}{o} \newcommand{\MechanismOutputSet}{\mathcal{S}} \newcommand{\MechanismOutputVector}{\mathbf{y}} \newcommand{\MechanismRenyiPrivacyBudget}{\epsilon_{\text{R},i}} \newcommand{\MemoryBusQueueDelay}{t_{\text{queue}}} \newcommand{\MemoryEntryBirthGeneration}{g_{\text{birth}}} \newcommand{\MemoryEntryDeathGeneration}{g_{\text{death}}} \newcommand{\MemoryHierarchyLevelCount}{N_{\text{mem}}} \newcommand{\MemoryHoldDuringWait}{O_{\text{mem}}} \newcommand{\MemorySubsystemEnergy}{E_{\text{memory}}} \newcommand{\MergedAttentionOutput}{\mathbf{O}^{\text{new}}} \newcommand{\MergedSoftmaxMaximum}{m^{\text{new}}} \newcommand{\MergedSoftmaxNormalizer}{z^{\text{new}}} \newcommand{\MessageInjectionGap}{g} \newcommand{\MessageQueueDelay}{T_q} \newcommand{\MessageStartupLatency}{\alpha} \newcommand{\MessageTimestamp}{t_{\text{msg}}} \newcommand{\MetricDepth}{z_{\text{metric}}} \newcommand{\MicroUnitPrefix}{\text{µ}} \newcommand{\MicrobatchCount}{m} \newcommand{\MicrobatchGradient}{\mathbf{g}} \newcommand{\MicrobatchIndex}{j} \newcommand{\MicrobatchPassTime}{T_{\text{micro},j}} \newcommand{\MicrobatchSize}{B_{\text{micro}}} \newcommand{\MicrocontrollerClockTime}{t_{\text{MCU}}} \newcommand{\MillerCapacitance}{C_{\text{gd}}} \newcommand{\MillerCharge}{Q_{\text{gd}}} \newcommand{\MillerDisplacementCurrent}{I_{\text{miller}}} \newcommand{\MillerPlateauDuration}{t_{\text{plateau}}} \newcommand{\MillerPlateauVoltage}{V_{\text{plateau}}} \newcommand{\MinHashPermutation}{\sigma} \newcommand{\MinHashPermutationCount}{n_{\sigma}} \newcommand{\MinHashSketchSize}{s} \newcommand{\MiniBatchActivation}{a} \newcommand{\MiniBatchSet}{\mathcal{B}} \newcommand{\MinibatchGradient}{\mathbf{g}} \newcommand{\MinimumActuatorEffort}{u_{\min}} \newcommand{\MinimumCellSupportCount}{N_{\min}} \newcommand{\MinimumChunkSetpointCount}{h_{\min}} \newcommand{\MinimumCompletionOffset}{c_{\min}} \newcommand{\MinimumDepthHypothesis}{d_{\min}} \newcommand{\MinimumDetectableEffect}{\delta_{\text{MDE}}} \newcommand{\MinimumPrefetchBufferCount}{Q_{\text{prefetch,min}}} \newcommand{\MinimumRailVoltage}{V_{\text{rail,min}}} \newcommand{\MinimumRoundTripLatency}{L_{\text{lat,min}}} \newcommand{\MinimumStableBatchSize}{B_{\text{min}}} \newcommand{\MinimumTransitTime}{t_{\min}} \newcommand{\MinimumTurnOnDelay}{t_{\text{on, min}}} \newcommand{\MisclassifiedFraction}{r_{\text{error}}} \newcommand{\MisroutedQueryFraction}{m} \newcommand{\MissAcceptanceProbability}{\alpha} \newcommand{\MissPathServiceTime}{T_{\text{cold}}} \newcommand{\MissionDuration}{T_{\text{mission}}} \newcommand{\MissionEnergy}{E_{\text{mission}}} \newcommand{\MissionExceedanceBudget}{\epsilon_{\text{mission}}} \newcommand{\MissionHandoffCount}{K} \newcommand{\MixtureComponentCount}{M} \newcommand{\MixtureComponentCovariance}{\boldsymbol{\Sigma}_m} \newcommand{\MixtureComponentIndex}{m} \newcommand{\MixtureComponentMean}{\boldsymbol{\mu}_m} \newcommand{\MixtureComponentWeight}{w_m} \newcommand{\MixupSample}{\tilde{x}} \newcommand{\MixupWeight}{\lambda_{\text{mix}}} \newcommand{\MlProductivityGoodput}{\text{MPG}} \newcommand{\MlpWeightArithmeticIntensity}{I_{\text{MLP}}} \newcommand{\MobileBaseBarrierFunction}{h_{\text{base}}} \newcommand{\ModelCallIndex}{i} \newcommand{\ModelCallRequest}{\mathcal{R}} \newcommand{\ModelDownloadEnergy}{E_{\text{download}}} \newcommand{\ModelFlopsUtilization}{\text{MFU}} \newcommand{\ModelGenerationIndex}{n} \newcommand{\ModelInput}{x} \newcommand{\ModelLifetimeCost}{C_{\text{total}}} \newcommand{\ModelParameters}{\theta} \newcommand{\ModelPointAbscissa}{X} \newcommand{\ModelPointHeight}{Z} \newcommand{\ModelPointOrdinate}{Y} \newcommand{\ModelPrediction}{\hat{y}} \newcommand{\ModelPredictor}{f} \newcommand{\ModelScore}{s} \newcommand{\ModelStepOperations}{O_{\text{model}}} \newcommand{\ModelTime}{T_{\text{model}}} \newcommand{\ModelTimeFraction}{f} \newcommand{\ModelWeight}{w} \newcommand{\MomentOrder}{\lambda_{\text{mom}}} \newcommand{\MonitorStartupTime}{T_{\text{vmm}}} \newcommand{\MonitoredFairnessMetricCount}{m} \newcommand{\MonitoredFeatureLevel}{x_{\text{feat}}} \newcommand{\MonitoredGroupCount}{k} \newcommand{\MonitoredMetric}{X} \newcommand{\MonitoredMetricMean}{\mu} \newcommand{\MonitoredMetricStandardDeviation}{\sigma} \newcommand{\MonitoringAlertCost}{C_{\text{alert}}} \newcommand{\MonitoringComputeCost}{C_{\text{compute}}} \newcommand{\MonitoringCostComponent}{C_*} \newcommand{\MonitoringIngestionCost}{C_{\text{ingest}}} \newcommand{\MonitoringStorageCost}{C_{\text{storage}}} \newcommand{\MonotonicClockInstant}{t} \newcommand{\MonthlyOptimizationSavings}{C_{\text{save,monthly}}} \newcommand{\MotionBlurLength}{L} \newcommand{\MotionCyclePeriod}{T_{\text{cycle}}} \newcommand{\MotionModelInput}{\mathbf{u}} \newcommand{\MotorBackEmfConstant}{K_e} \newcommand{\MotorConstant}{K_m} \newcommand{\MotorPhaseRmsCurrent}{I_{\text{phase}}} \newcommand{\MotorRotorAccelerations}{\ddot{\boldsymbol{\theta}}_{\text{motor}}} \newcommand{\MotorRotorCoordinates}{\boldsymbol{\theta}_{\text{motor}}} \newcommand{\MotorRotorVelocities}{\dot{\boldsymbol{\theta}}_{\text{motor}}} \newcommand{\MotorShaftDamping}{D_{\text{motor}}} \newcommand{\MotorShaftPosition}{q_{\text{motor}}} \newcommand{\MotorTorque}{\tau_{\text{motor}}} \newcommand{\MotorTorqueConstant}{K_t} \newcommand{\MotorViscousDamping}{B_{m}} \newcommand{\MotorViscousDampingMatrix}{\mathbf{B}_m} \newcommand{\MpcControlSequence}{\mathbf{u}_{0:N_{\text{mpc}}-1}} \newcommand{\MpcControlSequenceTail}{\mathbf{u}_{1:N_{\text{mpc}}-1}} \newcommand{\MpcHorizonObjective}{J} \newcommand{\MpcPredictionHorizon}{N_{\text{mpc}}} \newcommand{\MpcTerminalCost}{\ell_f} \newcommand{\MpcTerminalCostMatrix}{\mathbf{P}_{N_{\text{mpc}}}} \newcommand{\MultiAgentAcceptanceProbability}{p_{\text{multi}}} \newcommand{\MultiDeviceRunTime}{T_N} \newcommand{\MultimodalFusedTokenStream}{\mathbf{Z}} \newcommand{\MultimodalObservation}{\mathbf{o}} \newcommand{\MutatingToolAction}{a} \newcommand{\MutualInformation}{I} \newcommand{\NaturalLogarithmBase}{e} \newcommand{\NearestCandidateDistance}{D_{\min}} \newcommand{\NeesStatistic}{\epsilon} \newcommand{\NegativeGateSupplyVoltage}{V_{\text{ee}}} \newcommand{\NeighborCount}{k} \newcommand{\NeighborUserIndex}{j} \newcommand{\NeighboringDataset}{X} \newcommand{\NetAngularBrakingDeceleration}{\alpha_{\text{net}}} \newcommand{\NetBrakingDeceleration}{a_{\text{net}}} \newcommand{\NetworkBandwidth}{\text{BW}_{\text{network}}} \newcommand{\NetworkDelayStandardDeviation}{\sigma_d} \newcommand{\NetworkEnergy}{E_{\text{network}}} \newcommand{\NetworkFunction}{f_{\text{net}}} \newcommand{\NetworkLatency}{L_{\text{lat,network}}} \newcommand{\NetworkOutput}{y} \newcommand{\NetworkTrafficVolume}{M} \newcommand{\NeuralLyapunovFactor}{\mathbf{L}_{\phi}} \newcommand{\NeuronActivation}{a} \newcommand{\NeuronBias}{b} \newcommand{\NeuronConnectionWeight}{w_{ij}} \newcommand{\NeuronIndex}{j} \newcommand{\NeuronPreactivation}{z} \newcommand{\NextDecisionProcessState}{s'} \newcommand{\NextFailureTime}{F} \newcommand{\NextProprioceptiveObservation}{\mathbf{o}_{\text{proprio}, t+1}} \newcommand{\NextRobotAction}{\mathbf{a}'} \newcommand{\NextTokenDistribution}{p} \newcommand{\NextTokenEntropy}{\mathcal{H}} \newcommand{\NextTokenLogitFunction}{\mathbf{f}_\theta} \newcommand{\NgramLength}{n} \newcommand{\NicMttf}{\text{MTTF}_{\text{nic}}} \newcommand{\NicsPerNode}{n_{\text{nic}}} \newcommand{\NodeAcceleratorCount}{n_{\text{acc}}} \newcommand{\NodeHbmCapacity}{M_{\text{HBM}}} \newcommand{\NodeMtbf}{\text{MTBF}_{\text{node}}} \newcommand{\NodeStragglerProbability}{p_{\text{straggle}}} \newcommand{\NoisePredictionNetwork}{\boldsymbol{\epsilon}_\theta} \newcommand{\NoisedActionChunk}{\mathbf{A}^k} \newcommand{\NoisyClassProbability}{\tilde{p}} \newcommand{\NoisyClassProbabilityVector}{\tilde{\mathbf{p}}} \newcommand{\NoisyLabelSampleCount}{D_{\text{noisy}}} \newcommand{\NominalBitRate}{R_{\text{nom}}} \newcommand{\NominalBitTime}{T_{\text{bit,nom}}} \newcommand{\NominalBrakingDeceleration}{a_{\text{nominal}}} \newcommand{\NominalClearance}{C_{\text{nominal}}} \newcommand{\NominalClockFrequency}{f_{\text{nom}}} \newcommand{\NominalCommandWindow}{\mathbf{u}_{\text{nom}, t:t+H-1}} \newcommand{\NominalContactForces}{\mathbf{f}_{\text{nom}}} \newcommand{\NominalControlCommand}{\mathbf{u}_{\text{nom}}} \newcommand{\NominalFrameInterval}{T_{\text{nominal}}} \newcommand{\NominalFrictionCoefficient}{\mu_{\text{nom}}} \newcommand{\NominalOscillatorFrequency}{f_{\text{nom}}} \newcommand{\NominalPlanExpiry}{t_{\text{plan\_exp}}} \newcommand{\NominalRatedSpeed}{v_{\text{nominal}}} \newcommand{\NominalReferenceClearance}{c} \newcommand{\NominalSupplyVoltage}{V_{\text{nom}}} \newcommand{\NominalTickPeriod}{T_{\text{period}}} \newcommand{\NominalTrackingTolerance}{\epsilon_{\text{nom}}} \newcommand{\NonconformityScore}{s} \newcommand{\NoninferiorityRatioMargin}{\delta} \newcommand{\NoninferiorityTolerance}{\delta_{\text{tol}}} \newcommand{\NonlinearBiasTorque}{\mathbf{h}} \newcommand{\NonlinearObservationSpace}{\mathbf{O}_{\text{NL}}} \newcommand{\NonlinearOutputFunction}{\mathbf{h}} \newcommand{\NonzeroCount}{n_{\text{nz}}} \newcommand{\NonzeroParameterBudget}{k_{\text{nz}}} \newcommand{\NormWeightMatrix}{\mathbf{W}} \newcommand{\NormalContactForce}{f_{k, \perp}} \newcommand{\NormalContactImpulse}{P_n} \newcommand{\NormalizationScale}{\gamma} \newcommand{\NormalizationScaleVector}{\boldsymbol{\gamma}} \newcommand{\NormalizationShift}{\beta} \newcommand{\NormalizationShiftVector}{\boldsymbol{\beta}} \newcommand{\NormalizedActionCommand}{\tilde{a}} \newcommand{\NormalizedActionResidual}{e} \newcommand{\NormalizedActivation}{\hat{a}} \newcommand{\NormalizedCandidateScore}{c} \newcommand{\NormalizedElapsedTimeRatio}{D} \newcommand{\NormalizedGearRatio}{\tilde{N}} \newcommand{\NormalizedImageAbscissa}{x_n} \newcommand{\NormalizedImageOrdinate}{y_n} \newcommand{\NormalizedMetricBaseline}{v} \newcommand{\NormalizedPredicateMargin}{\bar{f}} \newcommand{\NormalizedRadialDistance}{r} \newcommand{\NormalizedStatusEnvelope}{\mathcal{N}} \newcommand{\NormalizerTokenIndex}{w} \newcommand{\NormalizingClassIndex}{k} \newcommand{\NormalizingKeyIndex}{m} \newcommand{\NormalizingNextState}{\tilde{s}} \newcommand{\NoticeByteAllocation}{M_{\text{notice}}} \newcommand{\NucleusProbabilityMass}{p} \newcommand{\NullSpaceProjector}{\mathbf{N}} \newcommand{\NullSpaceVelocityBias}{\dot{\mathbf{q}}_0} \newcommand{\NumericBitWidth}{b} \newcommand{\NumericalStabilityConstant}{\epsilon} \newcommand{\ObjectHandle}{h} \newcommand{\ObjectWrench}{\mathbf{w}_{\text{obj}}} \newcommand{\ObservabilityMatrix}{\mathbf{O}_{\text{obs}}} \newcommand{\ObservableModelOutput}{O} \newcommand{\ObservationAge}{t_{\text{age}}} \newcommand{\ObservationAgeBudget}{t_{\text{age},\max}} \newcommand{\ObservationAgeDisplacement}{\Delta \mathbf{p}} \newcommand{\ObservationBinding}{\lambda} \newcommand{\ObservationByteBudget}{M_{\text{obs},\max}} \newcommand{\ObservationCount}{N} \newcommand{\ObservationDataset}{\mathcal{D}} \newcommand{\ObservationEncodingTime}{t_{\text{enc}}} \newcommand{\ObservationFunction}{h} \newcommand{\ObservationHistory}{\mathbf{O}} \newcommand{\ObservationHistoryLength}{H_{\text{hist}}} \newcommand{\ObservationHistorySequence}{\mathbf{o}_{0:t}} \newcommand{\ObservationHistoryWindow}{\mathbf{o}_{t-H_{\text{hist}}:t}} \newcommand{\ObservationIntervalEnd}{t_{b}} \newcommand{\ObservationIntervalLength}{T_{\text{obs}}} \newcommand{\ObservationIntervalStart}{t_{a}} \newcommand{\ObservationPairingLag}{\Delta t_{\text{lag}}} \newcommand{\ObservationPayload}{\mathbf{T}_{\text{payload}}} \newcommand{\ObservationResponseLatency}{T_{\text{total}}} \newcommand{\ObservationTimestamp}{t_{\text{obs}}} \newcommand{\ObservationTokenCount}{S_{\text{obs}}} \newcommand{\ObservationTokenSequence}{\mathbf{z}_{\text{token}}} \newcommand{\ObservedAnnotatorAgreement}{p_o} \newcommand{\ObservedCategoryCount}{n_i^{\text{obs}}} \newcommand{\ObservedCycleCount}{N} \newcommand{\ObservedDataPoint}{\mathbf{x}} \newcommand{\ObservedFailureCount}{k} \newcommand{\ObservedFailureFraction}{\hat{p}} \newcommand{\ObservedFreeSpace}{\mathcal{M}_{\text{free}}} \newcommand{\ObservedLabelCount}{n} \newcommand{\ObservedOccupiedSpace}{\mathcal{M}_{\text{occ}}} \newcommand{\ObservedPixelCoordinates}{\tilde{\mathbf{m}}_{\text{observed}}} \newcommand{\ObservedPlantState}{\mathbf{x}_{\text{obs}}} \newcommand{\ObservedPointRange}{r} \newcommand{\ObservedRelativeSpeed}{v_{\text{rel}}} \newcommand{\ObservedSignificanceLevel}{p_{\text{val}}} \newcommand{\ObservedSuccessFraction}{\hat{p}} \newcommand{\ObservedTrialFailureCount}{k} \newcommand{\ObservedViolationFraction}{V} \newcommand{\ObservedVolume}{V_{\text{obs}}} \newcommand{\ObstacleConfigurationSet}{\mathcal{C}_{\text{obs}}} \newcommand{\ObstacleCostWeight}{\lambda_{\text{obs}}} \newcommand{\ObstaclePoint}{\mathbf{o}} \newcommand{\ObstaclePosition}{x_{\text{obstacle}}} \newcommand{\ObstacleProximityCost}{c_{\text{obs}}} \newcommand{\ObstacleRiskRadius}{r_{\text{risk}}} \newcommand{\ObstacleSeparationDistance}{d} \newcommand{\ObstacleStateSet}{\mathcal{X}_{\text{obs}}} \newcommand{\ObstacleSurfaceArea}{A_{\text{surface}}} \newcommand{\OccupancyCoverageMultiplier}{k_\sigma} \newcommand{\OccupancyLogOdds}{L} \newcommand{\OccupancyThreshold}{k} \newcommand{\OccupiedLogOddsIncrement}{L_{\text{occ}}} \newcommand{\OccupiedScenarioCellCount}{N_{\text{supported}}} \newcommand{\OdometryBaseTransform}{\mathbf{T}_{\text{odom}}^{\text{base}}} \newcommand{\OdometryCovarianceJacobian}{\mathbf{J}_{\text{odom}}} \newcommand{\OdometryNoiseStandardDeviation}{\sigma_{w}} \newcommand{\OdometryPoseCovariance}{\boldsymbol{\Sigma}_{\text{odom}}} \newcommand{\OdometryReferenceFrame}{\mathcal{F}_{\text{odom}}} \newcommand{\OfflineTransitionDataset}{\mathcal{D}_{\text{offline}}} \newcommand{\OffloadTailNetworkTime}{t_{\text{net}}^{\text{tail}}} \newcommand{\OffloadTailProcessingTime}{t_{\text{proc}}^{\text{tail}}} \newcommand{\OffloadTransactionWindow}{W} \newcommand{\OhmUnit}{\Omega} \newcommand{\OilBulkModulus}{\beta} \newcommand{\OnDieDecouplingCapacitance}{C_{\text{die}}} \newcommand{\OpenLoopTransferFunction}{L} \newcommand{\OpenLoopTransferMatrix}{\mathbf{L}} \newcommand{\OperationChargeBound}{\bar{c}} \newcommand{\OperationDispatchOverhead}{t_{\text{dispatch}}} \newcommand{\OperationRecipient}{r} \newcommand{\OperationReconciliationTime}{T_{\text{rec}}} \newcommand{\OperationalFailureProbability}{p_F} \newcommand{\OperationalOverheadFraction}{f_{\text{overhead}}} \newcommand{\OperationalScenarioDistribution}{p} \newcommand{\OperationalTaxonomyDimension}{C} \newcommand{\OperationalTestDistribution}{\mathcal{D}} \newcommand{\Operations}{O} \newcommand{\OperationsPerSample}{O_{\text{sample}}} \newcommand{\OperatorCognitiveTime}{T_{\text{cognitive}}} \newcommand{\OperatorMotorTime}{T_{\text{motor}}} \newcommand{\OperatorResponseLatency}{t_{\text{hum}}} \newcommand{\OperatorSensoryTime}{T_{\text{sensory}}} \newcommand{\OperatorStabilizationInstant}{t_{\text{stabilize}}} \newcommand{\OperatorWindowTime}{t'} \newcommand{\OperatorWorkspaceMemory}{M_{\text{workspace}}} \newcommand{\OpticalFrequency}{\nu} \newcommand{\OpticalWavelength}{\lambda_{\text{wl}}} \newcommand{\OptimalCheckpointInterval}{T^\ast_{\text{ckpt}}} \newcommand{\OptimalCostToGoDerivative}{\dot{V}} \newcommand{\OptimalCostToGoFunction}{V} \newcommand{\OptimalModelParameters}{\theta^*} \newcommand{\OptimalStateReturn}{V_{\text{RL}}} \newcommand{\OptimizationBreakevenTime}{T_{\text{breakeven}}} \newcommand{\OptimizationImplementationCost}{C_{\text{optimization}}} \newcommand{\OptimizationIterate}{x} \newcommand{\OptimizerStateMemory}{M_{\text{optimizer}}} \newcommand{\OptimizerStepIndex}{t} \newcommand{\OptimizerStepTime}{T_{\text{update}}} \newcommand{\OptimizerUpdateCount}{T} \newcommand{\OptimumMissFactor}{x} \newcommand{\OrderedTestRank}{r} \newcommand{\OrientationTolerance}{\theta_{\text{tol}}} \newcommand{\OrphanSweepInterval}{T} \newcommand{\OscillationPriorStateDigest}{h_{\text{state},t-2}} \newcommand{\OscillatorAcceleration}{\ddot{q}} \newcommand{\OscillatorNaturalFrequency}{\omega} \newcommand{\OscillatorPosition}{q} \newcommand{\OscillatorStepVelocity}{v} \newcommand{\OscillatorVelocity}{\dot{q}} \newcommand{\OutcomeAlphabet}{\mathcal{X}} \newcommand{\OutcomeCheckPassProbability}{p_{\text{out}}} \newcommand{\OutcomeCheckSlotTime}{T_{\text{out}}} \newcommand{\OutcomePairPrivacyLoss}{\mathcal{L}_{\text{priv},(X,X')}^{(o)}} \newcommand{\OutcomeStandardDeviation}{\sigma} \newcommand{\OutgoingChannelCommand}{u_{\text{prior}}} \newcommand{\OutgoingCommandDerivative}{\dot{u}_{\text{prior}}} \newcommand{\OutputBearingDamping}{D_{\text{joint}}} \newcommand{\OutputChannel}{y} \newcommand{\OutputChannelCount}{C_{\text{out}}} \newcommand{\OutputChannelIndex}{k} \newcommand{\OutputComponentFunction}{h} \newcommand{\OutputDimension}{p} \newcommand{\OutputFeatureMapHeight}{H_{\text{out}}} \newcommand{\OutputFeatureMapWidth}{W_{\text{out}}} \newcommand{\OutputIndex}{\ell} \newcommand{\OutputLayerBiasVector}{\mathbf{b}_{\text{out}}} \newcommand{\OutputLayerWeightMatrix}{\mathbf{W}_{\text{out}}} \newcommand{\OutputLength}{K} \newcommand{\OutputLengthStandardDeviation}{\sigma} \newcommand{\OutputLimit}{K_{\max}} \newcommand{\OutputLogit}{z} \newcommand{\OutputNodeAdjoint}{\bar{v}_W} \newcommand{\OutputNodePrimal}{v_W} \newcommand{\OutputProjectionOperations}{O_{\text{out}}} \newcommand{\OutputQuantizationScale}{s_Y} \newcommand{\OutputRelativeDegree}{r} \newcommand{\OutputToken}{y} \newcommand{\OutputTokenPrefix}{y_{<t}} \newcommand{\OutputTokenPrice}{c_{\text{out}}} \newcommand{\OutputTokenSequence}{y_{1:K}} \newcommand{\OutputTorqueCeiling}{\tau_{\text{out,max}}} \newcommand{\OutstandingItemCount}{N_{\text{out}}} \newcommand{\OverheadCameraEmbedding}{\mathbf{e}_{\text{overhead}}} \newcommand{\OverlappedBackwardCommunicationTime}{T_{\text{pipelined}}} \newcommand{\OverlappedTime}{T_{\text{overlap}}} \newcommand{\OverlappingGaussianSet}{\mathcal{N}} \newcommand{\OversubscriptionRatio}{R} \newcommand{\OwnershipAcquisitionTime}{T_{\text{own}}} \newcommand{\PackageDecouplingCapacitance}{C_{\text{pkg}}} \newcommand{\PackageInductance}{L_{\text{pkg}}} \newcommand{\PackageResistance}{R_{\text{pkg}}} \newcommand{\PackageThermalCapacitance}{C_{\text{th}}} \newcommand{\PackageThermalTimeConstant}{\tau_{\text{th}}} \newcommand{\PackedExampleIndex}{k} \newcommand{\PackedExampleLength}{s} \newcommand{\PackedExampleOffset}{b} \newcommand{\PacketBuffer}{b} \newcommand{\PaddingWasteFraction}{W} \newcommand{\PageRankDampingFactor}{d} \newcommand{\PageRankScoreVector}{\mathbf{r}} \newcommand{\PairedAcceptanceDifference}{\Delta} \newcommand{\PairedDifferenceLowerLimit}{L_{\Delta}} \newcommand{\PairedDifferenceUpperLimit}{U_{\Delta}} \newcommand{\PairedOutcomeCellCount}{n} \newcommand{\PairedRandomVariable}{Y} \newcommand{\PairedTaskIndex}{j} \newcommand{\PairedTimeInstant}{s} \newcommand{\PairedVerdictCorrelation}{\hat{\phi}} \newcommand{\PairingLagCeiling}{\Delta t_{\text{lag,max}}} \newcommand{\PairwiseCoordinationCoefficient}{\beta_{\text{pair}}} \newcommand{\PairwiseMaskSecret}{\mathbf{s}} \newcommand{\ParallelEnvironmentCount}{n_{\text{env}}} \newcommand{\ParallelFraction}{f_{\text{parallel}}} \newcommand{\ParallelLoopCount}{k_{\text{parallel}}} \newcommand{\ParallelRigCount}{N_{\text{rig}}} \newcommand{\ParameterPayload}{M_{\text{param}}} \newcommand{\ParameterRandomizationRanges}{\mathcal{P}} \newcommand{\ParameterScaleCoefficient}{A} \newcommand{\ParameterScalingExponent}{\alpha} \newcommand{\ParameterServerCount}{K_{\text{srv}}} \newcommand{\ParameterSpace}{\Theta} \newcommand{\ParameterSpaceDirection}{u} \newcommand{\ParameterStreamingTime}{t_{\text{stream}}} \newcommand{\ParameterVelocity}{\dot{\theta}} \newcommand{\ParameterizedPredictor}{f_{\theta}} \newcommand{\Parameters}{P} \newcommand{\ParametricProposalDistribution}{q_{\boldsymbol{\psi}}} \newcommand{\ParasiticLoopInductance}{L_{\text{parasitic}}} \newcommand{\ParentCapabilityGrant}{\Gamma_{\text{parent}}} \newcommand{\ParentFreeBalance}{F_{P}} \newcommand{\ParentNodeIndex}{k} \newcommand{\ParentReservedFunds}{R_{P}} \newcommand{\ParentSettledCharges}{E_{P}} \newcommand{\ParetoMinimumDemand}{x_{\min}} \newcommand{\ParetoTailExponent}{\alpha_{\text{tail}}} \newcommand{\ParetoTaskDemand}{X} \newcommand{\ParticipatingClientCount}{N_{\text{clients}}} \newcommand{\PartnerBitIndex}{k} \newcommand{\PassAtKEstimate}{\widehat{\operatorname{pass@}k}} \newcommand{\PassedTrialCount}{N_{\text{pass}}} \newcommand{\PassingRunCount}{s} \newcommand{\PassingSampleCount}{c} \newcommand{\PassiveModelPrediction}{\hat{Y}} \newcommand{\PastSynchronizationStepIndex}{j} \newcommand{\PatchColumnIndex}{w} \newcommand{\PatchRowIndex}{h} \newcommand{\PatchTokenCount}{N} \newcommand{\PathAcceleration}{\ddot{s}} \newcommand{\PathAccelerationInput}{u} \newcommand{\PathAccelerationLowerBound}{\ddot{s}_{\min}} \newcommand{\PathAccelerationTorqueCoefficient}{\mathbf{a}_{\tau}} \newcommand{\PathAccelerationUpperBound}{\ddot{s}_{\max}} \newcommand{\PathCoordinate}{s} \newcommand{\PathDelayAsymmetry}{\Delta t_{\text{asym}}} \newcommand{\PathGridPointCount}{N_{\text{grid}}} \newcommand{\PathVelocity}{\dot{s}} \newcommand{\PathVelocitySquaredTorqueCoefficient}{\mathbf{b}_{\tau}} \newcommand{\PayloadGravityTorque}{\tau_{g}} \newcommand{\PayloadLeverArm}{r} \newcommand{\PcieLinkFailureRate}{\lambda_{\text{PCIe}}} \newcommand{\PdnBranchCurrent}{I_{\text{branch}}} \newcommand{\PdnBranchResistance}{R_{\text{PDN}}} \newcommand{\PdnTargetImpedance}{Z_{\text{target}}} \newcommand{\PeakBridgeJerk}{j_{\text{peak}}} \newcommand{\PeakContactForce}{F_{\text{peak}}} \newcommand{\PeakCopperLossPower}{P_{\text{peak}}} \newcommand{\PeakCurrent}{I_{\text{peak}}} \newcommand{\PeakMemoryBandwidth}{\text{BW}_{\text{peak}}} \newcommand{\PeakPenetrationDepth}{\delta_{\max}} \newcommand{\PeakRate}{R_{\text{peak}}} \newcommand{\PeakRegenerativePower}{P_{\text{regen, peak}}} \newcommand{\PeakRotorAngularSpeed}{\omega_{\max}} \newcommand{\PeakSlipRatio}{\lambda_{\text{peak}}} \newcommand{\PeakStopDeceleration}{a_{\text{peak}}} \newcommand{\PeakTorque}{\tau_{\text{peak}}} \newcommand{\PeakTractionCoefficient}{\mu_{\text{peak}}} \newcommand{\PearsonFitStatistic}{\chi^2} \newcommand{\PeerReviewerIndex}{i} \newcommand{\PeerToolCallIndex}{j} \newcommand{\PenaltyContactDamping}{c} \newcommand{\PenaltyContactStiffness}{k_{\text{pen}}} \newcommand{\PenaltyPenetrationDepth}{\delta_{\text{pen}}} \newcommand{\PenaltyRestitutionDuration}{\Delta t_{\text{res}}} \newcommand{\PendulumNaturalFrequency}{\omega_0} \newcommand{\PenetrationDepth}{\delta} \newcommand{\PenetrationRate}{\dot{\delta}} \newcommand{\PenultimateLayerWidth}{n_{N_L-1}} \newcommand{\PerDeviceComputeTime}{T_{\text{compute,local}}} \newcommand{\PerDeviceWeightReadTime}{T_{\text{read}}} \newcommand{\PerExperimentComputeCost}{C_{\text{compute,per-exp}}} \newcommand{\PerExperimentEngineeringCost}{C_{\text{engineer,per-exp}}} \newcommand{\PerFrameDetectionProbability}{p_{\text{frame}}} \newcommand{\PerGpuNetworkFailureRate}{\lambda_{\text{network/GPU}}} \newcommand{\PerGpuPowerFailureRate}{\lambda_{\text{power/GPU}}} \newcommand{\PerGpuTotalFailureRate}{\lambda_{\text{total/GPU}}} \newcommand{\PerStepCostBound}{C_{\max}} \newcommand{\PerStepErrorRate}{\epsilon} \newcommand{\PerStreamTokenRate}{R} \newcommand{\PerTaskRunCount}{R} \newcommand{\PerTestSignificanceLevel}{\alpha_{\text{sig}}'} \newcommand{\PerTokenDecodeTime}{t_{\text{decode}}} \newcommand{\PerTokenKlEstimate}{\hat{\mathcal{D}}} \newcommand{\PerTokenMaskingTime}{t_{\text{mask}}} \newcommand{\PerTokenPrefillTime}{t_{\text{prefill}}} \newcommand{\PerWorkerBatchSize}{B_{\text{per-worker}}} \newcommand{\PerceptionDepthCovariance}{\boldsymbol{\Sigma}_{\text{depth}}} \newcommand{\PerceptionDispatchTime}{t_{\text{IPC}}} \newcommand{\PerceptionErrorScale}{\epsilon_{\text{scale}}} \newcommand{\PeriodicPeakWindingTemperature}{T_{\text{peak}}} \newcommand{\PeriodicTaskCount}{n} \newcommand{\PermanentMagnetFluxLinkage}{\lambda_{\text{pm}}} \newcommand{\PermissionLoopPeriod}{T_{\text{tick}}} \newcommand{\PermissionPathKernel}{G_\kappa} \newcommand{\PermissionPathParameters}{\kappa} \newcommand{\PermissionTickWaitTime}{t_{\text{wait}}} \newcommand{\PermissionTickWcet}{T_{\text{wcet}}} \newcommand{\PermittedActions}{\mathcal{A}_{\text{perm}}} \newcommand{\PermittedUsePassProbability}{p_{\text{use}}} \newcommand{\PersonApproachTravel}{S_h} \newcommand{\PersonPositionUncertainty}{Z_d} \newcommand{\PersonalizationPenaltyWeight}{\lambda_{\text{reg}}} \newcommand{\PersonalizationVector}{\mathbf{p}} \newcommand{\PerturbationNoiseStandardDeviation}{\sigma} \newcommand{\PerturbationNormOrder}{p} \newcommand{\PerturbedPose}{\mathbf{T}'} \newcommand{\PerturbedSignalDimension}{D} \newcommand{\PerturbedSignalVector}{\mathbf{x}} \newcommand{\PfcWatchdogTimeout}{T_{\text{watchdog}}} \newcommand{\PhaseInductance}{L_{\text{phase}}} \newcommand{\PhaseJoulePower}{P_{\text{phase}}} \newcommand{\PhaseMargin}{\Phi_m} \newcommand{\PhaseResistance}{R_{\text{phase}}} \newcommand{\PhotodiodeQuantumEfficiency}{\eta_{\text{QE}}} \newcommand{\PhysicalPlantDynamics}{f_{\text{real}}} \newcommand{\PhysicalRestoreTime}{t_{\text{physical\_restore}}} \newcommand{\PhysicalReturnLevel}{z_{T, \text{real}}} \newcommand{\PhysicalStateTrajectory}{s_{\text{real}}} \newcommand{\PhysicalStlRobustness}{\rho_{\text{real}}} \newcommand{\PhysicalTrajectorySet}{\mathcal{S}_{\text{real}}} \newcommand{\PhysicalWorldState}{s} \newcommand{\PidDerivativeGain}{K_d} \newcommand{\PidIntegralGain}{K_i} \newcommand{\PidProportionalGain}{K_p} \newcommand{\PidProportionalGainMatrix}{\mathbf{K}_p} \newcommand{\PipelineBubbleFraction}{b_{\text{pipe}}} \newcommand{\PipelineBufferMemory}{M_{\text{required}}} \newcommand{\PipelineClockSkew}{t_{\text{skew}}} \newcommand{\PipelineFlushDelay}{t_{\text{hw\_pipe}}} \newcommand{\PipelineIterationTime}{T_{\text{iteration}}} \newcommand{\PipelineParallelDegree}{N_{\text{PP}}} \newcommand{\PipelineTimeSlot}{t} \newcommand{\PipelinedExecutionTime}{T_{\text{pipelined}}} \newcommand{\PistonArea}{A} \newcommand{\PixelColumnCoordinate}{u} \newcommand{\PixelLastEventTime}{t_{\text{last}}} \newcommand{\PixelOpacityContribution}{\alpha'} \newcommand{\PixelRowCoordinate}{v} \newcommand{\PixelRowStandardDeviation}{\sigma_v} \newcommand{\PixelStandardDeviation}{\sigma_u} \newcommand{\PlaintextInput}{m} \newcommand{\PlanAction}{a} \newcommand{\PlanarHomographyMatrix}{\mathbf{H}} \newcommand{\PlanarPositionEmbedding}{\mathbf{E}_{\text{pos}}^{2D}} \newcommand{\PlanarSpecialEuclideanGroup}{SE(2)} \newcommand{\PlanckConstant}{h} \newcommand{\PlanningOperator}{o} \newcommand{\PlanningStageLatency}{T_{\text{plan}}} \newcommand{\PlanningStartInstant}{t_{\text{plan}}} \newcommand{\PlantDynamicsFunction}{\mathbf{f}} \newcommand{\PlantDynamicsParameters}{\theta_{\text{plant}}} \newcommand{\PlantOutcomeFunction}{g} \newcommand{\PlantParameters}{m} \newcommand{\PlantStateAcceleration}{\ddot{\mathbf{x}}} \newcommand{\PlantStateComponentCount}{N_s} \newcommand{\PlantStateDimension}{n} \newcommand{\PlantStateRate}{\dot{\mathbf{x}}} \newcommand{\PlantStateSpace}{\mathcal{X}} \newcommand{\PlantTransitionDensity}{p_m} \newcommand{\PlantTransitionKernel}{\mathcal{T}} \newcommand{\PlatformResourceCapacity}{\text{Cap}} \newcommand{\PlatformResourceIndex}{i} \newcommand{\PlatformTotalCost}{C_{\text{platform}}} \newcommand{\PlatformUtilization}{U_{\text{platform}}} \newcommand{\PointClearanceMargin}{d_{\text{margin}}} \newcommand{\PointToPointMessageSize}{n} \newcommand{\PointToPointTransferTime}{T} \newcommand{\PoisonedModel}{f_{\mathcal{S} \cup \mathcal{S}_{\text{poison}}}} \newcommand{\PoisoningDataset}{\mathcal{S}_{\text{poison}}} \newcommand{\PoisoningTargetDataset}{\mathcal{S}_{\text{test}}} \newcommand{\PoissonSubintervalCount}{n} \newcommand{\Policy}{\pi_\theta} \newcommand{\PolicyAction}{a} \newcommand{\PolicyActionStandardDeviation}{\sigma^{\pi}} \newcommand{\PolicyActionWindow}{\mathbf{A}_{t:t+H-1}} \newcommand{\PolicyCheckpoint}{v} \newcommand{\PolicyEnsembleCovariance}{\boldsymbol{\Sigma}_{\pi}} \newcommand{\PolicyEntropy}{\mathcal{H}} \newcommand{\PolicyGaussianMean}{\boldsymbol{\mu}_{\theta}} \newcommand{\PolicyGaussianMeanComponent}{\mu^{\pi}} \newcommand{\PolicyGaussianStandardDeviation}{\boldsymbol{\sigma}_{\theta}} \newcommand{\PolicyGradientBaseline}{b} \newcommand{\PolicyGradientEstimate}{\widehat{g}} \newcommand{\PolicyHistoryActionReturn}{Q^{\pi}} \newcommand{\PolicyHistoryAdvantage}{A^{\pi}} \newcommand{\PolicyImitationLoss}{\mathcal{L}_{\text{policy}}} \newcommand{\PolicyLipschitzBound}{L_{\text{lip}}} \newcommand{\PolicyObservedState}{s} \newcommand{\PolicyPassRate}{f} \newcommand{\PolicyProbabilityRatio}{\rho} \newcommand{\PolicyRemainingReturn}{V^{\pi}} \newcommand{\PolicyRequestLength}{S_{\pi}} \newcommand{\PolicyStateActionDistribution}{\rho_{\pi_\theta}} \newcommand{\PolicyTrajectoryDistribution}{p_\theta} \newcommand{\PolicyTti}{T_{\text{TTI}}} \newcommand{\PolicyUpdateStepTime}{T_{\text{step}}} \newcommand{\PolyakAveragingCoefficient}{\tau} \newcommand{\PolynomialCoefficientVector}{\mathbf{a}} \newcommand{\PolynomialTrajectoryCoefficient}{a} \newcommand{\PomdpActionSet}{\mathsf{A}} \newcommand{\PomdpObservationFunction}{\mathsf{O}} \newcommand{\PomdpObservationSet}{\Omega} \newcommand{\PomdpRewardFunction}{\mathsf{R}} \newcommand{\PomdpStateSpace}{\mathsf{S}} \newcommand{\PomdpTransitionFunction}{\mathsf{T}} \newcommand{\PoolResidentMemory}{M_{\text{pool}}} \newcommand{\PooledAcceptanceProbability}{\bar{p}} \newcommand{\PooledConversionRate}{\hat{p}} \newcommand{\PooledSampleApprovalRate}{\hat{p}} \newcommand{\PopulationStabilityBinCount}{n_{\text{bins}}} \newcommand{\PopulationStabilitySmoothingConstant}{\epsilon_{\text{smooth}}} \newcommand{\PortCycleNetEnergy}{\Delta E} \newcommand{\PortEffort}{\mathbf{F}} \newcommand{\PortFlow}{\dot{\mathbf{x}}} \newcommand{\PortInput}{\mathbf{u}} \newcommand{\PortOutput}{\mathbf{y}} \newcommand{\PortStoredEnergy}{E} \newcommand{\PortVelocity}{v} \newcommand{\Pose}{\mathbf{T}} \newcommand{\PoseTwistPerturbation}{\boldsymbol{\epsilon}} \newcommand{\PoseTwistPerturbationMatrix}{\hat{\boldsymbol{\epsilon}}} \newcommand{\PositionComponent}{p} \newcommand{\PositionConfidenceEllipsoidRadius}{\chi_{3,0.95}} \newcommand{\PositionErrorBound}{E} \newcommand{\PositionErrorCeiling}{e_{\max}} \newcommand{\PositionErrorCovariance}{\mathbf{P}_{pp}} \newcommand{\PositionErrorEnvelope}{e} \newcommand{\PositionLossMask}{m} \newcommand{\PositionUncertaintyRadius}{r} \newcommand{\PositionalTaskTolerance}{r_{\text{tol}}} \newcommand{\PositiveClassInput}{x_{+}} \newcommand{\PositiveIntegerExponent}{n} \newcommand{\PostContactDrivenStroke}{\Delta x_{\text{driven}}} \newcommand{\PostImpactNormalVelocity}{v_n^+} \newcommand{\PostRevocationDelay}{\tau_{\text{rev}}} \newcommand{\PosteriorCovarianceMatrix}{\boldsymbol{\Sigma}_{\text{post}}} \newcommand{\PosteriorDifferentialEntropy}{h_{\text{post}}} \newcommand{\PostprocessingLatency}{L_{\text{lat,post}}} \newcommand{\PotentialOutcome}{Y^{\text{pot}}} \newcommand{\PowerCriticalQuantile}{z_{\beta}} \newcommand{\PowerLimitBase}{a} \newcommand{\PowerRailInductance}{L_{\text{bus}}} \newcommand{\PowerRailResistance}{R_{\text{bus}}} \newcommand{\PoweredHoldCommand}{\mathbf{u}_{\text{hold}}} \newcommand{\PoweredHoldState}{\mathbf{x}_{\text{hold}}} \newcommand{\PoweredServerCount}{N} \newcommand{\PpoClippedSurrogateObjective}{\mathcal{L}^{\text{CLIP}}} \newcommand{\PqApproximateDistance}{\tilde{d}} \newcommand{\PqCentroidCode}{c^{\text{pq}}} \newcommand{\PqSubspaceIndex}{j} \newcommand{\PqSubvectorCount}{m} \newcommand{\PreForwardEnvironmentState}{\sigma_0} \newcommand{\PreImpactNormalVelocity}{v_n^-} \newcommand{\PreImpactSeparationDistance}{d_{\text{sep}}} \newcommand{\PrePivotCatchRate}{v} \newcommand{\PreTriggerWindowDuration}{T_{\text{pre}}} \newcommand{\PreactivationMatrix}{\mathbf{Z}} \newcommand{\PreactivationVector}{\mathbf{z}} \newcommand{\PrebrakeDelay}{\tau_{\text{delay}}} \newcommand{\PrebrakeDelayCeiling}{\tau_{\text{delay},\max}} \newcommand{\PredecessorGraphVertex}{u} \newcommand{\PredicateLipschitzConstant}{L_{\phi}} \newcommand{\PredicateNormalizationScale}{c} \newcommand{\PredictedActionComponent}{\hat{a}} \newcommand{\PredictedClassProbability}{p} \newcommand{\PredictedConfidence}{\hat{p}} \newcommand{\PredictedDecision}{\hat{Y}} \newcommand{\PredictedEnvironmentLatent}{\hat{\mathbf{z}}} \newcommand{\PredictedErrorCovariance}{\mathbf{P}_{k|k-1}} \newcommand{\PredictedForceReading}{\hat{y}} \newcommand{\PredictedOutput}{\hat{\mathbf{y}}} \newcommand{\PredictedOutputComponent}{\hat{y}} \newcommand{\PredictedPolicyAction}{\hat{\mathbf{a}}} \newcommand{\PredictedProtectedAttribute}{\hat{a}} \newcommand{\PredictedRelativeDepth}{z_{\text{pred}}} \newcommand{\PredictedStateEmbedding}{\mathbf{e}_{\text{state}}} \newcommand{\PredictedStateEstimate}{\hat{\mathbf{x}}_{k|k-1}} \newcommand{\PredictionHeadFunction}{g} \newcommand{\PredictionStepIndex}{i} \newcommand{\PredictiveEntropy}{H_{\text{pred}}} \newcommand{\PreemptionFanoutCount}{k} \newcommand{\PreemptionRate}{\lambda_{\text{preempt}}} \newcommand{\PreemptionTaxTime}{T_{\text{preempt}}} \newcommand{\PreferenceMargin}{z} \newcommand{\PreferencePairDataset}{\mathcal{D}} \newcommand{\PreferenceScale}{\beta} \newcommand{\PreferenceScoredPositionSet}{\mathcal{A}} \newcommand{\PreferredReferenceRelativeScore}{\Delta_w} \newcommand{\PreferredTrajectory}{\tau_w} \newcommand{\PrefetchBufferCount}{N_{\text{prefetch}}} \newcommand{\PrefillAllocatedTokenCount}{C} \newcommand{\PrefillArithmeticIntensity}{I_{\text{prefill}}} \newcommand{\PrefillChunkSize}{C_{\text{chunk}}} \newcommand{\PrefillOperations}{O_{\text{prefill}}} \newcommand{\PrefillRequestIndex}{i} \newcommand{\PrefillTime}{T_{\text{prefill}}} \newcommand{\PrefixHitRate}{\rho_{\text{prefix}}} \newcommand{\PregraspPosition}{\mathbf{p}_{\text{pre}}} \newcommand{\PreprocessingLatency}{L_{\text{lat,pre}}} \newcommand{\PreprocessingServiceTime}{T_{\text{preprocessing}}} \newcommand{\PreprocessingThroughput}{R_{\text{preprocessing}}} \newcommand{\PresaturationTorqueCommand}{\boldsymbol{\tau}_{\text{cmd}}} \newcommand{\PreviousLayerWidth}{n_{\ell-1}} \newcommand{\PreviousPeriodCost}{C_{\text{previous}}} \newcommand{\PreviousRangeObservationHistory}{z_{1:t-1}} \newcommand{\PreviousUpdatedErrorCovariance}{\mathbf{P}_{k-1|k-1}} \newcommand{\PreviousUpdatedStateEstimate}{\hat{\mathbf{x}}_{k-1|k-1}} \newcommand{\PrimitiveOperation}{\phi} \newcommand{\PrincipalPointColumn}{c_x} \newcommand{\PrincipalPointRow}{c_y} \newcommand{\PriorCovarianceMatrix}{\boldsymbol{\Sigma}_{\text{prior}}} \newcommand{\PriorDifferentialEntropy}{h_{\text{prior}}} \newcommand{\PriorStandardDeviation}{\sigma_0} \newcommand{\PriorTurnCount}{j} \newcommand{\PrivacyAdditiveSlack}{\delta} \newcommand{\PrivacyBudget}{\epsilon} \newcommand{\PrivacyLossVariable}{\mathcal{L}_{\text{priv}}} \newcommand{\PrivacyNoiseMultiplier}{\sigma} \newcommand{\PrivatizedQuery}{\tilde{f}} \newcommand{\PrivilegeTrapTime}{T_{\text{trap}}} \newcommand{\PrivilegedSimulatorState}{s_{\text{priv}}} \newcommand{\PrivilegedStateDimension}{d_{\text{priv}}} \newcommand{\PrivilegedStateEncoder}{E} \newcommand{\ProbabilityFunction}{p} \newcommand{\ProbabilitySimplex}{\Delta} \newcommand{\ProbedCellCount}{n_{\text{probe}}} \newcommand{\ProcessConditionCheckTime}{T_{\text{proc}}} \newcommand{\ProcessConditionPassProbability}{p_{\text{proc}}} \newcommand{\ProcessNoiseCovariance}{\mathbf{Q}} \newcommand{\ProcessNoiseIntensity}{\mathbf{Q}} \newcommand{\ProcessNoiseVector}{\mathbf{w}} \newcommand{\ProcessedDataVolume}{D_{\text{vol,processed}}} \newcommand{\ProcessedSampleCount}{N_{\text{samples}}} \newcommand{\ProcessingBufferCount}{N_{\text{processing}}} \newcommand{\ProcessingPrice}{R_{\text{process/GB}}} \newcommand{\ProductFactorIndex}{j} \newcommand{\ProductionExecutionCount}{N_{\text{prod}}} \newcommand{\ProductionModelCount}{N_{\text{models}}} \newcommand{\ProductionOnlyFailureCount}{n_{\text{prod}}} \newcommand{\ProfileAccelerationBound}{a_{\max}} \newcommand{\ProfileJerk}{\dot{a}} \newcommand{\ProgramGoodput}{\eta_{\text{program}}} \newcommand{\ProgramInvariantPredicate}{P} \newcommand{\ProgramState}{s} \newcommand{\ProgramStateSpace}{\Sigma} \newcommand{\ProjectedSeamState}{\hat{\mathbf{x}}_{\text{seam}}} \newcommand{\ProjectedTrajectoryRecord}{R} \newcommand{\ProjectedTurnGradientContribution}{Z} \newcommand{\ProjectionBallRadius}{\epsilon} \newcommand{\ProjectionConstraintSet}{\mathcal{C}} \newcommand{\ProjectiveDistanceSample}{s} \newcommand{\ProjectiveRayScale}{\lambda} \newcommand{\ProjectiveScaleFactor}{s} \newcommand{\PromotedFusionInputRank}{r'} \newcommand{\PromptLength}{S_{\text{prompt}}} \newcommand{\PromptToken}{x} \newcommand{\PromptTokensSent}{S_{\text{sent}}} \newcommand{\PropagatedPositionStandardDeviation}{\sigma_p} \newcommand{\PropensityPriorApprovalShape}{a} \newcommand{\PropensityPriorRejectionShape}{b} \newcommand{\ProportionTestStatistic}{z} \newcommand{\ProportionalGainMatrix}{\mathbf{K}_{p}} \newcommand{\ProportionalPotentialEnergy}{\mathcal{L}_{\text{pos}}} \newcommand{\ProposalDeserializationTime}{t_{\text{deser}}} \newcommand{\ProposalExpiryInstant}{t_{\text{valid}}} \newcommand{\ProposalFirstWaypoint}{\mathbf{a}_0} \newcommand{\ProposalLinkTransportTime}{t_{\text{link}}} \newcommand{\ProposalParameterVector}{\boldsymbol{\psi}} \newcommand{\ProposalPayload}{\mathcal{P}} \newcommand{\ProposedAccess}{r} \newcommand{\ProposedContactForce}{F_{\text{nom}}} \newcommand{\ProposedEndEffectorPoseSequence}{\mathbf{X}_{1:H}} \newcommand{\ProposedGripperCommandSequence}{\mathbf{g}_{1:H}} \newcommand{\ProposedJointPositionSequence}{\mathbf{Q}_{1:H}} \newcommand{\ProposedJointVelocitySequence}{\dot{\mathbf{Q}}_{1:H}} \newcommand{\ProposedOperation}{o} \newcommand{\ProposerConfidenceScore}{\hat{p}} \newcommand{\ProposerEvaluationRate}{f} \newcommand{\ProposerInferenceTime}{t_{\text{infer}}} \newcommand{\ProprioceptiveInputSpace}{\mathcal{X}} \newcommand{\ProprioceptiveInputVector}{\mathbf{x}} \newcommand{\ProprioceptiveTokenEmbeddings}{\mathbf{z}_{\text{proprio}}} \newcommand{\ProtectedAttribute}{a} \newcommand{\ProtectedGroupMembership}{G} \newcommand{\ProtectedTrainingRecord}{R} \newcommand{\ProtectionSwitchResistance}{R_{\text{switch}}} \newcommand{\ProtectiveClearanceMargin}{\delta_{\text{margin}}} \newcommand{\ProtectiveSeparationDistance}{S_p} \newcommand{\ProtectiveSpringStiffness}{k_{\text{spring}}} \newcommand{\ProtectiveSpringTravel}{\delta} \newcommand{\ProxyTrajectoryReward}{\hat{R}} \newcommand{\PrunedWeightMatrix}{\hat{\mathbf{W}}} \newcommand{\PruningMask}{\mathbf{M}} \newcommand{\PruningMaskEntry}{M_{i,j}} \newcommand{\PruningThreshold}{\delta_{\text{prune}}} \newcommand{\PsuMttf}{\text{MTTF}_{\text{psu}}} \newcommand{\PtpExchangeTimestamp}{t} \newcommand{\PtpForwardPathDelay}{T_{\text{prop}, M \to S}} \newcommand{\PtpHardwareTimestamp}{t_{\text{PTP}}} \newcommand{\PtpPropagationDelay}{T_{\text{prop}}} \newcommand{\PtpReversePathDelay}{T_{\text{prop}, S \to M}} \newcommand{\PublicationEpoch}{t_{\text{pub}}} \newcommand{\PufChallenge}{C} \newcommand{\PufResponse}{R} \newcommand{\PufResponseBit}{r} \newcommand{\PulseRoundTripTime}{\Delta t} \newcommand{\PureNoiseActionChunk}{\mathbf{A}^N} \newcommand{\PureTransportDelay}{T_d} \newcommand{\PwmPeriod}{T_{\text{pwm}}} \newcommand{\QuadratureAxisInductance}{L_q} \newcommand{\QuadratureAxisVoltage}{v_q} \newcommand{\QualifiedAdmissionRate}{r} \newcommand{\QualityObjective}{S_{\text{quality}}} \newcommand{\QuantileLevel}{u} \newcommand{\QuantileProbabilityLevel}{q} \newcommand{\QuantileThresholdCandidate}{x} \newcommand{\QuantizationBitWidth}{b} \newcommand{\QuantizationBlockSize}{b_{\text{block}}} \newcommand{\QuantizationScale}{s} \newcommand{\QuantizationStep}{\delta} \newcommand{\QuantizationZeroPoint}{z} \newcommand{\QuantizedGradient}{\mathbf{g}_{\text{int8}}} \newcommand{\QuantizedIntegerCode}{x_q} \newcommand{\QuantizedWeightEntry}{W_{ik}} \newcommand{\QuantizerInput}{x} \newcommand{\QuarterCycleCompressionTime}{t_{\text{peak}}} \newcommand{\QueryAxisLabel}{i} \newcommand{\QueryBlockCount}{T_r} \newcommand{\QueryBlockIndex}{i} \newcommand{\QueryBlockSize}{B_r} \newcommand{\QueryBoundaryCount}{S_{\text{eff}}} \newcommand{\QueryBufferPosition}{i} \newcommand{\QueryComponent}{q_{im}} \newcommand{\QueryPrice}{p_{\text{query}}} \newcommand{\QueryProjectionMatrix}{\mathbf{W}_{Q}} \newcommand{\QuerySensitivity}{\Delta} \newcommand{\QuerySourceMatrix}{\mathbf{X}_{Q}} \newcommand{\QueryVector}{\mathbf{q}} \newcommand{\QueryWord}{q} \newcommand{\QueryWordDocumentFrequency}{n} \newcommand{\QueryWordFrequency}{f} \newcommand{\QueryWorkspaceGeneration}{g_q} \newcommand{\QueueArrivalTime}{t_{\text{arr}, i}} \newcommand{\QueueServerCount}{c} \newcommand{\QueueServiceVariationCoefficient}{c_{s}} \newcommand{\QueueSystemCapacity}{K} \newcommand{\QueueWaitTime}{W_{q}} \newcommand{\QueuedJobCount}{N_{\text{queue}}} \newcommand{\QueuedTransactionBytes}{D_{\text{vol}}} \newcommand{\QueuedTransactionCount}{K} \newcommand{\QueuedTransactionSet}{\mathcal{Q}} \newcommand{\QueueingLatency}{L_{\text{lat,queue}}} \newcommand{\QuiescentJunctionTemperature}{T_{\text{j},\text{target}}} \newcommand{\QuiescentSocPower}{P_{\text{base}}} \newcommand{\QuinticBlendCoefficient}{\mathbf{a}} \newcommand{\QuotaReductionSensitivity}{\gamma_{\text{rate}}} \newcommand{\RadarRangeResolution}{\Delta R} \newcommand{\RadialBasisKernelCoefficient}{\gamma} \newcommand{\RadialDistortionCoefficient}{k} \newcommand{\RadialRange}{R} \newcommand{\RadialRangeStandardDeviation}{\sigma_R} \newcommand{\RadiationWavelength}{\lambda} \newcommand{\RailVoltageTolerance}{\delta_{\text{tol}}} \newcommand{\RandomEnvironmentState}{S} \newcommand{\RandomRetainedElementCount}{K_{\text{rand}}} \newcommand{\RandomSampleCollectionSize}{D_{\text{eval,total}}} \newcommand{\RandomVectorDimension}{d} \newcommand{\RandomizationClusterCount}{K} \newcommand{\RandomizedMechanism}{\mathcal{M}} \newcommand{\RandomizedSmoothingNoise}{\boldsymbol{\delta}} \newcommand{\RangeObservation}{z} \newcommand{\RangeObservationHistory}{z_{1:t}} \newcommand{\RankComponentIndex}{s} \newcommand{\RankConstrainedMatrix}{\mathbf{A}} \newcommand{\RankContribution}{x} \newcommand{\RankCountBinaryExponent}{m} \newcommand{\RankFusionSmoothingConstant}{k_{\text{rrf}}} \newcommand{\RankIndex}{i} \newcommand{\RankReductionResult}{y} \newcommand{\RankingFunction}{V} \newcommand{\RatedActuatorTorque}{\tau_{\text{rated}}} \newcommand{\RatedCurrentEquilibriumTemperature}{T_{\text{eq}}} \newcommand{\RatedFatigueLife}{L_{10}} \newcommand{\RatedJointTorque}{\boldsymbol{\tau}_{\text{rated}}} \newcommand{\RatingCategory}{y} \newcommand{\RatioClippingWidth}{\epsilon_{\text{clip}}} \newcommand{\RationaleTokens}{z} \newcommand{\RawClearanceBarrierFunction}{h_{\text{raw}}} \newcommand{\RawDataUploadEnergy}{E_{\text{raw}}} \newcommand{\RawHardwareFaultRate}{\lambda_{\text{raw}}} \newcommand{\RawPipelineInput}{x} \newcommand{\RawRecordCount}{N} \newcommand{\RawSensoryData}{\mathbf{S}} \newcommand{\RayReturnRange}{r_{\text{hit}}} \newcommand{\RayStepCount}{N_{\text{steps}}} \newcommand{\RayTraversalLength}{d_{\text{ray}}} \newcommand{\RayVoxelRange}{r_{\text{voxel}}} \newcommand{\RayleighDissipationFunction}{\mathcal{D}} \newcommand{\ReachabilityCostate}{\mathbf{p}} \newcommand{\ReachabilityHamiltonian}{\mathcal{H}} \newcommand{\ReachabilityHorizonInstant}{t'} \newcommand{\ReachabilityLevelFunction}{V} \newcommand{\ReachabilityTerminalTime}{T} \newcommand{\ReachableArtifactNode}{u} \newcommand{\ReachableDistance}{d_{\text{reach}}} \newcommand{\ReachableWorkspace}{\mathcal{W}} \newcommand{\ReadEndSequenceCount}{c_{\text{end}}} \newcommand{\ReadStartSequenceCount}{c_{\text{start}}} \newcommand{\ReadTimeCeiling}{R} \newcommand{\RealDataset}{\mathcal{S}_{\text{real}}} \newcommand{\RealTimeTaskIndex}{i} \newcommand{\RealityGapVector}{\boldsymbol{\Delta}_{\text{sim2real}}} \newcommand{\RealizedActuatorEffort}{u_{\text{act}}} \newcommand{\RealizedArrivalCount}{n} \newcommand{\RealizedDamageOutcome}{y} \newcommand{\RealizedDampingPower}{P_d} \newcommand{\RealizedDeviceComputeRate}{R} \newcommand{\RealizedFalseAlarmProbability}{\alpha_{*}} \newcommand{\RealizedMissedDegradationProbability}{\beta_{*}} \newcommand{\RealizedServiceTime}{s} \newcommand{\ReceiptSampleIndex}{t_{\text{recv}}} \newcommand{\ReceiveBandwidth}{\text{BW}_{\text{rx}}} \newcommand{\ReceiverOverhead}{o_{\text{recv}}} \newcommand{\ReceiverTimingJitter}{\sigma_{\Delta t}} \newcommand{\RecentUsageShare}{F_{\text{actual}}} \newcommand{\RecommenderItemCount}{N_{\text{items}}} \newcommand{\RecommenderUserCount}{N_{\text{users}}} \newcommand{\ReconcilableToolInterface}{\mathbb{T}_{a}} \newcommand{\ReconstructedGradient}{\hat{\mathbf{g}}} \newcommand{\ReconstructedWeight}{\hat{w}} \newcommand{\RecordAdequacyPassProbability}{p_{\text{record}}} \newcommand{\RecordSizeCeiling}{s_{\max}} \newcommand{\RecordedAuthorityState}{S_{\text{auth}}} \newcommand{\RecoveryCompletionInstant}{t_{\text{rec}}} \newcommand{\RecoveryPoseTolerance}{\epsilon_{\text{sync}}} \newcommand{\RecoveryTargetLogPosition}{j_{\text{target}}} \newcommand{\RecoveryWarmupTime}{T_{\text{warmup}}} \newcommand{\RecurrentHiddenBias}{\mathbf{b}_{\text{h}}} \newcommand{\RecurrentHiddenState}{\mathbf{h}} \newcommand{\RecurrentInputWeights}{\mathbf{W}_{\text{hx}}} \newcommand{\RecurrentOutputWeights}{\mathbf{W}_{\text{yh}}} \newcommand{\RecurrentStateWeights}{\mathbf{W}_{\text{hh}}} \newcommand{\ReduceScatterCompletionTime}{T_{\text{reducescatter}}} \newcommand{\ReducedBoundaryConditionVector}{\mathbf{b}_{\text{red}}} \newcommand{\ReducedImpactMass}{m_{\text{red}}} \newcommand{\ReducibleLoss}{\hat{\mathcal{L}}} \newcommand{\ReductionInputCount}{n} \newcommand{\RedundantComponentCount}{N_{\text{red}}} \newcommand{\RedundantReplicaCount}{k} \newcommand{\RedundantServiceAvailability}{A_{\text{system}}} \newcommand{\ReferenceActionDisadvantage}{A_t^{\pi^*}} \newcommand{\ReferenceAssessedFailure}{F} \newcommand{\ReferenceBinIndex}{b} \newcommand{\ReferenceBinProportion}{E} \newcommand{\ReferenceCostToGo}{Q_t^{\pi^*}} \newcommand{\ReferenceDisagreementProbability}{\mathcal{L}} \newcommand{\ReferenceDistribution}{p} \newcommand{\ReferenceJointAccelerations}{\ddot{\mathbf{q}}^{\text{ref}}} \newcommand{\ReferenceJointPosition}{q_{\text{reference}}} \newcommand{\ReferenceJointPositions}{\mathbf{q}^{\text{ref}}} \newcommand{\ReferenceJointVelocities}{\dot{\mathbf{q}}^{\text{ref}}} \newcommand{\ReferenceLogProbabilitySum}{\Delta_{\text{ref}}} \newcommand{\ReferenceMixingProbability}{\lambda} \newcommand{\ReferenceNextTokenDistribution}{q} \newcommand{\ReferencePosition}{\mathbf{r}} \newcommand{\ReferenceProbabilityRatio}{z} \newcommand{\ReferenceRelativeScore}{\Delta_\theta} \newcommand{\ReferenceRequestLength}{S_{\text{ref}}} \newcommand{\ReferenceSampleEmpiricalCdf}{F} \newcommand{\ReferenceStateDisagreementRate}{\epsilon_E} \newcommand{\ReferenceStateDistribution}{d_{\pi^*}} \newcommand{\ReferenceStepDisagreementRate}{\epsilon} \newcommand{\ReferenceWindingResistance}{R_0} \newcommand{\ReflectedContactForce}{F_{\text{contact}}} \newcommand{\ReflectedRotorInertia}{J_{\text{ref}}} \newcommand{\ReflectedRotorInertiaMatrix}{\mathbf{J}_m} \newcommand{\ReflectedTransmissionInputInertia}{J_{\text{ref,in}}} \newcommand{\ReflectionAngle}{\theta_{\text{refl}}} \newcommand{\ReflexCollisionBudget}{T_{\text{reflex\_budget}}} \newcommand{\RegeneratedBrakingEnergy}{E_{\text{regen}}} \newcommand{\RegenerativeBrakingTorque}{\tau_{\text{brake}}} \newcommand{\RegenerativeRecoveryEfficiency}{\eta_{\text{regen}}} \newcommand{\RegisterSetupTime}{t_{\text{setup}}} \newcommand{\RegisteredDescriptorCount}{n_{\text{reg}}} \newcommand{\RegularizedEulerIntegral}{I} \newcommand{\RejectionDecodeStep}{t_{\text{cut}}} \newcommand{\RelationalSelection}{\sigma} \newcommand{\RelativeContrastTolerance}{\epsilon_{\text{contrast}}} \newcommand{\RelativeDeviationBound}{\delta} \newcommand{\RelativeImprovementFraction}{\delta} \newcommand{\RelativeStandardError}{r} \newcommand{\RelevantRecordSet}{\mathcal{D}^*} \newcommand{\ReliabilityTargetIndex}{i} \newcommand{\ReliableDetectionFrameCount}{N_{\text{frames}}} \newcommand{\RemainingCallCount}{N_{\text{rem}}} \newcommand{\RemainingDistanceEstimate}{\hat{s}} \newcommand{\RemainingExecutionLease}{T_{\text{lease,rem}}} \newcommand{\RemainingHarmDistance}{d_{\text{rem}}} \newcommand{\RemainingIntentTime}{T_{\text{rem}}} \newcommand{\RemainingReturn}{R_{\geq k}} \newcommand{\RemainingUprightDistance}{s} \newcommand{\RemoteHardwareEfficiency}{\eta_{\text{hw,remote}}} \newcommand{\RemotePathTime}{T_{\text{remote}}} \newcommand{\RemotePeakRate}{R_{\text{peak,remote}}} \newcommand{\RenderedPixelColor}{C} \newcommand{\RenewalJitterAllowance}{T_{\text{jitter}}} \newcommand{\RenyiDivergence}{\mathcal{D}_{\alpha_{\text{R}}}} \newcommand{\RenyiOrder}{\alpha_{\text{R}}} \newcommand{\RenyiPrivacyBudget}{\epsilon_{\text{R}}} \newcommand{\RepairAttemptCost}{C_{\text{repair}}} \newcommand{\RepairCap}{K_{\text{repair}}} \newcommand{\RepairCapabilityGrant}{\Gamma_{\text{repair}}} \newcommand{\RepairFirstCost}{C_{\text{repair\ first}}} \newcommand{\RepairPatchArtifact}{P} \newcommand{\RepairSuccessProbability}{p} \newcommand{\RepairTurnLatency}{T_{\text{repair}}} \newcommand{\ReparameterizationNoise}{\boldsymbol{\epsilon}} \newcommand{\RepeatedRunCount}{k} \newcommand{\RepeatedRunMean}{\mu_{\text{run}}} \newcommand{\RepeatedRunStandardDeviation}{\sigma_{\text{run}}} \newcommand{\ReplacementLatency}{L} \newcommand{\ReplacementTimingReserve}{T_{\text{reserve}}} \newcommand{\ReplanRequestOffset}{T_{\text{request}}} \newcommand{\ReplayBuffer}{\mathcal{M}} \newcommand{\ReplayBufferTransitionCount}{n_{\text{replay}}} \newcommand{\ReplayedErrorCovariance}{\mathbf{P}_{t_{\text{recv}}}} \newcommand{\ReplayedStateEstimate}{\hat{\mathbf{x}}_{t_{\text{recv}}}} \newcommand{\ReplicaAvailability}{A_{\text{single}}} \newcommand{\ReplicaColdStartTime}{T_{\text{cold-start}}} \newcommand{\ReplicaCount}{R} \newcommand{\ReplicaModelLoadTime}{T_{\text{load}}} \newcommand{\ReplicaProvisioningTime}{T_{\text{provision}}} \newcommand{\ReplicaWarmupTime}{T_{\text{warmup}}} \newcommand{\ReplyLossProbability}{q_{\text{rep}}} \newcommand{\RepositoryEdgeSourceIndex}{i} \newcommand{\RepositoryEdgeTargetIndex}{j} \newcommand{\RepositoryEdgeWeight}{A} \newcommand{\RepositoryEdgeWeightMatrix}{\mathbf{A}} \newcommand{\RepositoryFileCount}{n} \newcommand{\RepositoryGraphEdgeSet}{E} \newcommand{\RepositoryGraphVertexSet}{V} \newcommand{\RepositoryTransitionMatrix}{\mathbf{P}_{\text{graph}}} \newcommand{\ReprojectionResidual}{\epsilon_{\text{reproj}}} \newcommand{\RepublicationIndex}{k} \newcommand{\RepublicationPeriod}{T_{\text{rep}}} \newcommand{\RequantizationScale}{s_{\text{eff}}} \newcommand{\RequestCompressionRatio}{\gamma_{\text{req}}} \newcommand{\RequestConcurrency}{Q_{\text{req}}} \newcommand{\RequestLossProbability}{q_{\text{req}}} \newcommand{\RequestOutputLength}{S} \newcommand{\RequestPromptTokens}{\mathbf{x}} \newcommand{\RequestQueueTime}{T_{\text{queue}}} \newcommand{\RequestResidenceTime}{W} \newcommand{\RequestResponseTime}{t} \newcommand{\RequestSeenBatchSize}{B_{\text{req}}} \newcommand{\RequestServiceTime}{T_{\text{svc}}} \newcommand{\RequestTimeInSystem}{T_{\text{lat}}} \newcommand{\RequestedActionTap}{a_{\text{req}}} \newcommand{\RequiredClearance}{C_{\text{safe}}} \newcommand{\RequiredComponentCount}{N} \newcommand{\RequiredDetectionRange}{d_{\text{detect}}} \newcommand{\RequiredInputBandwidth}{\text{BW}_{\text{required}}} \newcommand{\RequiredMemoryBandwidth}{\text{BW}_{\text{req}}} \newcommand{\RequiredPremiseClaim}{P} \newcommand{\RequiredPremiseConfidence}{p} \newcommand{\RequiredPremiseCount}{n} \newcommand{\RequiredResultCount}{k} \newcommand{\RequiredScenarioCellCount}{N_{\text{req}}} \newcommand{\RequiredScenarioSet}{\mathcal{S}_{\text{req}}} \newcommand{\RequiredServiceRate}{\mu_{\text{required}}} \newcommand{\RequiredTaskPairCount}{N'} \newcommand{\RequiredUsersPerVariant}{n} \newcommand{\ResampledReplacementToken}{T_4'} \newcommand{\ReservedDeviceMemory}{M_{\text{reserve}}} \newcommand{\ResetCalibrationTime}{t_{\text{calibration}}} \newcommand{\ResetDuration}{t_{\text{rst}}} \newcommand{\ResetLatency}{T_{\text{reset}}} \newcommand{\ResidentStopDistance}{d_{\text{suffix}}} \newcommand{\ResidentWeightMemory}{M_{\text{weights,resident}}} \newcommand{\ResidualAdapterFunction}{A} \newcommand{\ResidualBlockOutput}{\mathbf{y}} \newcommand{\ResidualCorrectionCeiling}{\Delta_{\max}} \newcommand{\ResidualDynamicsPerturbation}{\Delta \mathbf{f}} \newcommand{\ResidualFrequencyError}{\Delta f_{\text{res}}} \newcommand{\ResidualFunction}{\mathcal{F}} \newcommand{\ResidualGate}{g} \newcommand{\ResidualPolicyTorque}{\boldsymbol{\tau}_{\text{res},\theta}} \newcommand{\ResidualSamplingDistribution}{p_{\text{res}}} \newcommand{\ResolutionScalingRatio}{\gamma} \newcommand{\ResourceChangeRate}{r_{\text{chg}}} \newcommand{\ResourceCostBudget}{C_{\text{max}}} \newcommand{\ResourceTypeIndex}{r} \newcommand{\ResourceUtilization}{U} \newcommand{\ResponseActionTokens}{a} \newcommand{\ResponseMetadata}{\mathbf{m}} \newcommand{\ResponsePayload}{\mathbf{y}} \newcommand{\ResponseReward}{r} \newcommand{\ResponseThreshold}{\tau} \newcommand{\ResponseTimeDistributionFunction}{F} \newcommand{\ResponseTimeIterationIndex}{\ell} \newcommand{\ResponseTimeStandardDeviation}{\sigma_t} \newcommand{\RestConfiguration}{\mathbf{q}_{\text{rest}}} \newcommand{\RestitutionCoefficient}{e} \newcommand{\RestoreWorkerCount}{w} \newcommand{\RestrictedAccelerationBound}{a_{\text{restricted}}} \newcommand{\RestrictedSpeedBound}{v_{\text{restricted}}} \newcommand{\ResultActionTime}{T_{\text{action}}} \newcommand{\ResumeTime}{T_{\text{resume}}} \newcommand{\RetainedDigestCount}{m} \newcommand{\RetainedGradientElementCount}{K_{\text{top}}} \newcommand{\RetainedProductiveTime}{T_{\text{productive}}} \newcommand{\RetainedSpectralEnergyFraction}{\eta_r} \newcommand{\RetainingCallCount}{H_{\text{rem}}} \newcommand{\RetiringChunkJointVelocity}{\dot{q}_A} \newcommand{\RetiringChunkReferenceState}{\mathbf{x}_A} \newcommand{\RetrainingComputeCost}{C_{\text{compute}}} \newcommand{\RetrainingDeploymentCost}{C_{\text{deployment}}} \newcommand{\RetrainingInterval}{T} \newcommand{\RetrainingRiskCost}{C_{\text{risk}}} \newcommand{\RetrainingRunCost}{C} \newcommand{\RetrainingValidationCost}{C_{\text{validation}}} \newcommand{\RetrievalCollectionSize}{N} \newcommand{\RetrievalCutoffCount}{k} \newcommand{\RetrievalMethodIndex}{i} \newcommand{\RetrievedRecordSet}{\mathcal{R}} \newcommand{\RetryAttemptIndex}{j} \newcommand{\RetryBackoffInterval}{b} \newcommand{\RetryJitterDelay}{d} \newcommand{\ReturnLevel}{z} \newcommand{\ReturnPeriodTrialCount}{T} \newcommand{\ReturnStepOffset}{k} \newcommand{\ReturnedClassLabel}{c} \newcommand{\ReusedPrefixLength}{S_{\text{match}}} \newcommand{\ReverseModeWorkConstant}{C} \newcommand{\ReverseTransitionCovariance}{\boldsymbol{\Sigma}} \newcommand{\ReverseTransitionMean}{\boldsymbol{\mu}_\theta} \newcommand{\RevertFidelity}{\rho_{\text{revert}}} \newcommand{\ReviewerFalseApprovalIndicator}{X} \newcommand{\ReviewerIndex}{j} \newcommand{\RevisionPassProbability}{p_{\text{rev}}} \newcommand{\Reward}{r} \newcommand{\RewardFunction}{r} \newcommand{\RewardModel}{r} \newcommand{\RightEvasionAction}{\mathbf{a}_{\text{right}}} \newcommand{\RightSingularVectorMatrix}{\mathbf{Q}} \newcommand{\RigidGangJob}{J} \newcommand{\RigidImpactInstant}{t_{\text{impact}}} \newcommand{\RigidTransformTranslation}{\mathbf{t}} \newcommand{\RingAllReduceBandwidthTime}{T_{\text{bandwidth}}} \newcommand{\RingAllReduceCompletionTime}{T_{\text{ring}}} \newcommand{\RingAllReduceStartupTime}{T_{\text{latency}}} \newcommand{\RingBufferHorizon}{T_{\text{buffer}}} \newcommand{\RingBufferSlotCount}{N_{\text{buffer}}} \newcommand{\RingStepIndex}{s} \newcommand{\RingTreeCrossoverPayload}{M_{\text{crossover}}} \newcommand{\RmsMotorTorque}{\tau_{\text{rms}}} \newcommand{\RmspropSquaredGradientAverage}{s} \newcommand{\RobotAction}{\mathbf{a}} \newcommand{\RobotApproachSpeed}{v_r} \newcommand{\RobotApproachVelocity}{v_{\text{robot}}} \newcommand{\RobotObservation}{\mathbf{o}} \newcommand{\RobotPosition}{x_{\text{robot}}} \newcommand{\RobotPositionUncertainty}{Z_r} \newcommand{\RobotReactionTime}{T_r} \newcommand{\RobotReactionTravel}{S_r} \newcommand{\RobotStoppingTravel}{S_s} \newcommand{\RobotStructuralStiffness}{k_{\text{robot}}} \newcommand{\RobotTransitVolume}{\mathcal{T}_{\text{robot}}} \newcommand{\RollingShutterDistortion}{\Delta \mathbf{x}} \newcommand{\RollingShutterFrameSkew}{\Delta t_{\text{skew}}} \newcommand{\RollingShutterRowReadout}{t_{\text{row}}} \newcommand{\RolloutAction}{a} \newcommand{\RolloutActionSequence}{\mathbf{a}_{0:T}} \newcommand{\RolloutAdmissionAge}{\Delta T_{\text{rollout}}} \newcommand{\RolloutAssessmentTime}{T_{v}} \newcommand{\RolloutDuration}{T_{\text{rollout}}} \newcommand{\RolloutEnvironmentState}{s} \newcommand{\RolloutHorizon}{T} \newcommand{\RolloutLoss}{\mathcal{L}} \newcommand{\RolloutPolicyParameters}{\theta_{\text{old}}} \newcommand{\RolloutPolicyTokenCount}{N} \newcommand{\RolloutStateSequence}{s_{0:T}} \newcommand{\RolloutStepCount}{N} \newcommand{\RolloutStepIndex}{k} \newcommand{\RolloutSurrogateObjective}{\mathcal{L}} \newcommand{\RolloutTurnIndex}{k} \newcommand{\RooflineRidgePoint}{I_{\text{ridge}}} \newcommand{\RotaryRotationMatrix}{\mathbf{R}} \newcommand{\RotatingBodyAngularSpeed}{\omega} \newcommand{\RotatingBodyInertia}{J} \newcommand{\RotationOriginAcceleration}{\mathbf{a}_O} \newcommand{\RotationOriginVelocity}{\mathbf{v}_O} \newcommand{\RotationalKineticEnergy}{E_{k,\text{rot}}} \newcommand{\RotationalSpringStiffness}{K} \newcommand{\RotorAngularSpeed}{\omega_m} \newcommand{\RotorInertia}{J_{\text{rotor}}} \newcommand{\RotorPolePairCount}{N_{\text{poles}}} \newcommand{\RoundCommunicationVolume}{M_r} \newcommand{\RoundDownloadVolume}{M_{\text{download},r}} \newcommand{\RoundDuration}{t_r} \newcommand{\RoundEmittedTokenCount}{N_{\text{emit}}} \newcommand{\RoundProtocolVolume}{M_{\text{protocol},r}} \newcommand{\RoundRetryVolume}{M_{\text{retry},r}} \newcommand{\RoundSampleCount}{n_{\text{round}}} \newcommand{\RoundUploadVolume}{M_{\text{upload},r}} \newcommand{\RoundedClassProbability}{p^{\text{rnd}}} \newcommand{\RoundingDecimalCount}{d_{\text{dec}}} \newcommand{\RoutedExpertCount}{k_{\text{experts}}} \newcommand{\RouterGateProbability}{p_{\text{gate}}} \newcommand{\RowActivationDelay}{t_{\text{RCD}}} \newcommand{\RowActiveTime}{t_{\text{RAS}}} \newcommand{\RowAttitudeIncrement}{\Delta \boldsymbol{\theta}_{\text{att}}} \newcommand{\RowConflictCount}{N_{\text{conflict}}} \newcommand{\RowCycleTime}{t_{\text{RC}}} \newcommand{\RowExposureStartTime}{t_{\text{scan}}} \newcommand{\RowModeComponentVector}{\mathbf{a}_s} \newcommand{\RowModeFactorMatrix}{\mathbf{A}} \newcommand{\RowModeFactorSlice}{\mathbf{a}} \newcommand{\RowParallelOutputMatrix}{\mathbf{Z}} \newcommand{\RowParallelWeightMatrix}{\mathbf{B}} \newcommand{\RowPrechargeTime}{t_{\text{RP}}} \newcommand{\RunIndexSubset}{J} \newcommand{\RuntimeGoodput}{\eta_{\text{runtime}}} \newcommand{\RuntimeReserveMemory}{M_{\text{runtime}}} \newcommand{\SCurveAccelerationPhaseTime}{T_{\text{acc}}} \newcommand{\SafeApproachSpeedEnvelope}{v_{\text{safe}}} \newcommand{\SafeControlSet}{\mathcal{U}_{\text{safe}}} \newcommand{\SafeOverrideCommand}{\mathbf{u}_{\text{safe}}} \newcommand{\SafeSeparationDistance}{d_{\text{safe}}} \newcommand{\SafeSetProjection}{\mathcal{P}_{\mathcal{C}}} \newcommand{\SafeStateConstraintSet}{\mathcal{X}_{\text{safe}}} \newcommand{\SafeStateSet}{\mathcal{X}_{\text{safe}}} \newcommand{\SafeWorldState}{s_A} \newcommand{\SafeguardSeparationDistance}{S} \newcommand{\SafeguardStoppingTime}{T} \newcommand{\SafetyBoundaryManifold}{\partial \mathcal{C}} \newcommand{\SagaCompensatingStep}{C} \newcommand{\SagaFailedForwardStep}{F_k^{\text{fail}}} \newcommand{\SagaForwardStep}{F} \newcommand{\SagaStepIndex}{k} \newcommand{\SampleAcquisitionPrice}{c_{\text{sample}}} \newcommand{\SampleGradientStandardDeviation}{\sigma} \newcommand{\SampleLabelingPrice}{c_{\text{label}}} \newcommand{\SampleStatistic}{\widehat{\theta}} \newcommand{\SampleStorageSize}{s_{\text{sample}}} \newcommand{\SampledPolicyToken}{w} \newcommand{\SampledSimulationParameterVector}{\tilde{\boldsymbol{\xi}}} \newcommand{\SampledUnit}{y} \newcommand{\SampledUnitCount}{m} \newcommand{\SamplingParameters}{\boldsymbol{\Theta}_{\text{sample}}} \newcommand{\SamplingPeriod}{T_s} \newcommand{\SamplingRate}{f_s} \newcommand{\SamplingTemperature}{\tau_{\text{temp}}} \newcommand{\SandboxColdBootTime}{T_{\text{cold}}} \newcommand{\SaturatedJointTorque}{\boldsymbol{\tau}_{\text{act}}} \newcommand{\SavedEngineeringTime}{T_{\text{saved}}} \newcommand{\ScalarFieldSize}{k} \newcommand{\ScalarGraphFunction}{f} \newcommand{\ScalarKalmanGain}{g} \newcommand{\ScalarTrackingError}{e} \newcommand{\ScalarTrackingErrorAcceleration}{\ddot{e}} \newcommand{\ScalarTrackingErrorRate}{\dot{e}} \newcommand{\ScaleCoefficient}{A_{\mathcal{L}}} \newcommand{\ScaledBatchSize}{B_{\text{new}}} \newcommand{\ScaledJointStiffnessMatrix}{\tilde{\mathbf{K}}} \newcommand{\ScaledLearningRate}{\eta_{\text{new}}} \newcommand{\ScaledResource}{X} \newcommand{\ScaledSerialFraction}{s} \newcommand{\ScalingCurveWorkerCount}{k} \newcommand{\ScalingEfficiency}{\eta_{\text{scaling}}} \newcommand{\ScalingExponent}{\alpha_{\text{scale}}} \newcommand{\ScalingLawLoss}{\mathcal{L}} \newcommand{\ScanCapabilityGrant}{\Gamma_{\text{scan}}} \newcommand{\ScatteringCrossSection}{\sigma_s} \newcommand{\ScenarioCellRecordCount}{N_{\text{cell}}} \newcommand{\SceneRadiance}{I} \newcommand{\ScheduleFinishTime}{T_{\text{finish}}} \newcommand{\ScheduledSessionDuration}{T_{\text{sched}}} \newcommand{\SchedulingClassWeight}{w} \newcommand{\SchedulingGoodput}{\eta_{\text{scheduling}}} \newcommand{\SchedulingIntervalLength}{t} \newcommand{\ScoreNoiseStandardDeviation}{\sigma} \newcommand{\ScoreNoiseVector}{\mathbf{z}} \newcommand{\ScoreRefreshInterval}{k_{\text{refresh}}} \newcommand{\ScoredPrefixLength}{S_{\text{step}}} \newcommand{\ScoredStepCount}{J} \newcommand{\ScoredStepIndex}{j} \newcommand{\ScoredToolCall}{a} \newcommand{\ScoredToolCallCount}{N} \newcommand{\ScoringErrorStandardDeviation}{\sigma} \newcommand{\ScreenSpaceCovariance}{\boldsymbol{\Sigma}_{2D}} \newcommand{\ScreenedFeature}{x} \newcommand{\ScreenedFeatureSet}{X} \newcommand{\ScreeningMissRate}{m} \newcommand{\SeamActualAccelerations}{\ddot{\mathbf{q}}_{\text{actual}}} \newcommand{\SeamActualConfiguration}{\mathbf{q}_{\text{actual}}} \newcommand{\SeamActualVelocities}{\dot{\mathbf{q}}_{\text{actual}}} \newcommand{\SeamBlendReference}{\mathbf{s}} \newcommand{\SeamBridgeDuration}{T_{\text{blend}}} \newcommand{\SeamBridgePosition}{q_{\text{blend}}} \newcommand{\SeamInstant}{t_{\text{seam}}} \newcommand{\SeamStepTorque}{\tau_{\text{request}}} \newcommand{\SearchBranchingFactor}{b} \newcommand{\SearchDepth}{d_{\max}} \newcommand{\SearchDepthIndex}{d} \newcommand{\SearchQueryEmbedding}{\mathbf{q}} \newcommand{\SecondAdjacentCheckIndex}{b} \newcommand{\SecondAdjacentCheckPassProbability}{p_{b}} \newcommand{\SecondAdjacentCheckSlotTime}{T_{b}} \newcommand{\SecondCatalogDefinitionCount}{n_{\text{def},B}} \newcommand{\SecondCatalogDefinitionSize}{S_{B}} \newcommand{\SecondClassCoverageFloor}{b} \newcommand{\SecondClientMaskedUpdate}{\mathbf{y}_B} \newcommand{\SecondClientModelParameters}{\theta_B} \newcommand{\SecondComparedGroupLabel}{b} \newcommand{\SecondComparedItem}{j} \newcommand{\SecondFloatingPointAddend}{b} \newcommand{\SecondGroupClassificationThreshold}{\tau_{\text{thr},b}} \newcommand{\SecondGroupQualifiedFraction}{q_b} \newcommand{\SecondGroupSampleApprovalRate}{\hat{p}_b} \newcommand{\SecondGroupSampleSize}{n_b} \newcommand{\SecondJaccardSet}{\mathcal{B}} \newcommand{\SecondRankComputeTime}{T_{\text{rank}_1}} \newcommand{\SecondRaterCategoryFraction}{p_{y,2}} \newcommand{\SecondRingTraceElement}{b} \newcommand{\SecondSummandStandardDeviation}{\sigma_b} \newcommand{\SecondTwinCriticReturnEstimate}{Q_{\phi_2}} \newcommand{\SecurityLabelLattice}{\mathbb{L}} \newcommand{\SecurityLabelSet}{\mathcal{S}_{\text{lab}}} \newcommand{\SelectedActuationCommand}{\mathbf{u}_{\text{act}}} \newcommand{\SelectedDescriptorCount}{n_{\text{sel}}} \newcommand{\SelectedLayerSet}{\mathcal{S}} \newcommand{\SelectionOverheadSize}{S_{\text{sel}}} \newcommand{\SelectionScoreFunction}{f} \newcommand{\SelectionTime}{T_{\text{selection}}} \newcommand{\SelectiveAcceptanceScore}{\kappa} \newcommand{\SelfConsistencySampleCount}{k} \newcommand{\SelfWatchdogTimeout}{T_{\text{self}}} \newcommand{\SenderOverhead}{o_{\text{send}}} \newcommand{\SensingRealityGap}{\Delta_{\text{sens}}} \newcommand{\SensingStageLatency}{T_{\text{sense}}} \newcommand{\SensorErrorBound}{\epsilon} \newcommand{\SensorFeatureTokens}{\mathbf{z}_{\text{sensor}}} \newcommand{\SensorLeverArm}{\mathbf{r}_{P/O}} \newcommand{\SensorLeverArmLength}{r} \newcommand{\SensorLinkTransportTime}{t_{\text{transport}}} \newcommand{\SensorNoiseBound}{\epsilon} \newcommand{\SensorNoiseDensity}{N_{\text{IMU}}} \newcommand{\SensorNoiseStandardDeviation}{\sigma} \newcommand{\SensorObservationFunction}{g} \newcommand{\SensorPatternDictionary}{\boldsymbol{\Phi}_{\text{dict}}} \newcommand{\SensorPitchAngle}{\theta_{\text{pitch}}} \newcommand{\SensorPointAcceleration}{\mathbf{a}_P} \newcommand{\SensorPointVelocity}{\mathbf{v}_P} \newcommand{\SensorReadoutTime}{t_{\text{readout}}} \newcommand{\SensorReferenceFrame}{\mathcal{F}_{\text{sensor}}} \newcommand{\SensorRowIndex}{y} \newcommand{\SensorTraceMatrix}{\mathbf{X}} \newcommand{\SequenceCounterReading}{S} \newcommand{\SequenceIterationOperations}{c_{\text{decode}}} \newcommand{\SequenceLength}{S} \newcommand{\SequenceToken}{x} \newcommand{\SequentialAttemptIndex}{j} \newcommand{\SequentialBackwardCommunicationTime}{T_{\text{sequential}}} \newcommand{\SequentialCandidateCount}{M} \newcommand{\SequentialCostPerAcceptedTask}{C_{\text{eff,seq}}} \newcommand{\SequentialExecutionTime}{T_{\text{sequential}}} \newcommand{\SequentialLogLikelihoodRatio}{\Lambda_m} \newcommand{\SequentialTestObservation}{X} \newcommand{\SequentialTrialCount}{m} \newcommand{\SerialAutocorrelation}{\rho} \newcommand{\SerialCallCount}{n} \newcommand{\SerialFraction}{r} \newcommand{\SerialLinkClockFrequency}{f_{\text{link}}} \newcommand{\SerialReferenceTime}{T_{\text{serial}}} \newcommand{\SerializationLatency}{L_{\text{lat,serialization}}} \newcommand{\SerializedChunkVolume}{D_{\text{vol,chunk}}} \newcommand{\SerializedTrainingExample}{X} \newcommand{\SeriesComponentCount}{N_{\text{series}}} \newcommand{\SeriesElasticStiffness}{k} \newcommand{\SeriesPsuCount}{n_{\text{psu}}} \newcommand{\ServerAggregationEnergy}{E_{\text{aggregation}}} \newcommand{\ServerIndex}{i} \newcommand{\ServerPower}{P_{\text{server}}} \newcommand{\ServerRoutingWeight}{w} \newcommand{\ServiceRate}{\mu} \newcommand{\ServiceTimeStandardDeviation}{\sigma} \newcommand{\ServiceTimeVariationCoefficient}{c_{s}} \newcommand{\ServingCostPerQuery}{C_{\text{serving}}} \newcommand{\ServingEmpiricalCdf}{F_{P_t}} \newcommand{\ServingPathPredictor}{f_{\text{serve}}} \newcommand{\ServingTransformFunction}{f_{\text{serve}}} \newcommand{\ServingUtilization}{\rho_{\text{serv}}} \newcommand{\ServoFrequencyCorrection}{\Delta f} \newcommand{\SessionAttemptCount}{N_{\text{att}}} \newcommand{\SessionRequestCount}{N_{\text{session}}} \newcommand{\SetMemberPoint}{\mathbf{z}} \newcommand{\SetpointSampleIndex}{k} \newcommand{\SetpointStepInterval}{\Delta t_{\text{step}}} \newcommand{\SettledOperationCharge}{c} \newcommand{\SettledTrajectoryCost}{C} \newcommand{\SetupShareCap}{\phi} \newcommand{\ShadowOnlyFailureCount}{n_{\text{shadow}}} \newcommand{\ShannonEntropy}{H} \newcommand{\ShapedObservationSize}{S_{\text{shaped}}} \newcommand{\ShapedTotalReward}{r_{\text{total}}} \newcommand{\ShapingPotential}{\Phi} \newcommand{\ShardIndex}{s} \newcommand{\ShardReaderCount}{n_{\text{workers}}} \newcommand{\SharedBusBandwidth}{\text{BW}_{\text{bus}}} \newcommand{\SharedHardwareInterferenceDelay}{T_{\text{interf,shared}}} \newcommand{\SharedPoolWorkerCount}{N_{\text{pool}}} \newcommand{\SharedPrefixFraction}{f} \newcommand{\SharedPrefixLength}{S_{\text{prefix}}} \newcommand{\SharedPrefixRequestCount}{n_{\text{req}}} \newcommand{\ShellRelativeThickness}{\epsilon} \newcommand{\ShieldInterceptionCoverage}{c_h} \newcommand{\ShiftedMpcControlSequence}{\tilde{\mathbf{u}}_{0:N_{\text{mpc}}-1}} \newcommand{\ShiftedTestDistribution}{\mathcal{D}'} \newcommand{\ShingleLength}{w} \newcommand{\ShipDecision}{\mathbf{1}_{\text{ship}}} \newcommand{\ShootThroughCurrent}{I_{\text{shoot-through}}} \newcommand{\SiblingPolicyAction}{a'} \newcommand{\SiblingTeamAllocation}{U_{\text{allocated}}} \newcommand{\SightlineRange}{d} \newcommand{\SigmoidFunction}{\sigma} \newcommand{\SignalDimension}{n} \newcommand{\SignalHandoff}{\mathcal{H}} \newcommand{\SignalPropagationDelay}{t_{\text{prop}}} \newcommand{\SignalTrajectory}{s} \newcommand{\SignatureBandCount}{b} \newcommand{\SignificanceCriticalQuantile}{z_{1-\alpha_{\text{sig}}/2}} \newcommand{\SignificanceLevel}{\alpha} \newcommand{\SiliconThermalTimeConstant}{\tau_{\text{th,silicon}}} \newcommand{\SimplexProjection}{\Pi_{\Delta^{K-1}}} \newcommand{\SimulatedPlantDynamics}{f_{\text{sim}}} \newcommand{\SimulatedReturnLevel}{z_{T, \text{sim}}} \newcommand{\SimulatedStateTrajectory}{s_{\text{sim}}} \newcommand{\SimulatedStlRobustness}{\rho_{\text{sim}}} \newcommand{\SimulatedTrajectorySet}{\mathcal{S}_{\text{sim}}} \newcommand{\SimulatedTransportDelay}{T_{d,\text{sim}}} \newcommand{\SimulatedUnbrakedImpactForce}{F_{\text{unbraked,sim}}} \newcommand{\SimulationParameterSet}{\Xi} \newcommand{\SimulationParameterVector}{\boldsymbol{\xi}} \newcommand{\SimulatorStepFunction}{\mathbf{F}} \newcommand{\SingleAgentAcceptanceProbability}{p_{\text{single}}} \newcommand{\SingleDeviceContextLength}{S_{\text{single}}} \newcommand{\SingleDeviceRunTime}{T_1} \newcommand{\SingleJointAccelerationLimit}{\ddot{q}_{i,\max}} \newcommand{\SingleJointInertia}{M} \newcommand{\SingleJointVelocityLimit}{\dot{q}_{i,\max}} \newcommand{\SingleLinkBandwidth}{\text{BW}_{\text{link}}} \newcommand{\SingleStepImitationError}{\epsilon} \newcommand{\SingularSpectrumMatrix}{\boldsymbol{\Sigma}} \newcommand{\SisaShardCount}{K} \newcommand{\SisaTrainingShard}{S} \newcommand{\SixthHarmonicTorqueRipple}{\tau_{\text{ripple}}} \newcommand{\SkewDisplacementEnvelope}{d_{\text{skew}}} \newcommand{\SkillSelectionDistribution}{p} \newcommand{\SlaveDriveCount}{S} \newcommand{\SlaveDriveIndex}{s} \newcommand{\SlaveForwardingDelay}{t_{\text{slave},s}} \newcommand{\SlipAccelerationBound}{a_{\text{slip}}} \newcommand{\SlipRegularizationSpeed}{\epsilon_{\text{reg}}} \newcommand{\SloVector}{\mathbf{S}} \newcommand{\SlowdownPersistenceUpdateCount}{K} \newcommand{\SmallChange}{\delta} \newcommand{\SmallPerturbation}{\delta} \newcommand{\SmallestJacobianSingularNumber}{\sigma_{\min}} \newcommand{\SmallestKeySingularNumber}{\sigma_{\min(S, d_{\text{head}})}} \newcommand{\SmoothedClassifier}{g} \newcommand{\SmoothedRunnerUpProbability}{p_{B}} \newcommand{\SmoothedTargetAction}{\tilde{\mathbf{a}}'} \newcommand{\SmoothedTopClassProbability}{p_{A}} \newcommand{\SmoothingNoiseClipBound}{c} \newcommand{\SmoothingNoiseStandardDeviation}{\sigma} \newcommand{\SmoothnessConstant}{L_s} \newcommand{\SnapshotReadTime}{t_{\text{own}}} \newcommand{\SnapshotResetCycleTime}{T_{\text{cycle,snap}}} \newcommand{\SoftExpectedActionReturn}{Q} \newcommand{\SoftExpectedRemainingReturn}{V} \newcommand{\SoftenedStudentProbabilityVector}{\mathbf{p}_{\text{student}}^{(T_{\text{distill}})}} \newcommand{\SoftenedTeacherProbabilityVector}{\mathbf{p}_{\text{teacher}}^{(T_{\text{distill}})}} \newcommand{\SoftmaxFunction}{\sigma} \newcommand{\SoftmaxInputScore}{x} \newcommand{\SoftmaxInputVector}{\mathbf{x}} \newcommand{\SoftmaxNormalizer}{z} \newcommand{\SoftmaxOutputProbability}{p} \newcommand{\SoftmaxRowMaximum}{m} \newcommand{\SoftmaxRunningMaximum}{m} \newcommand{\SoftmaxVectorLength}{n} \newcommand{\SontagStabilizingControl}{\mathbf{u}_{\text{Sontag}}} \newcommand{\SourceCurrent}{I_{\text{source}}} \newcommand{\SourceEventTime}{T_{\text{event}}} \newcommand{\SourceFramePoint}{\mathbf{p}_B} \newcommand{\SourceSinkPathSet}{\Pi} \newcommand{\SourceVoltage}{V_{\text{source}}} \newcommand{\SourceWriteShardGrant}{\Gamma_{c}} \newcommand{\SpareStoppingClearance}{d_{\text{spare}}} \newcommand{\SparseMatrixEntryCount}{n_{\text{elem}}} \newcommand{\SparseMatrixRowCount}{n_{\text{rows}}} \newcommand{\SparseProductInputComponent}{v} \newcommand{\SparseWeightMatrix}{\mathbf{W}_{\text{sparse}}} \newcommand{\SparsityPenaltyWeight}{\lambda_{\text{L1}}} \newcommand{\SparsityRatio}{\rho_{\text{sparse}}} \newcommand{\SpatialClearancePredicate}{P_{\text{clear}}} \newcommand{\SpatialColumnIndex}{j} \newcommand{\SpatialCovarianceEmbedding}{\mathbf{e}_{\Sigma}} \newcommand{\SpatialErrorVector}{\boldsymbol{\epsilon}_{\text{spatial}}} \newcommand{\SpatialHashFunction}{h} \newcommand{\SpatialMemoryMap}{\mathcal{M}} \newcommand{\SpatialPositionCount}{N_{\text{pix}}} \newcommand{\SpatialRowIndex}{i} \newcommand{\SpatialTransformation}{\mathcal{T}} \newcommand{\SpecialEuclideanAlgebra}{\mathfrak{se}(3)} \newcommand{\SpecialEuclideanGroup}{SE(3)} \newcommand{\SpecialOrthogonalGroup}{SO(3)} \newcommand{\SpecializedEnergyProductivity}{\rho_{\text{energy,specific}}} \newcommand{\SpecificHeatCapacity}{c_p} \newcommand{\SpectrallyNormalizedWeightMatrix}{\overline{\mathbf{W}}} \newcommand{\SpeculativeDecodingSpeedup}{S_{\text{spec}}} \newcommand{\SpeculativeDraftLength}{K} \newcommand{\SpeculativeDraftTokenCount}{k} \newcommand{\SpeedAtDetection}{v} \newcommand{\SpeedBound}{v_{\max}} \newcommand{\SpendingWindowDuration}{T_{\text{win}}} \newcommand{\SphereSurfaceArea}{S_{D-1}} \newcommand{\SplineControlPoint}{\mathbf{p}} \newcommand{\SplineDegree}{p} \newcommand{\SplineFinalControlIndex}{L} \newcommand{\SplineKnotTime}{\xi} \newcommand{\SplitAssignmentMap}{s} \newcommand{\SplitMessageCount}{N_{\text{msg}}} \newcommand{\SpotHourlyPrice}{C_{\text{spot}}} \newcommand{\SpringBrakeEngagementTime}{t_{\text{engage}}} \newcommand{\SpringCompressionForce}{F} \newcommand{\SprtExpectedLogIncrement}{m} \newcommand{\SprtLowerBoundary}{\Lambda_{\text{lo}}} \newcommand{\SprtLowerLogBoundary}{b_{\text{low}}} \newcommand{\SprtStoppingSampleCount}{N_{\text{stop}}} \newcommand{\SprtUpperBoundary}{\Lambda_{\text{up}}} \newcommand{\SprtUpperLogBoundary}{u} \newcommand{\SquareGemmDimension}{N} \newcommand{\SquaredGaussianSumQuantile}{\chi} \newcommand{\SquaredPathVelocity}{x} \newcommand{\SquaredRadiusSubstitution}{u} \newcommand{\SquashedActionComponent}{a} \newcommand{\SramCapacity}{M_{\text{SRAM}}} \newcommand{\StabilizationErrorThreshold}{\epsilon_{\text{stable}}} \newcommand{\StabilizationSlewCeiling}{j_{\text{stable}}} \newcommand{\StackedContactForces}{\mathbf{f}_{\text{c}}} \newcommand{\StageConditionalAcceptanceProbability}{q} \newcommand{\StageEpisodeCount}{N_{\text{episodes}}} \newcommand{\StageReachProbability}{r} \newcommand{\StagedDefinitionCount}{n_{\text{def}}} \newcommand{\StagingExhaustionTime}{T_{\text{exhaust}}} \newcommand{\StagingStoreCapacity}{M_{\text{stage}}} \newcommand{\StaleSupportRate}{\epsilon_{\text{stale}}} \newcommand{\StalenessAdjustedLearningRate}{\eta'} \newcommand{\StalenessBound}{s} \newcommand{\StallCounterTorque}{\tau_{\text{stall}}} \newcommand{\StallTravelBound}{d_{\text{F1}}} \newcommand{\StandardDeviationMultiple}{k} \newcommand{\StandardNormalCumulativeDistribution}{\Phi} \newcommand{\StandardNormalQuantile}{z_q} \newcommand{\StandbyInstanceMemory}{M_{\text{standby}}} \newcommand{\StandbyPower}{P_{\text{idle}}} \newcommand{\StandbyReserveCount}{N_{\text{reserve}}} \newcommand{\StandstillSpeedThreshold}{\epsilon_{\text{vel}}} \newcommand{\StateConstraintMatrix}{\mathbf{H}_x} \newcommand{\StateConstraintVector}{\mathbf{b}_x} \newcommand{\StateCotangentSpace}{T_{\mathbf{x}}^*} \newcommand{\StateDimension}{n} \newcommand{\StateDistribution}{d_\pi} \newcommand{\StateEstimate}{\hat{\mathbf{x}}} \newcommand{\StateEstimateDerivative}{\dot{\hat{\mathbf{x}}}} \newcommand{\StateEstimationError}{\mathbf{e}} \newcommand{\StateExposureLevel}{S} \newcommand{\StateNormWeighting}{W} \newcommand{\StateOperation}{f} \newcommand{\StateParameterSensitivity}{\mathbf{S}} \newcommand{\StateRecurrencePeriod}{\ell} \newcommand{\StateScalarFunction}{\phi} \newcommand{\StateSpaceDimension}{d_s} \newcommand{\StateSpaceInputMatrix}{\mathbf{B}} \newcommand{\StateSpaceSystemMatrix}{\mathbf{A}_{\text{sys}}} \newcommand{\StateTokenCount}{K_s} \newcommand{\StateTrackingWeightMatrix}{\mathbf{W}_q} \newcommand{\StateTransitionMatrix}{\mathbf{F}} \newcommand{\StatelessCursorPayload}{d} \newcommand{\StaticBatchingOperations}{O_{\text{traditional}}} \newcommand{\StaticChassisPower}{P_{\text{chassis\_static}}} \newcommand{\StaticDataDistribution}{p_{\text{data}}} \newcommand{\StationaryConditionPolynomial}{P} \newcommand{\StatisticalDivergence}{\mathcal{D}(P_t \| P_0)} \newcommand{\StatisticalFalseNegativeRate}{\beta} \newcommand{\StatisticalHypothesis}{H} \newcommand{\StatisticalPowerQuantile}{z_{1-\beta}} \newcommand{\StatisticalSignificanceLevel}{\alpha_{\text{sig}}} \newcommand{\StatorCoreTemperature}{T_{\text{core}}} \newcommand{\StatorIronTemperature}{T_{\text{iron}}} \newcommand{\StatorThermalCapacitance}{C_{\text{th}}} \newcommand{\StatusPollCount}{N_{\text{poll}}} \newcommand{\SteadyDeceleration}{a} \newcommand{\SteadyStateAvailability}{A} \newcommand{\SteadyStateCurrent}{I_{\text{final}}} \newcommand{\SteadyStateErrorCovariance}{\mathbf{P}_{\text{est}}} \newcommand{\SteadyStateIntegratorState}{\mathbf{z}_{\text{ss}}} \newcommand{\SteadyStateTemperatureRise}{\Delta T_{\max}} \newcommand{\SteadyStateTrackingError}{\mathbf{e}_{\text{ss}}} \newcommand{\SteeringTransferTime}{T} \newcommand{\StepFailureHazard}{a} \newcommand{\StepGenerationCost}{C_{\text{gen}}} \newcommand{\StepGenerationTime}{T_{\text{step}}} \newcommand{\StepIoTime}{T_{\text{IO}}} \newcommand{\StepResponsePhaseLag}{\Delta \phi} \newcommand{\StepSettlingTime}{t_{\text{settle}}} \newcommand{\StepSuccessProbability}{p} \newcommand{\StepTestVoltage}{V_{\text{step}}} \newcommand{\StepTimePenalty}{c_{\text{time}}} \newcommand{\StepTokenLogit}{z_{t,v}} \newcommand{\StereoBaseline}{b} \newcommand{\StereoDisparity}{d} \newcommand{\StlEventuallyDeadline}{\tau} \newcommand{\StlFormula}{\phi} \newcommand{\StlIntervalEnd}{b} \newcommand{\StlIntervalStart}{a} \newcommand{\StlPredicateFunction}{f} \newcommand{\StlRobustness}{\rho} \newcommand{\StlUntilOperator}{\mathcal{U}_{[a, b]}} \newcommand{\StockoutNormalQuantile}{z_{1-\epsilon}} \newcommand{\StockoutProbabilityTarget}{\epsilon} \newcommand{\StopAxisAcceleration}{\ddot{q}_{\text{stop}}} \newcommand{\StopAxisPosition}{q_{\text{stop}}} \newcommand{\StopCompletionInstant}{t_{\text{stop\_end}}} \newcommand{\StopDecisionComputeBound}{T_{\text{compute}}} \newcommand{\StopProgress}{u} \newcommand{\StopSequenceSet}{\mathcal{S}_{\text{stop}}} \newcommand{\StoppingBoundaryClearance}{z} \newcommand{\StoppingCrossoverSpeed}{v^{*}} \newcommand{\StoppingDeadline}{t_{\text{deadline,stop}}} \newcommand{\StoppingDistance}{d_{\text{stop}}} \newcommand{\StoppingDistanceBudget}{d_{\text{budget}}} \newcommand{\StoppingDuration}{T_{\text{stop}}} \newcommand{\StorageAccessFactor}{F_{\text{access}}} \newcommand{\StorageBandwidth}{\text{BW}_{\text{storage}}} \newcommand{\StorageCapacityPrice}{C_{\text{storage/byte-time}}} \newcommand{\StorageFunction}{V} \newcommand{\StorageFunctionDerivative}{\dot{V}} \newcommand{\StorageIngestBandwidth}{\text{BW}_{\text{ingest}}} \newcommand{\StoragePrice}{c_{\text{storage}}} \newcommand{\StorageReadTime}{T_{\text{read}}} \newcommand{\StorageRetentionTime}{T_{\text{months}}} \newcommand{\StorageThroughput}{R_{\text{storage}}} \newcommand{\StoredDataVolume}{D_{\text{vol,store}}} \newcommand{\StoredEmbedding}{\mathbf{z}} \newcommand{\StoredIndexVector}{\mathbf{x}} \newcommand{\StoredSystemState}{s} \newcommand{\StoredTokenVolume}{V} \newcommand{\StragglerStepTime}{T_{\text{step,straggler}}} \newcommand{\StreamAcceptanceProbability}{p} \newcommand{\StreamingEndToEndLatency}{T_{\text{streaming}}} \newcommand{\StrideCheckpointCount}{N} \newcommand{\StrongConfigurationAttemptCost}{c_{\text{big}}} \newcommand{\StrongConfigurationPassProbability}{p_{\text{big}}} \newcommand{\StruckObjectMass}{m_{\text{obj}}} \newcommand{\StructuredSparsityGroupSize}{m_{\text{group}}} \newcommand{\StructuredSparsityNonzeroCount}{n_{\text{keep}}} \newcommand{\StudentProbabilityVector}{\mathbf{p}_{\text{student}}} \newcommand{\StuffBitTime}{t_{\text{stuff},i}} \newcommand{\SubgroupIndex}{g} \newcommand{\SubgroupSampleSize}{n} \newcommand{\SubintervalFailureProbability}{p} \newcommand{\SublevelSetThreshold}{c} \newcommand{\SubsequentArrivalTime}{\tau} \newcommand{\SubsetAllPassIndicator}{I_J^{\text{all}}} \newcommand{\SubsetAnyPassIndicator}{I_J} \newcommand{\SubsetDatasetSize}{D_{\text{subset}}} \newcommand{\SuccessCountIndex}{j} \newcommand{\SuccessLowerConfidenceLimit}{p_{\text{lower}}} \newcommand{\SuccessfulTrialCount}{k} \newcommand{\SuccessorActionVector}{\mathbf{a}'} \newcommand{\SuccessorPlanningState}{s'} \newcommand{\SuffixFoldTime}{T_{\text{fold}}} \newcommand{\SummaryOutputLength}{K_{\text{sum}}} \newcommand{\SummaryTokenEmbedding}{\mathbf{x}_{\text{class}}} \newcommand{\SupervisoryMtbi}{T_{\text{MTBI}}} \newcommand{\SupervisoryTakeoverLatency}{T_{\Sigma}} \newcommand{\SupplyVoltage}{V} \newcommand{\SupportPolygon}{\mathcal{P}_{\text{support}}} \newcommand{\SupportSetSize}{n_{\text{shot}}} \newcommand{\SustainableAttemptRate}{R_{\text{attempt}}} \newcommand{\SustainableCopperLossPower}{P_{\text{loss,ss}}} \newcommand{\SustainableHoldingTorque}{\tau_{\text{hold,max}}} \newcommand{\SustainedComputeRate}{R_{\text{sustained}}} \newcommand{\SustainedDropoutFrameCount}{N_{\text{drop}}} \newcommand{\SustainedMemoryBandwidth}{\text{BW}_{\text{mem}}} \newcommand{\SweepCandidateCostFraction}{f} \newcommand{\SweepCandidateCount}{k} \newcommand{\SwitchBreakdownVoltage}{V_{\text{breakdown}}} \newcommand{\SwitchInputCapacitance}{C_{\text{iss}}} \newcommand{\SwitchOnResistance}{R_{\text{ds(on)}}} \newcommand{\SwitchRadix}{k} \newcommand{\SwitchedCapacitance}{C} \newcommand{\SwitchingActivityFactor}{\alpha} \newcommand{\SwitchingEnergy}{E} \newcommand{\SwitchingTransitionTime}{t_{\text{sw}}} \newcommand{\SymbolicPlanningState}{s} \newcommand{\SymmetricClippingThreshold}{\alpha_{\text{sym}}} \newcommand{\SymmetricMessageOverhead}{o} \newcommand{\SymplecticEulerTransitionMatrix}{\mathbf{A}_{\text{symp}}} \newcommand{\SyncMessageInterval}{\Delta t_{\text{interval}}} \newcommand{\SyncPairingDisplacement}{\Delta \mathbf{x}_{\text{sync}}} \newcommand{\SynchronizationBlackout}{T_{\text{blackout}}} \newcommand{\SynchronizationClearanceMargin}{d_{\text{sync}}} \newcommand{\SynchronizationErrorBound}{\epsilon_{\text{sync}}} \newcommand{\SynchronizationStepIndex}{k} \newcommand{\SynchronizationTime}{T_{\text{sync}}} \newcommand{\SyntheticDataGenerator}{G_{\theta}} \newcommand{\SyntheticDataset}{\mathcal{S}_{\text{synthetic}}} \newcommand{\SystemCallFilterTime}{T_{\text{filter}}} \newcommand{\SystemCallOverheadTime}{T_{\text{syscall}}} \newcommand{\SystemFailureRate}{\lambda_{\text{system}}} \newcommand{\SystemHazardRate}{\lambda_{\text{system}, h}} \newcommand{\SystemInstructionTokenCount}{S_{\text{system}}} \newcommand{\SystemMatrixPowerIndex}{k} \newcommand{\SystemMemoryBandwidth}{\text{BW}_{\text{system}}} \newcommand{\SystemMtbf}{\text{MTBF}_{\text{system}}} \newcommand{\SystemReliability}{R_{\text{system}}} \newcommand{\TableRowCount}{N} \newcommand{\TailByteAllocation}{M_{\text{tail}}} \newcommand{\TailMomentOrder}{k} \newcommand{\TailPerformanceMetric}{X} \newcommand{\TailRequestLatency}{T_{\text{lat},\text{p99}}} \newcommand{\TailRequestSeenBatchSize}{B_{\text{req,p99}}} \newcommand{\TailRiskDistributionFunction}{F} \newcommand{\TailRiskObservation}{X} \newcommand{\TailRiskObservationLevel}{x} \newcommand{\TailShapeParameter}{\xi} \newcommand{\TailStepIoTime}{T_{\text{IO,p99}}} \newcommand{\TailSupportUpperEndpoint}{x_F} \newcommand{\TakeoverInstant}{t_{\text{takeover}}} \newcommand{\TakeoverResponseTime}{T_{\Sigma, 1}} \newcommand{\TakeoverStateVisitationDistribution}{p^{\text{takeover}}} \newcommand{\TakeoverTrackingError}{\mathbf{e}_{\text{track}}} \newcommand{\TangentDirection}{\mathbf{v}} \newcommand{\TangentSeedVector}{\dot{\mathbf{x}}} \newcommand{\TangentialContactShear}{\mathbf{f}_{k, \parallel}} \newcommand{\TangentialSpeed}{v_{\text{tangential}}} \newcommand{\TapeIntermediateResult}{y_{\text{tape}}} \newcommand{\TargetAcceptanceDifference}{\Delta} \newcommand{\TargetActionReturnEstimate}{\hat{Q}} \newcommand{\TargetActorParameters}{\theta'} \newcommand{\TargetBatchSize}{B_{\text{target}}} \newcommand{\TargetCompletionQuantile}{q} \newcommand{\TargetComputeRate}{R_{\text{ops}}} \newcommand{\TargetComputeTimeFraction}{\eta_{\text{target}}} \newcommand{\TargetCriticParameters}{\phi'} \newcommand{\TargetCriticReturnEstimate}{Q_{\phi'}} \newcommand{\TargetDeterministicPolicy}{\mu_{\theta'}} \newcommand{\TargetError}{\epsilon} \newcommand{\TargetExceedanceProbability}{\epsilon} \newcommand{\TargetFairShare}{F_{\text{target}}} \newcommand{\TargetFramePoint}{\mathbf{p}_A} \newcommand{\TargetHazardRate}{\lambda_{\text{target}}} \newcommand{\TargetImpedanceDampingMatrix}{\mathbf{D}_d} \newcommand{\TargetImpedanceInertiaMatrix}{\mathbf{M}_d} \newcommand{\TargetImpedanceStiffnessMatrix}{\mathbf{K}_d} \newcommand{\TargetInferenceLatency}{L_{\text{lat,target}}} \newcommand{\TargetKeyAttentionWeight}{\alpha_{\text{target}}} \newcommand{\TargetKeyLogit}{z_{\text{target}}} \newcommand{\TargetModelDistribution}{p_{\theta}} \newcommand{\TargetOrientation}{\mathbf{R}_{\text{target}}} \newcommand{\TargetPlantState}{\mathbf{x}_{f}} \newcommand{\TargetPolicyEntropy}{\overline{\mathcal{H}}} \newcommand{\TargetPose}{\mathbf{T}_{\text{target}}} \newcommand{\TargetPosition}{\mathbf{p}_{\text{target}}} \newcommand{\TargetPositionComponent}{p_{\text{target},i}} \newcommand{\TargetRange}{z} \newcommand{\TargetRepeatedRunConsistency}{p_{\text{target}}} \newcommand{\TargetSamplingDistribution}{p} \newcommand{\TargetServingUtilization}{\rho_{\text{target}}} \newcommand{\TargetSmoothingNoise}{\boldsymbol{\epsilon}} \newcommand{\TargetSmoothingNoiseStandardDeviation}{\sigma} \newcommand{\TargetTokenVolume}{W} \newcommand{\TargetTravelDistance}{d} \newcommand{\TargetTrialFailureProbability}{p_{*}} \newcommand{\TargetTrialSuccessProbability}{p_{\text{target}}} \newcommand{\TargetTwinCriticReturnEstimate}{Q_{\phi'_i}} \newcommand{\TargetUnitQuaternion}{\mathbf{q}_{\text{quat,target}}} \newcommand{\TargetUpdateCount}{K_{\text{target}}} \newcommand{\TargetUtilizationBatchSize}{B_{\text{util}}} \newcommand{\TargetXPosition}{x} \newcommand{\TargetYPosition}{p_y} \newcommand{\TargetZPosition}{z} \newcommand{\TaskAcceptanceLabel}{x} \newcommand{\TaskBlockingTime}{B} \newcommand{\TaskContract}{\mathcal{C}} \newcommand{\TaskContractGoal}{G} \newcommand{\TaskCost}{C_{\text{task}}} \newcommand{\TaskCount}{K} \newcommand{\TaskCoverageProbability}{Q} \newcommand{\TaskCriticalSections}{cs} \newcommand{\TaskDerivativeGain}{\mathbf{K}_{d,i}} \newcommand{\TaskDistance}{d_{\text{task}}} \newcommand{\TaskEnvironment}{\mathcal{E}_{\text{env}}} \newcommand{\TaskErrorTolerance}{\tau_{\text{tol}}} \newcommand{\TaskGroupMap}{g} \newcommand{\TaskIndex}{i} \newcommand{\TaskInterferenceTime}{I} \newcommand{\TaskJacobian}{\mathbf{J}} \newcommand{\TaskJacobianDerivative}{\dot{\mathbf{J}}} \newcommand{\TaskJacobianPseudoinverse}{\mathbf{J}^\dagger} \newcommand{\TaskKinematicMap}{f} \newcommand{\TaskLoss}{\mathcal{L}_{\text{task}}} \newcommand{\TaskLossGradient}{\nabla \mathcal{L}} \newcommand{\TaskPeriod}{T} \newcommand{\TaskProportionalGain}{\mathbf{K}_{p,i}} \newcommand{\TaskReadCount}{n_{\text{read}}} \newcommand{\TaskRelativeDeadline}{D} \newcommand{\TaskRelevantOutcome}{\mathbf{Y}_{\text{task}}} \newcommand{\TaskReward}{r_{\text{task}}} \newcommand{\TaskSetUtilization}{U} \newcommand{\TaskSpaceAcceleration}{\ddot{\mathbf{x}}} \newcommand{\TaskSpaceCoordinates}{\mathbf{x}} \newcommand{\TaskSpaceDimension}{m} \newcommand{\TaskSpaceReference}{\mathbf{x}_i^{\text{ref}}} \newcommand{\TaskSpaceReferenceAcceleration}{\ddot{\mathbf{x}}^{\text{ref}}} \newcommand{\TaskSpaceReferenceVelocity}{\dot{\mathbf{x}}^{\text{ref}}} \newcommand{\TaskSpaceVelocity}{\dot{\mathbf{x}}} \newcommand{\TaskSpecificLoss}{\mathcal{L}} \newcommand{\TaskStateTokenCount}{S_{\text{state}}} \newcommand{\TaskToleranceSemiAxes}{\mathbf{r}} \newcommand{\TaskToleranceSemiAxis}{r} \newcommand{\TaskTurnCost}{C_{\text{call}}} \newcommand{\TaskWeight}{w} \newcommand{\TasksPerComparisonArm}{N_{\text{arm}}} \newcommand{\TeamQuotaCap}{Q_{\text{team}}} \newcommand{\TelemetryFlushTime}{t_{\text{telemetry\_flush}}} \newcommand{\TelemetryFreshnessBound}{\Delta t_{\text{fresh}}} \newcommand{\TelemetryRetentionDuration}{T_{\text{retention}}} \newcommand{\TelemetrySamplingFrequency}{f_{\text{sample}}} \newcommand{\TelemetrySeriesCount}{N_{\text{series}}} \newcommand{\TelemetryTickInterval}{\Delta t_s} \newcommand{\TeleoperationCommandLatency}{t_{\text{cmd}}} \newcommand{\TeleoperationDownlinkTime}{T_{\text{downlink}}} \newcommand{\TeleoperationRoundTripLatency}{t_{\text{loop}}} \newcommand{\TeleoperationRoundTripTime}{T_{\text{RTT}}} \newcommand{\TeleoperationStateVisitationDistribution}{p^{\pi_{\text{teleop}}}} \newcommand{\TeleoperationUplinkTime}{T_{\text{uplink}}} \newcommand{\TeleoperationVideoLatency}{T_{\text{video}}} \newcommand{\TemperatureDualObjective}{\mathcal{L}} \newcommand{\TemperatureStepSize}{\lambda_{\alpha}} \newcommand{\TemplateSharedMemory}{M_{\text{template}}} \newcommand{\TemporalDifferenceResidual}{\delta} \newcommand{\TemporalEnsemblingWeight}{w_i} \newcommand{\TenantIndex}{i} \newcommand{\TenantResourceAllocation}{a_{i,r}} \newcommand{\TensorAxisCount}{n} \newcommand{\TensorColumnModeSize}{J} \newcommand{\TensorCoreAccumulatorMatrix}{\mathbf{C}_{\text{acc}}} \newcommand{\TensorCoreLeftInput}{\mathbf{A}_{\text{tc}}} \newcommand{\TensorCoreOutputMatrix}{\mathbf{D}_{\text{tc}}} \newcommand{\TensorCoreRightInput}{\mathbf{B}_{\text{tc}}} \newcommand{\TensorDepthModeSize}{T} \newcommand{\TensorElementCount}{N} \newcommand{\TensorModeIndex}{n_{\text{mode}}} \newcommand{\TensorParallelDegree}{N_{\text{TP}}} \newcommand{\TensorParallelLayerTime}{T_{\text{inference}}} \newcommand{\TensorRowModeSize}{I} \newcommand{\TerminalFeedbackGain}{\mathbf{K}_f} \newcommand{\TerminalInvariantSet}{\mathcal{X}_{f}} \newcommand{\TerminalPlantState}{\mathbf{x}_N} \newcommand{\TerminalTransitTime}{t_{\text{transit}}} \newcommand{\TerminalVoltageLimit}{V_{\max}} \newcommand{\TerminationProtocol}{\kappa} \newcommand{\TestExample}{z_{\text{test}}} \newcommand{\TestFamilySize}{k} \newcommand{\TestPhaseCapabilityGrant}{\Gamma_{\text{test}}} \newcommand{\TestsDirectoryShardGrant}{\Gamma_{a}} \newcommand{\TextTokenCount}{S_{\text{text}}} \newcommand{\TextTokenEmbeddings}{\mathbf{z}_{\text{text}}} \newcommand{\ThermalExpansionCoefficient}{\alpha} \newcommand{\ThermalPenaltyWeight}{\lambda_T} \newcommand{\ThermalPowerLimit}{P_{\text{thermal}}} \newcommand{\ThermalResistance}{R_{\text{th}}} \newcommand{\ThermalTimeConstant}{\tau_{\text{th}}} \newcommand{\ThirdFloatingPointAddend}{c} \newcommand{\ThirdRingTraceElement}{c} \newcommand{\ThresholdExceedanceCount}{N_u} \newcommand{\ThresholdExceedanceRate}{\zeta_u} \newcommand{\ThresholdExcess}{y} \newcommand{\ThresholdExcessVariable}{Y} \newcommand{\ThresholdedSparsityRatio}{\rho_{\text{sparse},\delta}} \newcommand{\ThrottleClearTemperature}{T_{\text{clear}}} \newcommand{\ThrottleOnsetJunctionTemperature}{T_{\text{j},\text{start}}} \newcommand{\ThrottleRecoveryTime}{t_{\text{recov}}} \newcommand{\ThrottleTripTemperature}{T_{\text{trip}}} \newcommand{\ThrottledClockFrequency}{f_{\text{throt}}} \newcommand{\TickCycleCount}{N} \newcommand{\TickIndex}{n} \newcommand{\TickPeriodJitterBound}{J_{\text{phase}}} \newcommand{\TieredRequestServiceTime}{T} \newcommand{\TightenedDiscreteSafeSet}{\mathcal{C}_{\text{discrete}}} \newcommand{\TileRowIndex}{m} \newcommand{\TiltAngle}{\theta_{\text{tilt}}} \newcommand{\Time}{T} \newcommand{\TimeBudgetUsedFraction}{\rho_T} \newcommand{\TimeInstant}{t} \newcommand{\TimeScaleSeparationRatio}{\epsilon} \newcommand{\TimeStepIndex}{t} \newcommand{\TimeToResult}{T_{\text{result}}} \newcommand{\TimeToTarget}{T_{\text{target}}} \newcommand{\TimeoutSafetyMultiplier}{k} \newcommand{\TimeoutTrialCount}{n_{\text{timeout}}} \newcommand{\TimerClockPeriod}{T_{\text{timer\_clk}}} \newcommand{\TimestampJitterDelay}{\delta_{\text{jitter}}} \newcommand{\TimestampQuantizationBound}{T_{\text{quant}}} \newcommand{\TimestampSkew}{t_{\text{skew}}} \newcommand{\TimingJitter}{\sigma_{\text{jitter}}} \newcommand{\TimingRealityGap}{\Delta_{\text{lat}}} \newcommand{\TokenAuthenticationCode}{\sigma} \newcommand{\TokenAveragedBatchLoss}{\mathcal{L}_{\text{token}}} \newcommand{\TokenBucketDepth}{b} \newcommand{\TokenBucketRefillRate}{r} \newcommand{\TokenBudgetUsedFraction}{\rho_N} \newcommand{\TokenByteDecoding}{s} \newcommand{\TokenCaveat}{c} \newcommand{\TokenDispatchTime}{T_{\text{dispatch}}} \newcommand{\TokenIdentifierSize}{s_{\text{id}}} \newcommand{\TokenIndex}{t} \newcommand{\TokenPrefix}{x_{<t}} \newcommand{\TokenVocabulary}{\mathcal{V}} \newcommand{\TokenizationTime}{T_{\text{tokenize}}} \newcommand{\ToleranceEllipsoidMatrix}{\mathbf{E}} \newcommand{\ToleratedFailureProbability}{\epsilon} \newcommand{\ToleratedPositionError}{\epsilon_{\text{pos}}} \newcommand{\TombstonedNodeSet}{V_{\text{tomb}}} \newcommand{\TombstonedRecordFraction}{\rho_{\text{dead}}} \newcommand{\ToolArgumentKey}{p} \newcommand{\ToolCallCategory}{y} \newcommand{\ToolCallCost}{c_{\text{tool}}} \newcommand{\ToolCallIndex}{i} \newcommand{\ToolCallReadSet}{R} \newcommand{\ToolCallWriteSet}{W} \newcommand{\ToolCartesianPose}{\mathbf{x}} \newcommand{\ToolCartesianVelocity}{\dot{\mathbf{x}}} \newcommand{\ToolCenterPointAxis}{\hat{\mathbf{z}}_{\text{TCP}}} \newcommand{\ToolCenterPointFrame}{\mathcal{F}_{\text{TCP}}} \newcommand{\ToolCenterPointPose}{\mathbf{T}_{\text{TCP}}} \newcommand{\ToolCenterPointPosition}{\mathbf{p}_{\text{TCP}}} \newcommand{\ToolClearanceDistance}{d_{\text{tool}}} \newcommand{\ToolDeclarationTokenCount}{S_{\text{tools}}} \newcommand{\ToolDescriptorSize}{S_{\text{desc}}} \newcommand{\ToolPlanarAbscissa}{x} \newcommand{\ToolPlanarOrdinate}{y} \newcommand{\ToolPositionError}{e_{\text{tool}}} \newcommand{\ToolServiceCount}{N_{\text{tool}}} \newcommand{\ToolSpeedLimit}{v_{\text{TCP}}} \newcommand{\ToolTargetState}{s} \newcommand{\ToolTime}{T_{\text{tool}}} \newcommand{\ToolTipPose}{\mathbf{T}_{\text{tool}}} \newcommand{\TopClassCount}{k} \newcommand{\TopMagnitudeIndicator}{\mathbf{1}_{|\mathbf{g}| \geq |\mathbf{g}|_{(K_{\text{top}})}}} \newcommand{\TopTokenSampleCount}{k} \newcommand{\TopologicalPlaceNode}{p^{\text{place}}} \newcommand{\TopologyEndpointCount}{N} \newcommand{\TorqueCutoffCommand}{\mathbf{u}_{\text{cutoff}}} \newcommand{\TorqueEffortPenaltyWeight}{\lambda_{\tau}} \newcommand{\TorqueProducingCurrent}{i_q} \newcommand{\TorqueRateLimit}{\dot{\tau}_{\max}} \newcommand{\TorqueRegularizationWeight}{w_\tau} \newcommand{\TorqueSlewPenaltyWeight}{\lambda_{\dot{\tau}}} \newcommand{\TorusFirstAxisChipCount}{X} \newcommand{\TorusSecondAxisChipCount}{Y} \newcommand{\TorusThirdAxisChipCount}{Z} \newcommand{\TotalChipPower}{P_{\text{total}}} \newcommand{\TotalCollisionQueryTime}{T_{\text{query\_total}}} \newcommand{\TotalDataCost}{C_{\text{total}}} \newcommand{\TotalDelayPhaseShift}{\phi_{\text{total}}} \newcommand{\TotalEnergy}{E_{\text{total}}} \newcommand{\TotalExecutedTrialCount}{N_{\text{total}}} \newcommand{\TotalFailureRecoveryTime}{T_{\text{recovery}}} \newcommand{\TotalGateCharge}{Q_g} \newcommand{\TotalInterventionCount}{N_{\text{int}}} \newcommand{\TotalKineticEnergy}{E_{k,\text{total}}} \newcommand{\TotalMemoryFootprint}{M_{\text{total}}} \newcommand{\TotalPipelineLatency}{L_{\text{lat,total}}} \newcommand{\TotalTrainingRunCost}{C_{\text{total}}} \newcommand{\TraceCrashCount}{N_{\text{crash}}} \newcommand{\TraceCrashIndex}{i} \newcommand{\TraceDecay}{\lambda} \newcommand{\TraceIntermediateAdjoint}{\bar{v}} \newcommand{\TraceIntermediateTangent}{\dot{v}} \newcommand{\TraceIntermediateVariable}{v} \newcommand{\TrackIndex}{i} \newcommand{\TrackLastUpdateTime}{t_{\text{last}}} \newcommand{\TrackLossTimeout}{T_{\text{lost}}} \newcommand{\TrackPositionDeviation}{\sigma_{\text{track}}} \newcommand{\TrackPredictedErrorCovariance}{\mathbf{P}_{t|t-1}} \newcommand{\TrackPredictedStateEstimate}{\hat{\mathbf{x}}_{t|t-1}} \newcommand{\TrackedEvidenceHorizon}{\tau_{\text{ev,tracked}}} \newcommand{\TrackerFrameIndex}{t} \newcommand{\TrackingErrorAcceleration}{\ddot{\mathbf{e}}} \newcommand{\TrackingErrorAllowance}{\epsilon_{\text{pos}}} \newcommand{\TrackingErrorBound}{\epsilon_{\text{track}}} \newcommand{\TrackingErrorDistance}{e} \newcommand{\TrackingErrorRate}{\dot{\mathbf{e}}} \newcommand{\TrackingErrorVector}{\mathbf{e}} \newcommand{\TrackingRelaxationSlack}{\delta} \newcommand{\TrackingSlackPenaltyWeight}{p} \newcommand{\TrackingStartInstant}{t_{\text{start}}} \newcommand{\TractionLimitedDeceleration}{a} \newcommand{\TractiveForce}{F_x} \newcommand{\TrainableStateMemory}{M_{\text{train}}} \newcommand{\TrainerUpdateTime}{T_{\text{train}}} \newcommand{\TrainingCompute}{O_{\text{train}}} \newcommand{\TrainingCost}{C_{\text{train}}} \newcommand{\TrainingDataset}{D} \newcommand{\TrainingDistribution}{P_0} \newcommand{\TrainingEmpiricalCdf}{F_{P_0}} \newcommand{\TrainingExample}{z} \newcommand{\TrainingFailureCount}{N_{\text{failures}}} \newcommand{\TrainingFeatureMean}{\mu} \newcommand{\TrainingFeatureStandardDeviation}{\sigma} \newcommand{\TrainingLabelMask}{\mathcal{M}_{\text{train}}} \newcommand{\TrainingLoss}{\mathcal{L}_{\text{train}}} \newcommand{\TrainingPathPredictor}{f_{\text{train}}} \newcommand{\TrainingPipelineFunction}{f} \newcommand{\TrainingRunCount}{N_{\text{runs}}} \newcommand{\TrainingSampleThroughput}{R_{\text{train}}} \newcommand{\TrainingSchemaKeySet}{\mathcal{K}_{\text{train}}} \newcommand{\TrainingServingSkew}{S_{\text{skew}}} \newcommand{\TrainingSplitFraction}{f_{\text{train}}} \newcommand{\TrainingStepCount}{K} \newcommand{\TrainingStepEnergy}{E_{\text{step}}} \newcommand{\TrainingStepOperations}{O_{\text{step}}} \newcommand{\TrainingStepTime}{T_{\text{step}}} \newcommand{\TrainingThroughput}{R_{\text{training}}} \newcommand{\TrainingTime}{T_{\text{train}}} \newcommand{\TrainingTransformFunction}{f_{\text{train}}} \newcommand{\Trajectory}{\tau} \newcommand{\TrajectoryAction}{a} \newcommand{\TrajectoryAdmissionRate}{\lambda_{\text{traj}}} \newcommand{\TrajectoryBudget}{\mathbf{B}} \newcommand{\TrajectoryCallCount}{N_{\text{call}}} \newcommand{\TrajectoryCategoryIndex}{j} \newcommand{\TrajectoryCheckpointCount}{N_{\text{ckpt}}} \newcommand{\TrajectoryDivergenceResidual}{e_{\text{div}}} \newcommand{\TrajectoryDuration}{T_{\text{traj}}} \newcommand{\TrajectoryGoodput}{\mathcal{G}} \newcommand{\TrajectoryObservation}{o} \newcommand{\TrajectoryOptimizationObjective}{\mathcal{U}} \newcommand{\TrajectoryRecordDuration}{T_{\text{record}}} \newcommand{\TrajectoryRecordFrame}{\mathcal{F}} \newcommand{\TrajectoryReturn}{R} \newcommand{\TrajectoryReward}{R} \newcommand{\TrajectorySampleCount}{N} \newcommand{\TrajectoryState}{s} \newcommand{\TrajectoryStateSpace}{\mathcal{S}} \newcommand{\TrajectoryTimeLimit}{T_{\max}} \newcommand{\TrajectoryTokenCost}{C_{\text{session}}} \newcommand{\TrajectoryTokenLimit}{N_{\max}} \newcommand{\TrajectoryTurnLimit}{H_{\max}} \newcommand{\TransceiverDelay}{t_{\text{transceiver}}} \newcommand{\TransductionInstant}{t_{\text{transduction}}} \newcommand{\TransferBufferCount}{N_{\text{transfer}}} \newcommand{\TransferDiscrepancyBound}{\epsilon_{\text{gap}}} \newcommand{\TransferTimeForPayload}{T_{\text{transfer}}} \newcommand{\TransferredDataVolume}{D_{\text{vol,transfer}}} \newcommand{\TransformGraph}{\mathcal{G}} \newcommand{\TransformGraphEdgeSet}{\mathcal{E}} \newcommand{\TransformGraphFrame}{\mathcal{F}} \newcommand{\TransformGraphVertexSet}{\mathcal{V}} \newcommand{\TransformRotationBlock}{\mathbf{R}_{AB}} \newcommand{\TransformTranslationBlock}{\mathbf{t}_{AB}} \newcommand{\TransformationInputCount}{k} \newcommand{\TransformedCartesianPosition}{\mathbf{p}'} \newcommand{\TransformedHomogeneousPointCoordinates}{\tilde{\mathbf{p}}'} \newcommand{\TransistorThresholdVoltage}{V_{\text{th}}} \newcommand{\TransitionStorageSize}{b_{\text{tr}}} \newcommand{\TranslationComponent}{v} \newcommand{\TranslationVector}{\mathbf{v}} \newcommand{\TranslationalDriftError}{e_{\text{trans}}} \newcommand{\TranslationalJerk}{j} \newcommand{\TranslationalKineticEnergy}{E_{k,\text{trans}}} \newcommand{\TransmissionEnergyPerByte}{E_{\text{tx}}} \newcommand{\TransmissionInputInertia}{J_{\text{in}}} \newcommand{\TransmissionTorsionalStiffness}{K_{\text{joint}}} \newcommand{\TransverseStandardDeviation}{\sigma_\perp} \newcommand{\TravelPosition}{x} \newcommand{\TraverseDistance}{d} \newcommand{\TreatedNeighborFraction}{e} \newcommand{\TreatmentAssignment}{w} \newcommand{\TreatmentConversionRate}{\hat{p}_B} \newcommand{\TreatmentSampleSize}{m_B} \newcommand{\TreeAllReduceCompletionTime}{T_{\text{tree}}} \newcommand{\TreeLikeAllReduceTime}{T_{\text{tree-like}}} \newcommand{\TreeSearchExplorationWeight}{c_{\text{explore}}} \newcommand{\TreeSearchLeafScore}{V} \newcommand{\TreeSearchMeanReturn}{Q} \newcommand{\TreeSearchPriorDistribution}{p_{\text{prior}}} \newcommand{\TreeSearchVisitCount}{N_{\text{visit}}} \newcommand{\TrialCampaignWallTime}{T_{\text{wall}}} \newcommand{\TrialCompletionIndicator}{Y} \newcommand{\TrialCondition}{c} \newcommand{\TrialControlStepCount}{N_{\text{steps}, i}} \newcommand{\TrialCount}{N} \newcommand{\TrialFailureIndicator}{x} \newcommand{\TrialFailureProbability}{p_{\text{fail}}} \newcommand{\TrialIndex}{n} \newcommand{\TrialInterventionCount}{n_{\text{int}}} \newcommand{\TrialLoadReversalCount}{n_{\text{rev}}} \newcommand{\TrialPassProbability}{p_{\text{trial}}} \newcommand{\TrialPathDistance}{d} \newcommand{\TrialResetLatency}{T_{\text{reset}}} \newcommand{\TrialResetTime}{t_{\text{reset}}} \newcommand{\TrialRolloutTime}{t_{\text{rollout}}} \newcommand{\TrialRunTime}{t_{\text{run}}} \newcommand{\TrialSuccessProbability}{p} \newcommand{\TriggeredWindowArrivalCount}{Q_{\text{arr}}} \newcommand{\TrueClearance}{C_{\text{true}}} \newcommand{\TrueLabelComponent}{y} \newcommand{\TrueOutcome}{Y} \newcommand{\TrueOutcomeLevel}{v} \newcommand{\TrueReferentScore}{c_{y_j}} \newcommand{\TruncatedDistanceSample}{d_{\mu}} \newcommand{\TruncatedKeyApproximation}{\hat{\mathbf{K}}_r} \newcommand{\TruncatedKeyLeftSingularMatrix}{\mathbf{U}_r} \newcommand{\TruncatedKeyRightSingularMatrix}{\mathbf{V}_r} \newcommand{\TruncatedKeySpectrumMatrix}{\boldsymbol{\Sigma}_r} \newcommand{\TruncationBandVolume}{V_{\text{band}}} \newcommand{\TruncationRank}{r} \newcommand{\TruthInstrumentSet}{\mathcal{I}_{\text{truth}}} \newcommand{\TsdfAccumulatedDistance}{D} \newcommand{\TsdfAccumulatedWeight}{W} \newcommand{\TsdfObservationWeight}{w} \newcommand{\TsdfTruncationBand}{\mu_{\text{tsdf}}} \newcommand{\TsdfWeightCap}{W_{\max}} \newcommand{\TuckerCoreTensor}{\mathcal{G}} \newcommand{\TurnAppendLength}{\Delta S_{\text{turn}}} \newcommand{\TurnBoundaryDelay}{t_{\text{boundary}}} \newcommand{\TurnBudgetUsedFraction}{\rho_H} \newcommand{\TurnContext}{c} \newcommand{\TurnContributionDeviationBound}{\sigma} \newcommand{\TurnCovarianceBoundScale}{C} \newcommand{\TurnCovarianceDecayRatio}{\alpha_{\text{corr}}} \newcommand{\TurnFailureRate}{\lambda_{\text{fail}}} \newcommand{\TurnGeneratedTokenCount}{n_{\text{gen}}} \newcommand{\TurnHorizon}{H} \newcommand{\TurnIndex}{t} \newcommand{\TurnInputTokenCost}{C_{\text{in}}} \newcommand{\TurnOffGateCurrent}{I_{g,\text{off}}} \newcommand{\TurnOffGateResistance}{R_{g,\text{off}}} \newcommand{\TurnOnGateResistance}{R_{g,\text{on}}} \newcommand{\TurnOutputTokenCost}{C_{\text{out}}} \newcommand{\TurnPayloadProbability}{q_{\text{turn}}} \newcommand{\TurnReadCount}{r} \newcommand{\TurnReconstructionTime}{T_{\text{recon}}} \newcommand{\TurnReexecutionTime}{T_{\text{exec}}} \newcommand{\TurnReward}{r} \newcommand{\TurnSandboxCost}{C_{\text{sandbox}}} \newcommand{\TurnStateGrowth}{s_{\text{turn}}} \newcommand{\TurnToolFeeCost}{C_{\text{tools}}} \newcommand{\TustinEigenvalue}{\lambda_{\text{Tustin}}} \newcommand{\TustinTransitionMatrix}{\mathbf{A}_{\text{Tustin}}} \newcommand{\TwinCriticReturnEstimate}{Q_{\phi_i}} \newcommand{\TwistCoordinates}{\boldsymbol{\xi}} \newcommand{\TwistCovarianceMatrix}{\boldsymbol{\Sigma}_{\boldsymbol{\xi}}} \newcommand{\TwistMatrix}{\hat{\boldsymbol{\xi}}} \newcommand{\TwistRotationAngle}{\theta_{\text{rot}}} \newcommand{\TwistRotationCoordinates}{\boldsymbol{\omega}} \newcommand{\TwistTranslationMatrix}{\mathbf{V}} \newcommand{\TwistWedgeOperator}{\wedge} \newcommand{\UnacceptedTaskMeanCost}{C_{\text{fail}}} \newcommand{\UnassistedCompletionCount}{N_{\text{unassisted}}} \newcommand{\UnassistedSuccessIndicator}{A} \newcommand{\UnbiasedAngularBrakingDeceleration}{\alpha_{\text{nom}}} \newcommand{\UnbrakedImpactForce}{F_{\text{unbraked}}} \newcommand{\UncachedInputTokenCount}{n_{\text{in}}} \newcommand{\UncachedPromptLength}{S_{\text{new}}} \newcommand{\UncertainScenarioParameters}{x} \newcommand{\UnconstrainedCallLatency}{T_{\text{free}}} \newcommand{\UnconstrainedParseFailureRate}{p_{\text{err}}} \newcommand{\UndampedNaturalFrequency}{\omega_n} \newcommand{\UnfoldedConvolutionOutput}{\mathbf{Y}_{\text{col}}} \newcommand{\UnfoldedPatchMatrix}{\mathbf{X}_{\text{col}}} \newcommand{\UniformDistribution}{\mathcal{U}} \newcommand{\UniformLoopTurnCost}{C_{\text{turn}}} \newcommand{\UnitAliasMultiplier}{k} \newcommand{\UnitImpulseFunction}{\delta} \newcommand{\UnitQuaternion}{\mathbf{q}_{\text{quat}}} \newcommand{\UnitQuaternionScalarComponent}{q_w} \newcommand{\UnitQuaternionSphere}{S^3} \newcommand{\UnitQuaternionXComponent}{q_x} \newcommand{\UnitQuaternionYComponent}{q_y} \newcommand{\UnitQuaternionZComponent}{q_z} \newcommand{\UnitTemperatureProbabilityVector}{\mathbf{p}_{\tau_{\text{temp}}=1}} \newcommand{\UnlabeledPool}{U} \newcommand{\UnloadedTickExecutionTime}{t_{\text{unloaded}}} \newcommand{\UnmitigatedHardwareFaultRate}{\lambda_{\text{unmitigated}}} \newcommand{\UnmodeledCommandPathDelay}{\Delta t_{\text{bus}}} \newcommand{\UnobservableForceOffset}{\Delta} \newcommand{\UnobservedUnknownSpace}{\mathcal{M}_{\text{unknown}}} \newcommand{\UnprojectionJacobian}{\mathbf{J}_{\text{unproj}}} \newcommand{\UnrecoverableDamageCost}{C_{\text{blast}}} \newcommand{\UnreservedStopDelay}{\delta} \newcommand{\UnshardedLocalExecutionTime}{T_{\text{compute}}} \newcommand{\UnsquashedLatentAction}{\mathbf{u}} \newcommand{\UntilPrefixTime}{t''} \newcommand{\UntrackedEvidenceHorizon}{\tau_{\text{ev,untracked}}} \newcommand{\UpdatedErrorCovariance}{\mathbf{P}_{k|k}} \newcommand{\UpdatedModelParameters}{\theta_{\text{new}}} \newcommand{\UpdatedParameterSubset}{\theta_{\text{updated}}} \newcommand{\UpdatedSoftmaxRunningMaximum}{m'} \newcommand{\UpdatedStateEstimate}{\hat{\mathbf{x}}_{k|k}} \newcommand{\UpperRatioClippingWidth}{\epsilon_{\text{high}}} \newcommand{\UprightPosition}{\mathbf{p}_{\text{upright}}} \newcommand{\UprightRange}{r} \newcommand{\UpstreamGradientElement}{\bar{y}} \newcommand{\UpstreamGradientVector}{\mathbf{v}} \newcommand{\UpstreamStageLatency}{X} \newcommand{\UsableDemonstrationYield}{Y_{\text{usable}}} \newcommand{\UsefulAcceleratorHourCost}{C_{\text{useful}}} \newcommand{\UsefulComputeFraction}{f_{\text{compute}}} \newcommand{\UsefulModelFlops}{O_{\text{useful}}} \newcommand{\UsefulStepCount}{N} \newcommand{\UsefulTrainingTime}{T_{\text{useful}}} \newcommand{\UserConnectionSet}{\mathcal{N}} \newcommand{\UserSpaceSetupTime}{T_{\text{user}}} \newcommand{\UvloThresholdVoltage}{V_{\text{UVLO}}} \newcommand{\VacuumLightSpeed}{c} \newcommand{\ValidCandidateRate}{p_{\text{valid}}} \newcommand{\ValidTokenSet}{\mathcal{V}_{\text{valid}}} \newcommand{\ValidatedMotionDuration}{T_{\text{yield}}} \newcommand{\ValidatedProposalEvent}{e_{\text{prop}}} \newcommand{\ValidationDataset}{\mathcal{D}_{\text{val}}} \newcommand{\ValidationGateThreshold}{\gamma_{\text{gate}}} \newcommand{\ValidationLoss}{\mathcal{L}_{\text{val}}} \newcommand{\VanishingTimeOffset}{\epsilon} \newcommand{\VariationalDistribution}{q_\phi} \newcommand{\VariationalParameters}{\phi} \newcommand{\VectorAngle}{\phi} \newcommand{\VectorElementCount}{N_{\text{vec}}} \newcommand{\Velocity}{\mathbf{v}} \newcommand{\VelocitySaturationExponent}{\alpha} \newcommand{\VerificationCheckCost}{C_{\text{ver}}} \newcommand{\VerificationCheckCount}{K} \newcommand{\VerificationPoolCapacity}{\mu_{\text{verify}}} \newcommand{\VerificationScheduleCost}{C} \newcommand{\VerificationTrialCount}{n_{\text{trial}}} \newcommand{\VerificationTrialIndex}{j} \newcommand{\VerificationTrialTime}{T_{\text{trial}}} \newcommand{\VerifiedDemonstrationDataset}{\mathcal{D}_{\text{verified}}} \newcommand{\VerifierFalseAcceptanceRate}{\epsilon_{\text{FA}}} \newcommand{\VerifierFalseRejectionRate}{\epsilon_{\text{FR}}} \newcommand{\VerifierPassProbability}{q} \newcommand{\VerifierPrecision}{\Pi_{V}} \newcommand{\VerifierTimeout}{T_{\text{out}}} \newcommand{\VerifierTrueAcceptanceRate}{u} \newcommand{\VerifierVerdict}{V} \newcommand{\VersionSkewBound}{k_{\text{skew}}} \newcommand{\VertexSlotTime}{d} \newcommand{\VerticalFocalLength}{f_y} \newcommand{\VibrationFrequency}{f_{\text{vib}}} \newcommand{\VirtualAccelerationCommand}{\ddot{\mathbf{q}}^*} \newcommand{\VirtualDampingMatrix}{\mathbf{D}_{\text{virt}}} \newcommand{\VirtualPipelineStagesPerDevice}{V} \newcommand{\ViscousDampingMatrix}{\mathbf{D}} \newcommand{\VisionBackboneTime}{t_{\text{backbone}}} \newcommand{\VisionTokenEmbeddings}{\mathbf{z}_{\text{vision}}} \newcommand{\VisualConditioningEmbedding}{\mathbf{E}} \newcommand{\VisualEncodingTime}{t_{\text{vis}}} \newcommand{\VitImagePatch}{\mathbf{x}_p} \newcommand{\VitPatchProjectionWeights}{\mathbf{W}_{\text{patch}}} \newcommand{\VitPatchSize}{p_{\text{patch}}} \newcommand{\VitPatchTokenEmbedding}{\mathbf{z}} \newcommand{\VocabularyToken}{v} \newcommand{\VocabularyTokenLogit}{o} \newcommand{\VolumetricFlowRate}{\dot{V}} \newcommand{\VoxelBlockCoordinate}{\mathbf{b}} \newcommand{\VoxelBlockEdgeLength}{L_{\text{blk}}} \newcommand{\VoxelCenterPosition}{\mathbf{p}_{\text{vox}}} \newcommand{\VoxelIndex}{i} \newcommand{\VoxelOccupancyState}{m} \newcommand{\VoxelPitch}{r} \newcommand{\VoxelStorageSize}{s_{\text{voxel}}} \newcommand{\VoxelUpdateTraffic}{s_{\text{rw}}} \newcommand{\WarmupEpochCount}{N_{\text{warmup}}} \newcommand{\WarmupStepCount}{W} \newcommand{\WatchdogClockFrequency}{f_{\text{wdg}}} \newcommand{\WatchdogCounterReading}{W} \newcommand{\WatchdogEarliestServiceTime}{T_{\text{lower}}} \newcommand{\WatchdogLatestServiceTime}{T_{\text{upper}}} \newcommand{\WatchdogLowerWindowCount}{W_{\text{lower}}} \newcommand{\WatchdogReloadCount}{W_{\text{init}}} \newcommand{\WatchdogServiceTime}{t_{\text{service}}} \newcommand{\WatchdogToken}{T} \newcommand{\WatchdogUpperWindowCount}{W_{\text{upper}}} \newcommand{\WaveImpedance}{b} \newcommand{\WeightElementStorageSize}{s_{\text{elem,W}}} \newcommand{\WeightMatrix}{\mathbf{W}} \newcommand{\WeightMatrixColumnCount}{n} \newcommand{\WeightMatrixEntry}{W_{ij}} \newcommand{\WeightMatrixRowCount}{m} \newcommand{\WeightMemory}{M_{\text{weights}}} \newcommand{\WeightOnlyStepTime}{t} \newcommand{\WeightPenaltyStrength}{\lambda_{\text{reg}}} \newcommand{\WeightQuantizationScale}{s_W} \newcommand{\WeightRangeBound}{W_{\text{max}}} \newcommand{\WeightVector}{\mathbf{w}} \newcommand{\WeightedNormArgument}{\mathbf{z}} \newcommand{\WheelAngularSpeed}{\omega} \newcommand{\WheelDiameter}{D_{\text{wheel}}} \newcommand{\WheelInertia}{J_{\text{wheel}}} \newcommand{\WheelNormalLoad}{F_z} \newcommand{\WheelRadius}{r} \newcommand{\WheelRevolutionCount}{N_{\text{rev}}} \newcommand{\WheelTrackWidth}{b} \newcommand{\WhiteNoiseProcess}{\mathcal{WN}} \newcommand{\WholeBodyDecisionVariables}{\mathbf{z}} \newcommand{\WholeRepositoryShardGrant}{\Gamma_{b}} \newcommand{\WidthMultiplier}{w_{\text{mult}}} \newcommand{\WidthScalingRatio}{\beta} \newcommand{\WilsonIntervalCenter}{\tilde{p}} \newcommand{\WindingCoreThermalResistance}{R_{\text{th,wc}}} \newcommand{\WindingCurrent}{I} \newcommand{\WindingJouleHeat}{E_{\text{thermal}}} \newcommand{\WindingLossPower}{P_{\text{loss}}} \newcommand{\WindingTemperature}{T_{\text{winding}}} \newcommand{\WindingTemperatureLimit}{T_{\text{limit}}} \newcommand{\WindingTerminalVoltage}{V_{\text{terminal}}} \newcommand{\WindingThermalCapacitance}{C_{\text{wind}}} \newcommand{\WindowArrivalCount}{k} \newcommand{\WindowArrivalOffset}{t} \newcommand{\WindowSpendingLimit}{C_{\text{win}}} \newcommand{\WithinTaskRunStandardDeviation}{\sigma_{\text{run}}} \newcommand{\WorkedTraceProduct}{c} \newcommand{\WorkedTraceProductAdjoint}{\bar{c}} \newcommand{\WorkedTraceSine}{b} \newcommand{\WorkedTraceSineAdjoint}{\bar{b}} \newcommand{\WorkedTraceSquare}{a} \newcommand{\WorkedTraceSquareAdjoint}{\bar{a}} \newcommand{\WorkerBaseCommitHash}{h_{\text{base}}} \newcommand{\WorkerCandidateCommitHash}{h_{\text{worker}}} \newcommand{\WorkerCompletionDistribution}{F} \newcommand{\WorkerCompletionTime}{T} \newcommand{\WorkerCount}{N_{\text{workers}}} \newcommand{\WorkerIndex}{k} \newcommand{\WorkerOverheadSlope}{\gamma} \newcommand{\WorkerTransformTime}{T_{\text{transform}}} \newcommand{\WorkerWrittenFileCount}{w} \newcommand{\WorkloadMeanOutputLength}{\mu} \newcommand{\WorkloadRequestIndex}{i} \newcommand{\WorkspaceExtentX}{L_x} \newcommand{\WorkspaceExtentY}{L_y} \newcommand{\WorkspaceExtentZ}{L_z} \newcommand{\WorkspaceRestoreTime}{T_{\text{ws}}} \newcommand{\WorkspaceVolume}{V_{\text{ws}}} \newcommand{\WorldBaseTransform}{\mathbf{T}_{WB}} \newcommand{\WorldBodyTransform}{\mathbf{T}_{wb}} \newcommand{\WorldFramePoint}{\mathbf{p}_{\text{world}}} \newcommand{\WorldLidarTransform}{\mathbf{T}_{wl}} \newcommand{\WorldMapTransform}{\mathbf{T}_{\text{world}}^{\text{map}}} \newcommand{\WorldPointCovariance}{\boldsymbol{\Sigma}_{\text{world}}} \newcommand{\WorldReferenceFrame}{\mathcal{F}_W} \newcommand{\WorldStateSpace}{\mathcal{S}} \newcommand{\WorldToCameraRotation}{\mathbf{R}_{CW}} \newcommand{\WorldToCameraTransform}{\mathbf{T}_{CW}} \newcommand{\WorldToCameraTranslation}{\mathbf{t}_{CW}} \newcommand{\WornPlantTransitionDistribution}{p_{n \gg 1}} \newcommand{\WorseArmSuccessProbability}{p_{\text{low}}} \newcommand{\WorstCaseExecutionTime}{C} \newcommand{\WorstCaseInterruptLatency}{t_{\text{irq,lat}}} \newcommand{\WorstCasePermissionCycleTime}{T_{\text{exec}}} \newcommand{\WorstCaseResponseTime}{R} \newcommand{\WristAngularVelocity}{\boldsymbol{\omega}_{\text{wrist}}} \newcommand{\WristCameraEmbedding}{\mathbf{e}_{\text{wrist}}} \newcommand{\WristLinearVelocity}{\mathbf{v}_{\text{wrist}}} \newcommand{\WristObjectTransform}{\mathbf{T}_{\text{wrist} \leftarrow \text{object}}} \newcommand{\WristSkewDisplacement}{\Delta \mathbf{p}_{\text{skew}}} \newcommand{\XAxisAngularRate}{\omega_x} \newcommand{\XAxisRotationCoordinate}{\omega_x} \newcommand{\XForceCeiling}{F_x} \newcommand{\XPositionErrorEnvelope}{e_x} \newcommand{\XTaskToleranceSemiAxis}{r_x} \newcommand{\XTorqueCeiling}{\tau_x} \newcommand{\YAxisAngularRate}{\omega_y} \newcommand{\YAxisRotationCoordinate}{\omega_y} \newcommand{\YForceCeiling}{F_y} \newcommand{\YPositionErrorEnvelope}{e_y} \newcommand{\YTaskToleranceSemiAxis}{r_y} \newcommand{\YTorqueCeiling}{\tau_y} \newcommand{\YawRate}{\omega_z} \newcommand{\YoshikawaManipulability}{w} \newcommand{\ZAxisRotationCoordinate}{\omega_z} \newcommand{\ZForceCeiling}{F_z} \newcommand{\ZPositionErrorEnvelope}{e_z} \newcommand{\ZTaskToleranceSemiAxis}{r_z} \newcommand{\ZTorqueCeiling}{\tau_z} \newcommand{\ZTransformVariable}{z} \newcommand{\ZeroEntryIndicator}{\mathbf{1}_{\{(\mathbf{W}_{\text{sparse}})_{ij} = 0\}}} \newcommand{\ZeroFailureTrialCount}{n} \newcommand{\ZeroFailureUpperConfidenceLimit}{p_{\text{fail, upper}}^{95\%}} \newcommand{\ZeroMatrix}{\mathbf{0}} \newcommand{\ZeroMomentPoint}{\mathbf{p}_{\text{ZMP}}} \newcommand{\ZeroVector}{\mathbf{0}} \newcommand{\ZohHoldTravel}{d_{\text{ZOH}}} \newcommand{\ZohPhaseShift}{\phi_{\text{ZOH}}} \newcommand{\ZohTransportDelay}{\tau_{\text{ZOH}}} \newcommand{\AuthorityLevels}{\AuthorityExposureLevel} \newcommand{\BreakEvenTaskVolume}{\BreakEvenTaskCount} \newcommand{\PertokenPricesCache}{\CachedInputTokenPrice} \newcommand{\ContentionAndCoherencyCoefficientsTwo}{\CoherencyCoefficient} \newcommand{\CoherencyContentionCoefficient}{\CoherencyCoefficient} \newcommand{\TaskDeadline}{\CompletionDeadline} \newcommand{\Deadline}{\CompletionDeadline} \newcommand{\Confidentiality}{\ConfidentialityLabel} \newcommand{\ContentionAndCoherencyCoefficients}{\ContentionCoefficient} \newcommand{\CostPerAcceptedTaskEff}{\CostPerAcceptedTask} \newcommand{\DuplicateeffectProbability}{\DuplicateEffectProbability} \newcommand{\EstimatedAdvantageK}{\EstimatedHistoryAdvantage} \newcommand{\EstimatedValueK}{\EstimatedRemainingReturn} \newcommand{\ExpectedIrreversibleLossA}{\ExpectedIrreversibleLoss} \newcommand{\PertokenPricesIn}{\InputTokenPrice} \newcommand{\CohensKappa}{\InterAnnotatorAgreement} \newcommand{\KvBlockSizeBlk}{\KvBlockSize} \newcommand{\MaskedFinetuningLossSft}{\MaskedFinetuningLoss} \newcommand{\ValidityIntervalOfAMemoryEntryBirth}{\MemoryEntryBirthGeneration} \newcommand{\ValidityIntervalOfAMemoryEntryDeath}{\MemoryEntryDeathGeneration} \newcommand{\MemoryHeldDuringAWait}{\MemoryHoldDuringWait} \newcommand{\OptimalCheckpointIntervalCkpt}{\OptimalCheckpointInterval} \newcommand{\PertokenPricesOut}{\OutputTokenPrice} \newcommand{\PertokenDecodeTime}{\PerTokenDecodeTime} \newcommand{\TokenLossMask}{\PositionLossMask} \newcommand{\LossMaskT}{\PositionLossMask} \newcommand{\ValidityIntervalOfAMemoryEntryQ}{\QueryWorkspaceGeneration} \newcommand{\RequestAndReplylossProbabilitiesTwo}{\ReplyLossProbability} \newcommand{\RequestAndReplylossProbabilities}{\RequestLossProbability} \newcommand{\EnvironmentStateK}{\RolloutEnvironmentState} \newcommand{\StalesupportRate}{\StaleSupportRate} \newcommand{\StateLevels}{\StateExposureLevel} \newcommand{\GoalContract}{\TaskContractGoal} \newcommand{\Environment}{\TaskEnvironment} \newcommand{\Vocabulary}{\TokenVocabulary} \newcommand{\ActionProposal}{\TrajectoryAction} \newcommand{\ConcurrentTrajectoriesTwo}{\TrajectoryAdmissionRate} \newcommand{\ActionObservation}{\TrajectoryObservation} \newcommand{\Observation}{\TrajectoryObservation} \newcommand{\StateAtTurn}{\TrajectoryState} \newcommand{\PerturnAppend}{\TurnAppendLength} \newcommand{\Context}{\TurnContext} \newcommand{\Horizon}{\TurnHorizon} \newcommand{\VerifierFalseacceptance}{\VerifierFalseAcceptanceRate} \newcommand{\VerifierFalseacceptanceFr}{\VerifierFalseRejectionRate} \newcommand{\WorkerCountWorkers}{\WorkerCount} \newcommand{\AllocationHoldTime}{\AllocatedWallTime} \newcommand{\CheckpointIntervalCkpt}{\CheckpointInterval} \newcommand{\AcceleratorsPerNodeNodes}{\ClusterNodeCount} \newcommand{\CommunicationcomputationRatio}{\CommunicationComputeRatio} \newcommand{\PercomponentFailureRate}{\ComponentFailureRate} \newcommand{\Correlation}{\CorrelationCoefficient} \newcommand{\DataparallelDegreeDp}{\DataParallelDegree} \newcommand{\NumberOfDevices}{\DeviceCount} \newcommand{\TypeIAndTypeIiErrorRatesStat}{\HypothesisTestFalseNegativeRate} \newcommand{\TypeIAndTypeIiErrorRatesSig}{\HypothesisTestSignificanceLevel} \newcommand{\DollarCostInfer}{\InferenceCost} \newcommand{\KvcacheBytesPerToken}{\KvCacheBytesPerToken} \newcommand{\KvcacheMemory}{\KvCacheMemory} \newcommand{\CrossoverPoint}{\LatencyBandwidthCrossoverSize} \newcommand{\LoggpLongmessageTime}{\LoggpLongMessageTime} \newcommand{\LogploggpNetworkLatency}{\LogpNetworkLatency} \newcommand{\LongmessageGapPerByte}{\LongMessageGapPerByte} \newcommand{\MeanTimeBetweenFailuresThree}{\MeanTimeBetweenFailures} \newcommand{\PermessageLatency}{\MessageStartupLatency} \newcommand{\NdeviceTime}{\MultiDeviceRunTime} \newcommand{\PipelineparallelDegreePp}{\PipelineParallelDegree} \newcommand{\MlProductivityGoodputFactorsProgram}{\ProgramGoodput} \newcommand{\ReceiverOverheadRecv}{\ReceiverOverhead} \newcommand{\CollectiveCompletionTimeRing}{\RingAllReduceCompletionTime} \newcommand{\RingtreeCrossoverPayload}{\RingTreeCrossoverPayload} \newcommand{\MlProductivityGoodputFactorsRuntime}{\RuntimeGoodput} \newcommand{\GoodputRatio}{\RuntimeGoodput} \newcommand{\ScalingExponentScale}{\ScalingExponent} \newcommand{\MlProductivityGoodputFactorsScheduling}{\SchedulingGoodput} \newcommand{\SingledeviceTimeOne}{\SingleDeviceRunTime} \newcommand{\ReliabilityFunctionSystem}{\SystemReliability} \newcommand{\TensorparallelDegreeTp}{\TensorParallelDegree} \newcommand{\SmallConstant}{\ToleratedFailureProbability} \newcommand{\DollarCostTrain}{\TrainingCost} \newcommand{\CollectiveCompletionTimeTree}{\TreeAllReduceCompletionTime} \newcommand{\UsefulComputetimeFraction}{\UsefulComputeFraction} \newcommand{\AccuracyAtTime}{\AccuracyAfterDeployment} \newcommand{\NumberOfAttentionHeads}{\AttentionHeadCount} \newcommand{\Distribution}{\InputDistribution} \newcommand{\NumberOfKeyValueHeads}{\KvHeadCount} \newcommand{\NumberOfKeyvalueHeadsKv}{\KvHeadCount} \newcommand{\NumberOfLayers}{\LayerCount} \newcommand{\LayerInputAndOutputWidths}{\LayerInputWidth} \newcommand{\LayerInputAndOutputWidthsTwo}{\LayerOutputWidth} \newcommand{\Gradient}{\LossGradient} \newcommand{\TrainingDistributionZero}{\TrainingDistribution} \newcommand{\AcceleratorCountGpu}{\AcceleratorCount} \newcommand{\ActivationMemoryActivations}{\ActivationMemory} \newcommand{\BatchServiceTimeSvc}{\BatchServiceTime} \newcommand{\EnergyPerOperationCompute}{\EnergyPerOperation} \newcommand{\GradientMemoryGradients}{\GradientMemory} \newcommand{\IronlawTermTimesCompute}{\IronLawComputeTime} \newcommand{\SingleDeviceComputeTime}{\IronLawComputeTime} \newcommand{\IronlawTermTimesMemory}{\IronLawMemoryTime} \newcommand{\LossscaleFactor}{\LossScaleFactor} \newcommand{\OptimizerstateMemory}{\OptimizerStateMemory} \newcommand{\RequestTimeInSystemLat}{\RequestTimeInSystem} \newcommand{\StoragePricePerByteTime}{\StorageCapacityPrice} \newcommand{\WeightMemoryWeights}{\WeightMemory} \newcommand{\WindingAndAmbientTemperatureTwo}{\AmbientTemperature} \newcommand{\BackemfVoltageBemf}{\BackEmfVoltage} \newcommand{\CoordinateReferenceFramesB}{\BodyReferenceFrame} \newcommand{\CameraframeThreedCoordinate}{\CameraFramePoint} \newcommand{\CartesianThreedPosition}{\CartesianPosition} \newcommand{\CommandTransportTimeBus}{\CommandTransportTime} \newcommand{\ContactForceVectorK}{\ContactPointForce} \newcommand{\ContactPointJacobianK}{\ContactPointJacobian} \newcommand{\ContinuousPeakCurrent}{\ContinuousCurrent} \newcommand{\CredibleDecelerationBrake}{\CredibleBrakingDeceleration} \newcommand{\OpenloopCrossoverFrequency}{\CrossoverFrequency} \newcommand{\PhaseLagDegradation}{\DelayPhaseLag} \newcommand{\DiffusionScheduleParameterK}{\DiffusionCumulativeSchedule} \newcommand{\DispatchtoadmissionIntervalDa}{\DispatchAdmissionInterval} \newcommand{\EmittedTokenCountOut}{\EmittedTokenCount} \newcommand{\FundamentalAndEssentialMatricesTwo}{\EssentialMatrix} \newcommand{\ForwardinvariantSafeSet}{\ForwardInvariantSafeSet} \newcommand{\FreespaceDepth}{\FreeSpaceDepth} \newcommand{\FundamentalAndEssentialMatrices}{\FundamentalMatrix} \newcommand{\TransmissionEfficiencyGear}{\GearboxTransmissionEfficiency} \newcommand{\HardwareAndCommoncauseRateOther}{\HardwareCommonCauseRate} \newcommand{\ContinuousPeakTorqueHold}{\HoldingTorque} \newcommand{\OptimalInertiamatchingRatio}{\InertiaMatchingRatio} \newcommand{\IntentleaseExpiryIntentexp}{\IntentLeaseExpiry} \newcommand{\LatentStyleStateEmbedding}{\LatentStyleVariable} \newcommand{\LinearBarrierDecayRateCbf}{\LinearBarrierDecayRate} \newcommand{\Momentum}{\LinearMomentum} \newcommand{\RotorAndLoadInertiaTwo}{\LoadInertia} \newcommand{\LqrGainAndWeights}{\LqrFeedbackGain} \newcommand{\CenterOfMass}{\MassCenterPosition} \newcommand{\TorqueAndBackemfConstants}{\MotorTorqueConstant} \newcommand{\NoisePredictionNetworkTwo}{\NoisedActionChunk} \newcommand{\ObservabilityMatricesNl}{\NonlinearObservationSpace} \newcommand{\ObservabilityMatrices}{\ObservabilityMatrix} \newcommand{\ContinuousPeakCurrentTwo}{\PeakCurrent} \newcommand{\ContinuousPeakTorque}{\PeakTorque} \newcommand{\PermissionloopPeriodTick}{\PermissionLoopPeriod} \newcommand{\PhaseInductanceAndResistance}{\PhaseInductance} \newcommand{\PhaseInductanceAndResistanceTwo}{\PhaseResistance} \newcommand{\InitialAndCeilingError}{\PositionErrorCeiling} \newcommand{\RenewaljitterAllowance}{\RenewalJitterAllowance} \newcommand{\ResidentStopDistanceSuffix}{\ResidentStopDistance} \newcommand{\CoefficientOfRestitution}{\RestitutionCoefficient} \newcommand{\RigidtransformTranslation}{\RigidTransformTranslation} \newcommand{\RotorAndLoadInertia}{\RotorInertia} \newcommand{\SamplingPeriodAndRate}{\SamplingPeriod} \newcommand{\SensorLeverarmVector}{\SensorLeverArm} \newcommand{\SequentialLoglikelihoodRatioM}{\SequentialLogLikelihoodRatio} \newcommand{\SinglestepImitationError}{\SingleStepImitationError} \newcommand{\SprtBoundariesLo}{\SprtLowerBoundary} \newcommand{\SprtBoundariesUp}{\SprtUpperBoundary} \newcommand{\LinearStatespaceMatrices}{\StateSpaceInputMatrix} \newcommand{\LinearStatespaceMatricesSys}{\StateSpaceSystemMatrix} \newcommand{\PertrialProbabilitiesTarget}{\TargetTrialSuccessProbability} \newcommand{\TorqueproducingCurrent}{\TorqueProducingCurrent} \newcommand{\TrackingerrorBound}{\TrackingErrorBound} \newcommand{\PertrialProbabilitiesFail}{\TrialFailureProbability} \newcommand{\TsdfAccumulatedVolumeVox}{\TsdfAccumulatedWeight} \newcommand{\VirtualDampingAndStiffness}{\VirtualDampingMatrix} \newcommand{\Radius}{\WheelRadius} \newcommand{\WindingAndAmbientTemperature}{\WindingTemperature} \newcommand{\CoordinateReferenceFramesW}{\WorldReferenceFrame} \newcommand{\ZerofailureTrialCount}{\ZeroFailureTrialCount} \newcommand{\ZeroMomentPointZmp}{\ZeroMomentPoint} \newcommand{\Glyph}[1]{#1} $$

16 Conclusion

Lecture slides for this chapter

Complete single-node ML systems atlas connecting data, model computation, framework lowering, accelerator execution, serving, operations feedback, and governance boundary.

Purpose

Seven-layer ML systems stack used as a chapter map: all seven layers (applications, operations, serving, training, models, frameworks, and hardware) are shaded evenly at a moderate level, so the chapter spans the whole stack; the data bar beside the stack has a moderate tint.

Architecture stack focus for this chapter.

What does mastering the full stack enable that expertise in any single layer cannot?

A single production decision travels through the entire stack. A data pipeline decides which events count as training signal. That signal shapes the architecture, which in turn fixes memory footprint and arithmetic intensity. Those properties constrain hardware choice, quantization strategy, serving latency, drift monitoring, and governance obligations. Mastered individually, each layer represents a valuable skill; mastered together, they confer the ability to reason across boundaries that no single specialty sees in full. An engineer who understands only compression can shrink a model, but cannot predict whether the accuracy loss matters for the deployment context. An engineer who understands only serving can optimize latency, but cannot trace a performance regression to a data pipeline change three stages upstream. Many of the costliest production failures arise at these boundaries, where every component passes its local tests yet the system as a whole misses its target. What endures is the ability to analyze a system before it is built, reasoning about how the constraints of Data, Algorithm, and Machine (D·A·M) will interact, where bottlenecks will emerge, and which architectural commitments will prove irreversible. The constraints that govern these interactions outlive any specific framework, hardware generation, or model family, because the cost of moving data, the speed of light, and the gap between an assumed and a measured bottleneck do not turn over with them. Thinking in systems rather than components separates an engineer who can build a part from one who can build the whole.

Learning Objectives
  • Trace how data, architecture, compression, hardware, serving, operations, and governance decisions propagate constraints across an ML system
  • Apply lighthouse-model reasoning to diagnose bottlenecks across cloud, mobile, edge, recommendation, and TinyML deployments
  • Synthesize core ML systems principles into a framework for reasoning across Data, Algorithm, and Machine constraints
  • Evaluate deployment trade-offs using latency budgets, memory and energy movement, drift, and responsibility constraints
  • Justify an engineering approach for emerging contexts such as embodied, composed, and multi-node systems, using cross-layer evidence to identify where single-node reasoning must widen its boundary

16.1 The System Is the Model

When a user asks a smartphone voice assistant a question, learned components convert speech to text, interpret intent, retrieve information, and generate a response within seconds (The AI Systems Moment). A failure in any stage, such as a drifted feature, a miscalibrated quantization range, or a queueing spike, degrades the answer even when the model weights are untouched. The system is the model: the behavior a user receives from a machine learning service is produced by the data pipeline, the trained weights, the execution stack, the serving path, and the monitoring loop together, never by the weights alone.

Every chapter since the introduction has given one stage of that voice-assistant request a mechanism and a cost. Responsible Engineering added the last constraint the book imposes, the obligations a system owes the people it affects. It showed that this constraint behaves like the latency and memory budgets before it, because it can be met only where every upstream stage preserved the freedom to meet it. An audit of outcomes for each subgroup, for example, is possible only if the data pipeline kept the subgroup labels the audit needs. Although each constraint was taught one layer at a time, the costliest failures arise where the layers meet.

A composite scenario, extending the calibration pitfall analyzed in Fallacies and Pitfalls rather than reporting any one incident, shows such a failure. To deploy an image classification model across a fleet of mobile devices, the architecture team chooses depthwise separable convolutions to factorize spatial filtering from channel projection. The compression team quantizes the resulting weights and activations to INT8 so they fit within on-chip static RAM (SRAM). The serving team brings end-to-end p99 latency inside a 50 ms target. Each team succeeded by its local metric, yet within weeks, accuracy dropped by four percentage points on specific firmware and device cohorts.

INT8 quantization fixes its clipping ranges during quantization-range calibration, permanently encoding the statistical distribution of the calibration images. On the affected cohorts, however, a firmware-specific preprocessing routine interpolated images differently and presented an altered input distribution to the quantized model. Because each team validated its component against standard inputs, no component failed in isolation and nothing crashed. Latency was evaluated end to end along the deployed request path, whereas accuracy was measured only as an aggregate scalar over an offline evaluation set. Users on the affected cohorts therefore received worse predictions that the system’s monitoring was never built to see, even though tracking accuracy separately for each device and firmware cohort from the first day of deployment would have shown the drop.

Vertical causal chain: INT8 calibration, then the firmware preprocessing path, then an input shift on one device cohort, ending in an accuracy drop marked in red.

A calibration choice surfaces as a cohort accuracy drop three stages downstream.

Most failures of this kind start at an interface between components, so the main task is to test the interfaces before they fail. Traditional software engineering treats functional correctness as decoupled from the underlying hardware and often treats the “model” as a weights checkpoint, a single file of floating-point numbers. In machine learning systems, however, the weights are often not the most fragile part, because statistical behavior is physically inseparable from the pipelines, memory hierarchies, and accelerators that train, serve, and monitor them. A model that reaches high benchmark accuracy still fails if it ingests corrupted features, and a model that converges cleanly during training still fails if it misses its deployment latency budget.

↩︎ The finding that model code is a small fraction of a production ML system, whose surrounding pipelines, serving, and monitoring are larger and more enduring, is established in From Code-Defined Logic to Data-Defined Behavior.

The fleet failure cost accuracy, but the same coupling between layers also decides how far a method can scale. The bitter lesson teaches that general methods scaling with computation outrun hand-encoded heuristics (The Bitter Lesson). Scaling such a method raises data movement, computation, and overhead together, and different layers of the stack pay each of those costs. The iron law of ML systems (principle 3) measures the cost of that scale, and it sits at the center of this discipline because it splits execution time into three terms, the time to move data, the time to compute, and fixed overhead, each with its own engineering lever.

Building intelligence requires more than a good statistical algorithm. It also requires honoring the silicon contract (principle 4), under which each architecture saturates one hardware resource first and the design must target that resource. A recommendation model, for example, fills accelerator memory with its embedding tables long before it saturates arithmetic, so a faster arithmetic unit leaves it no faster.

System capabilities therefore emerge from co-design across the Data, Algorithm, and Machine (D·A·M) triad rather than from isolated algorithmic breakthroughs. The transformer architecture (Vaswani et al. 2017) scaled into models such as GPT-3 and Llama 2 (Brown et al. 2020; Touvron et al. 2023) only because decisions in other layers made attention affordable: IO-aware attention kernels that keep intermediate scores in on-chip memory, low-precision tensor units that raise the peak arithmetic rate, and partitioning of tensor state across accelerators.

Vaswani, Ashish, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. 2017. “Attention Is All You Need.” Advances in Neural Information Processing Systems (NeurIPS) 30: 5998–6008.
Brown, Tom B., Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared Kaplan, Prafulla Dhariwal, Arvind Neelakantan, et al. 2020. “Language Models Are Few-Shot Learners.” Advances in Neural Information Processing Systems 33: 1877–901. https://doi.org/10.48550/arxiv.2005.14165.
Touvron, Hugo, Louis Martin, Kevin Stone, Peter Albert, Amjad Almahairi, Yasmine Babaei, Nikolay Bashlykov, et al. 2023. “Llama 2: Open Foundation and Fine-Tuned Chat Models.” arXiv Preprint arXiv:2307.09288.

↩︎ IO-aware attention tiling, which keeps attention scores in on-chip memory, is established in FlashAttention: IO-aware attention optimization.

Checkpoint 16.1: Systems thinking

Check that you can trace the system’s dependencies, feedback loops, and request path across its boundaries.

The integration

The holism

Tracing a request end to end exposes that cross-layer coupling, because every layer of the stack enforces physical and statistical constraints on the next. Data curation and selection first bound what the learner sees, after which architectures, training systems, and frameworks lower the resulting computation onto hardware. Compression, acceleration, and benchmarking then move the physical boundaries before serving, operations, and responsible engineering hold the result to tail-latency budgets, drift, and subgroup outcomes in production. Because these stages form a tightly coupled system rather than a sequence of isolated handoffs, engineering decisions never remain localized, and an engineer who optimizes a single layer in isolation cannot predict how the change will propagate.

The rest of the chapter makes that claim quantitative. The five lighthouse models come first, each traced from its home regime to the lever that paid off and the lever that was wasted. The thirteen quantitative principles follow, regrouped by the three questions the introduction asked of every ML system: what shapes its predictions, what limits its execution, and what evidence supports its deployment. The dual mandate is then measured on two lighthouses, DLRM for trustworthy behavior and the GPT-2 family for physical deliverability. The same principles then forecast where constraints tighten next, from microcontrollers to composed services and fleets. The chapter closes on the responsibility that follows from building such systems, the cross-boundary forms of the book’s recurring mistakes, and a final trace of the voice-assistant request through every layer.

Self-Check: Question
  1. A production image classifier deployed across a mobile device fleet shows a 4-percentage-point drop in accuracy on specific handset cohorts. The weights file is unchanged, the compression team verified INT8 kernel speedups, and the serving team confirmed a P99 latency of 48 ms (under the 50 ms SLO). Which diagnostic posture is most consistent with the ‘system is the model’ thesis?

    1. Focus the investigation exclusively on serving execution, because runtime inference is the only stage operating during production.
    2. Trace the interaction between INT8 quantization scaling factors and firmware-specific image preprocessing paths, because production behavior is defined by the weights combined with the data pipeline, runtime hardware, and monitoring loop.
    3. Escalate to the architecture team to train wider convolutional layers, because an unchanged weights file implies that any remaining error must stem from model capacity.
    4. Treat the 4-point regression as acceptable random noise, because all engineering teams independently satisfied their local component metrics and the aggregate P99 latency is within budget.
  2. True or False: If every engineering team in an ML organization independently satisfies its isolated component metric (e.g., architecture achieves an \(8.7\times\) FLOP reduction, compression achieves \(4\times\) weight reduction, and serving meets its P99 latency SLO), the integrated system is mathematically guaranteed to meet its end-to-end accuracy and correctness requirements in production.

  3. The conclusion argues that ‘the system is the model.’ Explain why treating the model solely as a static weights file (e.g., a 500 MB floating-point binary) fails in production, and define what constitutes the ‘true model.’

See Answers →

16.2 Lighthouse Models: Constraint Propagation

Predicting how an engineering change propagates across layers starts with identifying which physical resource limits the workload. Each of the book’s five lighthouse models has a home regime defined by the resource it saturates first under typical operating conditions: ResNet-50 is compute-bound, decode for GPT-2 and Llama is bandwidth-bound, DLRM is capacity-bound, MobileNetV2 is compute-bound in its efficient regime, and keyword spotting (KWS) is power-bound. MobileNetV2’s efficient regime is the whole network running on the phone’s neural processing unit (NPU) it was built for, where a few watts buy little arithmetic.

Each regime names the lever that pays. Adding peak arithmetic throughput to a batch-one large language model (LLM) decoder leaves token latency untouched because every token waits on high-bandwidth memory (HBM) weight reads. Adding memory bandwidth to a batched ResNet-50 convolution instead buys nothing once its arithmetic intensity, the operations it performs per byte moved, sits right of the ridge point, the intensity at which the bandwidth ceiling meets the compute ceiling. Roofline modeling (The roofline model) turns that comparison into a quantitative upper bound on attainable speed (Williams et al. 2009). Across the book, each lighthouse rewarded the lever aimed at its limiting term and wasted the effort aimed anywhere else (table 1).

Williams, Samuel, Andrew Waterman, and David Patterson. 2009. “Roofline: An Insightful Visual Performance Model for Multicore Architectures.” Communications of the ACM 52 (4): 65–76. https://doi.org/10.1145/1498765.1498785.

↩︎ The five lighthouse models and their diagnostic execution regimes are established in Lighthouse models put the iron law into practice.

Table 1: Lighthouse Constraint Traces: Each lighthouse probes one home regime, and the lever that paid off was the one aimed at that regime’s limiting term. A regime describes a workload on a machine rather than a model name, so a lighthouse crosses regimes when batch size, phase, or precision changes.
Lighthouse Home Regime Limiting Term Lever That Paid Lever Wasted
ResNet-50 Compute-bound Compute, \(\Operations/(\PeakRate \cdot \EfficiencyHw)\) Batching that reuses filter weights across inputs; reduced-precision tensor arithmetic More memory bandwidth once batched convolutions sit right of the ridge point
GPT-2/Llama decode Bandwidth-bound Data movement, \(\DataVolume/\Bandwidth\) Batching across requests; fewer bytes per weight; managing the per-request key-value cache More peak arithmetic throughput, or compute-only kernel tuning at batch one
DLRM Capacity-bound Memory capacity, a precondition before any term applies Placing and sharding embedding tables across memory tiers; caching frequently accessed rows Faster dense arithmetic for the small fully connected layers
MobileNetV2 Compute-bound in its efficient regime Compute within a phone’s power envelope; depthwise layers cross to bandwidth-bound Depthwise separable convolutions, then INT8 once depthwise layers became bandwidth-bound Further operation cuts on layers already bound by bandwidth
Keyword spotting (KWS) Power-bound Energy per inference within a milliwatt budget A sub-megabyte INT8 model with a tensor arena planned at build time Streaming audio to the cloud, whose radio transmission costs more energy than local inference

The regime belongs to the workload on a machine, so the same model can change regime, and the regime has to be checked before an optimization is chosen. GPT-2 training is compute-bound even though its decode is bandwidth-bound, because a training step reuses each weight across every token in the batch. ResNet-50 became input-bound in Model Training, starved by a data pipeline that could not keep the accelerator fed.

Precision and the machine move the regime as well. INT8 arithmetic doubles the H100’s peak rate without raising its memory bandwidth, so it doubles the ridge point. A ResNet-50 layer whose activations still move at 16 bits does not halve its bytes, so its intensity rises less than the ridge does, and the layer can fall below the doubled ridge and become bandwidth-bound (Memory bandwidth bounds). MobileNetV2 changes regime with the machine. The network that is compute-bound on the phone NPU falls below the far higher ridge of an H100, where its depthwise layers wait on memory bandwidth (Heterogeneous SoC Design). A recommendation model larger than DLRM, a larger decoder, a faster vision network, or a smaller keyword spotter differs from its lighthouse in scale, not in which term dominates, so the diagnosis carries forward to models that do not yet exist.

A regime diagnosis guides one decision, but a deployed model is the product of many decisions, and each one constrains the next. Table 2 follows MobileNetV2 through nine phases of the book, from the deployment tier’s envelope through architecture, training, data selection, compression, acceleration, benchmarking, serving, and runtime operations, and every engineering decision along the way narrows the options available downstream.

Table 2: The Lighthouse Journey (MobileNetV2): Applying the book’s nine phases to one model shows how decisions in one domain (for example, architecture) propagate constraints and opportunities into downstream domains (for example, hardware acceleration and monitoring).
Journey Phase System Lens MobileNetV2 Implementation
Foundations (System Paradigms) Deployment Tier Constraints Mobile tier sets a watt-scale power, thermal, and battery envelope that every later phase must respect
Architecture (Network Architectures) Algorithmic Efficiency Depthwise Separable Convolutions: 8.7× fewer FLOPs for a representative 3-by-3, 256-output-channel layer and 13.7× fewer operations than ResNet-50 at ImageNet scale
Training (Model Training) Throughput vs. Latency Trained at high-throughput batch sizes for a model that will serve single requests at low latency
Data Selection (Data Selection) Capacity-Matched Augmentation Milder augmentation matched to a compact network’s limited capacity, validated against deployment invariances such as device and lighting variation, at no inference cost
Compression (Model Compression) Navigating the Pareto Frontier INT8 Quantization: FP32 uses 4× and FP16 uses 2× the per-value storage of INT8, with accuracy revalidated per deployment
Acceleration (Hardware Acceleration) Honoring the Silicon Contract Mapping kernels to mobile neural processing units (NPUs) (for example, Apple Neural Engine) to maximize hardware execution efficiency
Benchmarking (Benchmarking) Component vs. End-to-End Confirming that compression and accelerator gains survive the full pipeline by separating accelerator latency from preprocessing and transfer, and rechecking INT8 accuracy on edge cases such as unusual lighting
Serving (Model Serving) Respecting the Latency Budget \(\text{p99} < 50\) ms constraint; optimizing preprocessing (resize/normalize) to avoid CPU bottlenecks
Operations (ML Operations) Managing System Entropy Drift Monitoring: Detecting distribution shifts and tracking cohort-level accuracy across heterogeneous device populations and lighting conditions

Decisions in one row constrain options in the next. Depthwise separable convolutions cut the operation count, but depthwise filtering reduces cross-channel reuse and often leaves these layers bandwidth-bound on mobile hardware. When profiling confirms that regime, a further cut in operations buys little, and the compression row’s reduction in bytes per value becomes the next lever. That lever pays only if the acceleration row confirms that the mobile NPU executes those INT8 operators, and only if the benchmarking row shows the gain surviving preprocessing and transfer. Every lighthouse follows the same rule, where an optimization in one layer pays off only when the adjacent layers’ physical and statistical constraints permit it.

Self-Check: Question
  1. A production recommender workload is dominated by embedding tables larger than one accelerator’s memory where engineers spend significant effort deciding where data physically resides across storage tiers rather than optimizing dense matrix math. Which lighthouse model embodies this constraint regime, and how does its primary bottleneck differ from low-batch GPT-2/Llama decoding?

    1. MobileNetV2; it is capacity-bound on microcontrollers, whereas autoregressive decoding is bound by network packet round-trip times.
    2. ResNet-50; it is capacity-bound by image batch activation footprints in host DRAM, whereas LLM decode is compute-bound.
    3. Keyword Spotting (KWS); it is capacity-bound by microcontroller flash storage, whereas LLM decode is strictly compute-bound by tensor core peak FLOP/s.
    4. DLRM; it is capacity-bound by embedding tables larger than one accelerator’s memory requiring physical data placement design, whereas low-batch LLM decode is memory-bandwidth-bound due to streaming weights with minimal arithmetic reuse per token.
  2. A team serving GPT-2 at batch size one on an H100 proposes two investments: hand-tuning the matrix-multiply kernels to raise achieved FLOP/s, or batching concurrent requests and storing weights in fewer bytes. Using the chapter’s lighthouse trace, which investment pays off, and why?

    1. Kernel tuning, because GPT-2 is compute-bound at every batch size and phase.
    2. Batching and fewer bytes per weight, because batch-one decode is bandwidth-bound: its data-movement term exceeds its compute term, so only levers that reuse each weight across more tokens or move fewer bytes per token shorten the step.
    3. Neither, because GPT-2 decode is capacity-bound like DLRM and must first be sharded across several devices.
    4. Kernel tuning, because a high ridge point means every workload gains more from compute than from bandwidth.
  3. Order the following phases of the MobileNetV2 lighthouse journey in their chronological lifecycle order as constraints propagate from initial requirements through deployment operations:

  1. Compression (INT8 quantization navigating the Pareto frontier)
  2. Acceleration (Mapping operators to mobile NPUs under the silicon contract)
  3. Foundations (Establishing battery, thermal, and machine constraints)
  4. Architecture (Depthwise separable convolutions reducing FLOPs)
  5. Operations (Cohort-level drift monitoring across heterogeneous devices)
  6. Serving (Enforcing P99 latency budgets under 50 ms)

See Answers →

16.3 Thirteen Quantitative Principles

Whether an engineer alters an embedding table layout in DLRM, doubles batch size in ResNet-50, or quantizes an attention layer from FP16 to INT8, the outcome follows from physical bounds, empirical trade-offs, and operational feedback rather than guesswork. Reasoning about those cross-layer effects before profiling is the job of the thirteen quantitative principles the book accumulated across its four parts (table 3).

The thirteen principles are not all the same kind of statement. Three are hard bounds (the Pareto frontier, the arithmetic intensity law, and Amdahl’s Law) and two are decompositions (the iron law and the energy-movement principle). Two are fitted models (statistical drift and bias feedback) and two are policies whose parameters a product decision sets (the verification gap and the latency budget). Four are heuristics (data-as-code, data gravity, the silicon contract, and training-serving skew). The silicon contract is a heuristic because it predicts which resource an architecture saturates first, a prediction that the arithmetic intensity bound then tests. The Pareto frontier, by contrast, is a bound because no feasible design lies beyond it. Each principle box on the part pages names its kind, and each principle is reliable only within its stated assumptions.

Table 3: Thirteen Quantitative Principles: Each tool appears in the part where its governing constraint or diagnostic use first becomes visible. The collection combines bounds, decompositions, fitted models, policy requirements, and heuristics. Each row holds under its stated assumptions; together they provide a shared analytical vocabulary for system design, optimization, and deployment.
# Principle Part Core Equation/Statement What It Predicts
1 Data-as-Code Principle I: Foundations Learned behavior \(\approx\text{Train}\)(training data, training procedure) Data changes behavior; other inputs also matter
2 Data-Gravity Principle I: Foundations Move compute toward data when repeated transfer costs exceed placement costs Depends on volume, reuse, network, and compute mobility
3 Iron Law of ML Systems II: Development \(\Time=\DataVolume/\Bandwidth+\Operations/(\PeakRate \cdot \EfficiencyHw)+\Latency\); overlap ranges from max to sum D·A·M factors multiply; stages add or overlap
4 Silicon Contract II: Development Each architecture saturates one resource (compute, bandwidth, or capacity) first Design must target the resource saturated first
5 Pareto Frontier III: Optimization No feasible point is at least as good on every objective and strictly better on one Along the frontier, improving one objective worsens another
6 Arithmetic Intensity Law III: Optimization \(\AttainableComputeRate \le \min(\PeakRate,\; \ArithmeticIntensity \times \Bandwidth)\) More compute cannot raise a bandwidth ceiling
7 Energy-Movement Principle III: Optimization \(\TotalEnergy\approx \DataVolume\times \EnergyPerByteMoved+\Operations\times \EnergyPerOperation\); dynamic RAM (DRAM) to FLOP cost ratio: 173–582× Total energy depends on bytes moved, operations, and per-event costs
8 Amdahl’s Law III: Optimization \(\text{Speedup} = \frac{1}{(1-\ParallelFraction) + \frac{\ParallelFraction}{\AcceleratedFractionSpeedup}}\) For fixed work, the serial fraction caps parallelism gains
9 Verification Gap IV: Deployment Deployment-population success probability must meet the specified target at the stated task-error tolerance Specify distance, tolerance, population, and required success probability
10 Statistical Drift Diagnostic IV: Deployment \(\AccuracyAfterDeployment(\DeploymentAge)\approx\InitialAccuracy-\FittedSensitivity\cdot\StatisticalDivergence\) A local fit; drift need not lower quality
11 Training-Serving Skew Diagnostic IV: Deployment \(\TrainingServingSkew=\mathbb{E}[\lvert \ServingPathPredictor(\ModelInput)-\TrainingPathPredictor(\ModelInput)\rvert]\) Output mismatch signals risk, not accuracy loss
12 Latency Budget Principle IV: Deployment \(\Pr[\EndToEndRequestLatency\le \CompletionDeadline]\ge \TargetCompletionQuantile\), where \(\EndToEndRequestLatency\) sums the request-path delays The product SLO selects \(\TargetCompletionQuantile\) and the deadline \(\CompletionDeadline\)
13 Bias Feedback Model IV: Deployment \(\GroupDisparity(\FeedbackIntervalCount)\approx\GroupDisparity(0)\BiasFeedbackFactor^\FeedbackIntervalCount\) with fitted \(\BiasFeedbackFactor\) Feedback may amplify harm; measure and intervene

Notation Guide for table 3: The verification-gap row is stated in words; its formal version on the part page (principle 9) uses the task-specific distance metric \(\TaskDistance\) and the acceptable error tolerance threshold \(\TaskErrorTolerance\). Finite tests estimate the deployment success probability with uncertainty; an evaluation must separately state the statistical confidence level of its interval or bound. \(\TargetCompletionQuantile\) is the target success probability for latency deadline \(\CompletionDeadline\), and \(\BiasFeedbackFactor\) is the amplification factor compounding disparity \(\GroupDisparity\) at step \(\FeedbackIntervalCount\). The drift row restates the degradation equation (equation 1.1), in which \(\FittedSensitivity\) is the sensitivity fitted from labeled outcomes and \(\StatisticalDivergence\) measures how far the current input distribution has moved from the training distribution. \(\TrainingServingSkew\) is the expected absolute difference between serving-path and training-path outputs on the same input. In the iron-law row, \(\DataVolume\) is the bytes moved, \(\Bandwidth\) the memory bandwidth, \(\Operations\) the operations performed, \(\PeakRate\) the peak arithmetic rate, \(\EfficiencyHw\) the fraction of that peak achieved, and \(\Latency\) the fixed overhead. Data transfer can overlap with computation, so the time for those two terms lies between their maximum (full overlap) and their sum (no overlap). In the arithmetic-intensity row, \(\AttainableComputeRate\) is the attainable compute rate and \(\ArithmeticIntensity\) the arithmetic intensity, the operations performed per byte moved. In the energy-movement row, \(\TotalEnergy\) is the total energy, \(\EnergyPerByteMoved\) the energy per byte moved, and \(\EnergyPerOperation\) the energy per operation. In efficiency bounds, \(\AcceleratedFractionSpeedup\) is the speedup factor applied to the parallelizable fraction \(\ParallelFraction\).

The thirteen principles are not independent axioms. The conservation-of-complexity heuristic1 introduced in Part I connects them into an integrated framework, because the complexity a decision displaces usually lands under another principle. The heuristic holds that simplifying one part of a system tends to move complexity to another part rather than remove it. In Part III, model compression demonstrated this displacement at the scale of a single model: pruning sacrifices capacity, quantization sacrifices precision, and distillation expends training compute. At the scale of the entire system the discipline is the same. After any local simplification, trace where the displaced complexity has migrated. The heuristic serves as a diagnostic rather than a physical conservation law. Accidental complexity, work the task never required such as an oversized model, can be removed outright by thoughtful design. Systemic complexity, which the task itself demands, often shifts elsewhere instead, as when quantizing a model moves it into validation.

1 Conservation-of-complexity heuristic: Tesler’s Law, a design aphorism, says that an application’s irreducible complexity must be handled somewhere in the interaction among user, application, and platform (Tesler 1984). Extending it to all ML-system complexity is an analogy, which is why the heuristic directs a search for displaced costs rather than guaranteeing that an equal compensating cost exists.

Tesler, Larry. 1984. The Law of Conservation of Complexity. Web page.

The part pages introduced the principles in the order the book needed them. Read together, they sort more usefully by the three questions the introduction asked of every ML system (Summary): what shapes its predictions, what limits its execution, and what evidence supports its deployment. The three groupings that follow keep each principle’s number, so every principle can still be found on its part page. Only two principles move away from the others of their part. Data gravity (2) joins the execution principles because it decides where computation runs, and bias feedback (13) joins data-as-code because it changes the data the next model learns from.

What shapes predictions (principles 1 and 13)

A single change to a data-cleaning filter can alter what a model predicts without touching a line of model code, and an automated credit model can satisfy every throughput and convergence target while systematically compounding disparities against underserved groups across retraining cycles. The data-as-code principle (1) explains the first behavior: because the training dataset dictates learned behavior, a modification to data curation is a behavioral change requiring the same rigorous versioning, code review, and regression testing applied to source code.

The bias feedback model (principle 13) extends that dependency past launch, because a deployed model’s predictions shape the data its successor trains on. It treats disparity as a quantity that compounds across retraining cycles at a fitted rate, turning fairness into a stability question about the deployment loop that must be intercepted by disaggregated monitoring rather than discovered in aggregate accuracy. Once the data that shapes predictions is fixed, the next question is what physical bounds govern the work of training and running the model on that data.

↩︎ The bias feedback model, with the fitted factor that projects when a disparity that met its release threshold will exceed it, is established in Operate: Fairness as loop stability.

What limits execution (principles 2–8)

Moving a petabyte-scale dataset between cloud regions costs days of transfer time and substantial egress fees, which readily justifies moving compute to the data rather than the reverse. The data-gravity principle (2) formalizes this placement constraint: where data volume resides dictates where computation can affordably execute.

↩︎ The transfer time and egress cost that make a large dataset the gravitational center of an architecture are established in Data gravity.

The lighthouse models carry the same placement constraint into execution. In DLRM, embedding tables that outgrow a single accelerator’s memory are sharded across accelerators and memory tiers, and where each shard sits decides how many lookups must cross a slower link, so the execution system is engineered around where the parameters physically reside. Compute-to-data placement recurs across deployment environments precisely because moving large, low-reuse datasets saturates interconnects.

Once placement fixes where the data sits, the iron law (principle 3) and the silicon contract (principle 4) govern how efficiently the work executes there. The iron law’s multiplicative D·A·M form connects data scale (\(\text{Samples/Task}\)), algorithmic work (\(\text{FLOPs/Sample}\)), and machine pace (\(\text{Seconds/FLOP}\)), while its three-term physical decomposition isolates data movement, computation, and overhead. The two forms describe the same execution time, and the sum, which splits that time by what the machine waits on, is the form a bottleneck diagnosis uses. The silicon contract predicts which term limits performance on a given architecture-hardware pair. Measured shapes, kernels, and runtime conditions confirm which regime of table 1 actually applies. Diagnosing whether an execution path is compute-bound, bandwidth-bound, or capacity-bound determines which optimizations yield speedup and which waste engineering effort. Execution time drops most when engineers target the limiting term directly rather than distributing effort uniformly.

↪ The bottleneck diagnostic that pairs each limiting iron-law term with the optimizations that work and those that are wasted is collected for reference in Acting on the limiting term.

The remaining four principles of the second question build on one another. The Pareto frontier (principle 5) identifies the designs that no alternative beats on every objective at once, so improving one objective along the frontier requires a trade-off against another within the same feasible design set. The arithmetic intensity law (principle 6) then diagnoses, for each candidate design on that frontier, whether compute or bandwidth caps the speed of its kernels on the target machine.

Moving data through memory costs energy as well as time. The energy-movement principle (principle 7) captures that cost by combining per-event costs with event counts. Under the reference energy constants, one DRAM access costs about 173–582× as much as one arithmetic operation. The DRAM-versus-FP32 ratio from hardware acceleration (Hardware Acceleration) sits at the lower end of that range, and the cheaper FP16 operation sets the upper end. Which cost dominates a whole workload still depends on how many of each event occur. Even after memory traffic and kernel execution are tuned, Amdahl’s Law (principle 8) sets the ceiling on any parallelism gain, explaining why data loading and preprocessing can become bottlenecks in highly optimized systems.

↩︎ The compute-versus-bandwidth-boundary and hardware balance (\(\RooflineRidgePoint\)) are established in Hardware ridge points.

Jacob, Benoit, Skirmantas Kligys, Bo Chen, Menglong Zhu, Matthew Tang, Andrew Howard, Hartwig Adam, and Dmitry Kalenichenko. 2018. “Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2704–13. https://doi.org/10.1109/cvpr.2018.00286.

MobileNetV2 touches all four. Depthwise separable convolutions move the Pareto frontier, buying far fewer operations for a small loss in accuracy (Sandler et al. 2018). INT8 quantization exploits the arithmetic intensity law by raising arithmetic intensity through reduced memory traffic (Jacob et al. 2018). The energy it saves follows the energy-movement principle because fewer bytes move, provided the NPU executes the INT8 operators natively, while Amdahl’s Law bounds end-to-end speedup when host-side preprocessing remains unaccelerated. Microcontroller workloads such as KWS compress these trade-offs further, operating under sub-megabyte memories that leave little room for avoidable overhead.

↩︎ Compression moves a model along the accuracy-efficiency frontier, as established in The accuracy-efficiency frontier.

What evidence supports deployment (principles 9–12)

A system that meets its throughput, memory, and accuracy targets on the bench can still fail silently in production when live inputs or serving pipelines diverge from the test harness. The verification gap (principle 9) names the distance between what finite tests can show and correctness on every future input. Because that gap never closes, the principle instead specifies the required success probability over a stated deployment population and error tolerance, and finite testing estimates whether the system meets that requirement at a stated statistical confidence level. Once the model is serving live traffic, the statistical drift diagnostic (principle 10) detects when that deployment population has changed, and labeled outcomes measure how much the shift costs in accuracy. The training-serving skew diagnostic (principle 11) catches internal divergence when training and serving paths compute the same features differently. The latency budget (principle 12) holds the entire request path to the tail quantile the product selects.

↩︎ Reusing training-time transformation parameters at serving time, the consistency imperative that prevents skew, is established in Training-serving consistency.

Monitoring infrastructure, drift detection, feature stores, and disaggregated subgroup metrics exist to make these principles measurable and to trigger corrective action. A recommendation system that achieves high offline accuracy still requires parity checks when training-serving skew corrupts feature pipelines (principle 11) and outcome auditing when user behavior shifts seasonally (principle 10).

↩︎ The monitoring infrastructure and drift quantification that surface these silent failures are established in Production Monitoring.

The integrated framework

Although the three questions group the thirteen principles by job, a single engineering decision activates principles across groups at once. Quantizing a model from FP16 to INT8 navigates the Pareto frontier (principle 5), trading numerical precision for memory traffic, and its consequences spread across the stack. Quantization alters the model’s silicon contract (principle 4), shifting its operating point on the arithmetic intensity curve (principle 6) and transforming its energy profile (principle 7). In deployment, the latency budget (principle 12) dictates whether the resulting speedup meets the service-level objective (SLO), while the verification gap (principle 9) demands verifying that the compiled serving graph preserves the empirical accuracy measured during compression testing.

The opening fleet failure escaped at exactly this verification step. Compression testing accepted the quantized model on images from the evaluation pipeline, while the firmware path presented a different population. The training-serving skew diagnostic (principle 11), comparing model outputs from the two preprocessing paths on the same captured inputs, is the measurement that would have exposed the mismatch before the affected cohort did. In that comparison the evaluation pipeline, which produced the calibration images, plays the role the diagnostic assigns to the training path, and the firmware path plays the serving path. The verification gap names why the failure escaped; the skew diagnostic names how to catch it.

The trace touched seven of the thirteen principles, and a different decision would have touched a different set. Had the same model moved off the device to a cloud endpoint, data placement (principle 2) would have entered, because every input image would then cross the network. Had preprocessing stayed on the host CPU while the NPU ran the faster INT8 kernels, Amdahl’s Law (principle 8) would have bounded how much of that speedup the request path could see. The principles activate in turn as a decision moves from model representation to hardware execution to production validation, so a deployment proposal can be checked against the same principles before anyone writes code.

Checkpoint 16.2: Applying the principles

A colleague proposes quantizing your model from FP16 to INT8 to reduce serving costs.

Trace the principles

In the part order of table 3, the principles form a cycle rather than a pipeline (figure 1), a property that the three-question grouping hides. The deployment principles (9–13) turn runtime telemetry into evidence that sends work back to the data foundations, through remediations such as canary rollbacks, fallback heuristics, dataset augmentation, model retraining, or kernel retuning, so each production lesson becomes the starting condition of the next design pass. Bias feedback (13) belongs with them because its feedback factor can be fitted only from retraining cycles after the model is serving. The conservation-of-complexity heuristic sits at the center of that cycle because every pass around it asks where the complexity displaced by the previous decision has landed.
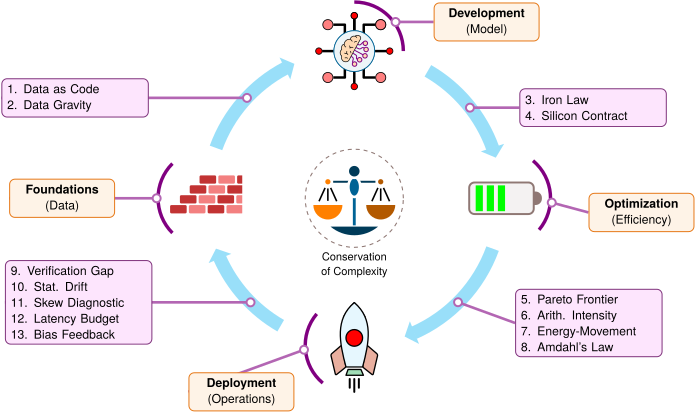
Figure 1: The Cycle of ML Systems (13 Principles): A four-phase systems engineering lifecycle organized around the conservation-of-complexity heuristic. The phases connect in a feedback cycle, and the thirteen principles sit along the transitions by the part that develops them, spanning bounds, decompositions, fitted models, policy requirements, and design heuristics whose assumptions must be checked. Icons mark the phases: bricks for the data foundations, a neural network for model development, a battery for the efficiency budget of optimization, and a rocket for launch into deployment.

The diagnostic framework is collected for reference in The D·A·M Taxonomy, and the reference constants for back-of-the-envelope calculations appear in System Assumptions. Tracing a quantization proposal through the principles it touches tests a single intervention, but in production a system must meet two broader commitments at once, keeping learned behavior trustworthy over time and delivering it within physical and economic limits, and the same principles measure both.

Self-Check: Question
  1. According to the Energy-Movement Principle (\(E_{\text{total}} = \sum_j N_j E_j\)), accessing off-chip DRAM requires approximately 100 to 1,000 times more energy than executing a single FP16 or FP32 arithmetic operation. What is the direct systems design implication of this physical reality?

    1. Inference engines should prioritize minimizing total ALU operations above all else, even if intermediate tensors must be repeatedly written to and read from off-chip DRAM.
    2. Hardware accelerators consume identical energy regardless of whether memory accesses hit on-chip SRAM or off-chip DRAM, because memory controller power is fixed.
    3. Quantization saves energy exclusively by simplifying ALU multiplication logic, while memory traffic volume has negligible impact on total package power.
    4. Architectures and runtimes should evaluate on-chip reuse and reduced memory traffic, counting accesses at their actual width and arithmetic operations to determine the energy savings.
  2. True or False: The conservation-of-complexity heuristic is an exact physical conservation law of computer science that proves every simplification in an ML pipeline interface creates an identical, mathematically equal compensating burden in another component.

  3. The thirteen quantitative principles are unified by a central meta-heuristic known as the ____ heuristic, which reminds engineers that simplifying one interface often displaces validation, state, or operational burdens to another part of the system.

  4. In the Cycle of ML Systems diagram in figure 1, the Deploy phase contains an explicit feedback arrow returning to Foundations (Data). Explain what production signals activate this feedback loop and why automated rollback is insufficient when the cause is external statistical drift.

See Answers →

16.4 The Dual Mandate Revisited

A recommendation model that ranks well on launch day can, six months later, be serving a population that its own rankings shaped, on hardware whose cost per query decides whether the service survives. The introduction named this pair of demands the dual mandate, and the thirteen principles make both halves measurable end to end on the book’s lighthouses.

↩︎ The dual mandate, trustworthy learned behavior delivered within the available time, memory, energy, and cost, is established in The AI Systems Moment.

Trustworthy learned behavior

DLRM carries the first half, because a recommendation service can pass its offline launch evaluation and still lose trustworthiness in production. At launch, the verification gap (principle 9) bounds what finite testing actually established over the evaluation population. Once live traffic arrives, training-serving skew (principle 11) can attack the model from inside when the online embedding lookup and the offline training pipeline compute a feature differently. Over time, the statistical drift diagnostic (principle 10) applies the degradation equation’s local fit (equation 1.1) to production telemetry, using divergence over user and item features as the early signal and delayed click and conversion outcomes as the confirmation. Across retraining cycles, the bias feedback model (principle 13) closes the loop, since items and creators that receive exposure generate the engagement data that earns them more exposure, and the resulting disparity can amplify or diminish according to a fitted factor \(\BiasFeedbackFactor\). Trust therefore has to be measured continuously, with alarms and a response plan, rather than certified once at launch, and that continuous service survives only if the hardware beneath it can deliver each query within its physical and economic budget.

Physical deliverability

GPT-2 carries the second half, and its family at scale shows the physics most sharply. Llama 2 70B is a decoder-only transformer of the same design with about 47× as many parameters as GPT-2’s 1.5-billion-parameter release. The larger scale does not move batch-one decode off the bandwidth side of the ridge point, because every generated token still reads every weight once. Serving one Llama 2 70B token on two H100s makes that cost concrete.

↩︎ The intensity of batch-one decode, about 1 FLOP/byte in FP16 because each weight read feeds a single multiply-accumulate, is established in Autoregressive decoding.

In FP16 the 70-billion-parameter model holds about 140 GB of weights, and each token costs about 140 GFLOP, two FLOPs per parameter. Sharded evenly across two NVIDIA H100s with an aggregate bandwidth of 6.70 TB/s and an aggregate FP16 peak of 1978 TFLOP/s (NVIDIA H100 (reference machine)), the iron law (principle 3) gives a memory-transfer lower bound \(\IronLawMemoryTime\) of about 20.9 ms. The peak-compute lower bound \(\IronLawComputeTime\) is about 0.07 ms, a ratio of 295.2×. The calculation is the decode floor of equation 13.14 and the GPT-2 XL throughput ceiling of Optimization by intensity regime, repeated at larger scale.

The arithmetic intensity law (principle 6) accounts for that 295.2× gap. Dividing memory time (\(\DataVolume/\Bandwidth\)) by compute time (\(\Operations/\PeakRate\)) gives the hardware ridge point (\(\PeakRate/\Bandwidth\)) divided by the workload’s arithmetic intensity (\(\Operations/\DataVolume\)). Batch-one decode has an intensity of about 1 FLOP/byte, far left of the ridge in the margin roofline, which is why the gap is so wide. Sharding does not move the ridge, because it doubles peak rate and bandwidth together. The bound leaves out KV-cache traffic, activations, attention over the cache, interconnect communication, and dispatch overhead, so only profiling establishes the realized step time. Compute-only tuning can approach the 0.07 ms bound but cannot lower the 20.9 ms one. Batching, which reuses each weight across requests, and quantization, which moves fewer bytes per weight, are the levers that can.
Idealized batch-one Llama decode point plotted to the left of the roofline ridge on an H100 chart.

In this batch-one lower-bound model, decode sits left of the roofline ridge in the bandwidth-bound regime.

This estimate turns a physical bound into a diagnosis whose architectural consequence follows from the silicon contract (principle 4). Accelerators are provisioned and purchased by peak arithmetic throughput, yet this workload saturates memory bandwidth first, so deliverable token generation speed is governed by bytes per second transferred from memory rather than by peak FLOP/s. The energy-movement principle (7) highlights the same weight traffic, since a DRAM access costs far more energy than an arithmetic operation by the ratio stated with that principle in section 16.3. Because this workload performs only about one operation per byte fetched, moving weights dominates the energy expenditure of each token. Because the energy ratio compares one access with one operation while an access moves several bytes, the exact cost per byte depends on how many it moves, and hardware telemetry settles that figure.

↩︎ The energy ladder from registers to off-chip memory, which sets the per-access cost of moving a weight, is established in Hardware Specialization.

Dean, Jeffrey, and Luiz André Barroso. 2013. “The Tail at Scale.” Communications of the ACM 56 (2): 74–80. https://doi.org/10.1145/2408776.2408794.

Of the two levers that can lower the memory bound, batching meets its limit at the service level, where the latency budget (principle 12) caps how far it may go. A larger batch raises throughput, but every request admitted to it can wait behind the other requests’ long prompts and generations, and those waits accumulate in the tail of the latency distribution. The relevant delay now includes prompt processing and request waiting, not only token decoding. Consider an illustrative LLM chat endpoint whose mean time to first token is 50 ms but whose p99, driven by long prompts and by queueing behind long generations, reaches 2,000 ms, a tail 40× the mean (illustrated in the margin). Both values are scenario assumptions rather than outputs of a queueing model. The actual tail depends on the request mix and scheduling policy and must be measured; the general importance of tail latency is established in Dean and Barroso (2013). The product commits to the tail quantile, so the batching that improves throughput must stop where it pushes that quantile past its deadline.
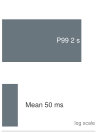
Two time bars on a linear scale: mean time to first token 50 ms is a sliver beside a p99 of 2,000 ms, a 40x tail.

Mean latency hides the tail; the selected tail quantile governs the SLO.

↩︎ The queueing model that relates utilization to tail latency, and the service-time assumptions under which its p99 estimate holds, is established in Tail latency.

The two traces use different principles, but they share one discipline: name the limiting term, measure it, and budget for it. Scale keeps working only if the system can afford it and its results can still be trusted, and the next test of that discipline is whether the same principles forecast where constraints will tighten in emerging deployments.

Self-Check: Question
  1. Six months after launch, a DLRM-based recommender still returns well-formed rankings with healthy latency, but click-through has fallen, and an audit finds that the online embedding lookup normalizes one user feature differently from the offline training pipeline. Which principle names this specific failure?

    1. The training-serving skew diagnostic, because the same model computes a feature differently in serving and in training, and that divergence is measurable without labels.
    2. The statistical drift diagnostic, because any drop in click-through proves that the user distribution has shifted.
    3. The verification gap, because the launch evaluation certified correctness for every future input.
    4. The latency budget principle, because falling click-through always indicates a missed tail-latency deadline.
  2. Consider serving one token at batch size 1 from a 70-billion-parameter Llama 2 model in FP16 (\(D_{\text{vol}} = 140\text{ GB}\), \(O \approx 140\text{ GFLOP}\)) sharded across two NVIDIA H100 GPUs (aggregate \(\text{BW} = 6.70\text{ TB/s}\), aggregate \(R_{\text{peak}} = 1,978\text{ TFLOP/s}\)). What are the idealized lower bounds for memory transfer (\(T_{\text{mem}}\)) and peak compute (\(T_{\text{comp}}\)), and what systems optimization strategy does this diagnostic suggest?

    1. Memory transfer time \(T_{\text{mem}} \approx 0.07\text{ ms}\) and compute time \(T_{\text{comp}} \approx 20.9\text{ ms}\); because compute time dominates by \(295\times\), the engineering team should prioritize hand-tuning tensor core matrix multiplication kernels.
    2. Memory transfer time \(T_{\text{mem}} \approx 2.09\text{ ms}\) and compute time \(T_{\text{comp}} \approx 2.09\text{ ms}\); because the workload operates exactly at the roofline ridge point, compute optimizations and memory optimizations provide identical returns.
    3. Memory transfer time \(T_{\text{mem}} \approx 20.9\text{ ms}\) and compute time \(T_{\text{comp}} \approx 0.07\text{ ms}\); because the memory bound is \(\approx 295\times\) larger than the compute bound, the modeled ceiling is bandwidth-bound, suggesting weight reuse and supported quantization as candidates whose latency effects require profiling.
    4. Memory transfer time \(T_{\text{mem}} \approx 41.8\text{ ms}\) and compute time \(T_{\text{comp}} \approx 0.14\text{ ms}\); because sharding across two GPUs doubles the communication overhead, execution time increases by \(2\times\) relative to a single GPU.
  3. A production serving dashboard for an interactive conversational assistant reports an average (mean) time to first token of 50 ms. However, user satisfaction metrics are declining, and detailed telemetry reveals a P99 time to first token of 2,000 ms (a \(40\times\) gap over the mean), violating the product SLO (\(T_{0.99} \le 200\text{ ms}\)). Which set of plausible mechanisms should engineers investigate using request-stage traces to explain the long tail?

    1. Uniform degradation of memory bus bandwidth across all simultaneous client connections.
    2. A 40x increase in model weight parameters triggered dynamically whenever traffic surges.
    3. Heavy-tailed sequence lengths in autoregressive decoding, runtime garbage collection pauses in Python servers, and queueing delays caused by dynamic batching timeouts under bursty request arrivals.
    4. Deterministic floating-point underflow occurring on exactly one percent of input requests.
  4. True or False: Responsible AI metrics, such as subgroup error rates and bias feedback amplification, can be adequately handled as a post-hoc compliance audit after model serving is fully optimized, because fairness properties remain stable once offline validation passes.

  5. Using the iron law and the arithmetic intensity law, explain why generating one token from a large decoder at batch size one is bound by memory rather than compute, and name two levers that move it toward the ridge point.

  6. The section traces trustworthiness on DLRM and physical deliverability on a Llama decoder with different principles. What single engineering discipline do the two traces share, and why does the bitter lesson make it necessary?

See Answers →

16.5 Future Directions

An autonomous vehicle navigating an unfamiliar intersection cannot wait for a cloud round-trip while its sensor streams compete with the model for the local bus, and a clinical assistant cannot afford an uncalibrated diagnostic response under distribution shift. When ML systems move beyond a single model in a data center, the same physical and statistical constraints apply with tighter margins. Three immediate pressures decide which of those limits dominates next: deployment across contrasting hardware tiers, robustness under distribution shift and adversarial conditions (including deliberately crafted inputs (Goodfellow et al. 2015)), and societal applications whose failures carry public consequences. A fourth horizon, systems that compose multiple models, tools, and verifiers or scale beyond one machine, extends the same reasoning rather than replacing it.

Goodfellow, I. J., J. Shlens, and C. Szegedy. 2015. “Explaining and Harnessing Adversarial Examples.” International Conference on Learning Representations (ICLR).

Applying principles to emerging deployment contexts

Moving a workload from a data-center rack to a mobile phone or a battery-powered sensor strips away orders of magnitude in memory capacity and power budget while tightening latency deadlines. That span tests whether one quantitative framework can explain systems across contrasting resource regimes. The cloud offers abundant power and centralized hardware, edge and mobile devices operate under strict latency and battery budgets, and TinyML and embedded systems compress the same design problem into kilobytes and milliwatts.

↩︎ The four deployment paradigms, and the physical constraints of power, latency, and memory that separate them, are established in Four Deployment Regimes Across Nine Orders of Magnitude.

In the cloud regime, the central decision is how to turn abundant hardware into useful throughput, which for ResNet-50 means keeping batched kernels near the compute ceiling and for DLRM means placing embedding tables that exceed one accelerator’s memory. Toward the small end of the spectrum, the MobileNetV2 and keyword-spotting lighthouses carry the forecast.

Mobile and edge devices, home to the MobileNetV2 lighthouse, operate under power, thermal, and memory bounds far tighter than the cloud’s, so they demand hardware-software co-design. An H100-class accelerator has about 10× the memory capacity and about 140× the power envelope of a reference mobile device, and efficient network architectures combined with model compression let models deploy within those limits. Edge deployment is mandatory when latency, privacy, intermittent connectivity, or egress bandwidth make centralized cloud inference infeasible. On these devices, efficiency decides whether a model runs at all.

↩︎ The per-device memory and power envelopes that separate the mobile tier from a data-center accelerator are established in Matching workloads to hardware.

Howard, Andrew G., Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, and Hartwig Adam. 2017. “MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications.” CoRR abs/1704.04861.
Sandler, Mark, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, and Liang-Chieh Chen. 2018. “MobileNetV2: Inverted Residuals and Linear Bottlenecks.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 4510–20. https://doi.org/10.1109/cvpr.2018.00474.
Tan, Mingxing, and Quoc V Le. 2019. “EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks.” International Conference on Machine Learning (ICML), 6105–14.

At the opposite extreme, TinyML and embedded systems, the domain of the keyword spotting lighthouse, operate within kilobyte SRAM budgets, milliwatt power envelopes, and multi-year operational lifecycles. Under those limits, a microcontroller cannot afford a fully dynamic runtime or heap allocation during inference, so the decisions a larger system makes at run time move to build time (Static runtimes for microcontrollers). The operator list, the kernels linked into the binary, and the memory plan for a fixed tensor arena are all settled before the device ships, so peak SRAM usage is known in advance. Across both the mobile and embedded tiers, these tight machine envelopes motivated compact architecture families such as MobileNets (Howard et al. 2017; Sandler et al. 2018) and EfficientNets (Tan and Le 2019), showing how hardware limits drive algorithmic design.

↩︎ The physical memory and latency envelopes that mandate compression for microcontroller and edge deployment are established in Deployment budgets and the running cases.

A related frontier is embodied AI and robotics, where models execute inside closed-loop sensorimotor control cycles. In this regime, the deadline \(\CompletionDeadline\) of the latency budget (principle 12) becomes a hard real-time safety constraint, because a tail-latency spike can cause mechanical instability or collision. Continuous high-bandwidth sensor streaming also competes directly with model weight traffic across constrained on-device memory buses.

Generative AI stresses all of these regimes at once. Autoregressive decode of the GPT-2/Llama family is bandwidth-bound at low batch, as the token estimate showed, and the serving responses to that bound each attack the limiting term in a different way. Batching raises weight reuse. Speculative decoding spends surplus compute on a small draft model that proposes several tokens, which the target model then checks together in one pass, so each pass over the target’s weights can yield more than one token. Prefill, the phase that processes the whole prompt in parallel before decode begins, reuses each weight across every prompt token, so a sufficiently long prompt shifts it toward the compute ceiling instead, and the same model crosses regimes within a single request.

↩︎ Continuous batching, key-value cache management, and speculative decoding for language model serving are established in LLM Serving.

The same physical bounds apply across these paradigms, while fitted statistical models and SLO policies remain deployment-specific, so each context needs the principles applied together rather than as isolated optimizations. Every added context also adds failure surfaces, which makes robustness in each one a limiting constraint at the next frontier.

Building robust AI systems

Across those failure surfaces, a machine learning system can respond confidently and incorrectly while conventional infrastructure health checks remain green, allowing silent failures to persist undetected for weeks. Accuracy can erode without any code change when the input distribution shifts, when rare edge cases fall outside the training data’s coverage, or when adversarial inputs (small, deliberately crafted perturbations that leave an input looking unchanged to a person) flip a prediction across a fragile decision boundary.

Because pre-launch evaluation estimates behavior only on a finite sample of a defined population, it cannot rule out every future edge case or adversarial perturbation before deployment. In production, statistical drift signals show when the input population has shifted, and labeled outcomes determine whether quality actually suffered. Together these limits make continuous monitoring, fallback policies, and periodic revalidation mandatory design requirements without assuming that every distribution shift causes degradation. The operational question is whether a failure will be detected and diagnosed before its impact spreads.

Robustness therefore demands designing for graceful degradation, not only prevention. At the single-system scale, that discipline appears as fallback paths, uncertainty thresholds that send low-confidence predictions down those paths, version-specific rollback policies, and monitoring hooks, with rollback reserved for a bad release rather than for external drift. At larger scale, the same logic extends to spare hardware and to ensembles of differently built models.

↩︎ Incident response procedures, including the choice among rollback, fallback, and traffic reduction, are established in Incident response for ML systems.

AI for societal benefit

Robust systems are the prerequisite for deploying AI in domains where technical failures carry public consequences. The diabetic retinopathy screening case from ML Lifecycle shows why. A model that reaches expert-level performance on high-quality images from standardized research cameras can fail on blurry, poorly lit images from older clinic cameras, not because the algorithm is wrong but because the deployment population has moved outside the training envelope. In verification-gap terms (principle 9), the launch evaluation certified the model on the wrong population. Each societal domain stresses a different principle.

↩︎ The lab-to-field gap in the diabetic retinopathy screening case, where field images fall outside the training distribution, is established in Lab-to-field data gap.

Scientific discovery workloads such as protein structure prediction can demand sustained training or inference throughput, so the iron law (principle 3) and the silicon contract (principle 4) decide how much of a search space a fixed compute budget can explore. Healthcare stresses the deployment principles instead. Calibrated uncertainty, external validation at each new site, clinical review, and continuous monitoring become safety requirements, because a diagnostic model trained on one hospital’s population may degrade at another with different demographics, disease prevalence, or imaging equipment. Personalized education stresses data governance and the data-as-code principle (1), since the student-interaction records that drive personalization are both sensitive and, in effect, the program the model learns from. A climate model that produces confident but uncalibrated projections carries the same verification problem into policy, where an overconfident forecast can steer decisions that are slow and costly to reverse.

In each of these domains the D·A·M taxonomy, the thirteen principles, and roofline analysis supply the systems questions, but the acceptable answers come from domain evidence such as clinical studies, educational outcome measurements, and physical validation, which no generic systems analysis provides. These applications also share a property that keeps their constraints tractable, because their task boundaries are fixed in advance. A diagnostic model classifies within a defined label set, and a structure predictor answers a defined kind of query. The next stress test removes that boundary.

System composition as a stress test

A task-general assistant or multi-component ML service may route one request through a chain of specialized stages: a planner model decides which steps to take, retrieval fetches relevant documents from an index while tool execution calls external programs such as a search engine or a calculator, a generator synthesizes the answer, and a verifier checks that output against rules or with a second model. The governing challenge is systems engineering as much as algorithm design, because the surrounding system must bound latency, reliability, cost, safety, and observability as work fans out across components.

System composition puts four of the principles under new load at once. As work fans out across retrieval, planning, tool execution, generation, and verification, the iron law must budget the computation and data movement of every stage. The silicon contract fragments because each stage saturates a different resource. An index lookup leans on memory capacity and bandwidth, generation on the weight traffic of decode, and a tool call on network round trips, so no single accelerator suits the whole request. Balancing those heterogeneous stages expands the Pareto frontier from two or three metrics, such as accuracy, latency, and memory, to a larger surface that also includes safety, fairness, factuality, privacy, and cost. Statistical drift now threatens retrieved documents, tool responses, and intermediate decisions as well as the final output.

The systems cost is visible in a single request. If an assistant fans out to retrieval, a planner, two tools, a generator, and a verifier, its realized latency follows the request’s critical path. That path is the retrieval time, plus the planner’s time, plus the slower of the two tool calls if they run in parallel, plus generation, verification, and the orchestration overhead between steps. The latency budget (principle 12) must hold that sum at the selected quantile.

Every additional component also creates another timeout, stale index, or verifier false negative to monitor. Some interfaces are also probabilistic, because a large language model planner may invent a tool name that does not exist or produce JSON that deviates from the declared schema (the agreed format of each call). Each interface has to validate what it receives and retry or reject what fails.

A composed system therefore cannot rely on a single model-quality claim; it needs interfaces whose behavior can be measured, because each interface is where one component’s assumptions about another become testable (Lampson 1983). Splitting a request into components gives up latency and architectural simplicity in exchange for control and observability, a move along a Pareto frontier rather than a free gain. Each component can be compressed and accelerated on its own back end, with its own silicon contract (principle 4) and arithmetic intensity profile, and the interfaces between components are natural observation points for drift, skew, and numerical degradation.

Lampson, Butler W. 1983. “Hints for Computer System Design.” Proceedings of the Ninth ACM Symposium on Operating Systems Principles, 33–48. https://doi.org/10.1145/800217.806614.

Systems Perspective 16.1: A new golden age
Hennessy and Patterson (2019) declared a “New Golden Age for Computer Architecture,” driven by the end of Dennard scaling, the slowdown of Moore’s Law, and new opportunities from domain-specific architectures. Large-scale AI workloads are one domain where those pressures are visible. Building more capable AI services will not be a matter of writing a better loss function alone; it will be a systems engineering challenge involving energy efficiency, high-bandwidth interconnects, memory hierarchy design, and software stacks that keep heterogeneous hardware useful rather than idle. The thirteen principles provide a quantitative vocabulary for navigating that regime while preserving the distinction between physical bounds and deployment-specific assumptions.

Hennessy, John L., and David A. Patterson. 2019. “A New Golden Age for Computer Architecture.” Communications of the ACM 62 (2): 48–60. https://doi.org/10.1145/3282307.

A horizon note: From node to fleet

A single accelerator with a reference mean time to failure (MTTF) of 5.7 years looks reliable in isolation. Across a 1,024-accelerator pool where every accelerator fails independently at the same constant rate, the cluster mean time between failures (MTBF), the average gap between failures when failed parts are swapped out and the pool keeps running, collapses to about 48.8 hours before accounting for correlated network or power outages (shown in the margin ladder). A synchronous training job on that pool halts at any single failure, so a multi-week run at this scale is highly likely to be interrupted and requires a fault-tolerance strategy built on the training checkpoints of Training state and checkpoints.

When workloads exceed a single node, the resource boundary moves outward while bottleneck reasoning remains invariant. Local memory capacity constraints are joined by limits on the network bandwidth between machines. Local exception handling expands into fleet-level fault tolerance, and training throughput becomes a distributed coordination problem. At fleet scale, the analysis does not abandon single-node principles; it widens their boundary. The engineer still identifies the limiting constraint, quantifies the governing cost terms in the iron law, and traces where displaced latency propagates.
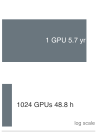
Margin ladder showing one GPU with about 5.7 years mean time to failure versus a 1024 GPU pool with about 48.8 hours mean time between failures.

Fleet scale turns rare component failures into routine system events.

This discipline rewards engineers who use bounds to guide benchmarks and measurements to test the assumptions behind those bounds. The same habit governs the last question this book raises, which is what the engineer owes the people a system affects.

Self-Check: Question
  1. A compound ML service processes queries through a multi-stage pipeline: a vector retriever (50 ms), two specialized tools executed concurrently in parallel (Tool A takes 110 ms, Tool B takes 70 ms), an LLM generation step (180 ms), and a safety verifier (30 ms). Assuming negligible orchestration overhead, what is the theoretical request critical-path latency, and what new systems reliability challenge emerges compared to a single monolithic model?

    1. 440 ms (sum of all steps); each stage introduces strictly deterministic latency with zero risk of interface contract violations.
    2. 370 ms (\(50\text{ ms} + \max(110, 70)\text{ ms} + 180\text{ ms} + 30\text{ ms}\)); each interface introduces probabilistic failure modes (e.g., malformed JSON, schema drift, hallucinated tool calls) that require defensive validation, retry budgets, and composed reliability accounting.
    3. 180 ms; parallel execution across all components collapses total latency to the single slowest module.
    4. 110 ms; the critical path is bounded exclusively by the longest tool execution.
  2. When comparing a TinyML microcontroller deployment (e.g., keyword spotting on a Cortex-M core) with an H100 GPU cloud inference service, which statement correctly explains how the book’s quantitative framework applies across both extremes?

    1. TinyML is bounded solely by network socket latency, whereas cloud LLM serving is bounded entirely by CPU single-thread clock speed.
    2. TinyML eliminates the memory wall completely because microcontrollers have infinite SRAM access bandwidth.
    3. Both systems obey identical physical principles (the Iron Law, Arithmetic Intensity, and Silicon Contract), but their limiting constraints diverge: TinyML is constrained by static SRAM/Flash capacity (\(<1\text{ MB}\)) and milliwatt power budgets, whereas low-batch cloud LLM decode is constrained by HBM memory bandwidth (\(3.35\text{ TB/s}\)).
    4. Cloud LLM inference operates with zero data movement overhead because H100 accelerators store all model weights permanently in ALU registers.
  3. True or False: In safety-critical ML applications (such as clinical diagnostic imaging), if standard cloud infrastructure monitoring reports 99.99% uptime, HTTP 200 status codes, and sub-50 ms latencies, the deployment is guaranteed to be operating safely and correctly.

  4. Explain why robust AI design in safety-critical applications requires building explicit mechanisms for graceful degradation (such as uncertainty thresholds and fallback heuristics) rather than relying exclusively on pre-deployment validation.

  5. A single data center GPU has an estimated Mean Time To Failure (MTTF) of approximately 5.7 years (\(\approx 50,000\text{ hours}\)). If an engineering team scales a distributed foundation model training run across a cluster of \(1,024\) identical GPUs, what is the expected cluster Mean Time Between Failures (\(\text{MTBF}_{\text{cluster}}\)) assuming independent constant-hazard failures, and what operational requirement does this impose?

    1. \(\text{MTBF}_{\text{cluster}} \approx 48.8\text{ hours}\) (approx. \(2\text{ days}\)); because cluster failure rate scales linearly with GPU count (\(\text{MTBF} = \text{MTTF} / N\)), multi-week training runs will routinely encounter hardware faults, making automated checkpointing and fast localized recovery an operational necessity.
    2. \(\text{MTBF}_{\text{cluster}} \approx 5.7\text{ years}\); hardware reliability is independent of the number of active nodes in the cluster.
    3. \(\text{MTBF}_{\text{cluster}} \approx 50\text{ minutes}\); network packet loss causes the entire cluster to crash once per hour.
    4. \(\text{MTBF}_{\text{cluster}} \approx 5,800\text{ years}\); distributed redundancy inherently increases total system reliability proportionally to cluster size.
  6. When moving from single-node ML systems to fleet-scale distributed systems, explain how the resource boundaries shift while the underlying physical laws remain invariant.

See Answers →

16.6 The Engineering Responsibility

A model that requires an array of high-end data-center accelerators for inference excludes organizations unable to procure specialized capital,2 while sustained accelerator power draw directly drives facility thermal dissipation and regional grid carbon emissions, and upstream training data that encodes historical sampling skews distorts downstream predictions. What an engineer owes the people a system affects is therefore decided inside the technical design itself rather than in an after-the-fact review, because choices from arithmetic precision to data curation distribute operational costs and societal consequences far beyond the engineering team.

2 AI democratization: Making AI accessible beyond a small number of well-resourced organizations through efficient systems engineering. Mobile-optimized models and cloud APIs can widen access, but doing so sustainably requires systematic optimization across hardware, algorithms, and infrastructure to maintain quality at scale.

↩︎ The accounting that converts accelerator energy, cooling overhead, and grid carbon intensity into emissions is established in Environmental and Cost Awareness.

Operating responsibly within those societal and physical bounds turns each external impact into a concrete engineering requirement: achieving the arithmetic efficiency needed to run on accessible hardware, maintaining fault tolerance against hardware anomalies, staying within strict thermal and power envelopes, and meeting justified, application-specific fairness requirements across demographic groups. As the healthcare and climate examples showed, high-consequence domains make governance criteria first-class engineering constraints. Meeting them rests on three habits that outlast any model family or hardware generation: measuring hidden dependencies, bounding trade-offs against physical hardware limits, and holding production deployments to real operational constraints.

↩︎ The lifecycle that turns responsibility into written requirements, release criteria, documentation, and operational monitoring is established in Responsible Engineering Across the Lifecycle.

The same responsibility demands continuous skepticism toward local wins. Optimizing a component in isolation is the most common way a system acquires failure modes that no team owns, and the benchmark win that does not survive production is its most familiar form.

Self-Check: Question
  1. How does the chapter demonstrate that ethical outcomes—such as accessibility, subgroup fairness, and environmental sustainability—are direct consequences of technical engineering decisions rather than abstract policy add-ons?

    1. Ethical concerns are external legal constraints that have no interaction with compiler flags, quantization formats, or model architecture.
    2. Engineering decisions—such as selecting high-precision floating-point formats (increasing datacenter carbon emissions), requiring multi-GPU nodes for inference (restricting deployment accessibility), or training on uncurated data (amplifying demographic bias)—directly dictate societal and ethical impacts.
    3. Model compression is purely a financial optimization that has no relationship to democratizing AI access.
    4. Algorithmic fairness can be fully guaranteed simply by omitting demographic feature columns from the raw dataset.
  2. The chapter argues that ethical considerations cannot be separated from physical and algorithmic design because the same decisions set both. Using hardware requirements for inference and sustained accelerator power draw as examples, explain how an engineering decision becomes a societal consequence.

See Answers →

16.7 Fallacies and Pitfalls

Fallacies and pitfalls in ML systems arise from one common source, which is treating the system as decomposable into independent parts. Each item below is the cross-boundary form of a mistake an earlier chapter met inside one layer, where optimizing one dimension, one metric, or one stage looks sufficient until that assumption meets production reality.

Fallacy: Systems engineering complexity disappears with better tools and abstractions.

Tools abstract complexity rather than eliminating physical constraints. A high-level framework that hides memory management still consumes memory, and an automated machine learning (AutoML) system that searches over hyperparameters still faces the Pareto frontier, so simplifying one interface may shift burden to another.

Pitfall: Optimizing one metric without tracing displaced costs.

When an optimization reduces latency by 50 percent, systems analysis demands asking what changed elsewhere. Quantization may add validation burden. Caching may trade memory capacity for serving speed. Some simplifications remove accidental complexity; others displace cost, and only profiling across the stack decides which occurred. Engineers who celebrate gains in one metric without tracing cross-stack effects build systems that fail in unexpected ways.

Fallacy: Mastering individual components equals mastering the system.

Component expertise is necessary but insufficient. An engineer who understands data pipelines, training, serving, and operations as isolated domains will still struggle with systems where a data schema change cascades through training, breaks quantization assumptions, and triggers silent accuracy degradation in production. Integration can create more complexity than the components reveal in isolation because interfaces multiply failure modes.

Pitfall: Scaling data collection without tracing its costs into the layers that absorb them.

A data team that grows its collection judges the result by model quality, yet the costs land in other layers. Storage and preprocessing grow with every sample, and each training epoch reads more bytes through the input pipeline. Repeatedly moving or scanning a larger dataset can exceed the cost of moving compute toward it, as the data-gravity principle (2) predicts. Within a fitted scaling regime, additional data can yield diminishing improvements (Diminishing returns and the ICR frontier) while those costs keep growing, and whether the next increment still follows that fit depends on its coverage, quality, and distribution and on how much more the model can learn. If a team judges collection only by its own metric, it gathers data whose costs other teams absorb, so the marginal information value per sample has to be weighed against those downstream costs.

Fallacy: A single accuracy metric captures model quality.

A model evaluated solely on top-line accuracy ignores the boundaries it must cross. The composite fleet scenario that opened this chapter passed its aggregate offline evaluation while accuracy on specific firmware and device cohorts fell by four percentage points. The serving boundary imposes its own test. Under a 100 ms tail-latency SLO, a 95 percent-accurate model executing in 500 ms is infeasible, whereas a 93 percent-accurate model with a measured 50 ms tail meets that latency requirement. It is a feasible deployment only if its accuracy, subgroup behavior, resource costs, and other acceptance criteria also pass. Pareto analysis (principle 5) evaluates latency, throughput, memory footprint, energy, fairness, and serving cost together, and disaggregated evaluation exposes the subgroup disparities that an aggregate conceals.

↩︎ Disaggregated evaluation, which tests each relevant subgroup separately as a release criterion, is established in Measure: Fairness criteria for release.

Pitfall: Treating every drift alarm as an automated rollback trigger.

The alarm fires in the monitoring layer, but its cause may sit in another layer entirely, and the response must follow the cause. Rollback is appropriate when a regression is traced to a flawed binary or pipeline release. External covariate drift, however, is not repaired by redeploying an older, equally stale checkpoint, and a shift introduced upstream, such as the firmware preprocessing path in the opening scenario, is repaired at the boundary where it entered. Safe operational responses (Model deployment) include pulling traffic back from the canary, fallback heuristics, prediction quarantine (keeping predictions logged during the degraded window out of the next training set), or scheduled retraining once ground-truth labels confirm degradation.

Fallacy: Optimizing the stage one team owns makes the system fast.

Teams tend to profile the stage they own, and the model kernel is the one most visible, instrumented, and owned by the ML team, while the surrounding data path is split across storage, preprocessing, networking, and application code. Amdahl’s Law (principle 8) shows what that division costs. Optimizing accelerator inference latency by 10× yields only 1.1× system speedup if CPU-bound preprocessing accounts for 90 percent of end-to-end latency. Serial fractions of that size can arise from host-side image augmentation, synchronous feature-store lookups, or tokenization that remains host bound in some implementations. End-to-end profiling across team boundaries keeps the target honest, because the stage to improve is the one that limits the system, not the one with the cleanest benchmark harness.

↩︎ Amdahl’s law, which caps the gain from speeding up one stage by the share of request time that the other stages take, is established in Anatomy of an Accelerator.

These fallacies and pitfalls share one root: local optimization that ignores the coupling of the system that executes it. Avoiding them in practice requires stepping back from individual stages to trace the whole request path and measure how data, algorithm, and machine constraints behave together.

↪ A diagnostic matrix that maps common production symptoms to candidate D·A·M axes and the measurements that confirm them is collected for reference in Confirming the hypothesis.

Self-Check: Question
  1. An engineer profiles an image classification serving pipeline and finds that host CPU-bound image decoding, resizing, and normalization consume 90% of end-to-end request latency (\(f_{\text{serial}} = 0.90\)), while GPU neural network inference consumes the remaining 10% (\(f_{\text{accelerated}} = 0.10\)). The engineer rewrites the GPU kernel to achieve a \(10\times\) inference speedup (\(S = 10\)). What is the resulting overall system-level speedup, and which systems principle explains this outcome?

    1. \(10.0\times\) overall speedup; accelerator improvements dominate user-perceived performance.
    2. \(5.5\times\) overall speedup; system improvement is the average of the two pipeline stage speedups.
    3. \(0.90\times\) overall speedup; kernel compilation overhead causes net performance regression.
    4. Approximately \(1.10\times\) overall speedup; according to Amdahl’s Law, the unaccelerated 90% serial preprocessing fraction strictly caps end-to-end speedup to \(\text{Speedup} = \frac{1}{0.90 + \frac{0.10}{10}} = \frac{1}{0.91} \approx 1.10\times\).
  2. A team selects Model Alpha over Model Beta because Alpha achieves 94.8% top-1 accuracy on a static benchmark versus Beta’s 93.2%. When deployed, Model Alpha violates the 100 ms P99 serving latency SLO by taking 420 ms, consumes \(4\times\) more memory, and exhibits a 16% error rate on an underrepresented user demographic. Which systems concept explains why single-metric evaluation led to this production failure?

    1. The Pareto Frontier; production ML systems operate across a multi-dimensional objective space (accuracy, tail latency, memory, energy, cost, and subgroup fairness), where optimizing aggregate accuracy in isolation can select an infeasible, costly, or discriminatory operating point.
    2. The Silicon Contract; models with higher accuracy automatically violate hardware execution contracts.
    3. Data Gravity; higher accuracy models physically pull network packets away from edge caches.
    4. Amdahl’s Law; aggregate accuracy scales inversely with the number of parallel workers.
  3. True or False: High-level software frameworks, AutoML tools, and compiler abstractions eliminate underlying physical ML systems constraints (such as memory bandwidth bottlenecks, thermal dissipation limits, and Amdahl’s Law ceilings), allowing software engineers to ignore low-level hardware characteristics.

  4. A production drift alarm fires due to seasonal changes in user shopping patterns. Explain why triggering an automated rollback to a model checkpoint trained three months earlier is an operational pitfall, and state the appropriate remediation.

  5. Looking across all seven fallacies and pitfalls detailed in the chapter (tools hiding complexity, untraced displaced costs, component-only mastery, untraced data-scaling costs, single-metric accuracy evaluation, unconditional rollbacks, and unprofiled stage optimization), identify the shared intellectual root cause that unites them and state the corrective systems engineering posture.

See Answers →

16.8 Summary

ML systems engineering differs from isolated component optimization by reasoning across boundaries. Because decisions couple across data, algorithm, and machine, the deployed system rather than the weights checkpoint is the model, and its costliest failures live at interfaces that no component test exercises. The thirteen principles, the conservation-of-complexity heuristic, and the lighthouse traces that carried them through the stack are the tools for reasoning about that system as a whole. Their stated assumptions distinguish exact bounds from fitted models, SLO policies, and design heuristics, allowing the tools to remain useful as frameworks, hardware generations, and model families change.

Key Takeaways: Reasoning across boundaries
  • Decisions couple across layers: In the composite fleet scenario every team met its local metric while accuracy on specific device and firmware cohorts fell by four percentage points, because quantization calibration and a firmware preprocessing path met only in production. Isolated component tests miss such cross-layer interactions; cross-path parity checks, integration tests, and cohort-level outcome tracking test the governing assumptions at the interfaces.
  • Each lighthouse rewards the lever aimed at its limiting term: ResNet-50 is compute-bound, GPT-2 and Llama decode bandwidth-bound, DLRM capacity-bound, MobileNetV2 compute-bound in its efficient regime on a phone’s NPU, and keyword spotting power-bound. The regime belongs to the workload on a machine, so batch size, phase, and precision can move a lighthouse across regimes, and the diagnosis carries forward to larger models of the same kind.
  • Assumptions matter across implementations: The thirteen principles turn framework-specific craft into measurable reasoning by combining physical bounds, decompositions, fitted models, requirements, and heuristics. Apply each only within its stated scope.
  • Trace displaced costs without assuming conservation: Compression, batching, monitoring, and governance can relocate burdens across data, algorithm, and machine. Measurement shows where each burden went.
  • Boundaries reveal the bottleneck: In the idealized batch-one, two-H100 model, the memory-transfer lower bound for a Llama 2 70B token is about 295.2× the peak-compute lower bound, and in the illustrative LLM chat endpoint the p99 time to first token is 40× the mean. Systems thinking means measuring where physics, traffic, and users set the limits.
  • Both halves of the dual mandate are measurable: Trustworthy behavior is tracked through drift, skew, and fitted feedback factors; physical deliverability through the iron law, the roofline, and energy per event. Neither is certified once at launch; both are budgets the system must keep meeting.

Hennessy and Patterson’s Computer Architecture: A Quantitative Approach gave processor designers a shared analytical discipline by decomposing CPU time into instruction count, cycles per instruction (CPI), and clock period, so that any proposed improvement could be judged by which factor it changed (Hennessy and Patterson 2011; Hennessy and Patterson 2017). The iron law plays the same role for machine learning systems, and the thirteen principles around it extend that discipline from execution time to energy, trade-offs, and deployed behavior. Together they give a shared analytical baseline for evaluating trade-offs across data, algorithms, and machines.

Hennessy, J. L., and D. A. Patterson. 2011. Computer Architecture: A Quantitative Approach. Morgan Kaufmann.
Hennessy, John L., and David A. Patterson. 2017. Computer Architecture: A Quantitative Approach. 6th ed. Morgan Kaufmann.

The voice-assistant request that opened the introduction can now be traced through every layer, as a composite assembled from the book’s lighthouses rather than from any one product’s design. First, a keyword-spotting model of about 200 thousand parameters listens for the wake word on a microcontroller. Its 200 KB of INT8 weights sit in 1 MB of flash, and its 20 MFLOP per inference repeat around the clock under a milliwatt power budget. Once the wake word triggers, an on-device speech front end takes over, assumed here to be a convolutional network that borrows only MobileNetV2’s size. It runs on the phone’s NPU, performing 600 MFLOP of work on 3.5 MB of INT8 weights within a 5 W envelope. When the transcribed query reaches the cloud, ranking the retrieved results falls to DLRM, whose 100 GB of embedding tables exceed one H100’s 80 GB before any arithmetic begins. Finally, a GPT-2 decoder generates the response on an H100, where every token reads 3 GB of FP16 weights. That sets a memory floor of about 0.9 ms per token, which exceeds the compute floor by 295×, assuming graph capture hides dispatch overhead (Graph capture and JIT compilation).

Power, compute, capacity, and bandwidth each set the limit in turn along one request, so an engineer who knows only one layer sees one of those four limits and misses the other three. The introduction’s three questions take a different answer at each stage. Wake-word recordings and ranking logs shape the predictions, a different resource limits each stage’s execution, and cohort-level monitoring across devices and users supplies the evidence that the whole request still deserves deployment.

What endures is the method: start from empirical evidence and physical bounds, quantify trade-offs, and treat system design as constrained optimization. That method is the engineering corollary of the bitter lesson drawn from seven decades of AI research. Because general methods that scale with computation repeatedly outrun hand-crafted expertise, the durable advantage belongs to systems engineering that can absorb that computation, not to any single clever architecture (Sutton 2019). Frameworks, chips, and architectures will change; measuring against physical limits will not.

Sutton, Richard S. 2019. “The Bitter Lesson.” Incompleteideas.net 43.

The world is rushing to build AI systems. Our task is to engineer them.

Prof. Vijay Janapa Reddi, Harvard University

16.9 Self-Check Answers

Self-Check: Answer
  1. A production image classifier deployed across a mobile device fleet shows a 4-percentage-point drop in accuracy on specific handset cohorts. The weights file is unchanged, the compression team verified INT8 kernel speedups, and the serving team confirmed a P99 latency of 48 ms (under the 50 ms SLO). Which diagnostic posture is most consistent with the ‘system is the model’ thesis?

    1. Focus the investigation exclusively on serving execution, because runtime inference is the only stage operating during production.
    2. Trace the interaction between INT8 quantization scaling factors and firmware-specific image preprocessing paths, because production behavior is defined by the weights combined with the data pipeline, runtime hardware, and monitoring loop.
    3. Escalate to the architecture team to train wider convolutional layers, because an unchanged weights file implies that any remaining error must stem from model capacity.
    4. Treat the 4-point regression as acceptable random noise, because all engineering teams independently satisfied their local component metrics and the aggregate P99 latency is within budget.

    Answer: The correct answer is B. Trace the interaction between INT8 quantization scaling factors and firmware-specific image preprocessing paths, because production behavior is defined by the weights combined with the data pipeline, runtime hardware, and monitoring loop. The central thesis of ML systems engineering is that ‘the system is the model’: the weights file is merely one component of a pipeline that includes data ingest, preprocessing, quantization scaling, hardware runtime execution, and drift monitoring. In the chapter’s mobile deployment case study, no single component failed in isolation; rather, a subtle coupling between INT8 quantization assumptions and device-specific image preprocessing firmware caused the localized accuracy loss. Escalating solely to architecture ignores the physical substrate; dismissing the drop as noise ignores cohort-specific degradation; and blaming only the serving runtime overlooks upstream preprocessing and quantization interactions.

    Learning Objective: Apply the ‘system is the model’ thesis to diagnose a production regression that emerges from cross-layer interactions between preprocessing, quantization, and hardware runtimes.

  2. True or False: If every engineering team in an ML organization independently satisfies its isolated component metric (e.g., architecture achieves an \(8.7\times\) FLOP reduction, compression achieves \(4\times\) weight reduction, and serving meets its P99 latency SLO), the integrated system is mathematically guaranteed to meet its end-to-end accuracy and correctness requirements in production.

    Answer: False. Component correctness is necessary but insufficient for system correctness because ML systems exhibit complex cross-layer couplings across interfaces. An architectural change alters arithmetic intensity and operator support requirements; quantization introduces scaling factors and rounding errors; firmware-specific preprocessing pipelines may alter input color spaces or normalization; and serving dynamic batchers can alter tail latency distributions. When these components interact in production, subtle edge cases (such as quantization clipping on specific camera sensor firmware) create localized accuracy regressions that aggregate offline benchmarks and component-level SLOs never measure in isolation.

    Learning Objective: Evaluate why component-level success metrics cannot guarantee end-to-end ML system correctness and reliability.

  3. The conclusion argues that ‘the system is the model.’ Explain why treating the model solely as a static weights file (e.g., a 500 MB floating-point binary) fails in production, and define what constitutes the ‘true model.’

    Answer: In production, model weights cannot function in isolation. The true model is the entire integrated pipeline: the data engineering pipeline that defines what features the model receives, the training infrastructure that determines what it learns, the serving runtime and hardware compiler that dictate how it executes, and the operational monitoring loop that tracks distribution drift. If upstream preprocessing changes or downstream hardware quantization clips values, model behavior degrades even if the weights file remains completely unchanged.

    Learning Objective: Explain why production ML behavior is defined by the full end-to-end system rather than the weights file alone.

← Back to Questions

Self-Check: Answer
  1. A production recommender workload is dominated by embedding tables larger than one accelerator’s memory where engineers spend significant effort deciding where data physically resides across storage tiers rather than optimizing dense matrix math. Which lighthouse model embodies this constraint regime, and how does its primary bottleneck differ from low-batch GPT-2/Llama decoding?

    1. MobileNetV2; it is capacity-bound on microcontrollers, whereas autoregressive decoding is bound by network packet round-trip times.
    2. ResNet-50; it is capacity-bound by image batch activation footprints in host DRAM, whereas LLM decode is compute-bound.
    3. Keyword Spotting (KWS); it is capacity-bound by microcontroller flash storage, whereas LLM decode is strictly compute-bound by tensor core peak FLOP/s.
    4. DLRM; it is capacity-bound by embedding tables larger than one accelerator’s memory requiring physical data placement design, whereas low-batch LLM decode is memory-bandwidth-bound due to streaming weights with minimal arithmetic reuse per token.

    Answer: The correct answer is D. DLRM; it is capacity-bound by embedding tables larger than one accelerator’s memory requiring physical data placement design, whereas low-batch LLM decode is memory-bandwidth-bound due to streaming weights with minimal arithmetic reuse per token. The five lighthouse models represent distinct home regimes across the systems spectrum: DLRM is capacity-bound because embedding tables larger than one accelerator’s memory cannot fit in one accelerator’s HBM, forcing the tables to be sharded across accelerators or memory tiers; low-batch autoregressive LLM decoding is bandwidth-bound because weights must be read from HBM for every token with an arithmetic intensity of \(\approx 1\text{ FLOP/byte}\); ResNet-50 at large batch sizes is compute-bound; MobileNetV2 operates under mobile battery/thermal envelopes; and KWS operates under sub-megabyte SRAM and milliwatt constraints. The other options misclassify the workloads and their physical bottlenecks.

    Learning Objective: Classify diverse ML workloads by their limiting physical constraints (capacity-bound vs. bandwidth-bound vs. compute-bound) using the lighthouse model framework.

  2. A team serving GPT-2 at batch size one on an H100 proposes two investments: hand-tuning the matrix-multiply kernels to raise achieved FLOP/s, or batching concurrent requests and storing weights in fewer bytes. Using the chapter’s lighthouse trace, which investment pays off, and why?

    1. Kernel tuning, because GPT-2 is compute-bound at every batch size and phase.
    2. Batching and fewer bytes per weight, because batch-one decode is bandwidth-bound: its data-movement term exceeds its compute term, so only levers that reuse each weight across more tokens or move fewer bytes per token shorten the step.
    3. Neither, because GPT-2 decode is capacity-bound like DLRM and must first be sharded across several devices.
    4. Kernel tuning, because a high ridge point means every workload gains more from compute than from bandwidth.

    Answer: The correct answer is B. Batching and fewer bytes per weight, because batch-one decode is bandwidth-bound: its data-movement term exceeds its compute term, so only levers that reuse each weight across more tokens or move fewer bytes per token shorten the step. The trace table pairs the bandwidth-bound regime of GPT-2/Llama decode with the data-movement term \(\DataVolume/\Bandwidth\); raising peak arithmetic throughput is the lever wasted at batch one. GPT-2 training is compute-bound, which is why the regime belongs to the workload and phase rather than to the model name. GPT-2 weights fit comfortably on one H100, so capacity is not the limit, and a high ridge point makes low-intensity workloads more bandwidth-bound, not less.

    Learning Objective: Use a lighthouse’s home regime and limiting term to select the optimization lever that pays and reject the one that is wasted.

  3. **Order the following phases of the MobileNetV2 lighthouse journey in their chronological lifecycle order as constraints propagate from initial requirements through deployment operations:

  1. Compression (INT8 quantization navigating the Pareto frontier)
  2. Acceleration (Mapping operators to mobile NPUs under the silicon contract)
  3. Foundations (Establishing battery, thermal, and machine constraints)
  4. Architecture (Depthwise separable convolutions reducing FLOPs)
  5. Operations (Cohort-level drift monitoring across heterogeneous devices)
  6. Serving (Enforcing P99 latency budgets under 50 ms)**

Answer: The correct order is (3) -> (4) -> (1) -> (2) -> (6) -> (5).

Step-by-step lifecycle propagation: 1. (3) Foundations: Establishes the physical battery, thermal, and memory envelope of the edge device. 2. (4) Architecture: Designs depthwise separable convolutions to reduce arithmetic FLOPs by \(\approx 8.7\times\). 3. (1) Compression: Applies INT8 post-training quantization to reduce weight byte traffic by \(4\times\) vs. FP32. 4. (2) Acceleration: Compiles and maps INT8 fused operators onto mobile NPUs (e.g., Apple Neural Engine). 5. (6) Serving: Optimizes runtime image preprocessing to satisfy the P99 \(< 50\text{ ms}\) latency budget. 6. (5) Operations: Deploys continuous monitoring to detect accuracy drift across device cohorts and lighting conditions.

Learning Objective: Order the lifecycle phases of ML systems constraint propagation from foundational hardware constraints through architecture, compression, acceleration, serving, and operational monitoring.

← Back to Questions

Self-Check: Answer
  1. According to the Energy-Movement Principle (\(E_{\text{total}} = \sum_j N_j E_j\)), accessing off-chip DRAM requires approximately 100 to 1,000 times more energy than executing a single FP16 or FP32 arithmetic operation. What is the direct systems design implication of this physical reality?

    1. Inference engines should prioritize minimizing total ALU operations above all else, even if intermediate tensors must be repeatedly written to and read from off-chip DRAM.
    2. Hardware accelerators consume identical energy regardless of whether memory accesses hit on-chip SRAM or off-chip DRAM, because memory controller power is fixed.
    3. Quantization saves energy exclusively by simplifying ALU multiplication logic, while memory traffic volume has negligible impact on total package power.
    4. Architectures and runtimes should evaluate on-chip reuse and reduced memory traffic, counting accesses at their actual width and arithmetic operations to determine the energy savings.

    Answer: The correct answer is D. Architectures and runtimes should evaluate on-chip reuse and reduced memory traffic, counting accesses at their actual width and arithmetic operations to determine the energy savings. The stated reference ratio compares one DRAM access with one arithmetic operation. An access moves several bytes, so byte volume must be converted to access counts using the actual transfer width. Fusion, tiling, and supported quantization can reduce memory traffic, but the savings depend on the number of accesses removed, changes in arithmetic and runtime costs, and the energy boundary. A whole-system energy estimate or measurement must include the remaining costs; the per-event ratio alone does not establish orders-of-magnitude total savings. The other choices ignore locality or assume energy contributions that the event counts do not establish.

    Learning Objective: Explain the physical basis of the Energy-Movement Principle and evaluate how on-chip data reuse and kernel fusion minimize total system energy.

  2. True or False: The conservation-of-complexity heuristic is an exact physical conservation law of computer science that proves every simplification in an ML pipeline interface creates an identical, mathematically equal compensating burden in another component.

    Answer: False. The conservation-of-complexity heuristic (analogous to Tesler’s Law in UI design) is a diagnostic design heuristic, not an exact physical conservation law. While simplifying one interface often displaces work elsewhere (e.g., shorter user prompts shifting parsing and retrieval burdens into system prompts and vector lookups, or INT8 quantization adding validation burden), good engineering design can eliminate accidental complexity outright without creating equal compensating costs. Its value is diagnostic: prompting engineers to trace where validation, state, or operational burdens move after simplifying a component.

    Learning Objective: Distinguish the conservation-of-complexity diagnostic heuristic from exact physical conservation laws.

  3. The thirteen quantitative principles are unified by a central meta-heuristic known as the ____ heuristic, which reminds engineers that simplifying one interface often displaces validation, state, or operational burdens to another part of the system.

    Answer: conservation of complexity (or conservation-of-complexity). The conservation-of-complexity heuristic serves as a diagnostic lens connecting Foundations, Build, Optimize, and Deploy. It prompts engineers to trace where costs land after optimizing or abstracting an individual component.

    Learning Objective: Identify the conservation-of-complexity heuristic as the overarching diagnostic framework uniting the thirteen quantitative principles.

  4. In the Cycle of ML Systems diagram in figure 1, the Deploy phase contains an explicit feedback arrow returning to Foundations (Data). Explain what production signals activate this feedback loop and why automated rollback is insufficient when the cause is external statistical drift.

    Answer: The Deploy-to-Foundations feedback loop is activated by deployment diagnostics: the verification gap (estimating accuracy bounds under real traffic), statistical drift (distribution shifts in input features or user cohorts), training-serving skew (mismatched feature preprocessing paths), and bias feedback amplification. When a drift signal is detected, automated rollback only repairs software regressions caused by faulty code or bad model releases. If the underlying cause is external real-world distribution change (e.g., seasonal shifts, macro trends, or new user populations), rolling back to an older checkpoint trained on even staler data fails to restore accuracy. The feedback arrow requires diagnosing the root cause, collecting newly representative data, revalidating feature pipelines, and retraining or adapting the model.

    Learning Objective: Analyze how deployment diagnostics (drift, skew, bias feedback) drive the feedback loop from production back to data engineering and retraining in the ML systems lifecycle.

← Back to Questions

Self-Check: Answer
  1. Six months after launch, a DLRM-based recommender still returns well-formed rankings with healthy latency, but click-through has fallen, and an audit finds that the online embedding lookup normalizes one user feature differently from the offline training pipeline. Which principle names this specific failure?

    1. The training-serving skew diagnostic, because the same model computes a feature differently in serving and in training, and that divergence is measurable without labels.
    2. The statistical drift diagnostic, because any drop in click-through proves that the user distribution has shifted.
    3. The verification gap, because the launch evaluation certified correctness for every future input.
    4. The latency budget principle, because falling click-through always indicates a missed tail-latency deadline.

    Answer: The correct answer is A. The failure described is a divergence between two code paths on identical inputs, which the training-serving skew diagnostic (principle 11) defines and can detect without waiting for labels. Drift would be a change in the input population, and divergence alone does not prove a quality drop. The verification gap says the opposite of that choice: launch evaluation estimates behavior over a stated population and tolerance, with uncertainty. The required population success probability and statistical confidence in that estimate are separate quantities. Latency is healthy here, so the latency budget is not the limiting principle.

    Learning Objective: Map a production trust failure on the DLRM lighthouse to the deployment principle that names and detects it.

  2. Consider serving one token at batch size 1 from a 70-billion-parameter Llama 2 model in FP16 (\(D_{\text{vol}} = 140\text{ GB}\), \(O \approx 140\text{ GFLOP}\)) sharded across two NVIDIA H100 GPUs (aggregate \(\text{BW} = 6.70\text{ TB/s}\), aggregate \(R_{\text{peak}} = 1,978\text{ TFLOP/s}\)). What are the idealized lower bounds for memory transfer (\(T_{\text{mem}}\)) and peak compute (\(T_{\text{comp}}\)), and what systems optimization strategy does this diagnostic suggest?

    1. Memory transfer time \(T_{\text{mem}} \approx 0.07\text{ ms}\) and compute time \(T_{\text{comp}} \approx 20.9\text{ ms}\); because compute time dominates by \(295\times\), the engineering team should prioritize hand-tuning tensor core matrix multiplication kernels.
    2. Memory transfer time \(T_{\text{mem}} \approx 2.09\text{ ms}\) and compute time \(T_{\text{comp}} \approx 2.09\text{ ms}\); because the workload operates exactly at the roofline ridge point, compute optimizations and memory optimizations provide identical returns.
    3. Memory transfer time \(T_{\text{mem}} \approx 20.9\text{ ms}\) and compute time \(T_{\text{comp}} \approx 0.07\text{ ms}\); because the memory bound is \(\approx 295\times\) larger than the compute bound, the modeled ceiling is bandwidth-bound, suggesting weight reuse and supported quantization as candidates whose latency effects require profiling.
    4. Memory transfer time \(T_{\text{mem}} \approx 41.8\text{ ms}\) and compute time \(T_{\text{comp}} \approx 0.14\text{ ms}\); because sharding across two GPUs doubles the communication overhead, execution time increases by \(2\times\) relative to a single GPU.

    Answer: The correct answer is C. Memory transfer time \(T_{\text{mem}} \approx 20.9\text{ ms}\) and compute time \(T_{\text{comp}} \approx 0.07\text{ ms}\); because the memory bound is \(\approx 295\times\) larger than the compute bound, the modeled ceiling is bandwidth-bound, suggesting weight reuse and supported quantization as candidates whose latency effects require profiling. Applying the Iron Law and Arithmetic Intensity formulas: \(T_{\text{mem}} = \frac{140\text{ GB}}{6.70\text{ TB/s}} = \frac{140\text{ GB}}{6,700\text{ GB/s}} \approx 20.9\text{ ms}\), while \(T_{\text{comp}} = \frac{140\times 10^9\text{ FLOP}}{1,978\times 10^{12}\text{ FLOP/s}} \approx 0.07\text{ ms}\). The ratio \(\frac{T_{\text{mem}}}{T_{\text{comp}}} = \frac{20.9}{0.07} \approx 295\times\). Arithmetic intensity is \(\approx 1\text{ FLOP/byte}\), which lies far to the left of the H100 ridge point (\(I_{\text{ridge}} = \frac{1978\text{ TFLOP/s}}{6.7\text{ TB/s}} \approx 295\text{ FLOP/byte}\)). This traffic model limits attainable arithmetic throughput relative to peak; it does not measure tensor-core busy or stalled cycles. Profiling must establish the realized bottleneck, including costs excluded from this calculation. Batching reuses weights across requests, and supported weight quantization reduces their byte volume, but their end-to-end latency effects depend on operator support, queueing, and the request path. Compute-only tuning cannot lower the modeled memory-transfer bound. Inverting the values confuses compute with memory; claiming equal time misplaces the ridge point; and doubling execution time misapplies sharding.

    Learning Objective: Calculate idealized memory-transfer and compute lower bounds for autoregressive token decoding and use arithmetic intensity to select high-leverage serving optimizations.

  3. A production serving dashboard for an interactive conversational assistant reports an average (mean) time to first token of 50 ms. However, user satisfaction metrics are declining, and detailed telemetry reveals a P99 time to first token of 2,000 ms (a \(40\times\) gap over the mean), violating the product SLO (\(T_{0.99} \le 200\text{ ms}\)). Which set of plausible mechanisms should engineers investigate using request-stage traces to explain the long tail?

    1. Uniform degradation of memory bus bandwidth across all simultaneous client connections.
    2. A 40x increase in model weight parameters triggered dynamically whenever traffic surges.
    3. Heavy-tailed sequence lengths in autoregressive decoding, runtime garbage collection pauses in Python servers, and queueing delays caused by dynamic batching timeouts under bursty request arrivals.
    4. Deterministic floating-point underflow occurring on exactly one percent of input requests.

    Answer: The correct answer is C. Variable sequence lengths, runtime pauses, and queueing under bursty arrivals are plausible mechanisms to investigate, not causes established by the mean and p99 alone. Request-stage traces must separate waiting, prompt processing, generation, and host-runtime pauses. Mean latency hides tail behavior (\(P99 \gg \text{mean}\)). In ML serving, possible sources of tail latency include variable-length prompt processing and generation loops in LLMs, garbage collection pauses in host runtimes, lock contention in dynamic batch schedulers, and queueing buildup when request arrival rates momentarily exceed processing capacity. Uniform bandwidth degradation could slow requests but is not diagnosed by these two summary statistics; dynamic parameter growth is technically nonsensical for static weights; and floating-point underflow confuses numerical precision with serving latency distributions.

    Learning Objective: Analyze root causes of tail-latency spikes (\(P99 \gg \text{mean}\)) in production inference serving systems and evaluate them against latency budget SLOs.

  4. True or False: Responsible AI metrics, such as subgroup error rates and bias feedback amplification, can be adequately handled as a post-hoc compliance audit after model serving is fully optimized, because fairness properties remain stable once offline validation passes.

    Answer: False. Responsible AI is a dynamic systems engineering constraint governed by the same measurement discipline as latency and throughput. High aggregate accuracy on an offline benchmark can easily conceal massive error rate disparities on underrepresented demographic cohorts. In production, algorithmic predictions influence future data collection, creating compounding feedback loops (principle 13: \(\Delta_g(k) \approx \Delta_g(0)\alpha_{\text{fb}}^k\)) whose fitted amplification factor determines whether disparity grows or diminishes within the modeled regime. Treating fairness as an afterthought can leave harms undetected. Disaggregated metrics, subgroup monitoring, and fairness validation provide evidence for response, but detection and mitigation depend on outcome-label delays, monitoring cadence, and the response path; they are not guaranteed in real time.

    Learning Objective: Justify why responsible AI monitoring and bias feedback mitigation are first-class operational systems constraints rather than post-hoc compliance audits.

  5. Using the iron law and the arithmetic intensity law, explain why generating one token from a large decoder at batch size one is bound by memory rather than compute, and name two levers that move it toward the ridge point.

    Answer: At batch size one, each generated token reads essentially every weight once and performs about one multiply-accumulate per weight, so arithmetic intensity is near 1 FLOP/byte, far left of the accelerator’s ridge point \(R_{\text{peak}}/\text{BW}\). The data term \(\DataVolume/\Bandwidth\) therefore dominates the iron law, and the memory-transfer bound exceeds the compute bound by a wide factor. Batching amortizes each weight read across several requests, reducing modeled weight traffic per generated token rather than necessarily reducing total traffic per batch. Supported quantization shrinks bytes per weight and raises modeled intensity. Energy savings depend on actual access widths and counts, arithmetic and runtime costs, and the measured system boundary. The latency budget limits how far batching can go.

    Learning Objective: Apply the iron law and the arithmetic intensity law to diagnose batch-one decode as memory bound and identify levers that raise arithmetic intensity.

  6. The section traces trustworthiness on DLRM and physical deliverability on a Llama decoder with different principles. What single engineering discipline do the two traces share, and why does the bitter lesson make it necessary?

    Answer: Both traces name the limiting term, measure it, and budget for it: drift, skew, and disparity get telemetry, thresholds, and response paths on the trust side, while the data term, intensity, and tail latency get bounds and budgets on the delivery side. The bitter lesson says general methods that exploit growing computation win, so systems keep scaling; only a system that can afford that scale and can still be trusted gets to keep scaling, which requires both halves of the mandate to be measured rather than assumed.

    Learning Objective: Synthesize the shared measurement discipline behind both halves of the dual mandate and connect it to the bitter lesson.

← Back to Questions

Self-Check: Answer
  1. A compound ML service processes queries through a multi-stage pipeline: a vector retriever (50 ms), two specialized tools executed concurrently in parallel (Tool A takes 110 ms, Tool B takes 70 ms), an LLM generation step (180 ms), and a safety verifier (30 ms). Assuming negligible orchestration overhead, what is the theoretical request critical-path latency, and what new systems reliability challenge emerges compared to a single monolithic model?

    1. 440 ms (sum of all steps); each stage introduces strictly deterministic latency with zero risk of interface contract violations.
    2. 370 ms (\(50\text{ ms} + \max(110, 70)\text{ ms} + 180\text{ ms} + 30\text{ ms}\)); each interface introduces probabilistic failure modes (e.g., malformed JSON, schema drift, hallucinated tool calls) that require defensive validation, retry budgets, and composed reliability accounting.
    3. 180 ms; parallel execution across all components collapses total latency to the single slowest module.
    4. 110 ms; the critical path is bounded exclusively by the longest tool execution.

    Answer: The correct answer is B. 370 ms (\(50\text{ ms} + \max(110, 70)\text{ ms} + 180\text{ ms} + 30\text{ ms}\)); each interface introduces probabilistic failure modes (e.g., malformed JSON, schema drift, hallucinated tool calls) that require defensive validation, retry budgets, and composed reliability accounting. On the critical path, parallel branches contribute their maximum rather than their sum: \(50 + \max(110, 70) + 180 + 30 = 50 + 110 + 180 + 30 = 370\text{ ms}\). Beyond latency, composed systems replace single monolithic model boundaries with multiple probabilistic interfaces. An LLM planner may produce schema deviations, tools may timeout, or verifiers may yield false rejections. Consequently, the system’s end-to-end reliability is the product of component reliabilities plus retry overheads, demanding defensive parsing, timeout budgets, and intermediate state observability. Summing all branches incorrectly adds parallel paths, while taking only the slowest module ignores serial dependencies.

    Learning Objective: Calculate the critical-path latency of composed multi-component ML pipelines and analyze the probabilistic interface failure modes of compound AI systems.

  2. When comparing a TinyML microcontroller deployment (e.g., keyword spotting on a Cortex-M core) with an H100 GPU cloud inference service, which statement correctly explains how the book’s quantitative framework applies across both extremes?

    1. TinyML is bounded solely by network socket latency, whereas cloud LLM serving is bounded entirely by CPU single-thread clock speed.
    2. TinyML eliminates the memory wall completely because microcontrollers have infinite SRAM access bandwidth.
    3. Both systems obey identical physical principles (the Iron Law, Arithmetic Intensity, and Silicon Contract), but their limiting constraints diverge: TinyML is constrained by static SRAM/Flash capacity (\(<1\text{ MB}\)) and milliwatt power budgets, whereas low-batch cloud LLM decode is constrained by HBM memory bandwidth (\(3.35\text{ TB/s}\)).
    4. Cloud LLM inference operates with zero data movement overhead because H100 accelerators store all model weights permanently in ALU registers.

    Answer: The correct answer is C. Both systems obey identical physical principles (the Iron Law, Arithmetic Intensity, and Silicon Contract), but their limiting constraints diverge: TinyML is constrained by static SRAM/Flash capacity (\(<1\text{ MB}\)) and milliwatt power budgets, whereas low-batch cloud LLM decode is constrained by HBM memory bandwidth (\(3.35\text{ TB/s}\)). The quantitative principles are invariant across deployment scales separated by roughly nine orders of magnitude in power (megawatts to milliwatts). On a microcontroller, memory capacity (e.g., 256 KB SRAM) and strict energy envelopes prevent dynamic batching or large weights, forcing static memory pre-allocation and aggressive integer quantization. In cloud LLM serving, abundant compute is starved by the rate at which 140 GB of weights can be streamed across the HBM bus during batch-1 decode. The governing physics remains constant; only the active limiting term shifts. The other choices contain physical and technical falsehoods regarding infinite SRAM, zero data movement, and socket bottlenecks.

    Learning Objective: Compare how the Iron Law and Silicon Contract manifest across contrasting deployment regimes from TinyML microcontrollers to cloud accelerator clusters.

  3. True or False: In safety-critical ML applications (such as clinical diagnostic imaging), if standard cloud infrastructure monitoring reports 99.99% uptime, HTTP 200 status codes, and sub-50 ms latencies, the deployment is guaranteed to be operating safely and correctly.

    Answer: False. ML systems introduce silent failure modes where infrastructure availability dashboards remain completely green while the model produces clinically dangerous, incorrect predictions. Factors such as demographic covariate shift, changes in hospital imaging hardware, or subtle data pipeline format corruption alter predictive accuracy without triggering traditional HTTP, CPU, or memory errors. Operational safety requires continuous statistical drift detection, subgroup outcome auditing, calibrated uncertainty thresholds, and clinical review fallbacks.

    Learning Objective: Analyze why traditional infrastructure uptime metrics fail to detect silent model degradation in safety-critical deployments.

  4. Explain why robust AI design in safety-critical applications requires building explicit mechanisms for graceful degradation (such as uncertainty thresholds and fallback heuristics) rather than relying exclusively on pre-deployment validation.

    Answer: Pre-deployment validation only tests finite samples from an assumed distribution and cannot guarantee correctness on out-of-distribution, adversarial, or shifted real-world inputs (the Verification Gap). Because neural networks can output confident but completely erroneous predictions, robust systems must design for graceful degradation at runtime. Concrete mechanisms include calibrated uncertainty estimation (triggering automated fallbacks to rule-based heuristics or human clinicians when confidence falls below safety thresholds), input sanity assertions, and defensive output validators. This bounds the blast radius of inevitable silent model failures.

    Learning Objective: Design graceful degradation and fallback architectures for safety-critical ML systems operating under real-world uncertainty.

  5. A single data center GPU has an estimated Mean Time To Failure (MTTF) of approximately 5.7 years (\(\approx 50,000\text{ hours}\)). If an engineering team scales a distributed foundation model training run across a cluster of \(1,024\) identical GPUs, what is the expected cluster Mean Time Between Failures (\(\text{MTBF}_{\text{cluster}}\)) assuming independent constant-hazard failures, and what operational requirement does this impose?

    1. \(\text{MTBF}_{\text{cluster}} \approx 48.8\text{ hours}\) (approx. \(2\text{ days}\)); because cluster failure rate scales linearly with GPU count (\(\text{MTBF} = \text{MTTF} / N\)), multi-week training runs will routinely encounter hardware faults, making automated checkpointing and fast localized recovery an operational necessity.
    2. \(\text{MTBF}_{\text{cluster}} \approx 5.7\text{ years}\); hardware reliability is independent of the number of active nodes in the cluster.
    3. \(\text{MTBF}_{\text{cluster}} \approx 50\text{ minutes}\); network packet loss causes the entire cluster to crash once per hour.
    4. \(\text{MTBF}_{\text{cluster}} \approx 5,800\text{ years}\); distributed redundancy inherently increases total system reliability proportionally to cluster size.

    Answer: The correct answer is A. \(\text{MTBF}_{\text{cluster}} \approx 48.8\text{ hours}\) (approx. \(2\text{ days}\)); because cluster failure rate scales linearly with GPU count (\(\text{MTBF} = \text{MTTF} / N\)), multi-week training runs will routinely encounter hardware faults, making automated checkpointing and fast localized recovery an operational necessity. Under an independent constant-hazard model where any single GPU failure halts the synchronous training job, cluster failure rate is \(\lambda_{\text{cluster}} = \sum_{i=1}^N \lambda_{\text{gpu}} = 1024 \times \frac{1}{50,000\text{ hr}} \approx 0.02048\text{ failures/hr}\). Taking the inverse yields \(\text{MTBF}_{\text{cluster}} = \frac{50,000}{1024} \approx 48.8\text{ hours} \approx 2.03\text{ days}\). Over a 30-day training run, the cluster is statistically guaranteed to experience \(\approx 15\) hardware failure events. Fault tolerance—via asynchronous non-blocking checkpointing to persistent storage and rapid worker node replacement—becomes a mandatory systems requirement rather than an optional safeguard. The alternative choices misapply basic reliability scaling laws.

    Learning Objective: Calculate cluster MTBF from component MTTF across large-scale accelerator pools and evaluate the operational necessity of fault tolerance and automated checkpointing.

  6. When moving from single-node ML systems to fleet-scale distributed systems, explain how the resource boundaries shift while the underlying physical laws remain invariant.

    Answer: Scaling from single-node to fleet scale does not change the governing physics—the Iron Law (\(T = D/\text{BW} + O/R_{\text{peak}} + L\)) still governs execution time—but the boundaries expand. Local memory bus bandwidth (HBM) is joined by cross-node network fabric bandwidth (InfiniBand/RoCE); single-device latency is joined by collective communication synchronization overhead (All-Reduce); single-GPU component MTTF (years) collapses into cluster MTBF (hours); and data gravity shifts from host-to-device transfers to cross-datacenter data placement. The engineer must apply the same quantitative bottleneck diagnosis across this wider boundary.

    Learning Objective: Explain how fleet-scale distributed systems expand resource boundaries (networking, collective communication, cluster MTBF) while preserving fundamental physical invariants.

← Back to Questions

Self-Check: Answer
  1. How does the chapter demonstrate that ethical outcomes—such as accessibility, subgroup fairness, and environmental sustainability—are direct consequences of technical engineering decisions rather than abstract policy add-ons?

    1. Ethical concerns are external legal constraints that have no interaction with compiler flags, quantization formats, or model architecture.
    2. Engineering decisions—such as selecting high-precision floating-point formats (increasing datacenter carbon emissions), requiring multi-GPU nodes for inference (restricting deployment accessibility), or training on uncurated data (amplifying demographic bias)—directly dictate societal and ethical impacts.
    3. Model compression is purely a financial optimization that has no relationship to democratizing AI access.
    4. Algorithmic fairness can be fully guaranteed simply by omitting demographic feature columns from the raw dataset.

    Answer: The correct answer is B. Engineering decisions—such as selecting high-precision floating-point formats (increasing datacenter carbon emissions), requiring multi-GPU nodes for inference (restricting deployment accessibility), or training on uncurated data (amplifying demographic bias)—directly dictate societal and ethical impacts. Technical choices inherently distribute costs and benefits: requiring high-end data center accelerators for serving excludes resource-constrained clinics from deploying medical AI (accessibility); unrepresentative data combined with feedback loops compounds disparities (fairness); and inefficient, uncompressed models increase Megawatt-hour datacenter power consumption and carbon footprints (sustainability). Ethics is an intrinsic dimension of technical design. The other options reflect discredited separation fallacies and naive fairness assumptions.

    Learning Objective: Analyze how technical engineering decisions regarding efficiency, data curation, and energy consumption propagate directly into ethical, accessibility, and environmental consequences.

  2. The chapter argues that ethical considerations cannot be separated from physical and algorithmic design because the same decisions set both. Using hardware requirements for inference and sustained accelerator power draw as examples, explain how an engineering decision becomes a societal consequence.

    Answer: A model that needs an array of high-end data-center accelerators for inference excludes organizations that cannot procure that hardware, so a sizing decision becomes an access decision. Sustained accelerator power draw drives facility heat dissipation and regional grid carbon emissions, so choices such as arithmetic precision and model size set an environmental cost borne outside the engineering team. Because the decision that fixes performance also fixes these consequences, responsibility has to be designed in alongside efficiency rather than added afterward.

    Learning Objective: Explain how technical decisions about hardware requirements and power draw propagate into access and environmental consequences.

← Back to Questions

Self-Check: Answer
  1. An engineer profiles an image classification serving pipeline and finds that host CPU-bound image decoding, resizing, and normalization consume 90% of end-to-end request latency (\(f_{\text{serial}} = 0.90\)), while GPU neural network inference consumes the remaining 10% (\(f_{\text{accelerated}} = 0.10\)). The engineer rewrites the GPU kernel to achieve a \(10\times\) inference speedup (\(S = 10\)). What is the resulting overall system-level speedup, and which systems principle explains this outcome?

    1. \(10.0\times\) overall speedup; accelerator improvements dominate user-perceived performance.
    2. \(5.5\times\) overall speedup; system improvement is the average of the two pipeline stage speedups.
    3. \(0.90\times\) overall speedup; kernel compilation overhead causes net performance regression.
    4. Approximately \(1.10\times\) overall speedup; according to Amdahl’s Law, the unaccelerated 90% serial preprocessing fraction strictly caps end-to-end speedup to \(\text{Speedup} = \frac{1}{0.90 + \frac{0.10}{10}} = \frac{1}{0.91} \approx 1.10\times\).

    Answer: The correct answer is D. Approximately \(1.10\times\) overall speedup; according to Amdahl’s Law, the unaccelerated 90% serial preprocessing fraction strictly caps end-to-end speedup to \(\text{Speedup} = \frac{1}{0.90 + \frac{0.10}{10}} = \frac{1}{0.91} \approx 1.10\times\). Amdahl’s Law (principle 8) governs end-to-end ML pipelines. When 90% of execution time remains unaccelerated on the host CPU (e.g., JPEG decoding, tokenization, or database feature lookups), even an infinite (\(S = \infty\)) speedup on the GPU inference kernel would yield at most \(\frac{1}{0.90} \approx 1.11\times\) overall system speedup. Optimizing without profiling where time actually goes is guessing, and Amdahl’s Law severely penalizes optimizations that target the non-dominant term. The other options violate Amdahl’s Law arithmetic.

    Learning Objective: Apply Amdahl’s Law to calculate end-to-end speedup when optimizing isolated pipeline stages and identify when unaccelerated preprocessing bounds system throughput.

  2. A team selects Model Alpha over Model Beta because Alpha achieves 94.8% top-1 accuracy on a static benchmark versus Beta’s 93.2%. When deployed, Model Alpha violates the 100 ms P99 serving latency SLO by taking 420 ms, consumes \(4\times\) more memory, and exhibits a 16% error rate on an underrepresented user demographic. Which systems concept explains why single-metric evaluation led to this production failure?

    1. The Pareto Frontier; production ML systems operate across a multi-dimensional objective space (accuracy, tail latency, memory, energy, cost, and subgroup fairness), where optimizing aggregate accuracy in isolation can select an infeasible, costly, or discriminatory operating point.
    2. The Silicon Contract; models with higher accuracy automatically violate hardware execution contracts.
    3. Data Gravity; higher accuracy models physically pull network packets away from edge caches.
    4. Amdahl’s Law; aggregate accuracy scales inversely with the number of parallel workers.

    Answer: The correct answer is A. The Pareto Frontier; production ML systems operate across a multi-dimensional objective space (accuracy, tail latency, memory, energy, cost, and subgroup fairness), where optimizing aggregate accuracy in isolation can select an infeasible, costly, or discriminatory operating point. Evaluating models solely along a single accuracy dimension inhabits a one-dimensional fantasy. In production, models must satisfy multi-objective constraints along the Pareto Frontier (principle 5): meeting P99 latency budgets (principle 12), fitting hardware memory capacity, respecting energy/cost limits, and ensuring equitable error rates across demographic subgroups (principle 13). A model with 1.6% higher aggregate accuracy that violates latency SLOs and exhibits extreme subgroup disparity is an engineering failure. The other options misapply unrelated systems concepts.

    Learning Objective: Critique single-metric accuracy evaluation and apply the Pareto Frontier to assess production models across latency, memory, energy, and subgroup fairness.

  3. True or False: High-level software frameworks, AutoML tools, and compiler abstractions eliminate underlying physical ML systems constraints (such as memory bandwidth bottlenecks, thermal dissipation limits, and Amdahl’s Law ceilings), allowing software engineers to ignore low-level hardware characteristics.

    Answer: False. Tools and abstractions hide and manage complexity; they do not eliminate physical constraints. A framework that abstracts memory management still transfers bytes across physical buses and consumes memory capacity; an AutoML engine tuning hyperparameters still operates on the Pareto frontier; and a compiler optimizing GPU kernels remains strictly bounded by Amdahl’s Law and memory wall physics. Engineers who assume tools eliminate physical constraints are routinely surprised when those constraints resurface at scale as mysterious OOM errors, tail latency spikes, or thermal throttling.

    Learning Objective: Analyze why software abstractions manage complexity rather than eliminating physical hardware constraints.

  4. A production drift alarm fires due to seasonal changes in user shopping patterns. Explain why triggering an automated rollback to a model checkpoint trained three months earlier is an operational pitfall, and state the appropriate remediation.

    Answer: Automated rollback is effective for software bugs or bad releases, but external real-world distribution drift cannot be repaired by restoring an older model trained on an even staler distribution. Restoring the older checkpoint will perform just as poorly or worse. The appropriate remediation is a diagnosed response: alerting the team, temporarily routing traffic to fallback heuristics or reducing traffic, collecting fresh ground-truth labels from the new distribution, and retraining/adapting the model.

    Learning Objective: Differentiate between release regressions and external distribution drift to select appropriate operational remediations.

  5. Looking across all seven fallacies and pitfalls detailed in the chapter (tools hiding complexity, untraced displaced costs, component-only mastery, untraced data-scaling costs, single-metric accuracy evaluation, unconditional rollbacks, and unprofiled stage optimization), identify the shared intellectual root cause that unites them and state the corrective systems engineering posture.

    Answer: The shared root cause is the reductionist temptation to treat an ML system as decomposable into independent, isolated parts—optimizing one dimension, one metric, one pipeline stage, or one moment in time as if the surrounding system were static. The corrective systems engineering posture is holistic boundary reasoning: measuring the end-to-end request path, profiling where time and bytes actually go before optimizing, tracing how decisions in one layer displace costs to other layers (conservation-of-complexity heuristic), and evaluating performance across the full multi-dimensional Pareto surface under real-world operational constraints.

    Learning Objective: Synthesize the shared systems misconception (reductionism and isolated optimization) underlying common ML systems failures.

← Back to Questions

Back to top