10 Model Compression
Purpose
Architecture stack focus for this chapter.
Why do the models that win benchmarks rarely become the models that run in production?
A capable trained model is not automatically a deployable one. Cloud, Edge, Mobile, and TinyML environments each impose physical constraints that research benchmarks ignore, including memory budgets measured in megabytes rather than gigabytes, latency targets measured in milliseconds rather than seconds, and power envelopes measured in milliwatts rather than kilowatts. Research optimizes for accuracy on held-out test sets; production optimizes for accuracy per dollar, accuracy per watt, and accuracy per millisecond. Models that win benchmarks are frequently larger, slower, and more resource-intensive than production envelopes permit. Bridging this gap requires a systematic discipline of compression that trades capabilities the deployment does not need for physical constraints it cannot violate. Because many trained models carry more numerical precision, parameters, or representational capacity than the target workload requires, some of that surplus can be removed while preserving predictive behavior, though a smaller representation is not automatically a faster one. Unless the hardware and runtime software stack exploit the new precision or structure, a nominal size reduction merely moves the bottleneck while latency remains unchanged: removing half the weights in a tensor leaves execution time and energy untouched if the underlying hardware still fetches, stores, and multiplies every zero. Applied effectively, compression reduces model size by integer factors, transforming a research artifact that runs only on data center accelerators into a production asset capable of executing on a mobile phone, sensor node, or embedded microcontroller. The engineering goal is to make the right model viable within its physical environment, which differs fundamentally from making a model as small as possible. In D·A·M terms, model compression enacts algorithm-machine co-design directly on the network, reshaping its mathematical structure to satisfy the physical limits of the target hardware.
Learning Objectives
- Explain compression as algorithm-machine co-design that trades surplus capacity for memory, latency, and energy constraints
- Compare pruning, distillation, and quantization by the resource each relaxes and where each lands on the accuracy-efficiency frontier
- Calculate parameter memory, precision, and sparsity reductions to estimate best-case compression gains
- Apply post-training, quantization-aware, and weight-only strategies under accuracy and hardware constraints
- Select structured pruning and operator choices that map to available accelerator kernels
- Design compression pipelines that order pruning, distillation, and quantization and account for why their combined gains do not multiply
- Evaluate measured latency, energy, and accuracy on target hardware rather than relying on FLOP counts
10.1 Fitting the Deployment Budget
A trained model arrives with demands on memory capacity, latency, and energy that were set by the server accelerators it trained on, not by the device it must run on. The target device instead enforces a strict deployment budget: the memory, time, and energy it grants to each result the model produces. Memory capacity bounds the bytes of weights and activations that can stay resident, a frame rate or token rate bounds the milliseconds available for each result, and a battery or thermal envelope bounds the joules that each result may consume. Bringing a model’s demands inside that budget, by changing what the model computes, how its values are stored, and how its operations execute, is the work of model compression.
Data Selection lowered the cost of producing a trained model by spending training compute only on examples that carry signal. Its savings end where the trained model begins. A model trained on a curated subset has the same parameter count, numerical precision, and memory footprint as one trained on the full corpus, so it can still overflow a phone’s memory or leave inference bound by memory bandwidth. Hardware Acceleration then examines the silicon that executes a model. Compression comes before it because compression decides what that silicon is asked to run: how many operations, how many bytes per value, and which kernels.
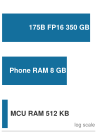
Frontier weights dwarf phone and microcontroller memory; compression bridges the gap.
The gap is easiest to see at its extreme. A 7-billion-parameter language model requires 14 GB merely to store its weights in FP16. A smartphone offers 8 GB of RAM shared across the operating system, background applications, and the user interface, so even if the operating system surrendered its entire memory pool to one process, the weights would not fit. Fitting in memory would only expose a second limit, the token rate. At batch size one, dense autoregressive decoding is memory-bandwidth bound because generating each token reads every weight from DRAM, and no other request shares those bytes. Over a flagship phone’s 51.2 GB/s low-power DDR (LPDDR) bus, streaming 14 GB takes about 270 ms per token and about 2 J of DRAM access energy, so the memory traffic alone would draw about 8 W, above the phone’s sustained thermal envelope of 3–5 W. A model of this size is the extreme case; the rest of the chapter works with models that come closer to fitting, where the engineering choices are less obvious.
Under the silicon contract (principle 4), compute throughput, memory bandwidth, memory capacity, and fixed launch overhead determine which physical resource binds first for a given model on a given machine. Training sets those quantities generously. Server-class accelerators supply the aggregate memory and floating-point throughput that wide layers, high numerical precision, and large auxiliary state require, because training must hold gradients, optimizer moment buffers, and activation caches across backward passes. Inference deployment relaxes several of these demands because execution is forward-only, intermediate activation buffers can be reused after their last consumer, and optimizer states disappear, even though residual branches still extend some tensor lifetimes and autoregressive decoding retains KV state across tokens. While mixed-precision methods improve training throughput by selectively adopting FP16 or BF16, deployment can reduce precision further, to INT8, INT4, or specialized microformats, when the target’s execution units support them. Model compression is the systematic process of meeting the silicon contract of a constrained execution context, reducing parameter footprint, memory traffic, or arithmetic operations while preserving task accuracy.
↩︎ Mixed-precision training with FP16 and BF16, including loss scaling and FP32 accumulation, is established in Mixed-precision training.
Across deployment targets, the disparity in weight memory spans about six orders of magnitude, from the 350 GB of FP16 weights in a 175-billion-parameter frontier model to the 512 KB of on-chip SRAM in an embedded microcontroller. The bitter lesson explains why this gap persists. General methods that scale with compute keep winning benchmarks, so the winning models grow with available training compute while a phone’s or microcontroller’s memory and power envelope stays fixed for the life of the device. Compression is the deployment-side counterweight to scale.
↩︎ The bitter lesson, that general methods which scale with compute keep displacing hand-engineered ones, is established in The Bitter Lesson.
Hendrycks, Dan, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, and Jacob Steinhardt. 2020. “Measuring Massive Multitask Language Understanding.” arXiv Preprint.
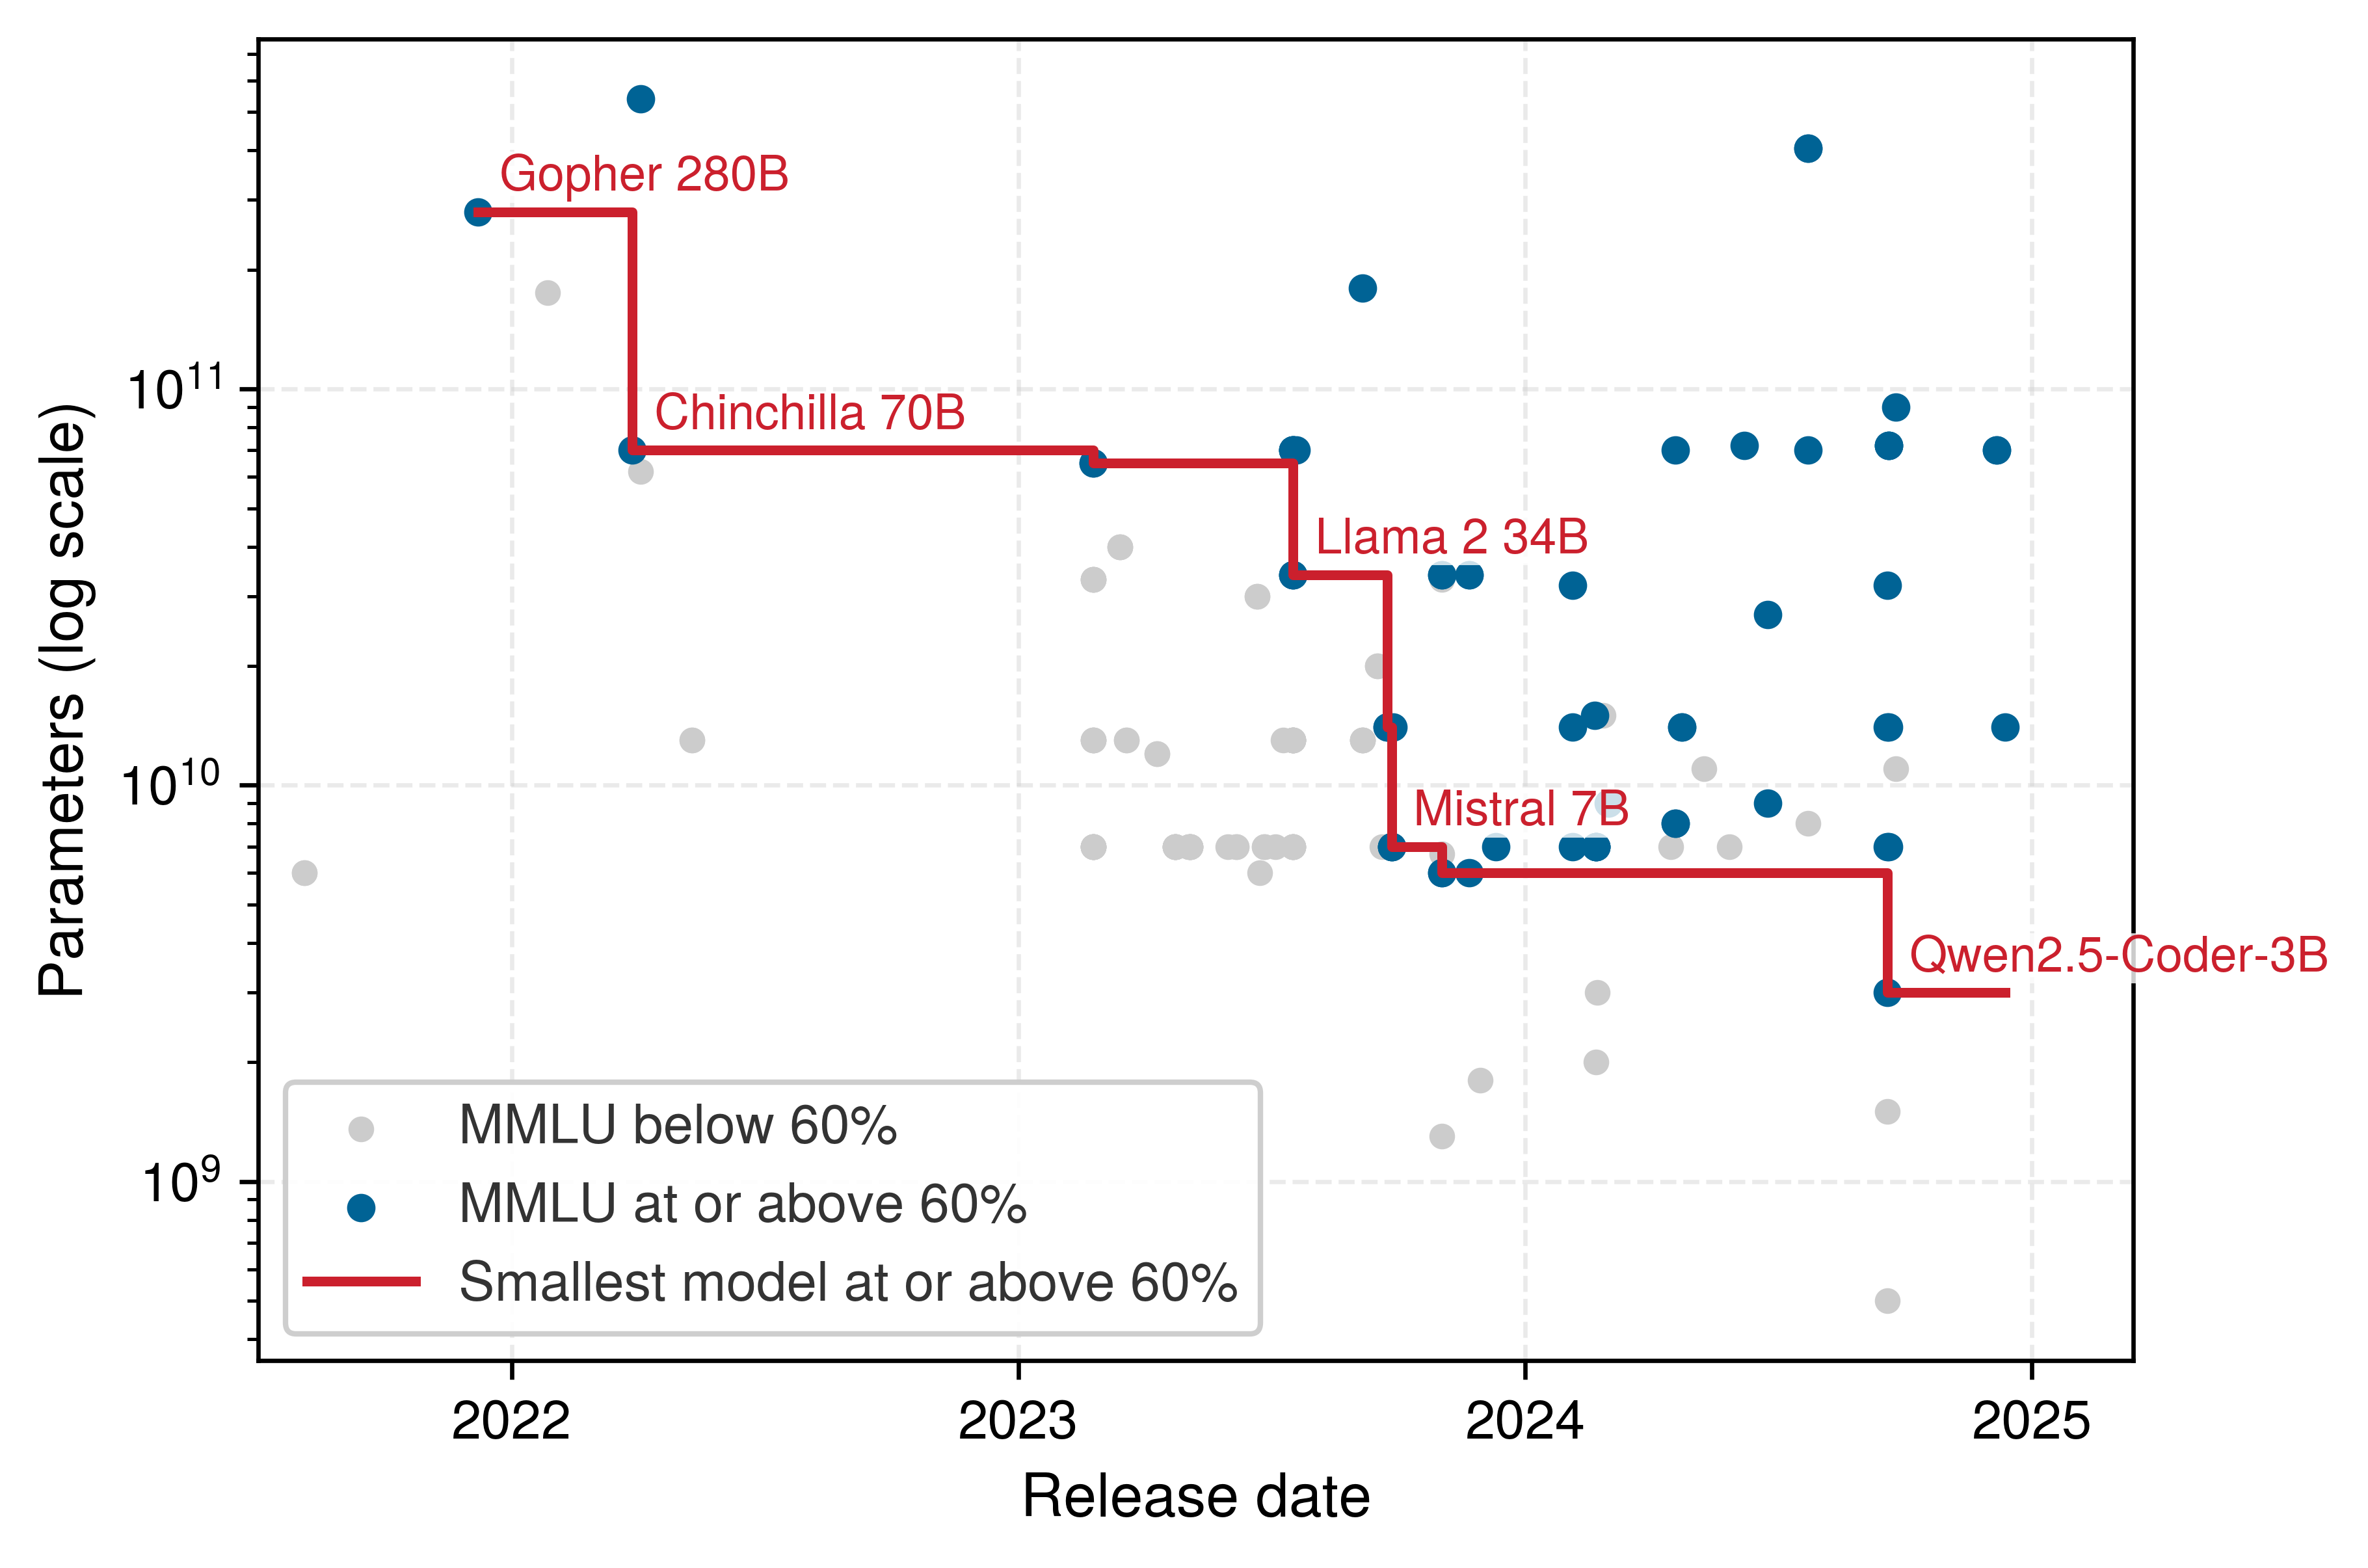
The record of language models shows how much ground that counterweight can recover. Figure 1 follows the smallest dense model reported to score at least 60 percent on the Massive Multitask Language Understanding (MMLU) benchmark (Hendrycks et al. 2020) at each point in time. That size fell from 280 billion parameters for Gopher at the end of 2021 to 3 billion for Qwen2.5-Coder-3B, a code-specialized model, in 2024, about 93× smaller in under three years (Epoch AI 2026). Better training data, longer training, and distillation from larger models all contributed, so the decline is not compression alone, but it shows that a capability first reached at frontier scale can later fit a far smaller deployment budget.
Epoch AI. 2026. Capabilities and Benchmarking.
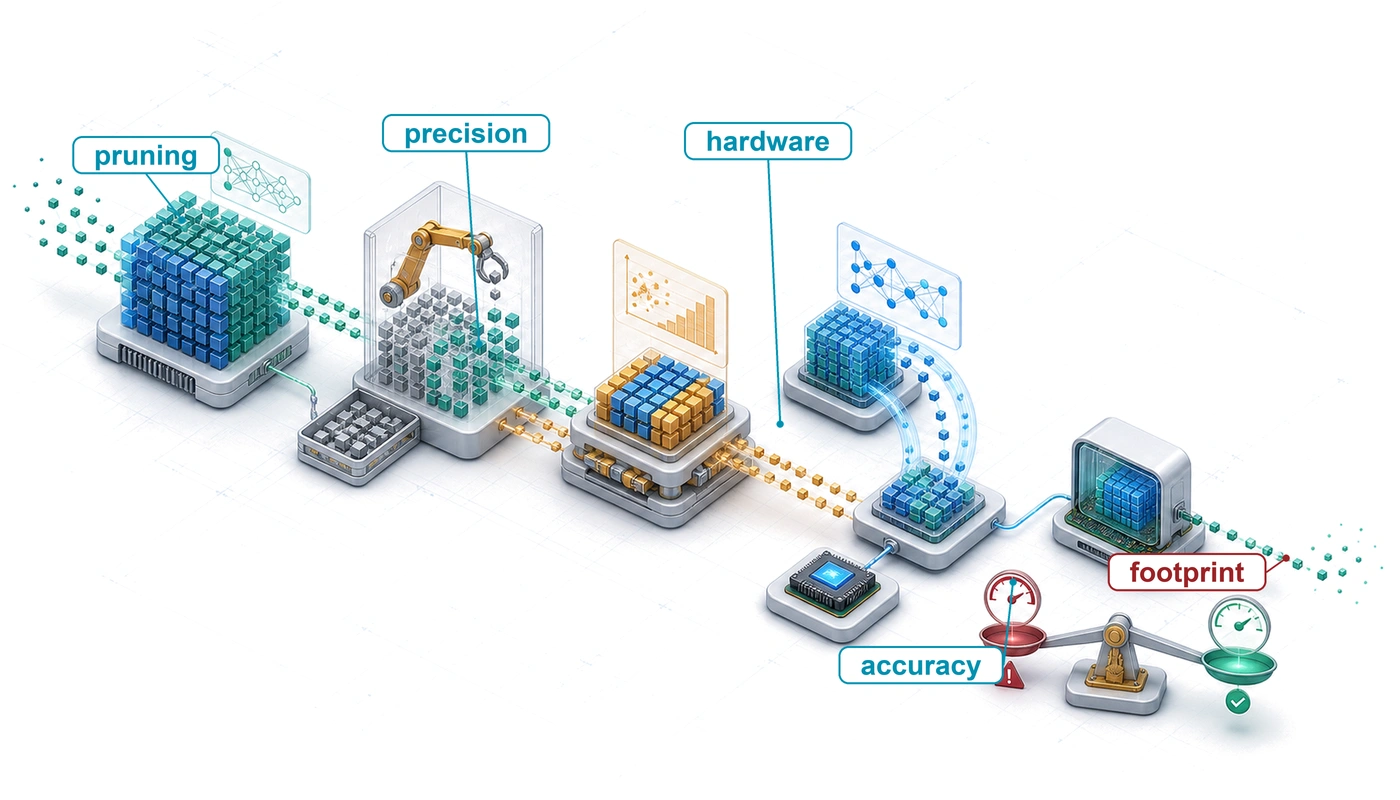
Bridging the gap between frontier models and fixed deployment targets requires an engineering framework with predictable physical trade-offs. Every compression technique removes specific structure from the model, whether unnecessary weights, surplus numerical bits, or redundant operator subgraphs. Designing a production deployment requires identifying which resource binds first on the target platform and analyzing how successive approximations compound across the memory hierarchy. The framework this chapter builds works on three tiers: what the model computes (its structure), how many bits represent each value (its precision), and how the result executes on the target processor (its implementation). Benefits compound only when transformations relieve distinct binding bottlenecks and the runtime supports the resulting graph.
Definition 10.1: Model compression
Model compression is a family of techniques that reduce a trained model’s computational cost and memory footprint by eliminating redundant parameters (pruning), reducing numerical precision (quantization), or transferring learned behavior into a smaller architecture (distillation), while preserving as much predictive accuracy as possible.
- Significance: In the iron law (principle 3), compression targets both the Algorithm factor (\(\text{FLOPs/Sample}\), and therefore total operations \(\Operations\)) and the Machine factor (\(\text{Seconds/FLOP}\), through its physical data-movement and compute terms). INT8 quantization of a 175-billion-parameter LLM leaves \(\text{FLOPs/Sample}\) unchanged but cuts weight memory from 350 GB (FP16) to 175 GB, a 2× reduction in \(\DataVolume\), while dedicated low-precision matrix units can raise \(\PeakRate\) when kernels and layouts use the supported INT8 path. Unstructured pruning to 50 percent sparsity halves the nonzero parameter count, but executed operations fall only when the runtime can skip those zeros through a supported sparse format or kernel without inflating \(\text{Seconds/FLOP}\) via index-traffic stalls.
- Distinction: Unlike post-training compression methods such as pruning and quantization, neural architecture search discovers efficient architectures from scratch by exploring a design space. Here, NAS is treated as a related structural optimization technique, because it changes the representation before training rather than compressing a finished model post hoc.
- Common pitfall: Compression techniques do not compose without interference. Pruning changes weight distributions and operation patterns; quantization adds calibration and kernel constraints. Their combination can lose accuracy or fail to accelerate without joint validation.
The three tiers form a stack that descends from algorithmic software toward physical silicon, the same direction in which ML Frameworks lowered a computational graph to kernels. At the top sits what operations the model executes, in the middle how many bits encode each operand, and at the bottom how kernels map onto the processor’s compute and memory structures (figure 2).
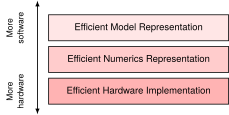
Each tier removes a different kind of surplus across the two levels of the iron law. The top tier, efficient model representation, removes structure and lowers the Algorithm factor (\(\text{FLOPs/Sample}\)). Pruning drops weights or whole channels that contribute little to accuracy, knowledge distillation trains a compact student to match a larger teacher, and neural architecture search (NAS) looks for layer shapes that meet an explicit latency or memory bound. The middle and bottom tiers leave \(\text{FLOPs/Sample}\) unchanged and instead lower the Machine factor (\(\text{Seconds/FLOP}\)). In the middle tier, efficient numerics representation removes bits. Quantization maps floating-point values to 8-bit or 4-bit integers, which shrinks weight memory and bus traffic (\(\DataVolume\)) by two to four times and lets integer units execute each operation at higher peak rate (\(\PeakRate\)) and lower energy. In the bottom tier, efficient hardware implementation removes wasted execution. Kernel fusion keeps intermediate activations in on-chip memory instead of sending them back to DRAM (shrinking \(\DataVolume\)) and reduces launch overhead (\(\Latency\)), while sparsity pays off only when its zeros follow a pattern the hardware can skip, such as two zeros in every group of four weights, so that cutting \(\text{FLOPs/Sample}\) does not inflate \(\text{Seconds/FLOP}\).
These three tiers are tightly coupled across the compilation and execution boundary. Pruning alters weight distributions and activation profiles, changing the dynamic ranges required for subsequent quantization-range calibration. Quantization reduces data-movement volume across the memory bus, shifting a previously memory-bound workload toward compute-bound execution where kernel fusion and tile scheduling dominate. Achieving compounding performance gains requires co-designing transformations across all three tiers rather than applying them in isolation, a composition strategy that section 10.5.3 develops through a staged pipeline.
Every technique in this chapter answers to the conservation-of-complexity heuristic that opened Part I. Complexity tends to move among the Data, Algorithm, and Machine axes rather than disappear, so engineers must account for where each technique sends cost and risk. It is a heuristic, not a literal conservation law, and removing genuinely avoidable work can reduce total cost. Pruning may reduce parameters while asking the runtime to exploit sparse structure; distillation may reduce inference cost while adding a teacher-student training phase; quantization may reduce data movement while spending numerical precision. The engineer’s task is to move complexity to where the cost is lowest given deployment constraints.
Which tier of the optimization stack yields the highest return depends entirely on the physical machine hosting the workload. A data-center server equipped with several high-bandwidth memory (HBM) accelerators tolerates multi-gigabyte models but demands high token throughput under concurrency. A smartphone or an embedded microcontroller operates under severe physical ceilings on memory capacity, bus bandwidth, and thermal dissipation.
10.1.1 Deployment budgets and the running cases
Cloud serving, a phone camera, and an embedded microcontroller each break down on a different term of the deployment budget, so compression begins by asking which term a given model violates and what it costs to stop violating it. Cloud inference centers on throughput (requests per second per dollar), where supported integer quantization paths increase serving density and kernel fusion reduces per-request kernel launch overhead (Choudhary et al. 2020; Dean et al. 2018). Mobile and edge deployments must fit within tight physical memory bounds while meeting deterministic real-time deadlines. A serialized camera pipeline that must finish each frame before the next arrives at 30 frames per second has about 33 ms per frame. A pipelined design that overlaps capture, inference, and display can sustain 30 frames per second even when each frame takes longer than 33 ms end to end, so it must check frame rate and per-frame latency as two separate budgets.
Choudhary, Tejalal, Vipul Mishra, Anurag Goswami, and Jagannathan Sarangapani. 2020. “A Comprehensive Survey on Model Compression and Acceleration.” Artificial Intelligence Review 53 (7): 5113–55. https://doi.org/10.1007/s10462-020-09816-7.
Dean, Jeff, David Patterson, and Cliff Young. 2018. “A New Golden Age in Computer Architecture: Empowering the Machine-Learning Revolution.” IEEE Micro 38 (2): 21–29. https://doi.org/10.1109/mm.2018.112130030.
Banbury, Colby R., Vijay Janapa Reddi, Max Lam, William Fu, Amin Fazel, Jeremy Holleman, Xinyuan Huang, et al. 2020. “Benchmarking TinyML Systems: Challenges and Direction.” arXiv Preprint arXiv:2003.04821.
TinyML makes physical fit a deployment requirement. A microcontroller with only a few hundred kilobytes of SRAM and limited model storage cannot accommodate a 100 MB model without a compatible placement strategy, regardless of predictive accuracy (Banbury et al. 2020). Persistent weights may reside in flash or other supported storage, while runtime buffers occupy working memory. Without paging, the peak SRAM working set must fit the available SRAM; the model artifact must separately fit its storage budget. Capacity is also a hard bound on mobile and cloud devices, though their placement options differ.
↩︎ The latency, memory, and power envelopes defining cloud, edge, mobile, and TinyML tiers are established in Four Deployment Regimes Across Nine Orders of Magnitude.
Meeting real-time deadlines on commodity mobile hardware depends as much on the hardware-supported precision path as on absolute memory capacity. When execution units provide hardware acceleration exclusively for fixed-point arithmetic, precision selection dictates whether a workload executes on energy-efficient neural processing units or falls back to power-hungry general-purpose cores. That choice decides the chapter’s running case, a camera pipeline that must meet an interactive frame rate within a phone’s thermal budget (Example 10.1).
Example 10.1: The running case: Real-time blur on a phone
Scenario: A labeled composite. A camera application deploys a MobileNetV2-based segmentation model for real-time background blur on mid-tier smartphones at 30 FPS.
Diagnosis: An uncompressed FP32 MobileNetV2 model runs on the phone’s CPU at only 8 FPS, about 125 ms per frame against a 33 ms budget, while holding the CPU at a power level the thermal envelope cannot sustain. The phone’s NPU or DSP accelerates integer matrix arithmetic, not FP32, so the uncompressed model cannot use it.
Systems lesson: INT8 quantization cuts raw parameter payload by 4\(\times\), but most of the gain from 8 FPS to 35 FPS comes from what INT8 unlocks, a move from the CPU onto the integer accelerator. The precision change is the enabler; the change of processor supplies most of the speed. The frame rates are illustrative, so speed and power still require device measurement.
The chapter follows that camera pipeline through the structural and hardware tiers of the stack. MobileNetV2 is the book’s compute-bound lighthouse in its efficient regime. Depthwise separable convolutions keep its arithmetic small, and at batch one on a phone its frame time goes to arithmetic and activation traffic rather than to reading weights. The precision tier needs a workload whose time is set by bytes, so it follows GPT-2 XL decoding on the same phone. GPT-2 XL is the book’s bandwidth-bound lighthouse, and every token it generates streams every weight. Two callouts mark the ends of the memory constraint. DLRM (Naumov et al. 2019), the capacity-bound lighthouse, shows precision deciding whether embedding tables fit, and keyword spotting (KWS) (Y. Zhang et al. 2017), the power-bound lighthouse, shows precision deciding whether a model fits a microcontroller’s SRAM and energy budget. ResNet-50, the compute-bound lighthouse, serves twice, as the teacher that distills into MobileNetV2 and as the subject of the closing INT8 deployment profile. Rather than running every technique on all five, the chapter returns to each workload where it exposes the binding resource most clearly.
↩︎ The iron law of ML systems, which splits execution time into data-movement, compute, and fixed-overhead terms, is established in Iron Law of ML Systems.
Table 1 places the cases’ weight bytes and work beside the deployment budget, and two of its rows explain how the chapter divides the work. MobileNetV2’s FP32 weights stream across the phone’s 51.2 GB/s memory bus in about 0.27 ms, roughly 1 percent of the 33 ms frame budget, so the frame is spent on its 600 MFLOP of arithmetic and on activation traffic, and the structural and execution tiers are the levers that matter. GPT-2 XL’s FP16 weights fit in the phone’s memory but take about 59 ms to stream for every generated token, so precision, which shrinks the bytes behind each weight, is the lever that matters. Even MobileNetV2 at INT8 exceeds the TinyML envelope by about 6.7×, while the purpose-built depthwise separable convolutional network (DS-CNN) keyword spotter fits it after INT8 quantization.
| Model and precision | Weight memory | Work per result | Weight streaming on the phone | Phone (8 GB) | TinyML (~512 KB) |
|---|---|---|---|---|---|
| MobileNetV2, FP32 | 14 MB | 600 MFLOP per frame | 0.27 ms | fits | no (26.7×) |
| MobileNetV2, INT8 | 3.5 MB | 600 MFLOP per frame | 0.07 ms | fits | no (6.7×) |
| ResNet-50, FP32 (teacher) | 102.4 MB | 8.2 GFLOP per image | 2 ms | fits | no (195.3×) |
| GPT-2 XL, FP16 | 3 GB | 3 GFLOP per token | 59 ms | fits | no (5722×) |
| GPT-2 XL, INT4 | 0.75 GB | 3 GFLOP per token | 15 ms | fits | no (1430.5×) |
| DS-CNN (KWS), INT8 | 200 KB | 20 MFLOP per inference | runs on a microcontroller | fits | fits |
| DLRM (reference) | 100 GB | lookup-dominated | does not fit | no (11.6×) | no (190734.9×) |
The chapter descends the optimization stack one tier at a time (table 2). Structural optimization changes what the model computes and carries the camera pipeline through pruning, low-rank factorization, distillation from a ResNet-50 teacher, efficient architecture design, architecture search, and input-dependent computation. Numerical precision changes how each surviving value is stored and carries GPT-2 XL decoding from numerical formats and their energy, through the quantization methods, to the conditions under which fewer bits run faster. Hardware implementation changes how the remaining operations execute, through the fusions and sparse kernels that compression makes possible and the gap between paper savings and measured ones. Choosing and combining techniques maps a binding constraint to the levers that relieve it, sequences them on the camera pipeline, and turns to the toolchains that apply them. Measuring compression gains closes the chapter on a ResNet-50 INT8 deployment profile, which Hardware Acceleration takes up. The descent begins at the top of the stack, with the structure of the model itself.
| Section | Tier of the stack | What changes | Iron law term most affected | Condition for a measured gain |
|---|---|---|---|---|
| Structural Optimization | Model representation | Which weights, channels, layers, and paths exist | Operations \(\Operations\), and weight bytes in \(\DataVolume\) | Removed structure leaves smaller dense tensors or a supported sparse format |
| Numerical Precision | Numerics representation | Bits per weight and activation | Bytes moved \(\DataVolume\), and energy per operation | The target has a kernel path for the format |
| Hardware Implementation | Hardware implementation | Which kernels run, and what they skip | \(\DataVolume\), fixed overhead \(\Latency\), and efficiency \(\EfficiencyHw\) | The compiler can fuse the pattern and the kernel can skip the zeros |
| Choosing and Combining Techniques | All three tiers | Which levers apply, and in what order | Whichever term binds | The binding resource is identified before any lever is applied |
| Measuring Compression Gains | The deployed system | Nothing in the model; the claims are measured | All terms, end to end | Measured on the target hardware against quality limits |
Self-Check: Question
The chapter’s optimization framework organizes model compression along three abstraction levels. Which sequence matches the stack from most software-level to most hardware-level?
- Efficient numerics representation → efficient model representation → efficient hardware implementation
- Efficient hardware implementation → efficient model representation → efficient numerics representation
- Efficient model representation → efficient numerics representation → efficient hardware implementation
- Efficient hardware implementation → efficient numerics representation → efficient model representation
A \(7\text{-billion}\)-parameter language model in FP16 occupies \(14\text{ GB}\) of weight memory alone. The target deployment platform is a smartphone with \(8\text{ GB}\) of shared RAM. Explain how quantizing weights to INT4 addresses both the physical memory capacity ceiling and the memory-bandwidth bottleneck during autoregressive token generation.
True or False: When a model cannot be deployed because its parameter footprint exceeds the device’s physical RAM capacity, operator fusion is an effective direct substitute for pruning or quantization.
A ____ is the memory, time, and energy that a target device grants to each result a model produces, and model compression is the work of bringing a trained model’s demands inside it.
Across the deployment contexts analyzed in the chapter, which platform most clearly makes model compression a feasibility requirement rather than mainly a throughput or cost optimization?
- TinyML microcontrollers, where SRAM and storage budgets are so small that some models cannot be placed at all without compression or redesign
- Cloud inference clusters, where only cloud systems face hard capacity limits and all smaller devices can compensate in software
- Autonomous edge servers, where continuous thermal throttling is preferred over changing the model
- Mobile smartphones, where unified memory architecture eliminates meaningful capacity constraints for large neural networks
A mobile video-conferencing feature requires \(30\text{ FPS}\) background segmentation, but baseline FP32 MobileNetV3 runs at only \(8\text{ FPS}\). Applying INT8 quantization accelerates the model to \(35\text{ FPS}\) with a minor \(0.4\%\) drop in mIoU, satisfying the shipping requirement. Which region of the chapter’s compression-accuracy Pareto frontier best describes this outcome?
- Region 1 (free lunch), because achieving 35 FPS proves that INT8 quantization incurs zero loss in segmentation boundary fidelity
- Region 3 (danger zone), because any reduction in numerical precision destabilizes temporal consistency in video processing
- An unfeasible operating point outside the Pareto frontier, because 35 FPS exceeds the maximum display refresh rate
- Region 2 (efficient trade), because a modest, acceptable drop in segmentation accuracy unlocks a 4.4× frame rate increase that satisfies the 30 FPS real-time shipping threshold
10.2 Structural Optimization: Changing What the Model Computes
A standard ResNet-50 trained on ImageNet contains over 25 million parameters, yet with careful magnitude pruning and retraining about 80 percent of its weights can be removed for roughly a one-point loss in top-1 accuracy (Gale et al. 2019). Modern neural networks routinely carry far more parameters than deployment requires.1 Unused capacity still consumes memory, computation, and energy. Structural optimization is the first tier of the stack, efficient model representation, by modifying what the model computes. Although additional capacity can aid optimization during training, parameters that do not improve the deployed model still impose deployment cost. The job is to remove capacity the task does not need without removing what it does need, and operating along the Pareto frontier2 means deciding where the conservation-of-complexity heuristic sends the cost, whether into training-time discovery, runtime sparse indexing, or student-model capacity.
1 Overparameterization: C. Zhang et al. (2017) demonstrated that networks large enough to fit ImageNet can also memorize completely random labels, showing that training capacity can exceed the structure needed for natural labels. Pruning studies then show the deployment consequence, that trained models often contain many parameters that can be removed or sparsified with modest task loss when pruning and fine-tuning are done carefully (Gale et al. 2019; Blalock et al. 2020). The redundancy is not a universal 10\(\times\) constant; it depends on architecture, dataset, sparsity pattern, and runtime support.
Zhang, Chiyuan, Samy Bengio, Moritz Hardt, Benjamin Recht, and Oriol Vinyals. 2017. “Understanding Deep Learning Requires Rethinking Generalization.” International Conference on Learning Representations (ICLR).
Gale, Trevor, Erich Elsen, and Sara Hooker. 2019. “The State of Sparsity in Deep Neural Networks.” arXiv Preprint arXiv:1902.09574.
2 Pareto frontier in compression: EfficientNet traces the frontier concretely, from B0 (77.1 percent accuracy, 390 million FLOPs) to B7 (84.4 percent, 37 billion FLOPs), a 95\(\times\) compute increase for 7.3 percentage points of accuracy, quantifying how steep the trade-off becomes at the frontier’s edge (Tan and Le 2019).
Tan, Mingxing, and Quoc V Le. 2019. “EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks.” International Conference on Machine Learning (ICML), 6105–14.
Hutter, Frank, Lars Kotthoff, and Joaquin Vanschoren. 2019. Automated Machine Learning: Methods, Systems, Challenges. In Automated Machine Learning. The Springer Series on Challenges in Machine Learning. Springer International Publishing. https://doi.org/10.1007/978-3-030-05318-5.
These techniques address the challenge through complementary structural mechanisms. Pruning eliminates redundant parameters from an existing network, and low-rank factorization stores an existing weight matrix as a product of two thin ones. Knowledge distillation transfers learned behavior into an independently designed compact network, efficient architecture design and neural architecture search build a network that is efficient on the target by construction (Hutter et al. 2019), and adaptive computation decides for each input how much of the network runs. In production pipelines, these techniques frequently compose, as when a NAS-discovered architecture, supervised by a distilled teacher, is pruned before final quantization.
The camera pipeline gives every structural technique the same test. MobileNetV2 must finish a frame within 33 ms on the phone, and its weights are not what fills that budget, so a structural change pays off only if it removes multiply-accumulates or activation traffic that the phone actually executes. The analysis below evaluates what structural artifact each method produces, what fine-tuning or recovery step it requires, and which hardware execution conditions allow it to deliver physical speedups. Pruning comes first because it exposes the systems constraint most directly. Eliminating mathematical parameters translates to physical hardware acceleration only when the resulting sparsity pattern aligns with the memory hierarchy and compute units of the target processor.
10.2.1 Pruning
For the camera pipeline, pruning3 is the first lever to try because it starts from the trained MobileNetV2 rather than from a new design. Removing whole channels from its convolutions shrinks every layer that consumes them and cuts the multiply-accumulates that fill the 33 ms frame budget. Removing scattered individual weights, by contrast, leaves the same layers in place and saves bytes or time only if the runtime stores the zeros compactly and skips them. The safe removable fraction depends on the architecture, task, pruning pattern, and recovery procedure, and every pruning design turns on three choices: what to prune (individual weights vs. entire structures), how to score what is expendable (magnitude, gradients, or activations), and when to prune (after training, during training, or at initialization).
3 Optimal Brain Damage: Introduced by LeCun et al. (1989), the method achieved 4\(\times\) parameter reduction, with proportional memory savings, in a handwriting recognizer by using a diagonal approximation to second-derivative (Hessian) information to estimate the loss increase from removing each weight. A full Hessian has \(\mathcal{O}(\Parameters^2)\) entries for \(\Parameters\) parameters, but Optimal Brain Damage avoids storing that full matrix by approximating its diagonal. Modern-scale pruning still favors cheaper criteria such as magnitude because even diagonal curvature estimation adds training cost.
LeCun, Yann, John S. Denker, and Sara A. Solla. 1989. “Optimal Brain Damage.” Advances in Neural Information Processing Systems 2 (NIPS 1989), 598–605.
Definition 10.2: Pruning
Pruning is a model-compression technique that sparsifies the parameter space by removing the weights or structures whose removal increases the training loss least.
- Significance: It can convert dense matrices into sparse structures, reducing memory footprint and total data volume \((\DataVolume)\) when the sparse representation, metadata, and recovery procedure preserve acceptable quality.
- Distinction: Unlike quantization, which reduces the precision of every weight, pruning reduces the count of weights by identifying and eliminating redundancy.
- Common pitfall: A frequent misconception is that pruning “automatically” speeds up execution. In reality, without specialized sparse execution support, the resulting sparse matrices may actually run slower than dense ones due to irregular memory access patterns. A speedup requires a storage format and a kernel that skip the zeros, not merely a faster processor.
The formal pruning objective seeks a sparse parameter tensor \(\PrunedWeightMatrix\) that minimizes empirical loss subject to a parameter budget \(\NonzeroParameterBudget\): \[ \min_{\PrunedWeightMatrix} \LossFunction(\PrunedWeightMatrix) \quad \text{subject to} \quad \|\PrunedWeightMatrix\|_0 \leq \NonzeroParameterBudget\] where \(\|\PrunedWeightMatrix\|_0\) is the \(\ell_0\) norm (the count of nonzero parameters). Solving this cardinality-constrained optimization is combinatorial, so practical methods use heuristics4 such as magnitude-based pruning. The thresholding heuristic keeps the largest weights and zeroes the rest (listing 1). Applied to an \(11\times 11\) weight tensor, it collapses sub-threshold entries to zero while irregular, high-magnitude weights persist across the grid (figure 3).
4 Heuristic: From Greek heuriskein (to discover), the same root as Archimedes’ “eureka.” In pruning, the dominant heuristic (larger magnitude means more important) works well empirically but creates a systems trap. Magnitude-based pruning applied globally can remove most parameters from overparameterized layers while leaving critical bottleneck layers largely intact, giving the appearance of aggressive compression while preserving much of the compute and memory cost in the layers that matter (Blalock et al. 2020). Iterative prune-retrain cycles with per-layer budgets are therefore often safer than naive global magnitude pruning, because each cycle lets the network redistribute importance before the next cut.
Blalock, Davis, Jose Javier Gonzalez Ortiz, Jonathan Frankle, and John Guttag. 2020. “What Is the State of Neural Network Pruning?” Proceedings of Machine Learning and Systems (MLSys) 2: 129–46.
import torch

# Original dense weight matrix
weights = torch.tensor(
    [[0.8, 0.1, -0.7], [0.05, -0.9, 0.03], [-0.6, 0.02, 0.4]]
)

# Simple magnitude-based pruning: keep only the 4 largest weights
threshold = 0.5
mask = torch.abs(weights) >= threshold
pruned_weights = weights * mask

print("Original:", weights)
print("Pruned (4 nonzeros):", pruned_weights)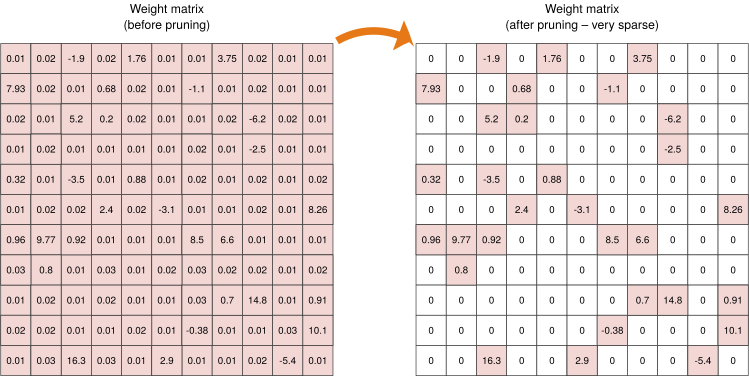
The resulting sparse matrix retains only the high-magnitude values (colored cells) while near-zero weights become exact zeros. In models amenable to pruning, much of the representational capacity remains intact after removing low-magnitude weights, establishing magnitude thresholding as an effective baseline heuristic.
To make pruning computationally tractable during gradient-based training, practical methods often relax the combinatorial \(\ell_0\) constraint with continuous penalties such as \(\ell_1\)-regularization \((\SparsityPenaltyWeight\| \WeightMatrix\|_1)\), where \(\SparsityPenaltyWeight\) scales the sparsity penalty applied to weight tensor \(\WeightMatrix\). Penalizing weight magnitudes drives non-essential parameters toward zero, making downstream thresholding easier. Practitioners typically couple this with iterative pruning, removing parameters in successive increments interleaved with fine-tuning cycles to recover lost accuracy (Gale et al. 2019; Blalock et al. 2020).
Target structures
The choice of what to prune depends on the deployment target’s hardware constraints and which resource is the binding bottleneck. When memory capacity is primary, neuron pruning can provide direct relief in models whose fully connected layers dominate parameter storage. Removing entire neurons and their associated weights and biases reduces layer width and parameter count. Profiling must first establish that these layers, rather than embeddings, activations, or another component, are the actual bottleneck.
When convolutional inference latency on commodity accelerators is the bottleneck, channel pruning (also called filter pruning) is a strong candidate. Eliminating entire channels or filters reduces feature-map depth and the multiply-accumulate count in subsequent layers. The resulting subnetwork remains dense and regular, so it can map to conventional GPU and Tensor Processing Unit (TPU) kernels without an unstructured sparse format. Realized latency still depends on the resulting dimensions, kernels, and memory traffic.
When a model contains removable stages, layer pruning removes entire layers from the network. Each removal eliminates all computation in that stage, but it also reduces representational depth and may change tensor shapes, residual paths, or downstream interfaces. The remaining layers must absorb the lost function, typically through fine-tuning or retraining. The nominal operation saving therefore does not guarantee proportional latency, because graph rewrites, kernel shapes, and memory traffic still govern execution. Layer pruning demands careful task validation and end-to-end profiling. Side by side, the two granularities differ in what they remove. An individual filter slice contracts intermediate feature depth, while an excised layer collapses a full computational stage (figure 4).
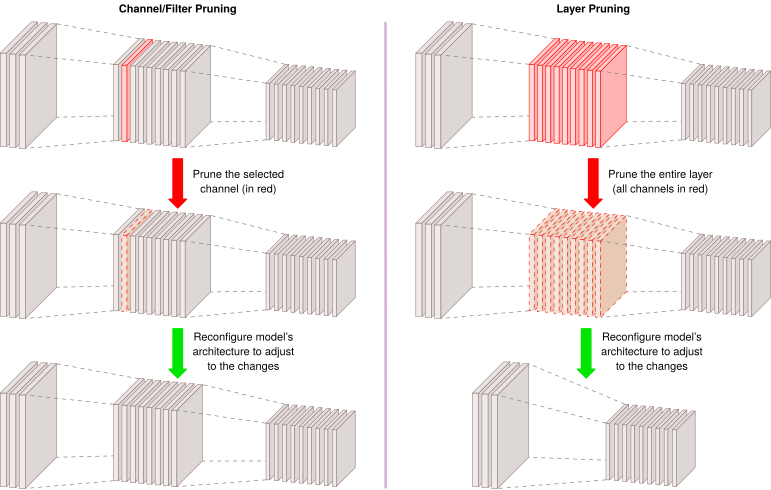
Channel and layer pruning place different demands on accelerator hardware. Channel pruning contracts the inner dimensions of dense general matrix multiply (GEMM) operations, because eliminating output channels in layer \(\ell\) reduces the input channel dimension in layer \(\ell+1\). The tensors remain dense and avoid sparse pointer lookups, but their dimensions still decide how well single instruction, multiple data (SIMD) lanes and Tensor Core tiles fill. Pruning a 256-channel layer to 250 channels, for example, removes about 2 percent of the work yet can leave a matrix unit that processes channels in groups of 8 running a partly empty final tile, so the layer may run no faster. Pruning to 248 keeps every tile full. The camera pipeline’s MobileNetV2 shows the same rule in its design, since its reference implementation rounds every channel count to a multiple of 8, and a pruning policy for the phone keeps the pruned counts on that grid. The preferred multiple depends on the kernel and numerical format, and because it counts elements rather than bytes, it is a different constraint from cache-line or memory-transaction alignment. Layer pruning removes full computational stages and their associated launches and intermediates, but the rewritten graph must still satisfy shape, residual-connection, and kernel-layout requirements. Both approaches require quality validation.
Unstructured pruning
Unstructured pruning removes individual weights while preserving the overall network architecture. Some connections become redundant during training, contributing little to the final output. Pruning these weak connections reduces the nonzero count and can preserve most task quality after recovery.
Formalizing this process, let \(\WeightMatrix\in \mathbb{R}^{\WeightMatrixRowCount\times \WeightMatrixColumnCount}\) represent a weight matrix in a given layer. Pruning removes a subset of weights by applying a binary mask \(\PruningMask\in \{0,1\}^{\WeightMatrixRowCount\times \WeightMatrixColumnCount}\), yielding a pruned weight matrix: \[ \PrunedWeightMatrix= \PruningMask\odot \WeightMatrix\] where \(\odot\) represents the element-wise Hadamard product. The mask \(\PruningMask\) is constructed based on a pruning criterion, typically weight magnitude. A common approach is magnitude-based pruning, which removes a fraction \(\SparsityRatio\) of the lowest-magnitude weights by defining a threshold \(\PruningThreshold\) such that: \[ \PruningMaskEntry = \begin{cases} 1, & \text{if } |\LayerWeightEntry_{i,j}| > \PruningThreshold\\ 0, & \text{otherwise} \end{cases} \] where \(\PruningThreshold\) is chosen to ensure that only the largest \((1 - \SparsityRatio)\) fraction of weights remain. This method assumes that larger-magnitude weights contribute more to the network’s function, making them preferable for retention.
Unstructured pruning reduces the count of nonzero parameters, but translating that reduction into physical storage savings requires an indexed sparse encoding such as Compressed Sparse Row (CSR) or coordinate list (COO), whose positional metadata can cancel the saving at low sparsity. Storing a dense tensor with zeroed entries saves no memory at all. Where the indexed formats break even in bytes and in time is a question about execution rather than about which weights to remove, and section 10.4.2.2 answers it.
Structured pruning
Where unstructured pruning removes individual weights across arbitrary tensor coordinates, structured pruning (Li et al. 2017) eliminates regular groups of parameters: channels, filters, attention heads, or entire layers. Because removing whole structural units contracts weight arrays into smaller, contiguous dense tensors, the remaining computation executes directly on standard Basic Linear Algebra Subprograms (BLAS) and convolution engines without specialized sparse libraries or metadata indexing overhead.
Li, Hao, Asim Kadav, Igor Durdanovic, Hanan Samet, and Hans Peter Graf. 2017. “Pruning Filters for Efficient ConvNets.” International Conference on Learning Representations (ICLR).
5 N:M structured sparsity: Introduced commercially with NVIDIA’s A100 GPU (2020), the 2:4 pattern was chosen because it halves multiply-accumulate operations while keeping position metadata small enough for the sparse Tensor Core path (NVIDIA Corporation 2020; Choquette et al. 2021). This fixed ratio is a hardware constraint, not a mathematical optimum. The A100 Sparse Tensor Core path accelerates 2:4 sparse operands, yielding up to 2\(\times\) math-throughput speedup over dense execution when kernels and layouts satisfy the constraint. Other ratios are not accelerated by this specific hardware path, illustrating how silicon design constrains which sparsity patterns translate to actual speedup.
NVIDIA Corporation. 2020. NVIDIA A100 Tensor Core GPU Architecture. NVIDIA Whitepaper, V1.0.
Choquette, Jack, Wishwesh Gandhi, Olivier Giroux, Nick Stam, and Ronny Krashinsky. 2021. “NVIDIA A100 Tensor Core GPU: Performance and Innovation.” IEEE Micro 41 (2): 29–35. https://doi.org/10.1109/mm.2021.3061394.
Between unconstrained irregular masks and coarse-grained channel excision lies hardware-aligned fine-grained regularity. Hardware-aware pruning strategies, such as N:M structured sparsity,5 enforce fine-grained patterns that map directly onto accelerator execution datapaths. Under a 2:4 structured sparsity constraint, every contiguous block of four weights must contain exactly two zeros and two nonzero values: \[ \text{Original block (4 values):}\quad [0.0,\; 1.4,\; 0.0,\; -2.1] \;\longrightarrow\; \text{Compressed storage:}\quad [1.4,\; -2.1] \quad \text{with 2-bit indices:}\; [01_2,\; 11_2] \] Because every group of four weights compresses to exactly two values, the value payload halves, and a 2-bit index per kept value adds only a small, fixed metadata cost with no structural irregularity. This chapter uses the 2:4 pattern as the canonical compression example, and section 10.4.2 returns to what a sparse matrix unit does with it.
↪ How sparse Tensor Cores use the 2-bit metadata to select matching activations and skip the zeroed multiplies is developed in N:M structured sparsity mechanics.
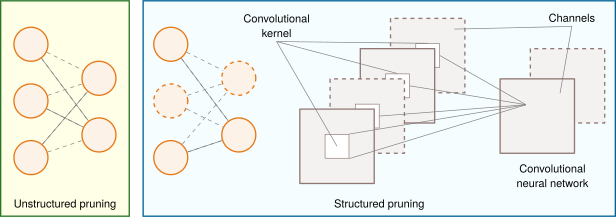
The regularity-compression trade-off spans three architectural granularities, from irregular connection masking to coarse-grained neuron dropping and full convolutional channel excision (figure 5). Moving from left to right trades per-weight freedom for dense tensor structure that standard hardware kernels can execute directly.
Qi, Chen, Shibo Shen, Rongpeng Li, Zhifeng Zhao, Qing Liu, Jing Liang, and Honggang Zhang. 2021. “An Efficient Pruning Scheme of Deep Neural Networks for Internet of Things Applications.” EURASIP Journal on Advances in Signal Processing 2021 (1): 31. https://doi.org/10.1186/s13634-021-00744-4.
In fully connected layers (center of figure 5), pruning neurons eliminates the corresponding rows and columns in adjacent weight matrices. In convolutional layers (right), pruning channels removes complete 3D filter slices. Either way the subnetwork stays dense, so the remaining systems requirement is matching the resulting tensor shapes and layouts to efficient kernels, the tile-filling condition of section 10.2.1.1.
A common approach to structured pruning ranks entire neurons or filters by the magnitude of their associated weights. A low group norm is an inexpensive proxy for low importance, not proof that the unit is dispensable. The score can use an \(\ell_1\)-norm or \(\ell_2\)-norm over the weights associated with each unit; groups below a selected threshold become pruning candidates. Layer-wise ranking matters because raw scales can differ across layers. The method needs no representative data pass, but computing scores, choosing a threshold, materializing the smaller graph, and validating or fine-tuning the result still incur engineering and compute cost.
Another strategy is activation-based pruning, which evaluates neuron or filter activations over a dataset. Units that remain weak across representative inputs become candidates for removal, subject to ablation or fine-tuning checks. This method captures input-dependent behavior rather than relying only on static weights. Its ranking can still miss rare but important inputs, depend on activation scaling, or change after upstream units are removed. Activation-based pruning therefore requires representative profiling data and validation after the selected structures are removed.
Gradient-based pruning uses loss derivatives to estimate how removing a neuron or filter would change the objective. A small first-order score suggests a candidate at the current checkpoint and on the sampled data; it does not establish permanent irrelevance or capture every interaction among units. Gradient-based criteria can combine a unit’s value with its gradient to rank the expected local loss change. Mathematically, this criterion approximates the change in loss \(\FiniteChange\LossFunction\) when zeroing parameter \(\ModelWeight_i\) via a first-order Taylor expansion: \(\FiniteChange\LossFunction \approx |\ModelWeight_i \cdot \frac{\partial \LossFunction}{\partial \ModelWeight_i}|\). Weights that are either near zero or have negligible gradients exert minimal influence on the objective, making them prime candidates for excision. Unlike weight-only magnitude criteria, they require backward computation and are usually integrated into training or fine-tuning. The pruned result still needs task-level validation because the score is a local approximation.
These criteria trade measurement cost against fidelity to model behavior. Magnitude scores are inexpensive and provide a useful baseline, but they ignore the input distribution. Activation scores incorporate representative inputs and expose units that are quiet on that workload, while gradient-based scores also incorporate the local loss surface at additional training cost. None dominates across models, and none establishes that removal is harmless. A sound comparison prunes to the same structural target, applies the same recovery budget, and measures task quality after removal. It then profiles the exported graph, because a better importance score can preserve quality without producing shapes that the target runtime executes efficiently. The choice therefore depends on available data and compute, the structure being removed, and the deployment’s quality margin.
Pruning trade-offs
The three pruning approaches occupy different positions on the regularity-versus-granularity trade-off. Unstructured pruning can remove individual weights and therefore express fine-grained sparsity, but accelerators need matching sparse formats and kernels to skip those zeros. Structured pruning removes channels, filters, or layers and can produce smaller dense operations that conventional hardware already supports. Dynamic pruning, which section 10.2.6 develops with the other input-dependent methods, makes the executed structure depend on each input, adding control and batching overhead in exchange for conditional allocation. The three differ in what they remove, what the runtime must support, and what recovery they need (table 3).
These categories describe deployed execution rather than mutually exclusive training algorithms. A structured subnetwork may be learned with a dynamic schedule and then frozen for serving; classify the artifact by what its runtime actually executes.
| Aspect | Unstructured Pruning | Structured Pruning | Dynamic Pruning |
|---|---|---|---|
| Removed unit | Individual weights in the model | Entire neurons, channels, filters, or layers | Adjusts pruning based on runtime conditions |
| Model structure | Sparse weight matrices; original architecture remains unchanged | Model architecture is modified; pruned layers are fully removed | Structure adapts dynamically |
| Impact on memory | Reduces the nonzero count; storage falls only with an appropriate sparse representation | Reduces model storage by removing entire components | Varies based on real-time pruning |
| Impact on computation | Dense work remains unless a supported sparse path skips zeros | Reduces nominal FLOPs; latency depends on resulting shapes and kernels | Varies with routing policy and controller overhead |
| Hardware compatibility | Requires sparse formats and matching execution support | Produces dense subnetworks, but awkward shapes can still underutilize hardware | Requires adaptive inference engines |
| Fine-tuning requirement | Often used to recover accuracy after pruning | Often used after structural modification | Depends on how the routing policy and subnetworks are trained |
| Use cases | Targets whose runtime provides sparse formats and kernels, or storage-bound high sparsity | Real-time inference optimization, mobile/edge AI, and efficient training | Adaptive AI applications, real-time systems |
Pruning schedules
The pruning schedule affects how much recovery training the network receives after capacity is removed. Two primary scheduling strategies govern weight removal: iterative pruning and one-shot pruning.
Iterative pruning
Iterative pruning removes capacity gradually, alternating each structural cut with fine-tuning so that the network recovers before the next cut. Across three successive prune-and-retrain cycles, accuracy drops after each cut and recovers during the fine-tuning that follows (figure 6).
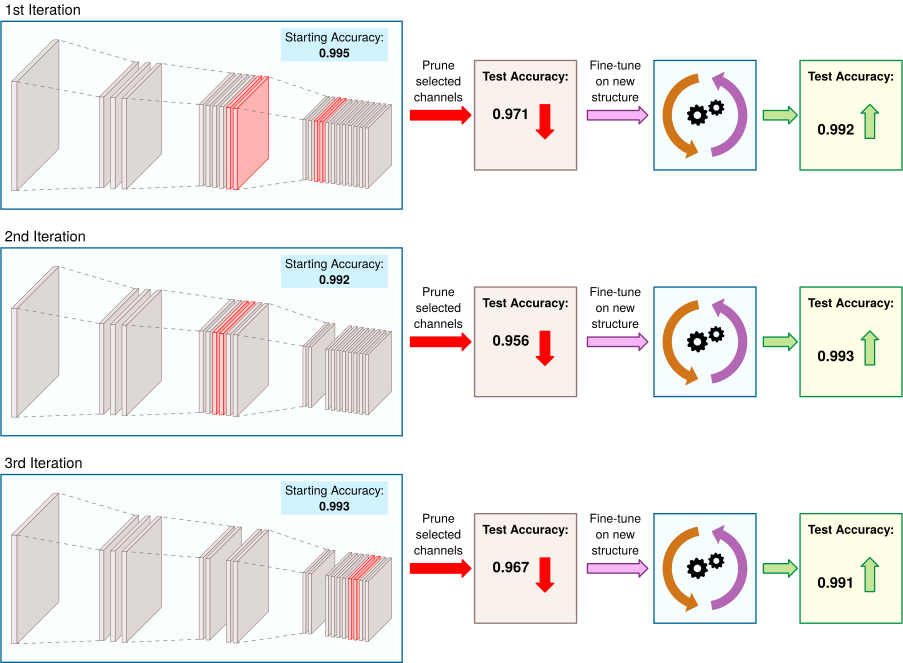
In the illustrative workflow, a convolutional network loses six channels with recovery between successive cuts. Rather than removing all six channels in a single pass, the pipeline removes two channels per cycle across three iterations, fine-tuning the remaining parameters after each cut. The initial cut drops accuracy from 0.995 to 0.971, but brief fine-tuning restores performance to 0.992. Two subsequent prune-and-tune cycles produce a final model at 0.991 accuracy, a 0.4 percent degradation despite a 27 percent reduction in channel count. Staging structural surgery across multiple retraining intervals allows surviving weights to adjust their representations along the loss landscape.
One-shot pruning
One-shot pruning removes multiple architectural components in a single step, followed by an extensive fine-tuning phase to recover model accuracy. This aggressive approach compresses the model quickly but risks greater accuracy degradation, as the network must adapt to significant structural changes simultaneously.
Applying one-shot pruning to the same network illustrates the hazard of aggressive structural truncation. Removing all six highlighted channels at once (figure 7) causes a sharp accuracy drop from 0.995 to 0.914, from which fine-tuning recovers only partially to 0.943, leaving about a 5 percent quality penalty under the recovery procedure shown. The two figures illustrate a mechanism, not a controlled result. Both runs end with the same tensor geometry, but the iterative run also received three rounds of fine-tuning, so its better final accuracy mixes the benefit of smaller cuts with the benefit of more recovery training. A fair comparison holds the final structure and the total recovery budget fixed.
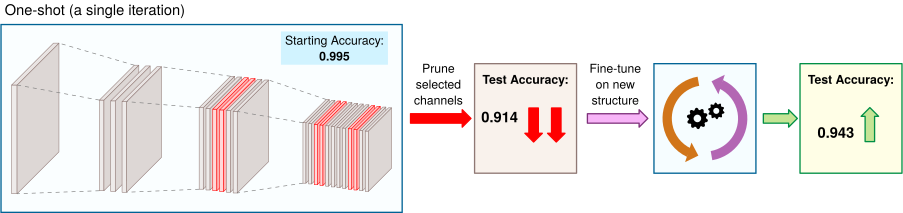
The working rule follows from that mechanism. Start with one-shot pruning plus recovery, because it is cheapest, and accept it if the recovered model meets the quality target. Move to an iterative schedule when it does not, which is most likely at high sparsity, where a single large cut removes capacity the network cannot rebuild in one recovery phase. Compare the two at a matched recovery budget, and spend the extra cycles only when the target accelerator can exploit the sparsity pattern that results.
Lottery ticket hypothesis (optional depth)
Standard pruning workflows assume a fully trained dense model from which weights are subsequently removed. Yet the relationship between network structure and optimization dynamics runs deeper, because pruning can reveal inherently efficient, highly trainable subnetworks embedded within the initial random parameterization.
This perspective leads to the Lottery Ticket Hypothesis6 (LTH), which challenges conventional pruning workflows by proposing that within large neural networks, there exist small, well-initialized subnetworks (“winning tickets”) that can achieve comparable accuracy to the full model when trained in isolation. Rather than viewing pruning as a post-training compression step, LTH suggests it can serve as a discovery mechanism to identify these efficient subnetworks early in training (Rachwan et al. 2022).
6 Lottery ticket hypothesis: Named for the intuition that training a large network is like buying many lottery tickets, most of which lose, while a few “winning tickets” (sparse subnetworks with favorable initializations) can train to comparable accuracy on their own. Frankle and Carbin (2019) established the hypothesis on smaller vision and fully connected networks; later work surveyed and extended the idea to larger settings (Rachwan et al. 2022). The systems implication is that some of the memory and compute spent training dense networks may be discoverable overhead, but the practical payoff depends on whether the winning subnetwork can be found before paying most of the original training cost.
Frankle, Jonathan, and Michael Carbin. 2019. “The Lottery Ticket Hypothesis: Finding Sparse, Trainable Neural Networks.” International Conference on Learning Representations (ICLR).
Rachwan, John, Daniel Zügner, Bertrand Charpentier, Simon Geisler, Morgane Ayle, and Stephan Günnemann. 2022. “Winning the Lottery Ahead of Time: Efficient Early Network Pruning.” International Conference on Machine Learning (ICML), 18293–309.
The discovery procedure is an iterative pruning-and-rewinding loop. After training to convergence and pruning low-magnitude connections, the surviving weights reset to their initialization state \(\ModelParameters_0\), which isolates a sparse subnetwork (figure 8). Repeating the cycle can isolate a sparse subnetwork that, in the reported settings, trains to accuracy comparable with the original network (Frankle and Carbin 2019). Whether the same procedure succeeds depends on architecture, scale, optimizer, and training budget.
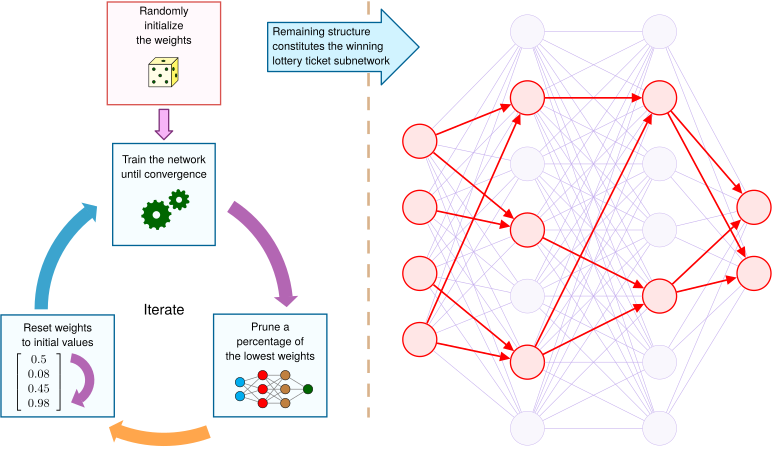
The Lottery Ticket Hypothesis suggests that compact, trainable subnetworks may exist inside an overparameterized initialization, which motivates direct sparse-training research. The standard discovery procedure, however, does not eliminate dense training cost. It first pays for one or more dense or partially dense runs, plus a rewind and a recovery phase per pruning cycle, to find the ticket. A winning ticket is therefore a training result. It becomes a systems win only when that total accelerator time, the final artifact size, target latency, and task quality beat the simpler alternatives: training a smaller dense model from the start, one-shot pruning with recovery, and direct sparse training.
Pruning in practice
While the Lottery Ticket Hypothesis illuminates the optimization landscape, practical serving systems care only about executable artifacts. Framework-level pruning is useful only when it materializes concrete hardware savings: a smaller dense tensor, a hardware-aligned structured sparse matrix, or an indexed sparse layout paired with matching runtime kernels. Training-time pruning often begins as mask application. The original tensor remains resident in memory, while a binary mask zeros selected weights during forward propagation. That mechanism guides gradient flow during recovery, but it delivers zero memory reduction or latency improvement on its own. Measurable efficiency gains emerge only after the masked structure is exported into the physical artifact loaded by the inference engine.
This artifact boundary is where the unstructured and structured strategies part ways. An exported unstructured mask still needs a sparse storage format and a matching kernel, whereas exported structured pruning is already a smaller dense graph. The systems audit therefore has three concrete steps. Identify what was pruned, identify the format the runtime receives, and verify that the target hardware has kernels that make the sparsity useful.
↪ Benchmark protocols that separate structured from unstructured pruning and specify the hardware and sparse-kernel support behind any measured speedup are developed in Compression benchmarks.
7 BERT pruning: BERT’s 12 attention heads per layer can contain substantial redundancy. Michel et al. (2019) found on MultiNLI that many heads could be removed without a statistically significant performance change. The removable fraction depends on the layer and task, so deployment pruning must measure both task quality and whether the resulting structure reduces runtime work.
Michel, Paul, Omer Levy, and Graham Neumann. 2019. “Are Sixteen Heads Really Better Than One?” Advances in Neural Information Processing Systems (NeurIPS).
Jiao, Xiaoqi, Yichun Yin, Lifeng Shang, Xin Jiang, Xiao Chen, Linlin Li, Fang Wang, and Qun Liu. 2020. “TinyBERT: Distilling BERT for Natural Language Understanding.” Findings of the Association for Computational Linguistics: EMNLP 2020, 4163–74. https://doi.org/10.18653/v1/2020.findings-emnlp.372.
In practice, BERT-style transformers7 have been pruned by removing redundant attention heads or intermediate dimensions, while separate distillation methods such as DistilBERT and TinyBERT train smaller dense student models that retain much of BERT’s performance (Sanh et al. 2019; Jiao et al. 2020). Pruning decides which weights exist, and every weight it keeps is still stored and multiplied at full size. A second way to shrink an existing layer keeps every weight position but stores the matrix as a product of two thin matrices, which suits layers whose weights carry less information than their dimensions suggest.
10.2.2 Low-rank factorization
Fetching and multiplying a full \(4096 \times 4096\) weight block from DRAM spends 93.75 percent of its memory traffic and arithmetic on directions that barely change the layer’s output when a rank-128 subspace already captures almost all of the transformation’s variance. Deep network weight matrices often show this rapid singular-value decay, and structured approximation exploits it by decomposing dense \(M \times N\) weight tensors into products of low-rank matrices or tensor factors that require only a fraction of the original scalar parameters (6.25 percent in the rank-128 case). Low-rank matrix factorization and multi-linear tensor decompositions translate this algebraic redundancy into reduced memory traffic and lower arithmetic cost. In the camera pipeline, the candidates are MobileNetV2’s pointwise convolutions, which are matrix multiplications over channels, and factoring one trades fewer multiply-accumulates against an extra kernel and an intermediate tensor, the trade-off developed below.
Matrix factorization
Low-rank matrix factorization (LRMF) approximates weight matrices with lower-rank representations. Given a weight matrix \(\WeightMatrix\in \mathbb{R}^{\WeightMatrixRowCount\times \WeightMatrixColumnCount}\), LRMF identifies factor matrices \(\LowRankLeftFactor\in \mathbb{R}^{\WeightMatrixRowCount\times \FactorizationRank}\) and \(\LowRankRightFactor\in \mathbb{R}^{\WeightMatrixColumnCount\times \FactorizationRank}\) such that: \[ \WeightMatrix\approx \LowRankLeftFactor\LowRankRightFactor^T \] where the approximation rank \(\FactorizationRank\ll \min(\WeightMatrixRowCount, \WeightMatrixColumnCount)\). This decomposition is typically computed via singular value decomposition (SVD),8 retaining only the \(\FactorizationRank\) largest singular values. Writing the truncated decomposition as \(\WeightMatrix\approx \LeftSingularVectorMatrix_k \SingularSpectrumMatrix_k \RightSingularVectorMatrix_k^T\) and splitting the singular values evenly between the two factors gives \(\LowRankLeftFactor= \LeftSingularVectorMatrix_k \SingularSpectrumMatrix_k^{1/2}\) and \(\LowRankRightFactor= \RightSingularVectorMatrix_k \SingularSpectrumMatrix_k^{1/2}\). During inference, computing the layer output as \(\HiddenActivation= \LowRankLeftFactor(\LowRankRightFactor^T \LayerInputVector)\) replaces a single large matrix-vector product with two sequential, smaller multiplications. The primary systems question is whether the reduction in parameter footprint and arithmetic operations compensates for the overhead of staging an intermediate activation and dispatching an additional kernel.
8 Singular value decomposition (SVD): The Eckart-Young theorem (1936) proves that retaining the top \(\FactorizationRank\) singular values yields an optimal rank-\(\FactorizationRank\) approximation in the Frobenius and spectral norms. The key systems trade-off is whether the high, one-time compute cost of this factorization, \(\mathcal{O}(\WeightMatrixRowCount \WeightMatrixColumnCount\cdot \min(\WeightMatrixRowCount,\WeightMatrixColumnCount))\), is amortized by the memory and bandwidth savings from using the smaller model in repeated inference calls.
Systems Perspective 10.1: The bandwidth-compute trade-off
Low-rank factorization can reduce both arithmetic and bandwidth demand when the retained rank is small, though it adds a second factor operation and possible kernel-launch overhead. Storing a 4096 by 4096 matrix requires 67.1 MB (at FP32). Fetching this matrix for a single inference imposes substantial memory traffic, especially when execution is limited by physical memory bandwidth.
Factoring the matrix at rank \(\FactorizationRank=\) 128 requires storing two smaller matrices (4096 by 128 and 128 by 4096), totaling only 4.2 MB, a 16× reduction in stored values. When inference uses the two factors directly, matrix-vector arithmetic also falls from \(\mathcal{O}(\WeightMatrixRowCount \WeightMatrixColumnCount)\) to \(\mathcal{O}(\FactorizationRank(\WeightMatrixRowCount+\WeightMatrixColumnCount))\) for small \(\FactorizationRank\). The deployment speeds up only if the two factor operations and their intermediate traffic cost less than the original dense kernel. Explicitly materializing \(\LowRankLeftFactor\LowRankRightFactor^T\) would add \(\mathcal{O}(\WeightMatrixRowCount \FactorizationRank \WeightMatrixColumnCount)\) work and defeat the purpose.
This bandwidth-compute trade-off exemplifies the memory wall at the operator level. When batch sizes are small, execution is bottlenecked by the time required to fetch weight bytes from DRAM rather than the time required to perform multiply-accumulate operations. In production serving engines, evaluating the factored representation avoids full-rank materialization entirely. The original \(\WeightMatrixRowCount\times \WeightMatrixColumnCount\) weight matrix \(\WeightMatrix\) becomes the product of a tall factor \(\LowRankLeftFactor\) (\(\WeightMatrixRowCount\times \FactorizationRank\)) and a wide factor \(\LowRankRightFactor^T\) (\(\FactorizationRank\times \WeightMatrixColumnCount\)) (figure 9).
↪ The AI memory wall, the regime in which arithmetic throughput outpaces the memory bandwidth that feeds it, is developed in The AI memory wall.
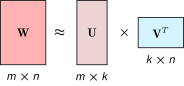
LRMF applies directly to fully connected projection layers and to flattened convolutional weight tensors. The storage and arithmetic savings derived above are only half of the accounting on a real accelerator. The intermediate activation vector \(\FactoredIntermediateActivation= \LowRankRightFactor^T \LayerInputVector\) must be staged in on-chip SRAM or round-tripped through memory, and dispatching two separate kernels incurs launch latency unless the operations are fused. Furthermore, if the approximation rank \(\FactorizationRank\) is small or unaligned with hardware tile dimensions (such as \(16{\times}16\) systolic arrays), the hardware compute units operate well below peak throughput. Selecting rank \(\FactorizationRank\) therefore balances memory footprint and bandwidth reduction against approximation error, kernel dispatch overhead, and hardware tile utilization.
↪ How a matrix is tiled onto a fixed-size systolic array, and why a dimension just past the tile width drops utilization sharply, is developed in Tiling.
Tensor decomposition (optional depth)
Tensor decomposition extends low-rank approximation to multidimensional arrays, such as four-dimensional convolutional kernels (\(\LayerOutputWidth \times \LayerInputWidth \times \KernelHeight \times \KernelWidth\)) and multi-head attention weights. Matrix factorization could compress such a tensor only after unfolding it into a matrix, which discards which axis was which. Tensor decompositions instead keep each axis separate by representing the tensor through multilinear products of lower-dimensional factors. A three-dimensional tensor \(\DecomposedTensor\in \mathbb{R}^{\TensorRowModeSize\times \TensorColumnModeSize\times \TensorDepthModeSize}\), for example, decomposes into three rank-\(\FactorizationRank\) factor matrices (\(\RowModeFactorMatrix\), \(\ColumnModeFactorMatrix\), and \(\DepthModeFactorMatrix\)), and outer products of the slice vectors \(\RowModeFactorSlice_i\), \(\ColumnModeFactorSlice_j\), and \(\DepthModeFactorSlice_t\) reconstruct entry \(\DecomposedTensorEntry\) (figure 10).
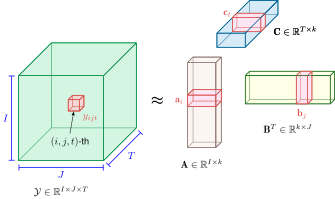
Formats trade parameter reduction against contraction complexity. CP decomposition (canonical polyadic decomposition) is the form drawn in figure 10. It expresses the tensor as a sum of \(\FactorizationRank\) rank-one components, \(\DecomposedTensor\approx \sum_{\RankComponentIndex=1}^{\FactorizationRank} \RowModeComponentVector \otimes \ColumnModeComponentVector \otimes \DepthModeComponentVector\), where \(\RowModeComponentVector\), \(\ColumnModeComponentVector\), and \(\DepthModeComponentVector\) are column \(\RankComponentIndex\) of \(\RowModeFactorMatrix\), \(\ColumnModeFactorMatrix\), and \(\DepthModeFactorMatrix\) (Lebedev et al. 2015), giving maximal parameter reduction but often unstable rank optimization. Tucker decomposition keeps a small dense core tensor multiplied along each mode by a factor matrix, \(\DecomposedTensor\approx \TuckerCoreTensor\times _1 \RowModeFactorMatrix\times _2 \ColumnModeFactorMatrix\times _3 \DepthModeFactorMatrix\), where \(\times_{\TensorModeIndex}\) multiplies along axis \(\TensorModeIndex\) of the tensor. Tensor-train (TT) stores a many-axis tensor (the order of a tensor is its number of axes) as a chain of small third-order cores, which avoids the exponential growth of Tucker cores with the number of axes.
Lebedev, Vadim, Yaroslav Ganin, Maksim Rakhuba, Ivan Oseledets, and Victor Lempitsky. 2015. “Speeding up Convolutional Neural Networks Using Fine-Tuned CP-Decomposition.” 3rd International Conference on Learning Representations (ICLR).
Tensor decomposition applies to convolutional filters, attention projections, and embedding tables. Its barrier is execution cost, because accelerators are specialized for dense matrix multiplication (GEMM). Contracting decomposed tensors needs transposition kernels or many small contractions, and without fused contraction kernels the data movement and launch latency can erase the arithmetic savings. LRMF and tensor decomposition differ in the data structures they apply to, the compression they achieve, and what they ask of the execution engine (table 4).
| Feature | Low-Rank Matrix Factorization (LRMF) | Tensor Decomposition |
|---|---|---|
| Applicable Data Structure | Two-dimensional matrices | Multi-dimensional tensors |
| Compression Mechanism | Factorizes a matrix into two or more lower-rank matrices | Decomposes a tensor into multiple lower-rank components |
| Common Methods | SVD; Alternating Least Squares (ALS), which fits one factor at a time | CP Decomposition, Tucker Decomposition, Tensor-Train (TT) |
| Compute cost | Depends on the factorization method, selected rank, and kernels | Depends on the decomposition, selected ranks, optimization procedure, and tensor-contraction kernels |
| Storage Reduction | Reduces storage from \(\mathcal{O}(\WeightMatrixRowCount \WeightMatrixColumnCount)\) to \(\mathcal{O}(\WeightMatrixRowCount \FactorizationRank+ \FactorizationRank \WeightMatrixColumnCount)\) | Depends on the decomposition and selected ranks; stores factor matrices and, for some methods, a core tensor |
| Inference execution | Replaces one dense operation with two factor operations | Introduces tensor contractions whose latency depends on available kernels |
| Primary Use Cases | Fully connected layers, embeddings, recommendation systems | Convolutional filters, attention mechanisms, multi-modal learning |
| Implementation Complexity | Easier to implement, often involves direct factorization methods | More complex, requiring iterative optimization and rank selection |
In production pipelines, practitioners frequently combine these structured approximations, applying LRMF to large linear projections and embedding tables while targeting multi-dimensional convolutional layers with tensor decompositions. Under the D·A·M taxonomy, structured approximation alters the Algorithm to relieve Machine memory-capacity and bandwidth bottlenecks. When fetched weights dominate serving latency, reducing weight bytes can reduce that component of execution time. Added factor operations, intermediate tensors, and launch overhead must still be counted; they can offset the saving in either a memory-bound or compute-bound workload.
Pruning and factorization both modify the parameterization of an existing model, and neither can replace an operator that suits the target poorly. If the original operator choices, kernel dimensions, or memory access patterns are ill-suited to the target accelerator, removing or factoring weights cannot substitute more efficient primitives. When deployment limits demand a different topology altogether, the compression objective shifts from subtracting weights to training a compact model to behave like the original.
10.2.3 Knowledge distillation
The camera pipeline’s MobileNetV2 does not have to learn its task from labels alone. A ResNet-50 trained for the same task needs 102.4 MB of FP32 weights and 8.2 GFLOP per image against MobileNetV2’s 14 MB and 600 MFLOP (table 1), far too much arithmetic for the phone’s frame budget, yet its output distribution carries information that labels do not. Knowledge distillation trains a compact student network, here MobileNetV2, to reproduce the output behavior and representations of an overparameterized teacher, here ResNet-50 (Hinton et al. 2015; Sanh et al. 2019). While the term borrows from chemical purification,9 the systems mechanism is algorithmic. Distillation transfers dark knowledge across architectures, amortizing a one-time training phase across millions of lower-latency inference queries.
9 Distillation: The name borrows from the chemical process of separating a mixture. In model compression, the student learns from a teacher’s softened output distribution or internal representations rather than copying its parameters. Soft targets can encode relationships among classes, but the student learns only what its objective and training data expose. The metaphor is useful but not literal, since the temperature parameter comes from softmax scaling, and the size-quality trade-off depends on the student, data, objective, and training procedure (Hinton et al. 2015). Deployment savings come from the student architecture, not from the metaphor itself.
Hinton, Geoffrey, Oriol Vinyals, and Jeff Dean. 2015. “Distilling the Knowledge in a Neural Network.” arXiv Preprint.
Definition 10.3: Knowledge distillation
Knowledge distillation is a model-compression technique that trains a smaller student model to match the behavior of a larger, pretrained teacher model.
- Significance: Distillation moves cost from repeated inference to an additional training phase. A student can be substantially smaller than its teacher while retaining useful task performance; DistilBERT, for example, reports 40 percent fewer parameters, 60 percent faster inference, and 97 percent of BERT’s language-understanding performance (Sanh et al. 2019). This trade-off is valuable when the student-training cost is amortized across many deployed queries.
- Distinction: Unlike pruning, which removes parameters from an existing architecture, and quantization, which lowers numerical precision, distillation trains a new dense architecture. The student inherits behavior from the teacher’s output distribution or intermediate representations rather than inheriting the teacher’s full parameter count or layer structure.
- Common pitfall: A frequent misconception is that distillation is lossless compression. In reality, the student is bounded by its own capacity, the quality of the teacher, and the match between the distillation data and deployment distribution; a student can faithfully reproduce teacher errors as well as teacher knowledge.
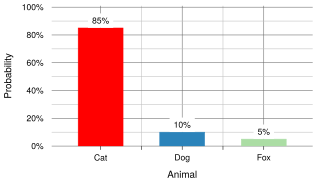
Data selection used the teacher’s soft targets as training data (Knowledge distillation); here they become a compression mechanism. Teacher models transfer semantic knowledge through nonzero probabilities assigned across non-target classes. Whereas a one-hot ground-truth label assigns a probability of one exclusively to the correct class, a teacher’s distribution keeps the inter-class correlations known as dark knowledge, revealing that an input classified as a cat (85 percent) shares subtle semantic features with a dog (10 percent) and a fox (5 percent) (figure 11).
Training a student model requires balancing teacher imitation against ground-truth task supervision. Operationally, the workflow requires four decisions before training begins: selecting a teacher with the desired behavior, designing a student whose dense architecture satisfies the target accelerator’s memory and compute budget, generating soft targets over the training corpus, and choosing the temperature and loss weights that govern optimization. In the resulting dual-path pipeline, an input sample \(\ModelInput\) passes through both the teacher and the student, temperature-scaled soft predictions (\(\DistillationTemperature > 1\)) feed the distillation loss, and unscaled student predictions (\(\DistillationTemperature = 1\)) are scored against ground-truth hard labels (figure 12).
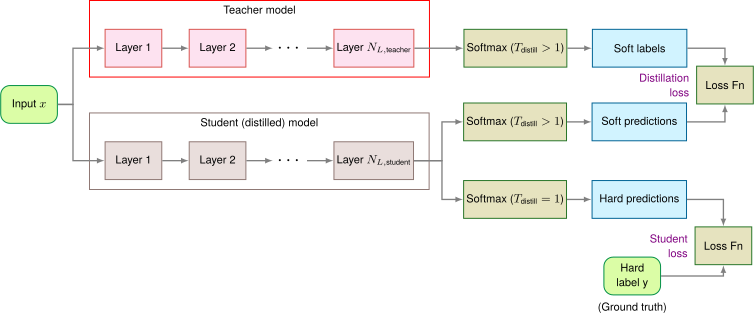
Deploying the distilled student requires verifying more than top-1 accuracy. Because a student can inherit the teacher’s systematic biases and miscalibrations as readily as its useful representations, verification must measure calibration error, subgroup behavior, and executed latency on the target hardware.
Distillation mathematics
Standard softmax normalization converts raw model logits \(\OutputLogit_i\) into probabilities. Introducing a temperature parameter10 \(\DistillationTemperature\) softens the resulting probability distribution across output classes: \[ \DistillationClassProbability_i = \frac{\exp(\OutputLogit_i/\DistillationTemperature)}{\sum_j \exp(\OutputLogit_j/\DistillationTemperature)} \]
10 Temperature (softmax): The term comes from the Boltzmann distribution in statistical mechanics. Dividing logits by a temperature above one produces a softer distribution and can expose relative probabilities among non-target classes. At \(\DistillationTemperature{=}1\), the expression is standard softmax; increasing the temperature reduces logit gaps but does not guarantee that the revealed probabilities help the student. The useful amount of softening depends on logit scale, teacher calibration, student capacity, loss weighting, and the accompanying \(\DistillationTemperature^2\) factor. Temperature is therefore selected empirically rather than fixed to a universal range.
11 KL divergence: Introduced by Solomon Kullback and Richard Leibler in 1951, \(\KlDivergence(\ReferenceDistribution\lVert \ApproximatingDistribution)\) quantifies the extra bits needed to encode samples from distribution \(\ReferenceDistribution\) using a code optimized for \(\ApproximatingDistribution\). The key asymmetric consequence: \(\KlDivergence(\text{teacher} \lVert \text{student})\) penalizes the student heavily for assigning zero probability to teacher-probable outputs, forcing the student to maintain broad coverage of the teacher’s distribution, including low-probability “soft labels” that carry the teacher’s learned uncertainty. Distillation can affect calibration, which must be evaluated separately.
A higher \(\DistillationTemperature\) flattens the softmax distribution and exposes more of the dark knowledge carried in relative class probabilities, such as a teacher assigning a small but nonzero probability to dog and near-zero probability to truck when classifying an image of a cat. The total distillation loss \(\DistillationLoss\) balances standard cross-entropy with the Kullback-Leibler (KL) divergence against the teacher’s softened distribution:11
\[ \DistillationLoss = (1 - \DistillationLossWeight) \CrossEntropyLoss(\StudentProbabilityVector, \LabelVector) + \DistillationLossWeight\DistillationTemperature^2 \KlDivergence(\SoftenedTeacherProbabilityVector \lVert \SoftenedStudentProbabilityVector) \]
Here \(\SoftenedTeacherProbabilityVector\) and \(\SoftenedStudentProbabilityVector\) are the probability vectors computed at temperature \(\DistillationTemperature\), \(\LabelVector\) is the one-hot ground-truth label vector, and \(\DistillationLossWeight\in [0,1]\) balances the hard-label and soft-target objectives. The scaling factor \(\DistillationTemperature^2\) ensures that the gradient magnitude of the distillation loss remains commensurate with the hard cross-entropy loss. Dividing logits by \(\DistillationTemperature\) scales the derivative of the softmax probabilities by \(1/\DistillationTemperature\), and the gradient of the KL divergence with respect to the student’s logits scales as \(1/\DistillationTemperature^2\) in the high-temperature limit. Multiplying by \(\DistillationTemperature^2\) prevents the teacher’s supervisory gradient from vanishing relative to the hard-label loss as \(\DistillationTemperature\) increases. This formulation defines response-based distillation, matching final output distributions. Modern pipelines also employ feature-based distillation, training intermediate student layers to directly match the teacher’s hidden representations or attention maps using mean squared error or cosine distance to guide gradient updates across deep backbones.
Efficiency gains and trade-offs
Distillation’s primary deployment advantage over unstructured pruning is that it produces a smaller dense model. Standard accelerators achieve peak throughput on contiguous matrix multiplications; unstructured sparse models incur irregular memory access and index decoding overheads that often negate theoretical FLOP reductions unless sparsity is extreme. A compact dense student maintains coalesced memory access and executes vendor-optimized dense GEMM kernels. However, parameter reduction alone does not guarantee lower latency, because operational intensity, layer depth, attention sequence length, and memory bandwidth limits still govern runtime. DistilBERT, for example, is about 60 percent faster (roughly 1.6\(\times\)) primarily because it removes half of BERT’s transformer layers (Sanh et al. 2019). The gap from the ideal 2\(\times\) reflects work that halving the layers does not remove, such as the embedding layer, the task head, and fixed per-request overheads.
Sanh, Victor, Lysandre Debut, Julien Chaumond, and Thomas Wolf. 2019. “DistilBERT, a Distilled Version of BERT: Smaller, Faster, Cheaper and Lighter.” arXiv Preprint arXiv:1910.01108, ahead of print. https://doi.org/10.48550/arXiv.1910.01108.
Gordon, Mitchell, Kevin Duh, and Nicholas Andrews. 2020. “Compressing BERT: Studying the Effects of Weight Pruning on Transfer Learning.” Proceedings of the 5th Workshop on Representation Learning for NLP, 143–55. https://doi.org/10.18653/v1/2020.repl4nlp-1.18.
Distillation composes with pruning and quantization in multi-stage compression pipelines, and the order matters. Quantization usually comes last, because its calibration must see the weight and activation distributions of the final structure. Pruning first and then distilling makes the pruned network itself the student, so distillation doubles as the recovery training after the cut. Section 10.5.3 applies this order to the camera pipeline and to a modeled BERT pipeline. Structural compression can also happen earlier than fine-tuning. Gordon et al. (2020) show that BERT pruned during pretraining transfers to downstream tasks, so the structural step need not wait for a task-specific model.
These operational gains trade inference efficiency for substantial training overhead. Distillation requires running inference across the teacher model to generate soft targets and backpropagating loss through the student across millions of tokens. For large models, this auxiliary training phase consumes significant accelerator FLOPs and memory bandwidth, whereas post-training quantization, introduced later in this chapter, needs only a pass over a small calibration set. Compression effectiveness is also bounded by student capacity and teacher fidelity. An undersized student lacks the capacity to absorb the teacher’s distribution, while an inaccurate or uncalibrated teacher imparts its own systematic errors to the student. Selecting an optimization strategy therefore requires evaluating task accuracy, parameter footprint, serving latency, and total training cost together, the comparison that table 11 in section 10.5 makes for distillation, pruning, and quantization.
Distillation still needs a student architecture, and the student’s own design decides how much of the frame budget remains for everything else. Efficient architecture design and neural architecture search build that student to be efficient on the target by construction.
10.2.4 Efficient architecture design
Hardware-aware design begins before compression. If the target device cannot keep convolution kernels fed, cannot store activations without spilling, or cannot meet the power budget at the chosen input resolution, pruning and quantization only treat symptoms. The architecture itself must expose the kind of work the hardware can execute efficiently. That means choosing layer shapes, scaling rules, and operator patterns with memory bandwidth, parallelism, and energy as first-class constraints rather than post-hoc deployment checks. The efficient families of Network Architectures, among them MobileNetV2’s depthwise separable factorization, are best read here as responses to a measured deployment bottleneck rather than as a catalog of architectures.
Efficient design principles
The first design step is to identify what the trace shows as the limiting resource. A model can miss its target because every layer is too expensive, because one convolution family dominates arithmetic, because activations or parameters do not fit the memory hierarchy, or because the candidate architecture ignores the platform’s preferred operators. Table 5 organizes the common responses by the bottleneck they address rather than by model family.
| Observed bottleneck | Architectural response | Example networks |
|---|---|---|
| Over-budget model scaling | Adjust depth, width, and resolution together so the model stays within the latency, memory, and power envelope. | EfficientNet |
| Redundant computation | Replace expensive dense operations with factorized or grouped operations that preserve useful channel mixing at lower arithmetic cost. | MobileNet, ResNeXt |
| Memory pressure | Reduce parameter storage or reuse features, then check peak activation lifetimes; feature reuse can retain a larger working set. | DenseNet, SqueezeNet |
| Platform mismatch | Include measured device latency, operator support, and power behavior in the architecture search or design loop instead of optimizing FLOPs alone. | MobileNetV3, MnasNet |
These responses interact. Reducing convolutional FLOPs with depthwise separable convolutions helps only if the target runtime has efficient kernels for the resulting operators. Shrinking a model with parameter-reduction layers helps only if activation storage or memory traffic was part of the measured problem. Hardware-aware design therefore does not replace profiling; it moves profiling information earlier, into the architecture itself.
Scaling optimization
The first architectural response is global. When every stage of the profile is over budget, the problem is not one bad layer; the model is scaled incorrectly for the deployment envelope. The design task is then to distribute capacity across depth, width, and input resolution rather than choose a single parameter count: depth adds sequential stages and activation storage, whereas width exposes more parallel work within each stage at the cost of larger weight and activation tensors, and higher input resolution sharpens spatial detail by multiplying the positions every convolution must visit. Which dimension to grow therefore depends on the machine, since a wide parallel accelerator can absorb extra channels while a small edge device is limited first by memory capacity and energy per access.
Mathematically, the total FLOPs for a convolutional model can be approximated as: \[ \Operations\propto \LayerCount \cdot \WidthMultiplier^2 \cdot \InputResolution^2, \] where \(\LayerCount\) is depth (number of layers), \(\WidthMultiplier\) is the width multiplier (channel count relative to a base model), and \(\InputResolution\) is the input resolution. This expression shows why naive scaling fails. Increasing width and resolution together multiplies work quickly, and the resulting model may exceed the memory bandwidth or power budget even when the parameter count appears reasonable.
The camera pipeline’s own architecture exposes one of these knobs directly. MobileNetV2’s width multiplier scales every layer’s channel count, and at a width of 0.75 the network shrinks from 3.5M to 2.6M parameters and from 600 MFLOP to 418 MFLOP per frame, keeping about 70 percent of the arithmetic. The square law predicts a larger cut, because depthwise layers cost in proportion to the width rather than its square, and the network’s final convolution keeps its full width at reduced multipliers. A width setting is therefore a trade the phone can measure directly, in milliseconds per frame, against the accuracy the narrower network loses.
Compound scaling turns this balancing act into a controlled design rule. Instead of adjusting depth, width, and resolution independently, compound scaling grows all three dimensions by fixed ratios \((\DepthScalingRatio, \WidthScalingRatio, \ResolutionScalingRatio)\) relative to a base model: \[ \LayerCount = \DepthScalingRatio^\CompoundScalingCoefficient \BaseLayerCount, \quad \WidthMultiplier= \WidthScalingRatio^\CompoundScalingCoefficient \BaseWidthMultiplier, \quad \InputResolution= \ResolutionScalingRatio^\CompoundScalingCoefficient \InputResolution_0 \] Here, \(\CompoundScalingCoefficient\) is a scaling coefficient, and \(\DepthScalingRatio\), \(\WidthScalingRatio\), and \(\ResolutionScalingRatio\) (as in the original EfficientNet paper) are scaling factors determined from empirical accuracy and efficiency measurements. The rule matters because it prevents one dimension from consuming the budget before the others can contribute useful accuracy.
EfficientNet (section 10.2.5) validated this principle by using search to find a baseline architecture and then scaling it with balanced depth, width, and resolution coefficients (Tan and Le 2019). The lesson is not that every deployment should use EfficientNet. The systems lesson is that scaling is a resource-allocation decision, because the same accuracy target can imply different depth-width-resolution trade-offs depending on which resource the target platform makes scarce. Benchmarking formalizes how to measure those trade-offs; the design principle here is to scale the dimensions against the binding resource.
The same logic extends beyond convolutional models. Transformer layers, attention heads, sequence length, and embedding width play roles analogous to depth, width, and resolution. Each increases capacity, but each stresses compute, memory bandwidth, or activation storage differently. Hardware-aware scaling keeps those dimensions tied to the measured bottleneck instead of treating model size as a single scalar.
Computation reduction
If the profile shows that a small set of convolutional operators dominates arithmetic, reducing the whole model uniformly is wasteful. The better response is to change the expensive operator. Modern efficient architectures do this by factorizing dense computations into cheaper pieces that preserve the representation needed for accuracy.
Depthwise separable convolutions, the factorization behind the MobileNetV2 and KWS lighthouses (Howard et al. 2017; Sandler et al. 2018), are the standard example. They split a standard convolution into a depthwise stage that filters each input channel separately and a pointwise \(1{\times}1\) stage that mixes channels, which cuts the arithmetic to about \(1/\LayerOutputWidth + 1/\KernelSize^2\) of a standard layer with \(\LayerOutputWidth\) output channels and kernel width \(\KernelSize\), roughly one-ninth for \(3{\times}3\) kernels and many output channels. What this chapter adds to that result is the deployment condition. The wall-clock benefit depends on kernel support and memory behavior. A mobile runtime with optimized depthwise kernels can convert much of this arithmetic reduction into latency savings, while a poorly supported backend may expose the factorized operations as many small, memory-bound kernels.
Howard, Andrew G., Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, and Hartwig Adam. 2017. “MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications.” CoRR abs/1704.04861.
↩︎ Depthwise separable convolution and its cost reduction relative to a standard convolution are established in Depthwise separable convolutions.
Other factorization patterns follow the same logic: ResNeXt’s grouped convolutions split feature maps into independent channel groups before merging them, whereas ResNet’s bottleneck blocks and SqueezeNet’s fire modules use \(1{\times}1\) convolutions to narrow the channel dimension before an expensive spatial convolution so that both arithmetic and parameter storage fall. Because all of these rewrites help only when the spatial convolution they shrink actually dominates the trace, they yield much smaller gains once memory traffic, launch overhead, or unsupported kernels become the binding cost.
Arithmetic reduction is only one possible response. When profiling instead identifies memory capacity or data movement as the binding resource on the target device, the architecture must address that memory bottleneck directly.
Memory optimization
When the profile points to memory rather than arithmetic, the architecture must reduce the working set or the number of expensive memory accesses. Activations, feature maps, and parameters can exceed cache, SRAM, accelerator memory, or edge-device storage even when the FLOP count is acceptable. Memory-efficient architectures therefore try to preserve useful information while storing or moving less data.
DenseNet illustrates the feature-reuse response (Huang et al. 2017). In a traditional convolutional network, each layer computes a new set of feature maps, increasing the activation footprint as the network deepens. DenseNet connects layers so later computations can reuse earlier feature maps instead of relearning similar representations. In DenseNet with \(\LayerCount\) layers and growth rate \(\FeatureMapGrowthRate\), each layer generates \(\FeatureMapGrowthRate\) new feature maps concatenated with prior layers, causing the total number of feature maps to grow linearly: \[ \mathcal{O}(\LayerCount \FeatureMapGrowthRate) \]
Huang, Gao, Zhuang Liu, Laurens Van Der Maaten, and Kilian Q. Weinberger. 2017. “Densely Connected Convolutional Networks.” 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 2261–69. https://doi.org/10.1109/cvpr.2017.243.
DenseNet reduces parameter redundancy through feature reuse, but concatenating retained features can increase activation storage and memory traffic. The resulting working set and runtime must be measured on the target hardware.
Parameter reduction applies the same reasoning to storage. SqueezeNet uses \(1{\times}1\) convolutions to reduce the number of input channels before applying standard convolutions, making the expensive layer operate on a smaller representation (Iandola et al. 2016). The number of parameters in a standard convolutional layer is: \[ \mathcal{O}(\LayerInputWidth \LayerOutputWidth \KernelSize^2) \]
Iandola, Forrest N., Song Han, Matthew W. Moskewicz, Khalid Ashraf, William J. Dally, and Kurt Keutzer. 2016. “SqueezeNet: AlexNet-Level Accuracy with 50x Fewer Parameters and <0.5MB Model Size.” ArXiv Preprint abs/1602.07360.
By reducing \(\LayerInputWidth\) using \(1{\times}1\) convolutions, SqueezeNet reduces parameter count, achieving the paper’s AlexNet-level accuracy target with far fewer parameters than AlexNet. That trade is attractive when the deployment constraint is flash storage, model download size, or parameter bandwidth; it is less decisive when activation memory or operator overhead dominates.
Feature reuse and parameter reduction are therefore not interchangeable recipes: reused features cut redundant representations, whereas \(1{\times}1\) bottlenecks cut parameter movement at deployment, so the profile’s binding memory term decides between them. Each of these manual motifs fixes one operator pattern at a time, leaving open how to choose kernel sizes, expansion ratios, and channel widths jointly across an entire network.
10.2.5 Neural architecture search
Hand-tuning kernel sizes, expansion ratios, and channel widths across twenty or more layers can explore only a handful of the billions of valid configurations that fit a phone’s latency budget, leaving significant accuracy or speed on the table. Neural architecture search (NAS) automates this structural design by systematically traversing a bounded space of operations, topologies, and compound scaling rules prior to training (Elsken et al. 2019). Early reinforcement-learning formulations maximized task accuracy without hardware constraints (Zoph and Le 2016); subsequent weight-sharing methods amortized evaluation overhead (Pham et al. 2018); and hardware-aware NAS explicitly incorporated measured device latency and energy into the multi-objective search (Tan et al. 2019). For the camera pipeline, architecture search is already part of the model’s lineage, since MnasNet and MobileNetV3, MobileNetV2’s successors, came from searches that measured candidate latency on phones (Tan et al. 2019; Howard et al. 2019).
Elsken, Thomas, Jan Hendrik Metzen, and Frank Hutter. 2019. “Neural Architecture Search.” In The Springer Series on Challenges in Machine Learning, vol. 20. Springer International Publishing. https://doi.org/10.1007/978-3-030-05318-5_3.
12 Hardware-aware NAS: Optimizes measured latency rather than FLOPs, which can diverge by 3–5\(\times\) when memory access or operator support dominates. Tan et al. (2019) fed device latency into search and found architectures 1.8\(\times\) faster than MobileNetV2 at higher accuracy.
Tan, Mingxing, Bo Chen, Ruoming Pang, Vijay Vasudevan, Mark Sandler, Andrew Howard, and Quoc V. Le. 2019. “MnasNet: Platform-Aware Neural Architecture Search for Mobile.” 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2815–23. https://doi.org/10.1109/cvpr.2019.00293.
Discovery runs as a closed loop. The search strategy samples candidate architectures \(\CandidateArchitecture\in \ArchitectureSearchSpace\) from the defined search space, and the performance estimation engine evaluates their latency or accuracy and feeds the result back to refine subsequent proposals (figure 13). NAS12 returns graphs that sit on the Pareto frontier under explicit resource bounds.
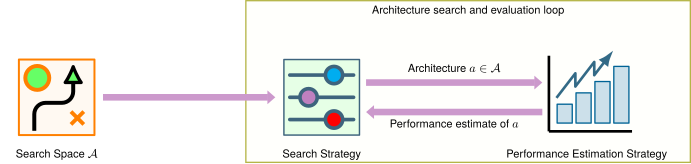
The NAS optimization problem (optional depth)
NAS rests on three design decisions: the search space, the search strategy, and how each candidate is evaluated. An architecture’s quality cannot be known until it is trained, and training is expensive, which creates two nested decisions: which operations to include (the architecture) and which parameters work best for them (the weights).
NAS is therefore a bi-level optimization problem.13 The outer loop searches the architecture space \(\ArchitectureSearchSpace\), while the inner loop trains candidate architectures to evaluate performance. Formally, the objective seeks the optimal architecture \(\CandidateArchitecture^*\) that minimizes validation loss \(\ValidationLoss\) under constraints \(\ArchitectureResourceCost\) (latency, memory): \[ \CandidateArchitecture^* = \operatorname{arg\,min}_{\CandidateArchitecture\in \ArchitectureSearchSpace} \ValidationLoss(\ModelParameters^*(\CandidateArchitecture), \CandidateArchitecture) \quad \text{subject to} \quad \ArchitectureResourceCost(\CandidateArchitecture) \leq \ResourceCostBudget\] where \(\ModelParameters^*(\CandidateArchitecture)\) represents the optimal model parameters for architecture \(\CandidateArchitecture\), obtained by minimizing training loss: \[ \ModelParameters^*(\CandidateArchitecture) = \operatorname{arg\,min}_{\ModelParameters} \TrainingLoss(\ModelParameters, \CandidateArchitecture) \]
13 Bi-level optimization: A formulation where one optimization problem sits inside another. In NAS, the outer level selects an architecture while the inner level trains that candidate’s weights, so early methods paid a full training cost for every architecture evaluated. Weight-sharing methods such as Efficient Neural Architecture Search (ENAS) amortize one training run across many candidates, reducing search cost by roughly 1,000× (Pham et al. 2018).
Pham, Hieu, Melody Y. Guan, Barret Zoph, Quoc V. Le, and Jeff Dean. 2018. “Efficient Neural Architecture Search via Parameter Sharing.” Proceedings of the 35th International Conference on Machine Learning (ICML), Proceedings of machine learning research, vol. 80: 4095–104.
The computational bottleneck lies in this inner loop. If evaluating every candidate requires independent training from scratch, a modest search space of 10 operation choices across 20 layers yields \(10^{20}\) possible architectures, making exhaustive enumeration impossible. Practical NAS methods overcome this combinatorial explosion through three mechanisms: restricting the search space to reusable cells, amortizing evaluation through weight sharing, or relaxing discrete choices into continuous, differentiable formulations.
Search space design (optional depth)
Many NAS systems search for reusable cells that are stacked to form complete networks, rather than searching whole architectures. A convolutional cell might choose among \(3{\times}3\) convolution, \(5{\times}5\) convolution, depthwise separable convolution, max pooling, or identity connections. A simplified cell with four nodes and two operations per edge yields roughly 10,000 possible cell designs, far more tractable than searching full architectures. NASNet discovered reusable normal and reduction cells this way.
Search spaces also encode hardware constraints by restricting candidate operations to primitives with efficient kernels on the target platform. Mobile search spaces, for example, prioritize depthwise separable convolutions with bounded kernel sizes and channel counts (Zhang et al. 2020). MobileNetV3 paired this structured block-level search space with NetAdapt to prune layer channels against measured mobile CPU latency (Howard et al. 2019).
Zhang, Li Lyna, Yuqing Yang, Yuhang Jiang, Wenwu Zhu, and Yunxin Liu. 2020. “Fast Hardware-Aware Neural Architecture Search.” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW). https://doi.org/10.1109/cvprw50498.2020.00354.
Search strategies (optional depth)
Search strategies trade search cost against architectural diversity (table 6). Reinforcement learning treats search as a sequential decision in which a controller proposes architectures and receives an accuracy reward. It discovered NASNet, but every reward requires training a candidate; Zoph and Le (2016) evaluated roughly 12,800 architectures on 800 GPUs for 28 days, a total of 22,400 GPU-days, a cost that pushed practical NAS toward weight sharing and cheaper performance predictors. Evolutionary algorithms instead mutate and recombine a population of candidates and keep the fittest; AmoebaNet reached ImageNet accuracy competitive with top human-designed models after 3,150 GPU-days (Real et al. 2019), a cost that needs proxy tasks, weight sharing, or massive parallelism to control. Gradient-based methods such as DARTS (Differentiable Architecture Search) (Liu et al. 2019) relax the search space into weighted combinations of all operations and optimize architecture weights and model weights jointly by gradient descent, reducing search cost from hundreds of GPU-days to one to four, though the relaxation may miss discrete patterns that discrete search finds.
Zoph, Barret, and Quoc V. Le. 2016. “Neural Architecture Search with Reinforcement Learning.” International Conference on Learning Representations 3.
Real, Esteban, Alok Aggarwal, Yanping Huang, and Quoc V. Le. 2019. “Regularized Evolution for Image Classifier Architecture Search.” Proceedings of the AAAI Conference on Artificial Intelligence 33 (01): 4780–89. https://doi.org/10.1609/aaai.v33i01.33014780.
Liu, Hanxiao, Karen Simonyan, and Yiming Yang. 2019. “DARTS: Differentiable Architecture Search.” International Conference on Learning Representations (ICLR).
| Strategy | Search Efficiency | When to Use | Key Challenge |
|---|---|---|---|
| Reinforcement Learning | 22,400 GPU-days | Novel domains, unconstrained search | High computational cost |
| Evolutionary Algorithms | 3,150 GPU-days | Parallel infrastructure available | Requires large populations |
| Gradient-Based (DARTS) | 1–4 GPU-days | Limited compute budget | May converge to suboptimal local minima |
Hardware-aware NAS optimizes execution metrics on target silicon rather than FLOP counts, which correlate poorly with latency when memory bandwidth or launch overheads dominate. Under the arithmetic intensity law (principle 6), an operation with few FLOPs but low arithmetic intensity can run slower than a higher-FLOP operation that saturates compute. MnasNet addresses this divergence by measuring each candidate’s latency directly on a mobile phone and folding it into the reward, which combines accuracy and latency through a weighted product: \[ \text{Reward}(\CandidateArchitecture) = \text{Accuracy}(\CandidateArchitecture) \times \left(\frac{\TargetInferenceLatency}{\InferenceLatency(\CandidateArchitecture)}\right)^{\LatencyRewardExponent}\] where \(\InferenceLatency(\CandidateArchitecture)\) is the measured on-device inference latency of architecture \(\CandidateArchitecture\), \(\TargetInferenceLatency\) is the latency constraint, and the exponent \(\LatencyRewardExponent\) controls the accuracy-latency trade-off. Architectures that exceed the latency target are penalized. In the reported MnasNet search space, varying inverted-residual expansion ratios produced a stronger accuracy-latency trade-off than uniform expansion.
When to use NAS
Neural architecture search can discover architectures that outperform hand-designed alternatives, but its cost demands a check on whether the investment is justified. NAS can be worthwhile for novel hardware platforms with unusual constraints, such as new accelerator architectures or highly constrained edge devices, where existing architectures are poorly optimized. It can also make sense at deployment scales where small efficiency improvements justify the upfront search cost, or when architecture families for cloud, edge, and mobile deployments can amortize one search across many variants.
Conversely, custom NAS is difficult to justify when standard deployment constraints already have well-optimized architecture families. If the compute budget is only a few GPU-days, large reinforcement-learning or evolutionary searches are impractical; differentiable or weight-sharing methods such as DARTS may remain feasible, but still require deployment-scale and validation-cost justification. Rapidly changing requirements also weaken the case because the target can move before search and validation finish.
For most practitioners, existing NAS-discovered or NAS-assisted architectures provide strong baselines before funding a search from scratch. EfficientNet jointly scales depth, width, and resolution with compound coefficients (Tan and Le 2019), MobileNetV3 combines hardware-aware search with NetAdapt for phone latency targets (Howard et al. 2019), MnasNet folds measured phone latency into its reward (Tan et al. 2019), and FBNet puts device-specific latency into a mobile-CPU search objective (Wu et al. 2019). NAS has also been applied to compact transformer models under compute or memory constraints. These results show what search found under particular spaces, objectives, and measurements, not that search universally beats careful manual design. When latency, memory, or energy enters the objective and is measured on the target platform, the search evaluates candidates against the resource deployment actually constrains, yet the transfer quality of the resulting architectures still depends on task and hardware. Reserve custom NAS for unusual constraints or deployment scales that can amortize the search and validation investment. Even a searched architecture, however, still executes the same fixed graph on every input, spending as much compute on a blank background frame as on a crowded street scene.
Howard, Andrew, Mark Sandler, Bo Chen, Weijun Wang, Liang-Chieh Chen, Mingxing Tan, Grace Chu, et al. 2019. “Searching for MobileNetV3.” 2019 IEEE/CVF International Conference on Computer Vision (ICCV), 1314–24. https://doi.org/10.1109/iccv.2019.00140.
Wu, Bichen, Kurt Keutzer, Xiaoliang Dai, Peizhao Zhang, Yanghan Wang, Fei Sun, Yiming Wu, Yuandong Tian, Peter Vajda, and Yangqing Jia. 2019. “FBNet: Hardware-Aware Efficient ConvNet Design via Differentiable Neural Architecture Search.” 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 10726–34. https://doi.org/10.1109/cvpr.2019.01099.
10.2.6 Adaptive computation methods
A static 24-layer transformer executes identical multiply-accumulate (MAC) operations and streams its entire parameter footprint from HBM or off-chip DRAM for an obvious, easily classified sample as it does for an ambiguous one. Because pruning, distillation, factorization, and architecture search all produce a fixed execution graph, every input follows the same scheduled path regardless of difficulty. Adaptive inference replaces this open-loop pipeline with an input-dependent control loop, in which intermediate representations or runtime budgets decide whether to terminate execution early or which specialized subnetwork receives the activations. While dynamic paths can reduce average arithmetic operations and memory traffic, they introduce runtime overheads in routing logic, batch management, confidence calibration, and latency variance. The camera pipeline is a natural candidate, because many frames are easy and the phone processes one frame at a time. Dynamic pruning applies the idea at the granularity of channels and filters; early exits, conditional layers, and expert subnetworks apply it at coarser grain, where the savings per decision are larger and so is the cost of a wrong one.
Dynamic pruning
Traditional pruning methods, whether unstructured or structured, produce a static pruning mask or subnetwork that remains fixed during deployment, even if the mask was learned gradually during training. Dynamic pruning instead decides at inference time, from each input, which computation is active, so the executed subnetwork changes from one input to the next.
Dynamic pruning can therefore allocate different amounts of work to different inputs and can use, for a hard input, capacity that a static deployment mask would remove permanently. Activation-conditioned pruning, for example, deactivates neurons or channels for particular inputs (Hu et al. 2023). On a simple image with mostly uniform regions, some convolutional filters produce negligible activations, and a dynamic policy can exclude them for that frame. The exclusion reduces nominal work, but the controller sits on the critical path, input-dependent routing fragments execution across SIMD vector lanes, and any quality change remains part of the result. Training may also need routing losses or regularization so that the policy actually uses its cheaper paths. Dynamic pruning is therefore a candidate when input complexity varies enough to repay the controller and batching overhead, not a default substitute for static pruning, and its gain must be measured as latency and accuracy together across the full input distribution.
Hu, Jie, Peng Lin, Huajun Zhang, Zining Lan, Wenxin Chen, Kailiang Xie, Siyun Chen, Hao Wang, and Sheng Chang. 2023. “A Dynamic Pruning Method on Multiple Sparse Structures in Deep Neural Networks.” IEEE Access 11: 38448–57. https://doi.org/10.1109/access.2023.3267469.
↪ Joint evaluation of compressed models on accuracy and target efficiency metrics such as latency, plotted as an efficiency-quality frontier, is measured in Compression validation: The efficiency-quality frontier.
Methods that change the mask during training are sometimes also called dynamic, but they solve a different problem. Gradual magnitude pruning progressively increases the fraction of pruned parameters while fine-tuning the survivors, which is the iterative schedule of section 10.2.1.5 run inside training, and dynamic sparse training additionally regrows connections that prove important later. Both end in a static mask for deployment, so this chapter reserves dynamic pruning for input-dependent execution.
Dynamic schemes
Because input samples vary widely in difficulty, spending the same compute budget on every input wastes memory bandwidth and execution cycles on simple cases. Dynamic schemes modulate execution paths to lower amortized computation while preserving the deep network for worst-case inputs. This architectural flexibility spans four primary control variables: network depth (early exit), structural routing (conditional layer skipping), expert subnetworks (mixture-of-experts), and continuous computational allocation.
To control execution depth, early exit architectures attach auxiliary classification heads to intermediate layers, terminating execution when intermediate representations yield sufficient prediction confidence (Teerapittayanon et al. 2017). BranchyNet implements this mechanism across convolutional backbones using shallow exit branches, whereas multi-exit vision transformers attach linear probes and entropy estimators between transformer blocks (Xin et al. 2021). When an input satisfies an exit criterion, such as softmax prediction entropy dropping below a pre-tuned threshold, the runtime halts evaluation and returns the intermediate prediction. The net operational benefit requires that the arithmetic operations and memory transfers avoided in subsequent layers exceed the computational overhead of evaluating the intermediate classifiers and gating thresholds.
Teerapittayanon, Surat, Bradley McDanel, and H. T. Kung. 2017. “BranchyNet: Fast Inference via Early Exiting from Deep Neural Networks.” 2016 23rd International Conference on Pattern Recognition (ICPR), 2464–69. https://doi.org/10.1109/icpr.2016.7900006.
Hu, Ting-Kuei, Tianlong Chen, Haotao Wang, and Zhangyang Wang. 2020. “Triple Wins: Boosting Accuracy, Robustness and Efficiency Together by Enabling Input-Adaptive Inference.” International Conference on Learning Representations (ICLR).
Chen, Yanxi, Xuchen Pan, Yaliang Li, Bolin Ding, and Jingren Zhou. 2024. “EE-LLM: Large-Scale Training and Inference of Early-Exit Large Language Models with 3D Parallelism.” Proceedings of the 41st International Conference on Machine Learning (ICML).
The systems trade-off diverges sharply across hardware deployment targets. On single-sample edge processors (batch size \(\BatchSize=1\), typical of microcontrollers and mobile NPUs), early exit immediately terminates the execution thread (Hu et al. 2020). Skipping remaining layers eliminates both the arithmetic operations and the off-chip DRAM transactions required to load subsequent layer weights into on-chip SRAM cache. Conversely, on parallel throughput accelerators (GPUs and TPUs) processing batched workloads (\(\BatchSize> 1\)), early exit introduces severe batch fragmentation (Chen et al. 2024). If only a subset of samples in a batch reaches the exit threshold, the remaining samples must still traverse deeper layers. Unless the runtime executes dynamic batch compaction (gathering unresolved activation tensors into a contiguous memory buffer through memory copies and kernel synchronizations), inactive samples remain allocated in memory, or the accelerator must mask inactive SIMD or single instruction, multiple threads (SIMT) lanes. Consequently, tail latency for the batch remains dictated by the deepest traversing sample. Along a transformer backbone, each block taps its intermediate representation into an auxiliary classifier and a learned confidence estimator (learning to exit, LTE) that can trigger an early exit, while unresolved inputs continue to deeper layers (figure 14).
↪ The latency-throughput trade-offs of batching under production request streams, including service-level objective (SLO) violations, are developed in Dynamic batching latency-throughput trade-offs.
Xin, Ji, Raphael Tang, Yaoliang Yu, and Jimmy Lin. 2021. “BERxiT: Early Exiting for BERT with Better Fine-Tuning and Extension to Regression.” In Proceedings of the 16th Conference of the European Chapter of the Association for Computational Linguistics: Main Volume, edited by Paola Merlo, Jorg Tiedemann, and Reut Tsarfaty. Association for Computational Linguistics. https://doi.org/10.18653/v1/2021.eacl-main.8.
Where early exit truncates depth along a single linear pipeline, conditional computation dynamically modulates the topological routing of activations through the network graph (Bengio et al. 2015). Instead of executing every block in a predefined sequence, gating functions evaluate activation tensors to bypass residual layers, alter operator kernels, or select specialized functional blocks. This converts a static directed acyclic graph (DAG) into an input-dependent dynamic graph.
Bengio, Emmanuel, Pierre-Luc Bacon, Joelle Pineau, and Doina Precup. 2015. “Conditional Computation in Neural Networks for Faster Models.” arXiv Preprint arXiv:1511.06297.
Wang, Xin, Fisher Yu, Zi-Yi Dou, Trevor Darrell, and Joseph E. Gonzalez. 2018. “SkipNet: Learning Dynamic Routing in Convolutional Networks.” In European Conference on Computer Vision (ECCV). Springer. https://doi.org/10.1007/978-3-030-01261-8_25.
SkipNet illustrates the pattern at the granularity of whole blocks. It uses lightweight recurrent or feedforward gating controllers to conditionally bypass residual blocks in convolutional networks, preserving full network depth only for computationally difficult inputs (Wang et al. 2018). From a hardware systems perspective, conditional routing achieves wall-clock speedups only when the cycles saved by bypassing operators surpass the latency of evaluating the gating network, executing host-device control synchronization, and managing uncoalesced memory accesses.
In a dense transformer, every token computes against every weight matrix, so parameter capacity and per-token compute grow together. The mixture-of-experts (MoE) architecture decouples them by replacing dense feedforward network (FFN) layers with a bank of parallel expert subnetworks coordinated by a parameterized router (Shazeer et al. 2017). Google’s Switch Transformer14 steers each token to a single expert (\(\RoutedExpertCount=1\)), which reduces communication overhead relative to routing to \(\RoutedExpertCount> 1\) experts (Fedus et al. 2022).
14 Switch Transformer: Fedus et al. (2022) scales to roughly 1.6 trillion total parameters while routing each token to one expert; in a compute-matched experiment, Switch-Base with 64 experts reached the T5-Base quality target in about one-seventh the training time; the trillion-parameter comparison reported roughly 4\(\times\) speedup over T5-XXL. Routing each token to one expert reduces communication relative to routing to \(\RoutedExpertCount> 1\) experts, but load imbalance requires auxiliary losses and capacity factors, which cap how many tokens each expert accepts per batch. This trade-off, massive parameter capacity at low per-token compute cost in exchange for complex load-balancing engineering, defines the MoE design space.
Fedus, William, Barret Zoph, and Noam Shazeer. 2022. “Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity.” Journal of Machine Learning Research 23 (120): 1–39.
Lepikhin, Dmitry, HyoukJoong Lee, Yuanzhong Xu, Dehao Chen, Orhan Firat, Yanping Huang, Maxim Krikun, Noam Shazeer, and Zhifeng Chen. 2021. “GShard: Scaling Giant Models with Conditional Computation and Automatic Sharding.” International Conference on Learning Representations (ICLR).
Sparse activation trades compute for memory. A token routed to one of \(\ExpertCount\) experts executes arithmetic against only \(1/\ExpertCount\) of the expert parameters, yet an all-resident deployment keeps all \(\ExpertCount\) expert matrices in device memory. In a Switch Transformer block, a Switching FFN layer sits inside the standard transformer stack, and its gating router dispatches individual tokens (“More” with \(\RouterGateProbability=0.65\), “Parameters” with \(\RouterGateProbability=0.8\)) to distinct expert sub-blocks (FFN 2 and FFN 1) while unselected experts stay idle (figure 15). Because the router lies on the critical path, the runtime must gather tokens assigned to the same expert into contiguous tiles (Lepikhin et al. 2021); at low batch sizes or under a skewed routing distribution, divergent routing leaves some experts with too few tokens to keep matrix units busy and overloads others, forcing the runtime either to truncate tokens or to launch kernels that leave lanes idle.
↪ How runtimes execute tensors whose shapes vary, by matching precompiled shape profiles, padding, splitting the batch, or falling back to a general kernel, is developed in Dynamic kernel execution.
Yang, Le, Yizeng Han, Xi Chen, Shiji Song, Jifeng Dai, and Gao Huang. 2020. “Resolution Adaptive Networks for Efficient Inference.” 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2366–75. https://doi.org/10.1109/cvpr42600.2020.00244.
Wu, Zuxuan, Tushar Nagarajan, Abhishek Kumar, Steven Rennie, Larry S. Davis, and Rogerio Feris. 2018. “BlockDrop: Dynamic Inference Paths in Residual Networks.” IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 8817–26. https://doi.org/10.1109/cvpr.2018.00919.
Early exit and MoE routing make discrete branch selections, but adaptive inference can also modulate depth or iteration counts continuously according to task difficulty (Yang et al. 2020). BlockDrop adjusts the number of active layers with a runtime policy network (Wu et al. 2018), and dynamic layer scaling adds computation until output uncertainty drops below a calibrated threshold. In an embedded vision system, high-contrast frames with clear road geometry resolve through a minimal prefix of layers, whereas degraded frames with occluded obstacles trigger deeper processing. The gain materializes only if the control evaluation remains computationally lightweight and the runtime schedules frames with matched execution depths concurrently to maintain high hardware utilization.
Implementation challenges
Realizing the efficiency gains of adaptive computation requires overcoming challenges across optimization, runtime orchestration, and hardware execution. During training, discrete routing decisions (such as non-differentiable \(\mathrm{argmax}\) branch selections) break standard gradient-based backpropagation. Practitioners overcome this with continuous relaxations such as the Gumbel-Softmax estimator, which replaces hard selections with smooth approximations so gradients flow, with policy gradients that reinforce routing choices that earn a reward, or with auxiliary load-balancing losses that keep routers from collapsing onto a single favored expert (Shazeer et al. 2017).
Shazeer, Noam, Azalia Mirhoseini, Krzysztof Maziarz, Andy Davis, Quoc Le, Geoffrey Hinton, and Jeff Dean. 2017. “Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer.” International Conference on Learning Representations (ICLR).
At runtime, control-flow branching conflicts with the lockstep execution of modern accelerators, where the threads of a warp execute the same instruction. When threads within a GPU warp take divergent branches, the hardware may serialize them and mask inactive threads, which erodes the theoretical FLOP savings. Gating also introduces control dependencies that can limit fusion, require token-permutation buffers, or trigger host-device synchronization. If these dispatch overheads exceed the compute time saved by skipping layers, the dynamic model has higher end-to-end latency than a dense baseline. Runtime strategies such as ragged batching and dynamic kernel launch queues manage these patterns, and they belong to the accelerator runtime rather than to the model.
Dynamic control also adds quality and security failure modes. Poorly calibrated gates underallocate computation to rare inputs, which degrades accuracy on safety-critical edge cases, and adversarial perturbations can push the gates toward truncated early exits or maximally deep paths. Evaluating adaptive models therefore cannot rely on average FLOP counts alone. Rigorous system profiling must report path distribution histograms, tail latency (p99), accuracy stratified by input difficulty, and throughput stability under dynamic batching, and a production deployment keeps monitoring route frequency and quality by route after launch.
↪ Infrastructure telemetry that tracks latency distributions in deployed systems, alongside the model-quality signals production monitoring pairs with it, is developed in Infrastructure telemetry and hardware utilization.
The structural techniques covered so far (pruning, low-rank factorization, distillation, efficient architecture design, NAS, and adaptive computation) all optimize what computations the model performs, including which parameters exist, which connections remain, how the architecture is structured, and which paths a given input executes. These techniques can substantially reduce parameter counts and theoretical FLOPs. Regardless of structural efficiency, every surviving weight and activation must still be stored and processed at some numerical precision.
Checkpoint 10.1: Choosing a structural method
Structural methods relocate deployment cost in different ways.
Structural optimizations alter what a model computes, but the surviving graph must still execute within the physical memory bandwidth, register files, and cache hierarchies of the target silicon. When structural pruning and distillation have carved away unnecessary parameters and layers, every remaining operation continues to incur a memory-movement and arithmetic cost determined entirely by its bit representation. Optimizing this numerical representation forms the second tier of the optimization stack, and its clearest case is a workload whose time is set by bytes rather than by arithmetic.
Self-Check: Question
A team prunes ResNet-50 to \(50\%\) sparsity using unstructured magnitude pruning and observes only a \(1.1\times\) speedup on a commodity GPU. Switching to structured channel pruning at the exact same \(50\%\) sparsity yields a \(1.8\times\) speedup. Which systems mechanism best explains this difference?
- Structured pruning removes more total weight parameters than unstructured pruning at any given nominal sparsity percentage
- Structured pruning removes entire contiguous channels or filters, allowing smaller dense kernels to execute efficiently, whereas unstructured sparsity needs sparse storage, metadata, and irregular activation access
- Unstructured magnitude pruning requires zero retraining or fine-tuning, whereas structured channel pruning requires full retraining from scratch
- Commodity GPU memory controllers automatically coalesce random non-zero memory addresses into single-cycle burst transfers
Order the stages of finding a winning lottery ticket in a neural network according to the Lottery Ticket Hypothesis (LTH): (1) Reset surviving weights to their original initialization values (\(W_0\)), (2) Train the dense unpruned network to convergence, (3) Retrain the sparse subnetwork to convergence, (4) Prune the lowest-magnitude weights to create a sparse mask.
A team must compress a large transformer model for deployment across a fleet of commodity GPUs that lack dedicated sparse-matrix acceleration kernels. Which structural optimization technique is the strongest candidate for producing a smaller model that still executes efficiently on this hardware?
- Unstructured magnitude pruning, because sparse matrix multiplication routines run with zero memory overhead on all standard GPUs
- Extreme binary weight quantization, because 1-bit representations eliminate all memory traffic without degrading language model perplexity
- Knowledge distillation, because it transfers teacher behavior into a compact dense student architecture that runs well on standard dense GPU kernels
- Low-rank factorization without fine-tuning, because mathematical decomposition guarantees zero loss in representation capacity
A square weight matrix of size \(4096 \times 4096\) in a transformer layer is decomposed using low-rank factorization at rank \(r = 128\). Calculate the theoretical reduction factor in both parameter count and multiply-accumulate (MAC) operations, and explain what trade-off this structural approximation introduces.
An engineering organization is deciding between running a custom Neural Architecture Search (NAS) from scratch versus adopting an established NAS-discovered family (such as MobileNetV3 or EfficientNet). Which circumstance most strongly justifies investing in custom NAS?
- Novel or custom hardware accelerators with unique memory hierarchies or massive production deployment scale where small per-inference efficiency gains amortize large one-time search costs
- Standard GPU clusters running established vision benchmarks where off-the-shelf architectures like MobileNetV3 already fit latency budgets
- Rapid prototyping projects with a total engineering timeline under one week and fewer than 10 available GPUs
- Small-scale enterprise applications processing fewer than 1,000 queries per day on cloud instances
Compare one-shot pruning with an iterative schedule that removes 10 percentage points of the original weights in each of 8 rounds with recovery between rounds. Explain why staged recovery can help, and what controlled comparison is needed before concluding that the iterative schedule is better.
10.3 Numerical Precision: Changing How Values Are Stored
GPT-2 XL decoding on the phone shows what structural changes leave untouched. Its FP16 weights fit in the phone’s memory, yet every generated token streams all 3 GB of them across a 51.2 GB/s bus, about 59 ms per token before any arithmetic (table 1). Pruning or factorizing its layers would change which weights exist; the complementary optimization leaves the network topology unaltered and reduces the bit width of every surviving tensor. Quantization trades numerical precision for a smaller memory footprint, higher cache utilization, and higher arithmetic throughput on hardware with integer datapaths.
Definition 10.4: Quantization
Quantization is a model-compression technique that reduces information fidelity by mapping high-precision continuous values to a lower-precision discrete set.
- Significance: FP32-to-INT8 conversion reduces the raw payload per quantized value by 4\(\times\). Real artifact size, traffic, and latency also depend on scales, metadata, packing, operator coverage, and the target kernels.
- Distinction: Unlike pruning, which reduces the count of parameters, quantization reduces the bit depth of selected weights and/or activations.
- Common pitfall: A frequent misconception is that quantization is just “rounding.” In reality, it is a lossy mapping that requires careful range estimation and, often, quantization-aware training (QAT) to minimize its impact on accuracy.
Quantization15 concerns every neural network weight and activation stored at some numerical precision: FP32 (32 bits), FP16 (16 bits), INT8 (8 bits), or lower. Bit width sets how many bytes each value occupies, how much cache it uses, and how fast specialized matrix engines can run.
15 Quantization: Rooted in Shannon’s theory of representing continuous signals with discrete values (Shannon 1948), reducing FP32 to INT8 collapses over four billion representable values to just 256. Neural networks often tolerate this because trained weights concentrate information in relative magnitudes, not absolute precision: INT8 inference can stay close to the full-precision baseline with appropriate calibration or quantization-aware training, while INT4 and lower-bit methods become more architecture- and method-dependent (Jacob et al. 2018; Gholami et al. 2022; Shen et al. 2020; Lin et al. 2024). The systems consequence is that quantization viability must be validated per-model and per-task, not assumed from aggregate benchmarks.
Shannon, Claude E. 1948. “A Mathematical Theory of Communication.” Bell System Technical Journal 27 (3): 379–423. https://doi.org/10.1002/j.1538-7305.1948.tb01338.x.
Jacob, Benoit, Skirmantas Kligys, Bo Chen, Menglong Zhu, Matthew Tang, Andrew Howard, Hartwig Adam, and Dmitry Kalenichenko. 2018. “Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2704–13. https://doi.org/10.1109/cvpr.2018.00286.
Gholami, Amir, Sehoon Kim, Zhen Dong, Zhewei Yao, Michael W. Mahoney, and Kurt Keutzer. 2022. “A Survey of Quantization Methods for Efficient Neural Network Inference.” In Low-Power Computer Vision: Improve the Efficiency of Artificial Intelligence. Chapman; Hall/CRC. https://doi.org/10.1201/9781003162810-13.
↪ How accelerators trade precision and dynamic range for matrix-engine throughput, pairing low-precision inputs with higher-precision accumulation, is developed in Numerics and sparsity on the datapath.
Gupta, Suyog, Ankur Agrawal, Kailash Gopalakrishnan, and Pritish Narayanan. 2015. “Deep Learning with Limited Numerical Precision.” International Conference on Machine Learning (ICML), 1737–46.
Wang, Yu Emma, Gu-Yeon Wei, and David Brooks. 2019. “Benchmarking TPU, GPU, and CPU Platforms for Deep Learning.” arXiv Preprint arXiv:1907.10701.
Quantization transforms three physical terms of execution. First, converting FP32 to INT8 reduces raw weight payload by 4\(\times\) before scale and packing metadata, allowing models to fit within constrained device memories. Second, when tensors remain packed across memory buses, memory traffic drops proportionally, directly reducing token latency in bandwidth-bound autoregressive decoding. Third, fixed-point integer arithmetic units occupy smaller silicon area and consume significantly less energy per operation than floating-point units, enabling higher compute density on supported hardware (Gupta et al. 2015; Wang et al. 2019).
The accuracy cost varies by model, task, quantizer, calibration data, and bit width. Many convolutional neural network (CNN) inference models tolerate INT8 well; transformers, speech models, and outlier-heavy layers may need different granularity, mixed precision, or training-aware methods. The main approaches are post-training quantization (PTQ), quantization-aware training (QAT), and mixed-precision or extreme quantization for lower-bit deployment. They differ in training cost and control, not in a guaranteed ordering of accuracy.
The viability of each approach depends on how much precision a given model architecture can shed before quality degrades. Across precision formats from FP32 down to INT2, both CNN and transformer curves follow a low-loss plateau where INT8 quantization closely matches full-precision performance, followed by a steep accuracy cliff at lower bit widths where representational capacity breaks down. Because tolerable accuracy degradation depends on end-to-end application constraints, engineering teams must evaluate these cliff boundaries for each target workload and range-calibration recipe (figure 16).
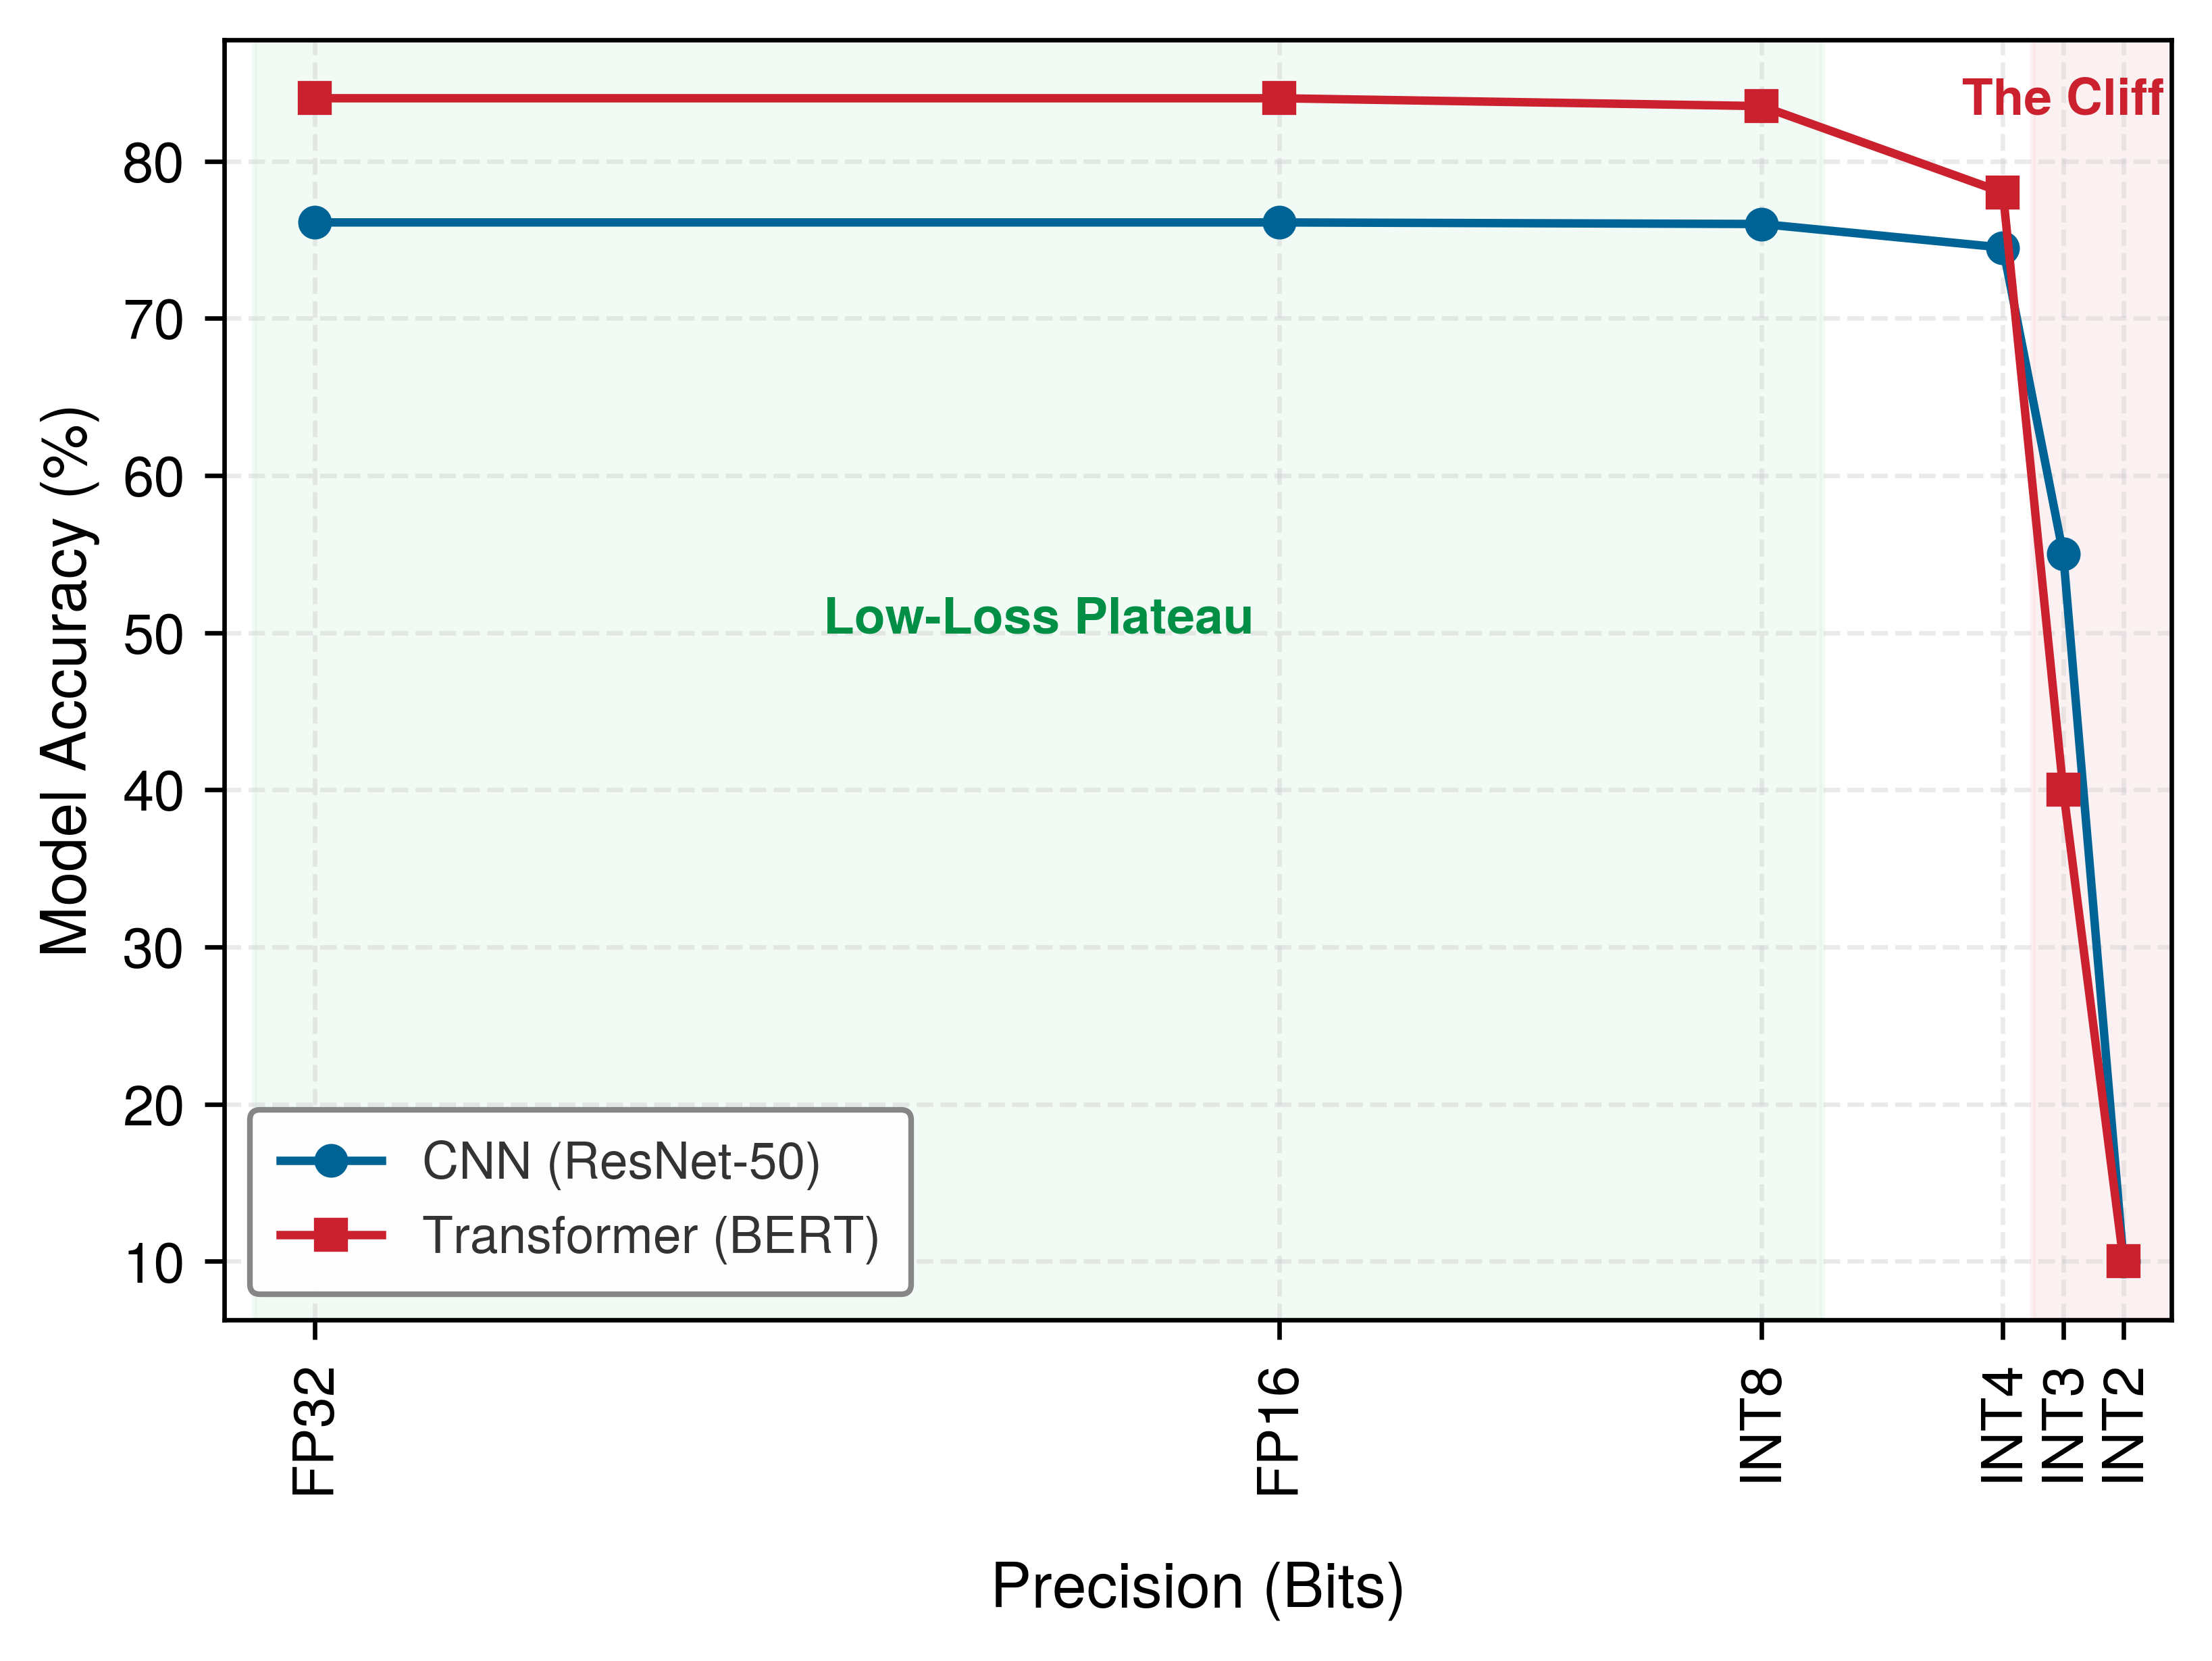
10.3.1 Numerical formats
Cutting a tensor from 32 bits to 16 or 8 bits can still overflow on large activation outliers if the format lacks exponent range, or stall in software unpacking if the target processor lacks a native datapath for that bit width. How a format divides its bits between exponent range and fraction precision decides which values survive conversion, and whether the silicon provides a matching execution unit decides whether narrower values run any faster. Because neither property follows from bit count alone, selecting a numerical format requires balancing dynamic range and hardware execution support against memory traffic rather than minimizing bit width blindly. The formats commonly deployed across accelerator architectures differ in raw storage, peak arithmetic rate, and hardware support, each measured against standard 32-bit floating point (FP32) (table 7).
| Precision Format | Bit-Width | Storage Reduction (vs. FP32) | Compute Speed (vs. FP32) | Power Effect | Use Cases |
|---|---|---|---|---|---|
| FP32 | 32-bit | Baseline (1\(\times\)) | Baseline (1\(\times\)) | Baseline | Training & inference (general-purpose) |
| FP16 | 16-bit | 2\(\times\) smaller | Up to 2\(\times\) peak on selected supported hardware | Hardware- and workload-dependent | Accelerated training, inference (NVIDIA Tensor Cores, TPUs) |
| BF16 (Brain Floating Point) | 16-bit | 2\(\times\) smaller | Hardware- and workload-dependent | Hardware- and workload-dependent | Training on TPUs, transformer-based models |
| TF32 (TensorFloat-32) | 19-bit | None (stored as FP32) | Up to 8\(\times\) peak on NVIDIA Ampere Tensor Cores | Hardware- and workload-dependent | Training on NVIDIA GPUs |
| FP8 (E4M3, E5M2) | 8-bit | 4\(\times\) smaller | 2× the dense FP16 peak on the H100 | Hardware- and workload-dependent | Inference and training on recent data-center accelerators |
| INT8 (8-bit Integer) | 8-bit | 4\(\times\) smaller | Hardware- and workload-dependent | Hardware- and workload-dependent | Quantized inference (Edge AI, mobile AI, NPUs) |
| INT4 (4-bit Integer) | 4-bit | 8\(\times\) smaller | Hardware- and workload-dependent | Hardware- and workload-dependent | Ultra-low-power AI, experimental quantization |
| Binary/Ternary (1-bit/2-bit) | 1–2-bit | 16–32\(\times\) smaller | Hardware- and workload-dependent | Hardware- and workload-dependent | Extreme efficiency (binary/ternary neural networks) |
At 16 bits, FP16 and BF16 halve memory storage relative to FP32 while targeting dedicated matrix execution units (such as NVIDIA Tensor Cores and Google TPUs) to accelerate arithmetic throughput. The range-versus-precision trade between them is established with mixed-precision training in Mixed-precision training, and figure 17 shows the bit layouts that set it. BF16 keeps FP32’s 8-bit exponent and therefore its dynamic range, whereas FP16 spends more bits on the fraction and caps finite values at 65,504, which is why FP16 training needs loss scaling and BF16 training does not. For inference, the same range limits decide whether activations with large outliers survive the narrower format. TensorFloat-32 (TF32) adopts a hybrid compromise. It retains the 8-bit exponent of FP32 and the 10-bit fraction of FP16, executing on Tensor Cores to accelerate matrix multiplication while storing values in standard 32-bit memory.
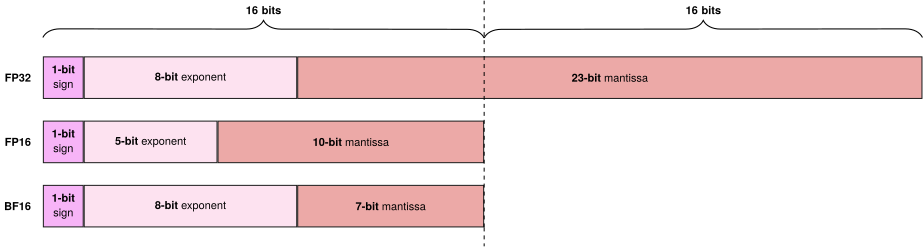
For inference workloads, INT8 precision provides a fourfold reduction in raw storage relative to FP32 when the chosen quantizer preserves acceptable prediction accuracy. Inference avoids the gradient backpropagation pass, eliminating the small-magnitude, high-dynamic-range updates that cause underflow during training. Activations and weights can still contain outliers or sensitive values, so range calibration or QAT must validate mapping them onto signed 8-bit integers (\([-128, 127]\)) using uniform affine or symmetric quantization scales. In bandwidth-limited inference regimes, such as autoregressive language model token generation, this \(4\times\) footprint reduction relieves memory bus contention by cutting DRAM and cache traffic. On compute-bound operators, dedicated INT8 vector and tensor units provide higher arithmetic operation density per clock cycle and per unit of silicon area than equivalent floating-point units.
FP8 gets its own row because it is the first 8-bit format that keeps an exponent. It comes in two layouts, each with one sign bit: E4M3, with four exponent and three mantissa bits, for weights and activations, and E5M2, with five exponent and two mantissa bits, for the wider range of gradients (Micikevicius et al. 2022). Like INT8, it halves the bytes of FP16, and on the reference H100 its peak matrix rate equals the INT8 rate, 2× the dense FP16 peak. Unlike INT8, it needs no zero-point, and its exponent absorbs the outliers that force an integer format to choose between clipping and resolution, so a model often converts to FP8 with less range-calibration effort than to INT8. FP8 as the default serving precision on such accelerators is developed in Model Serving. Microscaling formats carry the same idea below eight bits (Rouhani et al. 2023). A block of values, typically 32, shares one 8-bit power-of-two scale, so the elements of an MXFP8, MXFP6, or MXFP4 block borrow their range from the shared exponent and spend their few bits on precision. They are an awareness item here, because their payoff depends on accelerators with native support.
Micikevicius, Paulius, Dusan Stosic, Neil Burgess, Marius Cornea, Pradeep Dubey, Richard Grisenthwaite, Sangwon Ha, et al. 2022. “FP8 Formats for Deep Learning.” arXiv Preprint arXiv:2209.05433.
Rouhani, Bita Darvish, Ritchie Zhao, Ankit More, Mathew Hall, Alireza Khodamoradi, Summer Deng, Dhruv Choudhary, et al. 2023. “Microscaling Data Formats for Deep Learning.” arXiv Preprint arXiv:2310.10537.
Binary and ternary formats occupy the far end of table 7, constraining values to \(\{-1, +1\}\) or \(\{-1, 0, +1\}\) so that multiplication collapses into bitwise logic or a conditional add. They promise the largest storage ratio in the table, but byte-addressed memory and training stability make them a special case that section 10.3.4 develops in full. The keyword-spotting lighthouse shows why such formats are considered at all. Under the strict ~512 KB SRAM budget, INT8 is the baseline target, and INT4, binary, or ternary representations trade additional dynamic range to meet stricter memory and power bounds. Whereas table 7 counts bytes and peak rates, what each format saves in joules depends on where its bits travel, which is the subject of the energy comparison that follows.
10.3.2 Precision and energy
In silicon, energy dissipation scales directly with wire capacitance (\(\SwitchingEnergy\propto \SwitchedCapacitance \SupplyVoltage^2\)), so shuttling bits across long memory buses costs orders of magnitude more joules than toggling logic gates inside an arithmetic logic unit. Because physical data movement so often dominates a workload’s power budget, choosing a numerical precision is an energy decision governed by the number and location of memory accesses alongside the arithmetic performed. Reducing numerical precision directly shrinks the byte volume traversing the memory hierarchy (\(\DataVolume\)) and lowers the switching energy per ALU operation (\(\EnergyPerOperation\)), relaxing memory bandwidth and thermal bottlenecks across the hardware stack.
↪ Accelerator designs that keep operands in registers and on-chip SRAM, away from costly off-chip DRAM, are developed in Machine learning hardware specialization.
Where precision saves energy
Precision saves energy in two places, and the larger one is usually movement. The energy-movement principle (7), \(\EnergyPerByteMoved \gg \EnergyPerOperation\), says that moving an operand costs far more than operating on it (Horowitz 2014). In the reference technology model, a 32-bit read from off-chip DRAM costs about 640 pJ, roughly 2,100× the energy of the INT8 multiply-accumulate that consumes it, and the cost keeps rising as data leaves the chip for storage or the network (Energy Cost of Moving vs. Computing on a 32-Bit Value). A packed INT8 stream carries one quarter of the raw value bits of an FP32 stream, so each weight or activation that crosses the memory bus costs about a quarter of the movement energy, provided transactions stay full; caches, metadata, alignment, and transaction size set the realized saving. The reference measurements predate FP8, but an FP8 value moves the same eight bits as an INT8 value, so the movement saving applies to it unchanged.
Arithmetic supplies the second saving (table 8). An FP32 addition costs 0.9 pJ/op and an INT8 addition 0.03 pJ/op, a ratio of 30×; an FP32 multiply costs 3.7 pJ/op and an INT8 multiply 0.2 pJ/op, a ratio of 18.5×. Every multiply-accumulate a matrix unit performs combines the two, so the figure that governs a format decision is their combination. Because INT8 products accumulate in INT32, a full INT8 multiply-accumulate uses roughly 15× less energy than its FP32 equivalent, on top of the 4\(\times\) cut in bytes moved. Numbers to Know collects the reference energy ratios, and Numerical Representations compares numerical format trade-offs.
Horowitz, Mark. 2014. “1.1 Computing’s Energy Problem (and What We Can Do about It).” 2014 IEEE International Solid-State Circuits Conference Digest of Technical Papers (ISSCC), 10–14. https://doi.org/10.1109/isscc.2014.6757323.
| Operation | FP32 (pJ) | INT8 (pJ) | FP32 / INT8 |
|---|---|---|---|
| Add | 0.90 | 0.03 | 30× |
| Multiply | 3.70 | 0.20 | 18.5× |
| Multiply-accumulate | 4.60 | 0.30 | 15× |
Accelerators equipped with native low-precision units (such as NVIDIA Tensor Cores, Google TPUs, or mobile NPUs) compound these arithmetic savings with reduced memory traffic. In contrast, general-purpose processors lacking native low-precision execution pipelines lose much of this benefit to the runtime overhead of bit unpacking, format conversion, and scalar fallback. Precision is therefore a model-hardware decision, not a software configuration flag.
Which saving matters depends on where the workload sits. Under the iron law of ML systems (principle 3), reducing bit width changes the data-movement \((\DataVolume/\Bandwidth)\) and compute \((\Operations/(\PeakRate \cdot \EfficiencyHw))\) terms only through the execution path that uses the new representation. Workloads with little arithmetic per byte are memory bound, so shrinking data movement dominates; workloads with more arithmetic per byte are compute bound, so arithmetic savings matter more, a distinction the roofline model in The roofline model formalizes. Neither ratio predicts battery life on its own, because end-to-end energy also includes control, sensors, and idle power. When memory capacity binds, the more immediate benefit is placement, because smaller values may let the model reside in a memory tier that the uncompressed model cannot fit.

The machine’s memory capacity, not arithmetic, now sets the constraint.
Recommendation models convert the energy argument into a placement problem, in which quantization must shrink the dominant memory structures enough to reside in the host machine’s physical memory. When an embedding table outgrows a single accelerator’s HBM, reducing bytes per entry determines whether the table fits on the node at all.
Lighthouse 10.1: DLRM and embedding quantization
The DLRM lighthouse presents a compression challenge where memory capacity, rather than compute throughput or memory bandwidth, is the binding constraint (Naumov et al. 2019). Even the reference configuration in table 1 needs 100 GB of weights, more than one accelerator’s memory, and production embedding tables can grow to terabytes that must be sharded across many devices.
For DLRM, quantization targets storage density rather than arithmetic throughput. Reducing embedding-table precision from FP32 to INT8 (or lower) shrinks the memory footprint by 4–8\(\times\), allowing larger tables to fit on fewer GPUs when accuracy and lookup kernels tolerate the lower precision. Compressing the lookup tables ensures that physical device memory can accommodate the algorithmic model.
Naumov, Maxim, Dheevatsa Mudigere, Hao-Jun Michael Shi, Jianyu Huang, Narayanan Sundaraman, Jongsoo Park, Xiaodong Wang, et al. 2019. “Deep Learning Recommendation Model for Personalization and Recommendation Systems.” arXiv Preprint arXiv:1906.00091.
Lighthouse 10.2: Keyword spotting and the SRAM budget
The KWS lighthouse, DS-CNN, operates at the opposite extreme of the iron law from DLRM (Y. Zhang et al. 2017). Consider a deployment that keeps weights in roughly 512 KB of SRAM. Even the purpose-built DS-CNN keyword spotter overshoots that budget in FP32, where its weights occupy 800 KB. Quantized to INT8, its weights shrink to 200 KB, leaving space whose sufficiency must be checked against peak activation and runtime-buffer use. A device that reads weights directly from flash has a separate weight-storage budget; its SRAM feasibility still depends on the working set. A stricter smart-doorbell microcontroller with 256 KB SRAM leaves closer to 100 KB for model weights after runtime buffers, audio windows, and feature extraction state, motivating more aggressive INT4 or binary compression.
In FP32, even the compact DS-CNN architecture moves 4\(\times\) more raw weight bytes than in INT8, and the arithmetic path can also cost more on hardware with efficient integer units. For an always-on coin-cell device, that reduction contributes to longer battery life, but sensor, wake-up, feature-extraction, and idle-power costs may dominate. Here, quantization reduces the model’s data-movement term and can improve its compute term \((\Operations / (\PeakRate \cdot \EfficiencyHw))\) when the integer path is supported.
Zhang, Yundong, Naveen Suda, Liangzhen Lai, and Vikas Chandra. 2017. Hello Edge: Keyword Spotting on Microcontrollers.
Together, DLRM and the TinyML lighthouse (10.2) illustrate the two operational extremes of this memory constraint. DLRM uses lower precision to fit embedding tables that can reach terabytes into host memory; TinyML uses lower precision to keep every inference within a tiny energy envelope and a few hundred kilobytes of on-chip SRAM. Across both extremes, reducing numerical precision attacks physical execution costs on two fronts, arithmetic energy and latency in the ALU and byte traffic across the memory bus. Both savings assume that the low-precision values still represent the model faithfully, and producing such values is the job of the quantization methods.
10.3.3 Quantization methods
Casting trained FP32 weights and activations straight to narrow integers without fitting their range clips outlier channels and rounds small values to zero, so practical quantization methods differ in how much calibration or retraining they spend to keep that error small. Post-training quantization, quantization-aware training, and extreme low-bit formats differ chiefly in the training and validation cost they require. Representation choices, such as selecting INT8 versus INT4, mixing bit widths across sensitive layers, or choosing per-tensor versus per-channel ranges, are orthogonal options evaluated within these workflows rather than separate maturity levels. Ordered by the engineering effort each requires, the deployment sequence moves from fast post-training range calibration through quantization-aware retraining to custom low-bit pipelines (figure 18).
Post-training quantization is evaluated first, because it changes representations with minimal compute and pipeline overhead. When PTQ satisfies the application’s latency, energy, and quality thresholds, the optimization process stops. When post-training calibration introduces unacceptable accuracy degradation, quantization-aware training lets the weights adapt to discretization noise during backpropagation, and extreme sub-4-bit or ternary representations are reserved for targets that INT8 and INT4 cannot meet and whose hardware has kernels for them.
Post-training quantization
Retraining a large model checkpoint solely to adapt its weights to 8-bit arithmetic can cost hundreds of accelerator hours, and in many deployment pipelines the original training dataset or training cluster is not even available. Post-training quantization (PTQ) avoids that retraining loop altogether by converting weights and activation tensors from floating-point to fixed-point formats directly on a frozen checkpoint (Choukroun et al. 2019). Weight-only quantization requires only a single pass over static parameter tensors, while full integer quantization calibrates activation dynamic ranges using a small, unlabelled sample of representative inputs.
The principal constraint in PTQ is unmodeled discretization noise. Rounding introduces numerical error that cannot be compensated by gradient updates. While redundant architectures absorb 8-bit rounding noise with negligible accuracy loss, sensitive models or lower bit widths (such as INT4) experience degradation unless scaling granularities are refined or quantization-aware training is applied. Production runtimes such as TensorFlow Lite, Open Neural Network Exchange (ONNX) Runtime, and TensorRT provide automated calibration pipelines to profile tensor ranges and apply this conversion.
The core mechanism of PTQ is uniform quantization, which maps floating-point values to discrete integer levels using a consistent scaling factor. Because the interval between each quantized value is constant, uniform quantization simplifies implementation and enables efficient hardware execution. For the symmetric form shown here, \(\QuantizationScale\) is chosen from the maximum absolute value so that the resulting integers stay within the target range. The quantized value \(\QuantizedIntegerCode\) is computed as: \[ \QuantizedIntegerCode = \text{round} \left(\frac{\QuantizerInput}{\QuantizationScale} \right) \] where:
- \(\QuantizedIntegerCode\) is the quantized integer representation,
- \(\QuantizerInput\) is the original floating-point value,
- \(\QuantizationScale\) is a scaling factor that maps the floating-point range to the available integer range.
Uniform quantization from FP32 to INT8 reduces the raw value payload from 32 to 8 bits per weight at the cost of a measurable quantization error, with scale metadata and packing overhead excluded (listing 2). Once a model is quantized, the runtime can use integer arithmetic where supported (Gholami et al. 2022).
import torch

# Original FP32 weights
weights_fp32 = torch.tensor(
    [0.127, -0.084, 0.392, -0.203], dtype=torch.float32
)
print(f"Original FP32: {weights_fp32}")
print(f"Memory per weight: 32 bits")

# Simple uniform quantization to INT8 (-128 to 127)
# Step 1: Find scale factor
max_val = weights_fp32.abs().max()
scale = max_val / 127  # 127 is max positive INT8 value

# Step 2: Quantize using our formula x_q = round(x/s)
weights_int8 = torch.round(weights_fp32 / scale).to(torch.int8)
print(f"Quantized INT8: {weights_int8}")
print(f"Memory per weight: 8 bits (reduced from 32)")

# Step 3: Dequantize to verify
weights_dequantized = weights_int8.float() * scale
print(f"Dequantized: {weights_dequantized}")
print(
    f"Quantization error: "
    f"{(weights_fp32 - weights_dequantized).abs().mean():.6f}"
)
Rounding to a uniform grid introduces an error with a precise bound. A uniform quantizer maps each value to the nearest of evenly spaced levels separated by a step size \(\QuantizationScale\) (range calibration derives \(\QuantizationScale\) from the tensor’s clipping range in equation 1, later in this section). For any value inside the clipping range, rounding to the nearest level misses by at most half a step, so within-range error is bounded by \([-\QuantizationScale/2, \QuantizationScale/2]\). Aggregated across many tensors, most error concentrates inside that bound, while the tails carry the larger distortion that comes from saturation clipping and from mixing tensors that use different step sizes (figure 19). Many CNNs tolerate INT8 well, whereas large transformers often need outlier-aware or mixed-precision schemes because a few activation channels carry extreme values. Selecting the appropriate numerical precision therefore requires balancing accuracy constraints, hardware support, and efficiency gains.
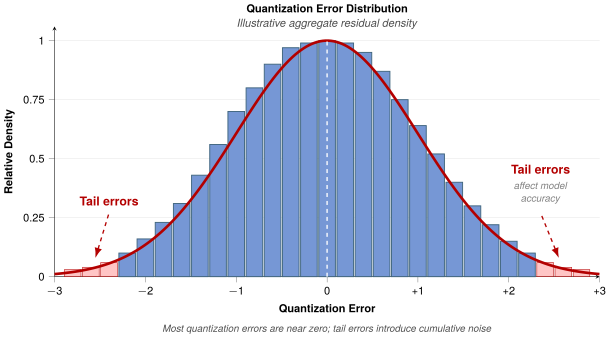
An alternative, nonuniform quantization, assigns finer-grained precision to numerical ranges that are more densely populated, which can preserve accuracy for models whose weight distributions concentrate around specific values. Nonuniform schemes require more complex calibration and are less common in production, but they can be effective for models particularly sensitive to precision changes. More generally, sensitivity to PTQ varies by architecture, layer, and distribution. When a uniform configuration misses the quality target, the next options include finer granularity, mixed precision, weight-only methods, better calibration, or QAT.
Range calibration
Mapping a tensor onto 8-bit or 4-bit integers with an ill-fitting range either saturates critical values through clipping or squanders available integer levels on sparse outliers. Quantization-range calibration prevents both failures by estimating the real-valued clipping range \([\ClippingRangeLowerBound, \ClippingRangeUpperBound]\) for each tensor (from here on, \(\ClippingRangeLowerBound\) and \(\ClippingRangeUpperBound\) denote its lower and upper bounds). Calibration minimizes representation error over the sampled distribution, although it does not guarantee bounds on out-of-distribution deployment inputs.
Because activation tensors vary with input data, profiling requires running an unlabelled calibration dataset through the forward pass to capture dynamic ranges. In the offline conversion pipeline, the pretrained model and a representative calibration dataset pass through a profiling stage that establishes dynamic ranges, and those ranges parameterize the quantization step that yields the final quantized model (figure 20). Layer by layer, activation observers record value distributions from which the scale and zero-point metadata are computed (algorithm 1). Range calibration in this sense is distinct from the confidence calibration that asks whether a model’s predicted probabilities match its observed accuracy, which returns in section 10.6.
The single calibration pass over \(\CalibrationDataset\) avoids retraining, and FP32-to-INT8 weight quantization cuts raw stored weight values by 4\(\times\) before scale, zero-point, and packing metadata. The price is that the static activation ranges fixed in the loop risk saturation or wasted integer levels when the calibration data misses deployment tails. The quantization step then converts model parameters to the lower-precision format, producing the final quantized model.
Mapping an unnecessarily wide real-valued interval to the 256 discrete bins of an 8-bit integer wastes numerical resolution on empty range, whereas clipping too aggressively truncates signal. Three calibration methods balance this clipping-versus-resolution trade-off: max sets bounds to the absolute extremum (preserving extreme values at the cost of vulnerability to outliers), entropy selects bounds by minimizing the Kullback–Leibler (KL) divergence between original and quantized distributions, and percentile retains a chosen fraction (such as 99.9 percent) and clips the remaining tail. In one ResNet-50 layer, the dense bulk of activations clusters below 1.1, while a sparse outlier tail stretching past 2.0 motivates testing a candidate clipping boundary near 1.1 to allocate more INT8 bins to the bulk (figure 21). Choosing a percentile boundary requires cumulative activation counts; the illustrated boundary is not assigned a percentile rank. Task validation must establish whether clipping that tail preserves important rare cases.
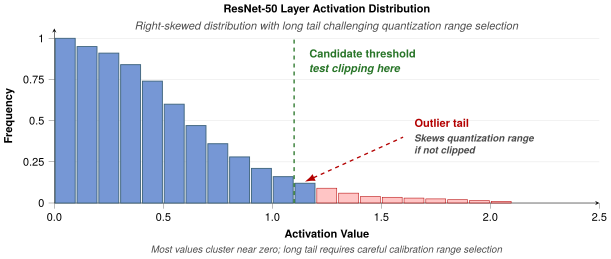
Tuning quantization ranges
Once calibration identifies clipping boundaries \([\ClippingRangeLowerBound, \ClippingRangeUpperBound]\), the range must be mapped onto integer endpoints, and two mapping schemes dominate (figure 22). A symmetric mapping uses a zero-centered range with zero-point zero, forcing real zero to integer zero by mapping \([-1, 1]\) directly onto \([-127, 127]\). An asymmetric mapping keeps one scale but a generally nonzero zero-point \(\QuantizationZeroPoint\), which accommodates skewed activation intervals such as \([-0.5, 1.5]\) across \([-128, 127]\).
Symmetric quantization simplifies integer matrix multiplication kernels because the zero-point is zero (\(\QuantizationZeroPoint= 0\)), eliminating cross-term additions during hardware accumulation. However, for activations following asymmetric distributions (such as post-ReLU feature maps where all values are non-negative), symmetric quantization wastes roughly half of the integer dynamic range on unused negative values. Asymmetric quantization recovers this dynamic range by mapping \([\ClippingRangeLowerBound, \ClippingRangeUpperBound]\) to \([0, 2^\QuantizationBitWidth- 1]\), but requires runtime hardware to compute offset corrections (\(\QuantizationZeroPoint\sum_k \QuantizedWeightEntry\) for output row \(\MatrixRowIndex\)) during multiply-accumulate operations. Either mapping is fully specified by two numbers per range, a scale and a zero-point, and the uniform quantizer introduced for PTQ is the special case whose zero-point is zero.
Napkin Math 10.1: Calculating scale and zero-point
The affine quantization formula: An affine map sends a floating-point range \([\ClippingRangeLowerBound, \ClippingRangeUpperBound]\) that includes zero to an integer range \([0, 2^\QuantizationBitWidth-1]\) (for example, UINT8) via the following construction.
Analysis: Affine quantization establishes a linear mapping \(\QuantizerInput\approx \QuantizationScale(\QuantizedIntegerCode - \QuantizationZeroPoint)\), where \(\QuantizationScale\) is the scale (step size) and \(\QuantizationZeroPoint\) is the zero-point (integer value corresponding to real zero). The mapping involves three computational steps:
Calculate scale \((\QuantizationScale)\): Divide the real range by the integer range using equation 1. \[\QuantizationScale= \frac{\ClippingRangeUpperBound- \ClippingRangeLowerBound}{2^\QuantizationBitWidth- 1} \tag{1}\]
Calculate zero-point \((\QuantizationZeroPoint)\): Shift the range so that real zero maps to an integer using equation 2. \[\QuantizationZeroPoint= \text{round}\left(\frac{-\ClippingRangeLowerBound}{\QuantizationScale}\right) \tag{2}\]
Quantize \((\QuantizerInput\to \QuantizedIntegerCode)\): Divide by the scale, add the zero-point, then round and clamp to the integer range using equation 3. \[\QuantizedIntegerCode = \text{clamp}\left(\text{round}\left(\frac{\QuantizerInput}{\QuantizationScale} + \QuantizationZeroPoint\right), 0, 2^\QuantizationBitWidth- 1\right) \tag{3}\]
Scenario: Consider quantizing a \(2 \times 2\) activation matrix with values ranging from \(\ClippingRangeLowerBound = -1\) to \(\ClippingRangeUpperBound = 3\), and the target precision is UINT8 \((\QuantizationBitWidth=8)\):
\[\mathbf{X} = \begin{pmatrix} -1 & 1 \\ 0 & 3 \end{pmatrix}\]
- Range: \(\ClippingRangeUpperBound - \ClippingRangeLowerBound = 4\).
- Steps: \(2^8 - 1\) = 255.
- Scale: \(\QuantizationScale = \frac{4}{255} \approx 0.0157\).
- Zero-point: \(\QuantizationZeroPoint = \text{round}(-(\ClippingRangeLowerBound)/\QuantizationScale) = \text{round}\!\left(-(-1)/\frac{4}{255}\right) = \text{round}(63.75) = 64\).
Applying equation 3 element-wise maps each floating-point entry to an integer bin:
\[\mathbf{X}_q = \begin{pmatrix} 0 & 128 \\ 64 & 255 \end{pmatrix}\]
Systems insight: The real value \(0.0\) is represented exactly by the integer 64. This is critical because it ensures that zero-padding (common in CNNs) is represented exactly, preventing “quantization drift” where padding introduces nonzero noise.
Granularity
In convolutional filters or transformer projection matrices, weight magnitudes often vary widely from one channel to the next, so sharing a single scale factor across an entire tensor can collapse small-magnitude channels to zero or clip wider channels. Quantization granularity governs how broadly scale factors and zero-points are shared across a tensor, balancing representation resolution against metadata overhead and kernel complexity: across convolutional channels (filters 1 through \(\LayerOutputWidth\)), a global layerwise threshold spans the widest distribution at the cost of resolution in narrower filters, whereas per-channel clipping boundaries adapt tightly to each filter’s dynamic range at the cost of tracking additional scale vectors during matrix multiplication (figure 23).
Quantization granularity trades calibration and metadata overhead against representation error. More local ranges can preserve information when channels differ, but they do not improve accuracy automatically and may lack an efficient kernel path. Each additional scale also has to be stored, loaded, and applied at the granularity supported by the backend. Four levels are common, from one shared layer range to local ranges within a filter (table 9).
| Level | Range sharing | Trade-off |
|---|---|---|
| Layerwise | One range per layer | Simple but suboptimal when filter ranges vary widely |
| Groupwise | Filters grouped with shared ranges | Used in Q-BERT (Shen et al. 2020) for transformer attention layers |
| Channelwise | One range per filter | Common default; balances quantization error against scale metadata and implementation overhead |
| Sub-channelwise | Ranges within each filter | More local ranges can reduce quantization error but increase metadata and implementation overhead |
Channelwise quantization preserves accuracy over layerwise quantization when channel dynamic ranges differ, at the cost of storing additional scale vectors and executing per-channel rescaling in the kernel pipeline. Beyond scale granularity, execution efficiency depends on the distinction between static weights and dynamic activations, which impose fundamentally different memory and latency constraints on the deployment system.
Weights vs. activations
Executing low-precision inference requires transforming floating-point inputs before kernel execution and requantizing intermediate accumulator outputs. During integer matrix multiplication, multiplying two 8-bit integers produces a 16-bit product. Summing these products across an inner dimension of length \(\GemmInnerDimension\) causes bit-growth that quickly overflows 8-bit registers; hardware therefore accumulates into 32-bit integer registers (INT32). Before feeding the result into subsequent layers, requantization rescales the 32-bit accumulated sum by the layer’s effective scale factor (\(\RequantizationScale= \frac{\WeightQuantizationScale \cdot \InputQuantizationScale}{\OutputQuantizationScale}\)) and clamps the values back into the 8-bit integer range. The full pipeline therefore has four stages (figure 24): quantizers convert floating-point activations and weights into INT8 operands, an integer core executes the matrix multiplication, a 32-bit accumulator holds the sum, and a requantization stage returns the result to INT8 before the nonlinear activation.
↪ How a single Tensor Core matrix instruction takes low-precision input tiles into higher-precision accumulator registers is developed in Tensor Cores.
Activation quantization maps layer outputs to a lower-precision representation during inference. It reduces intermediate payloads and can reduce arithmetic cost on hardware with an efficient integer path, but it also introduces error between layers. For example, a CNN may convert FP32 feature maps to INT8 before later convolutions. The benefit is greatest when consecutive operators remain on the integer path; isolated quantized operators may pay conversion cost without reducing enough work. Whether activation quantization improves latency therefore depends on supported kernels, scale handling, tensor lifetimes, and any quantize or dequantize boundaries that remain in the exported graph.
Static vs. dynamic quantization
The clipping range also depends on when activation ranges are computed, which divides activation quantization into two primary execution models: static quantization and dynamic quantization. In static quantization, the clipping range is precalculated during offline calibration and remains fixed during inference. This approach introduces zero runtime range-estimation overhead, because inputs are scaled by fixed factors and directly fed to integer execution units. However, static ranges risk saturation or underflow whenever production inputs deviate from the calibration distribution (Jacob et al. 2018; Yao et al. 2021).
Yao, Zhewei, Amir Gholami, Sheng Shen, Kurt Keutzer, and Michael W. Mahoney. 2021. “HAWQ-V3: Dyadic Neural Network Quantization.” Proceedings of the 38th International Conference on Machine Learning (ICML), 11875–86.
Dynamic quantization instead calculates scaling factors and zero-points dynamically from runtime activation tensors. Adapting the clipping window to each input reduces mismatch with a fixed calibration range. Outliers can still consume resolution, and a policy that clips tails can still saturate values. The trade-off is runtime memory and latency overhead, because the hardware must perform reduction passes over intermediate activation tensors to extract minimum and maximum values before integer arithmetic can begin. On memory-bandwidth-bound operators, this reduction pass can erode the execution advantage of lower precision.
Checkpoint 10.2: Calibration and range choices
Quantization succeeds only when the range policy matches deployment data and runtime constraints.
Range design
PTQ in practice
Post-training quantization balances deployment turnaround against accuracy control. PTQ requires no gradient backpropagation or retraining. Whether offline calibration is sufficient depends on the architecture, calibration data distribution, numerical quantizer design, and target hardware constraints.
The primary limitation is that PTQ freezes model parameters, preventing compensation for accuracy loss. When a quantized model falls below the production threshold, mitigations include recalibrating, refining scale granularity, adopting mixed precision, or escalating to quantization-aware training. QAT integrates precision constraints directly into the training graph using a straight-through estimator (STE) (section 10.3.3.2.1) to pass gradients through nondifferentiable rounding operators. This enables weights to adapt to low-bit representations during retraining, recovering accuracy at the cost of additional training compute (\(\TrainingCompute\)) and hyperparameter tuning.
Quantization-aware training
When post-training quantization drops a sensitive model or a 4-bit target below its accuracy floor because frozen weights cannot adjust to coarse rounding steps, only gradient updates can recover the lost quality. Quantization-aware training incorporates numerical rounding noise directly into the optimization graph, retraining or fine-tuning a quantized checkpoint on the training dataset so its parameters adapt to low-precision discretization error (figure 25).
Rather than training from scratch or cold-starting scale parameters, production workflows frequently initialize QAT using scale factors derived during an initial PTQ calibration pass. In this two-phase pipeline, a PTQ phase feeds calibration data into the pretrained model to establish initial scale metadata, and the resulting PTQ checkpoint enters a QAT phase in which the full training data drives fine-tuning (figure 26).
Training mathematics
During forward propagation, weights and activations are quantized and dequantized to mimic reduced precision. Let \(\QuantizerInput\) be a full-precision value, \(\QuantizationScale\) the scaling factor that maps floating-point values into a lower-precision range, and \(\FakeQuantizedOutput\) the simulated (quantized, then dequantized) value. Ignoring clipping and the zero-point for this simplified expression, the process is represented as: \[ \FakeQuantizedOutput= \text{round} \left(\frac{\QuantizerInput}{\QuantizationScale} \right) \times \QuantizationScale\]
Although the forward pass executes with simulated quantization, computing gradients requires backpropagating through the rounding operator \(\text{round}(\cdot)\). Because rounding is a piecewise-constant step function, its mathematical derivative is zero almost everywhere and undefined at step transitions, which would zero out gradients and halt gradient descent. The Straight-Through Estimator (STE) resolves this bottleneck by substituting the identity function for the rounding operator during backpropagation (Bengio et al. 2013).16
16 Straight-through estimator (STE): Proposed by Bengio et al. (2013), the common identity STE copies the upstream gradient through the quantizer unchanged. Because that identity is not the derivative of rounding, the estimate is biased, so QAT descends an approximation of the quantized model’s loss surface rather than the surface itself.
Bengio, Yoshua, Nicholas Léonard, and Aaron Courville. 2013. “Estimating or Propagating Gradients Through Stochastic Neurons for Conditional Computation.” arXiv Preprint arXiv:1308.3432.
Krishnamoorthi, Raghuraman. 2018. “Quantizing Deep Convolutional Networks for Efficient Inference: A Whitepaper.” arXiv Preprint arXiv:1806.08342 abs/1806.08342.
Integrating quantization effects during training lets the model adapt its weights and activation ranges to simulated low-precision error. QAT can recover quality that a post-training route loses, particularly at aggressive bit widths, but the advantage depends on the model, quantizer, calibration, and training procedure (Krishnamoorthi 2018).
Fake quantization nodes and implementation
QAT implementation relies on fake quantization operations that simulate quantization during forward propagation while maintaining full precision for gradient computation. These operations insert quantize-dequantize pairs into the computational graph, creating a training-time simulation of inference-time behavior.
A fake quantization node must preserve the same errors the inference runtime will see, so its three operations model the deployment path during training:
- Quantization: Map floating-point value to discrete quantization level
- Clipping: Enforce range constraints based on bit width
- Dequantization: Convert back to floating-point for subsequent operations
Mathematically, for symmetric quantization with bit width \(\QuantizationBitWidth\), given a floating-point input value \(\QuantizerInput\): \[ \begin{aligned} \QuantizedIntegerCode &= \text{clip}\left(\text{round}\left(\frac{\QuantizerInput}{\QuantizationScale}\right), -2^{\QuantizationBitWidth-1}, 2^{\QuantizationBitWidth-1} - 1\right) \\ \FakeQuantizedOutput&= \QuantizedIntegerCode \times \QuantizationScale\end{aligned} \] where \(\QuantizedIntegerCode\) is the quantized integer level, \(\QuantizationScale= \frac{\max(|\QuantizerInput|)}{2^{\QuantizationBitWidth-1} - 1}\) is the scale factor computed from the input distribution, and \(\FakeQuantizedOutput\) represents the fake-quantized output that mimics INT8 values but remains in floating-point format.
For asymmetric quantization supporting unsigned integers, the node applies the scale, zero-point, and quantize steps of equation 1, equation 2, and equation 3 to the observed range (extended to include zero) and then dequantizes: \[ \begin{aligned} \QuantizationScale&= \frac{\max(\QuantizerInput) - \min(\QuantizerInput)}{2^\QuantizationBitWidth- 1} \\ \QuantizationZeroPoint&= \text{round}\left(-\frac{\min(\QuantizerInput)}{\QuantizationScale}\right) \\ \QuantizedIntegerCode &= \text{clip}\left(\text{round}\left(\frac{\QuantizerInput}{\QuantizationScale} + \QuantizationZeroPoint\right), 0, 2^\QuantizationBitWidth- 1\right) \\ \FakeQuantizedOutput&= (\QuantizedIntegerCode - \QuantizationZeroPoint) \times \QuantizationScale\end{aligned} \] where \(\QuantizationZeroPoint\) is the zero-point offset enabling asymmetric range representation and the observed range \([\min(\QuantizerInput), \max(\QuantizerInput)]\) serves as the clipping range \([\ClippingRangeLowerBound, \ClippingRangeUpperBound]\).
In the QAT forward path, fake quantization is applied to inputs and weights before convolution, simulating INT8 numerics while retaining floating-point tensors for training (listing 3).
# Forward pass with fake quantization
def qat_conv_forward(x, weight):
    # Fake quantize input activations
    x_scale = compute_scale(x, bits=8, symmetric=False)
    x_zero = compute_zero_point(x, x_scale, bits=8)
    x_quant = fake_quantize(x, x_scale, x_zero, bits=8)

    # Fake quantize weights (typically symmetric)
    w_scale = compute_scale(weight, bits=8, symmetric=True)
    w_quant = fake_quantize(weight, w_scale, zero=0, bits=8)

    # Convolution with fake-quantized values
    output = conv2d(x_quant, w_quant)
    return output
During backpropagation, fake quantization nodes approximate gradients through a clipping-aware straight-through estimator: \[ \frac{\partial \FakeQuantizedOutput}{\partial \QuantizerInput} = \begin{cases} 1 & \text{if } \QuantizerInput\in [\ClippingRangeLowerBound, \ClippingRangeUpperBound] \\ 0 & \text{otherwise} \end{cases} \] Within the clipping range \([\ClippingRangeLowerBound, \ClippingRangeUpperBound]\), the estimator treats quantization as an identity mapping, passing the upstream gradient \(\frac{\partial \LossFunction}{\partial \FakeQuantizedOutput}\) unchanged to master weight \(\QuantizerInput\). Beyond clipping boundaries, the derivative evaluates to zero, blocking gradients from saturated outliers that would otherwise destabilize optimizer updates.
In practice, frameworks like PyTorch and TensorFlow implement fake quantization as custom autograd operators whose forward pass performs the quantize-dequantize round trip while the backward pass applies an STE. Scale handling depends on the method, since observers may track distributions and later freeze, or scales may be learned. Batch normalization also requires deployment-consistent handling. Workflows freeze batch-normalization statistics and fold them into the preceding convolution before export (section 10.4.1). Freezing running statistics before export allows fake-quantization scales to match the static fused parameters executed during inference.
QAT trade-offs
QAT’s17 primary advantage is additional control over quality at low precision. By incorporating simulated quantization noise during training or fine-tuning, the model can adapt to the deployed numerical path. Processors with dedicated integer units can then exploit INT8 arithmetic for faster or lower-energy inference when the exported operators are supported (Wu et al. 2020; Gholami et al. 2022). The benefit must be measured against PTQ for the same model and target, including the extra training cost and any difference in calibration, graph coverage, or kernel selection.
17 Quantization-aware training (QAT): QAT simulates low-precision behavior during training or fine-tuning so weight updates can adapt to clipping and rounding error. BERT studies report that training-aware or Hessian-aware methods can remain closer to full-precision General Language Understanding Evaluation (GLUE) baselines than simpler post-training routes in their evaluated settings (Zafrir et al. 2019; Shen et al. 2020). The exact gap depends on model, task, quantizer, bit width, training budget, and evaluation distribution; a closer benchmark result is evidence for trying QAT, not a guarantee that its added training cost or exported runtime will meet a production target.
Zafrir, Ofir, Guy Boudoukh, Peter Izsak, and Moshe Wasserblat. 2019. “Q8BERT: Quantized 8Bit BERT.” 2019 Fifth Workshop on Energy Efficient Machine Learning and Cognitive Computing - NeurIPS Edition (EMC2-NIPS), 36–39. https://doi.org/10.1109/emc2-nips53020.2019.00016.
Shen, Sheng, Zhen Dong, Jiayu Ye, Linjian Ma, Zhewei Yao, Amir Gholami, Michael W. Mahoney, and Kurt Keutzer. 2020. “Q-BERT: Hessian Based Ultra Low Precision Quantization of BERT.” Proceedings of the AAAI Conference on Artificial Intelligence 34 (05): 8815–21. https://doi.org/10.1609/aaai.v34i05.6409.
Wu, Hao, Patrick Judd, Xiaojie Zhang, Mikhail Isaev, and Paulius Micikevicius. 2020. “Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation.” arXiv Preprint arXiv:2004.09602 abs/2004.09602.
Choukroun, Yoni, Eli Kravchik, Fan Yang, and Pavel Kisilev. 2019. “Low-Bit Quantization of Neural Networks for Efficient Inference.” 2019 IEEE/CVF International Conference on Computer Vision Workshop (ICCVW), 3009–18. https://doi.org/10.1109/iccvw.2019.00363.
The cost is additional engineering complexity. QAT inserts simulated quantization into training, so teams must validate quantization schemes, scale behavior, and accuracy recovery on the target model. For very large models whose training budgets are already constrained, that overhead can make QAT impractical, and post-training routes avoid retraining altogether (Choukroun et al. 2019). QAT is therefore warranted only when the exported PTQ model misses its quality or deployment targets and training resources permit. A hybrid approach, starting with PTQ calibration and applying QAT fine-tuning only to accuracy-critical layers, often provides a useful balance.
The choice among PTQ, QAT, and dynamic quantization comes down to engineering budget, accuracy threshold, and input variability (table 10). Dynamic range computation is a timing choice orthogonal to PTQ versus QAT (dynamic PTQ is common), but it belongs in the comparison because it answers the third of those questions.
| Method | Engineering effort | Accuracy preservation | Input adaptability | Reach for it when |
|---|---|---|---|---|
| Static PTQ | Low: no retraining | Model-dependent; parameters do not adapt | Fixed calibration range | a calibrated model meets the measured accuracy and performance targets |
| Static QAT | High: additional training with quantization simulation | Often stronger when PTQ falls short | Fixed calibration range | PTQ misses the accuracy target and the training budget allows |
| Dynamic quantization | Moderate: ranges recomputed at runtime | Model-dependent; range fits each input | Per-input range | activation ranges vary widely across inputs and runtime overhead is acceptable |
PTQ serves as the low-effort baseline; QAT spends training cycles when PTQ degrades task accuracy, while dynamic quantization expends runtime memory traffic and compute to track input-dependent dynamic ranges. In practice, PTQ and QAT commonly target 8-bit or 4-bit precision, where retained accuracy depends on the model, task, and quantizer. Some deployment scenarios, however, demand even more aggressive compression, pushing precision to the absolute limits of what neural networks can tolerate.
10.3.4 Extreme quantization
On a microcontroller whose runtime buffers and audio feature extraction leave barely 100 KB of SRAM for weights, or on an energy-harvesting sensor whose power envelope cannot afford hardware multipliers, even 8-bit and 4-bit integers exceed the deployment budget. Extreme quantization pushes numerical precision down to 1 or 2 bits per value for those targets (Courbariaux et al. 2015; Zhu et al. 2017). Binarization constrains weights and activations to two values, typically encoded as \(\{-1, +1\}\). In digital logic, mapping \(-1\) to binary \(0\) and \(+1\) to binary \(1\) renders scalar multiplication isomorphic to the bitwise XNOR operation, replacing floating-point or integer MAC units with bitwise logic and population count (popcount) instructions (Rastegari et al. 2016). Because a 64-bit register packs 64 binary values, a single 64-bit XNOR instruction computes 64 binary products in parallel and a hardware popcount instruction counts the matching bits to accumulate the dot product (\(2 \times \text{popcount}(\BinaryWeightVector\text{ XNOR } \BinaryActivationVector) - 64\)), eliminating hardware multipliers altogether. That efficiency comes at a steep cost in expressiveness, since 1-bit representations degrade accuracy sharply on complex perceptual and language tasks (Hubara et al. 2018).
Courbariaux, Matthieu, Yoshua Bengio, and Jean-Pierre David. 2015. “BinaryConnect: Training Deep Neural Networks with Binary Weights During Propagations.” Advances in Neural Information Processing Systems (NeurIPS) 28: 3123–31.
Ternarization mitigates this capacity loss by allowing three values: \(\{-1, 0, +1\}\) (Zhu et al. 2017). The zero state introduces sparsity and simplifies arithmetic. Multiplying an activation by \(+1\) requires an addition, multiplying by \(-1\) requires a subtraction, and multiplying by \(0\) is skipped entirely. This eliminates general-purpose multipliers, reducing the arithmetic unit to a conditional adder-subtractor accumulator. However, ternary values cannot be packed at one bit per value. They require at least two bits per weight in standard byte-aligned memory (wasting one of four possible 2-bit states) or multi-trit encoding (such as packing five trits into a single byte, since \(3^5 = 243 < 256\)) that introduces runtime decoding overhead. The arithmetic gains of multiplier-free execution must outweigh the instruction overhead required to decode and unpack the weights on the target architecture.
Both binary and ternary quantization introduce step functions whose derivative is zero almost everywhere (\(\frac{\DerivativeOperator}{d\QuantizerInput}\text{sign}(\QuantizerInput) = 0\) for \(\QuantizerInput\neq 0\)), causing backpropagation gradients to vanish. To train these representations, quantization-aware training again relies on the straight-through estimator (Bengio et al. 2013; Choi et al. 2018) of section 10.3.3.2.1, whose gradients reach full-precision latent weights that accumulate small optimizer steps until they cross the quantization thresholds.
Choi, Jungwook, Zhuo Wang, Swagath Venkataramani, Pierce I-Jen Chuang, Vijayalakshmi Srinivasan, and Kailash Gopalakrishnan. 2018. “PACT: Parameterized Clipping Activation for Quantized Neural Networks.” arXiv Preprint.
Challenges and limitations
Translating sub-byte precision into actual wall-clock speedups is constrained by standard processor architectures. Native support for binary or two-bit matrix operations varies across processors and kernel libraries. On a target without a matching sub-byte path, executing these representations requires bit-shifting, masking, or unpacking routines. The instruction overhead of this bit manipulation frequently offsets memory-bandwidth savings unless workloads run on custom bit-serial accelerators, field-programmable gate arrays (FPGAs), or specialized hardware with native bitwise execution units (Umuroglu et al. 2017).
Umuroglu, Yaman, Nicholas J. Fraser, Giulio Gambardella, Michaela Blott, Philip Leong, Magnus Jahre, and Kees Vissers. 2017. “Finn: A Framework for Fast, Scalable Binarized Neural Network Inference.” Proceedings of the 2017 ACM/SIGDA International Symposium on Field-Programmable Gate Arrays, 65–74. https://doi.org/10.1145/3020078.3021744.
Rastegari, Mohammad, Vicente Ordonez, Joseph Redmon, and Ali Farhadi. 2016. “XNOR-Net: ImageNet Classification Using Binary Convolutional Neural Networks.” In European Conference on Computer Vision (ECCV). Springer. https://doi.org/10.1007/978-3-319-46493-0_32.
Hubara, Itay, Matthieu Courbariaux, Daniel Soudry, Ran El-Yaniv, and Yoshua Bengio. 2018. “Quantized Neural Networks: Training Neural Networks with Low Precision Weights and Activations.” Journal of Machine Learning Research 18 (187): 1–30.
Zhu, Chenzhuo, Song Han, Huizi Mao, and William J. Dally. 2017. “Trained Ternary Quantization.” International Conference on Learning Representations (ICLR) 4 (4): 1–16.
Model quality is the second barrier. Extreme quantization sharply reduces the representational capacity of a network. While low-entropy workloads such as KWS on a microcontroller SRAM budget may tolerate binary or ternary weights, complex perceptual and generative models suffer steep accuracy degradation. Binary and ternary quantization become viable candidates only when higher-precision alternatives such as INT8 or INT4 fail to satisfy physical memory or energy budgets, and when the deployment hardware can execute bit-packed operations natively (Rastegari et al. 2016; Hubara et al. 2018; Zhu et al. 2017; Umuroglu et al. 2017). Production deployment requires evaluating binary and ternary baselines against INT8, INT4, structured pruning, and compact architectural redesigns on the identical workload, measuring total binary artifact size, end-to-end latency, energy per inference, and task accuracy on target hardware. Whether a narrower format actually runs faster is the last question the precision tier must answer.
10.3.5 When fewer bits run faster
Shrinking weights from 16 bits to 8 bits fails to speed up a compute-bound matrix multiplication if the processor lacks a faster 8-bit datapath, just as faster integer ALUs fail to speed up autoregressive decoding when latency is stalled on memory-bus transfers. Every byte that quantization removes is a byte the memory system no longer moves, so whether a quantized model runs faster depends on which hardware resource binds: a compute-bound matrix multiplication speeds up only when the hardware provides a higher-throughput datapath for the narrower format, whereas a bandwidth-bound decode speeds up in proportion to the bytes removed from each token’s traffic. The worked examples below bracket the payoff, first on the reference H100 for a compute-bound layer and then on the running case’s phone for GPT-2 XL decoding.
Napkin Math 10.2: The quantization speedup (compute bound)
Problem: A compute-bound matrix multiplication (for example, in a transformer multilayer perceptron block at a large batch) switches from FP16 to INT8 on the reference H100. What throughput speedup can the integer matrix units deliver?
Math: On hardware with dedicated INT8 units:
- Integer throughput path: The H100 rates its INT8 matrix path at 1979 TOPS against 989 TFLOP/s on the dense FP16 path (NVIDIA Corporation 2022; Choquette 2023). The peak throughput increase is that spec ratio, about 2×.
- Memory bandwidth: Packed INT8 weights carry half the raw weight bytes of FP16. Their streaming time can approach half at the same achieved bandwidth, before metadata and conversion costs.
- Combined effect: For compute-bound operations, the ideal throughput factor is about 2× at comparable utilization of the two arithmetic paths.
Systems insight: The speedup from quantization depends on the bottleneck. Compute-bound operations (large batch sizes, high arithmetic intensity \(\ArithmeticIntensity\)) can approach about 2× at comparable utilization of supported INT8 units, where the gain comes from the integer matrix path rather than reduced memory traffic. The bandwidth-bound case inverts this. Halving the bytes moved (FP16 to INT8) yields up to 2×, and larger bit-width reductions scale the gain further, as the decode example below traces.
Choquette, Jack. 2023. “NVIDIA Hopper H100 GPU: Scaling Performance.” IEEE Micro 43 (3): 9–17. https://doi.org/10.1109/mm.2023.3256796.
NVIDIA Corporation. 2022. NVIDIA H100 Tensor Core GPU Architecture. NVIDIA Corporation.
Processors without dedicated matrix units see the same compute-bound effect through data-level parallelism in their registers, the path a phone’s CPU takes before a model moves to its integer accelerator. Fixed-width vector execution units (SIMD) and systolic arrays process more operands per cycle when each operand occupies fewer bits.
Napkin Math 10.3: The SIMD multiplier
Problem: A compute-bound layer executes using INT8 rather than FP32 on the same processor. Determine the architectural source of arithmetic speedup under fixed register width.
Mechanism: SIMD execution. A CPU or GPU core processes data in fixed-width vector registers (for example, AVX-512 is 512 bits wide).
Math:
- Register width: 512 bits.
- FP32 capacity: 512/32 = 16 elements per vector instruction.
- INT8 capacity: 512/8 = 64 elements per vector instruction.
Result: Switching to INT8 packs 4× more elements into the same register. \(\text{Throughput Gain} = \text{INT8 elements/inst} / \text{FP32 elements/inst}\) = 64/16 = 4×
Systems insight: The packing ratio gives an ideal 4× throughput factor, assuming comparable vector-instruction throughput, occupied lanes, and supported operators. It is a candidate bound for compute-bound layers, not a measured layer speedup; memory traffic and conversion overhead still affect execution.
When an operation is bandwidth bound, speedup tracks the reduction in bytes transferred per token rather than peak arithmetic throughput. In autoregressive token generation with small batch sizes, memory bus traffic dominates latency.
Napkin Math 10.4: The quantization speedup (bandwidth bound)
Problem: The running case’s phone decodes GPT-2 XL (1.5B parameters) at batch size one with a full 1,024-token context. Its memory bus delivers 51.2 GB/s, and each token must read every weight and the whole KV cache. How much faster does decoding run with INT4 weights than with FP16 weights?
Math (FP16 weights):
- Weights: 3 GB at two bytes per parameter.
- KV cache: Keys and values across 48 layers, 25 heads, and 64 dimensions per head, stored in FP16 for 1,024 tokens, occupy 0.31 GB.
- Total per token: 3.3 GB, which fits the phone’s 8 GB but takes 65 ms to stream, or about 15 tokens/s.
Fix (INT4 weights):
- Weights: 0.75 GB at half a byte per parameter, for 1.06 GB per token with the unchanged FP16 KV cache.
- Speed: Streaming that total takes 21 ms, or about 48 tokens/s.
Systems insight: INT4 weights yield a 3.1× speedup in this traffic model, below the 4\(\times\) weight reduction because the FP16 KV-cache traffic is unchanged. The model already fit in memory at FP16; quantization bought speed, not feasibility. The realized speedup still depends on a kernel that unpacks INT4 weights inside the matrix multiplication rather than in a separate pass.
Across three vision networks (Inception v3, MobileNet v1, and ResNet v2), INT8 conversion contracts weight storage by exactly \(4\times\) (135 MB to 33.75 MB for the illustrative Inception bar), while the latency change varies with the architecture and its kernels (figure 27).
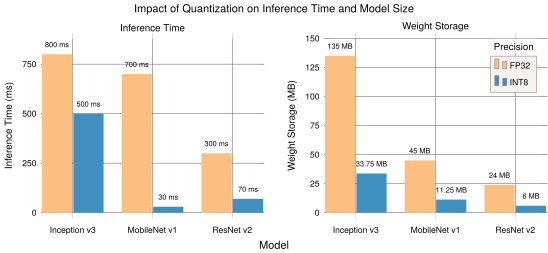
Quantization speedup depends on whether memory bandwidth or compute throughput is binding.
18 Activation-aware weight quantization (AWQ): Salience is determined by activation magnitude, not weight magnitude, a distinction that matters because a small weight multiplied by a large activation produces a large output contribution. AWQ protects about 1 percent of salient weight channels through activation-aware scaling while quantizing most weights to low-bit formats, so GPT-2 XL’s 3 GB of FP16 weights can move toward an INT4-class footprint of about 0.75 GB before metadata, scales, and kernel-specific packing overheads (Lin et al. 2024).
Lin, Ji, Jiaming Tang, Haotian Tang, Shang Yang, Wei-Ming Chen, Wei-Chen Wang, Guangxuan Xiao, Xingyu Dang, Chuang Gan, and Song Han. 2024. “AWQ: Activation-Aware Weight Quantization for on-Device LLM Compression and Acceleration.” Proceedings of Machine Learning and Systems 6: 87–100.
Activation-aware methods such as activation-aware weight quantization (AWQ)18 target weight traffic in large language model (LLM) inference. This approach serves exactly the regime of GPT-2 XL decoding on the phone, where loading model weights limits the token rate. By protecting a small fraction of salient weight channels based on activation magnitude, AWQ supports INT4-class weight quantization while controlling task degradation. Packed low-bit weights can reduce the memory traffic required during token generation when the runtime provides a matching kernel (Lin et al. 2024).
Checkpoint 10.3: Quantization and precision checkpoint
Quantization design review criteria:
These speedups are bounds computed from bytes and peak rates. Whether a deployed model reaches them depends on how its compressed operations are lowered onto kernels, which is the third tier of the stack.
Self-Check: Question
According to the chapter’s Horowitz energy constants, an INT8 integer addition consumes roughly \(0.03\text{ pJ}\) compared to \(0.90\text{ pJ}\) for an FP32 addition—a \(30\times\) energy reduction despite only a \(4\times\) reduction in bit-width. What explains this operation-level energy dividend?
- INT8 arithmetic eliminates the need for registers and ALU logic on the silicon die
- INT8 quantization automatically prunes zero-valued parameters before they reach the execution units
- The 8-bit integer adder circuit requires significantly fewer logic gates, capacitance, and switching energy per operation than a 32-bit floating-point adder with exponent alignment and normalization logic
- Floating-point operations require continuous synchronization with host CPU DRAM on every instruction
In affine (asymmetric) quantization, the integer parameter ____ shifts the quantized grid so that real-valued zero maps exactly to an integer representation, ensuring that zero-padded tensor regions introduce no numerical bias.
Order the stages of a standard post-training quantization workflow with static activation calibration: (1) quantize the finalized weights and export the deployment artifact, (2) run representative floating-point calibration inputs through the model and collect activation statistics, (3) choose activation clipping bounds from the collected statistics, (4) derive activation scales and zero-points from those chosen bounds.
Compare two validation settings for low-bit quantization: (1) candidate INT4 weight-only quantization for autoregressive decoding when profiling shows weight traffic dominates, and (2) candidate low-bit quantization for large-batch training of the same model. Explain why these two settings require different validation conditions before concluding the quantization is worthwhile.
During post-training quantization of a convolutional network, activation profiling reveals that values are heavily concentrated near zero with a small set of extreme positive outliers. Which calibration strategy best preserves numerical resolution for the bulk of typical activations?
- Max-absolute-value calibration, because extending the quantization grid to include extreme outliers guarantees zero clipping error across all layers
- Uncalibrated uniform quantization, because activation distributions in neural networks always follow a perfectly uniform probability density
- Static symmetric quantization with range [-128, +127] mapped unconditionally to [-1.0, +1.0] across every layer
- Percentile or KL-divergence (entropy) calibration, which can clip extreme tails so more integer levels represent the dense bulk of activations
A team quantizing a deep convolutional network finds that per-channel (filter-wise) quantization achieves significantly higher accuracy than per-tensor (layer-wise) quantization at the same INT8 bit-width. Which mechanism explains this accuracy advantage?
- Per-channel quantization eliminates the need to compute or store scale factors and zero-points
- Individual convolutional filters within a layer often exhibit drastically different weight magnitude ranges; per-channel quantization assigns an independent scale factor to each filter, preventing wide-range filters from degrading the precision of narrow-range filters
- Per-tensor quantization can only be executed on CPUs, whereas per-channel quantization is restricted to edge microcontrollers
- Per-channel quantization automatically converts float operations into sparse matrix multiplications
10.4 Hardware Implementation: Changing How the Model Executes
Pruning a model structurally to half its weights and quantizing the survivors from FP32 to INT8 cuts stored weight bytes by 2× and 4×, or 8× in all, yet in production such a model can easily run only 1.5× faster—roughly 18.8 percent of the paper projection. Profiling reveals where the missing speedup vanishes: sparse tensors continue to stream through dense kernels that cannot skip unindexed zeros, reduced-precision operators trigger unfused type conversions that flood the memory bus, and small layers spend more time launching kernels and moving intermediates than doing arithmetic. Paper metrics—parameter counts, theoretical FLOPs, and nominal bit depths—establish upper bounds that hold only when a workload is limited purely by weight traffic and every kernel exploits the new representation. Bridging the divide between paper reduction and measured hardware speedup is the job of the third tier of the stack, efficient hardware implementation.
The measured bottleneck selects the implementation technique. Kernel fusion consolidates memory-bound operator chains, custom dequantization loops keep packed low-precision weights inside cache, and hardware sparsity engines align with tensor layouts to bypass zeroed arithmetic.
10.4.1 Compression-specific fusion
In the camera pipeline’s MobileNetV2, every inverted residual block chains a convolution, a batch normalization, and a rectified linear unit (ReLU); executed as separate kernels, each operator writes its output to accelerator global memory and the next reads that output back, paying three memory round-trips for work that could stay in on-chip registers. Kernel fusion (or operator fusion) eliminates those redundant memory transactions by combining adjacent operators into a single kernel (Chen et al. 2018; NVIDIA 2024), and model compression introduces fusion requirements of its own. Folding batch normalization into a pruned convolution, keeping a dequantize step inside the matrix-multiplication kernel that consumes it, and choosing which adjacent operators of a rewritten graph can share one kernel are all fusion decisions that arise once the graph has been compressed.
Chen, Tianqi, Thierry Moreau, Ziheng Jiang, Lianmin Zheng, Eddie Q. Yan, Haichen Shen, Meghan Cowan, et al. 2018. “TVM: An Automated End-to-End Optimizing Compiler for Deep Learning.” Proceedings of the 13th USENIX Symposium on Operating Systems Design and Implementation (OSDI ’18), 578–94.
That read-compute-write cycle creates memory bandwidth bottlenecks for operations with low arithmetic intensity (FLOP/byte). The traffic rule for a fused chain, established in The memory wall and kernel fusion, bounds what fusion can recover. Fusing a chain of \(\ChainedOperationCount\) operations over an intermediate tensor of \(\IntermediateTensorSize\) bytes cuts idealized read-and-write traffic from \(2\,\ChainedOperationCount \IntermediateTensorSize\) to \(2\IntermediateTensorSize\) bytes, because the fused kernel reads its input once and writes its final output once. Weights, auxiliary inputs, cache effects, and register spills are outside this simple bound, and data dependencies, tensor shapes, and register pressure limit how much can legally be fused. Several inference patterns nevertheless approximate the bound closely enough for fusion to matter.
Convolution-BatchNorm-ReLU fusion
The common Conv-BN-ReLU pattern can replace three launches and intermediate round-trips with one fused path when the compiler can legally fold batch normalization and combine the activation (listing 4). Folding is compression-specific because it must happen after the convolution’s channels and scales are final. Workflows fold batch normalization into preceding convolution weights (\(\FusedConvolutionWeight= \frac{\NormalizationScaleVector}{\BatchNormRunningStandardDeviation} \WeightMatrix\)) where \(\BatchNormRunningStandardDeviation\) is the square root of the sum of running variance and the numerical stabilizer. Folding also adjusts the convolution bias, \(\FusedConvolutionBias = \frac{\NormalizationScaleVector}{\BatchNormRunningStandardDeviation}(\BiasVector- \BatchNormRunningMean) + \NormalizationShiftVector\), where \(\BatchNormRunningMean\) is the per-channel running mean and \(\NormalizationScaleVector\) and \(\NormalizationShiftVector\) are the learned batch-normalization scale and shift. Batch normalization’s per-channel scale thus multiplies into the surviving filters, and its shift becomes the convolution’s bias, so a pruned or quantized network is folded once its structure stops changing.
# Pseudocode: runtime APIs and fusion legality are
# implementation-dependent.
# === UNFUSED: 3 kernel launches, 6 memory transfers ===
conv_out = conv2d(input, weight)
bn_out = batch_norm(conv_out, ...)
relu_out = relu(bn_out)


# === FUSED: 1 kernel launch, 2 memory transfers ===
def conv_bn_relu_fused(input, weight, gamma, beta, mean, var):
    # Read input and weight once
    conv = conv2d(input, weight)

    # Apply batch norm in registers (no memory write)
    bn = gamma * (conv - mean) / sqrt(var + eps) + beta

    # Apply ReLU in registers (no memory write)
    output = relu(bn)

    # Write final result once
    return output
The idealized intermediate stream falls from six transfers to two.
The intended function is preserved, although batch-normalization folding changes the arithmetic sequence, and the intermediate traffic falls by 3×. Generic bias-activation and attention fusion, by contrast, do not depend on compression and belong to the general fusion toolkit of ML Frameworks.
↩︎ IO-aware attention tiling and its HBM-traffic accounting are established in FlashAttention: IO-aware attention optimization.
A ResNet-50 layer with 256 channels and a \(28{\times}28\) spatial size puts numbers on this. Its feature map occupies 802.8 KB, so the four intermediate transfers that fusion removes amount to \(4 \times 256 \times 28 \times 28 \times 4 \text{ bytes} \approx \text{3.2 MB}\) per layer. The full accounting also counts weights and parameters. Without fusion, each operation performs its own memory round-trip: Conv reads input (802.8 KB) plus weights (2.4 MB) and writes output (802.8 KB), totaling 4 MB. BN then reads that output, adds its parameters (2 KB), and writes again, for 1.6 MB. ReLU repeats the pattern for another 1.6 MB. The total unfused memory traffic is 7.2 MB. With fusion, the entire sequence reads input and weights once and writes the final output once, requiring only 4 MB, a 44.8 percent bandwidth reduction.
At the reference H100’s 3,350 GB/s HBM bandwidth, these traffic volumes imply ideal lower bounds of 2 microseconds before fusion and 1.2 microseconds after fusion, a 1.81× ratio for the traffic component alone. These are not full layer latencies because convolution compute, cache effects, and launch overhead must also be included. Furthermore, fusion needs the computation captured as a graph, and dynamic control flow, in-place mutation, or unsupported operations can block the rewrite, so the exported plan must be inspected rather than assumed (graph capture is developed in Graph capture and JIT compilation).
↪ The register pressure and accelerator-specific constraints that bound how far kernels can be fused on GPUs and TPUs are developed in Performance benefits and constraints.
Quantization adds a fusion of its own. A weight-only INT8 or INT4 kernel must turn each packed integer code \(\QuantizedIntegerCode\) back into a real value \(\QuantizerInput\) before multiplying it, using the scale \(\QuantizationScale\) and zero-point \(\QuantizationZeroPoint\) of equation 1 and equation 2: \[ \QuantizerInput= \QuantizationScale(\QuantizedIntegerCode - \QuantizationZeroPoint) \tag{4}\] Executed as a separate kernel, dequantization writes the full-precision weights back to memory and reads them again, restoring the traffic that quantization removed. Fused into the matrix-multiplication kernel, the dequantize step runs in registers on each tile as it arrives, so only the packed bytes cross the memory bus. That fusion is what lets GPT-2 XL’s INT4 weights deliver the decode speedup computed in section 10.3.5. When a runtime cannot fuse it, the quantized model can run slower than its FP16 baseline, a failure section 10.5.4.2 examines. Fusion removes intermediate traffic between operations that must all run, leaving the complementary hardware question of how to skip operands that pruning has already set to zero.
10.4.2 Sparsity exploitation
Replacing pruned weights with zeros inside a standard dense matrix still fetches every zero from memory and multiplies it in the ALU, yielding no wall-clock speedup. Sparsity exploitation designs the storage layouts and kernels that translate sparsity19—tensors where a substantial fraction of entries are zero—into reduced memory traffic and execution time.
19 Sparsity: From Latin sparsus (scattered), past participle of spargere (to scatter); in ML, \(\ell_1\) regularization such as the lasso can induce exact zeros rather than merely small values (Tibshirani 1996). Software can represent arbitrary sparsity patterns, while efficient hardware execution generally requires a supported format or structured pattern (for example, NVIDIA’s 2:4 sparsity). The gap between representable and executable sparsity separates theoretical compression from realized speedup.
Tibshirani, Robert. 1996. “Regression Shrinkage and Selection via the Lasso.” Journal of the Royal Statistical Society: Series B (Methodological) 58 (1): 267–88. https://doi.org/10.1111/j.2517-6161.1996.tb02080.x.
Formally, for a sparse weight matrix \(\SparseWeightMatrix\in \mathbb{R}^{\WeightMatrixRowCount\times \WeightMatrixColumnCount}\), the nominal sparsity ratio \(\SparsityRatio\) is: \[ \SparsityRatio= \frac{\Vert \ZeroEntryIndicator\Vert_0}{\WeightMatrixRowCount\times \WeightMatrixColumnCount} \] where \(\ZeroEntryIndicator\) is an indicator function that yields 1 if entry \((\MatrixRowIndex,\MatrixColumnIndex)\) is zero and 0 otherwise, and \(\Vert \cdot \Vert_0\) counts nonzero entries. When magnitude pruning treats entries below \(\PruningThreshold\) as removable, the thresholded sparsity ratio becomes: \[ \ThresholdedSparsityRatio= \frac{\Vert \BelowThresholdIndicator \Vert_0}{\WeightMatrixRowCount\times \WeightMatrixColumnCount} \] where \(\PruningThreshold\) defines the pruning boundary. Zeros yield wall-clock acceleration only when the execution pipeline skips both the arithmetic and the associated memory traffic.
From an execution standpoint, the spatial pattern of zeros determines memory transaction efficiency. As established in section 10.2.1.2, unstructured sparsity zeroes arbitrary scalar connections, requiring pointer arrays and non-unit-stride gathers that degrade bandwidth on SIMD and systolic units. Conversely, structured patterns, such as channel pruning or \(N\):\(M\) constraints, preserve predictable memory layouts, aligning with standard dense kernels or dedicated hardware datapaths.
Sparsity utilization methods
Translating zeros into runtime speedup requires a representation that encodes nonzero positions and a kernel that decodes those coordinates to bypass unneeded computation (Hoefler et al. 2021). In a matrix-vector product, a dense \(4{\times}4\) operator executes 16 multiply-accumulate operations, whereas a sparse execution path computes only the six nonzero products alongside the necessary metadata lookups: \[ \begin{bmatrix} 2 & 0 & 0 & 1 \\ 0 & 3 & 0 & 0 \\ 4 & 0 & 5 & 0 \\ 0 & 0 & 0 & 6 \end{bmatrix} \begin{bmatrix} \SparseProductInputComponent_1 \\ \SparseProductInputComponent_2 \\ \SparseProductInputComponent_3 \\ \SparseProductInputComponent_4 \end{bmatrix} = \begin{bmatrix} 2\SparseProductInputComponent_1 + \SparseProductInputComponent_4 \\ 3\SparseProductInputComponent_2 \\ 4\SparseProductInputComponent_1 + 5\SparseProductInputComponent_3 \\ 6\SparseProductInputComponent_4 \end{bmatrix} \]
The runtime benefit depends entirely on whether the latency eliminated by skipping 10 multiply-accumulate operations exceeds the latency added by coordinate decoding and non-contiguous activation loads. For unstructured sparsity, that trade has a computable answer in bytes and a measurable one in time.
Storage and execution break-even
A variant of the running case makes the byte side concrete. Suppose the camera team must also ship its MobileNetV2 to a wearable companion device whose microcontroller offers only 2 MB of flash memory, against the model’s 14 MB of FP32 weights. Retraining a smaller architecture from scratch would require weeks of data collection and validation that the product schedule does not allow. Suppose profiling shows that about 85.7 percent of the model’s weights are near zero and contribute little on the validation set. Removing those weights and fine-tuning the remainder for a few epochs leaves surviving weight values that total 2 MB with an acceptable accuracy loss. Whether the stored artifact also fits in 2 MB depends on how the surviving weights are stored. The numbers are a labeled scenario that anchors the engineering trade-off, not a universal MobileNet benchmark.
Storing only the surviving values requires an indexed sparse encoding such as Compressed Sparse Row (CSR) or coordinate list (COO). Because these formats must store positional metadata (such as column indices and row pointers) alongside the nonzero values, metadata overhead offsets savings at low sparsity. For example, storing a 16-bit floating-point weight with a 16-bit column index doubles the per-element byte footprint, requiring over 50 percent sparsity just to break even on artifact size (\(\DataVolume\)). Storing a dense tensor with zeroed entries saves zero memory. The wearable variant shows the consequence. Its surviving weights total 2 MB only if they cost nothing to locate. A 16-bit index beside each value adds half again to 32-bit values and doubles 16-bit ones, so the stored artifact misses the 2 MB flash budget. A denser position encoding, such as a bitmap, reduces the metadata overhead but cannot fit unchanged values that already consume the entire budget. Fitting requires further pruning or lower-precision values with room reserved for metadata, or structured removal of whole channels so that the remaining tensors can be stored without per-value indices.
↪ The memory footprint and index-pointer layouts for compressed sparse row (CSR) representations are collected for reference in Sparse matrix formats.
Nor does unstructured sparsity translate directly to inference acceleration on modern hardware. Commodity accelerators achieve peak throughput (\(\PeakRate\)) through dense systolic arrays and wide SIMD execution units that rely on memory coalescing. Memory transfers use device-dependent transaction granularity, and caches store data in cache lines. Coalescing nearby, aligned accesses lets parallel threads share transactions more efficiently. A dense masked tensor still moves its zero entries. An indexed sparse encoding instead packs nonzero values, but Sparse Matrix-Dense Matrix Multiplication (SpMM) kernels must decode metadata and gather the matching activations. Irregular activation accesses, load imbalance, and kernel overhead can offset the skipped arithmetic even when stored weight values are contiguous. The performance break-even point depends on shape, format, batch size, and the available sparse kernel, so artifact reduction alone does not establish a speedup.
Structured patterns
Structured patterns resolve the break-even problem by constraining where zeros occur, and achieving actual speedups from them requires hardware that can efficiently skip zero-valued computations. Processor architectures differ in which patterns they exploit. Ampere-generation and later Sparse Tensor Cores exploit fine-grained 2:4 structured patterns, while systolic arrays require dense block structures. Libraries such as cuSPARSE reformulate sparse computations into patterns the hardware handles well, and MegaBlocks (Gale et al. 2022) recasts sparse mixture-of-experts training as block-sparse operations on dense tiles.
Gale, Trevor, Deepak Narayanan, Cliff Young, and Matei Zaharia. 2022. “MegaBlocks: Efficient Sparse Training with Mixture-of-Experts.” arXiv Preprint.
A sparse pattern earns hardware speedup only when it is regular enough for kernels to predict. Two formats make that regularity explicit: block sparse matrices and N:M sparsity patterns. Block sparse matrices group nonzeros into dense submatrices, so operations on the large sparse matrix become a smaller number of dense operations on submatrices. In the illustrated representation, \(3\times 3\) dense sub-blocks are indexed by an auxiliary coordinate array, so sub-block kernels can bypass the empty tiles (figure 28) (NVIDIA 2020). The block size is a teaching choice. Actual speedup requires a block shape, layout, datatype, and kernel supported by the target library and hardware; regular blocks alone do not guarantee aligned memory transactions or Tensor Core execution.
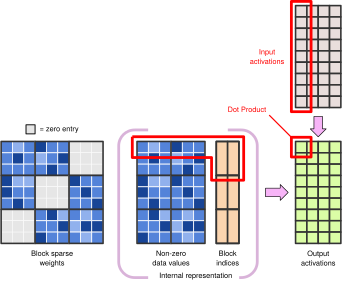
NVIDIA. 2020. Accelerating Matrix Multiplication with Block Sparse Format and NVIDIA Tensor Cores.
Similarly, N:M sparsity retains at most \(\StructuredSparsityNonzeroCount\) nonzeros in each group of \(\StructuredSparsityGroupSize\) consecutive elements; hardware-oriented pruning often enforces exactly \(\StructuredSparsityNonzeroCount\) retained values so every group has the same representation (Zhou et al. 2021). The deterministic format lets a supported kernel predict the value and metadata layout while retaining more capacity than removing whole channels or blocks. That regularity creates an executable compromise between arbitrary masks and dense computation, but only for targets with the matching path.
Zhou, Aojun, Yukun Ma, Junnan Zhu, Jianbo Liu, Zhijie Zhang, Kun Yuan, Wenxiu Sun, and Hongsheng Li. 2021. “Learning n:m Fine-Grained Structured Sparse Neural Networks from Scratch.” arXiv Preprint.
Lu, Yucheng, Shivani Agrawal, Suvinay Subramanian, Oleg Rybakov, Christopher De Sa, and Amir Yazdanbakhsh. 2023. “STEP: Learning n:m Structured Sparsity Masks from Scratch with Precondition.” arXiv Preprint.
On hardware with a sparse matrix path, the 2:4 pattern of section 10.2.1.3 turns into execution savings, since its 2-bit position indices cost far less than the pointer arrays of general CSR or COO formats (NVIDIA Corporation 2020). The sparse datapath that consumes those indices and skips the zeroed multiplies is developed in N:M structured sparsity mechanics. Learned masks need not stop at 2:4; STEP, for example, learns more general N:M masks for inference (Lu et al. 2023).
Unstructured pruning zeroes arbitrary individual weights. Those irregular locations can disrupt memory coalescing and lane utilization, while Compressed Sparse Row (CSR) or Coordinate (COO) metadata adds storage and non-unit-stride accesses. An unstructured sparse model can therefore run slower than its dense counterpart when metadata and underutilization outweigh skipped arithmetic. TPUs are useful contrast cases for dense systolic-array acceleration (Jouppi et al. 2021), but sparse acceleration still depends on a specific hardware and software path rather than accepting arbitrary masks. Field-programmable gate arrays can implement application-specific sparse formats, yet their efficiency depends on the chosen dataflow and resource budget; programmability is not a universal sparse-speedup guarantee.
Jouppi, Norman P., Doe Hyun Yoon, Matthew Ashcraft, Mark Gottscho, Thomas B. Jablin, George Kurian, James Laudon, et al. 2021. “Ten Lessons from Three Generations Shaped Google’s TPUv4i: Industrial Product.” 2021 ACM/IEEE 48th Annual International Symposium on Computer Architecture (ISCA), 1–14. https://doi.org/10.1109/isca52012.2021.00010.
Gale, Trevor, Matei Zaharia, Cliff Young, and Erich Elsen. 2020. “Sparse GPU Kernels for Deep Learning.” SC20: International Conference for High Performance Computing, Networking, Storage and Analysis 2020: 8955–67. https://doi.org/10.1109/sc41405.2020.00021.
Across all platforms, sparse operations can reduce memory bandwidth requirements and energy consumption when the sparse representation and kernels actually skip data movement rather than only arithmetic. This benefit compounds with quantization, since a sparse INT8 model can require less memory traffic than either technique alone when the format overhead is small enough (Hoefler et al. 2021; Gale et al. 2020).
Challenges and limitations

Unstructured sparsity pays off only after crossing a hardware- and kernel-specific break-even point.
The dependence of every sparse speedup on a matching format and kernel explains why nominal sparsity often fails to deliver speedups in practice. First, the performance break-even point varies with tensor dimensions, sparse format, kernel implementation, and hardware architecture. When coordinate metadata and irregular activation gathers saturate cache lines, an unstructured sparse kernel can run slower than an optimized dense baseline until sparsity exceeds 80 to 90 percent. Second, the accuracy-efficiency trade-off is nonlinear, because models often tolerate moderate pruning before task quality degrades abruptly past a critical density threshold. Finally, energy savings do not scale linearly with skipped operations; irregular memory access and index decoding can consume more power on edge devices than the arithmetic they eliminate. Fusion and sparse kernels thus decide whether each technique’s paper savings survive contact with the hardware. Most deployments apply several techniques at once, and choosing and ordering them is the next decision.
Self-Check: Question
A paper estimate predicts an \(8\times\) speedup for a compressed model under ideal assumptions, but the implementation measured on an unmodified GPU delivers only \(1.5\times\). Which statement best defines the role of hardware implementation in explaining this gap?
- It aligns computation graphs, memory access layouts, operator scheduling, and sparsity patterns with physical accelerator architectures so that theoretical compression can translate into measured wall-clock speedup
- It reduces the volume of training data needed to fine-tune compressed neural networks
- It eliminates all memory-bound operations by converting every neural network layer into a compute-bound GEMM
- It automates the hyperparameter tuning of learning rates and batch sizes during pretraining
Operator fusion of Conv-BatchNorm-ReLU sequences produces substantial execution speedup on modern GPUs even though the fused kernel preserves the intended layer function. Which mechanism explains this latency reduction?
- Fusion reduces the total number of weight parameters stored in the convolutional layer
- Fusion retrains the network to use lower numerical precision during the forward pass
- Fusion skips zero-valued activation elements by converting dense tensors to sparse matrices
- Fusion executes convolution, batch normalization, and ReLU inside a single GPU kernel, keeping intermediate activations on chip and cutting intermediate-tensor traffic and launch overhead
A compressed neural network achieves a \(50\%\) reduction in total floating-point operations (FLOPs), yet on the deployment accelerator, end-to-end inference latency decreases by only \(10\%\). Explain two distinct hardware and architectural mechanisms that cause this discrepancy.
True or False: Commodity SIMD vector units automatically achieve proportional latency reductions on weight matrices with \(50\%\) unstructured sparsity because vector lanes automatically skip zero values without overhead.
A team optimizes a deep network for NVIDIA Ampere GPUs that feature hardware-accelerated 2:4 structured sparsity. Which compression strategy directly engages this dedicated accelerator capability?
- Unconstrained unstructured magnitude pruning, because maximum zero count always yields the highest speedup on Ampere
- Dynamic channel pruning that alters tensor shapes per batch, because Tensor Cores require dynamic input dimensions
- Structured 2:4 sparsity (exactly 2 non-zero values in every contiguous block of 4 elements), because Ampere Tensor Cores include a supported sparse path for that pattern
- Activation checkpointing, because recomputing intermediate activations during inference eliminates sparse matrix indexing overhead
10.5 Choosing and Combining Techniques
When the chapter’s phone decodes GPT-2 XL, its FP16 weights and KV cache claim 3.3 GB of the 8 GB that the operating system and other applications also share, each generated token waits about 65 ms while every weight streams over the 51.2 GB/s bus, and the handset sustains only 3–5 W before thermal throttling. Choosing among compression techniques—and ordering them—starts from whichever of those physical limits binds first, alongside the allowable task accuracy loss and the available training budget.
The three primary optimization levers target different levels of the system stack. Distillation alters the algorithmic architecture by training a compact dense student to emulate a larger teacher, executing efficiently on standard hardware without specialized runtime support. Pruning modifies tensor topology and operation patterns, but yields wall-clock acceleration only when the resulting sparsity aligns with hardware execution units, such as 2:4 structured sparse matrix cores or channel-aligned sub-matrices. Quantization alters data representation by reducing numerical bit width, directly lowering memory bus traffic and cache footprint while engaging higher-throughput integer datapaths. Their first-order trade-offs, with representative ranges for common choices, sit side by side in table 11.
NVIDIA. 2024. NVIDIA TensorRT: Programmable Inference Accelerator.
Han, Song, Jeff Pool, John Tran, and William J. Dally. 2015. “Learning Both Weights and Connections for Efficient Neural Networks.” Advances in Neural Information Processing Systems 28 (NeurIPS 2015), 1135–43.
| Technique | Systems gain | Typical impact | Training cost | Hardware dependency | Region |
|---|---|---|---|---|---|
| Kernel fusion | 10–30% latency reduction | No accuracy loss | None | The compiler must recognize the pattern | 1 |
| FP32 → BF16 | 2\(\times\) memory, ~2\(\times\) throughput | \(<0.1\%\) accuracy drop | None for inference | A native BF16 path | 1 |
| FP16 → INT8 | 2\(\times\) memory, 2–4\(\times\) throughput | Quantization error, 0.5–1% accuracy drop | Low for PTQ; higher for QAT | INT8 kernels for a runtime speedup | 2 |
| 50% pruning | ~2\(\times\) smaller model | Capacity loss, 0.5–1% accuracy drop | Usually includes fine-tuning | Structured shapes or supported sparse kernels | 2 |
| Knowledge distillation | 2–10\(\times\) smaller student | Capability ceiling, 1–3% accuracy drop | Teacher inference and a student run | Low; the student is an ordinary dense model | 2 |
| 4-bit quantization | 4\(\times\) memory reduction | Significant error, 2–5% accuracy drop | Low for PTQ; higher for QAT | Low-bit kernels with fused dequantization | 2–3 |
| 90% pruning | ~10\(\times\) smaller model | Severe capacity loss, 5–15% accuracy drop | Iterative fine-tuning | Sparse kernels past the break-even point | 3 |
10.5.1 The accuracy-efficiency frontier
Pushing a single compression knob too far—such as pruning 90 percent of a network’s weights or quantizing sensitive layers to 4 bits without retraining—crosses a cliff where a modest extra byte saving costs 5 to 15 percentage points of task accuracy (table 11). Every lever in the table moves the model along this accuracy-efficiency trade-off: additional model capacity can improve predictive accuracy while demanding larger weight payloads, expanded activation working sets, and higher memory bandwidth during inference. On hardware with strict memory or power limits, engineers first eliminate avoidable implementation costs, then choose among feasible operating points on the Pareto frontier (principle 5).
Systems Perspective 10.2: The compression-accuracy trade-off curve
The measured trade-off is not uniform. A structure-preserving implementation improvement can move a dominated model toward the frontier with little or no accuracy loss. Once on an efficient frontier, improving one objective trades against another; aggressive structural changes can enter regions with steep quality penalties.
The engineering decision is where to stop. The “knee” of the curve marks a region where further resource savings incur a sharper quality penalty. It is a useful visual diagnostic, but accuracy points cannot be compared directly with milliseconds, bytes, or joules. Stop at an operating point that meets the deployment’s quality and resource thresholds, using explicit objective weights if a further trade must be ranked.
Techniques that preserve model structure, such as kernel fusion and modest precision reduction (FP32 to BF16), can yield latency or memory gains with little quality loss when the model and execution path support them. In contrast, techniques that alter network structure, such as pruning and distillation, yield larger reductions in memory and arithmetic volume but risk significant quality degradation without careful retraining. Optimization therefore begins by identifying the binding hardware constraint—memory capacity on mobile devices, frame latency in interactive pipelines, or energy per inference on battery-powered sensors—so each tier can target the resource that actually binds: structural methods cut parameter and operation counts, quantization shrinks memory traffic and raises arithmetic intensity, and compiler-level fusion eliminates intermediate memory round-trips. The regions in table 11 mark where each choice typically lands on that curve, and a structured decision framework maps each binding hardware constraint to the specific levers worth testing first.
Checkpoint 10.4: The efficiency frontier
Optimization can remove avoidable costs or trade among efficient operating points.
Trade-offs
10.5.2 Decision framework
Applying a compression technique that targets the wrong hardware bottleneck wastes engineering cycles and task accuracy: pruning FLOPs from a layer stalled on off-chip weight streaming leaves memory-bus latency intact, whereas quantizing weights to 8 bits on a compute-bound processor that lacks an integer matrix unit leaves arithmetic throughput unchanged. Identifying the binding hardware constraint first narrows the search to the optimization tiers that can relieve it. Under the D·A·M taxonomy, compression methods redistribute resource demands across Algorithm (topology, pruning, distillation, and the numerical representation of weights) and Machine (execution units and memory hierarchies); range-calibration sets are the main Data-axis input. Each system constraint maps to the optimization tiers that can relieve it (table 12), where the marks identify mechanisms to investigate rather than guaranteed deployment gains.
| System Constraint | Model Representation | Numerical Precision | Hardware Implementation |
|---|---|---|---|
| Computational Cost | ✓ | \(\triangle\) | ✓ |
| Memory and Storage | ✓ | ✓ | \(\triangle\) |
| Latency and Throughput | ✓ | \(\triangle\) | ✓ |
| Energy Efficiency | ✓ | ✓ | ✓ |
| Scalability | ✓ | \(\triangle\) | ✓ |
One technique can move more than one term of the iron law. For example, quantizing weights from FP32 to INT8 directly relieves on-device storage capacity. A bandwidth-limited operator approaches proportional latency savings only when the affected traffic dominates and conversion overhead does not consume the gain. A compute-limited operator needs a faster supported execution path. Unstructured pruning likewise reduces executed arithmetic only when sparse kernels exploit the removed weights; indexing and irregular memory accesses can offset the saving. The changed representation therefore supplies a candidate improvement whose effect must be measured on the target.
When persistent storage or device memory capacity binds the deployment, as over-the-air package limits and microcontroller flash budgets do, quantization provides the most direct payload reduction. Relative to FP32 storage, INT8 post-training quantization (PTQ) cuts raw weight storage by 4\(\times\) without requiring retraining cycles. INT4 cuts raw payload by 8\(\times\), though aggressive bit-width reduction increases the risk of accuracy degradation. If uniform low-bit quantization causes unacceptable accuracy loss on sensitive layers, distilling knowledge into a smaller dense architecture followed by moderate quantization preserves fidelity while satisfying the storage budget.
When latency is compute-bound, the workload operates above the accelerator’s ridge point, the arithmetic intensity at which its compute and memory-bandwidth limits meet, saturating execution units. Relieving this bottleneck requires reducing executed operations or increasing arithmetic throughput. Structured pruning removes channels, attention heads, or entire layers, yielding smaller dense matrices that execute on standard libraries without sparse runtime overhead; however, pruning to dimensions that misalign with hardware warp or tile sizes (such as channel counts not divisible by 8 or 16) degrades tensor core efficiency and curtails wall-clock gains. If the target platform provides dedicated integer execution units, INT8 quantization increases the instruction throughput rate, accelerating compute-bound kernels directly. Early-exit architectures provide an alternative algorithmic path by dynamically halting inference on simpler inputs, provided that routing and pipeline synchronization overhead do not disrupt batch processing.
↪ How the ridge point shifts across accelerators and precisions is developed in Hardware ridge points.
Small-batch transformer generation often exposes a weight-bandwidth bottleneck, as GPT-2 XL decoding on the phone showed, because dense decoding streams large parameter matrices for matrix-vector operations with low arithmetic intensity. When fetched weights dominate latency, weight-only quantization (such as INT4 or INT8 weights paired with FP16 activations) can approach a speedup proportional to the reduction in those bytes. KV-cache traffic and dequantization overhead limit that gain without necessarily making execution compute-bound; larger batches can increase weight reuse and shift the limiting resource.
When energy or thermal dissipation binds, quantization provides substantial benefits because moving data across off-chip memory buses consumes orders of magnitude more energy per bit than on-chip arithmetic or local SRAM access. Reducing operand bit widths directly lowers bus capacitance charging energy, while integer ALUs consume less switching energy than floating-point datapaths. Structured pruning compounds these savings by eliminating operations and memory transactions entirely. Full-system power audits must still measure peripheral components (memory refresh, host bus communication, and static idle leakage) to ensure that kernel-level energy savings translate into extended operating life.
Selection also depends on the engineering and computational budget available. Calibrated PTQ needs only a small representative dataset, and QAT adds training cost only when PTQ misses the accuracy threshold. Knowledge distillation costs more, requiring teacher forward passes and substantial training cycles to optimize a smaller student model. Hardware-aware NAS occupies the highest cost tier, justified only when high-volume deployment amortizes the extensive compute needed to explore the architectural search space.
Applied to GPT-2 XL decoding on the phone, this framework makes INT4 weight-only quantization the first candidate, not a completed solution. It cuts the weight bytes to a quarter of FP16, but each token also streams the unchanged KV cache, and the gain holds only when dequantization is fused into the matrix multiplication (section 10.3.5). Distillation to a smaller model is another candidate if the remaining gap justifies its training cost. Each candidate must pass task-quality, latency, peak-memory, and sustained-power checks against the phone’s 3–5 W envelope.
Choosing an individual technique addresses a single binding bottleneck, but production deployment budgets frequently require compounding gains across multiple dimensions. When memory capacity, bandwidth, and compute throughput are all constrained simultaneously, optimizing a system requires composing structural alterations, precision reductions, and custom execution kernels into an integrated transformation pipeline.
10.5.3 Combining and sequencing techniques
Quantizing a network to fixed 8-bit integer ranges before pruning its channels shifts the activation distributions that those ranges were calibrated to fit, while removing floating-point precision before distillation hinders gradient recovery. Because each tier changes the weight and activation distributions or tensor shapes that the next tier sees, the order in which compression techniques are applied governs both final accuracy and hardware utilization. On the camera pipeline, the sequence follows directly from those dependencies between the tiers. Channel pruning comes first, with pruned channel counts kept on a multiple of the hardware’s tile width so the smaller layers still fill the phone’s matrix tiles. Distillation from the ResNet-50 teacher then serves as the recovery training for the pruned network, the prune-then-distill order described in section 10.2.3. INT8 quantization comes last among the model changes, because range calibration must see the weight and activation distributions of the final structure, and because INT8 is what moves the model from the phone’s CPU onto its integer accelerator. Batch-normalization folding and the remaining fusions are applied when the graph is compiled for the device. Each step is profiled on the phone before the next is taken, because each one changes the bottleneck that the next one faces. The steps also move different quantities, and most of the frame time comes off at the step that changes the processor (figure 29).
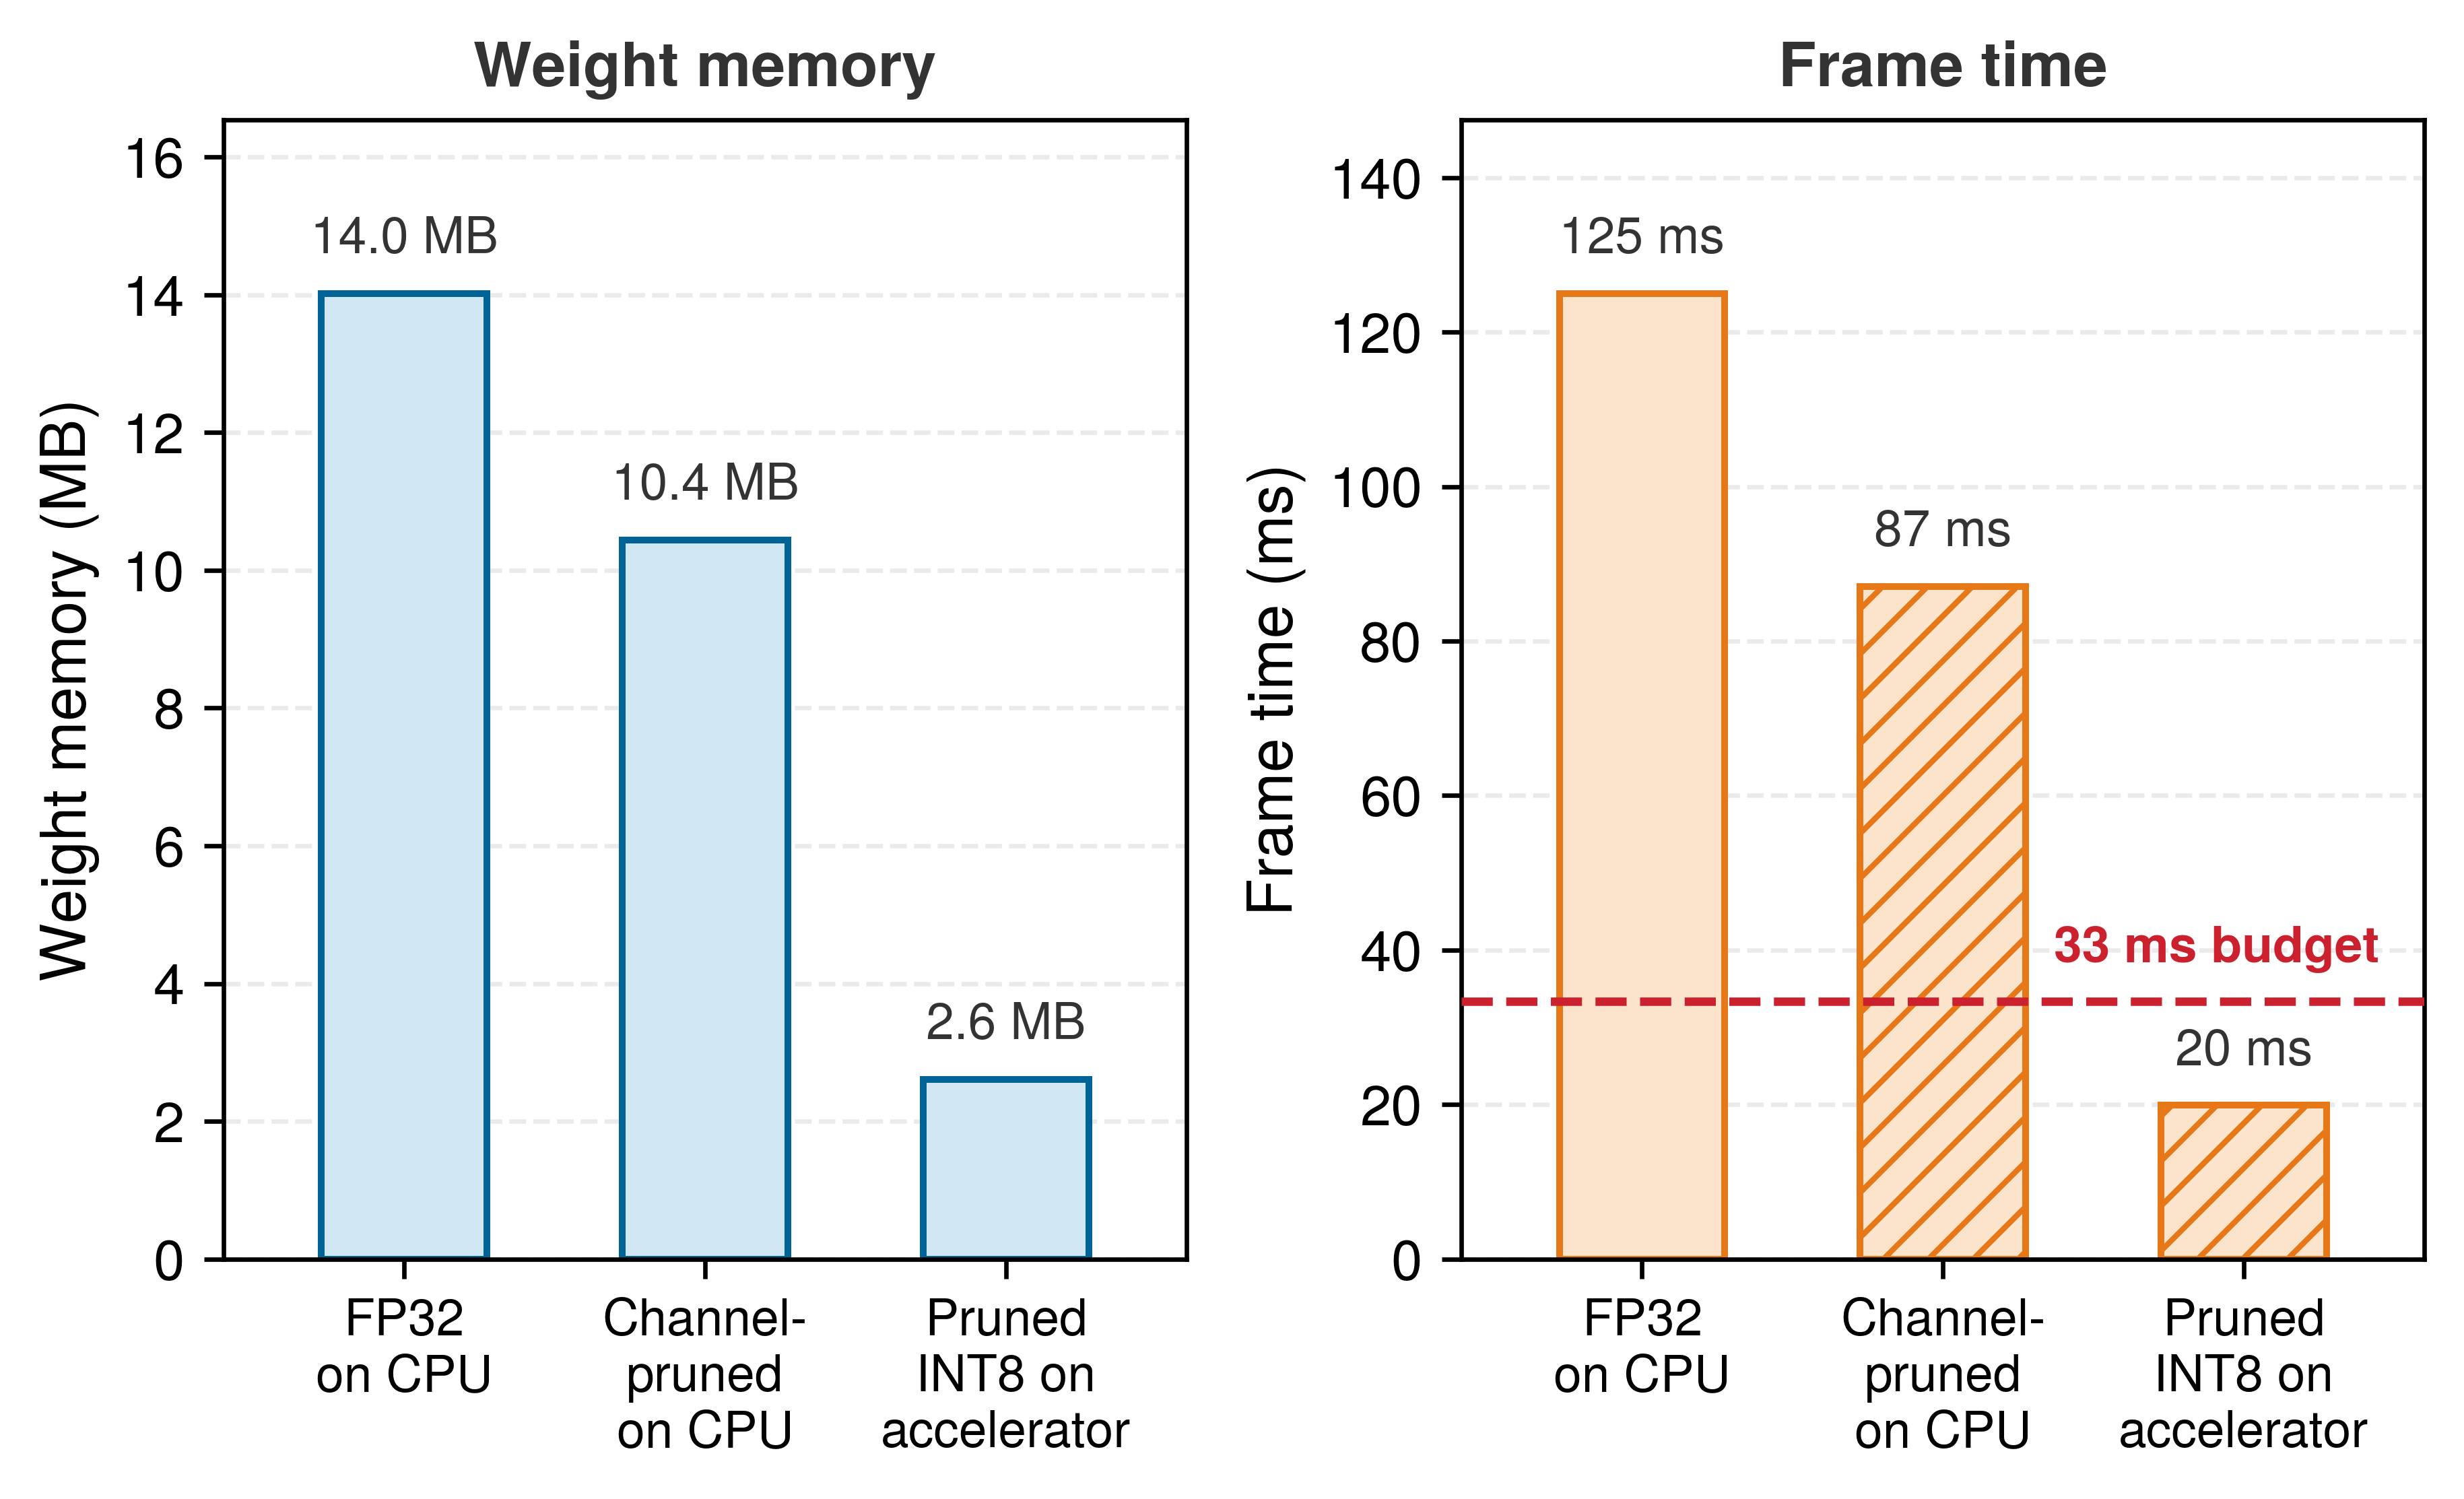
A modeled BERT-Base pipeline attaches numbers to the same staging. Pruning, distillation, and quantization together reduce its footprint from 440 MB to 28 MB (rounded), a 16× raw-footprint reduction. Each stage addresses a distinct bottleneck. Structural pruning removes redundant matrix multiplications, distillation supervises the compact student to recover representational capacity, and quantization packs weights and activations into lower-bit integers to relieve memory bandwidth pressure.
Example 10.2: BERT-Base mobile deployment pipeline
Scenario: A modeled deployment targets executing a 110M-parameter BERT-Base language model on resource-constrained mobile hardware. The compact graph is stipulated for this example; the figures are not reported DistilBERT results.
The FP32 teacher begins at 440 MB with assigned task accuracy 76.2 percent. Structural pruning produces a stipulated 27.5M-parameter graph, a 75 percent parameter reduction, with raw FP32 weights of 110 MB and assigned accuracy 75.1 percent.
That pruned graph is the distillation student. Teacher supervision recovers its assigned accuracy to 75.9 percent without another parameter-count reduction. Final INT8 quantization leaves the same parameter count, reduces raw weight storage to 27.5 MB, and has assigned accuracy 75.6 percent. The headline ratio uses this unrounded weight payload; scales, zero-points, packing, activations, and runtime workspace remain outside the calculation.
Diagnosis: In this modeled comparison, quantization before pruning has an assigned accuracy loss of 2.1 percent. One mechanism to investigate is whether structural changes invalidate previously calibrated ranges. Pruning and distillation before quantization allow calibration to use the resulting distributions. These modeled values illustrate the mechanism and do not establish a universal ordering.
Systems lesson: In this modeled pipeline, pruning, then distillation, then post-training INT8 quantization produce a 16× footprint reduction (440 MB to 28 MB) while limiting task accuracy loss to 0.6 percent. Because tensor distributions and hardware kernel efficiencies vary across architectures, each intermediate artifact must be profiled on the target runtime.
Sequencing matters because these transformations interact through shared parameters and activation distributions. Structural pruning removes channels or attention heads, altering the dynamic range and variance of surviving weight tensors. Quantizing before pruning can leave ranges poorly matched to the resulting distributions, so recalibration or joint adaptation may be needed. In the staged candidate, floating-point recovery lets the pruned network adapt, and distillation supplies a teacher signal before final quantization. QAT itself updates floating-point master weights through approximate gradients; it does not require direct integer weight updates. Alternative schedules should be compared at matched recovery and calibration budgets.
Combining techniques also changes the size-quality trade-off itself (Han et al. 2016). In one reported setting (figure 30), while individual SVD and pruning curves suffer steep accuracy cliffs below about 15 percent and 6 percent model size respectively, combining pruning with quantization extends the zero-loss plateau down to roughly 3 percent of original parameter footprint. This comparison does not isolate transformation order. The magnitude of these gains remains model- and runtime-specific, requiring engineers to validate each transformation stage independently.
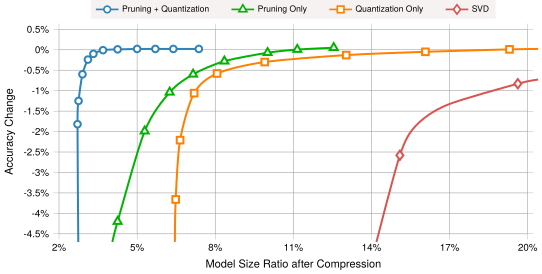
Han, Song, Huizi Mao, and William J. Dally. 2016. “Deep Compression: Compressing Deep Neural Networks with Pruning, Trained Quantization and Huffman Coding.” arXiv Preprint.
Systems Perspective 10.3: The optimization composition problem
Optimization techniques interact through shared representations and physical resources rather than composing as independent functions. Pruning changes the surviving value distribution, tensor shapes, or sparse format; quantization adds scales and changes the available kernels; fusion changes which intermediates are materialized and can alter the profile that justified earlier choices. Composing pruning with quantization, as when 2:4 structured sparsity is paired with INT8 weights, leaves an executable that must carry both the sparsity metadata and the quantization scales, and a pruned shape that breaks the memory alignment a quantized kernel expects can erase the speedup of both (Hoefler et al. 2021). Effective optimization therefore treats the model-runtime-hardware combination as a coupled system, measures it after every transformation, and revisits the sequence when a new bottleneck appears. This makes compression a systems engineering problem as well as a machine learning problem.
Hoefler, Torsten, Dan Alistarh, Tal Ben-Nun, Nikoli Dryden, and Alexandra Peste. 2021. “Sparsity in Deep Learning: Pruning and Growth for Efficient Inference and Training in Neural Networks.” Journal of Machine Learning Research 22 (241): 1–124.
A footprint reduction that compounds on paper therefore becomes a speedup only where the runtime supports every transformation in the sequence at once, which makes the toolchain that applies them part of the decision.
10.5.4 Compression toolchains
Quantizing a large model by hand would mean editing thousands of operator call sites to insert scale factors and track activation ranges. Manual graph surgery also cannot guarantee autograd consistency during retraining or the memory alignment that accelerator kernels require. Compression therefore runs through tooling, and the tool choice follows the layer of the software stack that owns the transformation. Framework APIs operate on the high-level computation graph during training and calibration, where the execution engine maintains visibility into weights, activations, and autograd state. At this stage, quantization is typically simulated, with fake-quantization nodes that clamp and round values within floating-point registers, modeling numerical precision loss while preserving differentiability.
Simulating quantization does not itself establish a physical speedup. A compiler or runtime must lower the graph into supported kernels; frameworks may integrate that stage or export to a separate deployment engine. The runtime compiler fuses scale factor arithmetic directly into matrix-multiplication compute tiles and packs sparse weights into hardware-specific metadata layouts (such as 2:4 structured sparsity formats). This lowering eliminates round-trip memory transactions to HBM that would otherwise negate the benefits of reduced precision.
Reproducibility is the first requirement of a multi-stage pipeline. Compressing a model alters its numerical representations across both the algorithm and machine layers of the D·A·M taxonomy. Unrecorded calibration inputs or mismatched rounding modes can degrade accuracy silently without raising runtime errors, so every deployed artifact must remain traceable from its source training checkpoint, through the calibration data, pruning schedule, and fusions that produced it, to its compiled hardware execution graph.
↪ Versioned artifacts and the lineage graphs that keep deployed models traceable are developed in Versioning and lineage.
Model optimization APIs and tools
At the model-development layer, compression algorithms require access to runtime state that downstream deployment compilers discard: gradient histories, optimizer state variables, and dynamic activation distributions. When post-training quantization or one-shot pruning degrades accuracy beyond acceptable operating thresholds, recovery requires retraining or iterative fine-tuning. Frameworks such as PyTorch and TensorFlow provide optimization APIs specifically to manage this graph-transformation boundary. These APIs inject quantization nodes and observers, reparameterize weight tensors with sparsity masks, and preserve calibration metadata alongside the trained parameters, which is what makes a compression recipe repeatable across many models.
Quantization-aware training demonstrates this graph-level intervention. Optimization APIs insert the fake-quantization operators of section 10.3.3.2.2 into the compute graph; these operators clamp and round in the forward pass and apply the straight-through estimator of section 10.3.3.2.1 in the backward pass. Producing a deployable low-precision artifact then takes a short sequence of graph transformations and metadata tracking (listing 5).
choose target precision and calibration policy
insert quantize/dequantize boundaries around selected tensors
train with simulated low-precision values while keeping gradient flow intact
record scales, zero points, accumulator precision, and unsupported operations
export the calibrated graph and metadata as one reproducible artifact
Pruning tools implement the mask-then-export boundary of section 10.2.1.7. A mask-based API keeps the dense weight tensor \(\WeightMatrix\) and a binary mask \(\PruningMask\) of the same shape during recovery training, computing \(\PrunedWeightMatrix= \PruningMask\odot \WeightMatrix\) in the forward pass so the existing dense kernels and gradient updates keep working. An export pass then finalizes the transformation, either slicing away pruned channels or encoding the nonzeros in a sparse format the target’s kernels accept. What must be recorded along the way, so that the compressed model can be reproduced, is short but not optional (listing 6).
choose pruning granularity: individual weights, channels, blocks, or attention heads
score candidate parameters by magnitude, sensitivity, or validation loss impact
remove or mask the selected structure according to the hardware-compatible rule
fine-tune the compressed model against the original validation target
export weights, masks, sparsity pattern, and calibration evidence together
Hardware-specific optimization libraries
Exporting an optimized model from a training framework produces an intermediate graph representation, not an executable binary. Compilers and runtime engines such as TensorRT, Accelerated Linear Algebra (XLA), OpenVINO, and TVM own the final translation step: compiling a pruned, quantized, or fused graph into machine instructions tailored to the target accelerator. In D·A·M terms, algorithmic compression remains theoretical until the graph maps to kernels that physically exploit the target machine’s memory hierarchy and execution units.
The compilation pass verifies whether nominal compression yields physical speedup. Pruning that leaves zeros in dense tensors still streams and multiplies those entries with a dense kernel. Compact sparse formats need matching kernels, such as a supported 2:4 path, while structured channel removal can produce smaller tensors for ordinary dense kernels. Quantization lowers bitwidth, but a weight-only path may unpack operands into floating-point registers before arithmetic. That unpacking adds instructions; its cost must be compared with the packed weight traffic saved.
The result can be the runtime dequantization trap. If an accelerator provides native INT8 matrix-multiplication kernels but lacks an INT8 implementation for an adjacent operation (such as LayerNorm, GeLU, or an attention softmax reduction), the runtime encounters a type boundary. An unfused execution path may allocate a temporary buffer, launch a dequantization kernel to recover floating-point values (\(\QuantizerInput= \QuantizationScale(\QuantizedIntegerCode - \QuantizationZeroPoint)\), equation 4), execute the unsupported operator, and launch another kernel to re-quantize its output. The floating-point format and opportunities to fuse conversion depend on the runtime. These intermediate format conversions incur extra kernel launches, introduce synchronization barriers, and add temporary floating-point traffic that can make the quantized model slower than the FP16 baseline. A fused weight-only path instead unpacks values within the consuming kernel, the fusion of section 10.4.1, and retains a net memory-traffic benefit.
Low-precision kernels also require specialized tensor layouts, such as tiled or interleaved memory channels, to ensure coalesced loads into shared memory or register files. When an unsupported operator sequence blocks the fusions of section 10.4.1, the memory-bandwidth bottleneck remains intact. Whether integrated into a framework or supplied separately, the compiler and runtime determine which graph-level opportunities become an efficient machine execution plan. Whether that plan delivers the savings computed in the earlier sections is a question only measurement on the target hardware can answer.
Self-Check: Question
A deployment fails because the model’s static weight footprint alone exceeds the available memory or storage budget on the target device. Which optimization dimensions should an engineer prioritize first?
- Hardware implementation alone, because runtime execution scheduling determines disk and RAM consumption
- Operator fusion alone, because fusing layers eliminates static weight parameter matrices
- Increasing training batch size, because larger batches compress parameter representations during optimization
- Model representation (pruning, distillation) and numerical precision (quantization), because both directly target the byte footprint of the deployed model
A \(13\text{-billion}\)-parameter FP16 language model fits on the target edge server only at short context, but the required production KV cache and workspace do not fit. Profiling that feasible short-context baseline shows autoregressive decoding is dominated by weight traffic. Which optimization is the most direct initial candidate to test?
- Weight-only INT4 or INT8 post-training quantization (PTQ), because it directly shrinks raw weight bytes and can reduce weight-bandwidth pressure if the remaining memory budget also fits
- Unstructured magnitude pruning with 90% target sparsity, because arbitrary sparse patterns run fastest on edge memory controllers
- Neural Architecture Search from scratch, because searching a new architecture is the fastest way to resolve an immediate deployment deadline
- LayerNorm operator fusion alone, because LayerNorm compute dominates total parameter storage in large language models
Order the stages of a practical compression decision procedure: (1) test a low-cost candidate and measure all relevant quality and resource constraints, (2) establish the binding constraint from a decisive capacity bound or from profiling a feasible baseline, (3) map that constraint to candidate optimization levers, (4) if the candidate fails, consider recovery training or a structural candidate appropriate to the failed constraint.
The chapter’s illustrative BERT compression pipeline compresses a \(440\text{ MB}\) FP32 model down to \(28\text{ MB}\) (roughly \(16\times\)) by sequencing pruning, distillation, and INT8 quantization. Why do these techniques compound multiplicatively rather than substituting for one another?
- The techniques duplicate each other’s reductions, causing total compression to saturate at the performance of the single strongest method
- Pruning produces the smaller student graph, distillation recovers its quality at the same parameter count, and quantization reduces numerical bit-width per parameter; because these operate on orthogonal resource axes, their compression ratios multiply (\(4\times \text{ structural} \times 4\times \text{ precision} \approx 16\times \text{ total}\))
- Applying quantization automatically converts the pruned network into a student model without requiring teacher supervision
- Multiplicative gains occur only when the pipeline starts with operator fusion on uncompressed weights
In a modeled scenario, one compression order loses \(0.6\%\) accuracy while the reversed order loses \(2.1\%\). Propose a plausible pruning-quantization interaction that could explain this gap, and state what a fair comparison should hold fixed before concluding the ordering matters.
A measured compression-quality curve shows a clear knee: before it, each extra compression step saves substantial resource with small quality loss; after it, additional compression yields much smaller resource savings for noticeably larger quality loss. Explain how an engineer should use that knee when choosing an operating point for a deployment with explicit quality and resource constraints.
An engineering team evaluates TensorFlow Model Optimization Toolkit (TFMOT) and PyTorch’s
torch.aoAPIs for a pipeline compressing hundreds of production models per month. What is the primary systems value these framework toolkits provide?- They eliminate the need for engineers to benchmark or validate models on physical target hardware
- They automate the insertion and state management of complex compression primitives—such as fake-quantization observers, dynamic range trackers, and sparsity masking hooks—making compression scalable and reproducible across hundreds of models
- They automatically discover optimal hyperparameter architectures from scratch without compute overhead
- They guarantee identical execution performance across all CPU, GPU, and TPU backends without requiring hardware-specific compilers
A model is pruned and quantized inside a training framework, but the exported deployment shows almost no speedup on the target accelerator. Explain why a hardware-specific compiler or runtime is still needed, and why framework-level masks or fake-quant operations are not enough evidence of real acceleration.
10.6 Measuring Compression Gains
Shrinking a model’s weights by \(4\times\) with INT8 quantization rarely cuts end-to-end latency by \(4\times\), because cache residency, memory bus contention, and kernel launch overhead absorb much of the theoretical gain. Every saving computed so far in this chapter is a paper bound, and only a measurement on the target device turns a bound into a result: profiling on the deployment hardware identifies which resource binds each layer, fixes an honest baseline, and separates model execution time from runtime and pipeline overhead.
10.6.1 Profiling and opportunity analysis
Compressing the layers with the most parameters or FLOPs can leave wall-clock latency barely changed when low-intensity operators—such as layer normalization or elementwise activations—contribute almost no FLOPs yet consume a large share of execution time by streaming whole activation tensors across memory. The top-down profiling method of Identifying Bottlenecks tells compression where to act, and two of its measurements decide the technique. Static footprint (weight tensors and persistent buffers) decides whether parameters fit in fast memory or device DRAM without spilling across PCIe, while dynamic allocation (activation tensors and KV caches) sets peak residency and so bounds batch size and serving concurrency. Alongside memory residency, each operator’s arithmetic intensity (\(\ArithmeticIntensity= \Operations/\DataVolume\)) shows whether removing FLOPs or removing bytes will actually shorten it.
A profile of a Vision Transformer (ViT) on an edge accelerator illustrates this operational heterogeneity. Per token and layer, the multilayer perceptron (MLP) block costs about \(8\HiddenDimension^2\) multiply-accumulates against \(4\HiddenDimension^2\) for the query, key, value, and output projections. In a ViT-Base-sized model the MLP blocks therefore carry nearly two-thirds of FLOPs and the projections just under one-third, with the attention score and weighting products adding only a few percent at standard image resolution. Layer normalization inverts the picture, contributing almost no FLOPs yet can claim a visible share of wall-clock latency, because it streams whole activation tensors with little arithmetic per byte. The camera pipeline’s MobileNetV2 splits the same way in convolutional form. Its \(1{\times}1\) expansion and projection layers carry most of the multiply-accumulates (Sandler et al. 2018), while its depthwise layers, like layer normalization, do little arithmetic per byte moved and take a larger share of time than of work. Profiling isolates the governing physical bottleneck for each component, dictating targeted optimizations rather than uniform compression: structured pruning of MLP hidden units relieves the compute-dominant blocks, kernel fusion eliminates intermediate global memory round-trips for memory-bound normalization layers, and INT8 quantization shrinks the static footprint that the MLP and projection weights dominate.
Sandler, Mark, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, and Liang-Chieh Chen. 2018. “MobileNetV2: Inverted Residuals and Linear Bottlenecks.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 4510–20. https://doi.org/10.1109/cvpr.2018.00474.
Non-model work dominates latency, so compression caps speedup at 1.25\(\times\).
Translating layer-level profiling metrics into end-to-end system speedup requires accounting for the complete serving pipeline. In production serving systems, model execution frequently represents only a fraction of total latency, with the remainder consumed by image decoding, tokenization, RPC deserialization, or network transfer. Optimizing the model in isolation encounters an Amdahl ceiling whenever non-model stages dominate the latency budget, a ceiling that End-to-end vs. component latency measures end to end.
Systems Perspective 10.4: FLOPs reduction is not proportional speedup
Reducing a model’s FLOPs by 50 percent does not guarantee 50 percent latency reduction. Memory-bound operations see little benefit from arithmetic reduction because data movement, not multiplication, sets their time. Amdahl’s law (principle 8) applies at the system level. If model inference accounts for only 20 percent of end-to-end latency (with the remaining 80 percent spent on data loading, preprocessing, and postprocessing), then even perfect model optimization yields at most 1.25× overall speedup. Tokenization and network transfer can occupy the non-model fraction in language-model serving; image decoding, resizing, and normalization can do the same in vision pipelines. Profile the complete path on target hardware before estimating optimization benefits.
Complementing latency and throughput profiles, layer-wise sensitivity analysis quantifies how individual layers tolerate perturbation. In deep networks, different layers tolerate very different amounts of precision reduction or weight removal. Profiling accuracy degradation while systematically perturbing one layer at a time, with quantization noise or weight removal, identifies which components require high-precision representations and which can absorb aggressive 4-bit quantization or structured pruning without compromising task accuracy. Once opportunity and sensitivity profiles have guided a compression pass, the resulting candidate must be evaluated across both statistical quality and physical execution metrics.
10.6.2 Measuring optimization effectiveness
Judging a compressed model by a single scalar metric—such as top-1 accuracy or parameter count—can approve a candidate whose batch-one latency barely budges under kernel-launch overhead or whose confidence calibration drifts past safety limits on rare subgroups. Evaluating compression requires balancing statistical quality against physical execution costs across the Data, Algorithm, and Machine (D·A·M) axes. Quality baselines must capture aggregate accuracy, confidence calibration (verifying that predicted probabilities reflect empirical correctness), and performance across underrepresented input slices. Simultaneously, efficiency baselines must record peak memory residency, latency distributions (including p99 tail latency), memory bus saturation, and per-inference energy.
ResNet-50, the camera pipeline’s teacher and the book’s compute-bound lighthouse, shows how one compression decision ripples across physical and statistical dimensions. Quantizing it from FP32 to INT8 on the reference H100 changes latency, throughput, artifact size, energy, accuracy, and confidence calibration at once, and a deployment profile must report all six rather than an isolated accuracy number (table 13).
| Metric | FP32 baseline | INT8 result | Deployment reading |
|---|---|---|---|
| Top-1 accuracy | 76.1% | 75.8% (0.3 pp drop) | Aggregate accuracy mostly holds, but subgroup checks still matter. |
| Batch-one latency | 0.38 ms | 0.30 ms (1.3×) | Fixed per-request costs dilute the gain for one image. |
| Large-batch throughput | 15,200 img/s | 89,470 img/s (5.9×) | INT8 Tensor Cores pay off once arithmetic dominates. |
| Model size | 102.4 MB | 25.6 MB (4×) | The artifact becomes easier to cache, transmit, and deploy on edge. |
| Energy/inference | 46.1 mJ | 7.8 mJ (5.9×) | Assumes full board power at large batch; measure it directly. |
| Confidence-calibration error | 2.1% | 3.4% | Confidence calibration can drift even when accuracy looks acceptable. |
Converting weights to INT8 shrinks the artifact by 4× (from 102.4 MB to 25.6 MB), but the speed gain depends on how the model is served. At batch one, a compiled INT8 engine is only 1.3× faster than its FP32 counterpart (0.30 ms against 0.38 ms), because launch overhead, per-kernel floors, and the weight read form most of a single image’s time and shrink little with precision. At large batch the arithmetic dominates, and INT8 throughput of 89,470 img/s, as MLPerf Inference measured it, is 5.9× the modeled FP32 rate, a ratio between a measured rate and a modeled one from different software stacks. Energy per image follows throughput only if the board draws its full 700 W in both precisions; the 5.9× energy figure is that assumption, not a separate measurement. The runtime comparison in Inference Runtime Selection derives both latency figures from the same engine profile. While aggregate top-1 accuracy drops by only 0.3 percentage points (from 76.1 percent to 75.8 percent), confidence-calibration error (the gap between predicted probability and observed accuracy, distinct from the range calibration of quantization) increases from 2.1 percent to 3.4 percent. Post-quantization probability distributions drift, which can compromise safety-critical confidence thresholds even when top-1 classification accuracy appears preserved. Production deployment decisions require corresponding quality, latency, and energy measurements using a supported execution path on target hardware.
Suppose the application requires at least 75.5 percent top-1 accuracy and no more than 3.0 percent confidence-calibration error, measured with the same validation data and calibration metric as the profile. The INT8 candidate passes the accuracy limit but fails the calibration limit. Its modeled resource savings therefore do not justify acceptance. Retain the baseline for comparison, try confidence recalibration or a less aggressive quantization configuration, and repeat the quality checks before validating resource gains on the target runtime.

The INT8 candidate fails the calibration limit despite holding accuracy.
A deployment profile shows whether a compressed model meets its limits but not why it misses one. Explaining a failure such as the calibration miss above requires looking inside the model, at where clipping, rounding, and pruning masks have changed its internal values.
10.6.3 Diagnostic visualization
When an exported model fails a quality or latency gate—like the ResNet-50 candidate whose confidence calibration drifted to 3.4 percent—summary metrics cannot tell whether the culprit is a single activation channel saturating its clipping bounds, a pruning mask erasing an active feature detector, or an unsupported operator falling back to floating point. Diagnostic inspection looks inside the compressed graph to verify numerical integrity after framework APIs calibrate the model and hardware optimization libraries lower it to the execution substrate (section 10.5.4). While system-scale validation and artifact monitoring belong to downstream deployment infrastructure, the immediate diagnostic task is verifying that quantization clipping, pruning masks, or sparsity patterns have not perturbed internal feature distributions beyond acceptable task error tolerances.
Quantization error histograms show whether error is broadly distributed or concentrated in outliers. Activation visualizations help detect clipping, overflow, and saturation. In a grid of first-layer convolutional filters, the top rows show distinct edge, color, and frequency detectors, while the bottom row shows uniform-looking filters that appear redundant at a glance but require measured activation tracing before they can be pruned safely (figure 31). Framework observers and debuggers can expose quantization ranges and tensor error, while compiler or runtime inspectors can show the graph and kernels that the exported model actually executes.
Sparsity diagnostics identify candidate layers for sparse execution. The layer-wise schematic in figure 32 spans convolutional, fully connected, and transformer layer types and is not a measurement from one model or pruning run. Its rows illustrate how a pruning policy might distribute zeros unevenly across architectural blocks. A real diagnostic would pair each layer’s density with its storage format and target-kernel profile to determine whether those zeros reduce memory traffic or execution time. Graph viewers and sparsity inspection tools help locate the affected tensors; profiling establishes the deployment benefit.
The diagnostic value is the nonuniformity, not the exact shade of any one cell. Greater sparsity in later layers shows where the policy removed weights; it does not establish that those representations were redundant. Compare task quality after removing weights from a candidate layer and after recovery training, including performance on important input slices. Early-layer sparsity warrants the same checks because damaging feature extraction can propagate through subsequent layers. Only those comparisons can establish whether the observed removal pattern preserves required behavior. Each density also has a machine reading, because a layer whose zeros never cross the storage and execution break-even of section 10.4.2.2 saves neither bytes nor time, however dark its tile.
Checkpoint 10.5: From compression claim to deployment evidence
A compressed artifact must pass the same application requirements as its baseline.
Implementation tools make compression repeatable, but they do not make the trade-offs disappear. Pruning alters model structure or parameter count, quantization changes numerical representation, and distillation trains the smaller artifact against a teacher’s output distribution, and composing them unmeasured can produce latency regressions or silent accuracy collapse on target hardware. The methodology that makes a measured gain trustworthy, from benchmark design to the statistics of repeated runs, is developed in Benchmarking. The fallacies that follow collect the places where intuitive compression assumptions fail.
Self-Check: Question
A profile of a ViT-Base-sized model shows that the MLP blocks carry nearly two-thirds of FLOPs and the query, key, value, and output projections just under one-third, while layer normalization contributes almost no FLOPs yet claims a visible share of wall-clock latency. What is the primary systems lesson this profile teaches?
- Optimization should focus exclusively on layer normalization because its latency share exceeds its FLOP share
- A single global optimization technique (such as uniform pruning) must be applied equally across all layers to ensure balanced execution
- Theoretical FLOP count is perfectly correlated with wall-clock execution time across all transformer layer types
- Different components exhibit distinct physical bottlenecks, so optimization must be component-specific rather than uniform across the whole model
An engineering team reports that an INT8-quantized ResNet-50 model maintains top-1 validation accuracy within \(0.2\%\) of its FP32 baseline on ImageNet. Explain why this metric alone is insufficient to certify the model as deployment-ready, identifying at least three additional critical measurement axes required by the chapter.
True or False: If an INT8-quantized classifier achieves the exact same top-1 accuracy as its full-precision baseline, its output probability distributions and confidence calibration are guaranteed to be equally reliable for downstream safety thresholds.
In PyTorch and TensorFlow quantization toolkits, ____ nodes are temporarily attached to tensor edges during calibration or Quantization-Aware Training (QAT) to collect running statistics (min/max or histograms) and compute scale and zero-point parameters without altering the forward-pass numerical values.
10.7 Fallacies and Pitfalls
A team deploying GPT-2 XL on a phone might find that an uncalibrated 4-bit quantization cuts weight memory by 4\(\times\) while generation quality collapses. Conversely, a vision team might achieve 70 percent weight sparsity through unstructured pruning only to find inference latency increases because commodity GPU kernels cannot execute irregular sparse indexing. Model compression presents numerous counterintuitive traps where theoretical parameter or FLOP reductions fail to produce wall-clock speedups. The following fallacies and pitfalls examine where standard engineering assumptions break down across the model-runtime interface.
Fallacy: Optimization techniques can be applied independently without considering their interactions.
Engineers assume optimization strategies compose additively: 50 percent pruning plus 4× quantization yields combined benefits. In reality, techniques interact nonlinearly and compound losses. In a representative BERT-style compression scenario, pruning to 70 percent sparsity may preserve most task performance, but applying INT8 quantization afterward can lose more accuracy than QAT on the pruned model. Knowledge distillation from heavily pruned teachers can also transfer degenerate attention patterns that reduce student accuracy compared with distilling from dense teachers. As section 10.5.3 demonstrates, successful optimization requires coordinated application where techniques are sequenced together.
Pitfall: Assuming theoretical metrics or compression ratios translate directly into proportional deployment speedup.
Teams frequently reduce FLOPs or parameter counts substantially without realizing proportional latency gains on physical hardware. In one representative trace, a pruned model with 40 percent fewer parameters achieves only a 12 percent latency reduction because irregular sparsity prevents efficient execution. Similarly, reducing a transformer from 440 MB to 110 MB through INT8 quantization yields a 4× raw weight-payload reduction, yet format conversion and scalar fallback on hardware without a native low-precision datapath erode the latency gain. In the chapter’s illustrative composed pipeline combining 50 percent structured pruning and INT8 quantization, the realized speedup reaches only 1.5× against an 8× paper target. Measure wall-clock latency on the target execution units rather than extrapolating from nominal compression ratios.
Fallacy: Aggressive quantization maintains model performance with minimal accuracy loss.
Engineers assume quantization error scales uniformly with bit width. In practice, precision reduction can show threshold effects, and the threshold depends on the model, layer, quantizer, calibration, and training method. The ResNet and BERT values in this chapter are illustrative rather than universal degradation bands. Even operations such as LayerNorm and Softmax can be implemented with integer approximations, so they do not universally require FP16; whether a low-precision implementation preserves task quality must be measured. As section 10.3.3 demonstrates, mixed-precision approaches can retain higher precision where uniform quantization fails.
Pitfall: Defaulting to FP32 everywhere to avoid quantization risk.
FP32 uses twice the raw storage and bandwidth of BF16, but lower-precision execution does not automatically preserve convergence or accuracy. Mixed-precision training often retains FP32 accumulators or master weights and may require loss scaling, while inference precision must be validated per model and operator. The right question is what lowest precision preserves quality on the evaluation distribution and maps efficiently to the target hardware.
Fallacy: Post-training optimization is always enough.
Teams often begin with post-training quantization (PTQ) because it avoids retraining, and move to quantization-aware training (QAT) only when the PTQ artifact misses its thresholds. Post-training pruning and post-hoc distillation can likewise underperform training-aware schedules at aggressive sparsity or bit width. As detailed in section 10.3.3, the production threshold, not a presumption that either path is universally superior, governs the decision.
Fallacy: Sparse matrix representations always save memory and accelerate inference.
Sparse formats introduce coordinate metadata that erodes storage savings at moderate densities, as the 16-bit case of section 10.4.2.2 showed; 32-bit indices make the penalty larger. To represent \(\NonzeroCount\) nonzero values across \(\SparseMatrixRowCount\) rows, a coordinate list (COO) stores explicit coordinate tuples (row_idx, col_idx, value). For 32-bit floats and 32-bit integer indices, each nonzero element consumes 12 bytes (\(3\times\) a dense 4-byte FP32 entry), requiring greater than 66.7 percent sparsity just to break even on memory footprint. Compressed sparse row (CSR) eliminates redundant row coordinates by storing three arrays: values (\(\NonzeroCount \times 4\text{ B}\)), col_indices (\(\NonzeroCount \times 4\text{ B}\)), and row_pointers (\((\SparseMatrixRowCount+1) \times 4\text{ B}\)). Each nonzero entry costs 8 bytes (\(2\times\) a dense FP32 entry), requiring over 50 percent sparsity before the sparse structure consumes less memory than the original dense tensor; below 50 percent sparsity, CSR metadata expands the model’s memory footprint.
Execution faces similar break-even constraints. Converting tensors to sparse storage as soon as pruning creates zeros degrades latency if metadata decoding, irregular gather operations, and poor cache locality outweigh the saved arithmetic. No universal sparsity threshold exists, because tensor dimensions, sparse format, runtime kernel, batch size, and hardware architecture jointly govern whether sparse execution outperforms dense execution. Specialized formats such as 2:4 structured sparsity eliminate index arrays in favor of fixed 2-bit multiplexer metadata, providing an accelerator datapath that nearly halves weight traffic with minimal indexing overhead (section 10.2.1.3). Production workflows must therefore measure realized density and commit to a sparse representation only after verifying that the operational break-even threshold has been crossed on target hardware.
Self-Check: Question
Which statement best captures the chapter’s analysis regarding the interaction between multiple model compression techniques?
- Compression techniques compose strictly linearly, so combining a \(2\times\) pruning gain and a \(2\times\) quantization gain always yields a \(4\times\) latency reduction regardless of hardware
- Quantization is the only technique that interacts with other methods, while pruning and distillation can always be designed in isolation
- Compression techniques interact nonlinearly through shared hardware bottlenecks (cache capacity, memory bandwidth) and competing accuracy budgets; their combined efficacy depends heavily on pipeline sequencing and joint on-target validation
- Applying more than one compression technique is never recommended because accuracy degradation is always strictly additive
True or False: If a neural network’s parameter count is reduced by \(4\times\) via magnitude pruning, its deployed end-to-end inference latency on a standard mobile CPU is guaranteed to improve by approximately \(4\times\).
Explain two distinct hidden runtime overheads—such as dynamic dequantization on unsupported hardware and uncoalesced memory access from unstructured sparsity—that can cause a model with an \(8\times\) theoretical compression ratio to exhibit virtually no wall-clock speedup when deployed in production.
10.8 Summary
Model compression fits a trained model inside a deployment budget by working three tiers of one stack, the descent the chapter map laid out at the start (table 2). Structural optimization changes what the model computes, precision changes how each value is stored, and hardware implementation decides how efficiently the remaining operations execute. The running cases showed each tier where it matters most. The camera pipeline’s MobileNetV2 spends its frame budget on arithmetic, so channel pruning, distillation from a ResNet-50 teacher, and an INT8 path onto the phone’s integer accelerator are its levers. GPT-2 XL decoding spends its token on bytes, so INT4 weights raise its token rate by 3.1× on the same phone, and only when dequantization is fused into the matrix multiplication. The tiers can compound, but their gains do not multiply automatically. Pruning, distillation, and quantization together produce the illustrative pipeline’s 16× footprint reduction from 440 MB to 28 MB; metadata, unsupported operators, and hardware mapping determine the realized deployment gain. A parameter reduction approaches the same latency reduction only when the affected work is on the critical path and the runtime can exploit the new representation. Profile on target hardware, not paper metrics.
Data selection and model compression divide the efficiency work along the D·A·M axes. Data selection acts on the Data axis and lowers the cost of producing a model by spending compute only on examples that carry signal. Compression acts where Algorithm meets Machine and lowers the cost of running the model by reshaping its structure and numerics for the target. Whether those deployment savings become real speedups still depends on the hardware and runtime that execute the compressed model. The need for them does not fade, because the bitter lesson keeps growing the models that win benchmarks while the envelopes of phones and microcontrollers stay fixed.
The counting rules developed across the chapter fit on one page (table 14). Together they let an engineer bound what a compression plan can save before a model is profiled on its target.
| Quantity | Formula | Where derived |
|---|---|---|
| Nominal sparsity | \(\SparsityRatio= \frac{\Vert \ZeroEntryIndicator\Vert_0}{\WeightMatrixRowCount\times \WeightMatrixColumnCount}\) | section 10.4.2 |
| Low-rank storage | \(\WeightMatrixRowCount \FactorizationRank + \FactorizationRank \WeightMatrixColumnCount\) values in place of \(\WeightMatrixRowCount \WeightMatrixColumnCount\) | section 10.2.2.1 |
| Depthwise separable cost | \(1/\LayerOutputWidth + 1/\KernelSize^2\) of a standard convolution’s arithmetic | section 10.2.4.3 |
| Convolutional model scaling | \(\Operations\propto \LayerCount \cdot \WidthMultiplier^2 \cdot \InputResolution^2\) | section 10.2.4.2 |
| Affine scale and zero-point | \(\QuantizationScale= \frac{\ClippingRangeUpperBound- \ClippingRangeLowerBound}{2^\QuantizationBitWidth- 1}\), \(\QuantizationZeroPoint= \text{round}\left(\frac{-\ClippingRangeLowerBound}{\QuantizationScale}\right)\) | equation 1, equation 2 |
| Dequantization | \(\QuantizerInput= \QuantizationScale(\QuantizedIntegerCode - \QuantizationZeroPoint)\) | equation 4 |
| Requantization scale | \(\RequantizationScale= \frac{\WeightQuantizationScale \cdot \InputQuantizationScale}{\OutputQuantizationScale}\) | section 10.3.3.1.4 |
| Fused chain traffic | \(2\,\ChainedOperationCount \IntermediateTensorSize\) bytes unfused; \(2\IntermediateTensorSize\) fused | section 10.4.1 |
| Bandwidth-bound decode time | \(\DataVolume/\Bandwidth\) per token, where \(\DataVolume\) counts the weight bytes plus the KV-cache bytes | section 10.3.5 |
Key Takeaways: From benchmark winner to production model
- Compression spends surplus capacity: Production models trade unused parameters, precision, and capacity for latency, memory, power, or cost limits the deployment cannot violate. The target is an artifact that meets the deployment objective and all required quality and resource constraints.
- Savings multiply only when aligned: Structural pruning, distillation, quantization, and architecture changes can compound raw footprint reductions, as the modeled BERT mobile pipeline’s 16× ratio illustrates. The gain becomes real only when task quality holds and the resulting operators match the target runtime and accelerator.
- Precision is a deployment decision: Where the target runtime supports it, INT8 post-training quantization is a useful first experiment because it reduces raw FP32 weight payload by 4\(\times\) without retraining. QAT, distillation, or mixed precision become candidates when range calibration or layer sensitivity exposes unacceptable error.
- Hardware decides what a saving is worth: Unstructured sparsity and theoretical FLOP cuts do not imply latency gains unless kernels and memory layouts can exploit them. The chapter’s hypothetical 8× paper target vs. 1.5× realized outcome illustrates why target-hardware profiling is mandatory.
- End-to-end latency caps model wins: Compression reduces end-to-end latency only when it accelerates the critical path; capacity or energy savings can remain valuable elsewhere. When inference is 20 percent of total request latency, Amdahl’s law (principle 8) caps even perfect model acceleration at 1.25×, so preprocessing, dispatch, and data movement may be the true optimization target.
The techniques in this chapter differ in almost every detail, yet one rule runs beneath all of them. Each obtains a smaller, faster, or cooler model by giving up something else. Pruning gives up capacity, quantization gives up numerical precision, and distillation consumes training compute. Where the model holds no surplus to give up, task quality degrades instead. Apart from removing genuinely avoidable work, such as an unfused intermediate round-trip, compression does not make the work disappear; it moves cost or risk from one part of the system to another, and the hardware decides how much each move saves. A technique that helps on a phone can therefore be worthless on a data-center GPU. This is the conservation-of-complexity heuristic at the level of a single model. A production artifact is a model whose structure, representation, and execution path have been engineered together until they fit the silicon and application constraints that govern deployment.
What’s Next: From math to physics
These optimization techniques compress the model’s logic, reducing the work the algorithm asks the machine to perform. Whether less work becomes less time depends on the silicon that executes it, and this chapter repeatedly ran into the memory wall, the regime where fetching a weight costs more than computing with it. Hardware Acceleration starts from that wall and from the ResNet-50 INT8 profile that closed this chapter, and explains how GPUs, TPUs, and NPUs organize tensor units, systolic arrays, and tiered SRAM/HBM hierarchies to keep arithmetic fed, which is what decides whether a quantized or sparse representation actually runs faster.
10.9 Self-Check Answers
Self-Check: Answer
The chapter’s optimization framework organizes model compression along three abstraction levels. Which sequence matches the stack from most software-level to most hardware-level?
- Efficient numerics representation → efficient model representation → efficient hardware implementation
- Efficient hardware implementation → efficient model representation → efficient numerics representation
- Efficient model representation → efficient numerics representation → efficient hardware implementation
- Efficient hardware implementation → efficient numerics representation → efficient model representation
Answer: The correct answer is C. The framework moves from changing the model graph itself, to changing how surviving values are represented, to changing how the resulting graph executes on hardware. An ordering that starts with hardware implementation confuses abstraction level with execution chronology: hardware constraints guide all three levels, but the figure presents a stack, not a compulsory workflow.
Learning Objective: Identify the three abstraction levels in the chapter’s optimization framework from model representation down to hardware implementation
A \(7\text{-billion}\)-parameter language model in FP16 occupies \(14\text{ GB}\) of weight memory alone. The target deployment platform is a smartphone with \(8\text{ GB}\) of shared RAM. Explain how quantizing weights to INT4 addresses both the physical memory capacity ceiling and the memory-bandwidth bottleneck during autoregressive token generation.
Answer: INT4 cuts the raw weight payload from about \(14\text{ GB}\) in FP16 to about \(3.5\text{ GB}\), which can make the model a candidate for an \(8\text{ GB}\) phone where memory is shared with the OS, runtime, KV cache, activations, and metadata. In low-batch autoregressive decoding, latency can be dominated by streaming dense weights, so reducing weight bytes by \(4\times\) can reduce that weight traffic by about \(4\times\). The practical consequence is that INT4 can relieve both fit and bandwidth pressure, but it does not guarantee full runtime fit or a \(4\times\) end-to-end throughput gain because other memory and kernel costs remain.
Learning Objective: Apply capacity and bandwidth reasoning to evaluate when INT4 weight quantization is a strong candidate for edge LLM deployment
True or False: When a model cannot be deployed because its parameter footprint exceeds the device’s physical RAM capacity, operator fusion is an effective direct substitute for pruning or quantization.
Answer: False. Fusion primarily reduces intermediate-tensor traffic and launch overhead by keeping adjacent operations on chip. If the dominant problem is the raw weight footprint itself, fusion does not remove enough stored parameter bytes to substitute for pruning or quantization, though some parameter folding patterns such as batch normalization folding can slightly change stored parameters.
Learning Objective: Distinguish execution optimizations that reduce intermediate traffic from techniques that reduce the dominant stored weight footprint
A ____ is the memory, time, and energy that a target device grants to each result a model produces, and model compression is the work of bringing a trained model’s demands inside it.
Answer: deployment budget. Memory capacity bounds the bytes of weights and activations that can stay resident, a frame rate or token rate bounds the milliseconds available for each result, and a battery or thermal envelope bounds the joules each result may consume. A trained model’s demands were set by the accelerators it trained on, not by the device it must run on.
Learning Objective: Define the deployment budget and name the three resources it bounds.
Across the deployment contexts analyzed in the chapter, which platform most clearly makes model compression a feasibility requirement rather than mainly a throughput or cost optimization?
- TinyML microcontrollers, where SRAM and storage budgets are so small that some models cannot be placed at all without compression or redesign
- Cloud inference clusters, where only cloud systems face hard capacity limits and all smaller devices can compensate in software
- Autonomous edge servers, where continuous thermal throttling is preferred over changing the model
- Mobile smartphones, where unified memory architecture eliminates meaningful capacity constraints for large neural networks
Answer: The correct answer is A. TinyML devices can have only hundreds of kilobytes of SRAM plus separate flash or storage limits, so a model may simply not fit unless its weights and working set are reduced enough. Capacity limits also matter on mobile and cloud systems, but the chapter uses microcontrollers to illustrate the clearest hard feasibility boundary. Claims that only cloud has hard limits or that phone memory is effectively unconstrained contradict the section’s deployment-budget comparison.
Learning Objective: Compare deployment contexts to identify where compression is most directly required for basic model feasibility
A mobile video-conferencing feature requires \(30\text{ FPS}\) background segmentation, but baseline FP32 MobileNetV3 runs at only \(8\text{ FPS}\). Applying INT8 quantization accelerates the model to \(35\text{ FPS}\) with a minor \(0.4\%\) drop in mIoU, satisfying the shipping requirement. Which region of the chapter’s compression-accuracy Pareto frontier best describes this outcome?
- Region 1 (free lunch), because achieving 35 FPS proves that INT8 quantization incurs zero loss in segmentation boundary fidelity
- Region 3 (danger zone), because any reduction in numerical precision destabilizes temporal consistency in video processing
- An unfeasible operating point outside the Pareto frontier, because 35 FPS exceeds the maximum display refresh rate
- Region 2 (efficient trade), because a modest, acceptable drop in segmentation accuracy unlocks a 4.4× frame rate increase that satisfies the 30 FPS real-time shipping threshold
Answer: The correct answer is D. Region 2 (efficient trade) represents the practical operational sweet spot where an engineer trades a small, tolerable accuracy concession for a massive efficiency gain (\(8\text{ FPS} \to 35\text{ FPS}\)) that moves the application across a hard production requirement (\(30\text{ FPS}\)). Calling this a ‘free lunch’ overlooks that INT8 rounding introduces real numerical quantization error, while placing it in the ‘danger zone’ confuses a successful deployment trade-off with catastrophic accuracy failure.
Learning Objective: Classify real-world deployment trade-offs into the three characteristic regions of the compression-accuracy Pareto frontier
Self-Check: Answer
A team prunes ResNet-50 to \(50\%\) sparsity using unstructured magnitude pruning and observes only a \(1.1\times\) speedup on a commodity GPU. Switching to structured channel pruning at the exact same \(50\%\) sparsity yields a \(1.8\times\) speedup. Which systems mechanism best explains this difference?
- Structured pruning removes more total weight parameters than unstructured pruning at any given nominal sparsity percentage
- Structured pruning removes entire contiguous channels or filters, allowing smaller dense kernels to execute efficiently, whereas unstructured sparsity needs sparse storage, metadata, and irregular activation access
- Unstructured magnitude pruning requires zero retraining or fine-tuning, whereas structured channel pruning requires full retraining from scratch
- Commodity GPU memory controllers automatically coalesce random non-zero memory addresses into single-cycle burst transfers
Answer: The correct answer is B. Structured channel pruning produces smaller dense tensors that still map well to standard dense kernels. Unstructured sparsity can reduce nonzeros, but exploiting it requires sparse encodings and matching kernels, which add metadata handling, irregular activation gathers, and possible load imbalance. The idea that random sparse accesses are automatically coalesced ignores the execution problem the section emphasizes, and equal nominal sparsity does not mean structured pruning removes more weights.
Learning Objective: Compare structured and unstructured pruning in terms of how well each maps to efficient execution on commodity accelerators
Order the stages of finding a winning lottery ticket in a neural network according to the Lottery Ticket Hypothesis (LTH): (1) Reset surviving weights to their original initialization values (\(W_0\)), (2) Train the dense unpruned network to convergence, (3) Retrain the sparse subnetwork to convergence, (4) Prune the lowest-magnitude weights to create a sparse mask.
Answer: The correct order is: (2) Train the dense unpruned network to convergence, (4) Prune the lowest-magnitude weights to create a sparse mask, (1) Reset surviving weights to their original initialization values (\(W_0\)), (3) Retrain the sparse subnetwork to convergence. First, dense training allows gradient descent to differentiate parameter importance. Second, magnitude pruning isolates the most critical connections to form a binary mask. Third, resetting surviving parameters to their exact initial values (\(W_0\)) isolates the subnetwork’s topological initialization. Finally, retraining the sparse subnetwork validates whether it can match or exceed the original dense model’s accuracy.
Learning Objective: Design an experimental procedure that sequences the iterative steps used to evaluate winning lottery tickets under the Lottery Ticket Hypothesis
A team must compress a large transformer model for deployment across a fleet of commodity GPUs that lack dedicated sparse-matrix acceleration kernels. Which structural optimization technique is the strongest candidate for producing a smaller model that still executes efficiently on this hardware?
- Unstructured magnitude pruning, because sparse matrix multiplication routines run with zero memory overhead on all standard GPUs
- Extreme binary weight quantization, because 1-bit representations eliminate all memory traffic without degrading language model perplexity
- Knowledge distillation, because it transfers teacher behavior into a compact dense student architecture that runs well on standard dense GPU kernels
- Low-rank factorization without fine-tuning, because mathematical decomposition guarantees zero loss in representation capacity
Answer: The correct answer is C. Distillation trains a new compact dense student, so the deployed model can use ordinary dense kernels that commodity GPUs already execute efficiently. That makes it a strong candidate when sparse acceleration support is absent. Unstructured pruning still depends on sparse formats and kernels, low-rank factorization is an approximation rather than a zero-loss guarantee, and the section does not claim pruning can never remove layers or that binary quantization is broadly safe for this setting.
Learning Objective: Evaluate distillation as a structural optimization candidate when deployment hardware favors dense execution
A square weight matrix of size \(4096 \times 4096\) in a transformer layer is decomposed using low-rank factorization at rank \(r = 128\). Calculate the theoretical reduction factor in both parameter count and multiply-accumulate (MAC) operations, and explain what trade-off this structural approximation introduces.
Answer: The original matrix contains \(4096 \times 4096 = 16{,}777{,}216\) parameters (\(16.78\text{M}\) MACs per vector product). Factoring into two matrices of dimensions \(4096 \times 128\) and \(128 \times 4096\) requires \(2 \times (4096 \times 128) = 1{,}048{,}576\) parameters (\(1.05\text{M}\) MACs). This yields an exact theoretical reduction factor of \(\frac{4096^2}{2 \times 4096 \times 128} = \frac{4096}{256} = 16\times\) for both parameter storage and arithmetic operations. The trade-off is that factorization restricts the layer’s representational capacity to a low-dimensional subspace of rank 128, which can degrade model expressiveness and task accuracy unless recovered through subsequent fine-tuning, while introducing the runtime overhead of launching two consecutive matrix multiplication kernels.
Learning Objective: Calculate parameter and arithmetic reduction factors for low-rank matrix factorization and evaluate the resulting rank-capacity trade-off
An engineering organization is deciding between running a custom Neural Architecture Search (NAS) from scratch versus adopting an established NAS-discovered family (such as MobileNetV3 or EfficientNet). Which circumstance most strongly justifies investing in custom NAS?
- Novel or custom hardware accelerators with unique memory hierarchies or massive production deployment scale where small per-inference efficiency gains amortize large one-time search costs
- Standard GPU clusters running established vision benchmarks where off-the-shelf architectures like MobileNetV3 already fit latency budgets
- Rapid prototyping projects with a total engineering timeline under one week and fewer than 10 available GPUs
- Small-scale enterprise applications processing fewer than 1,000 queries per day on cloud instances
Answer: The correct answer is A. Custom Neural Architecture Search (NAS) incurs substantial compute expenditure (historically hundreds to thousands of GPU-days), making it justifiable primarily when targeting novel hardware accelerators whose physical constraints are not served by existing architectures, or when extreme deployment scale (billions of daily inferences) allows modest per-query latency and energy gains to rapidly amortize the upfront search cost. For standard hardware, existing NAS-designed architectures (e.g., EfficientNet, MobileNetV3) provide proven efficiency out of the box without incurring search expenses. Fast prototyping and low-volume applications cannot justify the substantial time and compute cost required by NAS.
Learning Objective: Evaluate the economic and architectural conditions that justify custom Neural Architecture Search versus adopting established efficient architectures
Compare one-shot pruning with an iterative schedule that removes 10 percentage points of the original weights in each of 8 rounds with recovery between rounds. Explain why staged recovery can help, and what controlled comparison is needed before concluding that the iterative schedule is better.
Answer: Iterative pruning removes capacity in stages, giving the surviving weights chances to recover after each cut, so it is often a strong candidate when high sparsity is the goal. For example, eight rounds of removing \(10\) percentage points of the original weights each can reach \(80\%\) total sparsity while interleaving recovery. But the chapter does not claim this always beats one-shot pruning at the same final target: the outcome depends on the recovery budget, architecture, and pruning procedure. The practical implication is to compare schedules fairly at matched recovery effort instead of assuming staged pruning is universally superior.
Learning Objective: Compare one-shot and iterative pruning while recognizing that recovery quality depends on schedule and recovery budget, not a universal rule
Self-Check: Answer
According to the chapter’s Horowitz energy constants, an INT8 integer addition consumes roughly \(0.03\text{ pJ}\) compared to \(0.90\text{ pJ}\) for an FP32 addition—a \(30\times\) energy reduction despite only a \(4\times\) reduction in bit-width. What explains this operation-level energy dividend?
- INT8 arithmetic eliminates the need for registers and ALU logic on the silicon die
- INT8 quantization automatically prunes zero-valued parameters before they reach the execution units
- The 8-bit integer adder circuit requires significantly fewer logic gates, capacitance, and switching energy per operation than a 32-bit floating-point adder with exponent alignment and normalization logic
- Floating-point operations require continuous synchronization with host CPU DRAM on every instruction
Answer: The correct answer is C. The \(30\times\) arithmetic energy disparity (\(0.03\text{ pJ}\) for INT8 add vs. \(0.9\text{ pJ}\) for FP32 add based on Horowitz constants) stems directly from silicon circuit complexity: an 8-bit integer addition requires a compact adder circuit with minimal logic gates and switching capacitance, whereas a 32-bit floating-point adder requires extensive barrel shifters for exponent alignment, mantissa addition, normalization, and rounding logic. Quantization does not eliminate ALU circuitry or prune parameters, nor does FP32 require host CPU synchronization.
Learning Objective: Explain the circuit-level physical mechanisms responsible for the energy efficiency advantage of INT8 arithmetic over FP32
In affine (asymmetric) quantization, the integer parameter ____ shifts the quantized grid so that real-valued zero maps exactly to an integer representation, ensuring that zero-padded tensor regions introduce no numerical bias.
Answer: zero-point. The zero-point (or zero point, \(Z\)) provides an integer offset that ensures the real floating-point value \(0.0\) is mapped precisely to an integer without rounding error, which is crucial for preserving exact zero representations in padded convolutional feature maps and ReLU activations.
Learning Objective: Calculate the zero-point parameter in affine asymmetric quantization to preserve exact zero representations
Order the stages of a standard post-training quantization workflow with static activation calibration: (1) quantize the finalized weights and export the deployment artifact, (2) run representative floating-point calibration inputs through the model and collect activation statistics, (3) choose activation clipping bounds from the collected statistics, (4) derive activation scales and zero-points from those chosen bounds.
Answer: The correct order is: (2) run representative floating-point calibration inputs through the model and collect activation statistics, (3) choose activation clipping bounds from the collected statistics, (4) derive activation scales and zero-points from those chosen bounds, (1) quantize the finalized weights and export the deployment artifact. Calibration data must be observed before clipping bounds can be chosen, and those bounds must be fixed before scales and zero-points can be derived. Export belongs last because the deployment artifact should reflect the completed quantization parameters rather than precede them. Swapping calibration with export would freeze an artifact before the activation ranges needed to define it were established.
Learning Objective: Sequence the main stages of static-calibrated post-training quantization from calibration through export
Compare two validation settings for low-bit quantization: (1) candidate INT4 weight-only quantization for autoregressive decoding when profiling shows weight traffic dominates, and (2) candidate low-bit quantization for large-batch training of the same model. Explain why these two settings require different validation conditions before concluding the quantization is worthwhile.
Answer: In low-batch autoregressive decoding, each generated token can be dominated by streaming dense model weights, so cutting weight bytes from FP16 toward INT4 can substantially reduce weight traffic and improve latency when the runtime has a matching kernel. The ideal bound is set by the weight-byte reduction, not an automatic \(4\times\) end-to-end speedup, because KV-cache traffic, activations, and dequantization overhead remain. Large-batch training is different: it is not automatically accelerated by weight-only INT4, because training is often compute-heavy and also requires a low-precision training recipe, supported execution units, and numerical validation rather than just compressing stored weights.
Learning Objective: Contrast why weight-only low-bit quantization is most compelling for weight-bandwidth-bound decoding rather than automatically for training
During post-training quantization of a convolutional network, activation profiling reveals that values are heavily concentrated near zero with a small set of extreme positive outliers. Which calibration strategy best preserves numerical resolution for the bulk of typical activations?
- Max-absolute-value calibration, because extending the quantization grid to include extreme outliers guarantees zero clipping error across all layers
- Uncalibrated uniform quantization, because activation distributions in neural networks always follow a perfectly uniform probability density
- Static symmetric quantization with range [-128, +127] mapped unconditionally to [-1.0, +1.0] across every layer
- Percentile or KL-divergence (entropy) calibration, which can clip extreme tails so more integer levels represent the dense bulk of activations
Answer: The correct answer is D. When a tensor has a dense bulk near zero plus a rare outlier tail, percentile or KL-based calibration can trade some clipping of that tail for better resolution where most values actually lie. A percentile method such as keeping \(99.9\%\) of values clips the remaining tail by design. That trade can improve typical representation quality, but it is not harmless by definition because rare outliers may still matter for task accuracy. Max calibration instead spends range on those extremes and can waste bins on mostly empty space.
Learning Objective: Compare calibration strategies for long-tailed activation distributions by analyzing the trade-off between clipping and resolution
A team quantizing a deep convolutional network finds that per-channel (filter-wise) quantization achieves significantly higher accuracy than per-tensor (layer-wise) quantization at the same INT8 bit-width. Which mechanism explains this accuracy advantage?
- Per-channel quantization eliminates the need to compute or store scale factors and zero-points
- Individual convolutional filters within a layer often exhibit drastically different weight magnitude ranges; per-channel quantization assigns an independent scale factor to each filter, preventing wide-range filters from degrading the precision of narrow-range filters
- Per-tensor quantization can only be executed on CPUs, whereas per-channel quantization is restricted to edge microcontrollers
- Per-channel quantization automatically converts float operations into sparse matrix multiplications
Answer: The correct answer is B. In deep convolutional neural networks, different filters within the same layer specialize in distinct feature patterns, often resulting in weight distributions with variances that differ by orders of magnitude. Under per-tensor (layer-wise) quantization, a single clipping range must encompass all filters, forcing narrow-distribution filters into a tiny subset of quantization bins. Per-channel (per-filter) quantization assigns an independent scale factor \(S_c\) and zero-point \(Z_c\) to each output channel, giving narrow-range filters finer numerical resolution when their ranges differ. This can explain the measured quality advantage, but scale metadata, kernel support, and the calibration policy still determine the deployment trade-off.
Learning Objective: Explain why per-channel quantization granularity preserves accuracy in convolutional networks compared to per-tensor quantization
Self-Check: Answer
A paper estimate predicts an \(8\times\) speedup for a compressed model under ideal assumptions, but the implementation measured on an unmodified GPU delivers only \(1.5\times\). Which statement best defines the role of hardware implementation in explaining this gap?
- It aligns computation graphs, memory access layouts, operator scheduling, and sparsity patterns with physical accelerator architectures so that theoretical compression can translate into measured wall-clock speedup
- It reduces the volume of training data needed to fine-tune compressed neural networks
- It eliminates all memory-bound operations by converting every neural network layer into a compute-bound GEMM
- It automates the hyperparameter tuning of learning rates and batch sizes during pretraining
Answer: The correct answer is A. Hardware implementation is the layer that determines whether compressed representations map to efficient kernels, memory layouts, and execution paths on the target accelerator. A paper target such as \(8\times\) can collapse to a much smaller measured gain when sparse patterns, metadata, unsupported kernels, or layout issues block efficient execution. The section’s example is illustrative rather than a guaranteed multiplication of pruning and INT8 effects, so the right lesson is to explain the measured gap, not to assume the paper ratio must appear in practice.
Learning Objective: Explain how hardware implementation determines whether theoretical compression savings become real speedups on target hardware
Operator fusion of Conv-BatchNorm-ReLU sequences produces substantial execution speedup on modern GPUs even though the fused kernel preserves the intended layer function. Which mechanism explains this latency reduction?
- Fusion reduces the total number of weight parameters stored in the convolutional layer
- Fusion retrains the network to use lower numerical precision during the forward pass
- Fusion skips zero-valued activation elements by converting dense tensors to sparse matrices
- Fusion executes convolution, batch normalization, and ReLU inside a single GPU kernel, keeping intermediate activations on chip and cutting intermediate-tensor traffic and launch overhead
Answer: The correct answer is D. Fusion helps by avoiding extra writes and rereads of intermediate activations and by reducing separate kernel launches. In the chapter’s idealized Conv-BN-ReLU accounting, the intermediate-tensor stream falls from six transfers to two, but that count excludes weights, auxiliary inputs, cache effects, and spills. The idea that fusion preserves exactly the same arithmetic is too strong: some patterns such as batch-normalization folding change the operation sequence while preserving the intended function within numerical tolerance.
Learning Objective: Analyze operator fusion as a reduction in intermediate-tensor traffic and launch overhead rather than a change in model structure
A compressed neural network achieves a \(50\%\) reduction in total floating-point operations (FLOPs), yet on the deployment accelerator, end-to-end inference latency decreases by only \(10\%\). Explain two distinct hardware and architectural mechanisms that cause this discrepancy.
Answer: First, Amdahl’s Law at the pipeline level limits overall speedup: if model execution accounts for only a fraction of the end-to-end request pipeline (with data ingestion, preprocessing, tokenization, and postprocessing consuming the remainder), accelerating model arithmetic yields a diminished system-level improvement. Second, within the model itself, many non-compute-intensive layers (such as LayerNorm, Softmax, residual additions, and activation functions) are memory-bandwidth bound or latency-bound rather than compute-bound; cutting FLOPs in the compute-heavy layers leaves memory-bound execution time largely unchanged, capping measured speedup.
Learning Objective: Explain why theoretical FLOP reductions fail to produce proportional latency gains using Amdahl’s law and memory-bound layer analysis
True or False: Commodity SIMD vector units automatically achieve proportional latency reductions on weight matrices with \(50\%\) unstructured sparsity because vector lanes automatically skip zero values without overhead.
Answer: False. A dense masked tensor still moves and processes zeros. To skip them, the runtime needs a compact sparse representation and a matching kernel, but that path adds metadata handling, irregular activation accesses, and possible load imbalance. Whether sparse execution wins depends on format, shape, batch size, and hardware; there is no universal sparsity percentage that guarantees proportional speedup.
Learning Objective: Reject the misconception that unstructured sparsity automatically accelerates dense SIMD hardware
A team optimizes a deep network for NVIDIA Ampere GPUs that feature hardware-accelerated 2:4 structured sparsity. Which compression strategy directly engages this dedicated accelerator capability?
- Unconstrained unstructured magnitude pruning, because maximum zero count always yields the highest speedup on Ampere
- Dynamic channel pruning that alters tensor shapes per batch, because Tensor Cores require dynamic input dimensions
- Structured 2:4 sparsity (exactly 2 non-zero values in every contiguous block of 4 elements), because Ampere Tensor Cores include a supported sparse path for that pattern
- Activation checkpointing, because recomputing intermediate activations during inference eliminates sparse matrix indexing overhead
Answer: The correct answer is C. Ampere’s sparse Tensor Core path is designed for the specific 2:4 pattern, where each group of four weights keeps two nonzeros. The chapter’s example uses compact metadata with 2 bits per retained position, so one 4-element group carries 4 bits of position metadata alongside the retained values. That structure can nearly halve weight traffic and offers up to a \(2\times\) sparse arithmetic-rate improvement, but it is not an end-to-end guarantee once the rest of the execution path is included. Arbitrary unstructured masks do not activate this fixed hardware path.
Learning Objective: Match NVIDIA Ampere’s 2:4 sparse acceleration path to the structured sparsity pattern it is designed to support
Self-Check: Answer
A deployment fails because the model’s static weight footprint alone exceeds the available memory or storage budget on the target device. Which optimization dimensions should an engineer prioritize first?
- Hardware implementation alone, because runtime execution scheduling determines disk and RAM consumption
- Operator fusion alone, because fusing layers eliminates static weight parameter matrices
- Increasing training batch size, because larger batches compress parameter representations during optimization
- Model representation (pruning, distillation) and numerical precision (quantization), because both directly target the byte footprint of the deployed model
Answer: The correct answer is D. If capacity is the binding constraint, the first useful levers are the ones that can reduce stored model bytes: changing the representation or reducing numerical precision. Quantization often gives the most direct byte reduction, while pruning or distillation can further reduce model size when they preserve acceptable quality. Hardware implementation still matters, but fusion cannot generally solve a dominant static-weight-capacity problem by itself.
Learning Objective: Identify which optimization dimensions most directly address a deployment bottleneck in memory or storage capacity
A \(13\text{-billion}\)-parameter FP16 language model fits on the target edge server only at short context, but the required production KV cache and workspace do not fit. Profiling that feasible short-context baseline shows autoregressive decoding is dominated by weight traffic. Which optimization is the most direct initial candidate to test?
- Weight-only INT4 or INT8 post-training quantization (PTQ), because it directly shrinks raw weight bytes and can reduce weight-bandwidth pressure if the remaining memory budget also fits
- Unstructured magnitude pruning with 90% target sparsity, because arbitrary sparse patterns run fastest on edge memory controllers
- Neural Architecture Search from scratch, because searching a new architecture is the fastest way to resolve an immediate deployment deadline
- LayerNorm operator fusion alone, because LayerNorm compute dominates total parameter storage in large language models
Answer: The correct answer is A. In the chapter’s small-batch decoding regime, fetched weights can dominate latency, so lowering weight precision is the most direct way to attack both raw model size and streamed weight traffic. INT4 quarters raw weight bytes relative to FP16, while INT8 halves them. That makes weight-only PTQ a strong initial candidate, but not an automatic fix: feasibility still depends on the rest of memory usage, and realized speedup depends on the runtime path and overheads. Unstructured pruning and LayerNorm fusion do not target the dominant weight-byte bottleneck as directly.
Learning Objective: Select weight-only post-training quantization as the strongest first candidate for a weight-bandwidth-bound LLM deployment
Order the stages of a practical compression decision procedure: (1) test a low-cost candidate and measure all relevant quality and resource constraints, (2) establish the binding constraint from a decisive capacity bound or from profiling a feasible baseline, (3) map that constraint to candidate optimization levers, (4) if the candidate fails, consider recovery training or a structural candidate appropriate to the failed constraint.
Answer: The correct order is: (2) establish the binding constraint from a decisive capacity bound or from profiling a feasible baseline, (3) map that constraint to candidate optimization levers, (1) test a low-cost candidate and measure all relevant quality and resource constraints, (4) if the candidate fails, consider recovery training or a structural candidate appropriate to the failed constraint. The team must first know what resource actually binds, then connect that diagnosis to plausible levers before choosing an initial candidate. Only after measuring the candidate against the deployment’s real constraints does it make sense to escalate. Swapping testing with diagnosis would risk optimizing for the wrong bottleneck, while swapping escalation earlier would spend retraining effort before the simple candidate was fairly evaluated.
Learning Objective: Sequence a conditional compression workflow from bottleneck diagnosis through candidate testing and escalation
The chapter’s illustrative BERT compression pipeline compresses a \(440\text{ MB}\) FP32 model down to \(28\text{ MB}\) (roughly \(16\times\)) by sequencing pruning, distillation, and INT8 quantization. Why do these techniques compound multiplicatively rather than substituting for one another?
- The techniques duplicate each other’s reductions, causing total compression to saturate at the performance of the single strongest method
- Pruning produces the smaller student graph, distillation recovers its quality at the same parameter count, and quantization reduces numerical bit-width per parameter; because these operate on orthogonal resource axes, their compression ratios multiply (\(4\times \text{ structural} \times 4\times \text{ precision} \approx 16\times \text{ total}\))
- Applying quantization automatically converts the pruned network into a student model without requiring teacher supervision
- Multiplicative gains occur only when the pipeline starts with operator fusion on uncompressed weights
Answer: The correct answer is B. The stipulated pruned graph has 27.5M parameters, one quarter of the 110M teacher. Distillation recovers quality at that count; INT8 then stores each weight in one byte instead of four. The raw payload falls from 440 MB to 27.5 MB (rounded to 28 MB), a 16× reduction. Fusion changes execution rather than supplying either weight-storage factor. These arithmetic savings do not guarantee latency gains.
Learning Objective: Explain why combining orthogonal compression techniques across structural and numerical dimensions yields multiplicative compression ratios
In a modeled scenario, one compression order loses \(0.6\%\) accuracy while the reversed order loses \(2.1\%\). Propose a plausible pruning-quantization interaction that could explain this gap, and state what a fair comparison should hold fixed before concluding the ordering matters.
Answer: The modeled result illustrates one plausible interaction: pruning changes the surviving weight and activation distributions, so quantization ranges chosen earlier may no longer match the final artifact well. Quantizing first can also distort the fine-grained information used by importance scoring. Pruning first preserves full-precision information during structure selection, after which calibration or retraining can target the pruned model actually being deployed. The practical implication is not that one ordering is universally best, but that schedules should be compared under matched recovery and calibration budgets because pruning and quantization interact through shared distributions.
Learning Objective: Analyze why pruning and quantization order can matter by changing the distributions seen by importance scoring and calibration
A measured compression-quality curve shows a clear knee: before it, each extra compression step saves substantial resource with small quality loss; after it, additional compression yields much smaller resource savings for noticeably larger quality loss. Explain how an engineer should use that knee when choosing an operating point for a deployment with explicit quality and resource constraints.
Answer: The knee marks the region where marginal savings start to shrink relative to the quality penalty, so it is a warning that the trade-off is worsening. For example, one deployment may stop near the knee if it already meets its memory or latency target there, while another may compress past it if stricter resource limits require that sacrifice. The practical implication is that the knee helps interpret the curve, but the chosen operating point must still be the one that satisfies the deployment’s stated quality and resource constraints.
Learning Objective: Explain how the knee of a measured quality-efficiency curve informs operating-point selection under explicit deployment constraints
An engineering team evaluates TensorFlow Model Optimization Toolkit (TFMOT) and PyTorch’s
torch.aoAPIs for a pipeline compressing hundreds of production models per month. What is the primary systems value these framework toolkits provide?- They eliminate the need for engineers to benchmark or validate models on physical target hardware
- They automate the insertion and state management of complex compression primitives—such as fake-quantization observers, dynamic range trackers, and sparsity masking hooks—making compression scalable and reproducible across hundreds of models
- They automatically discover optimal hyperparameter architectures from scratch without compute overhead
- They guarantee identical execution performance across all CPU, GPU, and TPU backends without requiring hardware-specific compilers
Answer: The correct answer is B. Production-grade model compression requires managing thousands of observer nodes, tracking dynamic activation ranges, inserting fake-quantization operators for QAT, and scheduling sparsity masks across training steps. Framework APIs (such as PyTorch
torch.aoand TensorFlow Model Optimization Toolkit) automate this tedious and error-prone structural plumbing, enabling scalable, reproducible compression workflows. They do not replace empirical hardware benchmarking, eliminate search compute, or bypass the need for hardware-specific runtime lowering.Learning Objective: Explain how framework-level optimization toolkits automate structural compression workflows while preserving the need for hardware-aware validation
A model is pruned and quantized inside a training framework, but the exported deployment shows almost no speedup on the target accelerator. Explain why a hardware-specific compiler or runtime is still needed, and why framework-level masks or fake-quant operations are not enough evidence of real acceleration.
Answer: Framework-level pruning masks and fake-quant or graph annotations do not by themselves create a fast execution path. A hardware-specific runtime or compiler lowers the exported graph to supported kernels, fuses adjacent operators, chooses hardware-friendly layouts, and maps low-precision or sparse patterns onto the target’s actual execution units. Some deployment stacks integrate compiler and runtime functions, but the key requirement is still proof that the exported path really executes the compressed form efficiently. The practical implication is that compression inside the framework can remain only a logical transformation until the deployment runtime proves that the exported operators, layouts, and kernels really exploit it.
Learning Objective: Explain why deployment compilers or runtimes are needed to convert framework-level compression into actual hardware acceleration
Self-Check: Answer
A profile of a ViT-Base-sized model shows that the MLP blocks carry nearly two-thirds of FLOPs and the query, key, value, and output projections just under one-third, while layer normalization contributes almost no FLOPs yet claims a visible share of wall-clock latency. What is the primary systems lesson this profile teaches?
- Optimization should focus exclusively on layer normalization because its latency share exceeds its FLOP share
- A single global optimization technique (such as uniform pruning) must be applied equally across all layers to ensure balanced execution
- Theoretical FLOP count is perfectly correlated with wall-clock execution time across all transformer layer types
- Different components exhibit distinct physical bottlenecks, so optimization must be component-specific rather than uniform across the whole model
Answer: The correct answer is D. The profile shows that FLOP-heavy components and latency-heavy components are not always the same. MLP and projection blocks dominate arithmetic work, while LayerNorm can consume noticeable time because it streams activations with low arithmetic intensity. The right response is heterogeneous optimization based on the bottleneck each component presents. A profiler showing high achieved arithmetic utilization in the heavy matmul region would further support a compute-focused intervention there, while LayerNorm may call for fusion or other memory-traffic reductions.
Learning Objective: Use layerwise profiling to choose bottleneck-specific optimizations instead of assuming one metric or one tactic fits the whole model
An engineering team reports that an INT8-quantized ResNet-50 model maintains top-1 validation accuracy within \(0.2\%\) of its FP32 baseline on ImageNet. Explain why this metric alone is insufficient to certify the model as deployment-ready, identifying at least three additional critical measurement axes required by the chapter.
Answer: Near-baseline top-1 accuracy says little about whether the compressed model meets deployment constraints. The chapter also requires measuring on-target latency, peak runtime memory rather than just artifact size, and energy per inference in joules or sustained power in watts. It also calls for checking calibration drift, because confidence quality can degrade even when accuracy looks stable. For example, with a \(75.5\%\) minimum top-1 accuracy and a \(3.0\%\) maximum calibration error, the modeled INT8 profile passes accuracy but fails calibration. Acceptance requires satisfying each stated limit; resource gains cannot compensate for a failed quality requirement.
Learning Objective: Identify the additional latency, memory, energy, and calibration measurements needed beyond top-1 accuracy to validate a compressed model
True or False: If an INT8-quantized classifier achieves the exact same top-1 accuracy as its full-precision baseline, its output probability distributions and confidence calibration are guaranteed to be equally reliable for downstream safety thresholds.
Answer: False. Top-1 accuracy counts correct argmax predictions; equal aggregate accuracy does not require the same examples to be correct. Even when every argmax prediction stays unchanged, quantization can alter logit magnitudes and output probabilities, changing confidence calibration. In safety-critical systems, an uncalibrated quantized model may output overconfident or miscalibrated probabilities despite maintaining identical top-1 accuracy.
Learning Objective: Compare top-1 classification accuracy with confidence calibration and probability reliability in quantized models
In PyTorch and TensorFlow quantization toolkits, ____ nodes are temporarily attached to tensor edges during calibration or Quantization-Aware Training (QAT) to collect running statistics (min/max or histograms) and compute scale and zero-point parameters without altering the forward-pass numerical values.
Answer: observer. Observer nodes (or observers / quantization observers / observer nodes) monitor tensor value distributions during calibration passes or QAT epochs, calculating scale (\(S\)) and zero-point (\(Z\)) values before being removed or converted into fixed quantization parameters during final graph freezing.
Learning Objective: Explain the role of observer nodes in collecting activation statistics and computing quantization parameters
Self-Check: Answer
Which statement best captures the chapter’s analysis regarding the interaction between multiple model compression techniques?
- Compression techniques compose strictly linearly, so combining a \(2\times\) pruning gain and a \(2\times\) quantization gain always yields a \(4\times\) latency reduction regardless of hardware
- Quantization is the only technique that interacts with other methods, while pruning and distillation can always be designed in isolation
- Compression techniques interact nonlinearly through shared hardware bottlenecks (cache capacity, memory bandwidth) and competing accuracy budgets; their combined efficacy depends heavily on pipeline sequencing and joint on-target validation
- Applying more than one compression technique is never recommended because accuracy degradation is always strictly additive
Answer: The correct answer is C. The chapter emphasizes that compression techniques do not operate in a vacuum: they share physical hardware resources (memory bandwidth, cache capacity, register pressure) and draw from the same underlying model error tolerance. For instance, aggressive pruning reduces the numerical headroom available for subsequent quantization, and uncoalesced sparse memory access can negate quantization bandwidth savings. Therefore, techniques interact nonlinearly and must be evaluated and validated jointly. Claiming linear composition ignores hardware realities, while declaring multi-technique pipelines unviable contradicts proven multiplicative compounding.
Learning Objective: Analyze how compression techniques interact nonlinearly through shared physical resources and joint accuracy budgets
True or False: If a neural network’s parameter count is reduced by \(4\times\) via magnitude pruning, its deployed end-to-end inference latency on a standard mobile CPU is guaranteed to improve by approximately \(4\times\).
Answer: False. A \(4\times\) parameter reduction does not imply a \(4\times\) latency reduction because sparse execution depends on layout, kernel support, tensor shape, and device behavior. On a standard mobile CPU, unstructured sparsity may still incur dense-like traffic or sparse-format overhead, and end-to-end latency also includes work outside the pruned layers.
Learning Objective: Reject the assumption that parameter-count reduction guarantees proportional end-to-end latency improvement
Explain two distinct hidden runtime overheads—such as dynamic dequantization on unsupported hardware and uncoalesced memory access from unstructured sparsity—that can cause a model with an \(8\times\) theoretical compression ratio to exhibit virtually no wall-clock speedup when deployed in production.
Answer: One hidden cost is conversion overhead: if an exported graph crosses unsupported low-precision boundaries, the runtime may insert extra quantize or dequantize work and additional launches, increasing traffic and synchronization instead of reducing them. A fused weight-only path may still save weight traffic, so the real question is what the deployed operator path actually does. A second cost is sparse-execution overhead: unstructured sparsity can require metadata, irregular memory access, and weak cache or SIMD utilization. The practical consequence is that theoretical compression must be validated against the actual exported kernel path, not inferred from bytes or nonzeros alone.
Learning Objective: Analyze how conversion overhead and irregular sparse execution can erase theoretical compression gains in deployment