6 Network Architectures
Purpose
Architecture stack focus for this chapter.
Why is choosing a neural network architecture an infrastructure commitment as well as a modeling decision?
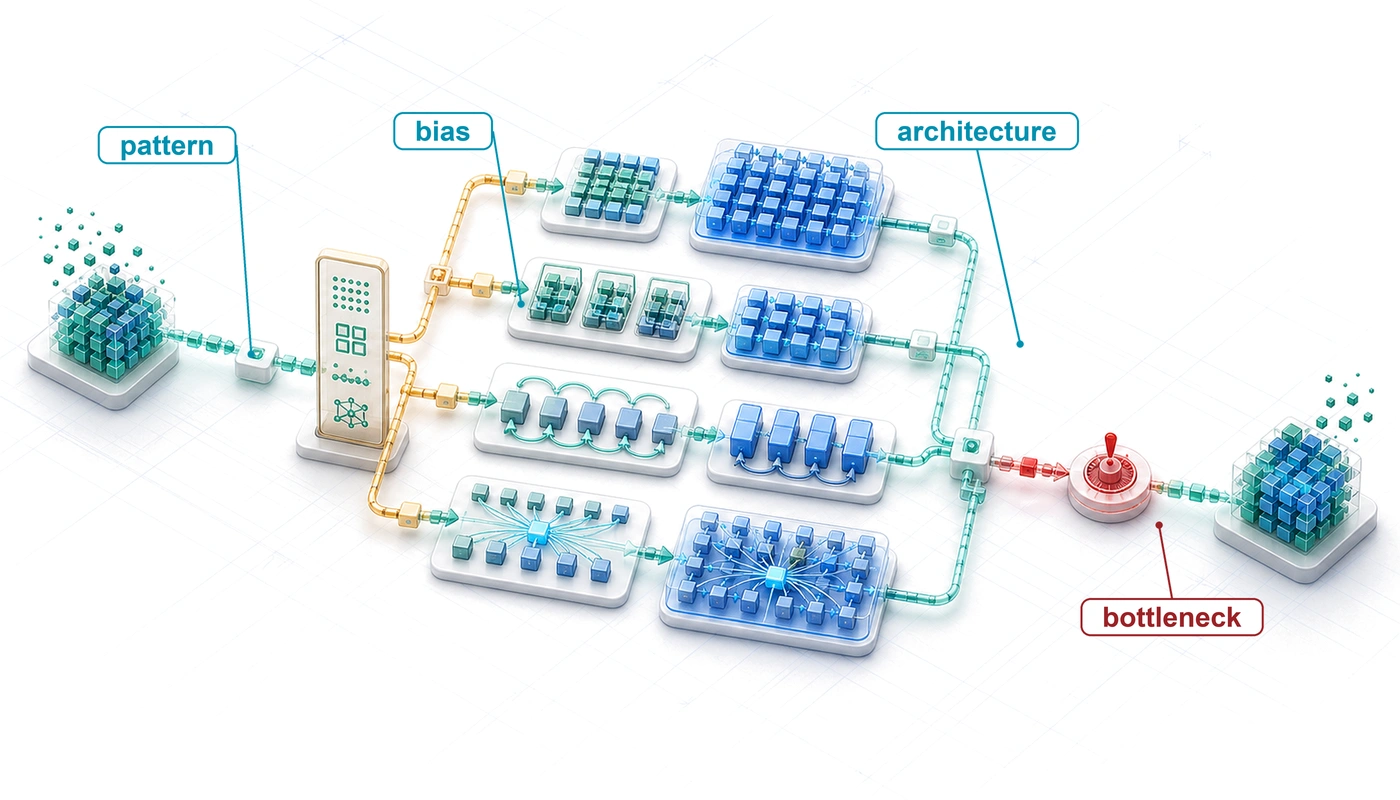
Selecting a neural network architecture is both a modeling decision and a contract with physics. The commitment begins with the structure in the data. An architecture that matches that structure can learn with fewer parameters and examples, while a poor match spends additional data and machine time compensating for the wrong computational pattern. Convolution, attention, recurrence, and embedding lookup do not merely encode different assumptions about data; they create different patterns of computation, state, and data movement. Those patterns determine whether work parallelizes cleanly, whether intermediate state fits in memory, and whether training and serving remain affordable at the required scale. Attention compares every element of a sequence with every other, so doubling the input length roughly quadruples that work, while the cost of a convolution grows in proportion to its input. Two architectures can deliver similar predictive quality yet impose different memory footprints and latency profiles while exposing different opportunities for later efficiency techniques. Benchmark accuracy alone therefore cannot reveal which design remains viable. Architectural commitments also propagate beyond the model. Data pipelines adopt particular input structures, training infrastructure is provisioned around the model’s compute profile, serving systems are tuned to its request path, and monitoring inherits its failure modes. Once those dependencies accumulate, replacing the architecture can mean rebuilding much of the surrounding system, a cost that grows with every month the design stays in service. An architecture decision is sound only when its predictive gains remain compatible with the full deployment context. In D·A·M terms, architecture is algorithm-machine co-design at its root, with the mathematical graph determining the work the machine must perform and the machine budget limiting which graphs remain practical.
Learning Objectives
- Explain how an architecture’s inductive bias matches the structure of images, sequences, and tabular data
- Distinguish how MLPs, CNNs, RNNs, transformers, and DLRM-style recommenders lower onto matrix multiplication and which operations remain memory bound
- Explain why skip connections and normalization make deep networks trainable and what each costs the machine
- Calculate the weights, multiply-accumulates, and memory of dense, convolutional, recurrent, attention, and embedding layers
- Analyze which iron-law term binds a workload, including transformer prefill and decode, from its arithmetic intensity
- Apply the architecture selection framework to a deployment’s data, memory, latency, and power budgets
- Critique architecture-selection fallacies about operation counts, context length, and training-versus-serving bottlenecks
Explore the concepts in this chapter
The volume’s concept map, opened on this chapter. Select a concept to read how it connects to ideas in other chapters. Open the full map ↗
6.1 Architectural Principles
Three requests reach the same accelerator: a camera frame for an image classifier, a prompt for a language model, and a click for a recommender. The silicon is identical, yet the first request keeps the arithmetic units busy, the second leaves them waiting on memory bandwidth, and the third cannot begin until the system decides where its multi-gigabyte embedding tables can live. What differs is the network architecture: how each model arranges the same arithmetic around the structure of its data.
Neural Computation built the operations that every network shares (matrix multiplication, activation functions, and gradient computation) and assembled them into a dense multilayer perceptron (MLP) that pays for a weight between every pixel and every hidden unit, including relationships an image rarely needs. Images have spatial locality, language has sequential dependencies, and tabular records often lack a fixed spatial or sequential organization. Architectures remove dense waste by arranging those shared operations into computational graphs shaped like the data. Under the silicon contract (principle 4), that graph is also an implicit agreement with hardware, making architecture selection a systems engineering problem that directly sets the iron law’s operations \(\Operations\) and data movement \(\DataVolume\). The structural assumptions that each architecture encodes are its inductive biases,1 and each family in this chapter is defined by the bias it chooses.
1 Inductive bias: From Latin inducere, “to lead into.” Encoding a structural assumption “leads” the model toward a smaller solution space, and every architecture discussed here (multilayer perceptron (MLP), convolutional neural network (CNN), recurrent neural network (RNN), and transformer) is defined by its choice of bias. A CNN’s locality bias cuts parameters by orders of magnitude vs. an equivalent MLP, directly shrinking the iron law’s \(\Operations\) and \(\DataVolume\) terms, while global attention trades quadratic score computation for long-range connectivity.
Definition 6.1: Inductive bias
Inductive bias is a structural constraint built into a model architecture that restricts the hypothesis space, enabling generalization from finite data by encoding domain-specific assumptions (such as spatial locality or sequential ordering) directly into the computational graph.
- Significance: Inductive bias can reduce the dataset size \((\DatasetSize)\) required for generalization. A detector that looks for a small pattern, such as an edge, can either give every pixel of the image its own weight or apply one small set of weights at every position. For a \(224{\times}224\) RGB image, a shared \(3{\times}3\) filter uses roughly 5,575× fewer parameters than one dense feature detector, reducing parameter storage and often the data required to avoid overfitting.
- Distinction: Unlike regularization (which penalizes hypothesis complexity at training time via L1/L2 terms), inductive bias restricts the hypothesis space at architecture design time, before any training begins.
- Common pitfall: A frequent misconception is that stronger inductive bias is always better. A strong locality bias (CNN) excels on spatial data but represents long-range dependencies in language less directly than global attention.

A stronger prior substitutes engineered structure for data and compute.
A convolutional neural network (CNN) encodes an inductive bias of spatial locality, assuming nearby pixels matter more than distant ones, whereas a transformer lets each element attend to any other at quadratic score-computation cost. Restricting the space of functions a model can represent lets it learn with less data and compute; relaxing those priors assumes that data and compute will grow large enough to compensate, which is the bitter lesson seen from inside a single architecture.
↩︎ The bitter lesson, that general methods which scale with computation outpace hand-built structure, is established in The Bitter Lesson.
That exchange sets up a core engineering trade-off between representational power vs. computational efficiency. Under the iron law of ML systems (principle 3), architectural choice is the primary determinant of the algorithmic work per sample (\(\text{FLOPs/Sample}\)), and thus of the operation-count term \(\Operations\): global attention buys long-range connectivity at quadratic score cost, while spatial locality keeps a CNN’s operations linear in the number of spatial positions. Architecture selection means matching the bias to the data while staying inside an operation budget, an ordering that section 6.9 turns into a selection procedure.
Choosing an architectural backbone sets the primary memory layout and compute pattern for downstream hardware. Table 1 contrasts the five major neural network families across the data structure each targets, its core innovation, and the system bottleneck it exposes in representative regimes.
| Architecture | Data Type | Core Innovation | System Bottleneck |
|---|---|---|---|
| MLPs | Tabular/Unstructured | Dense connectivity | Bandwidth with streamed weights at small batch |
| CNNs | Spatial (images) | Local filters + weight sharing | Compute throughput with sufficient reuse |
| RNNs | Sequential (time series) | Recurrent state | Sequential dependencies |
| Transformers | Relational (language) | Dynamic attention | Quadratic score compute; optional \(\SequenceLength^2\) storage |
| DLRM | Categorical (recommendations) | Embedding tables | Capacity when tables exceed device memory |
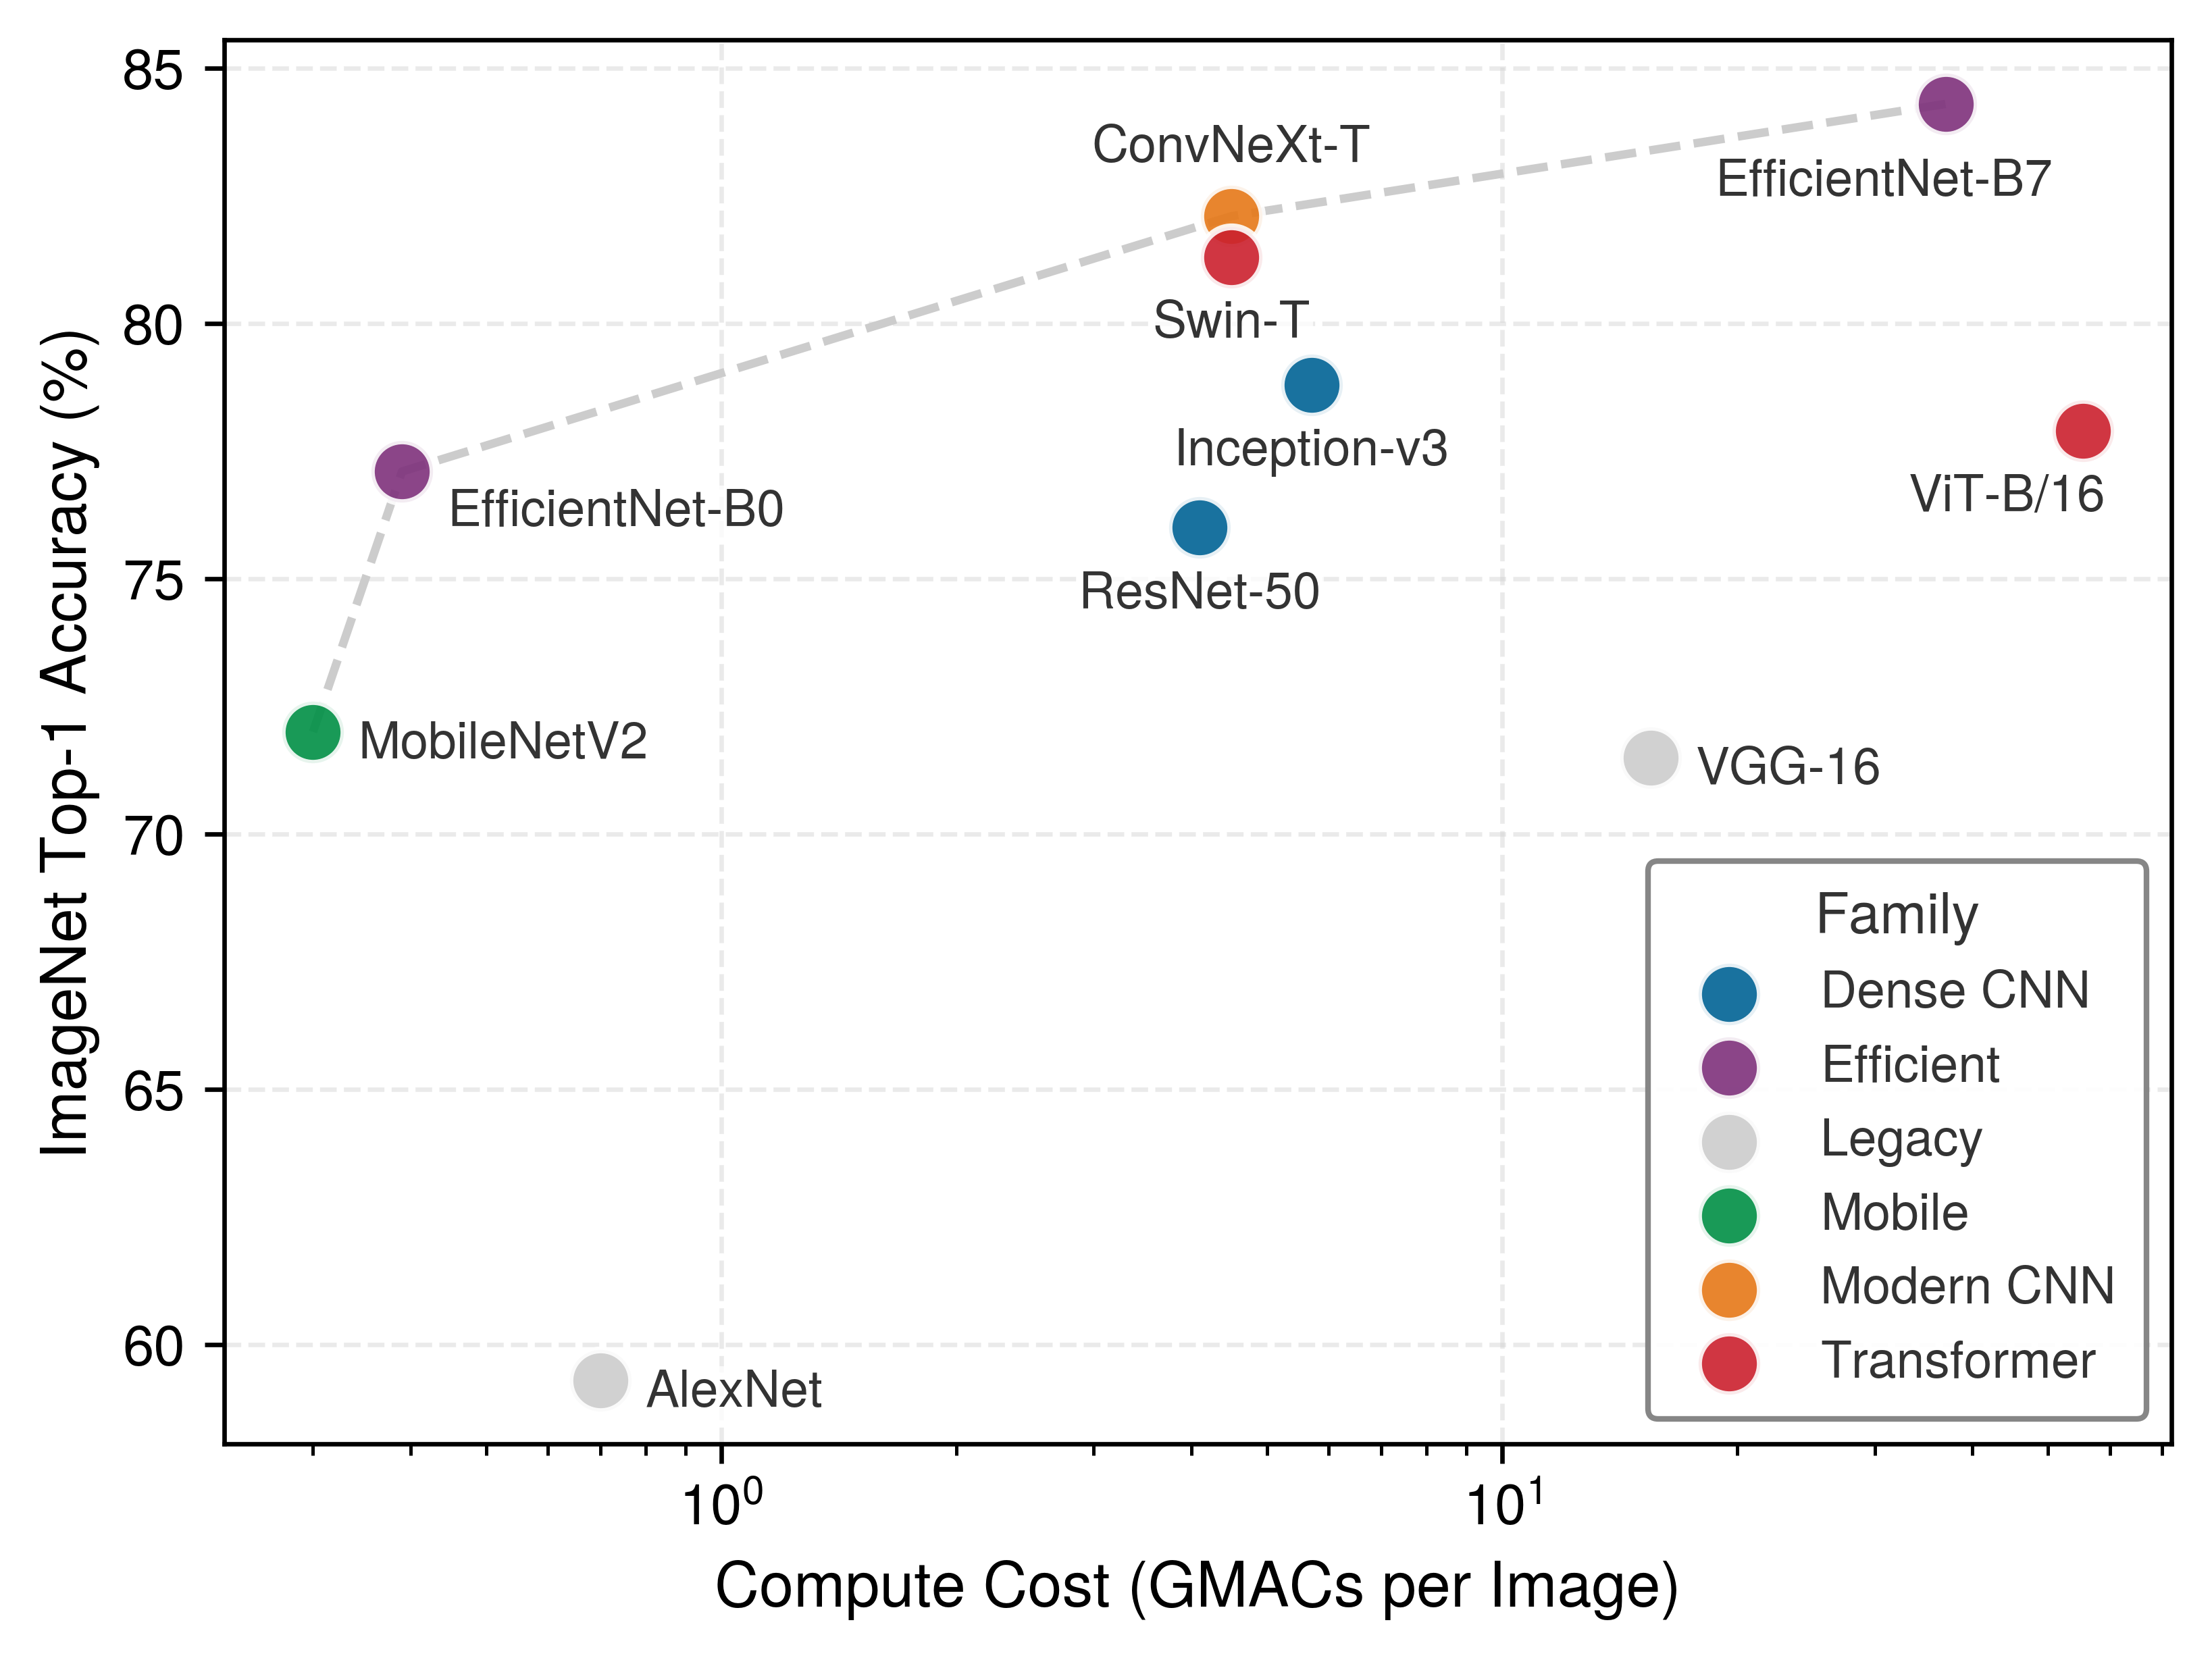
The five lighthouse models introduced with the iron law return here with their architectures exposed: ResNet-50 for compute throughput, GPT-2 for memory bandwidth, DLRM for memory capacity, MobileNetV2 for compute within a mobile power envelope, and keyword spotting (KWS) for an always-on power envelope. Earlier chapters used them as named workloads and mapped them onto workload archetypes (Workload archetypes), such as the compute-bound and bandwidth-bound archetypes. This chapter opens each one up inside the family that builds it, to show which architectural choice puts it in its archetype. MobileNetV2 sits on the empirical Pareto frontier plotted in figure 1, the set of models that no other plotted model beats on both accuracy and compute at once, while ResNet-50 sits well below it. The frontier bounds ImageNet2 top-1 accuracy against logarithmic compute cost, measured in GMACs (billions of multiply-accumulate operations) per image. The other three lighthouses sit off this plot because they were chosen for the bottlenecks they isolate rather than for image-classification accuracy.
2 ImageNet: The image-classification benchmark on which convolutional networks first proved themselves at scale. AlexNet’s 2012 victory in the ImageNet Large Scale Visual Recognition Challenge posted 15.3 percent top-5 error against 26.2 percent for the second-place entry, on the 1000-class challenge with roughly 1.3 million training images (Krizhevsky et al. 2012); the original ImageNet release contained 3.2 million images across 5,247 synsets (Deng et al. 2009). Subsequent architectures improved accuracy through changes in architecture, optimization, data, and compute budgets, illustrating the interaction between inductive bias and infrastructure cost.
Krizhevsky, Alex, Ilya Sutskever, and Geoffrey E. Hinton. 2012. “ImageNet Classification with Deep Convolutional Neural Networks.” Advances in Neural Information Processing Systems (NeurIPS) 25.
Deng, Jia, Wei Dong, Richard Socher, Li-Jia Li, Kai Li, and Li Fei-Fei. 2009. “ImageNet: A Large-Scale Hierarchical Image Database.” 2009 IEEE Conference on Computer Vision and Pattern Recognition, 248–55. https://doi.org/10.1109/cvpr.2009.5206848.
↩︎ The five lighthouse models, and the bottleneck each one isolates, are established in Lighthouse models put the iron law into practice.
Simonyan, Karen, and Andrew Zisserman. 2015. “Very Deep Convolutional Networks for Large-Scale Image Recognition.” arXiv Preprint.
Szegedy, Christian, Wei Liu, Yangqing Jia, Pierre Sermanet, Scott Reed, Dragomir Anguelov, Dumitru Erhan, Vincent Vanhoucke, and Andrew Rabinovich. 2015. “Going Deeper with Convolutions.” 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 1–9. https://doi.org/10.1109/cvpr.2015.7298594.
Sandler, Mark, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, and Liang-Chieh Chen. 2018. “MobileNetV2: Inverted Residuals and Linear Bottlenecks.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 4510–20. https://doi.org/10.1109/cvpr.2018.00474.
Tan, Mingxing, and Quoc V Le. 2019. “EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks.” International Conference on Machine Learning (ICML), 6105–14.
Liu, Ze, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, and Baining Guo. 2021. “Swin Transformer: Hierarchical Vision Transformer Using Shifted Windows.” 2021 IEEE/CVF International Conference on Computer Vision (ICCV), 9992–10002. https://doi.org/10.1109/ICCV48922.2021.00986.
Liu, Zhuang, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, and Saining Xie. 2022. “A ConvNet for the 2020s.” 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 11966–76. https://doi.org/10.1109/CVPR52688.2022.01167.
Across the frontier plotted in figure 1, successive architecture families occupy distinct computational cost regimes, from dense CNNs that prioritized accuracy regardless of operation count, through compact mobile networks engineered to minimize GMACs, to vision transformers (such as Swin-T and ViT-B/16) that trade compute for long-range spatial mixing. The plotted models are historical milestones rather than case studies; only ResNet-50 and MobileNetV2 receive detailed architectural breakdowns in this chapter. Architectural choices made at design time dictate where a system lands along this frontier.
Each family section that follows reads its architecture through the same four questions: the data pattern it targets, the computation it performs, how that computation maps onto hardware, and the bottleneck it exposes. The sequence begins with the family that assumes the least about its data, the dense multilayer perceptron, then moves through spatial CNNs and the skip connections and normalization that make depth trainable, on to recurrent networks, the attention primitive and the transformers built on it, and sparse recommendation models, before the closing section compares all five families on one machine and turns the comparison into a selection procedure.
Self-Check: Question
A team must choose between an MLP and a CNN for classifying \(224 \times 224\) pixel RGB medical images. A single dense first layer would require \(224 \times 224 \times 3 = 150{,}528\) input weights per output unit (yielding roughly 150 million weights for a 1,000-unit layer), whereas a CNN uses a shared \(3 \times 3 \times 3\) filter (27 weights). Using the chapter’s framing of inductive bias, which statement best explains why the CNN is the superior starting point?
- The CNN is strictly more expressive than the MLP, allowing it to approximate non-continuous functions that the Universal Approximation Theorem forbids.
- The MLP is mathematically incapable of representing any 2D spatial feature mapping due to lack of convolutional instruction support.
- The CNN eliminates gradient descent during optimization because convolutional spatial filters are deterministic, handcrafted operators.
- The CNN’s spatial locality and weight-sharing prior directly matches image structure: convolution is translation equivariant, later pooling or aggregation can provide invariance for classification, and each feature detector uses far fewer weights than a dense detector.
Because an inductive bias restricts the hypothesis space to a smaller set of representable functions, machine learning systems engineers should always select the architecture with the strongest possible inductive bias for every workload.
Why does the chapter describe selecting a neural network architecture as ‘signing a contract with physics’ rather than merely selecting a mathematical modeling preference? Explain how architectural graph structure shapes or constrains the terms in the iron law of ML systems (\(T_{\text{exec}} = D_{\text{vol}}/\text{BW} + O/(R_{\text{peak}} \cdot \eta_{\text{hw}}) + L_{\text{lat}}\)) without making those terms fully fixed.
6.2 MLPs: Dense Pattern Processing
Assuming the least about the input means letting every feature interact directly with every hidden unit. The MNIST digit classifier of Neural Computation is the purest example of that dense processing: each of its 784 pixel inputs connects to every hidden unit, and each hidden unit connects to every unit in the next layer. The same all-to-all pattern suits tabular inputs, such as the sender reputation, link count, and keyword features a spam filter scores, where no feature has a fixed neighbor.
MLPs3 turn this minimal prior into an architectural rule: they impose no specific spatial or temporal connectivity pattern, allowing any input to relate to any output. That generality makes MLPs versatile across arbitrary feature combinations, though costly whenever the input carries geometric structure that a specialized operator could exploit. Their representational capacity is guaranteed by the universal approximation theorem (UAT)4 (Cybenko 1989; Hornik et al. 1989), introduced in Neural Computation, which proves that a sufficiently wide MLP with nonlinear activations can approximate any continuous function on a compact domain.
3 Perceptron: Formed from “perception” and the device suffix “-tron” (as in cyclotron and klystron), coined by Frank Rosenblatt (Rosenblatt 1957) for the atomic unit of neural computation: a weighted sum followed by a nonlinear activation, extending the earlier McCulloch-Pitts neuron. MLPs are composed entirely of these units arranged in fully-connected layers, so the efficiency of this single operation, a multiply-accumulate, determines system throughput. Modern accelerators execute over \(10^{14}\) of these operations per second, making the perceptron the computational primitive that the entire ML hardware ecosystem is optimized around.
Rosenblatt, Frank. 1957. The Perceptron: A Perceiving and Recognizing Automaton. Report Nos. 85-460-1. Cornell Aeronautical Laboratory.
4 Universal approximation theorem (UAT): This theorem establishes representational capacity for continuous functions on a compact domain, given suitable nonlinear activations. The systems-level catch is that the existence guarantee supplies neither an efficient training procedure nor a practical width for a particular task. For a generic smooth target with no further structure, the width needed to reach a fixed accuracy can grow exponentially with input dimension (the curse of dimensionality), which is why the guarantee alone says little about a \(256{\times}256\) image; useful structure in the target is what keeps practical networks small.
Cybenko, George. 1989. “Approximation by Superpositions of a Sigmoidal Function.” Mathematics of Control, Signals, and Systems 2 (4): 303–14. https://doi.org/10.1007/bf02551274.
Hornik, Kurt, Maxwell Stinchcombe, and Halbert White. 1989. “Multilayer Feedforward Networks Are Universal Approximators.” Neural Networks 2 (5): 359–66. https://doi.org/10.1016/0893-6080(89)90020-8.
Definition 6.2: Multilayer perceptrons
Multilayer perceptrons are feed-forward neural network architectures that apply fully connected layers in sequence, where every neuron in one layer connects to every neuron in the next, without imposing a specific spatial or temporal connectivity pattern.
- Significance: The lack of structural prior gives dense layers quadratic parameter scaling in layer width: a single layer mapping 1,024 inputs to 1,024 outputs requires 1,048,576 parameters and about 2.1 MB of weight memory in FP16. Every input gets its own weight to every output, which makes MLPs inefficient for high-dimensional structured inputs like images.
- Distinction: Unlike convolutional neural networks, which exploit spatial locality to reduce parameter count, MLPs treat all input elements symmetrically, making them the architecture of choice for tabular data where no spatial or sequential structure is present.
- Common pitfall: A frequent misconception is that MLPs are too simple to matter for complex tasks. Dense layers carry much of the arithmetic inside the most complex models: every transformer block contains a position-wise feed-forward MLP, and recommendation models such as DLRM run dense MLP towers on their features. The other families add structure around dense layers (weight sharing, recurrence, attention) rather than replacing them.
Universal expressive power, however, does not explain why deeper, more constrained architectures outperform dense layers on structured inputs.
6.2.1 Representation vs. learnability
Although the UAT guarantees that a wide enough MLP can represent any continuous function on a bounded domain, it gives no guarantee that gradient descent can find those weights from a finite dataset or fit the required width in memory. Representation capacity refers to the functions an architecture can express given unlimited resources, whereas learnability refers to whether gradient descent can find good weights given finite training samples and compute budgets. A function may be representable in theory yet unlearnable in practice; the manifold hypothesis,5 which holds that high-dimensional data lies near a much simpler low-dimensional surface, explains why real-world functions have structure that a well-matched architecture can exploit.
5 Manifold hypothesis: The assumption that high-dimensional data lies near a low-dimensional surface embedded within the full space; a \(256{\times}256\) image lives in a 65,536-dimensional space, but “valid cat images” may occupy a much smaller structured region. Learned representations can expose that structure. The systems consequence is a potential reduction in the data and computation needed for learning; useful structure can also take other forms, such as a target depending on only a few input features.
This distinction resolves the apparent paradox between universal approximation and architectural progress. Specialized architectures such as CNNs and their deep ResNet descendants improve learnability by embedding inductive biases that match the structure of the data, even when doing so restricts representational capacity. Two factors create this learnability gap:
- Sample complexity: The UAT bounds neither the training examples nor the width needed, and some function classes require widths that grow rapidly with input dimension. For \(28{\times}28\) images, an MLP receives 784 pixel values without built-in local connectivity or spatial weight sharing. It can learn spatial correlations, as the digit classifier of Neural Computation shows, but must learn relationships that a CNN encodes structurally. When those priors match the task, a CNN can reach a target accuracy with fewer examples and represent the function more compactly. The sample requirement depends on the target function, data distribution, and learning procedure.
- Optimization difficulty: Even when optimal weights exist, gradient descent may not find them. Without architectural constraints to regularize the search space, MLP loss surfaces contain many poor local minima and flat regions. Specialized architectures narrow the search space and introduce symmetries that gradient descent can exploit. The classic MNIST handwritten digit benchmark illustrates this gap between representation and learnability concretely.
Example 6.1: MNIST: Representation vs. learnability
Scenario: Classifying \(28{\times}28\) MNIST digits with a fully connected MLP vs. a CNN.
Diagnosis: Whole-network parameter counts depend mostly on width choices. The 784-128-64-10 MLP has 109,184 weights, fewer than the 421,408 of a small two-convolution CNN, whose dense classifier head holds 96 percent of them. The locality saving appears per feature detector. A dense unit learns one weight for every pixel, so 32 features cost 25,088 weights; a convolutional layer learns one \(3{\times}3\) filter per feature, 288 weights in total, and reuses each filter at all 784 positions. At equal feature count, the convolutional layer needs 87× fewer weights.
Systems lesson: Inductive bias buys parameter efficiency per feature and reuse per weight. Fewer weights per detector reduce the data needed to learn spatial structure, and each weight fetched from memory feeds hundreds of multiply-accumulates, which raises arithmetic intensity.
The learnability gap motivates the core design principle of this chapter: embed inductive biases that match data structure. Each architecture sacrifices theoretical generality for practical learnability. The No Free Lunch theorem6 (Wolpert and Macready 1997) formalizes this trade-off: the bias that helps one task may hurt another. A bias that ignores where a pattern appears in an image aids image classification but impairs tasks where absolute position matters, such as locating an object. Choosing an architecture means choosing a bias that fits the data.
6 No free lunch theorem: Wolpert and Macready’s 1997 result proved that no optimization algorithm outperforms random search across all possible problems: averaged over every conceivable function, all algorithms are equivalent. The ML systems consequence is that an inductive bias (locality, equivariance, attention) can improve performance on problems matching that bias while hurting performance when its assumptions do not hold, making architecture selection an engineering commitment to a problem class.
Wolpert, D. H., and W. G. Macready. 1997. “No Free Lunch Theorems for Optimization.” IEEE Transactions on Evolutionary Computation 1 (1): 67–82. https://doi.org/10.1109/4235.585893.
Appropriate inductive biases reduce parameter counts (enabling edge deployment), accelerate convergence (reducing training costs), and produce structured computation patterns that map efficiently to specialized hardware. The MNIST comparison earned its per-detector saving by matching architecture to data structure, not by shrinking the network. Understanding where dense connectivity remains necessary requires identifying the data patterns that lack structural shortcuts.
6.2.2 Pattern processing needs
In a tabular dataset such as customer records or a credit risk model, any input column (income, account age, or recent transaction count) can interact with any other, and the columns have no spatial neighbors or time order. Because the data carries no grid or sequence structure, the network cannot restrict computation to local windows or sequential steps. Every output neuron must be free to combine every input feature, leaving gradient descent to learn which connections matter.
Applying that same unstructured treatment to images explains why the MNIST MLP in example 6.1 needed so many weights per detector: flattening each \(28{\times}28\) image into a 784-element vector discards the two-dimensional grid, so the layer treats adjacent pixels and pixels on opposite corners identically. While this lets every hidden unit relate any pixel to any class, the network must rediscover spatial adjacency from scratch during training. That all-to-all requirement leads directly to the matrix operations that define the MLP.
6.2.3 Algorithmic structure
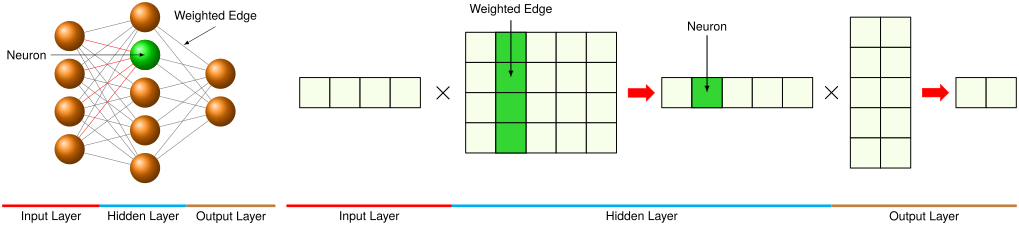
Letting every input feature interact with every output unit requires complete connectivity between adjacent layers. In an MLP, this takes the form of a sequence of fully connected layers where every neuron connects to every neuron in the preceding layer. Dense connectivity translates directly into matrix multiplication, the formulation that makes dense layers executable on parallel hardware. The fully connected graph on the left of figure 2 becomes the matrix-vector product on its right: each hidden neuron’s activation is the dot product of the input with one entire column of the weight matrix.
↩︎ The matrix multiplication formulation of a dense layer’s forward pass is established in Matrix multiplication formulation.
Reagen, Brandon, Robert Adolf, Paul Whatmough, Gu-Yeon Wei, and David Brooks. 2017. Deep Learning for Computer Architects. Synthesis Lectures on Computer Architecture. Springer International Publishing. https://doi.org/10.1007/978-3-031-01756-8.
Equation 1 expresses the dense layer’s affine transformation followed by its activation. \[ \HiddenActivation^{(\LayerIndex)} = \ActivationFunction\big(\HiddenActivation^{(\LayerIndex-1)}\WeightMatrix^{(\LayerIndex)} + \BiasVector^{(\LayerIndex)}\big) \tag{1}\]
\(\HiddenActivation^{(\LayerIndex)}\) represents the layer \(\LayerIndex\) output, \(\HiddenActivation^{(\LayerIndex-1)}\) represents the input from the previous layer, \(\WeightMatrix^{(\LayerIndex)}\) denotes the weight matrix for layer \(\LayerIndex\), \(\BiasVector^{(\LayerIndex)}\) denotes the bias vector, and \(\ActivationFunction(\cdot)\) denotes the activation function. The dimensions of these operations reveal the computational scale of dense pattern processing. The input vector \(\HiddenActivation^{(0)} \in \mathbb{R}^{\LayerInputWidth}\) (treated as a row vector in this formulation) represents all potential input features. Weight matrices \(\WeightMatrix^{(\LayerIndex)} \in \mathbb{R}^{\LayerInputWidth \times \LayerOutputWidth}\) capture all possible input-output relationships. The output vector \(\HiddenActivation^{(\LayerIndex)} \in \mathbb{R}^{\LayerOutputWidth}\) produces transformed representations. A four-pixel example turns this bookkeeping into arithmetic.
Example 6.2: Concrete computation example
Consider a simplified 4-pixel image processed by a 3-neuron hidden layer:
Input: \(\HiddenActivation^{(0)} = [0.8, 0.2, 0.9, 0.1]\) (4 pixel intensities)
Weight matrix: \[ \WeightMatrix^{(1)} = \begin{bmatrix} 0.5 & 0.1 & -0.2 \\ -0.3 & 0.8 & 0.4 \\ 0.2 & -0.4 & 0.6 \\ 0.7 & 0.3 & -0.1 \end{bmatrix}\quad (4{\times}3 \text{ matrix}) \]
Computation: \[\begin{gather*} \mathbf{z}^{(1)T} = (\mathbf{h}^{(0)}\mathbf{W}^{(1)})^T = \begin{bmatrix} 0.5{\times}0.8 + (-0.3)\times 0.2 + 0.2{\times}0.9 + 0.7{\times}0.1 \\ 0.1{\times}0.8 + 0.8{\times}0.2 + (-0.4)\times 0.9 + 0.3{\times}0.1 \\ (-0.2)\times 0.8 + 0.4{\times}0.2 + 0.6{\times}0.9 + (-0.1)\times 0.1 \end{bmatrix} = \begin{bmatrix} 0.59 \\ -0.09 \\ 0.45 \end{bmatrix} \end{gather*}\] After ReLU: \(\HiddenActivation^{(1)} = [0.59, 0, 0.45]\) (negative values zeroed)
Systems insight: Each hidden neuron combines all input pixels with different weights, demonstrating unrestricted feature interaction. Dense layers buy generality by paying the maximum connectivity cost.
The MNIST example makes this scale concrete. The 784-dimensional input connects to every one of the 128 neurons in the first hidden layer of the 784-128-64-10 network from Neural Computation. That layer is a \(784{\times}128\) weight matrix of 100,352 parameters, and each weight represents a learnable relationship between an input pixel and a hidden feature. This layer is the reference MNIST layer for the computational analysis in the rest of this chapter.
The matrix form specifies every input-output interaction, but it leaves the execution schedule open. Evaluating one sample at a time streams weights with little reuse; grouping samples lets several outputs share each fetched weight. The loop structure makes these alternatives visible.
6.2.4 Computational mapping
The layer equation fixes what a dense layer computes, not the order in which a processor computes it. At the framework level the whole layer is a single matrix call (listing 1).
def mlp_layer_matrix(X, W, b):
    """MLP forward pass using framework-level matrix operations."""
    # X: input matrix (batch_size by num_inputs)
    # W: weight matrix (num_inputs by num_outputs)
    # b: bias vector (num_outputs)

    # Single GEMM call: frameworks dispatch to optimized BLAS/cuBLAS
    # For MNIST: 784 * 128 = 100,352 MACs per sample
    H = activation(matmul(X, W) + b)
    return H
The function mlp_layer_matrix mirrors equation 1 directly, using high-level matrix primitives to express the forward transformation while delegating tile scheduling and execution to framework backends. Beneath this software interface, dense matrix multiplication lowers to a canonical three-deep loop nest that determines memory access locality, parallelization boundaries, and register allocation (listing 2). The outermost loop iterates across batch samples, the middle loop iterates over output neurons, and the innermost loop executes repeated multiply-accumulate (MAC) operations7 that pair each input feature with its weight.
7 MAC (multiply-accumulate): The atomic operation of neural networks: multiply two values and add to a running sum. In Horowitz’s 45 nm reference, an FP32 multiply plus add costs about 4.6 pJ, while a 32-bit off-chip DRAM access costs about 640 pJ (Horowitz 2014). These technology-specific values illustrate why data movement can dominate arithmetic energy; they are not universal constants for current hardware.
Horowitz, Mark. 2014. “1.1 Computing’s Energy Problem (and What We Can Do about It).” 2014 IEEE International Solid-State Circuits Conference Digest of Technical Papers (ISSCC), 10–14. https://doi.org/10.1109/isscc.2014.6757323.
def mlp_layer_compute(X, W, b):
    """Explicit loop structure exposing MLP computational patterns."""
    # Loop 1: Process each sample independently (parallelizable)
    for batch in range(batch_size):
        # Loop 2: Compute each output neuron
        for out in range(num_outputs):
            Z[batch, out] = b[out]  # Initialize with bias

            # Loop 3: Accumulate weighted inputs (innermost loop)
            # This is the MAC operation: result += input * weight
            for in_ in range(num_inputs):
                Z[batch, out] += X[batch, in_] * W[in_, out]
            # Total per output: num_inputs MACs +
            # num_inputs memory reads

    H = activation(Z)  # Element-wise nonlinearity
    return H
In the reference MNIST layer, computing 128 hidden neurons requires 100,352 MACs in total. Each individual output neuron requires 784 multiply-accumulate operations and 1,568 logical operand reads (784 for inputs, 784 for weights). Registers and caches can serve repeated reads, so this count is not a DRAM-traffic estimate. Production implementations call optimized matrix libraries such as Basic Linear Algebra Subprograms (BLAS),8 but the same nested-loop pattern still determines the system design problem. The hardware architectures that accelerate these matrix operations, including GPU Tensor Cores9 and specialized AI accelerators, are covered in Matrix operations hardware acceleration.
8 BLAS (basic linear algebra subprograms): This standard API for matrix operations enables the use of highly optimized libraries (for example, cuBLAS) to accelerate the 784 multiply-accumulates per neuron. The \(784{\times}128\) matrix in the MNIST example may use the hardware less efficiently than larger, well-aligned transformer matrices because utilization depends on matrix shape, batching, datatype, library, and accelerator.
9 Tensor Cores: Specialized units in NVIDIA GPUs that accelerate the thousands of multiply-accumulate operations described by fusing them into single, highly parallelized matrix instructions. Tensor Cores are most efficient when matrix dimensions meet datatype- and architecture-specific alignment multiples; modern cuBLAS/cuDNN can still use Tensor Cores for many nonaligned cases, often with lower efficiency or internal padding. The architectural lesson is vendor-independent: specialized matrix units reward dense, aligned general matrix multiplication (GEMM) workloads and penalize small, irregular shapes that cannot keep the units full.
6.2.5 System implications
While the reference MNIST layer \((784{\times}128)\) needs only 100,352 parameters, a single dense layer connecting 2048 inputs to 2048 outputs requires 4,194,304 parameters (16.8 MB at FP32), and evaluating one sample uses each weight only once. Because every input connects to every output, \(\mathcal{O}(\LayerInputWidth \times \LayerOutputWidth)\) weight storage dominates the memory footprint, and when those weights exceed on-chip cache and stream from DRAM on every request, memory bandwidth becomes the bottleneck. Dense layers therefore concentrate hardware pressure across three dimensions: memory capacity for weight storage, compute throughput on matrix engines, and memory bandwidth for weight movement.
The core computation is a dense matrix-vector product (GEMV), or a matrix-matrix product (GEMM) when batched. This computation is regular and parallelizable, but the arithmetic intensity (FLOP/byte) is low for small batches. A larger batch size amortizes weight-loading cost over more computations. Modern processors optimize dense layers with single instruction, multiple data (SIMD) units such as AVX-512 on CPUs. GPUs use dense matrix engines such as Tensor Cores, and Tensor Processing Units (TPUs) use systolic arrays10 (Jouppi et al. 2017). Each of these designs amortizes control overhead over large blocks of parallel arithmetic.
10 Systolic array: Named for the heart’s rhythmic contraction (Kung 1982), the array’s lockstep “pulse” of data through a grid of multiply-accumulate processors directly implements the data reuse that matrix multiplication and convolution require. By passing input values between neighboring processors, an expensive round-trip to off-chip DRAM is avoided for every single multiplication. This is critical for efficiency, because an off-chip memory access costs far more energy than the arithmetic it feeds.
Kung, H. T. 1982. “Why Systolic Architectures?” Computer 15 (1): 37–46. https://doi.org/10.1109/mc.1982.1653825.
Jouppi, Norman P., Cliff Young, Nishant Patil, David Patterson, Gaurav Agrawal, Raminder Bajwa, Sarah Bates, et al. 2017. “In-Datacenter Performance Analysis of a Tensor Processing Unit.” Proceedings of the 44th Annual International Symposium on Computer Architecture, ISCA ’17, 1–12. https://doi.org/10.1145/3079856.3080246.
Implementation and optimization considerations measured this weight-loading cost on the running network, where at batch one each weight read serves a single multiply-accumulate. For the reference layer, which reads \(784{\times}128\) weights to compute 128 hidden values, a weight-only model that counts one FP32 read per weight and omits input, output, bias, and cache traffic gives roughly 0.5 FLOP/byte at batch one. Equation 2 restates that ratio, where \(\LayerInputWidth\) and \(\LayerOutputWidth\) are the input and output widths. The memory tier serving those reads determines the relevant bandwidth. \[ \ArithmeticIntensity\approx \frac{2 \cdot \LayerInputWidth \cdot \LayerOutputWidth \text{ FLOPs}}{4 \cdot \LayerInputWidth \cdot \LayerOutputWidth \text{ bytes}} = 0.5 \text{ FLOP/byte} \tag{2}\]
If these weights stream from off-chip memory, a machine with an off-chip ridge point in the hundreds of FLOP/byte cannot supply them fast enough to reach peak arithmetic throughput. The small MNIST layer may instead remain cached across requests; its traffic must then be compared with the bandwidth of that cache, and dispatch overhead may matter more than off-chip bandwidth. Batching raises the weight-bound intensity in proportion to the batch size until input and activation traffic begin to dominate, but where it crosses the machine’s balance depends on matrix shape, precision, implementation, and hardware. This is why fully connected layers can become inference bottlenecks despite performing fewer total FLOPs than convolutional layers.
The same intensity sets the energy per inference. With the energy constants introduced alongside the iron law (Horowitz 2014), about 160 pJ per byte read from DRAM and 4.6 pJ per FP32 multiply-accumulate, a batch-one dense layer that streams its weights spends about 139× more energy moving each weight than computing with it. Batching divides that ratio by the batch size until activation traffic takes over, so the knob that raises throughput also cuts energy per inference.
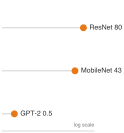
A batch-one dense layer sits far below convolution’s weight reuse.
Because dense connectivity offers little weight reuse within a single-example forward pass, applying MLPs to high-dimensional structured signals forces an undesirable trade-off between parameter explosion and memory starvation. When data possesses inherent physical organization (spatial coordinates in images, sequential order in time series), specialized architectures replace all-to-all connectivity with structural priors that simultaneously raise accuracy and computational efficiency. The most established of these spatial architectures is the convolutional neural network.
Self-Check: Question
A fully connected layer connecting 2,048 input units to 2,048 output units stores approximately 4.19 million weights (~16.8 MB in FP32). When applied to high-resolution image inputs, dense layers suffer severe parameter explosion. Which statement best captures the systems mechanism behind the MLP’s parameter and memory scaling?
- Dense layers use non-linear activations whose element-wise memory footprints dwarf the weight tensors by several orders of magnitude.
- MLP bias vectors grow quadratically with the output dimension, dominating total layer memory storage.
- The MLP encodes no specific spatial or temporal connectivity pattern, so every one of the \(d_{\text{in}}\) inputs can connect to every one of the \(d_{\text{out}}\) outputs, yielding \(\mathcal{O}(d_{\text{in}} \times d_{\text{out}})\) weights and, when weights stream for batch-1 inference, comparable weight-memory traffic per sample.
- Dense layers require storing three master copies of every weight matrix in hardware registers during inference forward passes.
A team cites the Universal Approximation Theorem (UAT) to argue that a wide 3-layer MLP should be used to classify \(256 \times 256\) RGB images instead of a CNN. Explain why UAT does not justify this design choice in practice, detailing both the statistical failure mode (sample complexity) and the systems failure mode (memory bandwidth and parameter explosion).
The ____ hypothesis states that high-dimensional real-world data (such as natural images) actually resides on a much lower-dimensional structured surface embedded within the full input space, helping explain why useful structure can be learned from finite data.
A single dense layer (\(2{,}048 \times 2{,}048\)) running FP32 inference on an A100 GPU at batch size 1 achieves only ~4% of peak compute throughput, with profilers reporting an arithmetic intensity of \(\approx 0.5\text{ FLOP/byte}\). What is the most effective engineering solution to move this kernel out of the memory-bandwidth-bound regime and raise hardware utilization?
- Increase the batch size (\(B > 1\)), transforming the matrix-vector multiplication (GEMV) into a matrix-matrix multiplication (GEMM), which amortizes weight loading across \(B\) samples and scales arithmetic intensity.
- Replace the dense matrix multiplication with an unvectorized scalar loop to avoid GPU kernel launch overhead.
- Upgrade to an accelerator with double the peak FP32 TFLOP/s while keeping the batch size at 1.
- Replace the linear transformation with an element-wise activation function to eliminate all weight memory traffic.
In the nested loop implementation of an MLP forward pass (
for batch,for out,for in_), calculate the exact number of multiply-accumulate (MAC) operations and logical operand reads required to compute 128 hidden neurons from a 784-dimensional MNIST input vector at batch size 1. In your count, treat the scalar loop as reading inputs and weights only, explicitly excluding bias traffic and output writes, and explain why this count is not the same as the number of DRAM transactions. Also explain how framework-level BLAS libraries optimize this pattern.
6.3 CNNs: Spatial Pattern Processing
The MLP’s assumption that every input may interact directly with every output proves particularly costly for spatially structured data like images. Connecting every pixel of a high-resolution input to every hidden unit creates a parameter footprint that exhausts accelerator memory and drives arithmetic intensity so low that the layer becomes bandwidth bound. The earlier MNIST comparison showed the remedy at small scale: a shared filter needs 87× fewer weights per feature detector than a dense unit that treats every pixel independently.
CNNs11 build that remedy into the network itself (Fukushima 1980; LeCun et al. 1998; Krizhevsky et al. 2012). Rather than materializing an all-to-all connectivity matrix, a CNN restricts each output activation to a local spatial patch and slides identical filter weights across the entire input aperture.
11 Convolution: From Latin convolvere (“to roll together”), describing a filter that slides across an input, combining local elements at each position. This “rolling together” enforces a locality constraint that is the source of the operation’s efficiency: a single \(5{\times}5\) kernel reuses its 25 weights at every spatial position instead of learning a separate weight for every pixel.
Fukushima, Kunihiko. 1980. “Neocognitron: A Self-Organizing Neural Network Model for a Mechanism of Pattern Recognition Unaffected by Shift in Position.” Biological Cybernetics 36 (4): 193–202. https://doi.org/10.1007/BF00344251.
LeCun, Yann, Léon Bottou, Yoshua Bengio, and Patrick Haffner. 1998. “Gradient-Based Learning Applied to Document Recognition.” Proceedings of the IEEE 86 (11): 2278–324. https://doi.org/10.1109/5.726791.
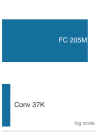
Weight sharing spares convolution the fully-connected parameter explosion.
This spatial inductive bias translates into two structural constraints on the computation graph. Parameter sharing applies the same small filter weights across every spatial position, reducing parameter storage from millions of distinct weights to a compact kernel that fits within on-chip caches. Local connectivity limits each neuron’s receptive field to a spatially adjacent neighborhood, eliminating computation on distant, uncorrelated pixels. Together, these constraints define the convolutional family.
Definition 6.3: Convolutional neural networks
Convolutional neural networks (CNNs) are architectures that exploit translation equivariance and spatial locality to share learned filters across all spatial positions, decoupling parameter count from input resolution.
- Significance: Weight sharing produces dramatic parameter reduction. A \(3{\times}3\) convolutional layer with 64 input and 64 output channels requires \(3 \times 3 \times 64 \times 64 \approx 37{,}000\) parameters regardless of whether the input image is \(224{\times}224\) or \(1024{\times}1024\). A fully connected layer mapping a \(224{\times}224{\times}64\) input to 64 scalar outputs would require \(224^2 \times 64 \times 64 \approx 205\) million parameters, a roughly 5,575\(\times\) difference. These output shapes differ: convolution reuses its 64 detectors across a spatial feature map, while the dense layer produces 64 scalars. Weight sharing keeps the filter budget constant as resolution grows, although feature-map storage still grows with image area.
- Distinction: Unlike MLPs, which connect every input element to every output element (global connectivity), CNNs restrict each output to a local spatial neighborhood, encoding the assumption that nearby pixels are more relevant than distant ones. This restriction eliminates entire hypothesis classes at architecture design time rather than penalizing them during training.
- Common pitfall: A frequent misconception is that CNNs are vision-only models. The convolution operation applies to any data with a grid-like topology: 1D convolutions process audio waveforms and time series, 2D convolutions process images and spectrograms, and 3D convolutions process video and volumetric data.
CNNs give up the all-to-all generality of MLPs for practical efficiency whenever data has local geometry. Seeing why that trade-off works on images begins with the spatial structure of a photograph.
6.3.1 Pattern processing needs
In a photograph, neighboring pixels carry closely related brightness and color values that together form local edges, corners, and textures, whereas pixels on opposite sides of the frame have almost nothing in common on their own. Stacking local filters lets a network build larger features out of smaller ones: early layers combine nearby pixels into edges, middle layers combine edges into contours and surface textures, and deeper layers assemble those patches into object parts and whole objects. From stage to stage the spatial grid shrinks while the number of channels grows, so each later feature summarizes a wider patch of the image, until the features flatten into one vector for a dense classifier (figure 3).
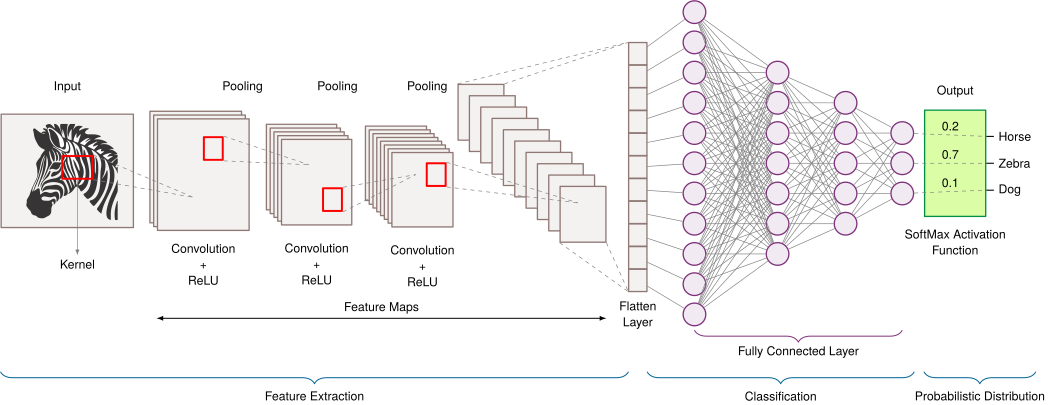
This hierarchical composition appears across multiple physical domains: localized pixel neighborhoods forming contours in computer vision, local time-frequency clusters identifying phonemes in speech spectrograms, and contiguous voxel blocks isolating tissue boundaries in volumetric tomography. The architecture works because images compose from local parts, whether or not it resembles biological vision.
In image processing, recognizing an object requires two distinct computational guarantees. First, the architecture must capture local geometric primitives over bounded receptive fields. Second, because an object retains its semantic identity regardless of where it appears in the frame, the network must identify those primitives across arbitrary coordinate translations. Convolutional networks satisfy both requirements by combining localized kernels with parameter sharing, enforcing translation equivariance at intermediate stages while pooling enables downstream invariance (LeCun et al. 1989; Krizhevsky et al. 2012).12 These architectural constraints, introduced by LeCun13 (LeCun et al. 1989), replace unconstrained dense matrix multiplications with structured spatial stencils.
LeCun, Yann, Bernhard Boser, John S. Denker, Donald Henderson, Richard E. Howard, Wayne Hubbard, and Lawrence D. Jackel. 1989. “Backpropagation Applied to Handwritten Zip Code Recognition.” Neural Computation 1 (4): 541–51. https://doi.org/10.1162/neco.1989.1.4.541.
12 Translation equivariance: An inherent property of the convolution operation where shifting the input guarantees a corresponding spatial shift in the resulting feature map. This is distinct from invariance, which pooling or later aggregation can approximate by discarding precise positional data. For example, \(2{\times}2\) pooling with stride 2 reduces the number of spatial elements by 75 percent.
13 Yann LeCun and LeNet: LeCun’s architecture directly addressed the intractable scaling of applying dense networks to images by enforcing the principles of local connectivity and parameter sharing. These constraints reduced the parameter count for an image-like input layer by over 95 percent, enabling LeNet-5 to achieve production-grade accuracy on commercial tasks like check reading with only ~60,000 total parameters.
6.3.2 Algorithmic structure
A convolutional layer’s weights form a four-dimensional tensor, and the reason is easiest to see by building one output feature in two stages, spatial filtering followed by channel accumulation. Consider a single RGB image with three input channels (\(\InputChannelCount= 3\)). A single output feature (such as an edge detector) requires its own dedicated \(\KernelSize{\times}\KernelSize\) spatial filter for the Red channel, another for Green, and a third for Blue:
- Spatial filtering: Each 2D filter slice slides across its corresponding color channel, computing multiply-accumulate dot products over local spatial windows as in a classic image filter.
- Channel accumulation: At each spatial coordinate \((\SpatialRowIndex, \SpatialColumnIndex)\), the dot-product outputs of all three input channels sum into a single scalar value.
This two-step process produces exactly one 2D output feature map. If the layer demands \(\OutputChannelCount= 64\) distinct features, the system repeats this procedure 64 times using 64 independent filter volumes. Thus, the weight tensor naturally requires four physical dimensions: \(\WeightMatrix\in \mathbb{R}^{\KernelSize\times \KernelSize\times \InputChannelCount\times \OutputChannelCount}\) (Kernel Height \(\times\) Kernel Width \(\times\) Input Channels \(\times\) Output Channels).
In formal terms, equation 3 evaluates this forward pass by computing local, channel-wise dot products across every spatial coordinate: \[ \ConvolutionActivation^{(\ell)}_{i,j,k} = \LayerNonlinearity\left(\sum_{\KernelRowOffset}\sum_{n}\sum_{\InputChannelIndex} \KernelWeight^{(\ell)}_{\KernelRowOffset,n,\InputChannelIndex,k}\ConvolutionActivation^{(\ell-1)}_{i+\KernelRowOffset,j+n,\InputChannelIndex} + \NeuronBias^{(\ell)}_k\right) \tag{3}\]
Here, \(\ConvolutionActivation^{(\ell)}_{i,j,k}\) denotes the activation at spatial position \((\SpatialRowIndex,\SpatialColumnIndex)\) in output channel \(\OutputChannelIndex\) of layer \(\ell\). The triple summation iterates across the filter dimensions: spatial offsets \((\KernelRowOffset,\KernelColumnOffset)\) span the local kernel window (defining the layer’s local receptive field),14 while \(\InputChannelIndex\) ranges over all input channels. The entries \(\KernelWeight^{(\ell)}_{\KernelRowOffset,n,\InputChannelIndex,k}\) of the weight tensor store the kernel weights connecting channel \(\InputChannelIndex\) to channel \(\OutputChannelIndex\), and \(\NeuronBias^{(\ell)}_k\) is the per-channel bias. Because the kernel weights \(\WeightMatrix^{(\LayerIndex)}\) do not depend on the spatial coordinates \((\SpatialRowIndex,\SpatialColumnIndex)\), the same filter parameters are reused at every coordinate.
14 Receptive field: The input region influencing a particular output neuron. With \(3{\times}3\) filters, receptive fields grow by 2 pixels per layer, so a neuron at layer 3 “sees” a \(7{\times}7\) region. This growth rate constrains architecture depth: detecting objects spanning 100+ pixels in a \(224{\times}224\) image requires either deep stacks of small filters (more layers, more memory for activations) or larger kernels (more parameters per layer), a fundamental depth-vs.-width trade-off in CNN design.
Wang, Zijie J., Robert Turko, Omar Shaikh, Haekyu Park, Nilaksh Das, Fred Hohman, Minsuk Kahng, and Duen Horng Polo Chau. 2021. “CNN Explainer: Learning Convolutional Neural Networks with Interactive Visualization.” IEEE Transactions on Visualization and Computer Graphics 27 (2): 1396–406. https://doi.org/10.1109/tvcg.2020.3030418.
Convolutional layers typically use small spatial kernels (\(3{\times}3\) or \(5{\times}5\)) to maintain compact parameter footprints while stacking layers to widen the effective receptive field. Each output activation depends on one small window of the input. In figure 4, a \(3{\times}3\) receptive field in a \(7{\times}7\) input produces one value of the \(5{\times}5\) output map, and sliding the same filter to every position fills in the rest. The interactive CNN Explainer tool (Wang et al. 2021) visualizes how these stacked sliding windows extract per-channel activation patterns across layers.
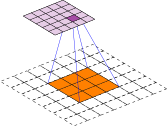
Applying a CNN to \(28{\times}28\) MNIST images demonstrates the difference in state representation. Rather than flattening the image into a 784-element vector that destroys spatial adjacency, each convolutional layer applies a bank of filters (for example, 32 filters of size \(3{\times}3\)) directly to the 2D grid. The stride is how many positions the filter moves between evaluations, and padding adds a border of zeros so that a filter centered on an edge pixel still has a full window. With unit stride and padding to preserve border dimensions, the layer outputs a \(28{\times}28{\times}32\) activation tensor preserving the spatial grid. Each coordinate holds 32 distinct feature measurements extracted from its immediate neighborhood. Between groups of convolutional layers, a pooling layer summarizes each small window, typically \(2{\times}2\), by its maximum or average. This shrinks the grid by a factor of four in area while keeping the channels, so later layers see a coarser map that covers more of the image at a quarter of the activation memory.
Preserving spatial topology changes how execution units access memory. Instead of loading an unshared weight matrix once per sample as in an MLP, a convolutional layer streams input feature maps through hardware registers while keeping compact filter weights pinned in fast on-chip SRAM or register files. This arithmetic pattern drives the memory-hierarchy optimizations of AI accelerators, where loop tiling (splitting the loops into blocks whose data fits on chip, developed under data movement below) and parallel channel reduction relieve high-bandwidth memory (HBM) traffic.
Weight sharing is what guarantees this reuse. Because the same filter applies at every coordinate, the computational schedule and memory access geometry are identical across spatial positions. The same sharing gives the layer a mathematical property, translation equivariance: translating the input produces an identical spatial translation in the output feature map.
Equivariance and invariance govern how an architecture responds to spatial transformations. An operator \(\LayerFunction\) is equivariant to a transformation \(\SpatialTransformation\) if transforming the input transforms the output by the same operator (equation 4): \[ \LayerFunction(\SpatialTransformation(\LayerInputVector)) = \SpatialTransformation(\LayerFunction(\LayerInputVector)) \tag{4}\]
For a stride-1 convolutional layer without boundary padding effects, translating the input by vector \(\TranslationVector= (\TranslationComponent_1, \TranslationComponent_2)\) shifts the resulting feature maps by exactly \(\TranslationVector\). Spatial coordinate information propagates deterministically through the layer. By contrast, an operator is invariant to \(\SpatialTransformation\) if transforming the input leaves the output unchanged (equation 5): \[ \LayerFunction(\SpatialTransformation(\LayerInputVector)) = \LayerFunction(\LayerInputVector) \tag{5}\]
A global average pooling layer over an entire feature map is translation-invariant: shifting the input alters the spatial locations of activations, but averaging across all spatial positions collapses coordinates into a scalar that is identical regardless of where the features appeared. This mathematical distinction dictates where equivariance must be maintained and where invariance should be introduced across the network hierarchy. Tasks such as object detection and semantic segmentation require equivariance through the final layer: bounding-box coordinates and per-pixel masks must track object coordinates precisely. Classification tasks, by contrast, require equivariance in intermediate feature extractors to preserve relative spatial relations (“eyes above nose”), while the final layers introduce translation invariance via pooling to collapse spatial coordinates into a class probability vector.
Re-indexing the convolution sum under a shift confirms that stride-1 convolution is translation equivariant up to boundary conditions. An equivariant convolutional layer preserves coordinate information, whereas an invariant pooling layer discards spatial coordinates entirely. Example 6.3 verifies this tracking through explicit matrix operations.
Example 6.3: Equivariance: Feature detection
Setup: Consider a \(7{\times}7\) image with a vertical edge at column 3: \[ \LayerInputVector= \begin{bmatrix} 0 & 0 & 1 & 0 & 0 & 0 & 0 \\ 0 & 0 & 1 & 0 & 0 & 0 & 0 \\ 0 & 0 & 1 & 0 & 0 & 0 & 0 \\ 0 & 0 & 1 & 0 & 0 & 0 & 0 \\ 0 & 0 & 1 & 0 & 0 & 0 & 0 \\ 0 & 0 & 1 & 0 & 0 & 0 & 0 \\ 0 & 0 & 1 & 0 & 0 & 0 & 0 \end{bmatrix} \]
Vertical edge detector filter: \[ \WeightMatrix= \begin{bmatrix} -1 & 0 & 1 \\ -1 & 0 & 1 \\ -1 & 0 & 1 \end{bmatrix} \]
Convolving original image:
Output feature map shows positive activation where the filter transitions from dark to bright (left side of edge) and negative activation where it transitions from bright to dark (right side): \[ \LayerFunction(\LayerInputVector) = \begin{bmatrix} 3 & 0 & -3 & 0 & 0 \\ 3 & 0 & -3 & 0 & 0 \\ 3 & 0 & -3 & 0 & 0 \\ 3 & 0 & -3 & 0 & 0 \\ 3 & 0 & -3 & 0 & 0 \end{bmatrix} \]
Shifted input (edge moved to column 5): \[ \SpatialTransformation_2 \LayerInputVector= \begin{bmatrix} 0 & 0 & 0 & 0 & 1 & 0 & 0 \\ 0 & 0 & 0 & 0 & 1 & 0 & 0 \\ 0 & 0 & 0 & 0 & 1 & 0 & 0 \\ 0 & 0 & 0 & 0 & 1 & 0 & 0 \\ 0 & 0 & 0 & 0 & 1 & 0 & 0 \\ 0 & 0 & 0 & 0 & 1 & 0 & 0 \\ 0 & 0 & 0 & 0 & 1 & 0 & 0 \end{bmatrix} \]
Convolving shifted image: \[ \LayerFunction(\SpatialTransformation_2 \LayerInputVector) = \begin{bmatrix} 0 & 0 & 3 & 0 & -3 \\ 0 & 0 & 3 & 0 & -3 \\ 0 & 0 & 3 & 0 & -3 \\ 0 & 0 & 3 & 0 & -3 \\ 0 & 0 & 3 & 0 & -3 \end{bmatrix} = \SpatialTransformation_2(\LayerFunction(\LayerInputVector)) \]
Systems insight: The feature activation shifts by the same amount as the input, demonstrating equivariance. The network knows the edge is at column 5 in the shifted image, not just that an edge exists somewhere.
Parameter efficiency is the most immediate systems consequence of the weight sharing that produces translation equivariance, because sharing decouples parameter capacity from the input resolution. For example, processing a \(224{\times}224\) RGB image with an MLP requires each hidden neuron to connect to all 150,528 input pixels. A CNN with a \(3{\times}3\) filter requires only 27 parameters per filter, reused across all \(224{\times}224\) spatial positions. A compact parameter footprint lets the weights stay resident in accelerator SRAM or L2 cache rather than streaming from external DRAM on every use.
Equivariance also increases sample efficiency, reducing training pipeline overhead. When a network updates a filter to recognize a feature at one coordinate, parameter sharing ensures that the feature is recognized across all spatial coordinates simultaneously. The model does not require separate training examples to learn the same feature at different pixel offsets, functioning as structural data augmentation. This sample efficiency reduces the total training iterations, dataset storage, and host-to-device I/O bandwidth required to reach target accuracy.
Convolution’s translation equivariance is one instance of a general principle: data symmetries can be embedded as equivariances in the architecture. Group-equivariant CNNs (Cohen and Welling 2016) extend the construction to rotations and reflections for satellite and medical imagery, where orientation does not determine meaning. For systems engineering, stronger symmetry constraints often produce smaller models, but specialized equivariances may require custom operations, such as rotation convolutions, that need either hardware support or efficient software implementations.
Cohen, Taco, and Max Welling. 2016. “Group Equivariant Convolutional Networks.” Proceedings of the 33rd International Conference on Machine Learning (ICML) 48: 2990–99.
Bengio, Yoshua, Aaron Courville, and Pascal Vincent. 2013. “Representation Learning: A Review and New Perspectives.” IEEE Transactions on Pattern Analysis and Machine Intelligence 35 (8): 1798–828. https://doi.org/10.1109/tpami.2013.50.
Zeiler, Matthew D., and Rob Fergus. 2014. “Visualizing and Understanding Convolutional Networks.” European Conference on Computer Vision (ECCV), 818–33. https://doi.org/10.1007/978-3-319-10590-1_53.
A single equivariant stencil sees only its \(\KernelSize{\times}\KernelSize\) window, so CNNs build the edge-to-object hierarchy of figure 3 by stacking layers (Bengio et al. 2013; Zeiler and Fergus 2014). With fixed \(\KernelSize{\times}\KernelSize\) kernels and unit stride, each added layer widens the effective receptive-field side length by \(\KernelSize-1\) pixels, while receptive-field area grows quadratically until later layers span the entire input. How efficiently accelerators execute this expanding stack depends on how sliding-window stencils map onto parallel execution pipelines.
6.3.3 Computational mapping
A framework expresses a whole convolutional layer as one call (listing 3). Behind that call, the underlying runtime must schedule memory traffic across cache hierarchies and lower sliding-window stencils onto matrix execution hardware.
def conv_layer_spatial(input, kernel, bias):
    """Framework-level convolution.

    Single call dispatches to optimized kernel (often via im2col + GEMM).
    """
    # Convolution applies shared weights across all positions
    # For a 3x3 kernel on 28x28 input (padded): 9 MACs per position x 784 positions
    output = convolution(input, kernel) + bias
    return activation(output)
To expose the mechanics that the framework abstraction conceals, listing 4 details the canonical seven-deep loop nest required to evaluate a direct 2D convolution. These loops partition into three structural tiers: batch iteration across samples, spatial traversal over feature map coordinates \((\FeatureMapRowCoordinate, \FeatureMapColumnCoordinate)\), and channel accumulation over input and output dimensions \((\InputChannelCount, \OutputChannelCount)\) coupled with kernel offsets \((\KernelVerticalLoopOffset, \KernelHorizontalLoopOffset)\). Traversing spatial coordinates and output channels defines the grid of independent output activations. The listing uses unit stride and no padding, with channels stored contiguously at each spatial position (NHWC: batch, height, width, channels). Each output window stays within the input, so the output height and width are the corresponding input dimensions minus the kernel dimensions plus one.
def conv_layer_compute(input, kernel, bias):
    # NHWC input; kernel axes: height, width, input, output channels.
    # Unit stride, no padding; activation follows the convolution.
    batch_size, in_h, in_w, in_channels = input.shape
    kernel_h, kernel_w, _, out_channels = kernel.shape
    out_h, out_w = in_h - kernel_h + 1, in_w - kernel_w + 1
    output = zeros((batch_size, out_h, out_w, out_channels))
    for image in range(batch_size):
        for y in range(out_h):
            for x in range(out_w):
                for out in range(out_channels):
                    result = bias[out]
                    for ky in range(kernel_h):
                        for kx in range(kernel_w):
                            for ch in range(in_channels):
                                result += (input[image, y + ky, x + kx, ch]
                                           * kernel[ky, kx, ch, out])
                    output[image, y, x, out] = result
    return activation(output)
The inner three loops execute the kernel dot product at each spatial site. For a \(3{\times}3\) filter, each output activation accumulates contributions from a local input patch across all input channels. Advancing x by one makes the next output read a patch overlapping the previous one, while changing out reuses the same patch with a different filter. These repeated accesses offer reuse, but the scalar schedule does not explicitly keep tiles in fast memory or distribute work across execution lanes. Their actual cost depends on which reads the cache serves and how the implementation maps iterations to hardware.
To expose these patches to optimized matrix engines, convolution implementations can use the im2col (image-to-column) transformation.15 By unfolding each receptive-field patch into a contiguous row of an input matrix and stacking filter weights into columns (figure 5 lays this out for two input channels), im2col recasts the entire convolution as a dense general matrix multiply (GEMM) that runs on mature, vendor-tuned libraries. To see how the lowering rearranges data in memory, consider a miniature single-channel image (\(\InputChannelCount= 1\)) of size \(3 \times 3\) convolved with a \(2 \times 2\) filter (\(\KernelSize= 2\)) with valid padding: \[
\LayerInputMatrix= \begin{bmatrix} 1 & 2 & 3 \\ 4 & 5 & 6 \\ 7 & 8 & 9 \end{bmatrix}, \qquad \WeightMatrix= \begin{bmatrix} \FilterWeight_1 & \FilterWeight_2 \\ \FilterWeight_3 & \FilterWeight_4 \end{bmatrix}
\] The window visits four overlapping \(2 \times 2\) receptive fields. To evaluate all four in one matrix multiplication, im2col flattens each patch into a row vector of length \(\KernelSize^2 = 4\) and stacks the rows into an unfolded matrix \(\UnfoldedPatchMatrix\): \[
\UnfoldedPatchMatrix= \begin{bmatrix} 1 & 2 & 4 & 5 \\ 2 & 3 & 5 & 6 \\ 4 & 5 & 7 & 8 \\ 5 & 6 & 8 & 9 \end{bmatrix}
\] Flattening the filter weights into a column vector \(\FlattenedFilterWeights= [\FilterWeight_1, \FilterWeight_2, \FilterWeight_3, \FilterWeight_4]^T\), the entire convolution collapses into a single standard matrix product: \(\UnfoldedConvolutionOutput= \UnfoldedPatchMatrix\FlattenedFilterWeights\). For batched multi-channel inputs, the unfolded matrix has shape \([(\BatchSize \cdot \OutputFeatureMapHeight \cdot \OutputFeatureMapWidth) \times (\KernelSize^2 \cdot \InputChannelCount)]\) and the filters reshape to \([(\KernelSize^2 \cdot \InputChannelCount) \times \OutputChannelCount]\). In \(\UnfoldedPatchMatrix\), input element 5 appears in all four rows, and the miniature input expands from nine elements to sixteen, a storage ratio of \(16/9\). For large stride-1 inputs, fully materialized unfolding approaches the kernel area as its expansion factor. The smaller ratio here reflects the borders of a valid convolution. Materializing the buffer trades this additional storage and traffic for access to wide matrix engines optimized for GEMM throughput. Implicit GEMM, described next, avoids allocating the duplicated buffer.
15 im2col (image to column): Rather than being a new learning algorithm, im2col-style lowering is an implementation technique used by CNN frameworks and libraries such as Caffe and cuDNN (Chellapilla et al. 2006; Jia et al. 2014; Chetlur et al. 2014): it converts convolutions into standard GEMM calls by unfolding overlapping patches into matrix columns. The trade-off is memory: in a simple fully materialized stride-1 \(\KernelSize{\times}\KernelSize\) transform, interior input elements can appear in up to \(\KernelSize^2\) columns (9 times for \(3{\times}3\) filters), though borders, stride, padding, tiling, and direct-convolution algorithms reduce the realized expansion. This memory-for-simplicity exchange explains why mobile frameworks (TFLite, NNAPI) prefer direct convolution, while data center GPUs with abundant HBM may use GEMM-oriented lowering when it improves throughput.
Chellapilla, Kumar, Sidd Puri, and Patrice Simard. 2006. High Performance Convolutional Neural Networks for Document Processing. Tenth International Workshop on Frontiers in Handwriting Recognition.
Jia, Yangqing, Evan Shelhamer, Jeff Donahue, Sergey Karayev, Jonathan Long, Ross Girshick, Sergio Guadarrama, and Trevor Darrell. 2014. “Caffe: Convolutional Architecture for Fast Feature Embedding.” Proceedings of the 22nd ACM International Conference on Multimedia, 675–78. https://doi.org/10.1145/2647868.2654889.
Chetlur, Sharan, Cliff Woolley, Philippe Vandermersch, Jonathan Cohen, John Tran, Bryan Catanzaro, and Evan Shelhamer. 2014. “cuDNN: Efficient Primitives for Deep Learning.” arXiv Preprint arXiv:1410.0759.
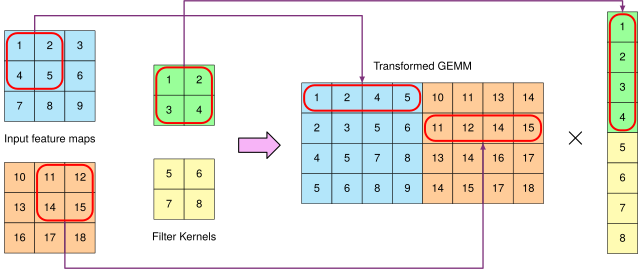
Implicit GEMM techniques run the same matrix multiplication without building the unfolded matrix. They compute each patch element’s address on the fly, inside the processor’s registers, so the duplicated buffer is never materialized. With \(3{\times}3\) filters and 32 output channels, each output coordinate requires only 9 MAC operations per input channel, whereas each output neuron of the reference MLP layer requires 784. The window overlap creates reuse that the memory system must be scheduled to exploit.
6.3.4 System implications
Weight sharing flips the hardware bottleneck of a neural network. Compact convolutional filters fit in on-chip cache and are reused across thousands of pixel positions, which pushes arithmetic intensity into the compute-bound regime. The intermediate feature maps they write out, however, dominate off-chip memory capacity and bandwidth. Whether a deep CNN stalls on memory or saturates the matrix units depends on layer depth, how long activations stay live for the backward pass, and whether feature-map tiles remain in on-chip SRAM or spill to external HBM.
Memory requirements
On a \(224{\times}224\) ImageNet input, a convolutional layer with 64 filters of size \(3{\times}3\) needs only 576 weights per input channel, or 36,864 weights (147.5 KB in FP32) across 64 input channels. These weights fit comfortably in on-chip L1 or L2 cache, yet the layer produces 3.2M output activation values (about 12.8 MB in FP32 per sample in the batch). Memory consumption in convolutional layers splits sharply between these compact, static filter weights and large, transient feature maps. During training, those feature maps must stay live in memory until backpropagation computes the layer’s gradients, making activation memory, not weight capacity, the binding memory constraint for deep CNNs on accelerators.
Accelerators exploit this footprint disparity through hierarchical caching. CPUs retain compact filter weights in L2/L3 caches while streaming activation tensors. GPUs stage filter weights and input tiles in on-chip scratchpad SRAM (shared memory) and register files, reusing loaded weights across thousands of spatial coordinates and eliminating redundant round-trips to off-chip HBM.
↪ The memory hierarchy of register files, on-chip SRAM, and HBM that these caching patterns exploit is developed in Memory hierarchy.
Compute requirements
Evaluating a convolutional layer requires repeatedly evaluating local dot products across spatial positions. For an ImageNet input with \(3{\times}3\) filters and 64 output channels, computing a single spatial position requires 576 multiply-accumulate operations per input channel. Summed over 64 input channels and repeated at all 50,176 spatial positions, one such layer performs about 1.85 billion multiply-accumulates. The general count follows the same steps: a layer with \(\FeatureMapHeight{\times}\FeatureMapWidth\) output positions performs \(\FeatureMapHeight \FeatureMapWidth \KernelSize^2 \InputChannelCount \OutputChannelCount\) multiply-accumulates, one \(\KernelSize^2 \InputChannelCount\) dot product for every output position and every filter. Although each spatial stencil touches fewer parameters than a dense layer, spatial repetition multiplies the total floating-point operation count.
This computational regularity provides rich opportunities for hardware parallelization. Because each spatial coordinate is independent, processors parallelize work along multiple axes simultaneously: across the batch dimension, across spatial coordinates \((\FeatureMapColumnCoordinate, \FeatureMapRowCoordinate)\), and across output channels. CPUs execute vectorized SIMD instructions16 to evaluate multiple spatial outputs per clock cycle, while GPUs dispatch thread warps across thousands of concurrent execution lanes.
16 SIMD (single instruction, multiple data): CPU instructions that apply the same operation to multiple data elements simultaneously; AVX-512 can process 16 single-precision values per vector instruction; realized speedup over scalar code also depends on instruction throughput, vectorization, and memory access. For CNN inference on edge CPUs without GPU access, SIMD utilization can affect whether a model meets real-time latency targets. Frameworks like TFLite and Open Neural Network Exchange (ONNX) Runtime use vectorized convolution kernels to exploit this parallelism.
Data movement
Data movement in a convolutional layer has an arithmetic intensity profile different from that of an MLP. In a fully connected layer at batch size one, each loaded weight is used exactly once, yielding an arithmetic intensity bounded below 1 FLOP/byte. In a 2D convolution, each \(3{\times}3\) filter weight is reused across all 50,176 positions of the \(224{\times}224\) feature map. This weight reuse increases operational intensity, shifting computation from the memory-bandwidth-bound regime toward the compute-bound ceiling.
The systems challenge shifts from loading weights to staging activations. Because adjacent spatial receptive fields overlap, a naive memory access pattern would re-fetch each input pixel from memory up to \(\KernelSize^2 = 9\) times. Runtimes avoid this redundant memory traffic by tiling computation into 2D spatial blocks sized to fit inside accelerator SRAM, the technique that Tiling develops for the accelerator’s memory hierarchy. Once an input tile is loaded into shared memory, all overlapping filter dot products for that tile execute in place, amortizing the DRAM/HBM transfer and maximizing the 50,176 reuses of each filter weight. Reuse also moves the energy. Each filter weight fetched from off-chip memory feeds tens of thousands of multiply-accumulates. Once filters and input tiles stay on chip, a convolutional layer spends its energy on arithmetic and on-chip SRAM rather than on DRAM reads, the reverse of the batch-one dense layer.
↪ The hardware ridge point (\(\RooflineRidgePoint\)), which decides whether spatial filter reuse saturates the arithmetic units or starves on memory bandwidth, is developed in Hardware ridge points.
Checkpoint 6.1: Spatial inductive bias
CNNs succeed because they match the structure of image data. Verify you understand how:
These memory, compute, and data-movement patterns converge in ResNet-50 (He et al. 2016a), which anchors the chapter’s compute-intensive vision lighthouse. The Residual Network (ResNet) addressed the degradation problem in deep plain networks: adding layers could increase training error despite sufficient capacity. By introducing skip connections, shortcut paths that add a block’s input directly to its output and so give gradients a route around each block (developed in section 6.4), it enabled networks of 50, 100, or even 1,000 layers. The ResNet architecture won the ImageNet 2015 competition (with 152-layer models), and ResNet-50 has become a widely used backbone and benchmark workload for computer vision.
Lighthouse 6.1: ResNet-50 (vision lighthouse)
Why it matters: ResNet-50 is a reference point for regular, convolution-heavy vision workloads. Its architecture consists almost entirely of dense convolutional layers, making it highly regular and efficient on GPUs. Under batched execution with good data reuse, ResNet-50 performance is typically limited by floating-point throughput (FLOP/s), making it a useful lighthouse for explaining data parallelism, quantization, and batching strategies. Table 2 summarizes the quantitative properties and their system consequences:
| Property | Value | System Implication |
|---|---|---|
| Parameters | 25.6M | 102.2 MB model size at FP32; fits comfortably in GPU memory. |
| FLOPs/Image | 8.2 GFLOP \((224{\times}224)\) | \(3{\times}3\) convolutions are the largest single kernel class at roughly 48% of MACs. |
| Constraint | Compute-heavy when batched | Limited by peak FLOP/s when weight and activation reuse are high; small-batch inference can move toward the memory-bound regime. |
| Bottleneck | FP Throughput | Benefits maximally from specialized Matrix Units (Tensor Cores). |
| Profile | High effective arithmetic intensity under reuse | Arithmetic intensity depends on batch size, convolution algorithm, and materialized memory traffic. |
6.3.5 Depthwise separable convolutions
ResNet-50’s compute-bound profile assumes abundant hardware resources, yet most inference runs on devices with power budgets three orders of magnitude smaller than a data center accelerator. Standard convolutions scale as \(\mathcal{O}(\SpatialPositionCount\times \KernelSize^2 \times \InputChannelCount\times \OutputChannelCount)\), a compute volume that exceeds the strict energy budgets of always-on edge devices. To bridge this gap, efficient architectures like depthwise separable CNNs (DS-CNN) decompose the standard convolution into two distinct operations. This factorization, introduced by Sifre in the context of feature extraction (Sifre and Mallat 2014) and popularized by MobileNet (Howard et al. 2017), decouples spatial filtering from cross-channel combination. The depthwise convolution applies filters to each input channel independently (\(\KernelSize\times \KernelSize\times \InputChannelCount\) parameters), while the pointwise convolution uses a \(1{\times}1\) convolution to project channels to the output dimension (\(1 \times 1 \times \InputChannelCount\times \OutputChannelCount\) parameters). Per output position, a standard layer performs \(\KernelSize^2 \InputChannelCount \OutputChannelCount\) multiply-accumulates, while the factorized pair performs \(\KernelSize^2 \InputChannelCount+ \InputChannelCount \OutputChannelCount\). Dividing the two shows that the decomposition reduces parameter count and FLOPs to roughly \(\frac{1}{\OutputChannelCount} + \frac{1}{\KernelSize^2}\) of standard convolution, a reduction factor approaching \(\KernelSize^2\), or about 8–9\(\times\) for \(3{\times}3\) filters with large \(\OutputChannelCount\). That reduction makes real-time execution feasible on resource-constrained microcontrollers.
Sifre, Laurent, and Stéphane Mallat. 2014. “Rigid-Motion Scattering for Image Classification.” arXiv Preprint arXiv:1403.1687, ahead of print. https://doi.org/10.48550/arXiv.1403.1687.
The channel paths in figure 6 show where the arithmetic reduction comes from. The depthwise stage produces one intermediate value per input channel at each output position, and the pointwise stage combines those values across channels.
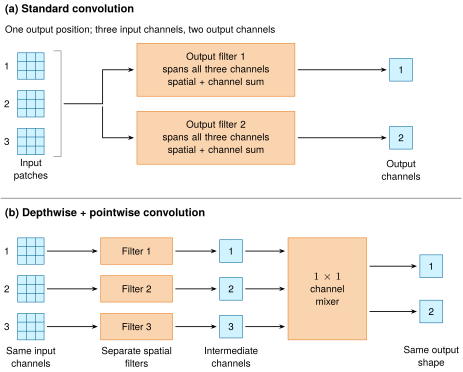
The shared spatial filter within each input channel restricts the functions the factorized layer can represent. Matching input and output shapes therefore does not make the pair an algebraically equivalent replacement for an arbitrary trained standard convolution. An implementation may also materialize the intermediate activations, adding a memory cost that the MAC count alone does not reveal.
MobileNet (Howard et al. 2017) made this factorization the basis of a model family, challenging the trend toward ever-larger networks by designing for the battery and latency budgets of smartphones and embedded devices. MobileNetV2 anchors the chapter’s edge-efficiency lighthouse, reaching competitive accuracy at a fraction of ResNet-50’s arithmetic, and its small compute footprint made it a natural target for compression and lower-precision deployment, which stores and computes with fewer bits per value.
Howard, Andrew G., Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, and Hartwig Adam. 2017. “MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications.” CoRR abs/1704.04861.
↪ Compression and lower-precision deployment techniques for compact models such as MobileNet are developed in Model Compression.
Lighthouse 6.2: MobileNetV2 (efficiency lighthouse)
Why it matters: MobileNetV2 represents edge workloads that must meet a latency budget within a power envelope. Its depthwise separable convolutions trade channel-mixing capacity for fewer operations, making it a useful baseline for mobile apps, embedded vision, and neural architecture search (NAS), automated search over model designs. Table 3 summarizes the efficiency lighthouse’s quantitative properties:
| Property | Value | System Implication |
|---|---|---|
| Parameters | 3.5M | 14 MB at FP32; 7.3× smaller than ResNet-50. |
| FLOPs/Image | 600 MFLOP | 13.7× fewer than ResNet-50 for similar accuracy. |
| Constraint | Latency Target | Single-image inference speed is the priority. |
| Bottleneck | Overhead/Memory Access | Operator dispatch and memory access can dominate actual compute. |
| Profile | Low Arithmetic Intensity | Memory access and control logic matter more than peak FLOP/s. |
Set side by side, the ResNet-50 and MobileNetV2 profiles show that a model with 13.7× fewer FLOPs does not automatically run 13.7× faster. Whether operational reduction translates into wall-clock speedup depends on arithmetic intensity, operator dispatch overhead, and the hardware’s roofline balance. A standard convolution reuses each loaded input patch across all output filters in a single matrix multiplication. Splitting that pass into depthwise and pointwise stages removes cross-channel reuse from the spatial step. Each depthwise filter operates on one channel in isolation, which cannot form a wide matrix product to fill GPU Tensor Cores, and the split writes and re-reads an extra intermediate feature map while performing roughly eight to nine times less arithmetic on those bytes. On data center GPUs engineered for high arithmetic intensity, MobileNetV2 therefore achieves only a modest speedup. Architectural efficiency techniques like depthwise separable convolutions and pruning (removing redundant weights or channels) alter this hardware mapping balance, and Perspective 6.1 addresses the central fallacy linking FLOP counts directly to execution latency.
Systems Perspective 6.1: Misconception: FLOPs equal speed
Fallacy: “MobileNetV2 has 13.7× fewer FLOPs than ResNet-50, so it must run 13.7× faster.”
Resolution: On high-end GPUs at small batch, MobileNetV2 gains far less than its FLOP advantage suggests, and in some framework configurations runs no faster than ResNet-50. MobileNetV2’s depthwise separable convolutions have low arithmetic intensity: they move more data relative to computation. GPUs optimized for dense matrix operations may use their compute units poorly on these kernels. FLOPs measure work; throughput depends on how well that work maps to hardware.
KWS (Warden 2018) pushes the same factorization to the microcontroller end of the spectrum and anchors the always-on TinyML lighthouse. A continuous audio stream is first converted by a short-time Fourier transform into a 2D time-frequency spectrogram (or Mel-frequency cepstral coefficients), so 2D convolutional filters can slide across time and frequency bins to detect acoustic phoneme signatures. Models that listen for “Hey Siri” or “Ok Google” run on always-on microcontrollers with kilobyte-scale memory and milliwatt power budgets (Warden and Situnayake 2020; C. R. Banbury et al. 2021; C. Banbury et al. 2021), so their designers count every byte and cycle.
Warden, Pete. 2018. “Speech Commands: A Dataset for Limited-Vocabulary Speech Recognition.” arXiv Preprint arXiv:1804.03209, ahead of print. https://doi.org/10.48550/arXiv.1804.03209.
Warden, Pete, and Daniel Situnayake. 2020. TinyML: Machine Learning with TensorFlow Lite on Arduino and Ultra-Low-Power Microcontrollers. O’Reilly Media.
Banbury, Colby R, Chuteng Zhou, Igor Fedorov, Ramon Matas, Urmish Thakker, Dibakar Gope, Vijay Janapa Reddi, Matthew Mattina, and Paul N Whatmough. 2021. “MicroNets: Neural Network Architectures for Deploying TinyML Applications on Commodity Microcontrollers.” Proceedings of Machine Learning and Systems 3: 517–32.
Banbury, Colby, Vijay Janapa Reddi, Peter Torelli, Jeremy Holleman, Nat Jeffries, Csaba Kiraly, Pietro Montino, et al. 2021. “MLPerf Tiny Benchmark.” arXiv Preprint.
Lighthouse 6.3: KWS (TinyML lighthouse)
Why it matters: Keyword spotting models (like DS-CNN) represent the power-constrained end of the spectrum. Used in always-on applications like smart doorbells that wake a larger vision pipeline only after an audio trigger, these models must run on microcontrollers with milliwatt power budgets.
At 200K parameters, a DS-CNN keyword spotter’s 800 KB of FP32 weights already exceeds the few hundred kilobytes of memory a typical microcontroller can devote to a model, so the model fits only after 8-bit quantization cuts it fourfold. KWS is therefore the lighthouse for extreme quantization (INT8/INT4) and specialized architectural primitives (depthwise separable convolutions) that trade theoretical representational power for maximum efficiency per watt.
From ResNet-50’s compute-heavy standard convolutions through MobileNet’s depthwise separable variants to KWS’s micro-power deployment, CNNs demonstrate how architectural constraints transform data structure into hardware efficiency. Local connectivity and weight sharing reduce parameter storage and expose reuse. Depth is what lets those stacks compose edges into objects, and ResNet-50’s fifty layers depend on two building blocks that make depth trainable at all.
Self-Check: Question
A \(3 \times 3\) convolutional layer with 64 input channels and 64 output channels processes a \(224 \times 224\) feature map, producing 64 spatial output channels. How does its parameter count compare with a dense layer that maps the flattened \(224 \times 224 \times 64\) input to 64 scalar outputs, and why are the outputs not shape-equivalent?
- The CNN requires \(205\text{ million}\) parameters, whereas the dense layer requires only \(36{,}864\) parameters due to flattened matrix vectorization.
- The CNN requires \(3 \times 3 \times 64 \times 64 = 36{,}864\) parameters (~37K), whereas a dense layer mapping a \(224^2 \times 64\) input to 64 scalar outputs requires \(224^2 \times 64 \times 64 \approx 205\text{ million}\) parameters; the output shapes are not equivalent.
- Both architectures require exactly the same number of parameters because both perform 64-to-64 channel transformations.
- The CNN requires 9 parameters because spatial weight sharing reduces all kernel weights across all channels to a single \(3 \times 3\) matrix.
Distinguish between translation equivariance (\(f(\mathcal{T}(\mathbf{x})) = \mathcal{T}(f(\mathbf{x}))\)) and translation invariance (\(f(\mathcal{T}(\mathbf{x})) = f(\mathbf{x})\)). Explain why intermediate convolutional layers must maintain equivariance for object detection while final classification layers often apply global average pooling to achieve invariance.
Order the sequence of operations performed when executing a 2D convolution layer via the standard im2col lowering transformation followed by activation:
- Multiply the unfolded patch matrix by the stacked filter weight matrix using a standard GEMM library call
- Reshape and fold the resulting 2D GEMM output matrix back into the 4D spatial feature map tensor \((B, C_{\text{out}}, H_{\text{out}}, W_{\text{out}})\)
- Unfold overlapping \(K \times K\) receptive field input patches into columns (or rows) of a 2D matrix
- Add channel bias vectors and apply the element-wise nonlinear activation function (e.g., ReLU)
- Receive the 4D input activation tensor of shape \((B, C_{\text{in}}, H_{\text{in}}, W_{\text{in}})\)
Because MobileNetV2 requires roughly 14\(\times\) fewer FLOPs than ResNet-50 per \(224 \times 224\) image, it is guaranteed to execute at least 10\(\times\) faster on any data center GPU.
A depthwise separable convolution decomposes standard convolution into two sequential operations: a ____ convolution that applies spatial filters to each input channel independently, followed by a \(1 \times 1\) pointwise convolution that projects and mixes channels across the depth dimension.
In a deep CNN using stacked \(3 \times 3\) convolutional filters with stride 1 and padding, by how much does the receptive field side length increase with each additional layer, and what is the architectural implication for detecting large objects?
- Receptive field increases by 9 pixels per layer, allowing a 3-layer network to cover an entire \(224 \times 224\) image.
- Receptive field side length doubles with each layer, scaling exponentially as \(3^L\).
- Receptive field side length grows linearly by 2 pixels per layer (a 3-layer stack sees a \(7 \times 7\) region), requiring deep stacks of layers or downsampling (pooling/striding) to detect objects spanning \(100+\) pixels in high-resolution images.
- Receptive field remains strictly fixed at \(3 \times 3\) across all layers because convolutional filter weights are shared across positions.
6.4 Skip Connections and Normalization
When plain convolutional networks are stacked beyond roughly 20 layers, adding more layers can make training error worse rather than better: gradients vanish or explode on the way back through the stack, and the scale of intermediate activations drifts on the way forward. Convolution made deep vision networks affordable in parameter count, and two building blocks made them trainable. Skip connections keep gradients alive through dozens of layers, and normalization keeps the activations those layers produce within a stable numerical range. Both arrived with deep CNNs, both carry their own memory and bandwidth costs, and both reappear in the deep families that follow, most visibly the transformer.
6.4.1 Skip connections and gradient flow
Why gradients vanish or explode across depth, and why additive identity shortcuts (skip connections) resolve that barrier, follows directly from the chain rule, whose layer-by-layer Jacobian form appears in Error signal propagation. For a deep network with layers \(\LayerFunction_1, \LayerFunction_2, \ldots, \FinalLayerFunction\), the gradient of the loss \(\LossFunction\) with respect to the weights in layer 1 is: \[ \frac{\partial \LossFunction}{\partial \WeightMatrix^{(1)}} = \frac{\partial \LossFunction}{\partial \ActivationVector^{(\LayerCount)}} \cdot \frac{\partial \ActivationVector^{(\LayerCount)}}{\partial \PreactivationVector^{(\LayerCount)}} \cdot \frac{\partial \PreactivationVector^{(\LayerCount)}}{\partial \ActivationVector^{(\LayerCount-1)}} \cdot \ldots \cdot \frac{\partial \PreactivationVector^{(2)}}{\partial \ActivationVector^{(1)}} \cdot \frac{\partial \ActivationVector^{(1)}}{\partial \PreactivationVector^{(1)}} \cdot \frac{\partial \PreactivationVector^{(1)}}{\partial \WeightMatrix^{(1)}} \] where \(\PreactivationVector^{(\LayerIndex)}\) represents the preactivation and \(\ActivationVector^{(\LayerIndex)} = \SigmoidFunction(\PreactivationVector^{(\LayerIndex)})\) the postactivation output of layer \(\LayerIndex\). Each layer contributes both a weight transformation and an activation derivative \(\SigmoidFunction'(\PreactivationVector^{(\LayerIndex)})\). With sigmoid activations, whose derivative peaks at 0.25 (Sigmoid), the activation-derivative factors alone contribute at most \((0.25)^{\LayerCount}\) along a path. The full gradient also depends on the intervening weight matrices; when their transformations do not offset this attenuation, early layers receive negligible updates. Exploding gradients are the destabilizing counterpart. If each layer Jacobian expands a shared direction by about 1.5, that component grows exponentially, producing overflow, NaN (not-a-number) values, and training divergence rather than a silent stall.
ReLU removes the activation’s share of this decay, since its derivative is one on active paths (ReLU), and that change made networks of 10–20 layers trainable. It does not remove the problem. Inactive units pass zero gradient, and a poorly initialized weight or a large update can leave a unit permanently dead. More fundamentally, ReLU does nothing to regulate the singular values of the weight matrices, which continue to attenuate or amplify gradients across depth. The original ResNet study showed the consequence on CIFAR-10: a 56-layer plain network had higher training and test error than a 20-layer plain network throughout training (He et al. 2016a). Because the deeper network was worse on the training set, the failure was an optimization barrier, not overfitting.
A residual block gives the gradient a direct path back through its input. Equation 6 adds the identity path \(\LayerInputVector\) to the residual mapping \(\ResidualFunction(\LayerInputVector)\): \[ \ResidualBlockOutput= \ResidualFunction(\LayerInputVector) + \LayerInputVector \tag{6}\] where \(\ResidualFunction(\LayerInputVector)\) represents the residual function (typically two convolutional layers with batch normalization and ReLU) and \(\LayerInputVector\) is the identity skip connection. The original post-activation ResNet block (figure 7) routes an identity shortcut around two weight layers and the ReLU between them, adds it back at a junction, and then applies the final activation.
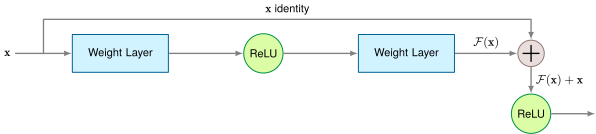
During backpropagation, the gradient flows through this addition, and applying the chain rule gives: \[ \frac{\partial \LossFunction}{\partial \LayerInputVector} = \frac{\partial \LossFunction}{\partial \ResidualBlockOutput} \cdot \left(\frac{\partial \ResidualFunction(\LayerInputVector)}{\partial \LayerInputVector} + \IdentityMatrix\right) = \frac{\partial \LossFunction}{\partial \ResidualBlockOutput} \cdot \ResidualFunction'(\LayerInputVector) + \frac{\partial \LossFunction}{\partial \ResidualBlockOutput} \]
Here \(\IdentityMatrix\) is the identity matrix, and the gradient decomposes into two additive terms. Even if the residual term \(\frac{\partial \LossFunction}{\partial \ResidualBlockOutput}\ResidualFunction'(\LayerInputVector)\) attenuates, the identity term passes \(\frac{\partial \LossFunction}{\partial \ResidualBlockOutput}\) directly to the earlier layer. While the residual branch can partially interfere with the identity signal, keeping \(\|\ResidualFunction'(\LayerInputVector)\|\) small keeps the block Jacobian close to identity and bounds its condition number. Through \(\LayerCount\) residual blocks, the gradient becomes: \[ \frac{\partial \LossFunction}{\partial \LayerInputVector^{(0)}} = \frac{\partial \LossFunction}{\partial \LayerInputVector^{(\LayerCount)}} \cdot \prod_{\LayerIndex=1}^{\LayerCount} \left(\ResidualFunction'_\LayerIndex(\LayerInputVector^{(\LayerIndex-1)}) + \IdentityMatrix\right) \]
Each factor \((\ResidualFunction'_\ell + \IdentityMatrix)\) contains the identity term, keeping the factor near identity when the residual-branch Jacobian is small. A plain network instead multiplies arbitrary layer Jacobians, and if their average gain is even slightly below one the product vanishes exponentially (\(0.9^{50} \approx 0.005\)). ResNets multiply near-identity factors. The deviations can still compound, and the additive path does not guarantee exact unit gain across arbitrary depth, but this structure improves conditioning enough to make networks with 100+ layers trainable. The CIFAR-10 experiments confirm it: a 56-layer residual network reached about 7.0 percent test error against 8.8 percent for its 20-layer residual counterpart, reversing the degradation seen in plain networks (He et al. 2016a). There is no single depth at which skip connections suddenly become mandatory; trainability also depends on initialization, normalization, optimizer dynamics, and block architecture (He et al. 2016b).
He, Kaiming, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. 2016a. “Deep Residual Learning for Image Recognition.” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 770–78. https://doi.org/10.1109/cvpr.2016.90.
He, Kaiming, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. 2016b. “Identity Mappings in Deep Residual Networks.” Computer Vision – ECCV 2016, 630–45. https://doi.org/10.1007/978-3-319-46493-0_38.
The shortcuts carry a concrete hardware cost that every deep network pays. Evaluating \(\ResidualBlockOutput= \ResidualFunction(\LayerInputVector) + \LayerInputVector\) requires the input tensor \(\LayerInputVector\) to remain resident in memory throughout the execution of every operation in the branch \(\ResidualFunction(\LayerInputVector)\). This extended liveness window increases peak activation memory in accelerator HBM during the forward pass and preserves \(\LayerInputVector\) for backpropagation unless activation checkpointing is used (Activation checkpointing). The elementwise addition is also memory-bandwidth bound. It performs one addition per two loaded operands and one stored result, about 0.08 FLOP/byte in FP32 (one FLOP per 12 bytes), so un-fused residual merges become memory stalls.
Residual connections stabilize the backward gradient path, but they do not constrain the forward scale of intermediate activations. Unbounded variance across depth can still destabilize layer inputs, which calls for a complementary block: normalization.
6.4.2 Normalization and activation stability
Without normalization, small weight updates in early layers compound across depth, shifting and amplifying intermediate activations until later nonlinearities saturate or overflow and training requires tiny learning rates. Skip connections protect the backward pass, and normalization steadies the forward pass by re-centering and re-scaling those intermediate activations at each block. Batch normalization in CNNs17 (Ioffe and Szegedy 2015), layer normalization for sequence models, and RMSNorm18 for large language models illustrate different choices of reduction axes and statistics.
17 Batch normalization (BatchNorm): The original normalization layer (Ioffe and Szegedy 2015), which re-scales activations using per-mini-batch statistics. In one ImageNet experiment, it reached the target accuracy with 14\(\times\) fewer training steps. Its batch-size dependency and training-serving skew (switching from batch statistics to running averages at inference) are systems limitations that motivated alternatives: LayerNorm removed batch dependency for transformers, and RMSNorm removed mean centering.
Ioffe, Sergey, and Christian Szegedy. 2015. “Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift.” Proceedings of the 32nd International Conference on Machine Learning (ICML) 37: 448–56.
18 RMSNorm (root mean square normalization): Introduced by Zhang and Sennrich (2019) at NeurIPS, RMSNorm simplifies LayerNorm by normalizing with the root mean square alone, dropping the mean-centering step. Across the paper’s tested models and implementations, RMSNorm reduced overall running time by 7–64 percent relative to LayerNorm. LLaMA-family and Mixtral-style transformer reports use RMSNorm (Touvron, Lavril, et al. 2023; Touvron, Martin, et al. 2023; Jiang et al. 2024), illustrating why a simpler normalization kernel matters at large language model scale.
Zhang, Biao, and Rico Sennrich. 2019. “Root Mean Square Layer Normalization.” Advances in Neural Information Processing Systems (NeurIPS).
Touvron, Hugo, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, et al. 2023. “LLaMA: Open and Efficient Foundation Language Models.” arXiv Preprint arXiv:2302.13971.
Touvron, Hugo, Louis Martin, Kevin Stone, Peter Albert, Amjad Almahairi, Yasmine Babaei, Nikolay Bashlykov, et al. 2023. “Llama 2: Open Foundation and Fine-Tuned Chat Models.” arXiv Preprint arXiv:2307.09288.
Jiang, A. Q., A. Sablayrolles, A. Roux, A. Mensch, B. Savary, C. Bamford, D. S. Chaplot, et al. 2024. “Mixtral of Experts.” arXiv Preprint arXiv:2401.04088.
Batch normalization standardizes activations using statistics computed across the mini-batch for each feature or channel during training. For fully connected activations, the reduction axis is the batch dimension. For convolutional activations, implementations compute per-channel statistics over both the batch and spatial positions (\(\BatchSize \times \FeatureMapHeight\times \FeatureMapWidth\)). For a mini-batch \(\MiniBatchSet= \{\MiniBatchActivation_1, \ldots, \FinalMiniBatchActivation\}\) of activations at a particular layer, the transformation proceeds in two stages, starting with the mini-batch mean and variance: \[ \BatchNormMean= \frac{1}{\BatchSize}\sum_{i=1}^{\BatchSize} \MiniBatchActivation_i \qquad \BatchNormStandardDeviation^2 = \frac{1}{\BatchSize}\sum_{i=1}^{\BatchSize} (\MiniBatchActivation_i - \BatchNormMean)^2 \]
The second stage normalizes each activation over the batch and applies a learned scale and shift. The normalization step in equation 7 centers and scales activations, while equation 8 lets the network learn a useful output scale and offset: \[ \NormalizedActivation_i = \frac{\MiniBatchActivation_i - \BatchNormMean}{\sqrt{\BatchNormStandardDeviation^2 + \NumericalStabilityConstant}} \tag{7}\] \[ \BatchNormOutput_i = \NormalizationScale\NormalizedActivation_i + \NormalizationShift \tag{8}\]
The parameters \(\NormalizationScale\) (scale) and \(\NormalizationShift\) (shift) are learned during training, while \(\NumericalStabilityConstant\) (typically \(10^{-5}\)) prevents division by zero. The affine transform restores learned scale and shift flexibility, but fixed \(\NormalizationScale\) and \(\NormalizationShift\) cannot exactly invert varying statistics for every batch. Normalization permits larger learning rates by preventing intermediate activations from exploding into saturating non-linear regimes, accelerating convergence relative to unnormalized networks.
While batch normalization enabled training of much deeper CNNs, it needs batch-wide statistics, which constrains distributed and sequence workloads. When a mini-batch is split across several accelerators, computing true mini-batch statistics requires an all-reduce, a collective that sums every accelerator’s partial statistics and returns the total to all of them, adding communication latency to every normalized layer. If instead computed locally on small per-accelerator batches, noisy empirical statistics destabilize optimization. Furthermore, batch normalization cannot handle variable-length sequences or text generation, which produces one token at a time, without complex padding masks and training-serving skew. Layer normalization resolves these limitations by normalizing across the feature dimension rather than across the batch (Ba et al. 2016).
Ba, Jimmy Lei, Jamie Ryan Kiros, and Geoffrey E. Hinton. 2016. “Layer Normalization.” arXiv Preprint arXiv:1607.06450.
↪ The AllReduce collective and its communication cost are developed in Data parallelism.
For an input vector \(\LayerInputVector\in \mathbb{R}^{\HiddenDimension}\) with \(\HiddenDimension\) features, layer normalization first computes the mean and variance across those \(\HiddenDimension\) components: \[ \LayerNormMean= \frac{1}{\HiddenDimension}\sum_{i=1}^{\HiddenDimension} \LayerInputComponent_i \qquad \LayerNormStandardDeviation^2 = \frac{1}{\HiddenDimension}\sum_{i=1}^{\HiddenDimension} (\LayerInputComponent_i - \LayerNormMean)^2 \]
With those per-token statistics in hand, equation 9 defines the complete layer normalization operation, where \(\odot\) denotes element-wise multiplication: \[ \text{LayerNorm}(\LayerInputVector) = \frac{\LayerInputVector- \LayerNormMean}{\sqrt{\LayerNormStandardDeviation^2 + \NumericalStabilityConstant}} \odot \NormalizationScaleVector+ \NormalizationShiftVector \tag{9}\]
Because each token or sample is normalized independently, the computation stays within an accelerator’s on-chip SRAM and registers, with no cross-sample or cross-device communication. That independence makes layer normalization the standard choice for transformers, where sequences vary in length and text generation evaluates a single token at a time. Table 4 contrasts the three variants along the machine and operational dimensions that decide between them.
| Characteristic | BatchNorm | LayerNorm | RMSNorm |
|---|---|---|---|
| Normalization Axis | Batch and, for CNNs, spatial positions | Feature dimension | Feature dimension |
| Batch Size Dependency | High (noisy for small batches) | None | None |
| Typical Use Case | CNNs, vision models | Transformers, RNNs | LLaMA, efficient transformers |
| Computation Cost | Higher (mean + variance) | Higher (mean + variance) | Lower (RMS only) |
| Training/Inference | Different (running stats) | Identical | Identical |
The computational profile of normalization is defined by its arithmetic intensity. Because normalization applies elementwise operations to large activation tensors, execution is memory-bandwidth bound rather than compute bound. A straightforward LayerNorm kernel makes two reductions across the hidden dimension \(\HiddenDimension\), one for the mean \(\LayerNormMean\) and one for the variance \(\LayerNormStandardDeviation^2\), although Welford’s algorithm can compute both in a single pass. RMSNorm drops the mean-centering reduction, leaving a single sum of squares, which simplifies the kernel and eases fusion with neighboring operations; its authors report 7–64 percent lower running time across the models they tested.
↪ Kernel fusion, which collapses memory-bound normalization and activation chains into single kernels whose intermediates stay on chip, is developed in The memory wall and kernel fusion.
The table’s last row is an operational cost. BatchNorm keeps nonlearned running mean and variance buffers and switches from mini-batch statistics in training to those running statistics at inference, so a mismatch between the buffers and deployment data is a frequent source of training-serving skew. LayerNorm and RMSNorm compute identically in both modes and carry no running state. With skip connections and normalization in place, depth stops being an optimization barrier.
Checkpoint 6.2: Making depth trainable
Depth extends how far a network’s view reaches across its input, but a convolutional stack still sees only its receptive field, whether that field spans pixels or the time bins of a spectrogram. A streaming system that must carry information across variable time spans within a fixed state budget motivates a different trade-off: updating a compact recurrent state as each observation arrives.
Self-Check: Question
In a residual block implementing \(\mathbf{y} = \mathcal{F}(\mathbf{x}) + \mathbf{x}\), how does the additive identity shortcut mathematically improve gradient conditioning through the layer Jacobian \(\mathbf{J} = \frac{\partial \mathbf{y}}{\partial \mathbf{x}}\) during backpropagation in very deep networks?
- The shortcut forces the residual function \(\mathcal{F}(\mathbf{x})\) to have zero weights, turning the network into an immutable linear identity operator.
- The Jacobian takes the form \(\mathbf{J} = \mathbf{I} + \frac{\partial \mathcal{F}}{\partial \mathbf{x}}\), so when residual-branch derivatives are small the block stays near identity and gradients have a direct additive path, improving conditioning without guaranteeing exact unit gain at arbitrary depth.
- The shortcut doubles the singular values of the weight matrix at every layer, ensuring gradients explode exponentially rather than vanish.
- The shortcut eliminates the backpropagation chain rule by replacing gradient updates with forward-only finite differences.
Compare Batch Normalization (BatchNorm) and Layer Normalization (LayerNorm) along two critical systems dimensions: (a) sensitivity to mini-batch size during training, and (b) operational differences between training and inference (including training-serving skew).
6.5 RNNs: Sequential Pattern Processing
An MLP requires a fixed-width input vector and a CNN sees only a bounded spatial window, so neither can process a continuous audio stream or a sentence of arbitrary length without padding, truncating, or stacking layers until activation memory overflows. Where convolutional networks exploit spatial structure, many real-world signals carry temporal structure, in which sequential order and prior context determine meaning. Recurrent networks process these variable-length streams within a fixed memory budget by carrying and updating a persistent state vector from one time step to the next.
Definition 6.4: Recurrent neural networks
Recurrent neural networks (RNNs) are sequence-processing architectures that maintain a hidden state \(\RecurrentHiddenState_t = \LayerFunction(\RecurrentHiddenState_{t-1}, \LayerInputVector_t)\) updated at each time step, encoding the assumption that the current output depends on all prior inputs through this fixed-size state vector.
- Significance: The fixed-size state provides \(\mathcal{O}(1)\) inference state memory regardless of sequence length (processing a 10,000-token sequence requires the same state memory as a 10-token sequence), but the sequential update rule forces all \(\SequenceLength\) recurrent transitions to execute in order. Separate per-step kernels (compiled accelerator routines, a different sense of the word from a convolution kernel) add launch overhead \((\Latency)\); fusion can reduce those launches while preserving the serial dependency chain.
- Distinction: Unlike MLPs, which require a fixed-dimensional input vector, or CNNs, which restrict context to a fixed spatial window, RNNs compress an unbounded history into a fixed-size bottleneck state, so they accept sequences of any length without widening the input layer. Gradient signals pass back through the recurrent steps, where repeated Jacobian products can attenuate or amplify them (derived below).
- Common pitfall: A frequent misconception is that RNNs are obsolete. For streaming inference on resource-constrained hardware, such as keyword spotting on a microcontroller, a model that must keep every past input to see the whole stream needs memory that grows with stream length, which can be prohibitive. An RNN’s \(\mathcal{O}(1)\) state size makes it a candidate when a fixed state budget is required.
RNNs hold state memory fixed, but latency grows with sequence length.
Elman, Jeffrey L. 1990. “Finding Structure in Time.” Cognitive Science 14 (2): 179–211. https://doi.org/10.1207/s15516709cog1402_1.
Recurrent architectures, from simple recurrent networks to gated variants such as long short-term memory (LSTM) networks (Elman 1990; Hochreiter and Schmidhuber 1997), encode a temporal inductive bias in which execution order follows causal time and history compresses into that recurring state. Rather than scaling parameter count or activation storage with dilated or deeply stacked windows when relevant tokens sit far apart, the network reuses one transition operator at every step. That choice trades parallelism for bounded state: it provides variable-length temporal context within a fixed memory footprint, but it introduces loop-carried data dependencies that serialize execution on parallel accelerator hardware.
6.5.1 Pattern processing needs
A word like “bank” cannot be disambiguated on its own: “river bank” refers to a shoreline, whereas “investment bank” refers to a financial institution. Only the preceding words resolve which meaning applies. Acoustic waveforms and sensor telemetry behave the same way: a single audio sample or temperature reading is ambiguous without the history that came before it.
Data with this sequential structure imposes three requirements on a model:
- Variable-length inputs: Sequences arrive with different lengths \(\SequenceLength\), ruling out a single fixed-width input layer.
- Long-range memory: The model must carry relevant signals across many time steps without requiring a fixed window size.
- Continuous state updates: Internal representations must update as each new token arrives, folding in new evidence while dropping stale history.
Meeting all three streaming requirements without growing the model alongside the input length requires turning the feedforward graph into a state machine whose output at step \(\TimeStepIndex-1\) feeds step \(\TimeStepIndex\).
6.5.2 Algorithmic structure
To meet the requirements of section 6.5.1, recurrent neural networks introduce directed cycles in their computational graph. Rather than mapping inputs directly to outputs through feedforward layers, an RNN maintains a persistent vector, the hidden state, that updates iteratively at each time step. The hidden state is a running summary of the past.
The fundamental state transition in equation 10 computes the current hidden state \(\RecurrentHiddenState_t\) by combining the incoming token vector \(\LayerInputVector_t\) with the preceding state \(\RecurrentHiddenState_{t-1}\): \[ \RecurrentHiddenState_t = \LayerNonlinearity(\RecurrentStateWeights\RecurrentHiddenState_{t-1} + \RecurrentInputWeights\LayerInputVector_t + \RecurrentHiddenBias) \tag{10}\] where \(\RecurrentHiddenState_t\) denotes the hidden state at time \(\TimeStepIndex\), \(\LayerInputVector_t\) denotes the input at time \(\TimeStepIndex\), \(\RecurrentStateWeights\) contains the recurrent weights, \(\RecurrentInputWeights\) contains the input weights, \(\RecurrentHiddenBias\) is the hidden-state bias vector, and \(\LayerNonlinearity\) is the activation function. The equation uses column vectors; the later listings use row-major batched tensors, so their weight multiplications appear on the right. Unrolled across time (figure 8, right), the loop becomes a chain of transitions \(\RecurrentHiddenState_{t-1} \to \RecurrentHiddenState_t \to \RecurrentHiddenState_{t+1}\) in which every link reuses the same recurrent weight matrix \(\RecurrentStateWeights\), so no step can begin until the one before it has finished.
Unfolding the recurrent loop across \(\SequenceLength\) steps reveals the algorithmic properties of recurrence. Parameter count remains independent of sequence length \(\SequenceLength\) because the weight matrices \(\RecurrentStateWeights\) and \(\RecurrentInputWeights\) are shared across all time steps. However, sharing weights across time establishes a loop-carried dependency: step \(\TimeStepIndex\) cannot evaluate \(\RecurrentHiddenState_t\) until step \(\TimeStepIndex-1\) finishes producing \(\RecurrentHiddenState_{t-1}\). This dependency forms a critical path of length \(\mathcal{O}(\SequenceLength)\) serial operations that prevents hardware accelerators from parallelizing across the sequence dimension.
This sequential structure produces different memory characteristics in inference and in training. During streaming inference, an RNN evaluates one step at a time, discarding prior raw inputs and retaining only the current hidden state. State memory overhead remains strictly \(\mathcal{O}(\HiddenDimension)\) in the hidden dimension \(\HiddenDimension\), regardless of whether the sequence spans 10 or 10,000 steps. In contrast, training via backpropagation through time (BPTT) (Werbos 1990) unrolls the graph across the entire sequence of length \(\SequenceLength\). Computing gradients via the chain rule requires evaluating the Jacobian product across all intermediate transitions: \[ \frac{\partial \LossFunction}{\partial \RecurrentHiddenState_0} = \frac{\partial \LossFunction}{\partial \FinalRecurrentHiddenState} \prod_{t=1}^{\SequenceLength} \frac{\partial \RecurrentHiddenState_t}{\partial \RecurrentHiddenState_{t-1}} \] Ordinary BPTT retains the intermediate activations \(\RecurrentHiddenState_1, \RecurrentHiddenState_2, \dots, \FinalRecurrentHiddenState\) for these Jacobian products. This retained-state scheme converts an \(\mathcal{O}(\HiddenDimension)\) runtime state into an \(\mathcal{O}(\SequenceLength \cdot \HiddenDimension)\) training footprint; recomputing saved intermediates trades additional work for memory. Because every factor in the product combines activation derivatives with \(\RecurrentStateWeights\), the backpropagated signal attenuates or amplifies exponentially over long horizons, preventing a plain RNN from learning dependencies across more than a few dozen time steps unless the recurrence gives the state a selective bypass around \(\RecurrentStateWeights\).
Werbos, Paul J. 1990. “Backpropagation Through Time: What It Does and How to Do It.” Proceedings of the IEEE 78 (10): 1550–60. https://doi.org/10.1109/5.58337.
6.5.3 Gated recurrence
Gated recurrent architectures prevent long-horizon gradients from vanishing by replacing the unconditional state overwrite of equation 10 with learned gates, elementwise valves that decide at each step how much of the stored state to keep, overwrite, or expose. Each gate applies a sigmoid to a learned projection of the current input and previous state, producing values between zero and one that multiply the quantity it controls: a value near one passes that quantity through, and a value near zero blocks it. LSTMs19 (Hochreiter and Schmidhuber 1997) maintain a separate cell state beside the hidden state and govern it with input, forget, and output gates plus a candidate update. When the forget gate stays near one, the cell state passes from step to step almost unchanged, giving gradients a path across long horizons without being multiplied by \(\RecurrentStateWeights\) at every transition. GRUs20 (Cho et al. 2014) merge the same mechanism into two gates. For the machine, an LSTM step computes four affine transformations of the input and previous state instead of one, so it holds four times the recurrent weights, performs four times the multiply-accumulates per step, and carries twice the state (hidden and cell). Runtimes fuse the four projections into one matrix multiply four times as wide, which raises its arithmetic intensity without shortening the serial chain of steps.
19 LSTM (long short-term memory): Invented by Hochreiter and Schmidhuber in 1997, LSTMs introduced a “Constant Error Carousel,” a gated cell state that protects error signals from exponential decay during backpropagation through time. The systems cost is that a standard LSTM computes input, forget, and output gates plus a candidate cell update, giving roughly four affine transformations per time step vs. one in a vanilla RNN. Transformers replaced LSTMs in many large-scale language workloads not because attention costs less arithmetic, since it costs more, but because it parallelizes across sequence positions where a recurrence cannot.
Hochreiter, Sepp, and Jürgen Schmidhuber. 1997. “Long Short-Term Memory.” Neural Computation 9 (8): 1735–80. https://doi.org/10.1162/neco.1997.9.8.1735.
20 GRU (gated recurrent unit): Cho et al. (2014) describes a gated hidden unit for encoder-decoder translation that uses reset and update gates to control how the hidden state is updated. Relative to an LSTM’s input, forget, and output gates plus candidate cell update, this gives a simpler gated recurrence. The broader systems lesson: architectural simplification can reduce state and matrix operations when it preserves task performance, a principle that recurs in efficiency-oriented designs from MobileNet to distilled transformers.
Cho, Kyunghyun, Bart van Merrienboer, Dzmitry Bahdanau, and Yoshua Bengio. 2014. “On the Properties of Neural Machine Translation: Encoder-Decoder Approaches.” Proceedings of SSST-8, Eighth Workshop on Syntax, Semantics and Structure in Statistical Translation, 103–11. https://doi.org/10.3115/v1/w14-4012.
6.5.4 Computational mapping
In hardware, a recurrent step is two matrix products followed by an elementwise update. Convolution reuses each weight across a grid of positions available all at once (section 6.3.4.3); a recurrent step reuses its weights only across time, and each step must wait for the state the previous step produces.
Listing 5 demonstrates the single-time-step mechanism using framework-level matrix operations: combine the previous hidden state with the current input, add the bias, and apply the activation to produce the next hidden state. The code is intentionally local to one step because the systems cost is not the step itself, but the dependency chain that prevents parallel execution across time.
def rnn_layer_step(x_t, h_prev, W_hh, W_hx, b):
    # x_t: input at time t (batch_size × input_dim)
    # h_prev: previous hidden state (batch_size × hidden_dim)
    # W_hh: recurrent weights (hidden_dim × hidden_dim)
    # W_hx: input weights (input_dim × hidden_dim)
    h_t = activation(matmul(h_prev, W_hh) + matmul(x_t, W_hx) + b)
    return h_t
At the framework level, rnn_layer_step hides the underlying loop structure and memory traffic behind high-level matrix multiplications (matmul). In hardware, evaluating this step requires moving weights and activations through the memory hierarchy. To see where execution serializes and where parallelism remains, listing 6 expands the matrix operations into explicit loop nests down to scalar multiply-accumulate operations.
def rnn_layer_compute(x_t, h_prev, W_hh, W_hx, b):
    # Initialize next hidden state
    h_t = np.zeros_like(h_prev)

    # Loop 1: Process each sequence in the batch
    for batch in range(batch_size):
        # Loop 2: Compute recurrent contribution (h_prev × W_hh)
        for i in range(hidden_dim):
            for j in range(hidden_dim):
                h_t[batch, i] += h_prev[batch, j] * W_hh[j, i]

        # Loop 3: Compute input contribution (x_t × W_hx)
        for i in range(hidden_dim):
            for j in range(input_dim):
                h_t[batch, i] += x_t[batch, j] * W_hx[j, i]

        # Loop 4: Add bias and apply activation
        for i in range(hidden_dim):
            h_t[batch, i] = activation(h_t[batch, i] + b[i])

    return h_t
The loop structure exposes the concurrency boundaries of recurrent execution. Batch instances in Loop 1 are independent, so sequences within a batch parallelize across accelerator cores without cross-talk. Within each batch instance, Loops 2 and 3 execute the recurrent transformation (\(\RecurrentHiddenState_{t-1}\RecurrentStateWeights\)) and input projection (\(\LayerInputVector_t\RecurrentInputWeights\)). Both reductions must accumulate fully before Loop 4 can apply the elementwise bias addition and activation function to produce \(\RecurrentHiddenState_t\).
For an input dimension of 100 and a hidden state dimension of 128, each step executes two matrix multiplications: a \(100{\times}128\) input projection and a \(128{\times}128\) recurrent transformation. When batch size is large (\(\BatchSize\gg 1\)), these operations execute as general matrix-matrix multiplications (GEMM) that reuse each loaded weight across all \(\BatchSize\) samples. When batch size is small (\(\BatchSize=1\), typical of real-time streaming inference), they collapse into the same weight-streaming matrix-vector products as the batch-one dense layer of equation 2, which starve accelerator compute units.
6.5.5 System implications
The hard physical constraint that recurrent architectures impose is sequential dependency. In the update \(\RecurrentHiddenState_t = \tanh(\RecurrentStateWeights\RecurrentHiddenState_{t-1} + \RecurrentInputWeights\LayerInputVector_t)\), the recurrent transformation at time step \(\TimeStepIndex\) needs the state produced by step \(\TimeStepIndex-1\). An input sequence of length \(\SequenceLength= 1{,}000\) therefore requires \(1{,}000\) ordered state updates, even when a fused kernel executes several or all updates within one launch. Hardware can parallelize across batch instances and within each matrix operation; input projections can also be computed across time when the inputs are available. Faster arithmetic or memory shortens individual steps, while the recurrent dependency chain remains.
During inference, recurrent networks need little state memory. Because the recurrent state compresses history into a fixed-size vector \(\RecurrentHiddenState_t\), inference state memory scales as \(\mathcal{O}(\HiddenDimension)\) (for example, 2 KB for a 512-dimensional FP32 state), remaining completely flat whether sequence length \(\SequenceLength\) is 10 or 10,000 tokens. This constant memory footprint contrasts sharply with attention mechanisms (section 6.6), whose stored context grows with every token generated, an \(\mathcal{O}(\SequenceLength\cdot \HiddenDimension)\) store that the transformer section sizes. For streaming deployments on memory-constrained edge hardware, such as microcontrollers, an RNN’s \(\mathcal{O}(1)\) runtime state avoids the growing context store that limits attention-based models.
Recurrent execution splits the memory hierarchy between two behaviors: high temporal locality for parameters, and low operational intensity under standard framework dispatch. Weight matrices \(\RecurrentStateWeights\) and \(\RecurrentInputWeights\) are reused at every time step, residing comfortably in SRAM or L2 cache if the model fits on-chip. However, naively launching separate kernels for input projection, recurrent projection, bias addition, and activation at each time step incurs severe kernel-launch overhead and forces intermediate tensors back and forth across HBM. To mitigate this memory-bandwidth bottleneck, production recurrent runtimes fuse the projections, bias addition, and activation into a single monolithic kernel that maintains \(\RecurrentHiddenState_t\) within GPU registers and shared memory throughout the sequence execution. At batch one, each recurrent step is the dense layer’s matrix-vector product again, with the same energy profile. Unless the recurrent weights stay on chip from step to step, every step pays DRAM energy for every weight, about 139× the energy of its arithmetic, which is a second reason streaming runtimes keep those weights resident.
↪ What a fused kernel that holds its state in registers and shared memory costs in on-chip capacity and occupancy is developed in Kernel fusion on the accelerator.
Checkpoint 6.3: Recurrent state and the serial chain
Recurrence trades parallelism for a fixed memory budget. Check your understanding:
This architectural tension between fixed-capacity state and serialized execution defined sequence processing before transformers. While recurrent networks maintain constant memory overhead regardless of sequence length, the sequential dependency prevents hardware from parallelizing across time steps. The fixed-capacity state also becomes an information bottleneck in which early inputs fade over long spans, and gradients through long chains of recurrent steps vanish or explode (the vanishing gradient problem) (Bengio et al. 1994). State-space models such as Mamba (Gu and Dao 2023) later revived recurrence for exactly its systems strength, a fixed-size state at decode time where an attention model’s stored context grows, while training with a parallel scan instead of a step-by-step loop. Overcoming the serial chain and the fading state in general, however, required an architecture capable of establishing direct, content-addressable links across arbitrary sequence positions without intervening recurrent steps: the attention mechanism (section 6.6).
Bengio, Yoshua, Patrice Simard, and Paolo Frasconi. 1994. “Learning Long-Term Dependencies with Gradient Descent Is Difficult.” IEEE Transactions on Neural Networks 5 (2): 157–66. https://doi.org/10.1109/72.279181.
Gu, Albert, and Tri Dao. 2023. “Mamba: Linear-Time Sequence Modeling with Selective State Spaces.” arXiv Preprint arXiv:2312.00752.
Self-Check: Question
An RNN processes a sequence of length \(S = 1{,}000\) tokens with hidden state dimension \(d_{\text{hidden}} = 128\). Which statement correctly describes the scaling of its inference state memory versus its training activation memory?
- Inference state memory is \(\mathcal{O}(d_{\text{hidden}})\) (constant \(\mathcal{O}(1)\) with respect to sequence length \(S\)), whereas training with backpropagation through time (BPTT) requires storing activations across all steps, scaling as \(\mathcal{O}(S \cdot d_{\text{hidden}})\) under ordinary retained-state BPTT.
- Both inference state memory and training activation memory scale quadratically as \(\mathcal{O}(S^2)\) due to recurrent hidden-to-hidden weight matrices.
- Inference state memory scales linearly as \(\mathcal{O}(S \cdot d_{\text{hidden}})\), while training memory is constant because weights are shared across all time steps.
- Inference requires zero memory because recurrent states are discarded immediately after computing output probabilities.
Explain why upgrading an accelerator from 10 TFLOP/s to 100 TFLOP/s can reduce the elapsed time per recurrent step in an RNN processing a single long sequence, but cannot reduce the number of ordered state updates on the critical dependency chain. Contrast this with the parallel sequence processing capability of a transformer.
Because transformers offer superior parallelization and representational capacity for long-range dependencies, recurrent neural networks are entirely obsolete and have no valid deployment use cases in modern ML systems.
Order the mathematical and dataflow operations executed during a single time-step forward pass of a standard Elman RNN cell:
- Multiply the previous hidden state vector \(\mathbf{h}_{t-1}\) by the recurrent weight matrix \(\mathbf{W}_{\text{hh}}\)
- Multiply the current input vector \(\mathbf{x}_t\) by the input weight matrix \(\mathbf{W}_{\text{hx}}\)
- Sum the recurrent contribution, input contribution, and hidden bias vector \(\mathbf{b}_h\)
- Apply the nonlinear activation function (e.g., \(\tanh\)) to generate the new hidden state \(\mathbf{h}_t\)
- Multiply the new hidden state \(\mathbf{h}_t\) by the output weight matrix \(\mathbf{W}_{\text{yh}}\) to produce output \(\mathbf{y}_t\)
During backpropagation through time (BPTT) over \(S\) time steps, the gradient of the loss with respect to the initial hidden state satisfies \(\frac{\partial \mathcal{L}}{\partial \mathbf{h}_0} \propto \prod_{t=1}^S \frac{\partial \mathbf{h}_t}{\partial \mathbf{h}_{t-1}}\). Explain the mathematical mechanism that causes gradients to vanish or explode as \(S\) grows large.
In a standard RNN layer with input dimension \(d_{\text{in}} = 100\) and hidden state dimension \(d_{\text{hidden}} = 128\), how many total multiply-accumulate (MAC) operations are performed per sequence step to compute the unactivated hidden state?
- 12,800 MACs, because only the input projection performs matrix multiplication.
- 29,184 MACs, consisting of \(128 \times 128 = 16{,}384\text{ MACs}\) for the recurrent projection plus \(100 \times 128 = 12{,}800\text{ MACs}\) for the input projection.
- 1,280,000 MACs, because recurrence multiplies all hidden states across all past time steps simultaneously.
- 256 MACs, because an RNN updates only a single vector addition per step.
6.6 Attention: Dynamic Processing
Recurrent networks serialize execution along the sequence dimension and compress all historical context into a fixed-capacity hidden state vector (section 6.5.5). In a sentence such as “The cat, which was sitting by the window overlooking the garden, was sleeping,” the subject “cat” and predicate “sleeping” are separated by ten intervening words, yet they form the core syntactic and semantic relationship. An RNN must process all intervening tokens sequentially, risking information loss across intermediate recurrent transitions while preventing hardware from parallelizing across time steps. This constraint motivates an alternative computational pattern: an operation that directly computes relevance between any two positions regardless of distance.
Attention mechanisms21 address this limitation (Bahdanau et al. 2015) by introducing dynamic connectivity patterns that adapt to input content. The setting was sequence-to-sequence translation, built as an encoder-decoder pair. An encoder network reads the input sentence into one representation per input position, and a decoder network generates the output sentence one token at a time, carrying its own recurrent decoder state. Recurrent versions of that pair passed only the encoder’s final state to the decoder. Rather than forcing all context through that single fixed-capacity vector, encoder-decoder attention computes similarity scores between the decoder state at each output step and all encoder positions, routing information dynamically across the sequence. A single decoder step compares one query with every encoder position. In full-sequence self-attention, each position queries all positions in the same sequence, so the number of score interactions grows quadratically with sequence length.
21 Bahdanau attention: This approach broke the “fixed-length vector” bottleneck of prior sequence-to-sequence models. The core trade-off was accepting a linear, \(\mathcal{O}(\SequenceLength)\) memory cost to store all input states in exchange for overcoming the information loss inherent in a single vector.
Definition 6.5: Attention mechanisms
Attention mechanisms are neural network operations that compute a weighted sum of value vectors, where the weights are derived from learned similarity scores between a query vector and a set of key vectors, enabling dynamic, content-dependent information routing between any two positions in a sequence.
- Significance: Attention connects any two tokens in \(\mathcal{O}(1)\) depth but computes \(\SequenceLength^2\) score interactions. If those scores are materialized, a 4,096-token sequence with 16-bit scores consumes 33.6 MB per layer per head (about 16.8M scores at 2 bytes each), directly increasing the iron law’s \(\DataVolume\) term.
- Distinction: Unlike RNNs, which compress all prior context into a single fixed-size state vector, attention mechanisms retain every token’s representation and compare tokens directly. When a model generates text one token at a time, it keeps the key and value vectors of earlier tokens rather than recomputing them, and that key-value (KV) cache grows as \(\mathcal{O}(\SequenceLength \HiddenDimension)\); the transformer section explains generation and sizes the cache.
- Common pitfall: A frequent misconception is that attention is a general-purpose weighting scheme that can be applied freely. Quadratic score computation is a hard scaling constraint: doubling the context quadruples score interactions. Naive implementations also quadruple score storage; tiled exact algorithms such as FlashAttention avoid the full matrix, while sparse variants reduce the scores computed (Child et al. 2019).
Child, Rewon, Scott Gray, Alec Radford, and Ilya Sutskever. 2019. “Generating Long Sequences with Sparse Transformers.” arXiv Preprint arXiv:1904.10509.
22 Transformer: The founding paper, “Attention Is All You Need,” made the explicit systems claim that a parallel attention mechanism could fully replace sequential recurrent processing. This architectural trade eliminates an RNN’s \(\mathcal{O}(\SequenceLength)\) path length constraint on parallelism but introduces \(\mathcal{O}(\SequenceLength^2)\) dense score computation, a quadratic cost that continues to shape context-window engineering.
The ability of attention to connect any position to any other made the recurrent structure unnecessary for many sequence tasks. The transformer22 (Vaswani et al. 2017) removed recurrence entirely, trading the RNN’s \(\mathcal{O}(\SequenceLength)\) sequential path for constant path length between positions within one attention layer and thereby enabling parallelization across sequence positions on high-throughput accelerators.
Attention functions as a computational primitive rather than an independent architecture family. The transformer (section 6.7), the family built around it, inherits its core systems properties directly from attention: content-dependent routing, parallel sequence execution, and quadratic score scaling. Evaluating those properties begins with the dynamic pattern-processing problem that attention addresses.
6.6.1 Pattern processing needs
In “the trophy did not fit in the suitcase because it was too big,” the word “it” refers to “trophy,” but if “big” changes to “small,” “it” refers to “suitcase.” The same positions, at the same distances, need different links depending on what the words mean. Neither a CNN’s fixed spatial window nor an RNN’s step-by-step hidden state can route information directly between arbitrary positions based on content. Dynamic sequence processing needs an operation that scores relationships from the tokens themselves, letting each word draw directly on the words that matter to it regardless of how far apart they sit (figure 9).
The bipartite connection lines in figure 9 illustrate how the pronoun “they” could receive information from “student” and “finish.” The hypothetical weights demonstrate a direct routing path, not a measured coreference result. Pairwise connections can be evaluated in parallel, allowing a single layer to connect these positions without propagating intermediate state across intervening tokens.
Input-dependent processing extends well beyond language. In protein structure prediction, amino-acid interactions depend on chemical properties and spatial arrangement, not only chain position; in document analysis, connections between sections depend on semantic content rather than proximity. Graph convolutional networks (GCNs) (Kipf and Welling 2017) share attention’s input-dependent routing but gather features along the sparse edges of each input graph, producing irregular memory access that can bind execution on memory bandwidth and cache misses rather than compute throughput.
Kipf, Thomas N, and Max Welling. 2017. “Semi-Supervised Classification with Graph Convolutional Networks.” International Conference on Learning Representations (ICLR).
Input dependence does not imply all-to-all connectivity. Dense attention scores every pair of sequence elements, whereas a GCN restricts aggregation to edges in the observed graph. The common systems challenge is that the computation or memory-access pattern responds to the input rather than following a fixed stencil. Even when tensor dimensions stay fixed, content-dependent scores determine which information is emphasized. Attention provides one mechanism for learning such relationships, and dense self-attention forms the foundation of the transformer architecture.
6.6.2 Algorithmic structure
To route information dynamically (section 6.6.1), the network needs an operator that turns a variable-length sequence into content-dependent weights (Bahdanau et al. 2015). The transformer architecture computes these weights with the scaled dot-product attention operator introduced by Vaswani et al. (2017): \[ \text{Attention}(\AttentionQueryMatrix, \AttentionKeyMatrix, \AttentionValuesMatrix) = \text{softmax} \left(\frac{\AttentionQueryMatrix\AttentionKeyMatrix^T}{\sqrt{\AttentionHeadDimension}}\right)\AttentionValuesMatrix\]
23 Query-key-value (QKV): The terminology is borrowed from information retrieval, explaining why the equation uses three distinct learned projections to calculate pairwise scores. Creating these projections requires three independent weight matrices, costing \(3 \times \HiddenDimension^2\) parameters per layer. Storing the key and value projections of earlier tokens is what produces the key-value (KV) cache of autoregressive serving (section 6.7.4.2).
For this self-attention case, the inputs \(\AttentionQueryMatrix\) (queries), \(\AttentionKeyMatrix\) (keys), and \(\AttentionValuesMatrix\) (values)23 are learned linear projections of the token representations (\(\AttentionQueryMatrix= \LayerInputMatrix\QueryProjectionMatrix\), \(\AttentionKeyMatrix= \LayerInputMatrix\KeyProjectionMatrix\), \(\AttentionValuesMatrix= \LayerInputMatrix\AttentionValuesProjectionMatrix\)). Attention uses three separate projection matrices rather than computing dot-product affinities directly between raw tokens (\(\LayerInputMatrix\LayerInputMatrix^T\)) for two architectural reasons:
- Asymmetric relationships: Direct token dot products \(\LayerInputVector_i \cdot \LayerInputVector_j\) are symmetric (\(\LayerInputVector_i \cdot \LayerInputVector_j = \LayerInputVector_j \cdot \LayerInputVector_i\)), whereas relationships in language are not. In “the chef cooked the meal,” the verb “cooked” looks for its direct object (“meal”), while “meal” plays a different role, so the two directions of the pair need different scores. Splitting the projection into a query (what a token looks for) and a key (what a token offers) lets \(\CookedTokenQueryVector\cdot \MealTokenKeyVector\) be high while \(\MealTokenQueryVector\cdot \CookedTokenKeyVector\) stays low.
- Separating where to look from what to pass on: The dot products \(\AttentionQueryMatrix\AttentionKeyMatrix^T\) decide where to look (routing weights), while the value projection \(\AttentionValuesMatrix\) decides what information to retrieve. Without a separate value projection, a token that serves mainly as a structural marker (such as a preposition or punctuation mark) would pass its entire raw embedding into later layers. Projecting through \(\AttentionValuesProjectionMatrix\) lets the network strip away surface token identity and pass along only the features downstream layers need.
For an input sequence of length \(\SequenceLength\) projected to a dimension \(\AttentionHeadDimension\) (here the full width \(\HiddenDimension\); the transformer’s multi-head attention later splits that width across several parallel attention computations called heads), the dot product \(\AttentionQueryMatrix\AttentionKeyMatrix^T\) computes all \(\SequenceLength^2\) pairwise token similarities. Scaling by \(1/\sqrt{\AttentionHeadDimension}\) prevents dot products from growing large in magnitude at high dimensions, which would push softmax into regions with vanishingly small gradients. The softmax operator24 normalizes each row of the score matrix into a probability distribution over key positions. Finally, multiplying these normalized weights by \(\AttentionValuesMatrix\) produces output vectors formed as weighted combinations of the value representations.
24 Softmax: Named as a “soft” (differentiable) version of argmax, with mathematical roots in Boltzmann’s statistical mechanics, softmax normalizes each query row over all \(\SequenceLength\) scores and therefore requires a reduction over each row. Online softmax lets that reduction run over tiles with running statistics, which is why it need not force quadratic storage (section 6.6.4.1).
↪ The dot product as a similarity measure is collected for reference in The dot product as similarity.
Figure 10 traces this dataflow for a sequence of length \(\SequenceLength= 6\): cyan query rows match against red key columns to populate the \(6{\times}6\) similarity matrix, whose rows subsequently weight the green value vectors to produce the contextualized output vectors on the right. Each row of the resulting \(\SequenceLength{\times}\SequenceLength\) matrix determines how strongly an individual token attends to every token in the sequence. In a trained model, the largest affinity values reflect strong contextual dependencies, while near-zero entries suppress irrelevant positions.
While attention weights vary dynamically with the input tokens, generating the query, key, and value vectors requires static linear projections against learned parameter matrices. In accelerator implementations, these three operations are fused into a single batched matrix multiplication to maximize Tensor Core saturation and reduce kernel launch overhead. Packing the three weight matrices side by side turns three projections into one (figure 11). The \(6{\times}768\) token embedding matrix (one learned 768-value vector per token) multiplies a \(768{\times}2304\) weight matrix whose three 768-column blocks hold the query, key, and value weights. Adding the bias yields a \(6{\times}2304\) output that contains all three projections, computed in a single kernel pass.
Cho, Aeree, Grace C. Kim, Alexander Karpekov, Alec Helbling, Zijie J. Wang, Seongmin Lee, Benjamin Hoover, and Duen Horng (Polo) Chau. 2025. “TRANSFORMER EXPLAINER: Interactive Learning of Text-Generative Models.” Proceedings of the AAAI Conference on Artificial Intelligence 39 (28): 29625–27. https://doi.org/10.1609/aaai.v39i28.35347.
6.6.3 Computational mapping
Lowering the attention operator \(\text{Attention}(\AttentionQueryMatrix, \AttentionKeyMatrix, \AttentionValuesMatrix) = \text{softmax}(\AttentionQueryMatrix\AttentionKeyMatrix^T/\sqrt{\AttentionHeadDimension})\AttentionValuesMatrix\) to physical execution exposes the system cost of data-dependent connectivity. Evaluating pairwise alignments requires two distinct matrix multiplications per attention head: the score GEMM (\(\AttentionQueryMatrix\AttentionKeyMatrix^T\)) and the context GEMM (\(\AttentionWeightMatrix\AttentionValuesMatrix\), where \(\AttentionWeightMatrix= \text{softmax}(\AttentionQueryMatrix\AttentionKeyMatrix^T/\sqrt{\AttentionHeadDimension})\)). For an input of sequence length \(\SequenceLength\) and head dimension \(\AttentionHeadDimension\), each phase executes \(\SequenceLength^2 \AttentionHeadDimension\) multiply-accumulate operations, yielding \(\mathcal{O}(\SequenceLength^2 \AttentionHeadDimension)\) computational complexity per head.
Listing 7 contrasts the high-level matrix formulation with an explicit loop implementation that exposes this quadratic scaling. The matrix version lowers to optimized GEMM routines on accelerator Tensor Cores, whereas the loop version reveals the underlying physical execution structure: batch iterations, quadratic query-key inner products, row-wise softmax reductions, and the final value accumulation pass across all sequence positions.
def attention_layer_matrix(Q, K, V):
    # Q, K, V: (batch_size × seq_len × d_head)
    # Compute attention scores
    scores = matmul(Q, K.transpose(-2, -1)) / sqrt(d_head)
    weights = softmax(scores)  # Normalize scores
    output = matmul(weights, V)  # Combine values
    return output

def attention_layer_compute(Q, K, V):
    # Initialize outputs
    scores = np.zeros((batch_size, seq_len, seq_len))
    outputs = np.zeros_like(V)

    # Loop 1: Process each sequence in batch
    for b in range(batch_size):
        # Loop 2: Compute attention for each query position
        for i in range(seq_len):
            # Loop 3: Compare with each key position
            for j in range(seq_len):
                # Compute attention score
                for d in range(d_head):
                    scores[b, i, j] += Q[b, i, d] * K[b, j, d]
                scores[b, i, j] /= sqrt(d_head)

        # Apply softmax to scores
        for i in range(seq_len):
            scores[b, i] = softmax(scores[b, i])

        # Loop 4: Combine values using attention weights
        for i in range(seq_len):
            for j in range(seq_len):
                for d in range(d_head):
                    outputs[b, i, d] += scores[b, i, j] * V[b, j, d]

    return outputs
6.6.4 System implications
Attention eliminates the latency-bound serial path of RNNs, but a naive implementation replaces it with an \(\SequenceLength{\times}\SequenceLength\) attention-score matrix that grows quadratically with sequence length \(\SequenceLength\). In iron law terms, dense attention trades serial recurrent steps for pairwise score arithmetic and heavy intermediate data movement. Some of these costs are inherent to computing all-to-all interactions; others come only from materializing the full score matrix in memory.
Memory requirements
Materializing an \(\SequenceLength{\times}\SequenceLength\) attention-weight matrix for every sequence and head creates a quadratic memory bottleneck that quickly dwarfs both the \(\SequenceLength{\times}\HiddenDimension\) activations and the fixed-size projection weights on long inputs. Tiled exact-attention kernels such as FlashAttention stream score blocks through on-chip SRAM and avoid writing the full score matrix to HBM. They still compute all \(\SequenceLength^2\) dense interactions (FlashAttention: IO-aware attention optimization develops the I/O-aware tiling in full, and Tiled attention and online softmax collects the online softmax recurrence for reference). This distinction separates the unavoidable quadratic compute cost of dense attention from the avoidable quadratic memory footprint of storing the full score matrix in HBM.
Doubling context quadruples score interactions and naive score storage.
Napkin Math 6.1: The quadratic bottleneck
Problem: How much memory does a materialized attention matrix require at sequence length \(\SequenceLength =\) 100,000 (context window)?
Math:
- Matrix size: The attention score matrix \((\AttentionQueryMatrix\AttentionKeyMatrix^T)\) has dimensions \(\SequenceLength{\times}\SequenceLength\) per head, across \(\AttentionHeadCount\) heads (12 heads in this example).
- Elements: 100,000 \(\times\) 100,000 \(\times\) 12 heads = 1.2 × 10¹¹ elements.
- Memory: At FP16 (2 bytes/element): 1.2 × 10¹¹ \(\times\) 2 bytes = 240 GB.
- Retained layers: 240 GB per layer \(\times\) 32 retained layers = 7,680 GB.
Systems insight: A materialized attention matrix consumes 240 GB per layer. Naive training that retains all 32 layers’ scores for backward would require 7,680 GB, far exceeding any single GPU’s capacity. This memory wall motivates two broad implementation strategies: avoid materializing the full matrix by tiling the computation, or reduce the number of scores computed in the first place.
Computation and data movement
Attention computation splits into two primary GEMM phases interleaved by a row-wise reduction: generating pairwise query-key scores and computing weighted sums over values. Query-key inner products require \(\BatchSize \times \AttentionHeadCount \times \SequenceLength^2 \times \AttentionHeadDimension\) MAC operations, mirrored symmetrically by the value-aggregation stage. The intervening softmax requires row-wise maximum finding, exponentiation, and summation. Unlike static weight convolutions where filter weights are reused across fixed grid positions, attention computes transient, input-dependent affinity matrices that must be refreshed for every token configuration.
Data movement in attention creates memory access patterns distinct from fixed-stencil operations. Evaluating attention requires projecting and streaming query, key, and value tensors, then routing value vectors according to dynamically evaluated scores. In naive implementations, staging the intermediate \(\SequenceLength \times \SequenceLength\) score matrix in global HBM/DRAM turns score materialization into the dominant bandwidth bottleneck. While static convolutions benefit from deterministic cache lines and RNNs reuse weights across time, naive attention generates large, short-lived activation footprints that challenge standard on-chip cache capacities.
Checkpoint 6.4: Quadratic scaling intuition
Long-context scaling is shaped by the cost of attention. Verify your intuition:
Attention replaces the serialized hidden-state bottleneck of recurrent models with dynamic, constant-depth routing, but shifts the system burden to score arithmetic and memory bandwidth traffic. Built into a full architecture without recurrence, this primitive enables end-to-end parallel sequence processing on modern accelerators. The transformer architecture (section 6.7) builds directly on this foundation, establishing the dominant architecture for modern large-scale machine learning systems.
Self-Check: Question
Why does scaled dot-product attention divide the query-key dot product \(\mathbf{Q}\mathbf{K}^T\) by \(\sqrt{d_{\text{head}}}\) prior to applying the softmax normalization function?
- To convert the matrix multiplication into a sparse graph lookup that reduces compute complexity from \(\mathcal{O}(S^2)\) to \(\mathcal{O}(S)\).
- Scaling limits the magnitude of attention scores as \(d_{\text{head}}\) grows, helping keep softmax from saturating too sharply; it does not remove quadratic score computation or guarantee universal overflow protection.
- To force the sum of all elements in the unnormalized query-key matrix to equal exactly 1.0 before applying softmax.
- To eliminate the need for Key weight matrices by making Query and Value representations mathematically identical.
Consider a single transformer self-attention layer processing a sequence of length \(S = 4{,}096\) with \(N_{\text{heads}} = 12\) attention heads in FP16 precision (2 bytes per score). Calculate the memory required to store the materialized attention score matrices \((\mathbf{Q}\mathbf{K}^T)\) for this single layer, and explain why doubling the context length to \(S = 8{,}192\) creates a super-linear memory wall.
True or False: IO-aware algorithms like FlashAttention reduce the computational complexity of dense self-attention from \(\mathcal{O}(S^2)\) down to \(\mathcal{O}(S)\) floating-point operations.
In the scaled dot-product attention mechanism, the input sequence is projected into three distinct learned representations known as Queries, Keys, and ____, drawing a direct analogy to content-addressable retrieval systems.
In an attention layer with sequence length \(S = 512\) and per-head feature dimension \(d_k = 64\), how many multiply-accumulate (MAC) operations are required to compute the query-key attention scores \((\mathbf{Q}\mathbf{K}^T)\) for a single attention head, excluding softmax normalization and value aggregation?
- 32,768 MACs, calculated as \(512 \times 64\).
- 262,144 MACs, calculated as \(512 \times 512\).
- 1,048,576 MACs, calculated as \(512 \times 512 \times 4\).
- 16,777,216 MACs (~16.8 million MACs), calculated as \(S \times S \times d_k = 512 \times 512 \times 64\).
6.7 Transformers: Parallel Sequence Processing
Attention provides the computational primitive of dynamic, content-dependent routing between positions, yet it was originally layered on top of recurrent architectures, inheriting their sequential bottleneck. The transformer architecture removes recurrence and makes attention the operation that mixes information between positions in every layer. This enables parallel computation across sequence positions during full-sequence processing while retaining dynamic connectivity. This architectural shift introduces distinct physical costs: quadratic attention-score cost over long inputs, a store of per-token state that grows while the model generates text, and memory-bandwidth pressure when it generates one token at a time.
Definition 6.6: Transformers
Transformers are neural network architectures that combine self-attention, feed-forward layers, residual connections, normalization, and positional information without recurrence, enabling parallel processing across sequence positions during training and prompt processing.
- Significance: Parallelism is the systems payoff. An RNN processing an \(\SequenceLength\)-token sequence executes \(\SequenceLength\) sequentially dependent steps. A transformer processes all positions of a sequence concurrently, mapping token interactions to large matrix multiplications (GEMMs) that maximize accelerator compute utilization. Dense self-attention retains the pairwise score cost (section 6.6.4.1).
- Distinction: Unlike attention used inside a recurrent backbone, which inherits the host architecture’s \(\mathcal{O}(\SequenceLength)\) sequential path, transformers use attention as the primary mixing operation between positions, alternating it with position-wise feed-forward networks.
- Common pitfall: A frequent misconception is that transformers have “infinite context.” Two distinct memory footprints matter: the \(\mathcal{O}(\SequenceLength^2)\) attention-score activation matrix when it is materialized over a long input, and the \(\mathcal{O}(\SequenceLength)\) key-value (KV) cache that accumulates while the model generates text. At long sequence lengths, the KV cache footprint can rival or exceed the static model weights, turning KV cache management and memory-bandwidth efficiency into dominant engineering constraints.
6.7.1 Pattern processing needs
The recurrent sequence-to-sequence hybrids that first carried attention (Sutskever et al. 2014; Bahdanau et al. 2015) fixed the single-vector information bottleneck of section 6.5.5, yet step \(\TimeStepIndex\) still waited on step \(\TimeStepIndex-1\): a 1,000-token input still paid 1,000 ordered state updates no matter how many matrix units the accelerator offered. Dropping the recurrent loop so all 1,000 tokens can be processed at once places three pattern-processing demands on the replacement block. It must link any two positions within the same sequence in a single parallel pass; it must inject sequence order explicitly, because without step-by-step state updates an all-to-all operation cannot tell whether one word came before or after another; and it must apply nonlinear feature transformations within each position after routing information between them. The transformer architecture (Vaswani et al. 2017) meets those three requirements by pairing self-attention with positional encodings and position-wise feed-forward networks, trading the spatial parameter efficiency of CNNs and the bounded \(\mathcal{O}(1)\) step state of RNNs for unconstrained sequence parallelism during training and prompt processing.
Sutskever, Ilya, Oriol Vinyals, and Quoc V. Le. 2014. “Sequence to Sequence Learning with Neural Networks.” Advances in Neural Information Processing Systems (NeurIPS) 27: 3104–12.
6.7.2 Algorithmic structure
To link tokens within a single sequence in one parallel pass, the transformer uses the self-attention projection introduced in section 6.6.2. Whereas encoder-decoder attention draws queries from a target sequence and keys and values from a separate source sequence, self-attention applies all three learned projection matrices (\(\QueryProjectionMatrix\), \(\KeyProjectionMatrix\), and \(\AttentionValuesProjectionMatrix\)) to the same input sequence \(\LayerInputMatrix\), as equation 11 writes in full: \[ \text{SelfAttention}(\LayerInputMatrix) = \text{softmax} \left(\frac{\LayerInputMatrix\QueryProjectionMatrix(\LayerInputMatrix\KeyProjectionMatrix)^T}{\sqrt{\AttentionHeadDimension}}\right)\LayerInputMatrix\AttentionValuesProjectionMatrix \tag{11}\]
Without positional information or an attention mask, matrix multiplication and row-wise softmax operate symmetrically across the token dimension, which makes self-attention permutation-equivariant. Shuffling the rows of \(\LayerInputMatrix\) merely shuffles the output rows identically, treating the sequence as an unordered set. Positional encodings, whether added as sinusoidal vectors or applied via rotary position embeddings (Su et al. 2024), inject sequence order and relative distance.
Su, Jianlin, Murtadha Ahmed, Yu Lu, Shengfeng Pan, Wen Bo, and Yunfeng Liu. 2024. “RoFormer: Enhanced Transformer with Rotary Position Embedding.” Neurocomputing 568: 127063. https://doi.org/10.1016/j.neucom.2023.127063.
25 Attention scaling \((\sqrt{\AttentionHeadDimension})\): This normalization directly counteracts the linear growth in variance \((\AttentionHeadDimension)\) of the query-key dot product, preventing the softmax function from saturating where gradients would otherwise vanish. The systems consequence is most acute in mixed-precision training: when activations grow large, unscaled dot products can produce logits that overflow the 16-bit float range, destabilizing or halting learning entirely.
Conceptually, attention implements a differentiable content-addressable memory. Whereas conventional memory architectures retrieve stored values at explicit addresses, self-attention uses the query vector \(\QueryVector_i\) to score similarity against all candidate keys \(\AttentionKeyMatrix\in \mathbb{R}^{\SequenceLength\times \AttentionHeadDimension}\). The resulting softmax distribution generates a continuous interpolation over the value vectors \(\AttentionValuesMatrix\in \mathbb{R}^{\SequenceLength\times \AttentionHeadDimension}\), functioning as a differentiable lookup operation. The \(\sqrt{\AttentionHeadDimension}\) divisor keeps that lookup numerically well-conditioned via a variance argument: if query and key components are independent random variables with zero mean and unit variance, their inner product \(\QueryVector_i \cdot \KeyVector_j = \sum_{\HeadComponentIndex=1}^{\AttentionHeadDimension} \QueryComponent \KeyComponent\) has zero mean and variance \(\AttentionHeadDimension\), so dividing by \(\sqrt{\AttentionHeadDimension}\) restores unit variance and keeps softmax out of its saturated, near-zero-gradient region at large head dimensions.25
Transformers extend single-head self-attention by executing multiple attention operations in parallel through multi-head attention. Instead of computing a single set of attention weights over \(\HiddenDimension\) dimensions, the architecture projects queries, keys, and values into \(\AttentionHeadCount\) distinct lower-dimensional subspaces of dimension \(\AttentionHeadDimension = \HiddenDimension/ \AttentionHeadCount\). Each head can learn a different pattern. Their outputs are concatenated and projected through an output matrix \(\AttentionOutputProjectionMatrix\), as formalized in equation 12: \[ \text{MultiHead}(\QuerySourceMatrix, \KeySourceMatrix, \AttentionValuesSourceMatrix) = \text{Concat}(\text{head}_1, \ldots, \text{head}_{\AttentionHeadCount})\AttentionOutputProjectionMatrix \tag{12}\] where each attention head is computed as follows. In this multi-head notation, \(\QuerySourceMatrix\), \(\KeySourceMatrix\), and \(\AttentionValuesSourceMatrix\) denote the source representations before the head-specific projections; for self-attention, all three are \(\LayerInputMatrix\). The head matrices apply the projections once: \[ \text{head}_i = \text{Attention}(\QuerySourceMatrix\HeadQueryProjectionMatrix, \KeySourceMatrix\HeadKeyProjectionMatrix, \AttentionValuesSourceMatrix\HeadValuesProjectionMatrix) \]
Although individual attention heads often specialize in distinct syntactic or semantic patterns (Clark et al. 2019), adapting the effective connectivity graph to each input sequence, empirical analyses reveal substantial head redundancy and acute numerical sensitivity in reduced-precision formats. These hardware-relevant behaviors motivate structural pruning, low-rank factorization, sparse attention patterns, and specialized quantization strategies.
Clark, Kevin, Urvashi Khandelwal, Omer Levy, and Christopher D. Manning. 2019. “What Does BERT Look at? An Analysis of BERT’s Attention.” Proceedings of the 2019 ACL Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP, 276–86. https://doi.org/10.18653/v1/w19-4828.
To build deep networks from these dynamic projections, the transformer places self-attention inside a repeating block (figure 12). Each block wraps multi-head attention and position-wise feed-forward sublayers with residual connections and layer normalization. Sinusoidal positional encodings combine with token embeddings at the base of both towers, feeding repeated multi-head attention and feed-forward stages before terminating in linear and softmax output heads. Because all positions can be processed in parallel rather than sequentially, the architecture trades recurrent state for large matrix operations that map well to accelerator training. A decoder-only model such as GPT-2 keeps only the right-hand tower of this figure, without the attention that reads an encoder’s output. Tokens enter as embedding vectors, pass through the stack of blocks, and leave as a probability distribution over the vocabulary for the next token. The residual paths and normalization layers in this stack are shared building blocks rather than transformer inventions; section 6.4.1 and section 6.4.2 explain why they make deep stacks trainable and what each costs the machine.
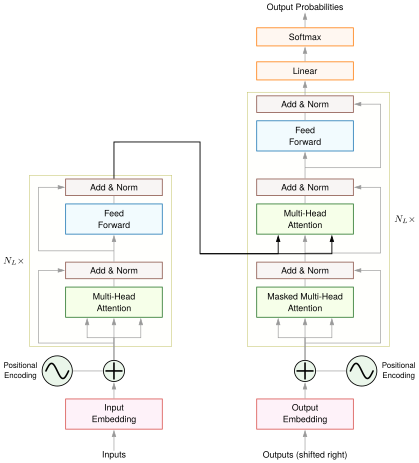
Vaswani, Ashish, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. 2017. “Attention Is All You Need.” Advances in Neural Information Processing Systems (NeurIPS) 30: 5998–6008.
Language models built from this block are usually autoregressive: they produce text one token at a time and feed each new token back as input for the next. Given the prompt “The cat sat on,” a model predicts “the,” appends it, predicts “mat” from the longer context, and continues until it emits an end token. A causal mask keeps that process honest. It sets the attention scores for later positions to negative infinity before the softmax, so each position attends only to itself and earlier tokens, exactly the information that will exist when the model generates.
The same mask is what lets training run in parallel. During next-token training the whole target sequence is already known, so shifting it right by one position pairs every input token with its successor (figure 12), and the mask guarantees that position \(\TimeStepIndex\) cannot see later tokens. An accelerator therefore evaluates every position at once with dense matrix multiplications instead of stepping through a serial time loop as an RNN must.
Generation splits into two phases with different machine profiles, drawn in figure 13. Prefill processes the whole prompt in one pass: every prompt token is known, so the model evaluates them in parallel, as in training, and stores each token’s keys and values. Decode then produces the remaining tokens one per step. Each step feeds a single token through the model, so its projections shrink from matrix-matrix to matrix-vector products, and its attention reads the stored keys and values of every earlier token instead of recomputing them. That store is the key-value (KV) cache, and section 6.7.4.2 shows why decode, not prefill, usually sets a language model’s serving cost.
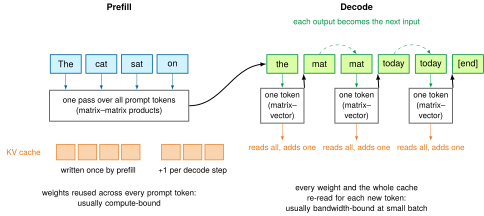
6.7.3 Computational mapping
In code, self-attention is three projections of the same input followed by the attention operator, and multi-head attention runs several smaller copies side by side before a final projection (listing 8). Writing both layers side by side shows how the multi-head variant partitions the hidden dimension across heads without changing the per-head attention kernel.
def self_attention_layer(X, W_Q, W_K, W_V, d_head):
    # X: input tensor (batch_size × seq_len × d_model)
    # W_Q, W_K, W_V: weight matrices (d_model × d_head)

    Q = matmul(X, W_Q)
    K = matmul(X, W_K)
    V = matmul(X, W_V)

    scores = matmul(Q, K.transpose(-2, -1)) / sqrt(d_head)
    attention_weights = softmax(scores, dim=-1)
    output = matmul(attention_weights, V)

    return output

def multi_head_attention(X, W_Q, W_K, W_V, W_O, num_heads, d_head):
    outputs = []
    for i in range(num_heads):
        head_output = self_attention_layer(
            X, W_Q[i], W_K[i], W_V[i], d_head
        )
        outputs.append(head_output)

    concat_output = concat(outputs, axis=-1)
    final_output = matmul(concat_output, W_O)

    return final_output
The attention listing accounts for information mixing across positions, but a complete block also transforms features within each position. An ordinary position-wise feed-forward network applies a dense projection from hidden width \(\HiddenDimension\) to an intermediate layer output width \(\LayerOutputWidth\), a nonlinear activation, and a second dense projection back to \(\HiddenDimension\). For a sequence of length \(\SequenceLength\), its tensor shapes follow \(\SequenceLength{\times}\HiddenDimension \to \SequenceLength{\times}\LayerOutputWidth \to \SequenceLength{\times}\HiddenDimension\). The same two weight matrices apply independently at every position, so the MLP accounting gives \(2\SequenceLength\HiddenDimension\LayerOutputWidth\) MACs and an intermediate tensor with \(\SequenceLength\LayerOutputWidth\) elements.
For one full-sequence block at batch one, with one standard multi-head self-attention sublayer and that two-layer feed-forward network, the query, key, value, and output projections together require \(4\SequenceLength\HiddenDimension^2\) MACs. The two attention products add \(2\SequenceLength^2\HiddenDimension\) MACs across all heads, whose widths sum to \(\HiddenDimension\). Adding the feed-forward cost completes the block’s matrix-product account. These counts omit biases, softmax, normalization, nonlinear activations, and residual additions, and assume dense evaluation of all position pairs. At fixed widths, projections and the feed-forward network grow linearly with sequence length, while the pairwise products grow quadratically. Which part dominates therefore depends on both the sequence length and the chosen widths, even before memory traffic is measured.
During autoregressive inference, generating output tokens step-by-step reintroduces sequential serialization. At batch one, projection matrix multiplications become matrix-vector operations with less weight reuse, making off-chip bandwidth a likely limit when weights exceed cache capacity, as quantified in section 6.7.4 via the GPT-2 XL lighthouse.
6.7.4 System implications
The quadratic bottleneck analyzed in section 6.6.4 manifests differently across execution regimes. Because full-sequence training and prompt prefill operate on known token sequences under causal masking, accelerators evaluate all positions concurrently using dense matrix multiplications. Autoregressive decoding, by contrast, must generate each token before predicting the next. That loss of token concurrency reduces weight reuse and can shift the primary performance limit from arithmetic throughput to memory bandwidth and state retrieval. Sequence length, batch size, and memory hierarchy limits determine whether that transition occurs.
Training and prefill
During training and prompt prefill, all token positions are processed in parallel, allowing accelerator Tensor Cores to achieve high floating-point utilization, but dense attention’s score computation grows as \(\mathcal{O}(\SequenceLength^2)\) with sequence length \(\SequenceLength\). I/O-aware tiling such as FlashAttention (Dao et al. 2022) keeps the score matrix out of HBM (section 6.6.4.1), so the quadratic arithmetic, not its storage, is the wall that remains.
Dao, T., D. Y. Fu, S. Ermon, A. Rudra, and C. Ré. 2022. “FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness.” Advances in Neural Information Processing Systems (NeurIPS) 35: 16344–59. https://doi.org/10.52202/068431-1189.
That wall arrives later than its name suggests. By the block account of section 6.7.3, with a feed-forward width four times the model width, a block’s projections and feed-forward network cost \(12\SequenceLength\HiddenDimension^2\) multiply-accumulates against \(2\SequenceLength^2\HiddenDimension\) for the attention products. Attention’s arithmetic therefore dominates only once the sequence passes about six times the model width, near 9,600 tokens for GPT-2 XL. Shorter training sequences are bound by the ordinary dense matrix multiplies, and the quadratic wall is a long-context phenomenon.
Expanding sequence length \(\SequenceLength\) challenges accelerator memory hierarchies because full-sequence self-attention cost grows with context length. Product context windows grew from 2K tokens to beyond 128K and into the 1M-token range within a few years (OpenAI 2023; Anthropic 2023; Google 2024), and the decoding discussion below sizes what that growth demands of memory. Longer context windows shift complexity from external retrieval and document chunking pipelines into accelerator memory capacity and bandwidth budgets. Exact tiling changes how much attention state is stored; sparse attention instead reduces the interactions computed (section 6.6.4.1).
OpenAI. 2023. New Models and Developer Products Announced at DevDay.
Anthropic. 2023. Introducing Claude 2.1.
Google. 2024. Our Next-Generation Model: Gemini 1.5.
Example 6.4: The quadratic wall
Scenario: BERT was pretrained with 512 learned position embeddings, so its deployments enforced a hard 512-token input limit (Devlin et al. 2019).
Diagnosis: Inputs beyond the pretrained positions are undefined for the model, however much memory is available. The limit itself was chosen partly because attention cost grows quadratically with sequence length. Extending from 512 to 4,096 tokens would multiply materialized score memory by 64×.
Systems lesson: Super-linear scaling turns algorithmic complexity into a hardware constraint that becomes fixed in the model itself once pretraining chooses it. No serving-time memory fix extends BERT past 512 positions, so its longer inputs must be truncated or split into windows. A model meant for long inputs must be pretrained with longer positions, and tiled or sparse attention is what keeps that training and its serving within the HBM activation budget.
Devlin, Jacob, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. 2019. “BERT: Pre-Training of Deep Bidirectional Transformers for Language Understanding.” Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, 4171–86. https://doi.org/10.18653/v1/n19-1423.
Autoregressive decoding
Autoregressive decoding generates one token at a time and often becomes memory-bandwidth bound at batch one (\(\BatchSize = 1\)) or small batch sizes when weights exceed on-chip memory. During prompt prefill or training, weight reuse across many token positions produces dense GEMMs with much higher arithmetic intensity. A large request batch (\(\BatchSize \gg 1\)) supplies many such positions, but prefill can obtain this reuse even for a single request with a long prompt.
During single-token generation (\(\BatchSize = 1\)), however, each projection layer collapses into a matrix-vector multiplication (GEMV). In the streamed-weight regime, the processor reads each projection weight from DRAM to multiply it by a single new token vector. This is the batch-one regime that equation 2 already derived for the MNIST layer at 0.5 FLOP/byte in FP32. Halving the weight width to 2 bytes in FP16, while still executing one multiply-accumulate operation (\(1\text{ MAC} = 2\text{ FLOPs}\)) per weight read, doubles that weight-only arithmetic intensity to exactly: \[\GemvArithmeticIntensity= \frac{2\text{ FLOPs}}{2\text{ bytes}} = 1.0\text{ FLOP/byte}\]
↩︎ The 1.0 FLOP/byte intensity of batch-one GEMV in 16-bit precision, and 0.5 FLOP/byte in FP32, is established in Optimizing inference throughput and latency.
Because modern accelerators require tens to hundreds of FLOPs per byte to reach peak compute throughput, running at \(1.0\text{ FLOP/byte}\) leaves compute cores idling for the vast majority of execution time, waiting for weights to arrive across the memory bus. To generate each token, the system must first stream every model parameter from off-chip memory into registers (for example, a 70B-parameter model streams 140 GB of FP16 weights per token, and GPT-2 XL makes that cost concrete below). It then executes the projection matrix-vector products at an arithmetic intensity capped at \(1.0\text{ FLOP/byte}\). Finally, it appends the new key and value vectors to the KV cache while streaming all historical keys and values from memory.
The KV cache26 introduced with prefill and decode grows linearly with sequence length (\(\mathcal{O}(\LayerCount \times 2 \times \AttentionHeadCount \times \SequenceLength\times \AttentionHeadDimension)\) per request, distinct from the \(\mathcal{O}(\SequenceLength^2)\) attention score matrix during training). It stores the key and value vectors for all previous tokens to avoid recomputing them (Pope et al. 2023; Kwon et al. 2023). Keys and values from past tokens are retained because the newly generated token’s query (\(\QueryVector_{t}\)) must attend across all historical context (\(\KeyVector_1 \dots \KeyVector_{t-1}\) and \(\AttentionValuesVector_1 \dots \AttentionValuesVector_{t-1}\)) to compute its next representation. Prior queries (\(\QueryVector_1 \dots \QueryVector_{t-1}\)) are safely discarded because past tokens never attend forward to future tokens, while caching past keys and values avoids re-running the entire model forward pass over the full prompt at every generated token. For long contexts, this cache can become large (for example, 100+ GB), and each decoding step reads prior keys and values. The resulting bandwidth pressure depends on context length, batching, attention architecture, cache layout, and hardware.
26 KV cache memory scaling: For a 7-billion-parameter transformer in FP16, model weights consume ~14 GB; a single request’s cache requires 32 layers \(\times\) 2 (K,V) \(\times\) 32 heads \(\times\) 2,048 positions \(\times\) 128 dimensions \(\times\) 2 bytes, or about 1.07 GB. At 8 concurrent users, the cache is ~8.6 GB, a substantial addition to the weights. Because the cache grows linearly with context and concurrency, scaling throughput forces choices such as grouped-query attention (Ainslie et al. 2023), shorter contexts, or KV paging and offloading (Kwon et al. 2023). Paging and offloading preserve model outputs, whereas grouped-query attention changes the architecture and shorter contexts truncate historical context.
Ainslie, Joshua, James Lee-Thorp, Michiel de Jong, Yury Zemlyanskiy, Federico Lebron, and Sumit Sanghai. 2023. “GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints.” Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, 4895–901. https://doi.org/10.18653/v1/2023.emnlp-main.298.
Kwon, Woosuk, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, Cody Hao Yu, Joseph Gonzalez, Hao Zhang, and Ion Stoica. 2023. “Efficient Memory Management for Large Language Model Serving with PagedAttention.” Proceedings of the 29th Symposium on Operating Systems Principles, 611–26. https://doi.org/10.1145/3600006.3613165.
↪ Budgeting KV cache memory across concurrent requests on a serving node is developed in Memory and KV cache.
For one model shape, the three memory regimes diverge sharply as context grows (figure 14). The weights do not grow with context at all, the KV cache grows linearly with every token a request keeps, and materialized attention scores grow with the square of the context. The cache overtakes the weights near 10,000 tokens, and one layer’s scores alone would fill an accelerator near 41,000 tokens, which is why serving systems size the cache per request and training kernels never materialize the scores.
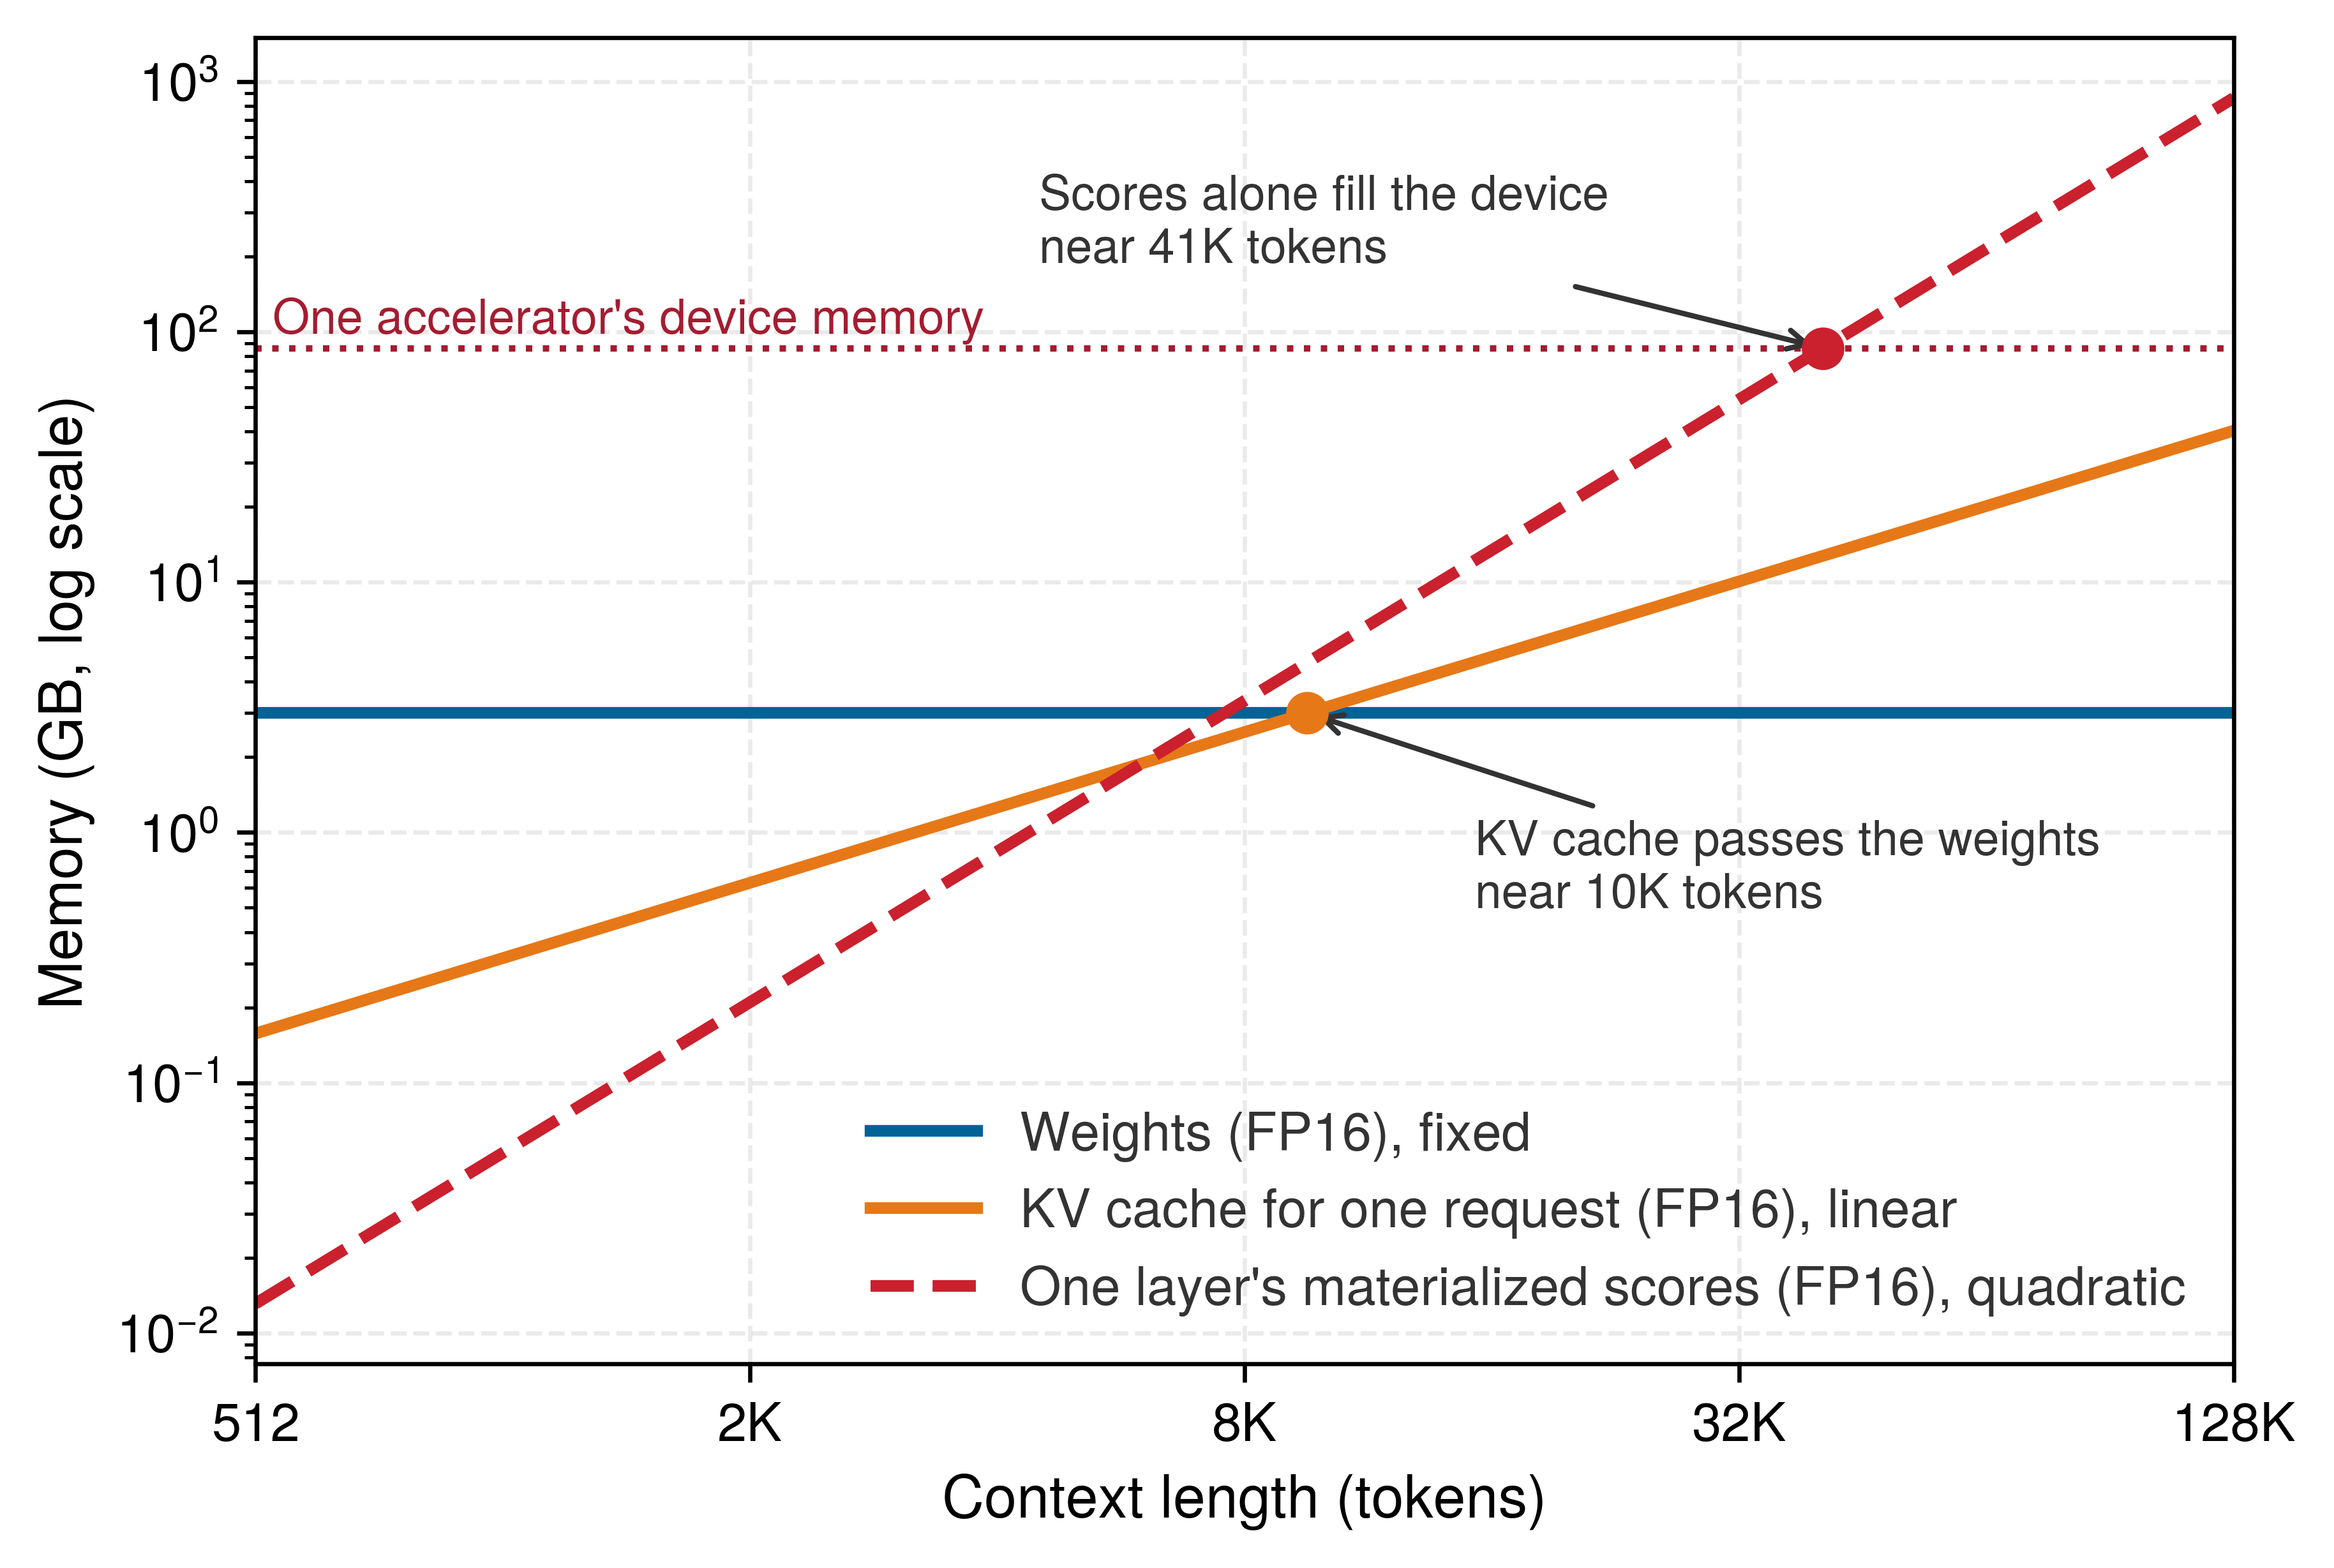
GPT-2 (Radford et al. 2019) anchors the chapter’s bandwidth-bound language lighthouse. It is a decoder-only transformer, the same design as today’s large language models such as Llama, yet small enough that every weight and every byte of its decoding traffic can be counted by hand. Unlike BERT, an encoder-style transformer that reads its whole context in both directions, GPT-2 generates text one token at a time, so batch-one decoding reads every weight for every token it produces. Two differences from current decoders matter for the machine. GPT-2 gives every attention head its own keys and values, so it stores 307.2 KB of KV cache per token in FP16, while newer models share keys and values across groups of heads (Ainslie et al. 2023) and store several times less per parameter. Batching also amortizes weights across requests but not caches, because each sequence keeps its own, which is why serving at scale binds on KV bytes as well as weight bytes. At GPT-2 XL’s size, one decoding step reads its weights in about 0.9 ms on a data-center accelerator, a few times shorter than the time to launch the step’s many small kernels (ML Frameworks). Bandwidth therefore dominates cleanly only as models grow toward tens of billions of parameters.
Radford, Alec, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. 2019. Language Models Are Unsupervised Multitask Learners. OpenAI.
Lighthouse 6.4: GPT-2 XL (bandwidth lighthouse)
Why it matters: GPT-2 XL exemplifies memory-bandwidth-bound batch-one decoding. In the weight-only model used here, each decoding step reads 6 GB of FP32 weights and performs matrix-vector operations. The resulting arithmetic intensity is about 0.5 FLOP/byte with FP32 weights or 1 FLOP/byte with FP16 weights. Batching can amortize this weight traffic, while KV-cache and activation traffic add to it. Table 5 summarizes the bandwidth lighthouse’s quantitative properties:
| Property | Value | System Implication |
|---|---|---|
| Parameters | 1.5B | Weight loading dominates inference latency. |
| Model Size | 6 GB (FP32) | Fits on one GPU but saturates HBM bandwidth. |
| Compute | 3 GFLOP/token | Low per-token compute; bottleneck is data movement, not math. |
| Constraint | Memory Bandwidth | Weight-bound batch-one tokens/s depends strongly on HBM bandwidth. |
| Profile | Bandwidth-Bound (small-batch decoding) | Larger batches can amortize weight traffic and shift the bottleneck. |
Across training and inference, transformers expose different opportunities for reuse. Full-sequence processing parallelizes across token positions while dense attention adds pairwise score cost, whereas small-batch autoregressive decoding stresses memory bandwidth when weights stream from off-chip memory.
Checkpoint 6.5: Prefill and decode
Yet dense, spatial, and sequence models do not cover the full spectrum of production workloads. Large-scale recommendation systems depart from standard arithmetic-dominated pipelines by coupling sparse embedding lookups (where memory capacity and irregular access distributions govern throughput) with downstream dense interaction layers. This hybrid matters at production scale: Meta reported that recommendation models accounted for most of its AI inference cycles (Gupta et al. 2020), even though such workloads receive less academic attention than language or vision models.
Gupta, Udit, Carole-Jean Wu, Xiaodong Wang, Maxim Naumov, Brandon Reagen, David Brooks, Bradford Cottel, et al. 2020. “The Architectural Implications of Facebook’s DNN-Based Personalized Recommendation.” 2020 IEEE International Symposium on High Performance Computer Architecture (HPCA), 488–501. https://doi.org/10.1109/HPCA47549.2020.00047.
Self-Check: Question
Why does position-free unmasked self-attention require explicit positional information supplied by mechanisms such as sinusoidal signals, learned positional embeddings, or related position-encoding schemes?
- Because matrix multiplication hardware cannot process tensors without fixed static padding across all dimensions.
- Because layer normalization removes the mean and variance of token vectors, destroying word identity.
- Because without positional information, unmasked self-attention is permutation equivariant: permuting the input rows permutes the output rows in the same way, so the layer by itself does not encode order.
- Because positional encodings reduce the computational complexity of the attention matrix from \(\mathcal{O}(S^2)\) to \(\mathcal{O}(S)\).
Under a weight-only memory model in FP16 precision, an autoregressive language model generates 1 token per forward pass at batch size 1, performing approximately 2 FLOPs per parameter while streaming the entire weight matrix from High Bandwidth Memory (HBM). Calculate the theoretical arithmetic intensity of this decoding step and explain why it causes accelerator matrix units (Tensor Cores) to remain severely underutilized.
Order the sub-layer operations executed within a single standard Transformer encoder block during a forward pass:
- Project input activations into Query, Key, and Value tensors via linear weight matrices
- Compute multi-head scaled dot-product self-attention across all sequence positions
- Apply residual skip connection addition and layer normalization to the attention output
- Pass normalized representations through a position-wise two-layer feed-forward network (MLP)
- Apply residual skip connection addition and layer normalization to the feed-forward output
A production serving system deploys a 32-layer transformer with 32 attention heads, head dimension \(d_{\text{head}} = 128\), and context length \(S = 2{,}048\) in FP16 precision (2 bytes per value). Calculate the memory footprint of the Key-Value (KV) cache for a single user request, and explain why KV-cache memory can surpass model weight memory under high concurrent batching.
True or False: During autoregressive language model inference, single-token generation at batch size 1 achieves near-peak GPU floating-point throughput (TFLOP/s) because the matrix-vector multiplication is highly optimized.
In a Multi-Head Attention layer with model dimension \(d_{\text{model}} = 768\) and \(N_{\text{heads}} = 12\) heads, what is the per-head dimension \(d_k\), and how does multi-head projection affect total computational FLOP complexity compared to a single attention head operating on the full 768 dimensions?
- The per-head dimension is \(d_k = 768\), increasing total projection FLOPs by \(12\times\) compared to a single head.
- The per-head dimension is \(d_k = 768 / 12 = 64\); running 12 heads of dimension 64 has the exact same total projection and score FLOP complexity as a single head of dimension 768, while enabling the model to jointly attend to information from 12 distinct representation subspaces.
- The per-head dimension is \(d_k = 12\), reducing total computational complexity by \(64\times\).
- Multi-head attention eliminates the output projection matrix \(\mathbf{W}^O\), halving layer parameter count.
6.8 Sparse Architectures: Recommendation Systems
Coupling sparse lookups with dense interaction layers is the defining pattern of industrial recommendation engines. When a user opens a streaming service or e-commerce platform, the system must select a handful of recommendations from a catalog of millions within an end-to-end budget of tens of milliseconds. Meeting that target requires mapping both users and items to dense vectors in a shared embedding space and scoring their interactions at scale, which exposes a regime governed first by memory capacity. A data-center accelerator engineered for dense matrix multiplication, providing hundreds of teraflops of arithmetic throughput alongside 80 GB of HBM, cannot hold terabytes of user and item embeddings locally. Its sparse stage gathers rows from those tables, placing different demands on the machine than the batched convolutions of section 6.3 or the streamed-weight decoding of section 6.7.
6.8.1 Pattern processing needs
A recommendation model must process user IDs across billions of accounts and item IDs across millions of products, yet raw integer IDs carry no inherent distance. User 1042 is no closer to user 1043 than to user 9,000,000, so a dense network cannot infer relationships from the numbers themselves. A single request also carries many such categorical features at once (the items a user recently viewed, the categories they follow), so one prediction can require dozens of separate ID lookups.
Embeddings solve the representation problem by mapping each discrete ID to a dense vector called an embedding27 (Mikolov et al. 2013). The vectors are ordinary learned parameters. Each row of an embedding table is a weight vector that gradient descent updates whenever its ID appears in a training example, so users and items with similar behavior end up near one another. The dot product of a user vector with an item vector becomes a learned score for how well they match. The system cost is that every lookup becomes an irregular read into a table spanning tens or hundreds of gigabytes. Recommendation models therefore encounter a capacity wall and a memory-bandwidth bottleneck before the first dense feedforward layer executes.
27 Embedding: Deriving from the mathematical embedding of one space into another, neural embeddings map discrete tokens (such as user IDs or vocabulary words) into continuous vector spaces where geometric proximity captures semantic similarity. Word2vec popularized neural word embeddings in 2013. For systems, embedding tables create a distinctive memory access pattern: each lookup is an irregular read into a potentially terabyte-scale table, producing a sparse, bandwidth-bound workload that makes DLRM different from compute-bound architectures like ResNet.
Mikolov, Tomas, Kai Chen, Greg Corrado, and Jeffrey Dean. 2013. “Efficient Estimation of Word Representations in Vector Space.” ICLR abs/1301.3781.
6.8.2 Algorithmic structure
The DLRM architecture (Naumov et al. 2019) organizes this computation into a four-stage pipeline split between dense and sparse paths. Continuous features such as user age or time of day first flow through a bottom MLP, a compute-intensive but memory-light stage dominated by dense matrix multiplications. The bottom MLP projects the raw continuous inputs into a single dense vector with the same dimension as each embedding table row (such as 128 elements), placing continuous and categorical features in a common vector space. In parallel, categorical IDs index into dedicated embedding tables, which is where the memory capacity wall appears.
For example, an embedding table for one billion users with 128-dimensional vectors requires \(10^9 \times 128 \times 4\) bytes \(\approx\) 512 GB of memory. This stage is memory-intensive but compute-light because each lookup is a memory copy with zero arithmetic reuse. Because the bottom MLP output and every gathered embedding row now share the same vector length, the interaction layer can combine the dense activations from the bottom MLP with the gathered sparse embedding vectors through pairwise dot products that capture user-item correlations. Finally, a top MLP processes the concatenated interaction representations through feedforward layers to predict a target probability such as click-through rate. Each of the four stages stresses a different part of the machine (figure 15), and section 6.8.3 quantifies the capacity-bound profile that results.
6.8.3 Computational mapping and system implications
DLRM’s computational mapping splits into two regimes that stress different hardware subsystems. The dense MLPs execute standard GEMM operations, identical to the MLP computational mapping discussed in section 6.2.4 and handled efficiently by Tensor Cores. The sparse embedding lookups, however, are qualitatively different. They are index-based memory gathers that copy parameter data with zero arithmetic reuse. An isolated lookup is bound by memory access latency. When a batch executes hundreds of lookups across features and samples, however, aggregate throughput becomes memory-bandwidth bound as concurrent requests saturate the memory bus. This operational throughput limit is distinct from the capacity constraint: total table size dictates whether parameters fit in accelerator memory or must spill across PCIe to host DRAM, whereas available bandwidth governs how fast gathered rows arrive. Within each selected row, an embedding vector is contiguous (for instance, 128 FP32 elements spanning 512 bytes), allowing the downstream pooling loop to consume every transferred byte. Across rows, however, data-dependent categorical IDs lack predictable spatial locality, defeating hardware prefetchers between row accesses. Access popularity remains heavily skewed: a small set of hot rows (popular items, frequent users) shows strong temporal locality in on-chip caches, while the long tail of rarely touched rows misses to main memory. Listing 9 writes this sparse stage as a loop nest parallel to those of the other families.
def embedding_bag_compute(sparse_ids, tables):
    # Loop 1: Process each sample in the batch (parallelizable)
    for b in range(batch_size):
        # Loop 2: Each categorical feature has its own table
        for f in range(num_features):
            pooled[b, f, :] = 0
            # Loop 3: Multi-hot feature, one gather per active ID
            for idx in sparse_ids[b][f]:  # data-dependent address
                row = tables[f][idx]  # irregular read, little reuse
                # Loop 4: Pool (sum) the gathered rows
                for d in range(embed_dim):
                    pooled[b, f, d] += row[d]
    return pooled  # feeds the interaction layer
DLRM (Naumov et al. 2019), which Meta open-sourced as a reference for this hybrid architecture, anchors the chapter’s recommendation lighthouse. Its combination of gigabyte-scale embedding tables and small multilayer perceptrons serves as the standard benchmark for memory capacity and irregular sparse access in the data center.
Naumov, Maxim, Dheevatsa Mudigere, Hao-Jun Michael Shi, Jianyu Huang, Narayanan Sundaraman, Jongsoo Park, Xiaodong Wang, et al. 2019. “Deep Learning Recommendation Model for Personalization and Recommendation Systems.” arXiv Preprint arXiv:1906.00091.
↪ The share of DLRM serving latency spent on embedding lookups is developed in Stage-by-stage latency breakdown.
Lighthouse 6.5: DLRM (recommendation lighthouse)
Why it matters: DLRM exemplifies memory-capacity-bound workloads. Its large embedding tables often exceed the memory of a single accelerator or server, so the system must decide where those tables live before it can optimize arithmetic throughput. The interaction layer then gathers selected embedding vectors and combines them with dense features, making capacity and irregular data movement the dominant constraints. This capacity-first decision differs from the batched convolution and streamed-weight decoding regimes examined here, requiring different hardware and deployment choices. Table 6 summarizes the recommendation lighthouse’s quantitative properties.
| Property | Value | System Implication |
|---|---|---|
| Embedding Parameters | 25B | Parameters \(\times\) 4 bytes; dominates total model size. |
| Model Size | 100 GB (FP32) | May exceed one device’s fast memory. |
| Constraint | Memory Capacity | Model size \(> \text{Single GPU Memory}\). |
| Bottleneck | Irregular Data Movement | Gather operations dominate sparse feature processing. |
| Profile | Mixed (Sparse/Dense) | Combines memory-heavy lookups with compute-heavy MLPs. |
Once embedding tables exceed one device, capacity, not arithmetic, becomes the primary systems constraint. While a ResNet-50 (102.2 MB) fits on a single accelerator and a dense language model like GPT-3 (Brown et al. 2020) (350 GB) fits within a single multi-GPU node, production recommendation models reach terabytes of embedding parameters. In iron law terms, capacity acts as a feasibility constraint that comes before either execution term. It decides where the tables live, and therefore which bandwidth the data term \(\DataVolume/\Bandwidth\) must use: HBM when the tables fit, host DRAM over PCIe or a peer accelerator over NVLink when they do not.
Brown, Tom B., Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared Kaplan, Prafulla Dhariwal, Arvind Neelakantan, et al. 2020. “Language Models Are Few-Shot Learners.” Advances in Neural Information Processing Systems 33: 1877–901. https://doi.org/10.48550/arxiv.2005.14165.
The architecture therefore breaks the single-device assumption that holds for smaller dense models. Systems designers have three ways to resolve the capacity wall. They can shrink the tables through compression, hashing, or pruning, at the risk of losing information on long-tail users and items. They can move the tables to host DRAM or external key-value stores, at the cost of slower remote lookups over PCIe or Ethernet. They can partition the tables across multiple accelerators so that no single device stores the full model, trading local memory pressure for cross-device communication. Architecturally, DLRM turns recommendation into a capacity-management challenge before it becomes a compute-optimization task. Training-time model partitioning and hardware-accelerated interconnects address these distributed layouts, and the baseline sizing calculation begins with a single table.
One embedding table fits an 80 GB A100; a second breaches the capacity wall.
Napkin Math 6.2: The capacity wall
Problem: Consider a recommendation system for a store with 100M items using an embedding size of 128. How much memory does the item table alone require?
Math:
- Table entries: 100M items.
- Vector size: 128 elements.
- Precision: FP32 (4 bytes per element).
- Table size: 100M items \(\times\) 128 \(\times\) 4 bytes ≈ 51.2 GB.
- Capacity share: 51.2 GB \(\div\) 80 GB = 64 percent of device capacity.
- Two-table check: Two tables at 64 percent each exceed 100 percent of device capacity.
Systems insight: A single embedding table for one feature (items) already consumes 64 percent of an 80 GB A100 GPU. Adding a user table of the same size means the embedding tables no longer fit on a single 80 GB accelerator, motivating table compression, off-device memory, or partitioning across devices. DLRM is capacity bound: the primary systems question is not how many FLOP/s the accelerator can deliver, but where the embedding state can physically reside.
Once the tables no longer fit on one device, sparse lookups cross memory and interconnect boundaries. A request may need rows owned by several accelerators, forcing the device executing the downstream MLP to wait while the system gathers them across PCIe or NVLink. Within a multi-accelerator server, gathering rows distributed across multiple GPUs turns memory routing into an interconnect bandwidth bottleneck, because every accelerator may need rows held by every other, an all-to-all exchange. The architectural consequence is that a recommendation model’s memory layout directly determines its cross-accelerator data-transfer traffic, creating coordination overhead for both training and serving.

Sharded tables can turn lookups into all-to-all accelerator traffic.
↪ Partitioning a model that exceeds one device’s memory across accelerators, and the communication that partition boundaries add, is developed in Model parallelism.
Checkpoint 6.6: DLRM and capacity-bound lookups
Recommendation systems stress a different part of the machine than CNNs or transformers.
With DLRM, the roster of five families is complete, and each has been analyzed on its own terms: the pattern it targets, the computation it performs, the mapping it induces, and the bottleneck it exposes. A deployment rarely gets to examine one family in isolation. The same accelerator that serves a vision model today may serve a language model or a recommender tomorrow, and the architecture decides which of its resources gives out first.
Self-Check: Question
In the Deep Learning Recommendation Model (DLRM) architecture, what is the primary computational role of the Interaction Layer?
- It applies 2D convolutions over user and item IDs to extract hierarchical spatial features.
- It normalizes categorical IDs across the batch using running mean and variance statistics.
- It performs autoregressive token decoding to predict the next search query.
- It computes pairwise dot products between the dense feature representations from the Bottom MLP and the sparse embedding vectors gathered from categorical tables to capture explicit feature interactions.
Explain why a large-table recommendation scenario becomes memory-capacity-bound rather than compute-bound when the model’s combined embedding tables exceed the fast memory of a single accelerator, and why the standard execution form of the Iron Law of ML Systems (\(T_{\text{exec}} = D_{\text{vol}}/\text{BW} + O/(R_{\text{peak}} \cdot \eta_{\text{hw}}) + L_{\text{lat}}\)) cannot directly determine whether that model can be deployed on one accelerator.
Order the four primary computational stages executed during an end-to-end inference pass in a DLRM recommendation model:
- Process continuous numerical features through the dense Bottom MLP to produce a dense representation
- Look up sparse categorical IDs across embedding tables to gather discrete embedding vectors
- Compute pairwise dot products (interactions) between the Bottom MLP output and all gathered embedding vectors
- Concatenate interaction dot products with Bottom MLP features and pass through the Top MLP to predict click-through probability
An e-commerce recommendation system maintains an item embedding table with 100 million items (\(10^8\)) and a user embedding table with 1 billion users (\(10^9\)), each using 128-dimensional FP32 vectors (4 bytes per parameter). Calculate the memory footprint of each table, verify why they cannot fit on a single 80 GB A100 GPU, and describe two systems strategies to handle this capacity wall.
Why do sparse embedding table lookups in recommendation workloads resist standard hardware caching and memory prefetching mechanisms that accelerate CNNs and MLPs?
- Because each incoming request queries arbitrary, non-contiguous row indices determined by sparse user and item IDs, producing irregular gathers with weak spatial locality, although popularity skew can still create temporal reuse for hot rows.
- Because embedding tables are permanently encrypted in DRAM, preventing hardware prefetchers from reading address buses.
- Because embedding lookups require performing high-order tensor contractions that stall CPU prefetch queues.
- Because recommendation systems execute only on storage-class memory where hardware caching is disabled by operating system kernels.
6.9 Comparing and Choosing Architectures
The three requests that opened this chapter can now be costed in numbers. A single ResNet-50 frame performs about 8.2 GFLOP of arithmetic against 102.2 MB of FP32 weights, and each convolutional filter is reused across its feature map, creating opportunities to keep arithmetic units busy. A single GPT-2 token at batch size one performs about 3 GFLOP/token against 3 GB of FP16 weights. Streaming those weights once gives a weight-only arithmetic intensity of roughly 1 FLOP/byte, making bandwidth a likely limit. A DLRM request gathers a handful of embedding rows from tables totaling 100 GB, more than the accelerator’s 80 GB of memory, so before any question of speed arises the system must decide where those tables live.
The silicon is identical in all three cases, but the demands differ. Convolutional reuse favors arithmetic throughput, streamed token projections stress bandwidth, and oversized embedding tables impose a capacity constraint that decides which bandwidth their lookups pay. The iron law (Iron Law of ML Systems) then predicts which term binds, given the execution conditions and machine balance.
Each of those costs comes from a counting rule derived in its family’s section. Table 7 collects the rules in exact form, so that a new model can be estimated on paper in the same order: count the weights, count the multiply-accumulates, count the bytes that must move or stay resident, then compare those counts with the machine.
| Building block | Weights | Multiply-accumulates per example | Bytes that move or stay resident |
|---|---|---|---|
| Dense layer | \(\LayerInputWidth \LayerOutputWidth\) | \(\LayerInputWidth \LayerOutputWidth\) | Every weight read once per batch, so weight-only intensity grows with batch size |
| Convolution layer | \(\KernelSize^2 \InputChannelCount \OutputChannelCount\) | \(\FeatureMapHeight \FeatureMapWidth \KernelSize^2 \InputChannelCount \OutputChannelCount\) | Output activations, \(\FeatureMapHeight \FeatureMapWidth \OutputChannelCount\) values per example |
| Depthwise separable convolution | \(\KernelSize^2 \InputChannelCount + \InputChannelCount \OutputChannelCount\) | \(\FeatureMapHeight \FeatureMapWidth (\KernelSize^2 \InputChannelCount + \InputChannelCount \OutputChannelCount)\) | Same activations as a standard layer for far fewer operations |
| Recurrent step | \(\HiddenDimension^2 + \HiddenDimension \LayerInputWidth\) | \(\HiddenDimension^2 + \HiddenDimension \LayerInputWidth\) per step, \(\SequenceLength\) steps in order (four times for an LSTM) | State of \(\HiddenDimension\) values at inference; \(\SequenceLength \HiddenDimension\) kept for training |
| Transformer block | \(4\HiddenDimension^2 + 2\HiddenDimension \FeedForwardWidth\) | \(4\SequenceLength\HiddenDimension^2 + 2\SequenceLength^2\HiddenDimension + 2\SequenceLength\HiddenDimension\FeedForwardWidth\) for \(\SequenceLength\) tokens | \(\SequenceLength^2\) scores per head if materialized |
| Decoding one token | All of the model’s weights | About one per weight | Every weight read per step, plus a KV cache of \(2\LayerCount\HiddenDimension\) values per token |
| Embedding lookup | Rows \(\times\) vector width | Almost none (rows are copied) | Whole table resident: rows \(\times\) width \(\times\) bytes per value |
6.9.1 Arithmetic intensity across workloads
Each family section measured reuse in its own terms: filters reused across a feature map, weights streamed once per decoded token, rows gathered from a table. Arithmetic intensity, the FLOP/byte ratio set against a machine’s balance, puts them on one scale and shows whether each workload is likely to be compute or memory bound.
↩︎ Arithmetic intensity and the system balance it is compared against are established in System Balance and Hardware.
The calculation here is a weight-only proxy rather than a complete measurement of main-memory traffic. It divides floating-point work by FP32 model-weight bytes, omitting activation, intermediate, and KV-cache traffic. Batching can amortize weight traffic across examples or tokens, while additional state movement can lower realized intensity. Operation cost reference gives the per-operation FLOP and parameter formulas used in the proxy. Under these assumptions ResNet-50’s proxy exceeds GPT-2 XL’s by roughly 160×, the widest gap among the lighthouses in table 8.
The intensity proxy is one input to architecture selection. Deployment constraints extend beyond the FLOP-to-byte ratio, and batch size, precision, sequence length, and target hardware decide whether the proxy predicts the deployed bottleneck. Table 8 sets the proxy beside parameter footprint, inference cost, and the governing hardware constraint for all five canonical workloads: compute throughput, memory bandwidth, memory capacity, latency, and power. For compute- and bandwidth-bound workloads, the iron law directly maps the primary bottleneck to operations (\(\Operations\)) or data movement (\(\DataVolume\)). For capacity-, latency-, and power-constrained workloads, physical boundaries dictate where and within what budget those operations must execute, determining which optimization strategies prove effective.
| Model | Domain | Params | FLOPs/Inf | Memory | Intensity (weight-only) | Bottleneck | Role in Textbook |
|---|---|---|---|---|---|---|---|
| ResNet-50 | Vision | 25.6M | 8.2 GFLOP | 102.2 MB | 80.2 FLOP/byte | Compute | Dense vision throughput |
| GPT-2 XL | Language | 1.5B | 3 GFLOP/token | 6 GB | 0.50 FLOP/byte | Mem. Bandwidth | Token-by-token serving |
| DLRM | Recommender | 25B | Low | 100 GB | n/a | Mem. Capacity | Embedding tables and capacity planning |
| MobileNetV2 | Edge Vision | 3.5M | 600 MFLOP | 14 MB | 42.8 FLOP/byte | Compute | Depthwise convolutions and efficiency |
| KWS (DS-CNN) | Audio | 200K | 20 MFLOP | 800 KB | 25 FLOP/byte | Power | Always-on power budget |
Architecture selection is ultimately an engineering trade-off between math \((\Operations)\) and memory movement \((\DataVolume)\). The mechanisms behind the intensities in table 8 explain why each lighthouse sits where it does on the intensity spectrum. ResNet-50 earns its high intensity because convolutional layers reuse each weight many times across the spatial dimensions of an image (individual deeper ResNet layers reach 100–200+ FLOP/byte). Arithmetic throughput becomes the limit when effective intensity exceeds the target machine’s compute-to-bandwidth balance. GPT-2 sits at the opposite extreme during batch-one decoding with streamed weights: each projection loads weights for one token’s matrix-vector product, making bandwidth a likely limit. MobileNet lands between the two at the whole-model level, with individual depthwise layers falling lower once activation traffic is included. Depthwise separable convolutions reduce total \(\Operations\) but move more data relative to that work, which fits mobile hardware well yet often “starves” high-end GPUs optimized for dense math.
Checkpoint 6.7: Arithmetic intensity and architecture
Match the architectural choice to its systems implication:
Comparing this spectrum with the target machine’s balance helps determine whether faster arithmetic or faster memory would improve performance. The roofline model (Williams et al. 2009) plots achievable throughput against arithmetic intensity to show where a workload turns from memory bound to compute bound. This chapter needs only the comparison introduced with system balance, a workload’s intensity set against the machine’s ratio of peak compute to memory bandwidth. The full construction, including the ridge point of an H100 and how the same operation falls on either side of it, is collected for reference in A concrete example: The H100 analysis.
Williams, Samuel, Andrew Waterman, and David Patterson. 2009. “Roofline: An Insightful Visual Performance Model for Multicore Architectures.” Communications of the ACM 52 (4): 65–76. https://doi.org/10.1145/1498765.1498785.
↪ The roofline model’s analytical treatment, from the memory-bound slope to the ridge point, is developed in Performance Bounds.
Intensity is one column of a fuller profile. Persistent state, per-request state, the axis along which the work parallelizes, and the iron-law term that binds complete the comparison.
6.9.2 Workload profiles
An architecture’s bottleneck depends on how a request exercises its state and parallelism as much as on its layer equations, which is why the transformer occupies two rows in table 9: prompt prefill and autoregressive decode reuse the exact same weights in different regimes (section 6.7.4.2). Each row of the table pairs a family in a representative execution regime with the workload archetypes of Workload archetypes. The compute-bound rows assume sufficient reuse to exceed the machine’s balance, the bandwidth-bound rows assume streamed operands, and the capacity-bound row assumes oversized tables. Reading across the columns follows a request through the machine: persistent state, per-request state, arithmetic intensity, parallel axes, and the likely limiting term under those assumptions.
| Family | Parameters | Activations | Intensity | Parallel Axis | Binding Term | Lighthouse |
|---|---|---|---|---|---|---|
| MLP | \(\mathcal{O}(\LayerInputWidth \LayerOutputWidth)\) per layer | \(\mathcal{O}(\BatchSize\, \LayerOutputWidth)\) | Low at batch one (GEMV); high when batched (GEMM) | Batch | \(\DataVolume/\Bandwidth\) at small batch | None (DLRM’s dense MLPs) |
| CNN | \(\mathcal{O}(\KernelSize^2 \InputChannelCount \OutputChannelCount)\) per layer, independent of image size | \(\mathcal{O}(\BatchSize\, \FeatureMapHeight \FeatureMapWidth \OutputChannelCount)\) | High (filters reused across positions); lower for depthwise | Batch and spatial positions | \(\Operations/(\PeakRate\,\EfficiencyHw)\) | ResNet-50; MobileNetV2 and KWS |
| RNN | \(\mathcal{O}(\HiddenDimension^2 + \HiddenDimension \LayerInputWidth)\), shared across steps | \(\mathcal{O}(\BatchSize\, \HiddenDimension)\) state; \(\mathcal{O}(\BatchSize \SequenceLength \HiddenDimension)\) in training | Low at batch one; higher with batching | Batch and within-step work; recurrent time is serial | Serial step cost; dispatch adds \(\Latency\) unless fused | None |
| Transformer (prefill) | \(\mathcal{O}(\HiddenDimension^2 + \HiddenDimension \FeedForwardWidth)\) per block | \(\mathcal{O}(\BatchSize \SequenceLength \HiddenDimension)\); \(\mathcal{O}(\BatchSize \SequenceLength^2)\) if scores are materialized | High (GEMM over all \(\SequenceLength\) tokens) | Batch and sequence positions | \(\Operations/(\PeakRate\,\EfficiencyHw)\), with an \(\SequenceLength^2\) attention term | GPT-2 (prompt) |
| Transformer (decode) | Same weights, reread for every token | KV cache, \(\mathcal{O}(\BatchSize \SequenceLength \HiddenDimension)\) per layer | Low (GEMV per token at small batch) | Batch only; tokens are serial | \(\DataVolume/\Bandwidth\) (weights and KV cache) | GPT-2 (generation) |
| DLRM | Embedding tables, one row per category, dominate; dense MLPs are small | Pooled embedding vectors per feature | Very low (gathers with little arithmetic) | Batch; tables sharded across devices | Capacity first, then \(\DataVolume/\Bandwidth\) | DLRM |
Table 9 states memory as growth rates; for the lighthouses the bytes are concrete (table 10). Deployment usually stores weights in a narrow format, so INT8 cuts every row by four. Training moves the other way. Each FP32 weight also carries a gradient and two optimizer moments, so the parameter state alone is four times the FP32 weights before any activation is saved (System cost of optimizer state itemizes this 16 bytes per parameter). A model that serves from one accelerator may not train on it.
| Model | FP32 Weights | INT8 Weights | Training State (16 Bytes per Parameter) | Fits One Accelerator for Training | Grows per Request With |
|---|---|---|---|---|---|
| ResNet-50 | 102.2 MB | 25.6 MB | 408.9 MB | Yes | Feature maps for each image in the batch |
| GPT-2 XL | 6 GB | 1.5 GB | 24 GB | Yes | KV cache, 307.2 KB per token in FP16 |
| DLRM | 100 GB | 25 GB | 400 GB | No | Gathered embedding rows for each lookup |
| MobileNetV2 | 14 MB | 3.5 MB | 56.1 MB | Yes | Feature maps for each image |
| KWS (DS-CNN) | 800 KB | 200 KB | 3.2 MB | Yes | Feature maps for each audio window |
The parameter and activation columns of table 9 decide how data reaches the arithmetic units, and the pattern of access matters as much as the volume. Three patterns cover the table. Sequential access, the streaming of contiguous weight rows in an MLP layer or a transformer projection, lets DRAM deliver long bursts and lets hardware prefetchers run ahead, so it approaches the interface’s peak bandwidth. Strided access, which a convolution produces when its window steps across a layout that does not keep the window contiguous, fetches whole cache lines to use a fraction of each. The im2col lowering (section 6.3.3) moves that gather into a separate copy pass so the matrix multiply itself reads sequentially, at the cost of up to \(\KernelSize^2\)-fold duplication (because overlapping sliding windows copy the same input pixels into multiple rows). Random access characterizes the DLRM row. Sparse IDs index arbitrary rows across multi-gigabyte tables. While each selected embedding vector is contiguous and fully consumed by pooling, row selection lacks predictable spatial locality between rows, which defeats hardware prefetchers and leaves sparse lookups exposed to memory latency unless many concurrent requests are in flight. Achieved bandwidth depends on vector width, alignment, and request concurrency, which is why caching popular rows is critical to reduce off-chip traffic. Attention is not random access despite its content-dependent weights, because its queries, keys, and values sit in contiguous tensors that tiled kernels stream through on-chip SRAM.
Whether an access incurs DRAM traffic at all depends on the working set, the data the execution units need at once. Small layers, such as the \(784{\times}128\) reference layer at 401.4 KB in FP32, fit in on-chip SRAM. Production-width layers of tens of megabytes do not, which is why unbatched MLP inference and transformer decode stream their weights from off-chip memory on every request. Accelerators answer both ends of the table with memory hierarchy rather than arithmetic. HBM stacks DRAM dies beside the processor to supply the streaming rows at more than an order of magnitude above standard DDR channels. Multi-megabyte on-chip SRAM, often an explicitly managed scratchpad, lets compilers stage tiles so that reuse happens on chip. The intensity column measures how much a family can profit from that staging, and it doubles as an energy column.
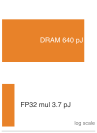
Moving a 32-bit value from DRAM costs far more energy than one FP32 multiply.
Systems Perspective 6.2: Reuse sets each family's energy cost
Moving a 32-bit value from DRAM costs far more energy than one arithmetic operation on it (Energy Cost of Moving vs. Computing on a 32-Bit Value in The feeding problem). Against the full multiply-accumulate that a dense layer performs, the gap is about 139×, the basis used for the MLP and RNN above. How much of that cost each family pays depends on reuse, so low-intensity rows are energy-dominated by DRAM traffic. An unbatched MLP or a decode step loads each weight once per request and spends most of its energy moving it. A CNN amortizes each filter load over \(\FeatureMapHeight\times \FeatureMapWidth\) applications, so the locality that makes it compute bound also makes it energy efficient, unless a fully materialized im2col buffer inflates temporary traffic by up to \(\KernelSize^2\). An RNN keeps its compact state in SRAM but idles execution units across serial steps, which raises energy per token. Tiled attention keeps score blocks on chip, so its energy tracks matrix multiplication rather than DRAM round-trips.
The parallel-axis column determines how data must move among processing elements once the work is spread out. Four data movement patterns (broadcast, scatter, gather, and reduction; figure 16) govern how tensors travel among processing elements, whether those are units on one chip or several accelerators in one server. Batch parallelism in MLPs, CNNs, and prefill broadcasts stationary weight tiles to many units, each working on a different example or position, and compilers tile loops to reuse each broadcast value as often as possible. Spatial and model partitioning scatter a tensor across tiles or devices. Mixture-of-experts models, which route each token to a few of many feedforward subnetworks, make the scatter input-dependent, so a popular expert can overload one accelerator while others idle. DLRM gathers embedding rows from wherever the sharded tables live, and each attention query gathers keys and values from every position in its sequence. Reductions combine values through sums or maxima (softmax denominators, normalization statistics, and the summing of gradients across accelerators that each trained on a different slice of the batch). Tree-structured reduction hardware finishes a reduction over \(\ReductionInputCount\) values in \(\mathcal{O}(\log \ReductionInputCount)\) stages rather than \(\mathcal{O}(\ReductionInputCount)\). The rows with a serial axis, RNNs and decode, are the rows these collectives cannot rescue, because no amount of broadcast or reduction bandwidth shortens a dependency chain.
The last column applies the iron law under each row’s execution assumptions. When effective intensity exceeds the machine’s balance and parallel work is sufficient (batched CNNs, prefill), the compute term \(\Operations/(\PeakRate\,\EfficiencyHw)\) binds. Below that balance (streamed small-batch MLPs, decode), the data term \(\DataVolume/\Bandwidth\) binds, favoring fewer transferred bytes, more reuse, or higher bandwidth. RNNs add a serial chain of state updates: faster arithmetic, memory, and reduced launch overhead \((\Latency)\) can shorten each step without removing the dependency. DLRM adds a constraint that sits in front of the equation. Capacity decides where the tables live and thus which bandwidth the data term pays. ResNet-50, GPT-2, and DLRM isolate these representative regimes. MobileNetV2 and KWS share the CNN row, with depthwise layers pulling their intensity down; they stand for latency and power, deployment budgets that bound the whole execution rather than one term. No lighthouse occupies the RNN row, whose serial chain the recurrent family section analyzes directly.
6.9.3 Shared building blocks
The rows of table 9 differ, but the operators inside them repeat. Each block was taught with the family that first needed it: dense projections with MLPs, skip connections and normalization with ResNet-50 (section 6.4.1 and section 6.4.2), and gating with recurrent networks (section 6.5.3). Table 11 connects each building block to a representative context and to other architectures that use it. Each block brings its hardware cost with it, so an optimization for residual additions or normalization kernels can transfer across families.
| Building Block | Example Context | Problem Solved | Now Used In |
|---|---|---|---|
| GEMM | MLPs | Universal function approximation | All architectures (feedforward layers) |
| Parameter Sharing | CNNs | Spatial efficiency | Transformers (shared projections), RNNs (weight reuse across time) |
| Skip Connections | ResNets (CNNs) | Gradient flow at depth | Transformers, DenseNets, U-Nets, many modern deep networks |
| Normalization | CNNs (BatchNorm) | Activation stability | LayerNorm (Transformers), RMSNorm (root-mean-square normalization), GroupNorm (grouped channels) |
| Gating | LSTMs (RNNs) | Selective signal routing | Transformers (mixture-of-experts routing), GRUs, highway networks |
Dense projections
General matrix multiplication is the one primitive every row of the profile shares. It is the feedforward layer inside every transformer block, the \(1{\times}1\) pointwise convolution in MobileNets, the input and recurrent projections inside every RNN cell, and the bottom and top MLPs of DLRM. Convolution reaches the same path through the im2col patch unfolding of figure 5, and dedicated matrix engines, such as GPU Tensor Cores and the systolic arrays of TPUs, exist because this one primitive dominates the operation count of nearly every workload. Its hardware cost depends on shape rather than on the family that invokes it. Batching therefore acts on every family that reaches this path as it acts on the dense layer measured in Implementation and optimization considerations, converting a matrix-vector product into a matrix-matrix product with greater reuse. The higher intensity can cross the target machine’s balance point, which is why batch size changes the modeled regime of three rows of the table.
Dense connectivity supplies a common cost baseline, but each family changes a different part of the workload. Convolution shares filters across spatial positions; attention combines dense projections with pairwise interactions; and embedding lookup replaces an arithmetic transformation with an indexed read. Their parameter storage, operation counts, and transferred bytes must therefore be compared separately, as in table 9. Dense projections remain inside all these architectures, so improvements to their execution can transfer between families.
Gating, routing, and the transformer block
Gating generalizes beyond recurrence as the basic mechanism for data-dependent routing. Highway Networks (Srivastava et al. 2015) used gates to interpolate between a transformation and an identity bypass, a gated precursor of the residual shortcut. Encoder-decoder attention (Bahdanau et al. 2015) computes a dynamic routing distribution over input representations, and in transformers the softmax attention weights act as data-dependent routing coefficients that decide how features aggregate across tokens. Mixture-of-experts architectures extend the idea to dispatch each token to a subset of feedforward experts (Jacobs et al. 1991; Shazeer et al. 2017), which separates the weights a token reads, and so its FLOPs and bytes, from the model’s total capacity. The hardware cost of gating is irregularity. Dense attention keeps static tensor shapes even though its weights vary per token, but sparse attention, expert routing, and dynamic graph execution introduce data-dependent control flow and runtime tensor sizes that defeat static memory allocation and balanced work dispatch.
Srivastava, Rupesh Kumar, Klaus Greff, and Jürgen Schmidhuber. 2015. “Highway Networks.” arXiv Preprint arXiv:1505.00387.
Bahdanau, Dzmitry, Kyunghyun Cho, and Yoshua Bengio. 2015. “Neural Machine Translation by Jointly Learning to Align and Translate.” International Conference on Learning Representations (ICLR).
Jacobs, Robert A., Michael I. Jordan, Steven J. Nowlan, and Geoffrey E. Hinton. 1991. “Adaptive Mixtures of Local Experts.” Neural Computation 3 (1): 79–87. https://doi.org/10.1162/neco.1991.3.1.79.
Shazeer, Noam, Azalia Mirhoseini, Krzysztof Maziarz, Andy Davis, Quoc Le, Geoffrey Hinton, and Jeff Dean. 2017. “Outrageously Large Neural Networks: The Sparsely-Gated Mixture-of-Experts Layer.” International Conference on Learning Representations (ICLR).
↪ The irregular memory access that unstructured sparsity, embedding lookups, and dynamic routing impose on hardware is developed in Irregular memory access.
28 Vision transformers (ViTs): Google’s 2020 ViT paper split \(224{\times}224\) images into \(16{\times}16\) patches (196 “tokens”) and applied standard transformer attention. ViTs replace CNN’s local convolutions with \(\mathcal{O}(\SequenceLength^2)\) global attention over patch tokens. In the original study, large-scale pretraining improved ViT’s competitiveness, illustrating how data and compute can compensate for weaker spatial inductive bias (Dosovitskiy et al. 2021).
Dosovitskiy, Alexey, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, et al. 2021. “An Image Is Worth 16x16 Words: Transformers for Image Recognition at Scale.” International Conference on Learning Representations (ICLR).
A transformer block is where all four building blocks meet. In the encoder tower of figure 12, residual paths bypass each multi-head attention and feed-forward sub-layer to preserve gradient flow through deep stacks, dense GEMM projections carry the attention and feedforward transformations, LayerNorm or RMSNorm stabilizes activations around each sub-layer, and softmax attention weights gate information across positions. What the transformer changed was the dependency structure. Replacing recurrence with all-to-all attention cut the sequential depth for tokens to interact from \(\mathcal{O}(\SequenceLength)\) steps to \(\mathcal{O}(1)\), which let the other three blocks run at full width on parallel hardware. Vision Transformers28 carry the same block set to images (Dosovitskiy et al. 2021).
This portability separates optimizations that transfer from those that do not. GEMM tiling and mixed-precision arithmetic help every row of table 9, residual memory management helps every deep network, and normalization kernel fusion helps CNNs and transformers alike. Attention-specific kernels remain tied to attention’s memory pattern, but even they are built from the same GEMM and memory-access primitives. The profile and the building blocks describe what each family costs; choosing among families for a particular deployment requires turning those costs into a procedure.
6.9.4 Architecture selection framework
Turning those family profiles into a selection procedure starts with a hard systems truth: deployment constraints eliminate architectures that look competitive on unconstrained accuracy benchmarks, and a structural mismatch chosen here cannot be rescued later by compiler optimization or kernel tuning. A battery-powered edge sensor bounded by milliwatts of thermal envelope and a data-center ranking service bounded by tens of milliseconds of tail latency rule out opposite rows of table 9 before training ever begins. Engineering teams nonetheless often default to architectures by popularity, deploying over-parameterized transformers where a compact convolutional network would suffice or selecting models whose state exceeds on-device memory. In D·A·M terms, architecture selection chooses the algorithm (\(\text{A}\)) that bridges the structure of the data (\(\text{D}\)) to the budgets of the machine (\(\text{M}\)): memory capacity, memory bandwidth, compute throughput, and thermal envelope.

Architecture selection turns on the algorithm axis, bridging data to machine.
Selection begins with data-to-architecture mapping, matching the symmetries of the input to an operator family. The useful strength of an inductive bias depends on the task (section 6.1). CNNs impose local connectivity, weight sharing, and translation equivariance, reducing parameter volume and exposing reuse for grid-like data. RNNs impose temporal recurrence, bounding inference state across sequence lengths at the cost of serialization. Transformers use content-based attention, gaining flexible interactions while paying for dense quadratic score computation. MLPs impose no specific spatial or temporal connectivity pattern, leaving those relationships to be learned. Ordered by the strength of their assumptions, the families therefore run from CNNs through RNNs and transformers to MLPs; the margin figure beside the inductive-bias definition draws the same ordering for CNNs, transformers, and MLPs. The stronger the prior, the fewer samples and the less computation a matching task needs, and the more a mismatched task loses, because a strong prior can exclude useful solutions as easily as it excludes useless ones. Model selection must test both predictive fit and the resulting machine costs, and the history of the Netflix Prize shows what happens when only the first test is run.
War Story 6.1: The ensemble Netflix did not ship (2009)
Context: Netflix awarded its $1M Grand Prize in 2009 for a 10 percent improvement in recommendation accuracy (Johnston 2012).
Mechanism: Bringing the winning improvement into production required substantial engineering effort just as Netflix’s business was shifting from mailed DVDs to streaming. That shift also produced richer viewing signals and changed what personalization needed to optimize.
Impact: The additional accuracy did not justify the production effort, so Netflix did not deploy the Grand Prize code.
Fix: Netflix retained two algorithms from the earlier Progress Prize and redirected its recommendation work toward streaming-era personalization.
Systems lesson: An offline metric gain is only valuable when its integration cost and objective still match the production system.
Johnston, Casey. 2012. “Netflix Never Used Its $1 Million Algorithm Due to Engineering Costs.” Ars Technica, April.
Figure 17 formalizes this selection pipeline as a multi-stage triage tree. Candidate architectures route first by input data structure (text, sequences, spatial grids, or tabular features) and then pass through sequential screening gates for memory capacity, compute budget, inference latency, accuracy targets, and hardware deployment readiness. High-cardinality recommendation workloads sit outside this dense flowchart and route to the sparse embedding family (section 6.8) before applying the same memory, compute, speed, accuracy, and deployment checks. If any constraint fails, the decision loop routes execution back to scale the model down, increase its capacity when accuracy falls short, or substitute an alternative architecture family.
The framework executes in three ordered phases, with model compression as the systematic way to scale a candidate down when it fails a budget:
- Data symmetry identification (\(\text{D}\)): Identify structural symmetries and invariances in the input data. Spatial locality routes candidates to CNNs; temporal sequence structure to RNNs; unconstrained cross-token dependency to transformers; tabular features without spatial geometry to MLPs; and high-cardinality categorical IDs to sparse embedding tables.
- Progressive physical constraint filtering (\(\text{A} \times \text{M}\)): Filter candidate models against hardware budgets: static parameter storage in flash/DRAM, peak dynamic activation footprint in SRAM/HBM, arithmetic intensity against the hardware roofline, and tail latency deadlines. A violation requires scaling down model width or depth, applying quantization and compression, or switching to a lower-overhead architecture family.
- Empirical capacity and deployment validation: Verify that candidate capacity meets target accuracy on representative evaluation distributions. If predictive accuracy falls short, scale model capacity and re-evaluate physical hardware constraints. If target accelerator hardware cannot sustain the required arithmetic throughput or memory bandwidth, select an alternative architecture rather than relying on marginal hyperparameter adjustments.
Kernel-level choices refine this decision. Im2col or direct convolution, fused normalization, and IO-aware tiled attention (FlashAttention: IO-aware attention optimization) change realized traffic and utilization, and can shift which iron-law term binds; ML Frameworks and Hardware Acceleration develop them. Architectural dependencies still matter. Batching independent recurrent sequences or fusing their operations reduces per-step cost, while the ordered state transitions remain. Candidate selection and kernel measurements therefore inform each other.
6.9.5 Architecture selection in practice
Every selection must first pass a feasibility check: whether the target hardware can sustain the required frame rate at all. A server-class vision pipeline on a mid-range GPU shows the throughput ceiling calculation in its simplest form. The wildlife monitoring deployment that follows applies the same checks under a watt-scale budget where GPUs are ruled out, which is where data structure, model capacity, and hardware budgets interact.
Napkin Math 6.3: The throughput ceiling
Problem: A real-time application must process 30 FPS of video with ResNet-50. What sustained compute throughput is required?
Math:
- Model cost: ResNet-50 requires ~8.2 GFLOP per \(224{\times}224\) image.
- Frame rate: 30 FPS required.
- Sustained throughput: 30 FPS \(\times\) 8.2 GFLOP = 246 GFLOP/s.
- Effective throughput: 10 TFLOP/s peak \(\times\) 50–60 percent utilization = 5 TFLOP/s–6 TFLOP/s.
- ResNet-50 headroom: 5 TFLOP/s \(\div\) 246 GFLOP/s = 20.3×.
- Detection-model check: 30 FPS \(\times\) 100 GFLOP = 3 TFLOP/s, leaving 1.7× headroom at the lower effective-throughput estimate.
Systems insight: A mid-range GPU delivering 10 TFLOP/s theoretical peak achieves 50–60 percent utilization in this planning scenario, yielding 5 TFLOP/s–6 TFLOP/s effective. For ResNet-50 at 30 FPS, the system has 20.3× headroom. Switching to an object detection model at 100 GFLOP per frame, however, requires 3 TFLOP/s sustained, leaving only 1.7× headroom. Batch size constraints or multi-stream processing quickly push the system toward the compute ceiling. The headroom assumes the GPU stays busy; a single 30 FPS stream runs at batch one, where kernel launches and small matrices usually hold utilization well below this planning figure.
The throughput ceiling converts an abstract compute requirement into a concrete hardware utilization percentage. A real-world deployment adds physical constraints the ceiling alone does not capture.
Worked example: Real-time wildlife monitoring
The design task is an embedded ML system that classifies wildlife species from camera trap images in an isolated national park. The deployment must execute inference entirely on-device with zero network connectivity, operate on solar-recharged battery power for six months, and achieve 90 percent accuracy across 50 target animal species. The walk-through applies the three-phase framework in five steps. Data characterization is the symmetry phase. Deployment constraint profiling, candidate architecture evaluation, and hardware budget checks carry out the constraint-filtering phase. Operational risk assessment sets up the validation phase that only target-device measurement can complete.
The first step characterizes the data. The input consists of camera trap image frames (\(1920{\times}1080\) raw sensor resolution, downsampled to \(224{\times}224\) for inference). Three properties favor a CNN candidate: spatial locality (fur textures or ear shapes occupy bounded neighborhoods), label invariance to translation (moving an animal within the frame should preserve its species label), and hierarchical composition (edges combine into textures, anatomical parts, and organisms). Convolution provides equivariant intermediate features that follow the animal’s location; pooling can then support an invariant classification. Local weight sharing supplies a compact feature detector for these images.
The second step, constraint profiling, translates the deployment environment into hard hardware boundaries. Table 12 catalogs these physical constraints alongside the architectural requirements each imposes:
| Constraint | Requirement | Implication |
|---|---|---|
| Connectivity | None (offline) | All inference must run on-device |
| Power | ~2 W average (solar + battery) | Rules out GPUs; needs a low-power SoC or edge NPU |
| Latency | <500 ms per detection | Allows batch size 1, no real-time streaming |
| Memory | 512 MB RAM, 2 GB storage | Model, activations, and runtime buffers must fit locally |
| Accuracy | 90%+ on 50 species | Requires sufficient model capacity |
With physical constraints established, the third step evaluates candidate architectures against reference model baselines. The planning scenario reserves 100 MB of the available RAM for model weights, leaving the rest for activations, system software, and runtime buffers:
- ResNet-50 (25.6M parameters, 8.2 GFLOP): A costly starting point for the 2 W envelope. Its weights fit once quantized (25.6 MB in INT8 against 102.2 MB in FP32), but its arithmetic does not: at the platform’s 2 GOPS of sustained INT8 throughput assumed below, one frame takes about 4.1 seconds against a 500 ms target.
- MobileNetV1 (4.2M parameters, 1138 MFLOP): A viable footprint and operation count. Its low arithmetic intensity, which can leave a data center GPU’s matrix units idle, costs far less on a batch-one edge CPU whose much smaller compute peak is easier to keep busy. Storing weights in INT8 reduces model footprint to 4.2 MB (16.8 MB in FP32), and factorized depthwise separable convolutions reduce arithmetic operations.
- KWS DS-CNN (200K parameters, 20 MFLOP): An unmatched baseline. This model targets audio keyword spotting, so its reported size and task results do not establish accuracy on visual species classification. An adapted compact vision model would require training and evaluation on the camera-trap task.
While MobileNetV1 demonstrates the viability of depthwise separable convolutions, MobileNetV2 offers inverted residual blocks with linear bottlenecks as another compact candidate. Sizing the model with width multiplier 0.75× yields ~2.6M parameters (10.4 MB FP32, 2.6 MB with INT8 weights) and costs ~418 MFLOP at \(224{\times}224\) input resolution. Its weight footprint fits the allocation; task evaluation must establish whether its capacity meets the accuracy target for the 50 species.
The fourth step, hardware sizing, checks the candidate against physical platform budgets. INT8 weights occupy 2.6 MB, the network’s largest activation tensor, a \(112{\times}112{\times}72\) expansion inside its second bottleneck block, occupies 0.9 MB in INT8, and the scenario reserves 50 MB for OS and runtime buffers. Their 53.5 MB subtotal is only a single-tensor screen. Peak memory must instead include the weights, the maximum sum of simultaneously live tensor bytes, kernel workspace, and OS and runtime buffers. Inputs and outputs can coexist, and a residual path retains its input while the branch executes. The scenario has not yet established that live-tensor peak or the required workspace, so the small subtotal supports candidacy without confirming a fit in 512 MB of RAM.
For the candidate system-on-chip (SoC), an ARM Cortex-A53 at 1.2 GHz with NEON SIMD, this planning calculation assumes sustained throughput of ~2 GOPS INT8: \(\frac{418 \times 10^6 \text{ INT8 ops}}{0.002 \times 10^{12} \text{ INT8 ops/s}} = 209 ms \text{ latency} \ll 500 ms \text{ target}~\checkmark\)
Active power represents the final physical gate. At an estimated active inference draw of ~200 mW over 209 ms, each classification consumes 41.8 mJ. For a trigger-based rate of 100 inferences/day, model execution consumes 4.2 J/day. Full-system energy must also include image capture, sleep current, storage, and peripherals. Battery capacity, conversion losses, trigger frequency, and seasonal solar yield determine whether that daily budget supports six months of operation.
The fifth step assesses operational risks in the field. Table 13 pairs the primary accuracy, thermal, and coverage failure modes with corresponding systems engineering mitigations:
| Risk | Mitigation |
|---|---|
| 90% accuracy not achieved | Train on augmented dataset; consider EfficientNet-Lite if MobileNet insufficient |
| Thermal throttling in enclosure | Add passive heatsink; reduce inference frequency in high-temperature conditions |
| New species added postdeployment | Expand or retrain the output head; install the update during a physical service visit |
The sizing exercise selects MobileNetV2 (0.75× width multiplier) quantized to INT8 as a candidate for an ARM Cortex-A53 SoC with 512 MB RAM. Under the assumed sustained throughput, the arithmetic estimate is approximately 209 ms per frame. Qualification now requires target-device measurements of end-to-end latency, peak memory, thermal behavior, and full-system energy, together with classification accuracy on representative camera distributions and seasonal battery tests. In production, this qualification phase regularly exposes counterintuitive trade-offs: models with fewer FLOPs can stall on bandwidth-limited hardware, expressive architectures can degrade on datasets lacking matched structure, and lab prototypes can fail against deployment memory hierarchies.
Self-Check: Question
The workload profile gives the transformer two rows, prefill and decode, even though both run the same weights. Under the table’s representative reuse and streaming assumptions, which statement correctly explains why the binding iron-law term can differ between them at small batch size?
- Prefill binds on the data term because it must read the whole prompt from storage, while decode binds on the compute term because each token requires a full forward pass.
- Prefill processes all \(S\) prompt tokens together, which can raise effective reuse and arithmetic intensity enough for the compute term to bind under the stated assumptions; decode processes one token at a time with reread weights and a growing KV cache, so the data term often binds at small batch.
- Both phases bind on memory capacity, because the KV cache always exceeds device memory.
- Decode is compute bound because its \(\mathcal{O}(S^2)\) attention scores dominate, while prefill is latency bound because tokens are processed serially.
The chapter notes that the intensity column of the workload profile doubles as an energy column. Which statement correctly explains why a batch-one MLP or transformer decode step spends far more energy per useful operation than a convolutional layer, even on the same accelerator?
- The MLP and decode step perform more multiply-accumulates per weight than a convolution, so their arithmetic energy is higher.
- The CNN’s spatial locality lets it skip most of its multiply-accumulates, so it performs less arithmetic overall.
- All three load weights from DRAM once per batch, so their energy per operation is the same; only latency differs.
- The MLP and decode step load each weight from DRAM and use it about once per request, so DRAM traffic dominates their energy, while a convolution reuses each filter load across every position of its feature map and amortizes that movement.
In the systematic Architecture Selection Decision Framework, if a candidate model fails the inference speed or memory budget constraint check on the target device, the engineer must immediately abandon on-device edge execution and route all inference to a cloud data center.
In the wildlife monitoring edge deployment case study (50 species classification on a 2 W battery-powered Cortex-A53 device with 512 MB RAM and a <500 ms latency target), explain why MobileNetV2 (0.75 width multiplier with INT8 quantization) was selected as the candidate to validate over ResNet-50 and KWS DS-CNN.
A dense MLP layer running batch-1 FP32 inference reports an arithmetic intensity of \(\approx 0.5\text{ FLOP/byte}\), while an image convolution bottleneck layer achieves \(>50\text{ FLOP/byte}\) on the same accelerator. Using the roofline model and an accelerator ridge point of \(150\text{ FLOP/byte}\), explain what follows from these numbers and what additional convolution measurement is needed before calling the convolution compute bound. Also explain why upgrading to an accelerator with double the peak TFLOP/s but unchanged memory bandwidth will not speed up the batch-1 MLP.
A production profiler reveals that a model’s embedding tables consume over 1 TB of memory across cluster nodes, inference requests perform sparse random row lookups rather than dense matrix multiplies, and accelerator compute units remain over 95% idle. Which lighthouse archetype best represents this workload’s dominant system constraint?
- DLRM, because the binding constraint is memory capacity for terabyte-scale embedding tables accessed via sparse, irregular memory gathers.
- ResNet-50, because it stresses dense matrix floating-point throughput across regular convolutional grids.
- GPT-2, because autoregressive decoding is the canonical memory-bandwidth-limited serving workload.
- MobileNetV2, because depthwise-separable convolutions produce low arithmetic intensity on server GPUs.
6.10 Fallacies and Pitfalls
Architecture choice is a systems decision, not a leaderboard selection. The common mistakes in architecture selection arise when teams treat architecture families as interchangeable accuracy tools while ignoring inductive bias, memory traffic, hardware mapping, and deployment state.
Fallacy: More complex architectures always perform better than simpler ones.
Engineers often assume that transformers outperform simpler architectures on all tasks. In production, the better choice is the simplest model that matches the data’s structure and the machine’s budget. Vision transformers matched CNN accuracy on ImageNet only after pretraining on far larger datasets (Dosovitskiy et al. 2021), or later with heavy augmentation and distillation; without that data or that training machinery, the CNN’s locality bias wins at lower cost. The bitter lesson favors weak priors only once data and compute are large enough to pay for them, and a deployment that cannot supply that data and compute gets the cost of the weak prior without its benefit. Accuracy, training cost, and inference latency still require measurement for the specific implementation and task.
Pitfall: Selecting architectures based solely on accuracy metrics without analyzing computational requirements.
Practitioners choose architectures from papers reporting top-line accuracy, ignoring computational implications. RNNs expose a sequential critical path that limits parallelism, while transformers compute dense attention scores whose storage grows quadratically in naive implementations. Sequence length 2,048 therefore requires 16× more materialized score memory than length 512. Systems that ignore these characteristics can miss latency targets, exceed memory budgets, and deliver much lower hardware utilization than expected.
Fallacy: An architecture has one dominant bottleneck across training and inference.
The same computation graph can occupy different systems regimes. Transformer training and prefill process many positions together and may bind on dense attention compute; small-batch autoregressive decoding repeatedly streams weights and KV-cache state and may bind on memory bandwidth. Batching, sequence length, precision, and cache layout can shift that boundary. A benchmark from one regime therefore cannot establish another’s bottleneck; measure each against the iron law.
Pitfall: Combining architectural patterns without analyzing interaction effects at the system level.
Engineers add attention to CNNs or convolutions to transformers expecting additive benefits. Each pattern creates distinct memory access characteristics: CNNs exploit spatial locality through sliding windows, while dense attention introduces all-to-all score computation. Combining them can increase intermediate traffic and disrupt locality, so the hybrid’s throughput cannot be inferred by adding the components’ benefits. Adding recurrent connections to transformers likewise reintroduces sequential dependencies. Successful hybrids require profiling memory access and cache behavior before combining patterns.
Fallacy: Architecture wins on training hardware transfer directly to deployment hardware.
Teams design for high-end GPU clusters, then discover deployment failures on target hardware. An architecture exploiting 8\(\times\) A100 GPUs (640 GB total memory) cannot deploy unchanged to a representative edge node such as the NVIDIA Jetson Orin NX (16 GB system memory). As section 6.9.4 emphasizes, architecture selection must analyze the full system stack because storage, latency, and power budgets vary by deployment target.
Pitfall: Ignoring KV cache growth when estimating transformer serving costs.
Teams budget transformer deployment based on model weight memory alone, overlooking the key-value (KV) cache used during autoregressive generation (Pope et al. 2023; Kwon et al. 2023). The cache grows linearly with concurrent sequences, layers, heads, and sequence length, so at long contexts or high concurrency it can become a binding serving constraint. The KV-cache footnote in section 6.7.4.2 works through the chapter’s 32-layer, 32-head example. With 128-dimensional heads, 2,048-token sequences, and FP16 storage, each concurrent request holds \(\approx\) 1 GB of KV cache. At 2–4 users, the cache alone consumes 2 GB–4 GB before allocator, activation, and workspace overhead. Those values consume part of the post-weight headroom of an 80 GB device and grow linearly with context and concurrency. Capacity planning must therefore budget weights, cache, and runtime buffers together, then reduce concurrency, context, or cache footprint, or add memory capacity, when the combined total approaches device memory.
Pope, Reiner, Sholto Douglas, Aakanksha Chowdhery, Jacob Devlin, James Bradbury, Jonathan Heek, Kefan Xiao, Shivani Agrawal, and Jeff Dean. 2023. “Efficiently Scaling Transformer Inference.” Proceedings of Machine Learning and Systems (MLSys) 5: 606–24.
Self-Check: Question
Why is estimating LLM transformer serving memory based solely on static model parameter footprint (e.g., 14 GB for a 7B FP16 model) a critical engineering pitfall in production deployments?
- Because model weights expand by \(10\times\) in memory due to framework compilation graph overhead.
- Because inference requires storing three full optimizer states (momentum and variance buffers) in GPU RAM.
- Because transformers delete their weights after processing each token and must reload them from disk.
- Because autoregressive decoding dynamically accumulates a Key-Value (KV) cache that scales linearly with context length and concurrency (\(\mathcal{O}(B \times S)\)), which at high concurrency or long context windows can rival or exceed the static weight memory.
Explain the fallacy: ‘An architecture has one dominant bottleneck across training and inference.’ Use the Transformer architecture to illustrate how execution regime (full-sequence training/prefill vs. batch-1 autoregressive decoding) shifts the primary hardware bottleneck.
True or False: Because a hybrid neural network architecture combining convolutional layers with self-attention achieves higher top-1 accuracy on a benchmark leaderboard, it is guaranteed to maintain the high throughput and low memory traffic of the pure CNN baseline.
A vision model trained on a cluster of \(8 \times \text{A100}\) GPUs (640 GB total memory) achieves state-of-the-art accuracy. Why is assuming this model will deploy successfully to an edge device such as an NVIDIA Jetson Orin NX (16 GB memory) a dangerous fallacy, even if the model weights require only 8 GB?
- Because total runtime memory during inference includes intermediate activation tensors, workspace scratchpads, and operating system buffers; under high batch sizes or high input resolutions, these activation and workspace buffers easily exceed the remaining 8 GB memory ceiling.
- Because edge devices are mathematically incapable of executing the floating-point multiplication instructions used by server GPUs.
- Because models trained on 8 GPUs permanently hardcode an 8-way tensor parallel communication protocol that fails if fewer than 8 physical GPUs are connected.
- Because PyTorch and TensorFlow models can only run on cloud-hosted Linux kernels and cannot execute on embedded SoCs.
6.11 Summary
Architecture is infrastructure. Choosing among MLPs, CNNs, RNNs, transformers, and recommendation models (DLRM) shapes the physical terms in the serialized form of the iron law of ML systems (\(\Time= \DataVolume/\Bandwidth + \Operations / (\PeakRate \cdot \EfficiencyHw) + \Latency\)). Examining each architecture through the four-part lens (pattern processing needs, algorithmic structure, computational mapping, and system implications) connects mathematical inductive bias to work, state, and dependencies. Execution conditions and the target machine then determine which term binds hardware performance.
The durable tool is arithmetic intensity read against the machine’s balance. Reuse raises \(\ArithmeticIntensity = \Operations/\DataVolume\) and pushes a workload toward the compute term, as ResNet-50 does when batched; streamed weights lower it and expose the data term, as GPT-2 decoding does at small batch. Two families escape that single axis. A recurrent dependency chain sets a floor of \(\SequenceLength\) ordered updates that neither term removes, and an oversized embedding table imposes a capacity decision that fixes which bandwidth the data term pays before any arithmetic begins. Low FLOP counts, as MobileNetV2 and KWS show, help only when the resulting operation shapes still keep the hardware’s functional units busy.
Key Takeaways: Architecture is infrastructure
- Inductive bias is the unifying concept: Every architecture encodes structural assumptions, such as locality for CNNs, sequence for RNNs, and global context for transformers. These biases trade generality for sample efficiency and determine which problems an architecture can solve efficiently.
- Intensity against balance names the bottleneck: A workload’s arithmetic intensity, set against the machine’s balance, predicts whether compute or bandwidth binds. One transformer sits on both sides: prefill reuses every weight across the prompt, while batch-one decode re-reads every weight and a growing KV cache for each token.
- Quadratic costs are permanent constraints: Dense transformer attention computes \(\mathcal{O}(\SequenceLength^2)\) score interactions. Naive implementations also use quadratic score storage; tiled exact attention removes that storage cost but not the dense computation.
- Lighthouse models isolate distinct bottlenecks: ResNet-50 (compute), GPT-2 (bandwidth), DLRM (capacity), MobileNetV2 (compute-bound in its efficient regime, under an edge latency budget), KWS (power-bound). Each isolates one regime, and together they diagnose which physical constraint dominates a given system.
- Depth benefits from architectural support: Skip connections and normalization improve optimization in deep networks rather than acting as universal prerequisites beyond a fixed depth. These building blocks, illustrated here through CNNs, transfer to many deep architectures, including transformers.
- FLOPs do not equal speed: MobileNetV2 uses 13.7× fewer FLOPs than ResNet-50 but can gain far less than that on data center GPUs when its operation shapes and arithmetic intensity use the available compute units poorly. Architecture-hardware alignment, not operation count alone, determines throughput.
- Architecture selection is deployment selection: Choosing a transformer over a CNN determines memory requirements, latency floors, hardware utilization, and infrastructure costs. The architecture is the system constraint.
Architecture selection signs the silicon contract (principle 4) with hardware. A CNN commits to spatial locality and weight reuse; dense attention commits to \(\mathcal{O}(\SequenceLength^2)\) score computation; and an RNN commits to serial time-step dependencies. These topological choices constrain operations \(\Operations\), opportunities for reducing transferred data \(\DataVolume\), and dependency order. Realized memory footprint, bandwidth demand, and parallel efficiency also depend on the implementation. Pipelining consecutive stages across execution units overlaps work without removing the serial time-step path. Systems engineers can therefore anticipate likely bottleneck shifts before implementation by matching model inductive bias and data geometry to silicon physics.
What’s Next: From blueprints to construction
Raw computational primitives (Neural Computation) became concrete architectures in this chapter. Each architecture fixes what work must be performed, yet nothing in an architecture says when its operations run, how their gradients are computed, or which device executes them. A machine learning framework answers those three questions, acting as a compiler that lowers the architectural graph to the silicon. ML Frameworks examines how PyTorch, TensorFlow, and JAX solve these execution, differentiation, and hardware-abstraction problems, turning architectural graphs into computational graphs, autograd records, and optimized device kernels.
6.12 Self-Check Answers
Self-Check: Answer
A team must choose between an MLP and a CNN for classifying \(224 \times 224\) pixel RGB medical images. A single dense first layer would require \(224 \times 224 \times 3 = 150{,}528\) input weights per output unit (yielding roughly 150 million weights for a 1,000-unit layer), whereas a CNN uses a shared \(3 \times 3 \times 3\) filter (27 weights). Using the chapter’s framing of inductive bias, which statement best explains why the CNN is the superior starting point?
- The CNN is strictly more expressive than the MLP, allowing it to approximate non-continuous functions that the Universal Approximation Theorem forbids.
- The MLP is mathematically incapable of representing any 2D spatial feature mapping due to lack of convolutional instruction support.
- The CNN eliminates gradient descent during optimization because convolutional spatial filters are deterministic, handcrafted operators.
- The CNN’s spatial locality and weight-sharing prior directly matches image structure: convolution is translation equivariant, later pooling or aggregation can provide invariance for classification, and each feature detector uses far fewer weights than a dense detector.
Answer: The correct answer is D. The chapter’s point is not that CNNs are universally better, but that their locality and weight-sharing prior matches image structure well: the same detector can be reused across positions, and convolution is translation equivariant while later pooling can support invariant class labels. An answer based on greater expressiveness gets the comparison backwards, since CNNs are more constrained than MLPs, and the claim that convolutions remove learning is false because CNN filters are still learned by gradient descent.
Learning Objective: Apply the inductive bias concept to justify a CNN-over-MLP architecture choice on structured spatial data and explain how the bias reduces per-detector parameter count while preserving useful spatial structure.
Because an inductive bias restricts the hypothesis space to a smaller set of representable functions, machine learning systems engineers should always select the architecture with the strongest possible inductive bias for every workload.
Answer: False. By the No Free Lunch theorem, an inductive bias only improves generalization and efficiency when its structural assumptions align with the true data-generating distribution. Imposing a strong spatial locality bias (such as a CNN) on tabular records or global language dependencies prevents the model from representing necessary non-local relationships, resulting in severe underfitting and degraded accuracy.
Learning Objective: Evaluate the trade-offs of inductive bias strength and justify why structural assumptions must align with data domain properties.
Why does the chapter describe selecting a neural network architecture as ‘signing a contract with physics’ rather than merely selecting a mathematical modeling preference? Explain how architectural graph structure shapes or constrains the terms in the iron law of ML systems (\(T_{\text{exec}} = D_{\text{vol}}/\text{BW} + O/(R_{\text{peak}} \cdot \eta_{\text{hw}}) + L_{\text{lat}}\)) without making those terms fully fixed.
Answer: Selecting an architecture commits the system to a particular pattern of work, state, and dependencies before low-level optimization begins. A CNN tends to create local reuse, an RNN imposes ordered state updates, a transformer creates dense token interactions and KV-cache growth, and a DLRM can create capacity pressure when embedding tables exceed device memory; batching, cache behavior, precision, and kernel choices then determine how those structural commitments appear in realized data movement, utilization, and overhead. The practical consequence is that architecture choice constrains which iron-law term is likely to bind, but it does not make memory traffic or launch overhead immutable properties of the family.
Learning Objective: Explain how architectural graph structure acts as an infrastructure commitment by setting work, state, and dependency patterns that shape the iron-law terms.
Self-Check: Answer
A fully connected layer connecting 2,048 input units to 2,048 output units stores approximately 4.19 million weights (~16.8 MB in FP32). When applied to high-resolution image inputs, dense layers suffer severe parameter explosion. Which statement best captures the systems mechanism behind the MLP’s parameter and memory scaling?
- Dense layers use non-linear activations whose element-wise memory footprints dwarf the weight tensors by several orders of magnitude.
- MLP bias vectors grow quadratically with the output dimension, dominating total layer memory storage.
- The MLP encodes no specific spatial or temporal connectivity pattern, so every one of the \(d_{\text{in}}\) inputs can connect to every one of the \(d_{\text{out}}\) outputs, yielding \(\mathcal{O}(d_{\text{in}} \times d_{\text{out}})\) weights and, when weights stream for batch-1 inference, comparable weight-memory traffic per sample.
- Dense layers require storing three master copies of every weight matrix in hardware registers during inference forward passes.
Answer: The correct answer is C. The chapter defines MLPs by the absence of a specific spatial or temporal prior, so the layer must materialize the full \(d_{\text{in}} \times d_{\text{out}}\) matrix. That fixes dense parameter storage by dimensions, and in small-batch streamed-weight inference it can also make weight traffic scale with the same matrix size. The bias-vector explanation is too small to dominate, and an answer focused on activation memory confuses a conditional runtime effect with the architectural source of the parameter count.
Learning Objective: Apply the MLP’s unrestricted connectivity pattern to explain why parameter count scales as \(\mathcal{O}(d_{\text{in}} \times d_{\text{out}})\) and why streamed-weight inference can become bandwidth limited.
A team cites the Universal Approximation Theorem (UAT) to argue that a wide 3-layer MLP should be used to classify \(256 \times 256\) RGB images instead of a CNN. Explain why UAT does not justify this design choice in practice, detailing both the statistical failure mode (sample complexity) and the systems failure mode (memory bandwidth and parameter explosion).
Answer: UAT is only an existence result: it says a sufficiently large MLP can represent a target function, not that gradient descent will find it efficiently or that the required width will be practical. For images, flattening \(256 \times 256\) RGB inputs into 196,608 features removes the spatial prior, so the model must learn locality and reuse from data that a matched CNN encodes structurally; sample needs therefore depend on the target distribution and learning procedure, and a CNN can need fewer examples when that prior matches the task. On the systems side, connecting 196,608 inputs to 4,096 hidden units creates about 805 million weights, which is useful for capacity planning, and under a streamed-weight batch-1 model leaves low arithmetic intensity unless batching or cache reuse changes the traffic pattern.
Learning Objective: Analyze the gap between UAT’s representational guarantee and practical learnability, and connect it to both sample-efficiency and systems-cost consequences for image models.
The ____ hypothesis states that high-dimensional real-world data (such as natural images) actually resides on a much lower-dimensional structured surface embedded within the full input space, helping explain why useful structure can be learned from finite data.
Answer: manifold. The manifold hypothesis proposes that high-dimensional data lies near a lower-dimensional structured region in the ambient space, which helps explain why learning can exploit structure without searching the full input space.
Learning Objective: Identify the manifold hypothesis from its description and explain how it motivates learnability in high-dimensional settings.
A single dense layer (\(2{,}048 \times 2{,}048\)) running FP32 inference on an A100 GPU at batch size 1 achieves only ~4% of peak compute throughput, with profilers reporting an arithmetic intensity of \(\approx 0.5\text{ FLOP/byte}\). What is the most effective engineering solution to move this kernel out of the memory-bandwidth-bound regime and raise hardware utilization?
- Increase the batch size (\(B > 1\)), transforming the matrix-vector multiplication (GEMV) into a matrix-matrix multiplication (GEMM), which amortizes weight loading across \(B\) samples and scales arithmetic intensity.
- Replace the dense matrix multiplication with an unvectorized scalar loop to avoid GPU kernel launch overhead.
- Upgrade to an accelerator with double the peak FP32 TFLOP/s while keeping the batch size at 1.
- Replace the linear transformation with an element-wise activation function to eliminate all weight memory traffic.
Answer: The correct answer is A. At batch size 1, each weight is read from memory to compute a single multiply-accumulate (GEMV), yielding \(I \approx \frac{2 \cdot M \cdot N}{4 \cdot M \cdot N} = 0.5\text{ FLOP/byte}\) in FP32. Batching \(B\) samples together transforms the kernel into a GEMM (\(\mathbf{X}\mathbf{W}\) where \(\mathbf{X} \in \mathbb{R}^{B \times M}\)), performing \(2 \cdot B \cdot M \cdot N\) FLOPs for the same \(4 \cdot M \cdot N\) weight bytes read (ignoring activation traffic), which scales arithmetic intensity linearly with \(B\) and pushes execution into the compute-bound regime. An unvectorized scalar loop would severely degrade SIMD instruction throughput. Upgrading peak TFLOP/s leaves memory bandwidth unchanged and does not solve a bandwidth bottleneck. Eliminating the matrix multiplication would change the underlying mathematical function of the network.
Learning Objective: Analyze a batch-1 dense-layer kernel as bandwidth-bound from a FLOP/byte signature and select batching as the intensity-raising fix rather than a compute upgrade.
In the nested loop implementation of an MLP forward pass (
for batch,for out,for in_), calculate the exact number of multiply-accumulate (MAC) operations and logical operand reads required to compute 128 hidden neurons from a 784-dimensional MNIST input vector at batch size 1. In your count, treat the scalar loop as reading inputs and weights only, explicitly excluding bias traffic and output writes, and explain why this count is not the same as the number of DRAM transactions. Also explain how framework-level BLAS libraries optimize this pattern.Answer: For 128 outputs and 784 inputs at batch size 1, the layer performs \(784 \times 128 = 100{,}352\) MACs, or 200,704 FLOPs if each MAC is counted as 2 FLOPs. At the scalar-loop level, each output neuron reads 784 input values and 784 weights, for 1,568 logical operand reads per neuron and 200,704 across the layer, explicitly excluding bias reads and output writes; as the text notes, that is not the same as 200,704 DRAM transactions because caches, registers, and tiling can satisfy many logical reads from faster memory after reuse. The practical consequence is that BLAS libraries improve throughput by blocking, vectorizing, and reusing this regular pattern so more operand reads are served from fast memory tiers rather than repeatedly fetched from DRAM.
Learning Objective: Calculate the exact MAC count and logical operand-read count of an MLP layer, and distinguish that count from physical DRAM traffic.
Self-Check: Answer
A \(3 \times 3\) convolutional layer with 64 input channels and 64 output channels processes a \(224 \times 224\) feature map, producing 64 spatial output channels. How does its parameter count compare with a dense layer that maps the flattened \(224 \times 224 \times 64\) input to 64 scalar outputs, and why are the outputs not shape-equivalent?
- The CNN requires \(205\text{ million}\) parameters, whereas the dense layer requires only \(36{,}864\) parameters due to flattened matrix vectorization.
- The CNN requires \(3 \times 3 \times 64 \times 64 = 36{,}864\) parameters (~37K), whereas a dense layer mapping a \(224^2 \times 64\) input to 64 scalar outputs requires \(224^2 \times 64 \times 64 \approx 205\text{ million}\) parameters; the output shapes are not equivalent.
- Both architectures require exactly the same number of parameters because both perform 64-to-64 channel transformations.
- The CNN requires 9 parameters because spatial weight sharing reduces all kernel weights across all channels to a single \(3 \times 3\) matrix.
Answer: The correct answer is B. Convolution shares one \(3 \times 3\) detector per input-output channel pair across all spatial positions, so its parameter count depends on kernel size and channels, not image resolution. The dense comparison reaches about 205 million parameters only because it maps the flattened \(224 \times 224 \times 64\) input to 64 scalar outputs, which is not the same output shape as 64 spatial feature maps. An answer claiming the counts are equal ignores weight sharing, while the 9-parameter answer forgets that channel mixing still needs separate weights.
Learning Objective: Calculate how convolutional weight sharing changes parameter count, and distinguish per-detector comparisons from non-equivalent whole-output comparisons.
Distinguish between translation equivariance (\(f(\mathcal{T}(\mathbf{x})) = \mathcal{T}(f(\mathbf{x}))\)) and translation invariance (\(f(\mathcal{T}(\mathbf{x})) = f(\mathbf{x})\)). Explain why intermediate convolutional layers must maintain equivariance for object detection while final classification layers often apply global average pooling to achieve invariance.
Answer: Translation equivariance means that shifting the input shifts the output feature map by the exact same spatial offset, preserving precise positional and geometric relationships (‘eye above nose’). Invariance means that transforming the input produces an identical, unchanging output, discarding spatial coordinates. Intermediate layers in object detection must remain equivariant so that downstream bounding box predictors can accurately localize object coordinates \((x, y, w, h)\). Final classification layers introduce invariance (via global average pooling) because the class label (‘dog’) must remain unchanged regardless of where the object appears in the frame.
Learning Objective: Compare translation equivariance and invariance, and justify their respective roles in intermediate feature extraction versus final classification.
**Order the sequence of operations performed when executing a 2D convolution layer via the standard im2col lowering transformation followed by activation:
- Multiply the unfolded patch matrix by the stacked filter weight matrix using a standard GEMM library call
- Reshape and fold the resulting 2D GEMM output matrix back into the 4D spatial feature map tensor \((B, C_{\text{out}}, H_{\text{out}}, W_{\text{out}})\)
- Unfold overlapping \(K \times K\) receptive field input patches into columns (or rows) of a 2D matrix
- Add channel bias vectors and apply the element-wise nonlinear activation function (e.g., ReLU)
- Receive the 4D input activation tensor of shape \((B, C_{\text{in}}, H_{\text{in}}, W_{\text{in}})\)**
Answer: The correct order is (5) -> (3) -> (1) -> (2) -> (4). Step 1 is (5) Receive 4D input tensor \((B, C_{\text{in}}, H_{\text{in}}, W_{\text{in}})\). Step 2 is (3) Unfold input patches into a 2D matrix via im2col. Step 3 is (1) Multiply unfolded input matrix by filter weights via GEMM. Step 4 is (2) Reshape 2D GEMM result into 4D output feature map. Step 5 is (4) Add bias and apply element-wise activation.
Learning Objective: Explain the operational sequence of the im2col transformation in lowering 2D convolutions to matrix multiplications.
Because MobileNetV2 requires roughly 14\(\times\) fewer FLOPs than ResNet-50 per \(224 \times 224\) image, it is guaranteed to execute at least 10\(\times\) faster on any data center GPU.
Answer: False. FLOPs measure arithmetic work, not execution latency. MobileNetV2 uses depthwise separable convolutions that have low arithmetic intensity and small channel dimensions per kernel, which can fail to saturate dense matrix units (such as Tensor Cores) on server GPUs. Because memory access and operator launch overhead can dominate compute, MobileNetV2 may achieve less than proportional speedup or even run slower than ResNet-50 on high-end GPUs.
Learning Objective: Evaluate the fallacy that FLOP count directly equals inference latency and explain why arithmetic intensity dictates hardware speedup.
A depthwise separable convolution decomposes standard convolution into two sequential operations: a ____ convolution that applies spatial filters to each input channel independently, followed by a \(1 \times 1\) pointwise convolution that projects and mixes channels across the depth dimension.
Answer: depthwise. Depthwise separable convolution factorizes standard convolution into a depthwise convolution (spatial filtering per channel) and a pointwise convolution (\(1 \times 1\) cross-channel linear combination).
Learning Objective: Explain depthwise separable convolution components and explain how factorizing spatial and channel mixing reduces arithmetic complexity.
In a deep CNN using stacked \(3 \times 3\) convolutional filters with stride 1 and padding, by how much does the receptive field side length increase with each additional layer, and what is the architectural implication for detecting large objects?
- Receptive field increases by 9 pixels per layer, allowing a 3-layer network to cover an entire \(224 \times 224\) image.
- Receptive field side length doubles with each layer, scaling exponentially as \(3^L\).
- Receptive field side length grows linearly by 2 pixels per layer (a 3-layer stack sees a \(7 \times 7\) region), requiring deep stacks of layers or downsampling (pooling/striding) to detect objects spanning \(100+\) pixels in high-resolution images.
- Receptive field remains strictly fixed at \(3 \times 3\) across all layers because convolutional filter weights are shared across positions.
Answer: The correct answer is C. Each successive \(3 \times 3\) stride-1 convolutional layer expands the receptive field side length by \(K - 1 = 2\) pixels (layer 1 sees \(3 \times 3\), layer 2 sees \(5 \times 5\), layer 3 sees \(7 \times 7\)). To detect large objects spanning 100+ pixels in a \(224 \times 224\) image, networks must either use deep stacks of layers, strided convolutions, or pooling operations. The claim of 9 pixels confuses kernel area with linear side growth. The claim of exponential doubling is incorrect for stride-1 layers. The claim that receptive field remains \(3 \times 3\) confuses single-layer kernel size with cumulative receptive field depth.
Learning Objective: Calculate receptive field growth across stacked convolutional layers and analyze the depth-versus-downsampling trade-off in network design.
Self-Check: Answer
In a residual block implementing \(\mathbf{y} = \mathcal{F}(\mathbf{x}) + \mathbf{x}\), how does the additive identity shortcut mathematically improve gradient conditioning through the layer Jacobian \(\mathbf{J} = \frac{\partial \mathbf{y}}{\partial \mathbf{x}}\) during backpropagation in very deep networks?
- The shortcut forces the residual function \(\mathcal{F}(\mathbf{x})\) to have zero weights, turning the network into an immutable linear identity operator.
- The Jacobian takes the form \(\mathbf{J} = \mathbf{I} + \frac{\partial \mathcal{F}}{\partial \mathbf{x}}\), so when residual-branch derivatives are small the block stays near identity and gradients have a direct additive path, improving conditioning without guaranteeing exact unit gain at arbitrary depth.
- The shortcut doubles the singular values of the weight matrix at every layer, ensuring gradients explode exponentially rather than vanish.
- The shortcut eliminates the backpropagation chain rule by replacing gradient updates with forward-only finite differences.
Answer: The correct answer is B. Residual addition changes the block Jacobian from an arbitrary transformation to an identity-plus-residual form. When the residual branch stays small, that factor remains near the identity, so gradient propagation is better conditioned than in a plain deep stack. The shortcut does not force zero weights or remove backpropagation; it provides a direct path that improves conditioning, although those near-identity factors can still compound across depth rather than guaranteeing perfect unit gain.
Learning Objective: Analyze how identity skip connections change the block Jacobian to improve gradient conditioning in deep networks without guaranteeing perfect unit gain.
Compare Batch Normalization (BatchNorm) and Layer Normalization (LayerNorm) along two critical systems dimensions: (a) sensitivity to mini-batch size during training, and (b) operational differences between training and inference (including training-serving skew).
Answer: BatchNorm depends on batch statistics during training, so small batches can make those estimates noisy; for CNN activations it reduces over batch and spatial positions, not just batch alone. LayerNorm instead normalizes each sample independently across its feature dimension, so its behavior does not depend on mini-batch size. The practical consequence is that BatchNorm also changes behavior between training and inference by switching to running statistics, which can create training-serving mismatch, whereas LayerNorm uses the same per-sample computation in both modes.
Learning Objective: Compare BatchNorm and LayerNorm in terms of reduction axes, batch-size sensitivity, and training-versus-inference behavior.
Self-Check: Answer
An RNN processes a sequence of length \(S = 1{,}000\) tokens with hidden state dimension \(d_{\text{hidden}} = 128\). Which statement correctly describes the scaling of its inference state memory versus its training activation memory?
- Inference state memory is \(\mathcal{O}(d_{\text{hidden}})\) (constant \(\mathcal{O}(1)\) with respect to sequence length \(S\)), whereas training with backpropagation through time (BPTT) requires storing activations across all steps, scaling as \(\mathcal{O}(S \cdot d_{\text{hidden}})\) under ordinary retained-state BPTT.
- Both inference state memory and training activation memory scale quadratically as \(\mathcal{O}(S^2)\) due to recurrent hidden-to-hidden weight matrices.
- Inference state memory scales linearly as \(\mathcal{O}(S \cdot d_{\text{hidden}})\), while training memory is constant because weights are shared across all time steps.
- Inference requires zero memory because recurrent states are discarded immediately after computing output probabilities.
Answer: The correct answer is A. During inference, the recurrent update only needs the current hidden state, so runtime state is constant with respect to sequence length. Under ordinary full BPTT, training retains intermediate activations across all \(S\) steps so gradients can be propagated backward through time, which makes memory grow as \(\mathcal{O}(S \cdot d_{\text{hidden}})\). The quadratic answer confuses RNNs with dense attention, and saying this is a lower bound ignores that recomputation or checkpointing can trade extra work for less retained memory.
Learning Objective: Compare the memory complexity of RNN inference state with ordinary BPTT training memory, and distinguish retained activations from possible recomputation strategies.
Explain why upgrading an accelerator from 10 TFLOP/s to 100 TFLOP/s can reduce the elapsed time per recurrent step in an RNN processing a single long sequence, but cannot reduce the number of ordered state updates on the critical dependency chain. Contrast this with the parallel sequence processing capability of a transformer.
Answer: An RNN still has to execute the recurrence in order: step \(t\) depends on the hidden state produced at step \(t-1\), so the dependency chain still contains \(S\) ordered state updates even if faster hardware shortens the wall-clock time of each step. Kernel fusion can cut launch overhead and within-step work such as input projections can exploit parallel hardware, but those improvements do not remove the ordered state-update chain or make the dependency depth collapse. By contrast, a transformer’s full-sequence training or prefill path can process all positions together, replacing the recurrent time-step chain with parallel operations across sequence positions.
Learning Objective: Analyze why faster hardware can shorten recurrent step time without removing the sequential dependency chain, and contrast that with transformer prefill parallelism.
Because transformers offer superior parallelization and representational capacity for long-range dependencies, recurrent neural networks are entirely obsolete and have no valid deployment use cases in modern ML systems.
Answer: False. For streaming inference on resource-constrained microcontrollers (TinyML) and always-on audio devices with strict power and memory budgets, an RNN’s constant \(\mathcal{O}(1)\) state memory footprint (e.g., 2 KiB for a 512-dimensional FP32 state) is vastly superior to the linear KV-cache growth and quadratic attention requirements of transformers, making RNNs a systems-justified choice.
Learning Objective: Justify edge and streaming use cases where RNN constant-state memory is superior to transformer memory scaling.
**Order the mathematical and dataflow operations executed during a single time-step forward pass of a standard Elman RNN cell:
- Multiply the previous hidden state vector \(\mathbf{h}_{t-1}\) by the recurrent weight matrix \(\mathbf{W}_{\text{hh}}\)
- Multiply the current input vector \(\mathbf{x}_t\) by the input weight matrix \(\mathbf{W}_{\text{hx}}\)
- Sum the recurrent contribution, input contribution, and hidden bias vector \(\mathbf{b}_h\)
- Apply the nonlinear activation function (e.g., \(\tanh\)) to generate the new hidden state \(\mathbf{h}_t\)
- Multiply the new hidden state \(\mathbf{h}_t\) by the output weight matrix \(\mathbf{W}_{\text{yh}}\) to produce output \(\mathbf{y}_t\)**
Answer: The correct order is (2) -> (1) -> (3) -> (4) -> (5) (or (1) and (2) computed in parallel -> (3) -> (4) -> (5)). Step 1 and 2 project the input \(\mathbf{x}_t \mathbf{W}_{\text{hx}}\) and previous hidden state \(\mathbf{h}_{t-1} \mathbf{W}_{\text{hh}}\). Step 3 is (3) Sum the projections with bias \(\mathbf{b}_h\). Step 4 is (4) Apply \(\tanh\) activation to produce \(\mathbf{h}_t\). Step 5 is (5) Project \(\mathbf{h}_t\) via \(\mathbf{W}_{\text{yh}}\) to compute output \(\mathbf{y}_t\).
Learning Objective: Explain the operational dataflow and matrix operations executed within a single RNN time step.
During backpropagation through time (BPTT) over \(S\) time steps, the gradient of the loss with respect to the initial hidden state satisfies \(\frac{\partial \mathcal{L}}{\partial \mathbf{h}_0} \propto \prod_{t=1}^S \frac{\partial \mathbf{h}_t}{\partial \mathbf{h}_{t-1}}\). Explain the mathematical mechanism that causes gradients to vanish or explode as \(S\) grows large.
Answer: The gradient is a product of Jacobians across many recurrent steps, and for the column-vector recurrence in the text one step has the form \(\mathbf{J}_t = \operatorname{diag}(f'(\mathbf{z}_t))\,\mathbf{W}_{\text{hh}}\). If these repeated transformations contract the propagated directions, the product shrinks and long-range gradients vanish; if they repeatedly expand the propagated directions, the product grows and gradients can explode. The practical consequence is that simple RNNs can lose distant information or become numerically unstable over long horizons, even though a single step may look well behaved.
Learning Objective: Analyze how repeated Jacobian products in BPTT can contract or amplify gradients across long recurrent horizons.
In a standard RNN layer with input dimension \(d_{\text{in}} = 100\) and hidden state dimension \(d_{\text{hidden}} = 128\), how many total multiply-accumulate (MAC) operations are performed per sequence step to compute the unactivated hidden state?
- 12,800 MACs, because only the input projection performs matrix multiplication.
- 29,184 MACs, consisting of \(128 \times 128 = 16{,}384\text{ MACs}\) for the recurrent projection plus \(100 \times 128 = 12{,}800\text{ MACs}\) for the input projection.
- 1,280,000 MACs, because recurrence multiplies all hidden states across all past time steps simultaneously.
- 256 MACs, because an RNN updates only a single vector addition per step.
Answer: The correct answer is B. At each time step, the RNN performs two distinct matrix multiplications: the recurrent projection \(\mathbf{h}_{t-1} \mathbf{W}_{\text{hh}}\) requires \(128 \times 128 = 16{,}384\text{ MACs}\), and the input projection \(\mathbf{x}_t \mathbf{W}_{\text{hx}}\) requires \(100 \times 128 = 12{,}800\text{ MACs}\). Together, these sum to \(16{,}384 + 12{,}800 = 29{,}184\text{ MACs}\) per step per batch item. The choice of 12,800 MACs omits the recurrent projection. The choice of 1,280,000 MACs incorrectly assumes quadratic all-to-all history computation. The choice of 256 MACs confuses dimension addition with full matrix transformations.
Learning Objective: Calculate the per-step multiply-accumulate arithmetic cost of input and recurrent projections in an RNN layer.
Self-Check: Answer
Why does scaled dot-product attention divide the query-key dot product \(\mathbf{Q}\mathbf{K}^T\) by \(\sqrt{d_{\text{head}}}\) prior to applying the softmax normalization function?
- To convert the matrix multiplication into a sparse graph lookup that reduces compute complexity from \(\mathcal{O}(S^2)\) to \(\mathcal{O}(S)\).
- Scaling limits the magnitude of attention scores as \(d_{\text{head}}\) grows, helping keep softmax from saturating too sharply; it does not remove quadratic score computation or guarantee universal overflow protection.
- To force the sum of all elements in the unnormalized query-key matrix to equal exactly 1.0 before applying softmax.
- To eliminate the need for Key weight matrices by making Query and Value representations mathematically identical.
Answer: The correct answer is B. In this section, the taught point is that larger head dimensions can make raw dot products grow in magnitude, which would push softmax toward saturation and make learning harder. Dividing by \(\sqrt{d_{\text{head}}}\) reins in those score magnitudes before normalization. An answer about changing \(\mathcal{O}(S^2)\) complexity confuses numerical scaling with algorithmic structure, and scaling also does not make keys unnecessary.
Learning Objective: Explain why scaling attention scores by \(\sqrt{d_{\text{head}}}\) helps control score magnitude and softmax saturation in scaled dot-product attention.
Consider a single transformer self-attention layer processing a sequence of length \(S = 4{,}096\) with \(N_{\text{heads}} = 12\) attention heads in FP16 precision (2 bytes per score). Calculate the memory required to store the materialized attention score matrices \((\mathbf{Q}\mathbf{K}^T)\) for this single layer, and explain why doubling the context length to \(S = 8{,}192\) creates a super-linear memory wall.
Answer: For \(S = 4{,}096\) and 12 heads, the number of score elements in one layer is \(S \times S \times N_{\text{heads}} = 4{,}096 \times 4{,}096 \times 12 = 201{,}326{,}592\text{ elements}\). At 2 bytes per element (FP16), this consumes \(201{,}326{,}592 \times 2 = 402{,}653{,}184\text{ bytes} \approx 402.7\text{ MB}\) per layer (or ~33.6 MB per head). Because dense score interactions scale quadratically as \(\mathcal{O}(S^2)\), doubling the context length from 4,096 to 8,192 increases the score elements by a factor of \((8{,}192/4{,}096)^2 = 4\times\), requiring \(\approx 1.61\text{ GB}\) per layer. Across 32 retained layers during training, materialized score storage explodes from ~12.9 GB to ~51.5 GB, quickly exceeding available accelerator SRAM/HBM capacity.
Learning Objective: Calculate the memory footprint of materialized attention score matrices and analyze quadratic context scaling.
True or False: IO-aware algorithms like FlashAttention reduce the computational complexity of dense self-attention from \(\mathcal{O}(S^2)\) down to \(\mathcal{O}(S)\) floating-point operations.
Answer: False. FlashAttention keeps dense self-attention’s quadratic arithmetic because it still computes the full set of exact score interactions. Its gain is avoiding full score-matrix storage in HBM by tiling the computation and applying online softmax, so the memory-traffic benefit depends on the kernel and memory hierarchy rather than changing the dense arithmetic to linear in \(S\).
Learning Objective: Compare exact tiled attention with naive attention by separating dense arithmetic cost from score-storage and memory-traffic cost.
In the scaled dot-product attention mechanism, the input sequence is projected into three distinct learned representations known as Queries, Keys, and ____, drawing a direct analogy to content-addressable retrieval systems.
Answer: Values (or values). Attention projects inputs into Queries, Keys, and Values, where Queries match Keys to compute weights that aggregate Values.
Learning Objective: Explain the three core projection components (Q, K, V) of the attention mechanism and describe their roles in content-based routing.
In an attention layer with sequence length \(S = 512\) and per-head feature dimension \(d_k = 64\), how many multiply-accumulate (MAC) operations are required to compute the query-key attention scores \((\mathbf{Q}\mathbf{K}^T)\) for a single attention head, excluding softmax normalization and value aggregation?
- 32,768 MACs, calculated as \(512 \times 64\).
- 262,144 MACs, calculated as \(512 \times 512\).
- 1,048,576 MACs, calculated as \(512 \times 512 \times 4\).
- 16,777,216 MACs (~16.8 million MACs), calculated as \(S \times S \times d_k = 512 \times 512 \times 64\).
Answer: The correct answer is D. Computing the score matrix \(\mathbf{Q}\mathbf{K}^T\) for a single head involves multiplying an \(S \times d_k\) matrix by a \(d_k \times S\) matrix. This produces an \(S \times S\) output matrix where each of the \(512 \times 512 = 262{,}144\) entries requires a \(d_k = 64\) dimensional dot product. The total arithmetic cost is \(512 \times 512 \times 64 = 16{,}777{,}216\text{ MACs}\) (approx. 16.8M MACs). The choice of 32,768 MACs computes only a single vector-matrix projection. The choice of 262,144 MACs counts output matrix elements without multiplying by feature depth \(d_k\).
Learning Objective: Calculate the exact multiply-accumulate operation count required for pairwise query-key score computation in an attention head.
Self-Check: Answer
Why does position-free unmasked self-attention require explicit positional information supplied by mechanisms such as sinusoidal signals, learned positional embeddings, or related position-encoding schemes?
- Because matrix multiplication hardware cannot process tensors without fixed static padding across all dimensions.
- Because layer normalization removes the mean and variance of token vectors, destroying word identity.
- Because without positional information, unmasked self-attention is permutation equivariant: permuting the input rows permutes the output rows in the same way, so the layer by itself does not encode order.
- Because positional encodings reduce the computational complexity of the attention matrix from \(\mathcal{O}(S^2)\) to \(\mathcal{O}(S)\).
Answer: The correct answer is C. The section states that unmasked self-attention treats the sequence as an unordered set unless position information is injected: if the rows of \(\mathbf{X}\) are permuted, the output rows are permuted the same way. That is permutation equivariance, not invariance, and it is why positional information from embeddings, sinusoidal signals, or related mechanisms is needed to represent order. The hardware-padding and complexity answers are unrelated to the mathematical issue.
Learning Objective: Explain why unmasked self-attention is permutation equivariant and justify the role of positional information in sequence modeling.
Under a weight-only memory model in FP16 precision, an autoregressive language model generates 1 token per forward pass at batch size 1, performing approximately 2 FLOPs per parameter while streaming the entire weight matrix from High Bandwidth Memory (HBM). Calculate the theoretical arithmetic intensity of this decoding step and explain why it causes accelerator matrix units (Tensor Cores) to remain severely underutilized.
Answer: In FP16 precision, each parameter occupies 2 bytes, so 2 FLOPs per streamed parameter gives an arithmetic intensity of \(1.0\text{ FLOP/byte}\). For a hypothetical accelerator with matching FP16 compute throughput of 312 TFLOP/s and HBM bandwidth of 2.0 TB/s, the ridge point is approximately \(156\text{ FLOP/byte}\). The streamed-weight model therefore has a bandwidth roofline of 2.0 TFLOP/s, far below the compute ceiling. This bound explains why compute throughput can remain low; it does not measure Tensor Core idle time or prove that a particular implementation saturates HBM. Realized traffic, cache reuse, launch overhead, and available parallelism require profiling.
Learning Objective: Calculate the arithmetic intensity of batch-1 autoregressive decoding and evaluate why memory bandwidth bottlenecks single-token generation.
**Order the sub-layer operations executed within a single standard Transformer encoder block during a forward pass:
- Project input activations into Query, Key, and Value tensors via linear weight matrices
- Compute multi-head scaled dot-product self-attention across all sequence positions
- Apply residual skip connection addition and layer normalization to the attention output
- Pass normalized representations through a position-wise two-layer feed-forward network (MLP)
- Apply residual skip connection addition and layer normalization to the feed-forward output**
Answer: The correct order is (1) -> (2) -> (3) -> (4) -> (5). Step 1 is (1) Linear Q, K, V projections. Step 2 is (2) Multi-head scaled dot-product attention. Step 3 is (3) First residual addition and layer normalization. Step 4 is (4) Position-wise feed-forward MLP. Step 5 is (5) Second residual addition and layer normalization.
Learning Objective: Explain the architectural layout and sub-layer execution order of a standard Transformer encoder block.
A production serving system deploys a 32-layer transformer with 32 attention heads, head dimension \(d_{\text{head}} = 128\), and context length \(S = 2{,}048\) in FP16 precision (2 bytes per value). Calculate the memory footprint of the Key-Value (KV) cache for a single user request, and explain why KV-cache memory can surpass model weight memory under high concurrent batching.
Answer: For a single request, the KV cache stores key and value tensors across all layers: \(\text{Memory} = N_L \times 2 \times N_{\text{heads}} \times S \times d_{\text{head}} \times \text{bytes} = 32 \times 2 \times 32 \times 2{,}048 \times 128 \times 2\text{ bytes} = 1{,}073{,}741{,}824\text{ bytes} = 1.07\text{ GB}\) (exactly 1.0 GiB). While a 7B parameter FP16 model weight footprint is fixed at ~14 GB, serving 32 concurrent user requests requires \(32 \times 1.07\text{ GB} \approx 34.3\text{ GB}\) of dynamic KV cache, more than double the static weight memory. This linear growth with concurrency and context length makes the KV cache the dominant serving memory bottleneck.
Learning Objective: Calculate the per-request Key-Value (KV) cache memory footprint and analyze how concurrency shifts serving memory bottlenecks from weights to activation state.
True or False: During autoregressive language model inference, single-token generation at batch size 1 achieves near-peak GPU floating-point throughput (TFLOP/s) because the matrix-vector multiplication is highly optimized.
Answer: False. The chapter’s streamed-weight batch-1 decode model has low arithmetic intensity, so optimization alone does not guarantee near-peak compute throughput. Whether decode is bandwidth bound depends on the machine balance and realized traffic, and prefill or larger batches can reuse weights more effectively than single-token batch-1 generation.
Learning Objective: Evaluate why highly optimized batch-1 autoregressive decoding can still fall far below peak compute throughput under a low-intensity streamed-weight regime.
In a Multi-Head Attention layer with model dimension \(d_{\text{model}} = 768\) and \(N_{\text{heads}} = 12\) heads, what is the per-head dimension \(d_k\), and how does multi-head projection affect total computational FLOP complexity compared to a single attention head operating on the full 768 dimensions?
- The per-head dimension is \(d_k = 768\), increasing total projection FLOPs by \(12\times\) compared to a single head.
- The per-head dimension is \(d_k = 768 / 12 = 64\); running 12 heads of dimension 64 has the exact same total projection and score FLOP complexity as a single head of dimension 768, while enabling the model to jointly attend to information from 12 distinct representation subspaces.
- The per-head dimension is \(d_k = 12\), reducing total computational complexity by \(64\times\).
- Multi-head attention eliminates the output projection matrix \(\mathbf{W}^O\), halving layer parameter count.
Answer: The correct answer is B. Multi-head attention partitions the model dimension across heads such that \(d_k = d_{\text{model}} / N_{\text{heads}} = 768 / 12 = 64\). For \(N_{\text{heads}}\) heads, the \(S \times S\) score calculation requires \(N_{\text{heads}} \times (S \times S \times d_k) = S^2 \times (N_{\text{heads}} \cdot d_k) = S^2 \cdot d_{\text{model}}\) MACs, which is mathematically identical to the arithmetic cost of a single full-width attention head while providing the representational capacity of diverse attention subspaces. The claim that \(d_k = 768\) misstates the per-head dimension. The claim of \(d_k = 12\) inverts the head count and head dimension. The claim that multi-head attention eliminates the output projection matrix is false because \(\mathbf{W}^O\) is required to mix the concatenated head outputs.
Learning Objective: Analyze the dimension partitioning mechanics of multi-head attention and explain why multi-head projection preserves total computational complexity.
Self-Check: Answer
In the Deep Learning Recommendation Model (DLRM) architecture, what is the primary computational role of the Interaction Layer?
- It applies 2D convolutions over user and item IDs to extract hierarchical spatial features.
- It normalizes categorical IDs across the batch using running mean and variance statistics.
- It performs autoregressive token decoding to predict the next search query.
- It computes pairwise dot products between the dense feature representations from the Bottom MLP and the sparse embedding vectors gathered from categorical tables to capture explicit feature interactions.
Answer: The correct answer is D. In DLRM, continuous numerical features are processed through a dense Bottom MLP, while categorical features are looked up in sparse embedding tables. The Interaction Layer takes these resulting dense vectors and computes all-to-all pairwise dot products, explicitly capturing interactions between numerical context and categorical embeddings before passing the concatenated results to the Top MLP. Convolutions are vision operators that do not apply to unstructured IDs. Batch normalization does not compute cross-feature dot product interactions. Autoregressive token decoding is a language model mechanism.
Learning Objective: Explain the architectural function and computational role of the Interaction Layer in DLRM recommendation models.
Explain why a large-table recommendation scenario becomes memory-capacity-bound rather than compute-bound when the model’s combined embedding tables exceed the fast memory of a single accelerator, and why the standard execution form of the Iron Law of ML Systems (\(T_{\text{exec}} = D_{\text{vol}}/\text{BW} + O/(R_{\text{peak}} \cdot \eta_{\text{hw}}) + L_{\text{lat}}\)) cannot directly determine whether that model can be deployed on one accelerator.
Answer: DLRM becomes capacity bound when its combined embedding tables exceed the fast memory of one device, so the first question is not how quickly arithmetic runs but whether the model state can reside locally at all. In that regime, compression, offloading to host or remote memory, or partitioning across devices become the architectural options before runtime optimization of the dense MLPs matters. The practical consequence is that the iron-law execution terms only apply cleanly after placement is feasible, because capacity decides where the tables live and therefore which bandwidth the data term must pay.
Learning Objective: Analyze why recommendation workloads can hit a capacity wall before arithmetic throughput matters, and identify the architectural responses that follow.
**Order the four primary computational stages executed during an end-to-end inference pass in a DLRM recommendation model:
- Process continuous numerical features through the dense Bottom MLP to produce a dense representation
- Look up sparse categorical IDs across embedding tables to gather discrete embedding vectors
- Compute pairwise dot products (interactions) between the Bottom MLP output and all gathered embedding vectors
- Concatenate interaction dot products with Bottom MLP features and pass through the Top MLP to predict click-through probability**
Answer: The correct order is (1) and (2) in parallel -> (3) -> (4) (or (1) -> (2) -> (3) -> (4)). Step 1 and 2 are (1) Continuous features through Bottom MLP and (2) Categorical ID embedding table lookups. Step 3 is (3) Pairwise dot product feature interactions. Step 4 is (4) Top MLP classification for click-through rate prediction.
Learning Objective: Analyze and sequence the four main pipeline stages of DLRM inference dataflow.
An e-commerce recommendation system maintains an item embedding table with 100 million items (\(10^8\)) and a user embedding table with 1 billion users (\(10^9\)), each using 128-dimensional FP32 vectors (4 bytes per parameter). Calculate the memory footprint of each table, verify why they cannot fit on a single 80 GB A100 GPU, and describe two systems strategies to handle this capacity wall.
Answer: The item table requires \(10^8 \times 128 \times 4\text{ bytes} = 51.2\text{ GB}\). The user table requires \(10^9 \times 128 \times 4\text{ bytes} = 512.0\text{ GB}\). Combined, they require \(563.2\text{ GB}\), which exceeds the 80 GB capacity of an A100 by \(>7\times\) (even the item table alone consumes ~64% of an 80 GB GPU). Two systems strategies to resolve this capacity wall: (1) Model-parallel table sharding, where embedding tables are partitioned across the memory of multiple GPUs or cluster nodes; (2) Hierarchical memory offloading, where frequently accessed embeddings are cached in GPU HBM while the vast majority of cold embeddings reside in host CPU DRAM or NVMe storage.
Learning Objective: Calculate embedding table capacity requirements and formulate systems strategies (sharding, offloading) to bypass the memory capacity wall.
Why do sparse embedding table lookups in recommendation workloads resist standard hardware caching and memory prefetching mechanisms that accelerate CNNs and MLPs?
- Because each incoming request queries arbitrary, non-contiguous row indices determined by sparse user and item IDs, producing irregular gathers with weak spatial locality, although popularity skew can still create temporal reuse for hot rows.
- Because embedding tables are permanently encrypted in DRAM, preventing hardware prefetchers from reading address buses.
- Because embedding lookups require performing high-order tensor contractions that stall CPU prefetch queues.
- Because recommendation systems execute only on storage-class memory where hardware caching is disabled by operating system kernels.
Answer: The correct answer is A. The chapter contrasts sparse recommendation lookups with the regular contiguous or strided access of dense layers and convolutions: IDs select arbitrary rows, so spatial locality and prefetching help much less. But caches are not universally defeated, because popular users or items recur and create temporal locality for hot rows. The answers about encryption, tensor contractions, or disabled caching invent mechanisms the section does not describe.
Learning Objective: Explain why sparse embedding lookups weaken spatial locality and prefetching, while popularity skew can still create useful cache reuse for hot rows.
Self-Check: Answer
The workload profile gives the transformer two rows, prefill and decode, even though both run the same weights. Under the table’s representative reuse and streaming assumptions, which statement correctly explains why the binding iron-law term can differ between them at small batch size?
- Prefill binds on the data term because it must read the whole prompt from storage, while decode binds on the compute term because each token requires a full forward pass.
- Prefill processes all \(S\) prompt tokens together, which can raise effective reuse and arithmetic intensity enough for the compute term to bind under the stated assumptions; decode processes one token at a time with reread weights and a growing KV cache, so the data term often binds at small batch.
- Both phases bind on memory capacity, because the KV cache always exceeds device memory.
- Decode is compute bound because its \(\mathcal{O}(S^2)\) attention scores dominate, while prefill is latency bound because tokens are processed serially.
Answer: The correct answer is B. The table is explicit that these are representative regimes under stated assumptions, not universal bottlenecks. In prefill, processing many prompt tokens together can reuse weights across the sequence and raise effective intensity enough for the compute term to matter; in small-batch decode, one-token-at-a-time execution rereads weights and accesses the KV cache with much lower reuse, so the data term is often the limiter. The capacity answer overstates a special case, and the serial-latency answer confuses decode with recurrent processing.
Learning Objective: Use the workload-profile assumptions to predict why transformer prefill and decode can land on different sides of the iron law.
The chapter notes that the intensity column of the workload profile doubles as an energy column. Which statement correctly explains why a batch-one MLP or transformer decode step spends far more energy per useful operation than a convolutional layer, even on the same accelerator?
- The MLP and decode step perform more multiply-accumulates per weight than a convolution, so their arithmetic energy is higher.
- The CNN’s spatial locality lets it skip most of its multiply-accumulates, so it performs less arithmetic overall.
- All three load weights from DRAM once per batch, so their energy per operation is the same; only latency differs.
- The MLP and decode step load each weight from DRAM and use it about once per request, so DRAM traffic dominates their energy, while a convolution reuses each filter load across every position of its feature map and amortizes that movement.
Answer: The correct answer is D. Moving a 32-bit value from DRAM costs far more energy than one multiply-accumulate, so what decides a family’s energy is how many operations each loaded weight feeds. A batch-one dense layer or decode step streams every weight once per request and spends most of its energy moving it; a convolution amortizes each filter load over the whole feature map, so the locality that makes it compute bound also makes it energy efficient. The first two choices misplace the cost in arithmetic, and the third ignores the difference in reuse.
Learning Objective: Explain how weight reuse determines whether data movement dominates an architecture family’s energy per inference.
In the systematic Architecture Selection Decision Framework, if a candidate model fails the inference speed or memory budget constraint check on the target device, the engineer must immediately abandon on-device edge execution and route all inference to a cloud data center.
Answer: False. The Architecture Selection Decision Framework provides an iterative ‘Scale Down’ loop: when a model breaches memory or latency constraints, the team should first apply model compression (such as INT8 quantization, pruning, or structural width multipliers) or evaluate a more efficient architectural variant (such as MobileNet instead of ResNet) before abandoning local edge deployment.
Learning Objective: Explain the iterative scale-down loop in the Architecture Selection Decision Framework when models breach memory or latency ceilings.
In the wildlife monitoring edge deployment case study (50 species classification on a 2 W battery-powered Cortex-A53 device with 512 MB RAM and a <500 ms latency target), explain why MobileNetV2 (0.75 width multiplier with INT8 quantization) was selected as the candidate to validate over ResNet-50 and KWS DS-CNN.
Answer: MobileNetV2 was selected as the candidate because its compact weight footprint and lower operation count make it plausible for the device budget. ResNet-50’s FP32 model weights alone exceed the chapter’s 100 MB model allocation within the 512 MB total system budget before accounting for activations, runtime overhead, and the rest of the application, while its heavier compute load separately pressures latency and energy. The DS-CNN keyword-spotting model is not rejected because a 200K-parameter model can never classify 50 species, but because its published workload is an audio task, so its reported accuracy and latency do not validate this visual deployment. The practical consequence is that the chapter treats MobileNetV2’s roughly 209 ms estimate on the assumed throughput as a screening calculation, then requires target-device measurement of end-to-end latency, peak memory, thermal behavior, seasonal battery qualification, full-system energy, and representative task accuracy before deployment.
Learning Objective: Apply the chapter’s deployment-screening framework to justify why MobileNetV2 is a candidate for validation in the wildlife edge scenario.
A dense MLP layer running batch-1 FP32 inference reports an arithmetic intensity of \(\approx 0.5\text{ FLOP/byte}\), while an image convolution bottleneck layer achieves \(>50\text{ FLOP/byte}\) on the same accelerator. Using the roofline model and an accelerator ridge point of \(150\text{ FLOP/byte}\), explain what follows from these numbers and what additional convolution measurement is needed before calling the convolution compute bound. Also explain why upgrading to an accelerator with double the peak TFLOP/s but unchanged memory bandwidth will not speed up the batch-1 MLP.
Answer: The batch-1 MLP is clearly below the \(150\text{ FLOP/byte}\) ridge point, so under this streamed-weight model it is in the bandwidth-bound regime. The convolution’s \(>50\text{ FLOP/byte}\) is higher, but it still does not by itself prove a compute-bound regime because values above 50 can still lie below the \(150\text{ FLOP/byte}\) ridge; the next measurement is the convolution’s effective realized intensity, including the traffic pattern for that kernel on this machine, and then comparing it directly with the ridge point. The practical consequence is that doubling peak TFLOP/s without raising memory bandwidth will not help the batch-1 MLP, because its limit is bytes delivered per second, not arithmetic ceiling.
Learning Objective: Analyze what arithmetic-intensity values do and do not imply under a roofline model, and identify the additional measurement needed before classifying a convolution as compute bound.
A production profiler reveals that a model’s embedding tables consume over 1 TB of memory across cluster nodes, inference requests perform sparse random row lookups rather than dense matrix multiplies, and accelerator compute units remain over 95% idle. Which lighthouse archetype best represents this workload’s dominant system constraint?
- DLRM, because the binding constraint is memory capacity for terabyte-scale embedding tables accessed via sparse, irregular memory gathers.
- ResNet-50, because it stresses dense matrix floating-point throughput across regular convolutional grids.
- GPT-2, because autoregressive decoding is the canonical memory-bandwidth-limited serving workload.
- MobileNetV2, because depthwise-separable convolutions produce low arithmetic intensity on server GPUs.
Answer: The correct answer is A. A terabyte-scale parameter footprint dominated by sparse, random embedding table lookups with largely idle compute units is the hallmark signature of DLRM (Deep Learning Recommendation Model). DLRM models are memory-capacity-bound and memory-latency-bound, requiring model-parallel table sharding across cluster memory. The ResNet-50 archetype represents compute-bound dense convolutions with high arithmetic intensity. The GPT-2 archetype represents bandwidth-bound autoregressive decoding dominated by streaming weights per token. The MobileNetV2 archetype represents latency-constrained mobile vision with depthwise separable convolutions.
Learning Objective: Classify a production workload by matching its profile signature (table size, access pattern, compute utilization) to the correct lighthouse archetype.
Self-Check: Answer
Why is estimating LLM transformer serving memory based solely on static model parameter footprint (e.g., 14 GB for a 7B FP16 model) a critical engineering pitfall in production deployments?
- Because model weights expand by \(10\times\) in memory due to framework compilation graph overhead.
- Because inference requires storing three full optimizer states (momentum and variance buffers) in GPU RAM.
- Because transformers delete their weights after processing each token and must reload them from disk.
- Because autoregressive decoding dynamically accumulates a Key-Value (KV) cache that scales linearly with context length and concurrency (\(\mathcal{O}(B \times S)\)), which at high concurrency or long context windows can rival or exceed the static weight memory.
Answer: The correct answer is D. Serving large language models requires memory for both static model weights and dynamic activation state. During autoregressive decoding, the system stores key and value vectors for all prior tokens in the KV cache (\(B \times N_L \times 2 \times N_{\text{heads}} \times S \times d_{\text{head}} \times \text{bytes}\)). For a 7B model (14 GB weights), 32 concurrent users at 2,048 tokens require ~34.3 GB of KV cache alone, more than double the model weight footprint. The claim of 10x graph expansion is incorrect. Optimizer states are stored during training, not inference. Model weights remain resident in GPU memory during serving and are not reloaded from disk per token.
Learning Objective: Analyze the pitfall of budgeting transformer serving memory from weights alone and analyze KV cache scaling with concurrency and context length.
Explain the fallacy: ‘An architecture has one dominant bottleneck across training and inference.’ Use the Transformer architecture to illustrate how execution regime (full-sequence training/prefill vs. batch-1 autoregressive decoding) shifts the primary hardware bottleneck.
Answer: The fallacy is treating a bottleneck as a fixed property of the architecture rather than a property of the architecture running in a specific regime. In a transformer’s training or prefill path, many sequence positions are processed together, which can create large matrix-matrix operations and much higher effective reuse; in small-batch autoregressive decoding, the same weights are reused poorly because generation proceeds one token at a time and repeatedly streams weights and KV-cache state. The practical consequence is that exact tiling, batching, cache behavior, and machine balance can shift whether compute or bandwidth binds, so each regime must be measured separately.
Learning Objective: Analyze how changing execution regime can move the same transformer architecture between compute-leaning and bandwidth-leaning operating points.
True or False: Because a hybrid neural network architecture combining convolutional layers with self-attention achieves higher top-1 accuracy on a benchmark leaderboard, it is guaranteed to maintain the high throughput and low memory traffic of the pure CNN baseline.
Answer: False. The chapter’s warning is that hybrid accuracy does not predict hybrid system behavior. Dense attention operates on regular contiguous tensors and does not inherently destroy CNN locality, but adding it can still increase score computation, intermediate traffic, and runtime cost. Throughput and memory efficiency therefore have to be profiled for the combined design rather than inferred from the CNN baseline.
Learning Objective: Evaluate why improved benchmark accuracy in a CNN-attention hybrid does not guarantee preserved throughput or memory efficiency.
A vision model trained on a cluster of \(8 \times \text{A100}\) GPUs (640 GB total memory) achieves state-of-the-art accuracy. Why is assuming this model will deploy successfully to an edge device such as an NVIDIA Jetson Orin NX (16 GB memory) a dangerous fallacy, even if the model weights require only 8 GB?
- Because total runtime memory during inference includes intermediate activation tensors, workspace scratchpads, and operating system buffers; under high batch sizes or high input resolutions, these activation and workspace buffers easily exceed the remaining 8 GB memory ceiling.
- Because edge devices are mathematically incapable of executing the floating-point multiplication instructions used by server GPUs.
- Because models trained on 8 GPUs permanently hardcode an 8-way tensor parallel communication protocol that fails if fewer than 8 physical GPUs are connected.
- Because PyTorch and TensorFlow models can only run on cloud-hosted Linux kernels and cannot execute on embedded SoCs.
Answer: The correct answer is A. Model weight storage is only one component of runtime memory. During inference, the system must also allocate memory for intermediate activation feature maps, framework execution workspaces, CUDA runtime context, and operating system buffers. An 8 GB model on a 16 GB edge device leaves only 8 GB of shared system RAM; high-resolution inputs or concurrent streams can cause activation memory to breach this budget, triggering out-of-memory crashes. The assertions regarding floating-point incompatibility, permanent 8-way GPU communication hardcoding, and cloud-only execution are factually false.
Learning Objective: Analyze the fallacy that training cluster success transfers to edge hardware and evaluate total runtime memory components.