14 ML Operations
Purpose
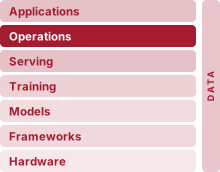
Architecture stack focus for this chapter.
Why can an ML system be perfectly available and perfectly wrong at the same time?
Conventional monitoring often detects crashes, latency regressions, and availability failures quickly, but semantic errors can remain silent in any software system. ML systems add another silent failure mode. A model experiencing data drift can continue serving ordinary-looking predictions while accuracy degrades, triggering no alerts because every health check (latency, throughput, uptime) remains green. A fraud model can keep answering in milliseconds for months after the patterns it learned have moved elsewhere, and the first alarm may be the losses themselves. Model quality can degrade because the world changes. Customer behavior shifts, new product categories appear, seasonal patterns evolve, and the distribution the model learned from diverges from the one it now faces. Drift is not a certainty but a persistent risk for deployed models. Unlike latency or uptime, correctness may become observable only after labels or downstream outcomes arrive, so detecting degradation often requires imperfect signals and explicit investigation rather than a single threshold. Managing it requires continuous monitoring that tracks prediction quality alongside system health, drift signals that trigger investigation, retraining when outcome evidence supports it, and deployment strategies that validate new model versions against production traffic before full rollout. The gap between development and production is not a hurdle cleared once but a condition managed indefinitely, for as long as the model makes decisions that someone relies on. Machine learning operations exists because uptime without measured accuracy may still deliver wrong answers at scale. In D·A·M terms, operations makes co-design continuous, because the data environment can remain a moving target long after initial deployment.
Learning Objectives
- Explain why ML systems can remain available while prediction quality silently degrades under distribution shift
- Diagnose technical debt across data-model, model-infrastructure, and production-monitoring interface boundaries
- Design model registries, parity tests, and CI/CD pipelines that preserve training-serving consistency and reproducible rollback
- Compare canary, blue-green, shadow, and rollback strategies by the release risk they contain and the accelerator memory they hold
- Design the operations loop’s layered monitoring and incident response to trace drift, skew, and degradation to a data, model, or infrastructure cause
- Apply the retraining staleness model to choose cost-aware retraining triggers and intervals
- Evaluate operational maturity and investment using model criticality, operational risk, and organizational readiness
Explore the concepts in this chapter
The volume’s concept map, opened on this chapter. Select a concept to read how it connects to ideas in other chapters. Open the full map ↗
14.1 Silent Failure in Production
A serving cluster can return HTTP 200 on every request, stay well inside its tail-latency budget, and pass every infrastructure health check while the recommendations it serves lose relevance week after week. A silent failure is a production model that keeps answering every request on time, raises no error, and passes every health check while its answers grow worse. Any deployed model is exposed to it, because a model is a fit to the data it trained on and the world it serves keeps moving after training ends. Model Serving built the request path that delivers those answers, a service that meets its latency budget, holds headroom for bursts, and turns throughput into cost per inference. A benchmark establishes performance at a point in time, and serving infrastructure verifies that the required fraction of requests finishes within the latency budget. Neither check asks whether the answers are still right. Operations is the stage of the lifecycle (ML Lifecycle) that has no finish line. It keeps a model correct for as long as anyone relies on its decisions.
A team deploys a model to production, and week one looks excellent. In week two, customer behavior shifts, seasonal patterns evolve, and new item categories appear, while a model that succeeded in development often has no postdeployment owner or monitoring to notice. The root cause is an operational mismatch. Availability-focused monitoring tracks server uptime, request latency, and request success rates, whereas ML monitoring must also track statistical health, including accuracy over time, input-distribution shift, and per-segment prediction quality.
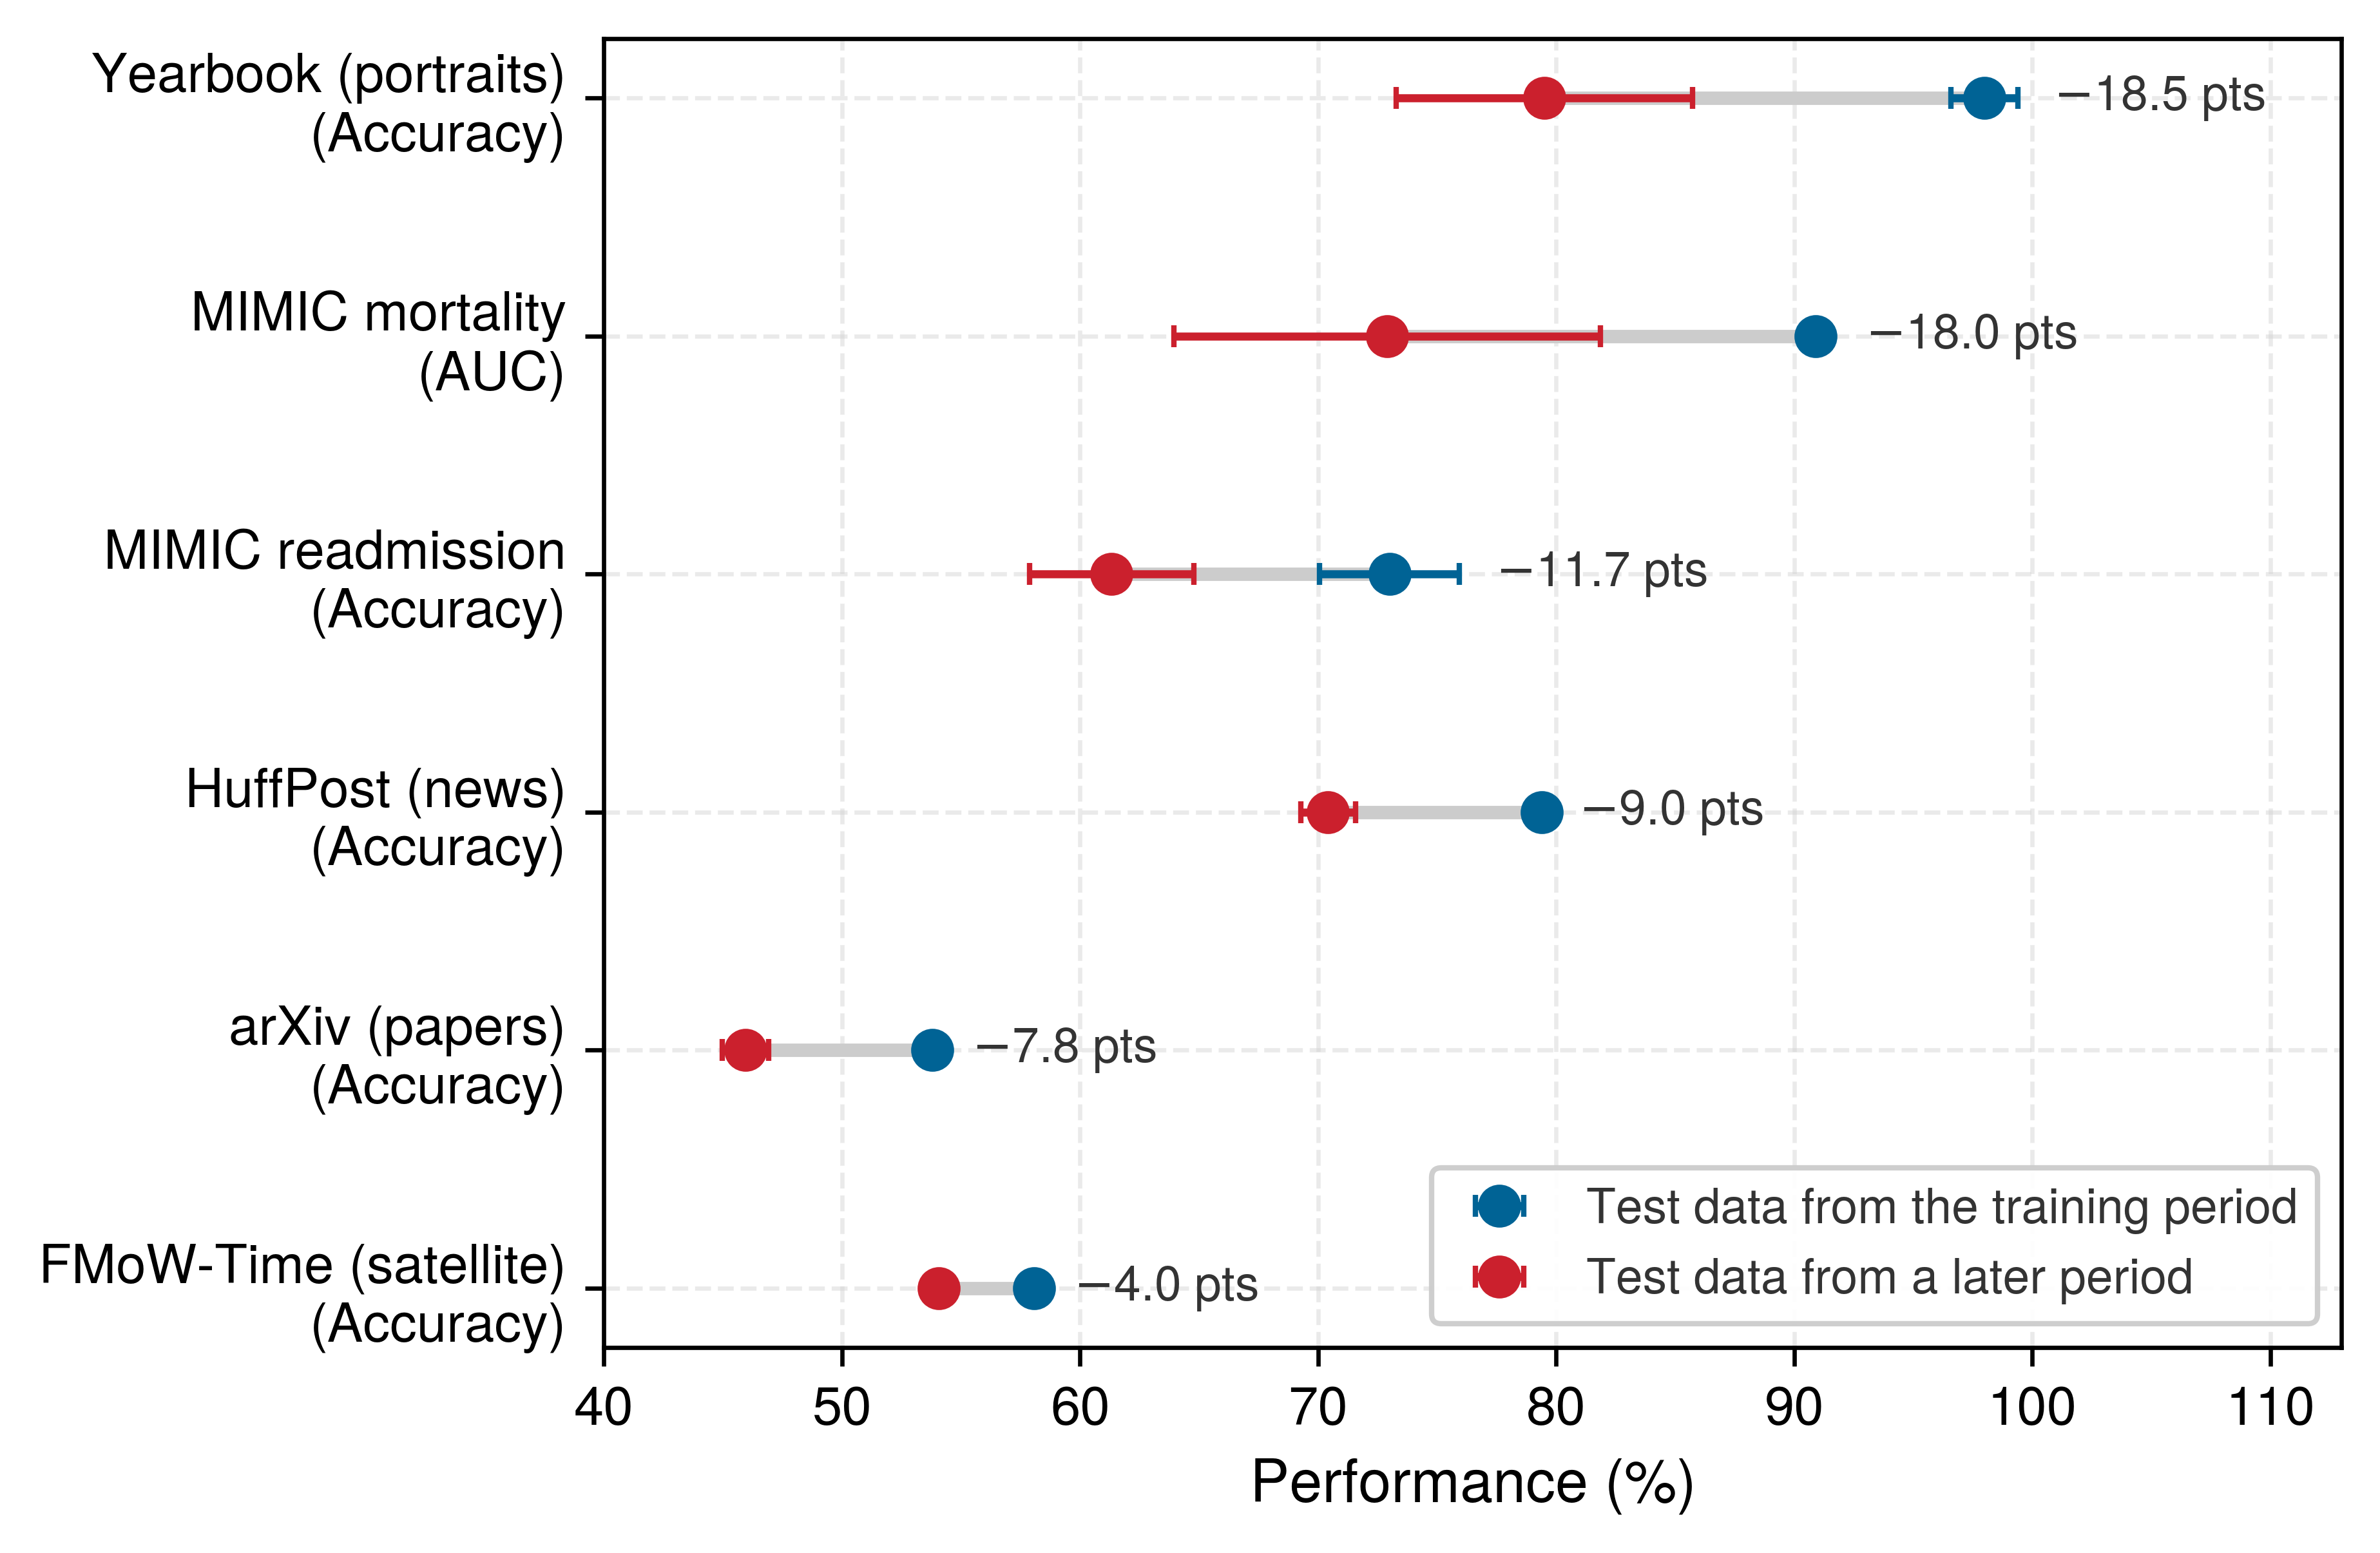
The degradation is measurable. In the Wild-Time benchmark, Yao et al. (2022) train a model on data from one period and test it both on held-out data from that period and on data from later years, across six real datasets that span yearbook portraits, satellite imagery, hospital records, news, and scientific papers. Figure 1 shows the result. On every dataset the same model scores lower on the later data, by 4 to 18.5 points of accuracy or of area under the curve (AUC), although nothing about the model or its serving path changed. The loss comes entirely from the world moving away from the training data, and only monitoring that compares predictions against fresh outcomes can see it.
Yao, Huaxiu, Caroline Choi, Bochuan Cao, Yoonho Lee, Pang Wei Koh, and Chelsea Finn. 2022. “Wild-Time: A Benchmark of in-the-Wild Distribution Shift over Time.” arXiv Preprint arXiv:2211.14238.
The discipline that makes these invisible failures visible is machine learning operations (MLOps). It inherits the automation and operations lineage of DevOps (Kreuzberger et al. 2023), but addresses a different failure mode. Conventional services can often be tested against deterministic code paths, while ML systems depend on training data distributions, learned parameters, and environmental conditions that shift continuously. Data distributions, learned parameters, slice-level evaluations, and runtime feedback loops therefore all function as release artifacts that govern production behavior, and a release extends far beyond an executable binary or code diff. Because these artifacts pass between traditionally isolated domains (data science, machine learning engineering, and systems operations (Amershi et al. 2019)), MLOps also formalizes the interfaces and responsibilities among them through continuous retraining, A/B evaluation, graduated rollout, and standardized artifact tracking that supports reproducibility and auditability.
Amershi, Saleema, Andrew Begel, Christian Bird, Robert DeLine, Harald Gall, Ece Kamar, Nachiappan Nagappan, Besmira Nushi, and Thomas Zimmermann. 2019. “Software Engineering for Machine Learning: A Case Study.” 2019 IEEE/ACM 41st International Conference on Software Engineering: Software Engineering in Practice (ICSE-SEIP), 291–300. https://doi.org/10.1109/icse-seip.2019.00042.
If benchmarking provides the sensors for the system, MLOps is the complete control system, and the degradation equation (equation 1.1) names the quantity it controls. Accuracy falls by a fitted sensitivity \(\FittedSensitivity\) times the divergence between the serving and training distributions. Data drift is the movement of live inputs away from the training data, and that divergence measures how far they have moved. Operations must therefore measure that divergence continuously and estimate \(\FittedSensitivity\) from paired drift and outcome data, because divergence alone does not prove that accuracy will fall.
↩︎ Data drift and the statistics that measure it are established in Data drift detection and response.
Definition 14.1: MLOps
Machine learning operations (MLOps) is the engineering practice of productionizing ML systems through CI/CD, workflow orchestration, reproducibility, versioning, collaboration, continuous training and evaluation, monitoring, and feedback loops (Kreuzberger et al. 2023).
- Significance: Leaving the loop open shows up as stale predictions, silent accuracy degradation, and prolonged recovery times. Drift thresholds, retraining triggers, and mean time to recovery (MTTR) targets are deployment-specific, calibrated from prediction value, label delay, validation risk, and retraining compute expense. A retraining run is justified only when the expected accuracy gain outweighs its execution cost and rollout risk.
- Distinction: DevOps monitors functional correctness, throughput, and availability. MLOps adds statistical controls for predictive correctness, which can decay while uptime, latency, and HTTP status codes stay healthy.
- Common pitfall: A frequent misconception is that retraining on new data automatically resolves distribution shift. Retraining without diagnosing what shifted (the inputs the model receives, the relationship between those inputs and the correct answers, or both) preserves the underlying failure or amplifies collection bias. Reweighting the training data can correct a change in input mix, but only new outcome evidence shows whether a changed input-output relationship requires adaptation; section 14.5.2 separates the two cases formally.
Kreuzberger, Dominik, Niklas Kühl, and Sebastian Hirschl. 2023. “Machine Learning Operations (MLOps): Overview, Definition, and Architecture.” IEEE Access 11: 31866–79. https://doi.org/10.1109/access.2023.3262138.
The MLOps loop has three stages (design, model development, and operations), but its defining feature is the return path. Runtime telemetry and retraining triggers carry live performance signals from operations back into requirements and data engineering, so deployment feeds the next design cycle instead of ending the project (figure 2).
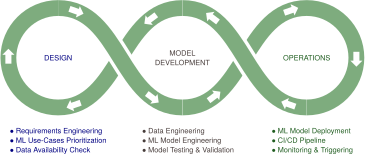
The MLOps loop spans a model’s whole life, from requirements through redesign. Inside its operations stage, a second and much faster cycle of five steps runs on every production model for as long as it serves traffic. This cycle is the operations loop. It detects a change in inputs, outputs, or outcomes; diagnoses which layer of the system caused it; decides whether retraining, rollback, or waiting is worth its cost; releases a replacement under controlled exposure; and recovers to a known-good version when a release misbehaves. Each step is a control that a team must build and pay for, and each consumes a concrete machine resource: telemetry bytes for detection, logged requests for diagnosis, accelerator-hours for a retraining run, and a second resident copy of the model for a safe release. The decide step spends those accelerator-hours when it approves a run, and the recover step draws on the same resident copy, because a rollback is immediate only while the previous version stays loaded.
The operations loop runs on a basic operational unit, the ML node, a complete system comprising data pipelines, feature computation, model training, serving infrastructure, and monitoring for a single machine learning application. Platform operations at larger scale (managing hundreds of models, cross-model dependencies, multi-region coordination, and organization-wide ML platform engineering) constitute advanced topics that build on these single-model foundations.
Keeping one ML node correct decomposes into three interfaces that follow the artifact from data ingestion to live traffic and back again. At the start of the pipeline, the data-model interface governs the handoff between data infrastructure and model training, where the goal is feature consistency so that training and serving pipelines compute features the same way. Once a checkpoint is trained, the model-infrastructure interface carries those weights into a scalable service. Its challenge is environment parity, because a model that works in a notebook can fail in production when versions, dependencies, or runtimes differ. Closing the loop, the production-monitoring interface returns statistical telemetry1 from live serving back to training, enabling self-correction when distribution shift degrades accuracy without crashing the service.
1 Telemetry: The feedback path that can make model degradation visible before it becomes a business failure; crashes and error codes expose some software failures, but semantic errors can remain silent in any application. ML systems add distribution shift, which can go undetected without statistical telemetry such as feature distributions, prediction confidence, and drift indicators.
These three interfaces determine how operational infrastructure partitions responsibility across the lifecycle. Feature stores stabilize feature computation at the data-model boundary, and model registries (versioned stores of trained models) and deployment pipelines preserve the model-infrastructure handoff. Drift monitors, retraining triggers, and governance policies connect production evidence back to a controlled response, which shortens the window in which degradation goes unaddressed.
To show how those three interfaces and their controls behave under different hardware constraints, two of the book’s lighthouse workloads (Lighthouse models put the iron law into practice) carry the chapter, one for each end of the deployment spectrum. The cloud half follows a ranking service built on DLRM, the recommendation model that Model Serving set against ResNet-50’s compute-bound service. DLRM’s home regime is capacity-bound. Its 100 GB of embedding tables exceed the 80 GB of one H100, so even its smallest deployment spans two accelerators before throughput enters the calculation. Every operational control that needs a second copy of the model pays for it in memory. A ranking model is also the workload whose world moves fastest. User interests and the item catalog change daily, click labels arrive within hours, and the model’s own rankings shape the clicks it later trains on.
The edge half follows the keyword spotter, whose home regime is power-bound. Its 200 KB INT8 model listens continuously on a microcontroller with 4 MB of flash, where every radio transmission and flash write draws on a small energy budget. Operational Data Health left that spotter six months after launch with a detection rate four percentage points below its target, and the edge sections of this chapter pick up the drop. The device cannot be reached by hand, its audio cannot leave it, and a failed update must not disable it.
The week-two problem takes concrete shape on the ranking service in an illustrative scenario. Initial measurements show 94 percent click-prediction accuracy, p99 latency inside the service’s budget, and strong performance across test segments. By week four, accuracy has dropped to 88 percent, but the infrastructure metrics show nothing wrong. By week eight, a product manager notices that recommended items convert poorly; investigation reveals the model has not adapted to a competitor’s new promotion that shifted what users click. The model needed investigation six weeks ago, but no system was watching for this degradation. MLOps provides the framework to detect such changes, assess whether retraining addresses them, and validate replacement models while limiting the impact on users.
The chapter builds the operations loop in the order a team needs it (table 1). Technical debt explains why ML systems accumulate the hidden coupling that makes silent failure likely. Development infrastructure builds the pipeline that can rebuild and trace any model exactly, and releasing models moves a candidate onto live traffic with a tested path back. Production monitoring then watches the deployed model for the evidence the loop runs on, and retraining decisions turn that evidence into a choice to retrain, roll back, or wait. Incident response and governance handle the failures that monitoring surfaces, operational maturity decides which control a team should add next, and two case studies carry the loop to the edge and into the clinic.
| Section | Loop step | Question it answers | Machine cost on the ranking service |
|---|---|---|---|
| Technical Debt | Why the loop exists | Where hidden coupling accumulates | Glue code and unused features that still move bytes |
| Development Infrastructure | Release (prepare) | How a model is rebuilt and traced exactly | Versioned copies of data, features, and 100 GB of tables |
| Releasing Models | Release, recover | How a candidate reaches traffic and how it is withdrawn | A second resident copy of the tables for each release control |
| Production Monitoring | Detect | Whether predictions are still right | Telemetry bytes per second and their retention |
| Retraining Decisions | Decide | Whether a new model is worth its run | Accelerator-hours that contend with serving |
| Incident Response and Governance | Diagnose, recover | Which layer failed, and who acts | Replay and slice queries over logged requests |
| Operational Maturity | All steps | Which control to add next | Operational spend matched to the model’s value |
| Case Studies | All steps | How the loop changes at the edge and in the clinic | Flash banks, radio energy, and clinician review time |
Operating this feedback path requires adding statistical controls to the release and reliability practices of DevOps. Technical debt accumulates wherever one of the three interface boundaries erodes. Feature stores, versioning, and CI/CD pipelines restore the reproducibility needed to isolate a fault at those boundaries, while monitoring, drift detection, and staged rollout protect predictive quality once inputs begin to shift. A small set of foundational principles decides which of these controls a given model needs and when each should act.
14.1.1 Five operational principles
Without clear operating rules, a team cannot tell whether an accuracy drop came from an unrecorded data change, a mismatched serving feature, or an overdue retraining run. Five operational principles prevent these blind spots by anchoring each boundary of the ML node to a measurable quantity, from a complete artifact hash for reproducibility to net retraining value for automation (table 2). The sections that follow build the controls that enforce them.
| Principle | Core Insight | Key Metric |
|---|---|---|
| Reproducibility | Version all artifacts | Complete artifact hash |
| Separation of concerns | Independent layer evolution | Layers touched per change |
| Consistency | Training equals serving | Feature skew rate |
| Observable degradation | Make failures visible | Time to detection |
| Cost-aware automation | Optimize total cost | Net retraining value |
Reproducibility
Reproducibility requires every artifact2 that influences model behavior to be versioned and traceable. This principle extends beyond code repositories to encompass input datasets, feature schemas, hyperparameter configurations, and execution environments. Equation 1 expresses this dependency formally: \[\text{Model Output} = \TrainingPipelineFunction(\text{Code}_\ArtifactVersion, \text{Data}_\ArtifactVersion, \text{Config}_\ArtifactVersion, \text{Environment}_\ArtifactVersion; \ExecutionNondeterminism) \tag{1}\] where \(\ArtifactVersion\) identifies an immutable version hash and \(\ExecutionNondeterminism\) captures execution nondeterminism. Exact reproduction requires freezing all four versioned inputs alongside random seeds, dataloader sample ordering, deterministic GPU reduction kernels, and identical accelerator hardware architectures.
2 Artifact: Model weights are realized training outputs; the inputs and randomness that produced them cannot generally be inferred from the parameters. Versioning only code is therefore insufficient, and even versioning code, data, configuration, and environment may not guarantee exact replay when kernels or training are nondeterministic.
Fixing random seeds (such as torch.manual_seed(42)) still fails to guarantee bitwise reproducibility across training runs on accelerator hardware. The root cause is finite-precision arithmetic. In exact arithmetic, addition is associative, so \((\FirstFloatingPointAddend+ \SecondFloatingPointAddend) + \ThirdFloatingPointAddend= \FirstFloatingPointAddend+ (\SecondFloatingPointAddend+ \ThirdFloatingPointAddend)\). Floating-point addition breaks associativity because each intermediate sum is rounded to fit a finite number of bits. Because concurrent atomic updates on an accelerator reach memory in an order that varies from run to run, the rounded sums differ in their least significant bits, and these differences compound over thousands of optimization steps. Two runs with identical seeds and code can therefore diverge into measurably different weights unless deterministic reduction algorithms are enabled. These algorithms fix the summation tree at the cost of parallel throughput (Reproducibility develops this trade-off between reproducibility and performance).
↩︎ The floating-point formats, their dynamic ranges, and where accumulated rounding error matters in training are established in Mixed-precision training.
Separation of concerns
Reproducing a run is tractable only when changing one part of the system does not force rebuilding the rest. Separation of concerns decomposes MLOps systems into distinct functional layers that can evolve independently. Because data schemas, training algorithms, traffic patterns, and business rules change on different schedules, isolating each layer lets a team update one without rebuilding the others, as table 3 summarizes:
| Layer | Responsibility | Stability |
|---|---|---|
| Data Layer | Feature computation, storage, serving | Changes with data schema evolution |
| Training Layer | Model development, hyperparameter optimization | Changes with algorithm research |
| Serving Layer | Inference, scaling, latency management | Changes with traffic patterns |
| Monitoring Layer | Drift detection, performance tracking | Changes with business requirements |
Consistency imperative
The architectural boundaries in table 3 allow teams to upgrade serving runtimes without retraining models, adjust alert thresholds without redeployment, and modify data ingestion pipelines while preserving interface contracts. That architectural independence remains safe only when training and serving environments process features identically, establishing training-serving parity as the consistency imperative of Training-serving consistency. A violation of that parity is training-serving skew. The training-serving skew diagnostic (principle 11) detects it without waiting for labels, by comparing what the training and serving code paths compute, from features through model scores, for the same inputs. The financial consequence of this discrepancy is captured in equation 2: \[\text{Skew Cost} = \text{Rate}_{\text{skew}} \times \DailyQueryVolume\times \ErroneousPredictionCost \tag{2}\] where \(\text{Rate}_{\text{skew}}\) is the fraction of queries with erroneous predictions caused by training-serving skew, \(\DailyQueryVolume\) is the daily query volume, and \(\ErroneousPredictionCost\) is the average business cost incurred per erroneous prediction.
For a system serving 1,000,000 queries/day with 1 percent skew-induced errors costing $0.10 each, equation 2 gives a daily loss, and over the 365 days of a year that loss reaches $365,000. The loss recurs every year until consistency mechanisms remove its cause. Shared feature stores, unified C++ or Rust feature-extraction libraries invoked identically during offline training and online serving, and automated schema validation tests support consistency at the system boundary; matched-input tests must still verify feature values and semantics.
Observable degradation
Even when training and serving compute features identically, accuracy still erodes as the live population moves away from the training set. Observable degradation requires ML systems to make silent failures visible through continuous measurement. Model accuracy degrades along a continuous statistical spectrum rather than failing as a discrete binary crash. An observed failure’s time signature (an acute drop, gradual drift, or localized cohort decay) governs both the detection mechanism and the operational response. The ranking service’s four-week slide from 94 to 88 percent was a gradual signature, the kind that trend analysis on accuracy catches and that no uptime or latency alert can see. Making degradation observable therefore means pairing each failure signature with the telemetry that can see it and the countermeasure it calls for, as table 4 outlines.
| Degradation Type | Detection Mechanism | Response Strategy |
|---|---|---|
| Sudden accuracy drop | Threshold alerts | Diagnose; roll back if release-related |
| Gradual drift | Trend analysis | Diagnose, then retrain if warranted |
| Subgroup degradation | Cohort monitoring | Targeted data collection |
| Latency increase | Percentile tracking | Infrastructure scaling |
Cost-aware automation
Once telemetry detects degradation, the fifth principle governs when executing a countermeasure is worth its price. Cost-aware automation balances computational costs against accuracy improvements. Let \(\FiniteChange\text{Accuracy}\) be the expected gain in accuracy percentage points, \(\text{Value per Point}\) the monetary value of one percentage-point gain over the decision horizon, \(\text{Training Cost}\) the compute and labor cost of a retraining run, and \(\text{Deployment Risk}\) the expected cost of validation and rollout failure. Equation 3 models this trade-off: \[\text{Retrain if: } \FiniteChange\text{Accuracy} \times \text{Value per Point} > \text{Training Cost} + \text{Deployment Risk} \tag{3}\]
The inequality acts as an operational decision criterion rather than an unconstrained trigger. An automated pipeline should initiate retraining only when empirical evidence indicates that expected accuracy gains surpass execution cost and rollout risk. This economic trade-off governs retraining triggers, validation thresholds, and rollout criteria; section 14.6 formalizes this model to calculate optimal retraining cadences. The margin by which the left side of equation 3 exceeds the right is the net retraining value, the quantity that a retraining trigger should test.
How these principles manifest in practice depends on the workload. The ranking service drifts daily as user preferences shift, while the keyword spotter may run unchanged for months between over-the-air (OTA) updates, which reach devices by radio. The monitoring strategy must match the workload’s regime and, more decisively, the labels its deployment can observe.
Lighthouse 14.1: Monitoring strategy by archetype
The dominant failure modes and monitoring priorities differ across workload archetypes. Table 5 compares four representative archetypes by drift pattern, monitoring metric, and example retraining trigger:
| Archetype | Dominant Drift Pattern | Primary Monitoring Metric | Example Retraining Trigger |
|---|---|---|---|
| Compute-bound (ResNet-50) | Visual distribution shift (lighting, camera, new object classes) | Accuracy on holdout set (ground truth available) | Accuracy drops > 2% from baseline (\(\sim\)monthly for stable domains) |
| Bandwidth-bound (GPT-2) | Vocabulary drift, topic shift, emerging entities | Perplexity on live traffic (no ground truth needed) | Perplexity increases > 10%; new vocabulary detected (\(\sim\)weekly for news domains) |
| Capacity-bound (DLRM) | User behavior shift, item catalog churn, cold-start items | CTR/CVR delta vs. historical cohorts | Engagement drops > 5%; catalog refresh (\(\sim\)daily for e-commerce) |
| Power-bound (KWS DS-CNN) | Acoustic environment change (noise floor shift) | Duty cycle (wakeups/hour) + false positive rate | False wake rate > 1%; battery drain exceeds spec (\(\sim\)quarterly OTA update) |
Systems insight: Ground-truth availability governs monitoring design. A workload’s limiting regime sets its cost and capacity but does not determine which quality signal is observable. Vision tasks with labels (ResNet-50) track holdout accuracy. Language and recommendation services (GPT-2, DLRM) rely on signals that need no labeling. Perplexity measures how poorly the model predicts each next word of live text, and the text itself supplies those words. Click-through rate (CTR) and conversion rate (CVR) count the fraction of shown items that users click or buy. Microcontroller models without labels (the keyword spotter’s DS-CNN) monitor duty cycles, while estimating false-wake rates requires a reference signal or reviewed examples. Retraining cadence is constrained by label delay, deployment access, validation cost, and the rate of observed change.
↩︎ Perplexity as the standard quality measure for language models is established in Large language model benchmarks.
3 Concept drift: Concept-drift and data-stream research formalized the problem that a model’s target relationship can change after deployment (Widmer and Kubat 1996; Gama et al. 2014). In adversarial domains such as spam, fraud, and abuse detection, the distribution can actively adapt in response to the model, making continuous monitoring and retraining a structural requirement rather than an operational luxury.
Widmer, Gerhard, and Miroslav Kubat. 1996. “Learning in the Presence of Concept Drift and Hidden Contexts.” Machine Learning 23 (1): 69–101. https://doi.org/10.1023/a:1018046501280.
Gama, João, Indrė Žliobaitė, Albert Bifet, Mykola Pechenizkiy, and Abdelhamid Bouchachia. 2014. “A Survey on Concept Drift Adaptation.” ACM Computing Surveys 46 (4): 1–37. https://doi.org/10.1145/2523813.
Schelter, Sebastian, Dustin Lange, Philipp Schmidt, Meltem Celikel, Felix Biessmann, and Andreas Grafberger. 2018. “Automating Large-Scale Data Quality Verification.” Proceedings of the VLDB Endowment 11 (12): 1781–94. https://doi.org/10.14778/3229863.3229867.
4 DVC (Data Version Control): DVC brings Git-like versioning to datasets and model artifacts (Iterative 2024), closing the artifact gap that equation 1 formalizes. Without data versioning, the \(\text{Data}_\ArtifactVersion\) term is unrecoverable, and no combination of code commits can reconstruct the model that was deployed.
Iterative. 2024. Data Version Control (DVC).
These principles respond to three recurring operational failures: concept drift3 (a change in how inputs relate to their correct outputs), data-quality defects (Schelter et al. 2018), and silent postdeployment degradation. Addressing them changes what a team versions and monitors, and who must coordinate. Data versioning,4 model versioning, and continuous statistical monitoring extend beyond traditional software engineering. Treating datasets and pipeline state as first-class versioned artifacts alongside source code turns deployment from a linear release pipeline into a continuous, evidence-driven feedback loop.
Checkpoint 14.1: The MLOps loop
The MLOps loop feeds production evidence back into design.
The feedback cycle
The artifacts
The five operational principles anchor reproducibility, consistency, observable degradation, cost-aware automation, and failure containment across the three boundaries of an ML node. When a team ships models by bypassing those boundary contracts, each iteration through the operations loop accumulates hidden dependencies that slow releases and erode accuracy.
Self-Check: Question
The chapter’s ranking service keeps its P99 latency inside budget, 99.99% server availability, and zero HTTP error responses. However, over four weeks, its click-prediction accuracy drops from 94% to 88% after a competitor’s promotion shifts what users click. Which operational challenge does this scenario illustrate?
- The hardware compute capacity ceiling between GPU memory and host memory
- The protocol communication overhead between REST endpoints and gRPC streaming
- The operational mismatch between traditional infrastructure availability and statistical predictive correctness
- The serialization throughput bottleneck between CPU preprocessing and accelerator execution
Which scenario represents a direct failure of the Data-Model Interface in a production ML system?
- An inference container crashes upon startup because the host system has an incompatible CUDA driver
- A candidate model deployment is delayed because previous model weights were not cached in warm standby
- A statistical drift alert is routed to an unmonitored ticketing queue instead of the on-call engineer
- An online inference service computes user_session_duration in seconds while the offline training pipeline calculated it in minutes
Explain why MLOps treats a deployed model as a closed-loop control system rather than a terminal release pipeline.
True or False: An ML Node is defined solely as the trained neural network weight file packaged inside a container runtime.
A production recommendation service processes \(Q = 2 \times 10^6\) queries per day. Due to a feature encoding discrepancy between offline training and online serving, \(\text{Rate}_{\text{skew}} = 0.005\) (\(0.5\%\) of queries) receive incorrect predictions, each causing an estimated business loss of \(C_{\text{error}} = \$0.20\). Using the chapter’s skew-cost equation, what is the annual financial impact of this inconsistency over a 365-day year?
- \(\$730,000\) per year
- \(\$73,000\) per year
- \(\$200,000\) per year
- \(\$36,500\) per year
Explain how the principle of ‘Separation of Concerns’ across the four MLOps functional layers (Data, Training, Serving, Monitoring) limits the blast radius of operational updates.
14.2 Technical Debt
A team that ships a model by copying feature scripts, skipping schema checks, and wiring predictions directly into downstream services reaches production quickly, only to spend the following year debugging silent regressions as external distributions shift and stale parameters break downstream consumers. In traditional software systems, technical debt5 represents the future rework created when expedient shortcuts replace disciplined architecture (Cunningham 1992). In machine learning systems, that debt compounds across the operations loop through statistical coupling and data dependencies that code review and unit tests cannot detect (Sculley et al. 2015), which the ML Test Score rubric (Breck et al. 2017) audits in section 14.8.1.
5 Technical debt: Ward Cunningham’s 1992 WyCash experience report introduced the debt metaphor for expedient code and delayed consolidation (Cunningham 1992).
Cunningham, Ward. 1992. “The WyCash Portfolio Management System.” ACM SIGPLAN OOPS Messenger 4 (2): 29–30. https://doi.org/10.1145/157710.157715.
Definition 14.2: Technical debt in ML
Technical debt in machine learning is the accumulating maintenance and change cost created by implicit data dependencies, entangled features, and undeclared consumers in ML systems, where the resulting liabilities may also appear as silent accuracy degradation.
- Significance: Google’s analysis of production ML systems argues that model code is only a small fraction of the surrounding system; the larger operational surface includes data collection, feature extraction, configuration, serving infrastructure, monitoring, and process management (Sculley et al. 2015). ML-specific debt drivers compound this. Changing one input feature can silently shift the learned representation of every other feature (entanglement). A model trained to correct another model’s errors creates a fragile dependency chain (correction cascades). Downstream systems that consume model outputs without explicit contracts become undeclared consumers, which break silently when the model is updated.
- Distinction: ML technical debt includes system- and data-level dependencies that code review and ordinary code-focused tests may miss. It can slow development and degrade prediction quality even while availability metrics remain healthy.
- Common pitfall: A frequent misconception is that “better code” solves technical debt in ML. In reality, it is a systems architecture problem: the debt accumulates when the assumptions of the training distribution (feature ranges, label meanings, data freshness) are not enforced as runtime contracts at the system boundary.
A break-even calculation makes the cost dynamics of technical debt concrete. Teams often resist automation investment because manual processes seem faster in early development, but that advantage disappears once recurring manual interventions exceed the up-front automation cost.
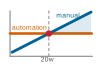
Cumulative manual work overtakes the one-time automation investment near week 20.
Napkin Math 14.1: The cumulative cost of manual operations
Problem: Why build automated pipelines when manual retraining is faster?
Physics: Manual work accumulates over time.
- Manual retrain: 4 hours of engineering per week.
- Pipeline build: 80 engineering hours (one-time).
Math:
- Result: 80 engineering hours \(\div\) 4 hours per week = 20 weeks.
- Assumption: This simplified calculation sets pipeline upkeep to zero, so automation removes the weekly task entirely.
- Upkeep: Real pipelines need maintenance and new features. Each week then recovers only the difference between the manual load and the upkeep, which pushes break-even later. Automation still pays back whenever its weekly upkeep stays below the manual work it replaces.
- Consequence: After 1 year, manual teams still spend 4 hours per week on maintenance, while pipeline teams spend only their upkeep (0 recurring hours under this calculation’s assumption).
Context: Over a system’s lifetime, the cost of maintaining it can exceed the cost of building it. In ML, technical debt is often data-driven rather than code-driven, because correct code can still fail when the data it processes shifts. Without telemetry, the team cannot tell whether maintenance work is reducing debt or merely hiding it.
Systems insight: A team that retrains by hand eventually has no time left to ship new models, provided automation upkeep stays below the manual load it removes. Without monitoring that makes silent failures visible, the team also accumulates debt in a system that grows harder to manage.
The debt is larger than manual retraining alone, because modeling code constitutes only a small fraction of a real-world deployment. Core modeling code is one component among ten around the ML system, alongside nine supporting subsystems spanning data verification, feature extraction, configuration, and machine resource management (figure 3). Their presence broadens the maintenance surface; the diagram does not measure each component’s cost.
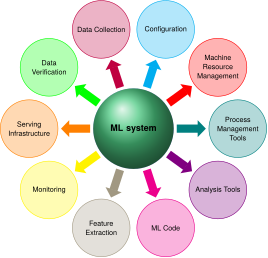
While automation addresses the recurring operational overhead of manual retraining, it cannot prevent architectural decay. Deployed systems accumulate hidden complexity through systemic failure modes that emerge from statistical coupling rather than deterministic logic. The patterns group by where the coupling hides: in eroded boundaries and the correction cascades they invite, in interface dependencies that no import statement declares, in feedback and configuration that accumulate as the system evolves, and in the code and architecture around the model.
14.2.1 Boundary erosion
When an upstream pipeline changes how missing ages are filled or rescales a price column, every syntactic check and unit test in the repository can pass while the shifted feature distribution silently degrades downstream model accuracy. Statistical software loses its modular boundaries more easily than conventional software does because component behavior depends on the distribution of incoming data rather than on type signatures alone. Whereas modular encapsulation and typed APIs make code-level dependencies explicit (even though changes can still violate behavioral contracts), implicit coupling through data pipelines creates unmonitored dependencies among feature engineering, training pipelines, and serving endpoints.
This erosion produces entanglement, where dependencies between features and components become so intertwined that local changes demand global coordination. The resulting failure mode reflects the CACE principle: Change Anything Changes Everything. When systems lack strict statistical checks at their boundaries, adjusting a feature encoding or data filtering threshold can shift learned weights throughout the model during retraining. With frozen weights, the same change leaves the learned parameters alone but alters the inputs the model sees, and potentially its predictions. For example, changing the binning strategy of a continuous feature shifts the feature’s variance and covariance structure, causing a previously calibrated model to underperform and forcing downstream recalibrations across dependent services.
Defending against boundary erosion requires architectural modularity enforced at runtime. Components require explicit data contracts that govern statistical invariants, including allowed feature ranges, null tolerances, and drift thresholds. Enforcing separation between data ingestion, feature generation, and inference logic creates verification boundaries where data distributions can be validated before reaching model weights. Because boundary erosion remains silent during initial prototyping, schema contracts and invariant checks are the earliest point at which statistical coupling can be detected and managed.
14.2.2 Correction cascades
When boundary erosion goes unaddressed, engineering fixes frequently trigger a correction cascade: patching a specific model defect with an auxiliary post-filter introduces secondary errors elsewhere, requiring further patches that destabilize the entire pipeline. In ML systems, these cascades are severe because changes propagate through statistical dependencies rather than deterministic code branches. Retraining a model to correct a specific false-positive cluster may degrade accuracy across previously stable cohorts. Adding an auxiliary model to override edge-case predictions introduces uncalibrated scores that confuse downstream consumers. Repeated dependent patches can demand coordinated revalidation, with maintenance costs that may exceed those of revising the base model.
Figure 4 traces this failure propagation along a four-stage dependency chain (Models A through D), where each downstream component compensates for the residual errors of its predecessor. When an upstream patch alters Model A, the dashed red arcs mark every downstream correction that requires revalidation and may need retraining.
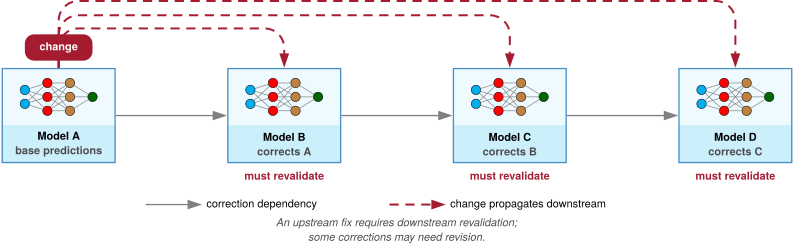
Model reuse is a common starting point for such a chain. A cascade requires dependent correction models, so fine-tuning or reusing an established model does not create one by itself. Reuse does, however, inherit representations and assumptions from the original task, and those require evaluation on the new task. Where they fit it poorly, the risk is that errors get patched downstream instead of fixed in the base model. Over time, those inherited properties become rigid architectural constraints that complicate future updates.
For example, fine-tuning an existing customer churn model for a new product line inherits the base model’s feature encodings and calibration thresholds. If the new product has different user engagement patterns, patching prediction errors with auxiliary post-processing rules creates a fragile multi-stage pipeline. When accuracy degrades, engineering teams discover that the root failure lies several layers upstream, in the base model’s original labeling conventions, such as what its training data counted as a churned customer.
Mitigating correction cascades requires balancing component reuse against redesign. While fine-tuning reduces initial compute and data collection costs, training a replacement base model can remove dependencies on a chain of auxiliary corrections, while data and labeling assumptions still require validation. The architectural decision depends on task similarity, covariate alignment (how closely the new task’s inputs match those the base model trained on), and the ongoing maintenance cost of chained models. Where dependent models are unavoidable, systems must decouple them through version-pinned model artifacts and frozen intermediate representations.
14.2.3 Undeclared consumers and data dependencies
Boundary erosion and correction cascades both stem from interface dependencies that bypass formal software contracts. Traditional software dependencies are declared through import statements, package managers, and RPC schemas, allowing static analysis tools to map dependency graphs. In machine learning systems, by contrast, when Model A writes its predictions to a shared warehouse table and Model B later reads that column as a training feature, neither repository’s import graph records the connection because the dependency hides inside the shared data stream.
Hidden coupling frequently manifests as undeclared consumers, where downstream services consume model predictions without formal registration or service-level agreements. When the upstream model is retrained or its output distribution shifts, these untracked consumers fail silently. For example, an automated marketing system that reads a credit risk score and targets every applicant below a fixed cutoff keeps applying that cutoff after a retrained model rescales its scores, because no one told its owners that the same number now means a different risk. The same consumer can also close a loop when its targeting alters applicant pools and feeds shifted distributions back into future training runs, so the model increasingly trains on the applicants its own scores favored. Such feedback loops form a further kind of hidden debt.
Undeclared consumers are compounded by data dependency debt, which accumulates when ML pipelines ingest unversioned tables, unstable upstream features, or signals with volatile distributions. Eliminating this interface debt requires infrastructure-enforced boundaries: strict authentication and registration for model prediction endpoints, machine-readable schema contracts for feature stores, and automated data lineage tracking that registers consumers before granting read access.
14.2.4 Feedback loops and configuration sprawl
As an ML system evolves, even with documented interfaces, the most dangerous dynamic is the feedback loop, where a deployed model shapes the data distribution that trains its successors. In the ranking service, suggested content dictates user engagement, clicks generate subsequent training sets, and the model reinforces its own historical selections while starving unselected content of exposure. In production, this failure mode often surfaces as a widening performance gap across demographic cohorts. Underrepresented groups receive worse recommendations, which generate sparse engagement logs that further weaken cohort representation in subsequent retraining runs. Responsible engineering returns to this self-reinforcing loop as the bias feedback model (principle 13). Detecting feedback loops requires cohort-stratified monitoring that tracks error distributions across user segments rather than relying on aggregate validation metrics.
↪ A worked example that fits the bias feedback factor from two audits and treats fairness as a stability property of the retraining loop is developed in Operate: Fairness as loop stability.
Evolution also degrades the workflows around the model. Over repeated deployment cycles, they accumulate pipeline and configuration debt, growing into sprawling collections of ad hoc glue scripts and divergent hyperparameter files. When pipelines lack modular interfaces, teams copy existing scripts rather than refactor brittle data loaders, producing redundant pipelines that process the same raw inputs with subtle inconsistencies. Compounding this, rapid prototyping frequently embeds business logic directly into feature preparation scripts. Controlling pipeline evolution requires workflow orchestration engines with immutable directed acyclic graph (DAG) definitions, strict parameter validation, and configuration versioning managed under the same source control as model code.
14.2.5 Code and architecture debt
Production ML repositories are rarely dominated by model definitions; instead, they fill with glue code, the integration wrappers written to shuttle tensors and records between general-purpose ML frameworks, feature pipelines, and low-latency serving engines (Sculley et al. 2015). Sculley et al. (2015) observe that a mature system can end up at most 5 percent machine learning code and at least 95 percent glue code. The proportion varies by system, but the asymmetry explains why integration code, not the model, dominates the maintenance surface. The resulting tight coupling to framework-specific APIs is a maintenance liability, because minor upstream framework updates force extensive rewrites of the surrounding integration scaffolding. Isolating third-party libraries behind stable internal interfaces prevents external API churn from propagating throughout the serving stack.
Rapid experimentation further burdens codebases through dead experimental codepaths. Research iterations leave behind legacy branches, alternative feature transforms, and abandoned scoring logic. Unlike traditional dead code that static analyzers flag and compilers prune, experimental ML codepaths often remain executable at runtime because they are guarded by dynamic configuration flags. These dormant branches expand the test matrix, complicate regression verification, and obscure the precise execution graph operating in production. Enforcing deprecation schedules and pruning retired feature flags prevents experimental residue from destabilizing the serving runtime. The same residue accumulates in data as well as code, where a retired feature can keep flowing through the pipeline long after anyone remembers why it exists.
Systems Perspective 14.1: Zombie features
Long-lived production models often accumulate features whose original owners, semantics, or intended use have faded. A feature can be deprecated in application code while still flowing through a feature store, training dataset, or serialized model input contract. The model may learn to ignore it, split signal across a duplicate, or depend on a preprocessing artifact that nobody still owns. Removing such a feature is therefore no longer a local cleanup. It becomes a compatibility change that can affect retraining, serving, monitoring, and downstream analysis.
Features in ML systems do not disappear just because code owners stop thinking about them. Every byte of an unused feature still adds to the data volume \(\DataVolume\) that each request moves, so at a fixed memory bandwidth \(\Bandwidth\) it lengthens the transfer time \(\DataVolume/\Bandwidth\) and inflates serialization overhead without improving accuracy. Without explicit deprecation policies and feature-store governance, models accumulate “dead code” that complicates debugging (Sculley et al. 2015).
Underlying both patterns is abstraction debt. Traditional software engineering relies on mature abstractions such as objects, interfaces, and modules, whereas ML engineering lacks universal abstractions for concepts such as a feature, a training dataset slice, or a model lifecycle state. Without standardized primitives, teams frequently reinvent bespoke abstractions or abandon encapsulation altogether. Infrastructure components such as feature stores, model registries, and standardized prediction services mitigate this debt by providing uniform abstractions for feature transformation, artifact lineage, and inference routing.
Sculley et al. (2015) also list warning signs of mounting debt, called system smells, among them passing unvalidated raw values rather than domain types, stitching several languages across the training-serving boundary, and promoting throwaway research notebooks directly into production. Treating debt paydown as a routine operational discipline rather than an emergency intervention keeps these smells from accumulating.
14.2.6 Technical debt in practice
A valuation forecast that directly sets home-purchase offers or a ranking model whose recommendations generate tomorrow’s click logs can pass every unit test in the repository while accumulating hundreds of millions of dollars in exposure. When statistical dependencies, undeclared consumers, and unversioned configurations go unchecked in production, they surface not as compiler warnings but as commercial losses and operational incidents that code-level testing alone cannot contain.
Production debt patterns
Four documented cases show these patterns in production. The first pair shows coupling through model behavior. YouTube’s recommendation system learns from noisy user-behavior signals, so its ranking objectives, per-user weighting, and live A/B evaluation are part of the system design rather than offline details (Covington et al. 2016). Its own rankings shape what users watch, which makes today’s recommendations tomorrow’s training signal, the feedback loop that evaluation on fixed historical logs can miss. Zillow’s iBuying venture exposes the decision-coupling version of a cascade, in which a forecast drives purchases that cannot be undone when the forecast is later corrected (war story 14.1).
Covington, Paul, Jay Adams, and Emre Sargin. 2016. “Deep Neural Networks for YouTube Recommendations.” Proceedings of the 10th ACM Conference on Recommender Systems, 191–98. https://doi.org/10.1145/2959100.2959190.
War Story 14.1: The Zillow Offers wind-down (2021)
Context: Zillow, a real-estate marketplace, ran Zillow Offers, an iBuying business that bought homes directly on the strength of forecasts of home prices and resale economics (Zillow Group 2021).
Mechanism: The valuation forecast did not remain a prediction. It set purchase prices, purchases became inventory, and inventory carried the forecast’s error onto the balance sheet. Zillow reported that it had bought homes at prices above its revised estimates of future selling prices, while resale-capacity constraints delayed some closings (Zillow Group 2021). Revising the forecast corrected the model’s view of the market but could not reverse commitments made on the earlier view, so the correction propagated downstream as losses rather than as a repair.
Impact: In November 2021 Zillow announced that it would wind down Zillow Offers, reported a $304 million third-quarter inventory write-down, and cut about 25 percent of its workforce (Zillow Group 2021).
Response: A safer design caps the inventory exposure any one forecast can create, keeps manual override between prediction and purchase, and places circuit breakers that halt purchasing when forecast uncertainty exceeds the accepted risk budget.
Systems lesson: The case does not show a chain of residual-correction models, and retraining alone would not have removed the business risk. It shows the hazard that correction cascades share: a fix applied at one stage cannot undo the state that downstream stages already built on its earlier output. When predictions trigger irreversible actions, the dependency chain runs through the physical world, and the operational controls must sit on that chain.
Zillow Group. 2021. Zillow Group Reports Third-Quarter 2021 Financial Results and Shares Plan to Wind down Zillow Offers Operations. Investor Relations Press Release.
National Transportation Safety Board. 2017. Collision Between a Car Operating with Automated Vehicle Control Systems and a Tractor-Semitrailer Truck Near Williston, Florida, May 7, 2016. HAR-17/02. National Transportation Safety Board.
Engineering, M. 2016. Introducing FBLearner Flow: Facebook’s AI Backbone. Engineering at Meta Blog.
Mosseri, Adam. 2018. Bringing People Closer Together. Meta Newsroom.
The second pair exposes coupling through ownership and configuration. In safety-critical driving automation, automated-control outputs, driver expectations, and subsystem responsibilities that are not specified clearly enough let operational failures cross component boundaries rather than stay local (National Transportation Safety Board 2017). In the 2016 crash that the National Transportation Safety Board investigated, a driver-assistance system was in use on a road with cross traffic that it was not designed to handle, while the driver relied on it to do so, and the failure fell into the gap between what the software did and what its human consumer expected. Facebook’s News Feed iterations show the configuration version of the same problem, in which rapid ranking changes without traceable settings and explicit objectives become hard to audit after deployment (Engineering 2016; Mosseri 2018).
In every case the remedy is structural. Mitigating technical debt requires end-to-end MLOps infrastructure: feature registries that enforce runtime schemas, metadata stores that track model-data lineage, automated CI/CD pipelines that validate statistical properties, and observability platforms that detect distribution shift before silent errors propagate downstream.
Silent interface decay, untracked consumers, and unversioned pipeline dependencies can each make a model unsafe to serve while its offline validation metrics look acceptable. Table 6 collects the debt patterns of this section with their root causes, failure symptoms, and mitigation strategies, the catalog of failure modes that a production-readiness rubric must detect.
| Debt Pattern | Primary Cause | Key Symptoms | Mitigation Strategies |
|---|---|---|---|
| Boundary Erosion | Tightly coupled components, unclear interfaces | Changes cascade unpredictably, CACE principle violations | Enforce modular interfaces, design for encapsulation |
| Correction Cascades | Sequential model dependencies, inherited assumptions | Upstream fixes break downstream systems, escalating revisions | Careful reuse vs. redesign trade-offs, clear versioning |
| Undeclared Consumers | Informal output sharing, untracked dependencies | Silent breakage from model updates, hidden feedback loops | Strict access controls, formal interface contracts, usage monitoring |
| Data Dependency Debt | Unstable or underutilized data inputs | Model failures from data changes, brittle feature pipelines | Data versioning, lineage tracking, leave-one-out analysis |
| Feedback Loops | Model outputs influence future training data | Self-reinforcing behavior, hidden performance degradation | Cohort-based monitoring, canary deployments, architectural isolation |
| Pipeline Debt | Ad hoc workflows, lack of standard interfaces | Fragile execution, duplication, maintenance burden | Modular design, workflow orchestration tools, shared libraries |
| Configuration Debt | Fragmented settings, poor versioning | Irreproducible results, silent failures, tuning opacity | Version control, validation, structured formats, automation |
| Prototype Debt | Rapid prototyping shortcuts, tight code-logic coupling | Inflexibility as systems scale, difficult team collaboration | Flexible foundations, intentional debt tracking, planned refactoring |
These patterns can also be read by interface, because most of them accumulate at one of the ML node’s three interfaces. Boundary erosion, correction cascades, and data dependency debt tend to form at the data-model interface, where one component’s output becomes a model’s input. Glue code, pipeline and configuration debt, and undeclared consumers tend to form at the model-infrastructure interface, where a trained model meets the systems that run it and read its predictions. Feedback loops tend to form at the production-monitoring interface, where live behavior returns to training. An engineer who can name the eroded interface knows which controls to inspect first.
The mitigation column reads as a requirements list for the rest of the chapter. Shared feature definitions, versioned artifacts, and automated pipelines are development infrastructure. Cohort monitoring belongs to production monitoring. The rubric that scores a system against the whole catalog, the ML Test Score, is taken up with operational maturity (section 14.8.1), once the controls it audits have been built. Development infrastructure comes first, because a fault cannot be traced to a boundary that was never versioned.
Self-Check: Question
According to Sculley et al. (2015), what additional mechanisms make technical debt in machine learning systems especially hard to detect and manage compared with ordinary code-focused debt?
- Because ML frameworks prevent developers from running unit tests or continuous integration jobs
- Because ML algorithms require more lines of raw mathematical code than supporting infrastructure software
- Because ML debt accumulates through implicit statistical relationships, data dependencies, and feedback loops that can degrade predictive quality silently without throwing runtime exceptions
- Because neural network parameters cannot be serialized to disk or stored in artifact registries
A data engineering team spends 6 hours per week manually extracting features, executing training runs, and validating a customer churn model. Building an automated CI/CD retraining pipeline requires a one-time upfront investment of 120 engineering hours. In this simplified calculation, assume all 6 weekly hours are saved, automation has no ongoing maintenance cost, and each additional model would impose a similar manual cost if the process scaled linearly. What is the breakeven time for this automation investment, and what long-term capacity risk arises if the team remains manual?
- Breakeven is 6 weeks; manual processes remain more cost-effective for multi-model deployments
- Breakeven is 10 weeks; automated pipelines eliminate the need for future model monitoring
- Breakeven is 40 weeks; manual maintenance has zero ongoing engineering cost after the first year
- Breakeven is 20 weeks; manual maintenance scales linearly with the number of deployed models until routine operations consume a growing share of engineering capacity
Explain why ‘correction cascades’ create a severe maintenance trap in production ML architectures, and state the primary architectural remedy.
True or False: In production ML systems, ‘glue code’ refers to the core machine learning algorithm.
The systemic vulnerability where changing one input feature’s distribution or encoding during retraining can alter model behavior and the contributions of other features elsewhere in the system is known as the ____ principle.
14.3 Development Infrastructure
When a production model fails an accuracy check, an engineer who cannot recover the exact training dataset, feature transformation code, and container image that produced it can only guess which input changed. Development infrastructure turns the debt patterns diagnosed in section 14.2 into concrete enforcement points. A feature schema that drifts upstream cannot be repaired by a dashboard alone; it needs a shared contract, a versioned artifact, and a deployment path that rejects incompatible changes before they reach production. Table 7 maps each component directly to a foundational principle (section 14.1.1) and a specific failure mode. CI/CD pipelines also carry versioned artifacts, but the table assigns them cost-aware automation because the pipeline is where the retraining and promotion criteria of equation 3 are actually checked, automating only the changes that meet them.
| Infrastructure Component | Principle Implemented | Debt Pattern Addressed |
|---|---|---|
| Feature stores | Consistency | Data dependency debt, training-serving skew |
| Versioning systems | Reproducibility | Configuration debt, correction cascades |
| CI/CD pipelines | Cost-aware automation | Pipeline debt, boundary erosion |
| Monitoring systems | Observable degradation | Feedback loops, silent failures |
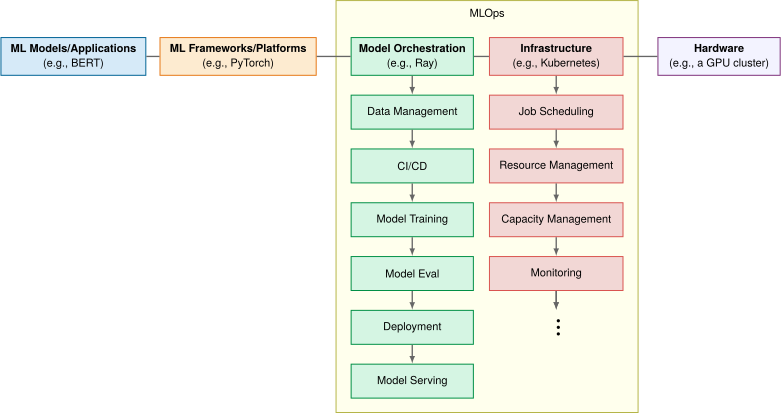
These operational components sit between the framework and the hardware and track what neither of them tracks, the data lineage and the cluster state. MLOps occupies the middle tiers of the implementation stack in figure 5, between the models and frameworks on one side and the hardware on the other. Model orchestration, which runs from data management to serving, and operational infrastructure, which runs from job scheduling to monitoring, together bridge mathematical frameworks and physical accelerator clusters and enforce the remediations of table 7. The tiers say where a component sits in the implementation stack, while the four layers of table 3 say who owns an operational responsibility; the rest of the chapter reasons with the layers and the three interfaces.
Inside the orchestration and infrastructure tiers, four architectural mechanisms execute these operational responsibilities. At the data boundary, a feature storage and retrieval layer serves a unified schema across two disparate access patterns. Offline training uses high-throughput analytical scans over immutable columnar files, and online serving uses low-latency point lookups against key-value stores (section 14.3.1.1). To keep every transformation and checkpoint traceable, an artifact and lineage store records content-addressed hashes for dataset snapshots, code commits, container images, and model weights. Any live prediction can then be audited back to its exact training inputs (section 14.3.1.2). Workflow orchestration then sequences the pipeline stages, from ingestion and validation through training and evaluation, as declared dependency graphs with retry semantics and automated triggers (section 14.3.2.1). A compute runtime underneath schedules accelerator hardware, host memory, and processor cores across training jobs and serving endpoints under strict resource isolation (section 14.3.2.2). Specific frameworks implement pieces of this decomposition, but the underlying mechanisms and interface boundaries outlast any particular tool.
14.3.1 Data infrastructure and preparation
Because unversioned datasets erode system boundaries, inconsistent feature computation triggers correction cascades, and undocumented data dependencies create hidden downstream consumers, paying down machine learning technical debt begins at the data boundary. If an offline training pipeline reads a backfilled warehouse table while the online serving path reads a live event stream with different null defaults, the deployed model evaluates inputs it never learned to score. Data engineering built the collection, preprocessing, and feature-transformation pipelines, together with the validation and dataset versioning that make one pipeline correct and reproducible. Operations turns those pipelines into versioned interfaces that it enforces across every pipeline touching a model. Where data engineering optimizes single-pipeline correctness and ingestion throughput, MLOps data management governs cross-pipeline consistency, ensuring that offline training and online serving compute identical features.
↩︎ The collection, preprocessing, and feature-transformation pipelines that MLOps formalizes are established in Data Engineering.
Apache Software Foundation. 2024. Apache Airflow.
HumanSignal. 2024. Label Studio: Open Source Data Labeling Platform.
Operations holds those interfaces to three properties: consistency, freshness, and quality. Consistency requires every artifact that influences model behavior, from raw records to engineered feature tables, to remain addressable by version, so that a checkpoint can be traced to the dataset snapshot that produced it (section 14.3.1.2). It also requires training and serving to share one feature definition (section 14.3.1.1). Content-addressed dataset versioning tools such as DVC (Iterative 2024) supply the first half of this requirement. Because consistent definitions still degrade if inputs arrive late, freshness requires scheduled pipelines, declared in workflow orchestrators such as Apache Airflow (Apache Software Foundation 2024), to deliver current data on a known cadence. A late run then becomes a visible failure rather than a stale feature. Even timely, versioned pipelines can ingest corrupted values, so quality requires the validation checks of Quality through validation and monitoring to run as automatic checks that reject a corrupted batch before it reaches training or serving. Annotation platforms such as Label Studio (HumanSignal 2024) keep label corrections under version history.
On the ranking service, the three properties operate in concert. Click and session events are ingested and joined with the item catalog through a scheduled pipeline (freshness). The resulting features, such as session length and rolling click rates, are stored in a feature store for both offline retraining and low-latency online lookup (consistency). Schema validation, range checks, missingness tests, and label audits reject corrupted event records before they enter the training set (quality), while dataset versioning and model-registry integration maintain traceability from raw event logs to deployed predictions.
Feature stores
Keeping those ranking features consistent across offline training and online serving fails whenever the two paths maintain separate feature code, the root cause of the data-dependency debt in section 14.2. Without a unified feature layer, feature definitions are typically implemented twice. On the ranking service, a data scientist writes user_session_length in Python over historical batch logs, while a systems engineer reimplements the calculation in Java or C++ to meet millisecond serving latencies. Any discrepancy in how the two implementations bound a session or handle missing events trains the model on one feature and serves it with another, degrading accuracy silently in production. Feature stores6 address this divergence by providing an abstraction layer between data engineering and machine learning, implementing the consistency imperative through a single source of truth for feature transformations. In pipelines lacking this abstraction, duplicated feature logic across environments introduces training-serving skew, temporal data leakage, and distribution drift.
6 Feature store: Uber’s Michelangelo platform described a centralized feature store for sharing and serving features across production models (Hermann and Del Balso 2017). At that scale, the consistency guarantee must hold under an online latency budget. A feature store differs from a shared library of feature code because its shared feature path must also serve fresh features fast enough for real-time inference.
Hermann, Jeremy, and Mike Del Balso. 2017. Meet Michelangelo: Uber’s Machine Learning Platform. Uber Engineering Blog.
↩︎ Training-serving skew, a violation of the consistency imperative, is established in Training-serving consistency.
Feature stores resolve the tension between batch throughput and online latency by keeping two synchronized storage tiers behind one API, an offline store for high-throughput training scans and an online store for point lookups under a tail-latency service-level objective (SLO). Their as-of join also gives each training example only the feature values that existed at its observation time (Feature stores). Operations depends on that guarantee because a ranking model trained on leaked features looks excellent offline and fails on live traffic.
Beyond consistency, feature stores support versioning, metadata management, and feature reuse across models. A ranking model and a fraud model built on the same user activity frequently depend on overlapping features that can be centrally maintained, validated, and shared. Integration with data pipelines and model registries preserves lineage. When an upstream feature definition is updated or deprecated, downstream models can be automatically identified and scheduled for retraining.
Training-serving skew: Diagnosis and prevention
Training-serving skew manifests operationally through feature store inconsistencies and pipeline divergence. Table 8 summarizes common causes and their detection methods:
| Skew Type | Example | Detection Method |
|---|---|---|
| Feature preprocessing | Normalization uses different statistics | Same-input replay and value comparison |
| Missing data handling | Training fills NaN with mean; serving uses 0 | Schema validation with explicit null handling |
| Time-dependent features | Features computed with different time cutoffs | Timestamp validation in feature pipelines |
| Library version drift | NumPy or Pandas version differences | Environment hash comparison |
Training-serving skew case study
Two implementations of user_session_length are enough to break a model that no one has touched. After a later release of the ranking service’s serving path, the model loses 8 percent of its accuracy despite zero alterations to model code or weights. Comparing feature distributions reveals that user_session_length has an empirical mean of 45 minutes in the training set but only 12 minutes in online inference. That difference starts the investigation; different user populations could produce it even with identical feature logic. Replaying the same recorded sessions through the versioned training and serving transformations, with the same available events and cutoff, reveals different durations for the same requests. Inspection of those artifacts then identifies feature-definition skew. The offline training pipeline calculated wall-clock duration from the initial event to the final event in a session, whereas the online serving path counted only foreground-active time after filtering idle periods. The model learned decision boundaries against a feature distribution that the serving infrastructure never delivers.
Feature stores resolve this discrepancy by centralizing feature logic into a single versioned definition, extending upstream data pipelines. In listing 1, training materializes historical features with point-in-time correctness, serving performs real-time point lookups, and both pipelines reference the identical versioned definition hash rather than independent code paths.
feature_definitions = registry.load(version="2026-06-01")

training_features = feature_definitions.materialize_historical(
    entities=training_entities,
    at_event_time=True,
    names=["user.session_length", "user.purchase_history"],
)

serving_features = feature_definitions.lookup_online(
    entities=[{"user_id": 12345}],
    names=["user.session_length", "user.purchase_history"],
)

assert training_features.schema == serving_features.schema
assert (
    training_features.definition_hash
    == serving_features.definition_hash
)
Centralizing the definition of session_length ensures that both offline and online pipelines execute identical transformation logic, though automated integration tests must still verify value parity. Centralized registries also record metadata and lineage, enabling rapid diagnosis when feature definitions evolve (Hermann and Del Balso 2017; Gojek and Google 2019).
Gojek, and Google. 2019. Feast: An Open Source Feature Store for Machine Learning. Google Cloud Blog.
The consistency imperative (section 14.1.1.3) priced this failure per query, and the user_session_length divergence in this case study shows how a single feature computed two ways produces such errors, at a cost of 8 percent of the model’s accuracy. To prevent those recurring losses without duplicating effort, centralized feature stores amortize the engineering cost of this infrastructure across multiple models and services, translating architectural consistency into measurable operational savings.
Skew detection in CI/CD
Continuous integration pipelines must validate feature consistency before deployment. A parity test replays recorded inputs through the versioned training and serving transformations, aligns results by request identifier, and compares each feature using its declared semantics and numerical tolerance. Both paths must receive the exact event snapshot available at the prediction cutoff. Otherwise an offline path reading a backfilled warehouse table will include events that arrived after the request, confounding code differences with differences in available information. For a duration feature, the contract specifies the time unit and whether idle periods count. Categorical values and missingness must agree exactly, whereas floating-point values may use a feature-specific tolerance.
A small counterexample shows why distributions cannot replace this check. Suppose the training transformation returns session durations of 12 and 45 minutes for requests A and B, respectively, while serving returns 45 and 12 minutes for those same requests. The marginal distributions, the feature’s values taken on their own without regard to which request produced each one, are identical, so a Kolmogorov-Smirnov (KS) comparison, which sees only the two sets of values, finds no difference, but request-keyed comparison detects both mismatches. Conversely, a new population of shorter sessions can shift the marginal distribution while both paths still agree for every replayed request. Point-in-time correctness remains a separate requirement, because two replay paths fed the same unwindowed log will agree with each other while both leak future events that did not exist at prediction time.
Listing 2 supplies a complementary distribution screen using the two-sample KS test that the data pipeline already uses to watch for drift (Quality through validation and monitoring). The KS statistic is the largest vertical gap between the empirical cumulative distribution functions (eCDFs) of the training and serving samples. Setting the threshold to \(0.1\) asserts that cumulative probabilities do not diverge by more than 10 percentage points at any value across the feature’s support. In this illustrative release policy, exceeding the threshold pauses promotion for review rather than diagnosing skew. The threshold must be calibrated against sample size and feature sensitivity. Passing the screen establishes only limited marginal divergence at that threshold; it does not establish per-request parity.
def screen_feature_distributions(
    training_features, serving_features, threshold=0.1
):
    """Pause promotion for review if distributions diverge."""
    for feature in training_features.columns:
        ks_stat = ks_2samp(
            training_features[feature], serving_features[feature]
        )
        if ks_stat.statistic > threshold:
            raise DistributionReviewRequired(
                f"{feature}: KS={ks_stat.statistic:.3f}"
            )
Versioning and lineage
Replaying recorded requests to isolate skew or pausing promotion on a distribution screen works only when the team can recover the exact feature definitions, dataset snapshot, and model checkpoint that ran. Lineage tracking and versioning provide that record, implementing the reproducibility principle formalized in section 14.1.1. Software artifact provenance already depends on source code, build tools, dependencies, and configuration. In machine learning systems, model behavior is the joint product of code, hyperparameter configuration, and the training dataset snapshot. Changing any single dependency produces an entirely distinct model artifact. Each artifact gets a content hash, so any model can be traced to its inputs.
↩︎ Content-addressed dataset versioning, which records each dataset release by its hash, is established in Data versioning for ML reproducibility.
7 Model registry: Prevents “registry bypass,” the failure mode where the undocumented production model diverges from the trained artifact through different preprocessing, stale serialization formats, or manual hotfixes applied directly to the serving endpoint. Without a registry enforcing versioned, immutable artifacts with queryable metadata and state, rollbacks require locating the correct weights from an ad hoc artifact store under incident pressure.
MLflow Project. 2026. MLflow Model Registry.
Data versioning addresses dataset mutability by retaining raw data snapshots and intermediate feature tables under content-addressable hashes, so the recorded inputs to historical runs remain retrievable. Hashes identify artifacts but cannot reconstruct missing content or remove execution nondeterminism. Model versioning registers trained weights as immutable artifacts alongside training hyperparameters, evaluation metrics, and environment dependency manifests. A model registry7 is the store that holds these immutable artifacts under lifecycle states (such as staging, production, or retired) and exposes lineage graphs tracing the complete dependency chain from raw ingested records to deployed prediction endpoints (MLflow Project 2026; Google Cloud 2024).
The registry is also what lets the release machinery promote, hold, or roll back the exact artifact that was evaluated. It stores immutable version tags, links evaluation metrics to artifact hashes, and governs which checkpoint each serving tier runs (Google Cloud 2024). This distinguishes a registry from an exploratory model catalog, which indexes candidate architectures for experimentation; a model enters the registry only when it becomes a versioned candidate for deployment. Experiment tracking frameworks such as MLflow8 (Databricks 2024) and unified distributed runtimes such as Ray9 record the surrounding execution state, training parameters, and lineage. Together, registry governance and lineage tracking turn experimental validation into controlled release, so a tested candidate can be promoted to production, monitored under live traffic, and reversed without losing provenance.
Google Cloud. 2024. Vertex AI Model Registry.
8 MLflow: An open-source MLOps framework that records hyperparameter runs, model binary hashes, and deployment stage transitions. The systems trade-off is centralizing lineage tracking vs. bottlenecking its metadata store during massive parallel hyperparameter sweeps.
9 Ray: A distributed computing framework (Moritz et al. 2018) with a unified task and actor interface. The broader MLOps lesson is that fragmented infrastructure creates translation points where preprocessing logic, normalization constants, tokenizer versions, or artifact formats can diverge silently. Shared execution abstractions can reduce that fragmentation, but training-serving skew still requires explicit consistency checks across data, features, and serving code.
Moritz, Philipp, Robert Nishihara, Stephanie Wang, Alexey Tumanov, Richard Liaw, Eric Liang, Melih Elibol, et al. 2018. “Ray: A Distributed Framework for Emerging AI Applications.” Proceedings of the 13th USENIX Symposium on Operating Systems Design and Implementation (OSDI), 561–77.
Together, these mechanisms construct the lineage graph of the machine learning system and establish the audit trail required to diagnose production failures: determining whether an incoming request distribution diverged from training baselines, whether upstream feature calculations changed, or whether the serving environment loaded an unvalidated weight checkpoint. Recording provenance as a required, queryable artifact gives incident triage a verifiable record against which to test root-cause hypotheses.
14.3.2 Continuous pipelines and automation
Feature stores and versioning systems lock down data and artifact consistency at a single point in time. Production models, however, must repeat preprocessing, training, evaluation, and release without an engineer running scripts by hand and risking a skipped validation check or a mismatched dataset path. Continuous automation joins those static controls into integrated workflows that respond to new data, shifting objectives, and operational constraints (Orr et al. 2021; Google Cloud 2026).
Orr, Laurel, Atindriyo Sanyal, Xiao Ling, Karan Goel, and Megan Leszczynski. 2021. “Managing ML Pipelines: Feature Stores and the Coming Wave of Embedding Ecosystems.” Proceedings of the VLDB Endowment 14 (12): 3178–81. https://doi.org/10.14778/3476311.3476402.
CI/CD pipelines
CI/CD pipelines carry that consistency from the data side to the process side, ensuring that changes flow through validated stages rather than ad hoc deployments. ML CI/CD pipelines must handle complexity absent from traditional software: data dependencies, model training workflows, and artifact versioning that couple code changes to statistical behavior changes.
A typical ML CI/CD pipeline consists of coordinated stages: checking out updated code, preprocessing input data, training a candidate model, validating performance, packaging the model, and deploying to a serving environment. In some cases, pipelines also include triggers for automatic retraining based on data drift or performance degradation. Codifying these steps in CI/CD pipelines10 reduces manual intervention, enforces quality checks, and supports continuous improvement of deployed systems.
10 Idempotency: This property ensures that retrying a pipeline stage does not create duplicate externally visible effects, conflicting registrations, or repeated deployment actions. Producing identical models from identical inputs is a separate property (determinism and reproducibility), and the training stage may violate it due to randomness such as weight initialization. Production systems therefore combine stable run identifiers and atomic publication for idempotency with fixed random seeds, deterministic kernels, fixed library versions, and controlled data ordering for reproducibility.
GitHub, Inc. 2024b. GitHub Actions.
Authors, Kubeflow. 2024. Kubeflow.
ML CI/CD adds a second tier of tooling because a general-purpose orchestrator handles code but not data or models. A general-purpose CI/CD orchestrator (GitHub Actions (GitHub, Inc. 2024b), for example) manages version-control events and execution logic, but the ML layer must additionally version data, block promotion on model metrics, and trigger retraining. Teams therefore add an ML platform or workflow orchestrator (Kubeflow (Authors 2024), for example) that supplies higher-level abstractions for those tasks.
Without this automation, model deployment degrades into a manual, error-prone process in which an engineer retrains locally, copies artifacts to a staging server, and promotes to production with no guarantee that the data, code, or hyperparameters match what was validated. The cost of such ad hoc workflows compounds with team size and deployment frequency, producing configuration drift and silent regressions that surface only after the model has served incorrect predictions.
A continuous training pipeline runs seven sequential stages, from dataset ingestion, data validation, and data transformation through training, evaluation, validation, and registry promotion (figure 6). Driven by dedicated processing, training, and evaluation engines beneath the pipeline, the workflow coordinates with surrounding dataset, model, and metadata repositories whenever an external trigger initiates retraining.
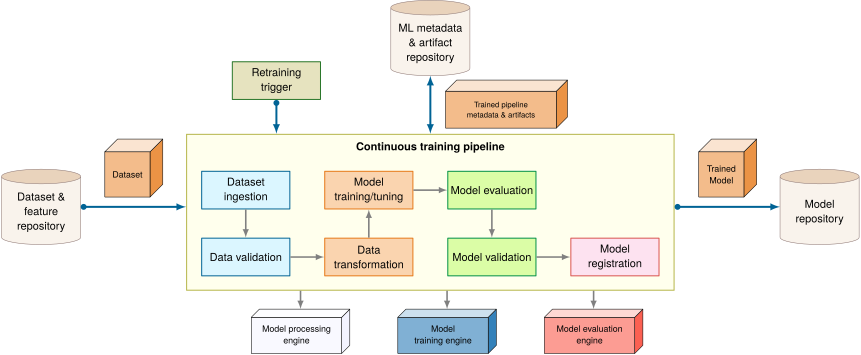
Google Cloud. 2026. MLOps: Continuous Delivery and Automation Pipelines in Machine Learning.
Consider the ranking model under active development. When a developer commits code changes, the CI pipeline pulls the specified dataset version, performs feature preprocessing, and initiates model training. Experiments are tracked with an experiment tracker such as MLflow (Databricks 2024), which logs loss curves and also registers model artifacts. After passing automated offline validation, the model is containerized and deployed to a staging cluster. If the candidate satisfies staging validation, the pipeline executes a canary rollout (section 14.4.3), gradually shifting production query traffic to the new model while monitoring inference latency and error rates. If a performance regression emerges, traffic automatically rolls back to the previous model checkpoint.
Databricks. 2024. MLflow: An Open Source Platform for the Machine Learning Lifecycle.
CI/CD becomes foundational when systems release models repeatedly or carry meaningful production risk, turning ad hoc experimentation into structured, repeatable deployment. Scaling beyond one pipeline requires reusable components and explicitly specified artifact schemas.
Example 14.1: Google TFX production ML pipelines
Scenario: Google’s production experience motivated TensorFlow Extended (TFX), a set of reusable components for production ML pipelines (Baylor et al. 2017). As pipelines multiply, ad hoc handoffs make validation, lineage, and reproducibility difficult.
Diagnosis: Each stage needs explicit validation and metadata so a deployed model can be traced to the data, transformations, code, and evaluation that produced it.
Systems lesson: Directed acyclic graph orchestration alone does not establish reproducibility. Standardized components and ML Metadata (MLMD), a store that records the inputs and outputs of every pipeline component run, preserve lineage through recorded inputs and transformations.
Baylor, Denis, Eric Breck, Heng-Tze Cheng, Noah Fiedel, Chuan Yu Foo, Zakaria Haque, Salem Haykal, et al. 2017. “TFX: A TensorFlow-Based Production-Scale Machine Learning Platform.” Proceedings of the 23rd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining, 1387–95. https://doi.org/10.1145/3097983.3098021.
Training pipelines
CI/CD pipelines orchestrate the overall workflow, but training itself requires specialized compute infrastructure. Model training builds on the single-node parallel execution primitives that training systems already provide. Within MLOps, training activities become components of a reproducible pipeline supporting continual experimentation and production deployment.
↩︎ The single-node data- and model-parallel execution that training pipelines schedule is established in Single-node multi-GPU training.
Abadi, Martı́n, Paul Barham, Jianmin Chen, Zhifeng Chen, Andy Davis, Jeffrey Dean, Matthieu Devin, et al. 2016. “TensorFlow: A System for Large-Scale Machine Learning.” Proceedings of the 12th USENIX Symposium on Operating Systems Design and Implementation (OSDI), 265–83.
Paszke, Adam, Sam Gross, Francisco Massa, Adam Lerer, James Bradbury, Gregory Chanan, Trevor Killeen, et al. 2019. “PyTorch: An Imperative Style, High-Performance Deep Learning Library.” Advances in Neural Information Processing Systems (NeurIPS) 32: 8024–35.
Chollet, François et al. 2024. Keras.
Frameworks such as TensorFlow (Abadi et al. 2016), PyTorch (Paszke et al. 2019), and Keras (Chollet et al. 2024) supply modular components for model architectures and optimization routines. Operational discipline determines which exploratory training routines graduate into versioned, tested retraining jobs, and under what execution triggers.
↩︎ The criteria for selecting a framework are established in Framework selection criteria.
Torvalds, Linus, and Junio Hamano. 2024. Git.
GitHub, Inc. 2024a. GitHub.
Project Jupyter. 2024. Project Jupyter.
Training scripts and environment configurations are version-controlled with Git (Torvalds and Hamano 2024) and hosted on GitHub (GitHub, Inc. 2024a). Interactive Jupyter (Project Jupyter 2024) notebooks accelerate prototyping by coupling code, inline visualizations, and execution state, but running them unaltered in production pipelines introduces severe operational liabilities.
Notebooks in production
Automated CI/CD pipelines assume deterministic and reproducible code execution, but Jupyter notebooks violate this assumption through persistent kernel state. In an interactive session, cells can be executed out of linear order, creating hidden memory dependencies that cannot be reproduced from a clean interpreter restart. A common production failure occurs when development relies on cells executed in sequence 1-3-2; a scheduled batch runner executing top-to-bottom (1-2-3) fails due to undefined variables or altered intermediate tensors.
Testing difficulties compound this state vulnerability. Standard unit-testing harnesses and mocking frameworks do not interface cleanly with interactive notebook documents. Cell-level assertions are rarely parameterized or wired into test runners, leaving notebooks significantly less tested than modular Python code.
Both liabilities shrink once a notebook runs like a script. Headless execution with injected parameters (Papermill (Papermill Project 2026)) runs cells top-to-bottom as discrete pipeline stages, and export to a plain script (nbconvert (Project Jupyter 2026)) exposes the code to linters and CI test runners. Teams must still select or refactor exploratory cells and verify clean, ordered execution.
Papermill Project. 2026. Papermill Documentation.
Project Jupyter. 2026. nbconvert: Convert Notebooks to Other Formats.
Extracting code from notebooks into tested modules introduces refactoring overhead, but it prevents hidden state assumptions from causing training-serving skew in production. Such skew is a silent failure whose cost grows with every day it goes undetected, as the silent-failure calculation in the monitoring discussion shows (notebook 14.3).
Modular training logic also allows a pipeline to schedule repeatable experiments within the node’s resource budget. Concurrent runs compete for accelerator memory, host preprocessing capacity, and storage bandwidth; enforcing resource limits recorded alongside each run’s configuration keeps experiments within the capacity reserved for them. If execution can be interrupted, checkpoint-and-resume (Training state and checkpoints) preserves completed training work without requiring the entire run to restart.
How often to run this pipeline depends on evidence that only production monitoring supplies, so section 14.6 takes up the decision after monitoring. A pipeline that can run on demand still produces only candidates, and validation decides which of them may ship.
Model validation
Training pipelines produce model candidates; model validation determines which candidates merit production deployment. Unlike research evaluation, where a model that beats a benchmark on a static test set may be considered successful, production validation must assess operational readiness under representative conditions and establish the monitoring and rollback controls needed after the distribution changes. This is where MLOps manages the verification gap (principle 9), the distance between what a finite test set can verify and what the model meets in deployment, rather than closing it. No test suite covers the deployment population, so validation keeps re-estimating performance as that population changes.
↩︎ Model validation as the evidence-based check that decides whether a model ships is established in Stage 4: Evaluation and Validation.
Rainio, Oona, Jarmo Teuho, and Riku Klén. 2024. “Evaluation Metrics and Statistical Tests for Machine Learning.” Scientific Reports 14 (1): 6086. https://doi.org/10.1038/s41598-024-56706-x.
IBM. 2024. IBM Watson OpenScale: Data Drift Detection.
The evaluation process begins with performance testing against a holdout test set sampled to represent the current production population and refreshed as that population changes. Core metrics such as accuracy, AUC, precision, recall, and F1 score (Rainio et al. 2024) are computed and tracked longitudinally to detect degradation from data drift (IBM 2024). Section 14.5.2 shows how such drift appears in live telemetry.
Beyond static evaluation, production pipelines expose candidate weights to live traffic in controlled stages (shadow, canary, and blue-green deployment) while bounding the blast radius, and section 14.4.3 develops each. Validation defines the evidence every stage must produce before a candidate advances. Evaluating candidates under identical operational conditions is the prerequisite for a sound promotion decision. A candidate that shows apparent metric gains only because it was evaluated against a differing traffic slice or temporal window confounds model quality with data variance. Cloud ML platforms support controlled evaluation through request replay, shadow serving, and synthetic load testing. The comparison must also be recorded. Experiment trackers such as Weights & Biases (Weights & Biases, Inc. 2024) log the data slice, time window, configuration, and metrics used for each candidate, so a promotion decision can be audited and repeated under the same conditions.
Weights & Biases, Inc. 2024. Weights & Biases: The AI Developer Platform.
While automated validation checks protect against regressions on primary aggregate metrics, production validation also requires auditing slices and long-tail behavior. Automated test suites often mask severe performance drops on underrepresented subpopulations or safety-critical edge cases. Production architectures combine automated checks with policy reviews, particularly for models deployed in regulated domains. This multi-stage validation discipline bridges offline evaluation with live production monitoring, ensuring that candidate models satisfy accuracy, latency, and safety invariants before receiving unconstrained serving traffic.
14.3.3 Infrastructure integration
A versioned model checkpoint is still unsafe to deploy if the serving cluster runs a different feature definition or lacks a tested path back to the previous weights. Development infrastructure locks these pieces together across two of the three system interfaces. Feature stores and data versioning reduce inconsistency at the data-model interface by centralizing and tracking feature access across training and serving. CI/CD pipelines, model registries, and validation checks stabilize the model-infrastructure interface by automating the transition from trained weights to containerized services with rollback capability. Together, these controls prepare an artifact for release. The third interface, production monitoring, closes the operations loop by tracking whether predictive quality holds as inputs and operating conditions change, though the release must come first.
Self-Check: Question
A team versions its model training code in Git, but datasets are pulled dynamically from unversioned live database queries and training hyperparameters are passed via ad hoc shell flags. Which foundational MLOps principle is violated, and what formal dependency does this break?
- Observable degradation; it prevents inference proxies from logging P99 latency percentiles
- Reproducibility; it breaks the ability to reconstruct a training run from versioned Code, Data, Config, and Environment artifacts while controlling for or characterizing execution nondeterminism
- Separation of concerns; it couples feature transformation code with neural loss calculation
- Cost-aware automation; it prevents the workload scheduler from executing batch inference
Explain how a centralized feature store’s point-in-time (time-travel) query capability prevents data leakage during model training.
Order the following stages in a feature-consistency investigation after a production symptom has already been observed: (1) compare the resulting training-side and serving-side feature values to locate the discrepancy, (2) evaluate whether correcting that discrepancy is worth the expected benefit, implementation cost, and deployment risk, (3) replay the same recorded input through both the training and serving transformations, (4) retrieve the versioned training and serving transformation artifacts for the affected deployment.
After drift has been investigated and retraining has been approved under policy, an automated MLOps continuous training and delivery pipeline executes. Place the following pipeline stages in their correct execution order:
- Data Validation Check: Run schema and statistical boundary checks on newly ingested data.
- Staged Rollout / Canary Deployment: Route a small percentage of live production traffic to the new model.
- Model Training & Hyperparameter Optimization: Train candidate model weights on the validated dataset.
- Model Evaluation & Guardrail Check: Evaluate candidate model against golden test slices and latency SLOs.
- Model Registry Registration: Tag and store the validated model binary, metadata, and container hash.
- True or False: In automated ML pipelines, a ‘reproducibility failure’ and an ‘operational idempotence failure’ describe the exact same defect.
14.4 Releasing Models
A model that passes every offline check has still not made a single production decision. Between the validated checkpoint and the first user-facing prediction lie packaging, conversion to a serving runtime, staged exposure to live traffic, and a path back if the new version misbehaves. At each step, the artifact users see can drift from the artifact that was evaluated. Deployment transforms a static checkpoint into a versioned, reproducible execution artifact. Serving then allocates accelerator memory, stages input batches, and schedules compute kernels to satisfy latency SLOs under dynamic request loads. The release and recover steps of the operations loop own the seams between the two: proving that what ships is what was validated, limiting how much traffic a bad version can reach, and keeping rollback fast enough to use. On the ranking service each of those seams also costs memory, because any control that keeps two versions alive must hold two copies of the embedding tables.
14.4.1 Infrastructure as code
Holding two copies of the ranking tables across a staged release only works if staging and production provision the same accelerator hardware, memory limits, and scaling quotas. When teams manage clusters through manual commands or tickets instead of code, environments drift apart. A model that passed staging can fail in production because an operator provisioned a different GPU type, a training job can crash because a colleague’s experiment exhausted shared memory, and an inference service can fail to scale because its resource quotas were set in an informal message six months earlier.
Infrastructure as code (IaC) treats infrastructure configuration as software (version-controlled, reviewed, tested, and automatically executed) rather than something configured through graphical interfaces or command-line tools. Changes are tracked, configurations can be tested before deployment, and environments can be reliably reproduced.
The specific tool matters less than the property it enforces. Infrastructure-as-code tools such as Terraform (HashiCorp 2014) version infrastructure definitions alongside application code. A team can then reproduce the accelerator type, network policy, storage permissions, and scaling limits of a training or serving environment on any cloud provider or on-premises hardware, and can audit and test those definitions in the same CI/CD pipelines as the model. Containerization provides the same reproducibility boundary for runtime dependencies. Docker (Merkel 2014) packages the model, libraries, and serving code into an isolated unit, and orchestration systems such as Kubernetes (Cloud Native Computing Foundation 2024a) deploy that unit repeatedly while keeping resource allocation, scaling, and health management explicit.
HashiCorp. 2014. Terraform: Infrastructure as Code. Software available from https://www.terraform.io/.
Cloud Native Computing Foundation. 2024a. Kubernetes: Production-Grade Container Orchestration.
11 ML autoscaling: Autoscaling adjusts capacity based on demand signals (Amazon Web Services 2024), but ML serving adds constraints absent from stateless web services. Autoscaling decisions must account for model loading time (cold-start overhead), GPU memory fragmentation, and batching behavior in addition to CPU utilization. Scaling up too slowly violates latency SLOs; scaling down too aggressively forces repeated cold starts that degrade p99 latency.
Amazon Web Services. 2024. AWS Auto Scaling.
To absorb spikes during hyperparameter tuning and surges in prediction traffic, teams use autoscaling11 (Amazon Web Services 2024), which adjusts compute capacity from usage metrics to balance performance and cost. The same infrastructure definitions must also cover on-premises and edge targets when latency, privacy, or regulation keeps part of a deployment off the cloud.
Infrastructure as code addresses how to provision resources reproducibly, but operators must still decide when and how much capacity to allocate. ML workloads break the assumptions of conventional web provisioning. Training jobs demand high-concurrency bursts across distributed accelerator topologies, creating friction between cluster utilization efficiency and time-to-solution. Inference services require sustained baseline allocations with rapid elastic scale-out to absorb request spikes under strict tail-latency SLOs, a balance that the utilization targets of section 14.5.1.1 quantify.
14.4.2 Validating the serving artifact
Matching the cluster and container across staging and production still does not guarantee that the model inside the container computes the same predictions it produced in evaluation, because the artifact that reaches the serving fleet is rarely the raw training checkpoint. Before deployment, the model is usually compiled from eager framework code into a static graph for a specific runtime and often lowered in precision. Each conversion trades portability for speed, and each can change what the model computes, so the operational obligation is to prove that the converted artifact still behaves like the model that was validated.
↩︎ Inference runtimes and the precision choices they support for serving are established in Inference Runtime Selection.
That proof must target the failure modes that conversion introduces silently. Consider a team that deploys an INT8-quantized model after verifying only throughput improvement. Classification accuracy drops on rare but high-value edge cases, and the degradation goes undetected for weeks because aggregate metrics remain within SLO bounds. The first validation layer is numerical equivalence, comparing optimized outputs against the original model on a representative test set with application-specific divergence thresholds. That check is necessary but insufficient, because a static calibration slice (the fixed sample of inputs used to set the quantization scales) is not live traffic. Rare inputs, out-of-distribution examples, and subgroup-specific cases can expose quantization artifacts that aggregate test metrics hide, so the comparison must be disaggregated by the same cohorts that production monitoring tracks (section 14.5).
↩︎ Range calibration, which sets quantization scales from a sample of inputs, is established in Range calibration.
The second layer is operational validation. Memory footprint must be measured at peak runtime utilization, including dynamic allocations during inference, since some optimizations trade increased runtime memory for computational speed. Warm-up behavior varies by runtime: Accelerated Linear Algebra (XLA) may just-in-time (JIT) compile kernels during initial execution, whereas TensorRT builds its compiled engine before deployment. Loading that engine can still add startup latency. Runtime version compatibility then closes the loop. Deployment configurations need explicit version pinning, because even a minor runtime upgrade can change kernel selection, and with it both latency and numerical results, in an artifact whose weights never changed. An unpinned runtime is an untracked input to equation 1.
14.4.3 Model deployment
Even a verified, runtime-pinned model engine can fail on its first live request if an engineer copies the weights onto a production server whose feature-extraction library differs from the one used in evaluation, causing the ranking model to score nearly every item the same. Model deployment is therefore a systems release problem rather than a file transfer, because the validated model weights, pinned serving runtime, and preprocessing configuration must ship as a single deployable unit. Packaging that bundle into the immutable container image of section 14.4.112 enforces environment parity between development and cluster nodes.
12 Containerization for ML deployment: Docker (Merkel 2014) packages code with dependencies into portable units; Kubernetes (Burns et al. 2016) orchestrates those units across clusters. Containerization addresses the \(\text{Environment}_\ArtifactVersion\) term in equation 1 partially by capturing user-space dependencies as a versioned artifact; host kernels, drivers, and hardware remain external dependencies.
Merkel, Dirk. 2014. “Docker: Lightweight Linux Containers for Consistent Development and Deployment.” Linux Journal 2014 (239).
Burns, Brendan, Brian Grant, David Oppenheimer, Eric Brewer, and John Wilkes. 2016. “Borg, Omega, and Kubernetes.” Communications of the ACM 59 (5): 50–57. https://doi.org/10.1145/2890784.
Chen, Andrew, Andy Chow, Aaron Davidson, Arjun DCunha, Ali Ghodsi, Sue Ann Hong, Andy Konwinski, et al. 2020. “Developments in MLflow: A System to Accelerate the Machine Learning Lifecycle.” Proceedings of the Fourth International Workshop on Data Management for End-to-End Machine Learning, 1–4. https://doi.org/10.1145/3399579.3399867.
13 Staging validation: ML staging adds statistical quality checks to conventional functional and operational validation. A model can pass unit tests and still fail in production because the test data does not reflect the deployment distribution, so rollout checks must compare prediction statistics, evaluation slices, and business guardrails against calibrated thresholds rather than rely on unit tests alone.
When the model registry promotes that containerized candidate (Chen et al. 2020), the release pipeline first deploys it to a staging or QA environment13 to verify functional and statistical invariants before any user traffic reaches it.
A staged rollout carries that staging validation into live traffic in steps, widening a candidate’s exposure only after the previous step shows no regression. Three release strategies put it into practice. Shadow deployments14 duplicate live production traffic asynchronously to a candidate model without returning its inferences to users, enabling latency and output comparison without direct user exposure; accuracy still requires labels or another ground-truth reference. Canary deployments15 route a small share of user traffic to the candidate and keep ramping that share toward full traffic as long as no regression appears under live load. Blue-green deployments16 maintain parallel environments for router-level cutover and rapid rollback. Each strategy reduces a different release risk, but none removes the need for tested rollback procedures and production monitoring.
14 Shadow deployment: Economically justified when its expected reduction in rollout loss exceeds the cost of shadow infrastructure for duplicated inference without serving results.
15 Canary deployment: The ML-specific challenge is that a “failure” is statistical degradation, not a deterministic crash: detecting a small accuracy difference with high confidence can require thousands of inferences, creating a tension between decision speed and statistical power that determines minimum canary duration.
16 Blue-green deployment: Maintains two comparable production environments, “blue” (serving current traffic) and “green” (running the candidate), then switches traffic in a routing change once the green environment passes validation. Because rollback is a traffic flip rather than a staged drain, recovery can be faster than a gradual canary for stateless services. The trade-off is extra infrastructure during the switch, so blue-green wins over canary when brief duplicate capacity is acceptable and per-segment statistical validation is expensive.
↩︎ Staged rollout as the lifecycle’s last validation step, extending offline evaluation to live traffic, is established in Offline and online evaluation.
Fowler, Martin. 2014. Canary Release. Martin Fowler’s Blog.
In a canary release, the router exposes the candidate to an initial slice of live traffic (Fowler 2014) while telemetry pipelines monitor inference latency, system stability, and prediction distributions. On the ranking service, a candidate receives 5 percent of live queries while the team compares click-through rate, p99 latency, and prediction drift against the baseline model. Only after the candidate demonstrates statistical stability without latency regressions is it promoted to serve full production traffic.
War Story 14.2: The Knight Capital error (2012)
Context: Knight Capital Group was a major market maker in US equities whose trading accounted for about 10 percent of all trading in listed US stocks. In August 2012, an operational deployment updated SMARS, the firm’s automated order-routing software, on seven of eight production servers but omitted the eighth (U.S. Securities and Exchange Commission 2013).
Mechanism: The deployment repurposed a binary feature flag that, on the un-updated eighth server, activated Power Peg, an obsolete order-handling routine that had been left in the code. On the stale server, Power Peg no longer counted how many shares of each incoming parent order had already been filled, so it kept sending smaller child orders to trading venues without stopping.
Impact: In about 45 minutes, 212 parent orders produced millions of child orders and more than 4 million executions in 154 stocks, covering more than 397 million shares, and Knight lost more than $460 million. Less than a year later, Knight’s parent company combined with GETCO Holding Company to form KCG Holdings.
Response: The incident motivates verifying that every production node runs the intended version before it receives traffic, explicit feature-flag lifecycle controls, and circuit breakers that limit the damage a faulty release can cause.
Systems lesson: One server running the wrong version was enough to cause a $460 million loss. ML deployments share this vulnerability: a model registry version mismatch, un-synchronized feature schemas, or partial canary routing can flood production with corrupted inference requests before telemetry alerts fire.
U.S. Securities and Exchange Commission. 2013. “Securities Exchange Act of 1934, Release No. 70694: Knight Capital Americas LLC.”
Knight Capital shows why every node must be verified to run the intended version before traffic reaches it. Each serving node therefore reports the content hash of the bundle it loaded, and the release pipeline compares that hash with the version the model registry promoted and keeps any node that disagrees out of rotation. Staged rollouts add a complementary protection by limiting how much traffic a bad version sees, but they can also expose load-dependent behavior.
When canary deployments reveal anomalies at elevated traffic shares (such as memory exhaustion, queue spillover, or p99 tail latency inflation appearing at 30 percent traffic that remained undetectable at 5 percent), isolation requires systematic debugging across the stack. Effective diagnosis requires correlating multiple signals: performance benchmarking metrics, data distribution analysis to detect drift, and feature importance shifts that might explain degradation. Teams maintain debug toolkits for this work, including A/B test analysis (section 14.4.3.2), feature attribution (section 14.7.1.2.3), and slice analyzers that identify which subpopulations are experiencing degraded performance (section 14.7.1.2.2). That diagnosis loop must connect directly to the release pipeline, because CI/CD integration automates deployment and rollback only when rollback is designed as part of the rollout mechanism rather than treated as an emergency script.
Rollback strategies and safety mechanisms
Without reliable rollback17 capability, teams become deployment-averse and slow their iteration velocity, so an effective rollback design plans for three distinct scenarios. The fastest tier, immediate rollback, addresses critical failures detected right after deployment, such as serving errors, latency spikes, or obvious prediction failures, keeping the previous model version loaded and warm to switch traffic without cold-start delay. Rapid rollback handles performance degradation detected through canary metrics soon after deployment and relies on model registry integration to redeploy previous versions with minimal configuration changes. Once a release has ramped to full traffic, delayed rollback addresses subtler regressions that surface later in business metrics or user feedback. Reverting there must also handle model-dependent data such as personalization state or cached embeddings accumulated under the new version. Table 9 summarizes implementation patterns for each rollback type:
17 Rollback (from database transaction management): This “undo” action for deployments is complicated in ML by model-dependent state (for example, cached embeddings), which may be incompatible between model versions. This mismatch can prolong recovery and contribute to deployment aversion and slower iteration.
| Rollback Type | Trigger | Implementation | State Handling |
|---|---|---|---|
| Immediate | Serving errors, crashes | Hot standby with fast routing switch | Verify state compatibility |
| Rapid | Canary metric degradation | Registry-based redeployment | Clear caches, restart sessions |
| Delayed | Business metric decline | Full redeployment with migration | Migrate state, replay if needed |
Rollback testing
Rollback procedures that have never been exercised often fail during an active incident, when cognitive load and time pressure are highest, because configuration dependencies, incompatible state, or unclear ownership only surface when a revert is actually attempted. Periodic rollback drills expose those gaps beforehand, while step-by-step runbooks ensure that the on-call responder can execute the revert without having designed the deployment. Automated rollback triggers shorten reaction time further, provided their thresholds are calibrated to the service with safeguards against flapping (a metric hovering near its threshold that rolls the service back and forward repeatedly) and the restored model is checked against live caches rather than serving predictions corrupted by incompatible feature state.
Stateful vs. stateless rollback
ML systems vary in statefulness, which directly governs rollback complexity. For stateless workloads like tabular classification and static regression, rollback requires only swapping model weights or routing traffic back to the prior container, because individual inferences share no execution context. In contrast, stateful models (including sequential recommenders, session-based search rankers, and conversational systems) accumulate transient user state. Reverting such workloads can demand session resets, schema shims for cached context vectors, or explicit state migration. Capturing versioned checkpoints at deployment boundaries mitigates this friction, but clean restoration remains an architectural property that requires empirical validation rather than assumption.
The ranking service is the stateful case. It precalculates dense user and item embeddings and holds them in low-latency caches, so if version 2 rotates the latent vector space or changes the embedding dimension, the cached vectors become meaningless to a rolled-back version 1. A stateful rollback must therefore redeploy the weights together with either an atomic cache invalidation or a namespace switch, in which each version’s cached vectors live under their own versioned key prefix (a namespace) and the rollback points lookups back to version 1’s prefix, so that no query is scored against an incompatible vector space. In systems with feedback loops, the most complex failure mode arises when bad predictions pollute downstream feature logs or clickstream training sets during the degraded window. Reverting the serving binary then leaves contaminated data in the retraining corpus, and that data must be expunged or quarantined before previous behavior is restored.
The compatible unit of rollback is larger than the weights. Figure 7 separates the bundle selected for a new request from the bundle retained by a request already in flight.
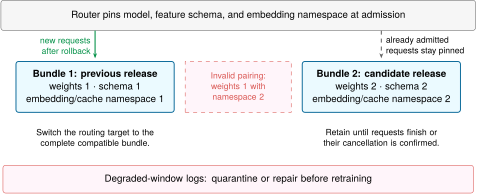
The router must select the compatible model, schema, and namespace as one decision at request admission. A cutover changes that decision for later requests; it does not migrate earlier requests into a different vector space. A single ranking request finishes in milliseconds, so for it the overlap is brief, but a session in a session-based ranker or a conversational system can stay pinned to one bundle for minutes. Keeping the candidate bundle available until those requests finish or their cancellation is confirmed preserves the contract during coexistence, while log quarantine addresses a separate repair obligation.
A/B testing for model validation
Rollback contains a release that degrades service health, and canary routing verifies that a candidate runs without errors or latency spikes, but neither check proves that the candidate improves user outcomes over the incumbent. A/B testing provides the statistical foundation for that promotion decision by comparing model versions on live traffic under controlled conditions, measuring whether the new model improves business metrics with statistical confidence.
Experiment setup and decision rules
A valid A/B test establishes four controls to ensure deployment decisions remain statistically sound. First, the randomization unit specifies whether traffic is split by user ID or individual request. User-level hashing preserves consistency across sessions at the expense of larger sample requirements, whereas request-level splitting maximizes sample throughput but risks exposing a single user to alternating model variants. Second, the required traffic volume follows from two probabilities that the team fixes in advance. Confidence is the probability that the test does not report a difference when none exists, and statistical power is the probability that it detects a real difference of the chosen size. Under a common-variance Normal approximation, which treats each variant’s average outcome as normally distributed with the same spread, let \(\RequiredUsersPerVariant\) be the required users per variant and \(\MinimumDetectableEffect\) the minimum detectable effect. Let \(\OutcomeStandardDeviation\) be the outcome standard deviation (for a conversion metric, each user’s outcome is a yes-or-no event, so \(\OutcomeStandardDeviation^2\) is the baseline conversion rate times one minus that rate). Let \(\ConfidenceCriticalQuantile\) and \(\PowerCriticalQuantile\) be the positive standard-Normal critical values for the chosen two-sided confidence and power. The worked scenario uses 95 percent confidence and 80 percent power. Equation 4 translates those design targets into required traffic before launch. \[\RequiredUsersPerVariant= \frac{2(\ConfidenceCriticalQuantile+ \PowerCriticalQuantile)^2 \OutcomeStandardDeviation^2}{\MinimumDetectableEffect^2} \tag{4}\] The equation’s form follows from sampling noise. The uncertainty of an average shrinks only with the square root of its sample size, so halving the minimum detectable effect quadruples the required traffic, and doubling the outcome standard deviation quadruples it too.
For a 2 percent relative lift on a 5 percent baseline conversion rate (5 percent to 5.1 percent) and 80 percent power, the experiment requires roughly 745,644 users per variant. If traffic limits the test to 25,000 users per variant instead, solving equation 4 for \(\MinimumDetectableEffect\) shows that the test can detect only a much larger lift, about 0.5 percentage points absolute.
Third, guardrail metrics define operational and behavioral boundaries that must not degrade even if the primary metric improves. A recommendation model improving click-through rate by 10 percent while increasing p99 response latency by 500 ms violates system guardrails and risks cascading timeouts across downstream services. Fourth, a fixed evaluation horizon runs the test until the preregistered sample size and a minimum duration covering weekly seasonality are reached. Stopping the moment significance first appears inflates false positive rates through repeated peeking; sequential designs permit early stopping but need specialized analysis.
Those controls establish the statistical envelope, yet ML systems add failure modes that ordinary web experiments can hide. Conversion events may arrive days after prediction, creating delayed feedback: a recommendation shown Monday can drive a purchase Friday, so the attribution window must be part of the test design. Novelty effects can also inflate early performance as users engage with fresh recommendations, which is why mature experiments include a burn-in period before measurement. Ranking systems add interference effects, because showing an item to one user can change what remains available to another, violating the independence assumption behind standard A/B analysis. Segment heterogeneity creates a further problem when an overall neutral result hides opposite effects in different cohorts. Guardrails, segment analysis, and preregistered decisions therefore belong to the experiment design, and table 10 turns those constraints into a deployment decision:
| Primary Metric | Guardrails | Decision |
|---|---|---|
| Significant improvement | All pass | Ship new model |
| Significant improvement | Some fail | Investigate trade-offs, may need model iteration |
| No significant change | All pass | Evidence inconclusive; retain current model unless a prespecified equivalence or noninferiority test supports the change |
| Significant degradation | N/A | Do not ship; investigate root cause |
The “no significant change” row needs care, because failing to detect a difference does not show that none exists. Two tests address that gap directly, each against a margin fixed in advance. A noninferiority test asks whether the candidate is worse than the incumbent by no more than that margin, and an equivalence test asks whether the difference in either direction stays inside it.
↩︎ The rule that nonsignificance never shows equivalence is established in Statistical and methodological issues.
Deng, Alex, Ya Xu, Ron Kohavi, and Toby Walker. 2013. “Improving the Sensitivity of Online Controlled Experiments by Utilizing Pre-Experiment Data.” Proceedings of the Sixth ACM International Conference on Web Search and Data Mining (WSDM), 123–32. https://doi.org/10.1145/2433396.2433413.
The decision matrix is reliable only when the evaluation methodology is preregistered before launch, establishing expected effect sizes, the randomization unit, attribution windows, guardrail thresholds, and minimum runtimes prior to observing production traffic. Variance-reduction techniques (Deng et al. 2013) can shorten an experiment without sacrificing power. Automated analysis pipelines protect the decision boundary from manual calculation errors, and archiving negative results discourages repeating unproductive architectures. An A/B deployment decision is actionable only when the release machinery can promote, hold, or roll back the exact artifact that was evaluated, which is the guarantee the model registry of section 14.3.1.2 provides.
14.4.4 Edge AI deployment
The keyword spotter needs the same two operational guarantees, controlled rollout and fast rollback, on devices with limited power, memory, and connectivity. Consider it after its detection drop. When its model degrades, an engineer cannot SSH into the device, roll back to a previous version, and restart. The device sits in someone’s home on intermittent Wi-Fi, and its 200 KB model shares 4 MB of flash with the firmware that runs it. Every operational assumption from cloud MLOps (instant rollback, centralized logging, real-time monitoring) must be reimagined.
Edge AI runs machine learning inference at or near the data source rather than in centralized cloud infrastructure (Reddi et al. 2019), and its operations inherit the memory and power envelopes that separate the deployment tiers (TinyML: Ubiquitous Sensing). A model reaches an edge device already quantized, pruned, or distilled to fit those envelopes (Warden and Situnayake 2020; David et al. 2021), and on microcontrollers (TinyML) it runs on specialized engines such as TensorFlow Lite Micro and CMSIS-NN (Lai et al. 2018). Power budgets across edge devices span about four orders of magnitude, from milliwatts for sensors through watts for gateways to tens of watts in automotive systems. A deployment splits work across three tiers of its own, from the device up to the cloud: sensor-level microcontrollers at 1–100 mW filter and detect, gateways at 1–10 W run heavier inference, and the cloud distributes models and retrains. Latency-critical decisions stay local while expensive work moves upward.
Reddi, Vijay Janapa, Christine Cheng, David Kanter, Peter Mattson, Guenther Schmuelling, Carole-Jean Wu, Brian Anderson, et al. 2019. “MLPerf Inference Benchmark.” 2020 ACM/IEEE 47th Annual International Symposium on Computer Architecture (ISCA), 446–59. https://doi.org/10.1109/isca45697.2020.00045.
Warden, Pete, and Daniel Situnayake. 2020. TinyML: Machine Learning with TensorFlow Lite on Arduino and Ultra-Low-Power Microcontrollers. O’Reilly Media.
David, Robert, Jared Duke, Advait Jain, Vijay Janapa Reddi, Nat Jeffries, Jian Li, Nick Kreeger, et al. 2021. “TensorFlow Lite Micro: Embedded Machine Learning for TinyML Systems.” Proceedings of Machine Learning and Systems 3: 800–811.
Lai, Liangzhen, Naveen Suda, and Vikas Chandra. 2018. “CMSIS-NN: Efficient Neural Network Kernels for Arm Cortex-M CPUs.” ArXiv Preprint abs/1801.06601.
Every operational control must fit inside the tier that runs it. An update shares flash with the running model, telemetry competes with the radio’s energy budget, and a failed release must recover without a technician. Safety-critical real-time targets also add worst-case execution time (WCET) analysis, which bounds the longest a single inference can take, to the release criteria, because thermal throttling and memory contention can push inference past a deadline that average latency never reveals.
↩︎ The quantization, pruning, and knowledge-distillation techniques that edge deployment relies on are established in Model Compression.
Power budgets across the three edge tiers span about four orders of magnitude.
OTA model updates are how operations reaches physically inaccessible devices. OTA pipelines need secure model distribution, artifact verification, and rollback mechanisms; delta or differential updates can reduce transfer volume when devices need not receive a complete model artifact. The keyword spotter’s fail-safe OTA design uses dual-bank flash memory, a pattern common on microcontroller and embedded targets. The device keeps running from Bank A while it writes the candidate model and runtime to Bank B. After switching to Bank B, a hardware watchdog timer and a post-update self-test supervise the first inferences. If the new model triggers memory faults, hangs, or violates latency budgets, the bootloader automatically reverts execution to Bank A, preventing physically inaccessible devices from being bricked. Update scheduling must account for device connectivity patterns, power availability, and operational criticality.
Monitoring and tier coordination must fit inside the same power and bandwidth budgets. Because continuous streaming would drain the battery, lightweight telemetry reports compact operational counters (inference latency, power draw, and accuracy indicators) alongside device-level health signals (thermal status, battery levels, and connectivity quality) that predict maintenance needs before a node fails. When local load or link quality shifts, edge-cloud coordination can offload heavier inference to a gateway where feature caching avoids redundant computation. Federated learning lets edge devices contribute model updates rather than raw training records, and Technical privacy protection methods develops the privacy protections those updates still need.
Graceful degradation is a core operational pattern for edge AI. When thermal limits or battery depletion constrain hardware capacity, edge runtimes must dynamically shed load (downsampling input sample rates, skipping optional processing stages, or falling back to shallow heuristic models) within a fallback policy validated for the application’s safety and quality requirements.
14.4.5 Memory and compute of release controls
Every control in this section keeps a second version of the model alive, and for a capacity-bound model that second version, not the extra arithmetic, is the dominant cost (table 11). A shadow deployment scores every request twice. A canary, an A/B test, and a blue-green switch divert traffic rather than adding work, yet each must hold the candidate’s full embedding tables in accelerator memory whatever share of traffic it serves, because any request in that share can look up any row of those tables. A hot standby for immediate rollback holds the previous version for the same reason. The ranking service’s 5 percent canary therefore doubles the accelerators that hold tables, from 2 to 4, while it carries a twentieth of the requests. A compute-bound ResNet-50 service pays the opposite way. Its 51.1 MB of FP16 weights fit beside the serving copy on one accelerator, so its canary costs almost no memory and only its share of compute. The keyword spotter’s dual-bank update costs flash instead of accelerator memory, a second 200 KB bank that brings the model’s share of the device’s 4 MB to 400 KB.
| Release control | Extra resident memory | Extra inference work | What it buys |
|---|---|---|---|
| Shadow deployment | Second copy of the tables (100 GB); 2 \(\rightarrow\) 4 H100s | Every request scored twice | Output and latency comparison with no user exposure |
| Canary (5% of traffic) | Second copy; 2 \(\rightarrow\) 4 H100s | None; a share of requests is diverted | Live quality evidence on a bounded share of users |
| A/B test | Second copy; 2 \(\rightarrow\) 4 H100s | None; traffic is split between variants | A statistically valid outcome comparison |
| Blue-green switch | Full second environment; 2 \(\rightarrow\) 4 H100s | Duplicate provisioned capacity during the switch | Rollback by a single routing change |
| Hot standby | Previous version resident; 2 \(\rightarrow\) 4 H100s | None until rollback | Immediate rollback without a cold start |
| KWS dual-bank update | Second flash bank (200 KB in 4 MB of flash) | None | Automatic revert after a failed update |
Checkpoint 14.2: Evidence for a release
Infrastructure as code, compiled-artifact validation, and staged rollout with reserved rollback capacity ensure that the exact model validated offline reaches production safely and can be reverted quickly if the release fails. Once a candidate passes its rollout window, however, those release gates have finished their job and no longer watch how the promoted model behaves over the weeks that follow.
Self-Check: Question
An engineering team needs to evaluate the live inference latency, resource consumption, and numerical output distribution of a new deep recommender against live production traffic without exposing users to potential prediction quality regressions. Which deployment pattern should they select?
- Canary deployment, routing 5% of user-facing production traffic directly to the candidate model
- Blue-green deployment, performing an immediate router-level cutover of 100% of user traffic
- Shadow deployment, asynchronously duplicating live production traffic to the candidate model while returning only the incumbent model’s predictions to users
- In-place deployment, updating the model weights directly on active production inference servers
A two-tower recommender caches precomputed user and item embeddings. Model v2 changed the embedding dimension, and after a regression the team rolls back to v1 by redeploying v1’s weights. Explain why this rollback can still fail, and state what a stateful rollback procedure must include.
True or False: Once an INT8-converted model passes numerical-equivalence tests against the original, upgrading the inference runtime by a minor version needs no revalidation, because the model weights have not changed.
14.5 Production Monitoring
A newly promoted ranking model can pass its canary check on Monday, only to lose five points of accuracy by Thursday when an upstream catalog migration or a competitor’s promotion alters live user traffic while every HTTP and GPU gauge stays green. A deployed model loses accuracy at a rate that must be measured rather than assumed. Every decision left in the operations loop (retrain, roll back, or wait) rests on evidence that only production monitoring can supply, including the decay rate that the retraining economics of section 14.6 must fit. An ML service is correct only while its live inputs resemble the data it learned from, so as they change (the silent degradation of When ML Systems Fail Silently), predictive quality may decline. Monitoring is the detect step of the operations loop and the production-monitoring interface at work, and it makes that risk observable. Paired with staged rollout, input and outcome monitoring lets teams investigate a failing version and limit its impact while the evidence accumulates.
14.5.1 Infrastructure telemetry and hardware utilization
When an on-call engineer is paged for a p99 latency spike on the ranking service, a single GPU busy-time gauge cannot say what the accelerator is doing. It may be saturated with math, stalled on embedding-table memory gathers, throttling its clocks from heat, or sitting idle while a host thread waits on the feature store. In production, serving failures span immediate hardware or request-path bottlenecks as well as gradual distributional drift. Disentangling them requires two distinct telemetry layers. Infrastructure metrics reveal whether the serving system itself is compute-, memory-, or I/O-bound, and statistical and outcome metrics track whether the predictions remain accurate.
The first layer, infrastructure-level monitoring, tracks CPU and GPU activity, memory bandwidth, disk consumption, network latency, and service availability. Because a single utilization counter cannot separate arithmetic saturation from memory or host-pipeline stalls, operators correlate kernel execution times with memory bandwidth utilization and input-pipeline queue depths across the node.
Power-efficiency metrics (such as inferences per joule or FLOP/s/W, depending on workload) add a cost-normalized view that enables mixed-workload scheduling. Thermal monitoring similarly informs operational scheduling, particularly under sustained high load where thermal throttling forces hardware clocks down, introducing tail-latency spikes that violate SLOs. An MLOps telemetry pipeline incorporates thermal headroom metrics to steer traffic across available accelerators before throttling occurs. Time-series engines such as Prometheus18 (Cloud Native Computing Foundation 2024b), Grafana (Labs 2024), and Elastic (Elastic NV 2024) collect and visualize these operational metrics across the serving fleet.
18 Prometheus: Prometheus periodically scrapes targets and stores time series for aggregation. Scrape and rule-evaluation intervals jointly affect alert latency and may miss short excursions. Monitoring per-accelerator thermals allows precise workload routing at higher data cost, while server-level aggregates can mask component-level throttling.
Cloud Native Computing Foundation. 2024b. Prometheus: Monitoring System and Time Series Database.
Labs, Grafana. 2024. Grafana.
Elastic NV. 2024. Elasticsearch: Distributed Search and Analytics Engine.
Hardware counters locate a bottleneck inside the accelerator, but a latency regression often originates elsewhere on the request path. Request scheduling, batching, and runtime selection belong to the serving system, and The latency budget shows that model inference is only one slice of end-to-end latency, and often not the largest (principle 12). Operations uses that decomposition as a diagnostic instrument. When p99 regresses, per-stage timings for network, feature retrieval, parsing, inference, and serialization tell the on-call engineer which stage moved, and therefore which fix and which team the incident needs. Without stage-level tracing, every latency regression looks like a model problem, and the reflexive responses of rolling back or quantizing further cannot recover time lost in a feature store or a network hop (principle 8).
The serving endpoint contributes two of those stages, parsing and serialization, and its capacity model adds a third when it scales to zero. Protocol and serialization costs are developed in Interface protocols and serialization, and the cold start that scale-to-zero capacity pays after every idle period in Cold start and initialization dynamics. Operations inherits both as stages to trace, so that a regression in either is not mistaken for a model problem.
Hardware utilization patterns
Even when stage-level tracing isolates a slowdown to the model-inference stage, coarse hardware gauges can mislead. Standard administrative GPU utilization metrics, such as the reading from nvidia-smi, report the fraction of time a kernel is executing rather than the fraction of peak arithmetic throughput achieved. Identifying Bottlenecks draws this distinction between busy time and model FLOPs utilization (MFU). The ranking service’s gathers of non-contiguous embedding vectors can therefore hold a high utilization reading while every resident warp stalls on memory, and a green gauge on the operations dashboard says nothing about compute efficiency.
↩︎ The analytical model separating compute-bound execution from memory-bandwidth saturation across arithmetic intensities is established in Performance Bounds.
Distinguishing compute execution from memory or pipeline stalls requires measuring achieved arithmetic throughput alongside memory bandwidth and I/O saturation. Table 12 gives illustrative screening patterns. Here GPU utilization is kernel-active time; measured FLOP rate, execution traces, and relevant stall counters are needed to test the proposed bottleneck:
| Pattern | GPU Util | Memory bandwidth util. | Optimization Strategy |
|---|---|---|---|
| Possible compute limit | >85% | <70% | Check achieved FLOP rate; evaluate faster kernels or compute capacity |
| Possible bandwidth limit | 50–85% | >85% | Check traffic and stalls; evaluate quantization or memory access |
| Possible input limit | <50% | <50% | Trace input starvation before changing prefetch or storage |
| Batch-starved | Variable (spiky) | Variable | Dynamic batching, request queuing on single server |
Each candidate maps to a term of the iron law of ML systems (principle 3), which writes execution time as a memory term, a compute term, and a fixed latency overhead. The compute-bound signature points to the compute term \(\Operations/(\PeakRate \cdot \EfficiencyHw)\), the memory-bound signature points to the memory term \(\DataVolume/\Bandwidth\), and low utilization of both points to the data pipeline, so the trace and counters guide which term to investigate when a latency SLO is violated (Acting on the limiting term maps each symptom to its dominant D·A·M term and identifies which optimizations move the limiting constraint).
Utilization targets differ by workload. Batch training and batch (static) inference, which tolerates queuing and offline scheduling, can run above 80 to 85 percent kernel-active time while the team measures useful throughput. Online inference instead targets 50–70 percent of measured sustainable capacity at median load, holding back headroom so that bursts do not cascade into p99 timeouts (Queuing Theory). These figures are diagnostic starting points rather than thresholds, because kernel-active time and demand relative to capacity have different denominators. For large language model (LLM) serving, KV-cache utilization on each node, the per-request store of past attention state, is an equally important capacity-planning signal. It matters because near the limit, the scheduler must queue or reject requests, shrink batches, or shorten the admissible context (Memory and KV cache sizes and schedules the cache).
Utilization and memory telemetry also feed the number the business sees. Cost per inference, the hourly accelerator bill divided by sustained throughput, is defined and worked out in Cost per inference across hardware. Operationally, it belongs on the same dashboard as the utilization signatures in table 12, because a rising cost per thousand inferences at constant pricing is often the first visible symptom of efficiency erosion (smaller effective batches, a shift in traffic mix, or a regression that stays inside the latency SLO).
Alerts convert these signals into intervention before silent degradation reaches downstream consumers. Infrastructure alerts signal memory saturation, thermal throttling, or degraded network throughput, while a sustained drop in model quality triggers drift investigation. The latency of these alerts governs the window of undetected failure, and each alert must record the model version, affected input subpopulation, and triggering aggregation window so responders can isolate and reproduce the failure state.
Example 14.2: Recommendation monitoring at scale
Scenario: Consider the ranking service at high throughput, its latency within the SLO while recommendation quality declined as user behavior changed.
Diagnosis: Traditional infrastructure metrics (CPU utilization, HTTP error rates) remained green while cohort-level CTR fell. CTR counts how often users click what they are shown, whereas the ranking service’s click-prediction accuracy scores each prediction against whether its item was actually clicked. The engagement decline therefore motivates investigation of traffic, feature pipelines, and ranking behavior; it does not establish classification accuracy loss.
Systems lesson: Infrastructure telemetry alone cannot establish recommendation quality. Cohort-level outcome tracking exposes localized engagement changes, while matched comparisons and mature labels are needed to assess predictive-quality changes and their causes.
14.5.2 Statistical monitoring and drift detection
Even when GPU utilization, memory bandwidth, and stage-level latency sit comfortably inside their operating bands, a model can still return systematically wrong predictions, because live user inputs may drift away from the training distribution. The reverse error also occurs, when incomplete outcome data make a healthy model look wrong. Infrastructure telemetry shows how the serving hardware behaves; statistical monitoring shows whether the model’s predictions remain correct by tracking evaluation metrics such as accuracy, precision, recall, and confusion matrix shifts (changes in how often each true class is predicted as each other class) (scikit-learn developers 2024) across live prediction streams. Unit tests can verify deterministic components but cannot by themselves establish population-level predictive performance, which must be estimated statistically. Monitoring implements observable degradation (section 14.1.1), transforming this theoretical limitation into operational practice. Without continuous statistical monitoring and the deeper observability it enables (the ability to infer internal state from outputs), teams lack the evidence needed to distinguish a healthy model from an unobserved regression.
scikit-learn developers. 2024. Sklearn.metrics.confusion_matrix — Scikit-Learn Documentation. Scikit-learn Documentation.
Those quality metrics require joining predictions to outcomes under a fixed evaluation horizon. Consider a conversion model whose prediction log records a request identifier, prediction time, score, and the immutable version actually served. The outcome log records the same identifier, event time, and observation time. For an older request served by the previous version, a purchase event within the horizon supplies a positive label once observed; a completed observation window with no purchase supplies a negative label, provided outcome collection is complete. A recent request served by the candidate with no recorded purchase remains pending until its horizon and the permitted reporting delay have elapsed. The absence of a purchase record while that window is open is unknown, not a negative outcome. Joining by identifier and retaining the served version attributes each completed outcome to the model that made the prediction rather than to whichever model is deployed when the label arrives.
A quality comparison groups predictions by serving period and version, then evaluates cohorts whose outcome windows have matured under the same horizon and reporting policy, with comparable traffic conditions. Each metric and slice must report label coverage, the fraction of eligible predictions with resolved outcomes. An apparent drop caused by comparing the candidate’s pending outcomes with the previous version’s completed outcomes does not justify retraining; it calls for completing the window or repairing outcome collection. Even a mature window can contain selective labels, outcomes that exist only for the cases the system chose to act on, such as clicks recorded only for recommendations that were shown or fraud verdicts only for transactions that were reviewed. Coverage and collection-policy checks must accompany uncertainty estimates before a quality regression supports diagnosis and a retraining decision.
A mature, well-covered quality metric can still hide a slow decline, because gradual long-term degradation evades coarse detection thresholds. Small day-to-day changes in a quality metric compound into material degradation over a year without tripping monthly alerts. Seasonal patterns compound this complexity; a model trained in summer may perform well through autumn but fail in winter conditions it never observed. Detecting such gradual degradation requires multi-timescale monitoring: performance baselines across multiple time horizons (daily, weekly, quarterly), sliding window comparisons that detect slow trends, and seasonal profiles that account for cyclical variation.
Statistical monitoring has to separate two axes of distribution shift,19 because they differ in what a monitor can observe without ground-truth labels. The three kinds of shift defined for the data pipeline in Data drift detection and response, where the keyword spotter’s microphone change is the worked case, fall on those two axes. The first axis is data drift, which combines covariate shift and label shift. Covariate shift20 changes the input distribution \(\InputDistribution\) while the relationship between inputs and labels, \(\ConditionalDistribution\), stays stable. Label shift changes how often each label occurs while the inputs typical of each label stay the same. Both reach live traffic as a changed input mix or a changed distribution of predicted scores, so both can usually be detected without labels.
19 Label-free vs. label-dependent detection: A change in \(\InputDistribution\), or in the model’s prediction distribution, can be estimated from sufficient samples without labels, although detection is not immediate. Concept drift generally requires labeled outcomes, which in high-stakes domains (medical diagnosis, fraud detection, legal decisions) can take days, weeks, or months. Proxy metrics such as prediction-confidence distributions and output entropy can provide imperfect early warnings that trade false-alarm rate for detection speed.
20 Covariate shift: Reweighting training examples to correct for covariate shift assumes that every deployment input could have appeared in training, just with different probability. When deployment contains genuinely out-of-distribution inputs (new product categories, new demographics, adversarial inputs), the correction can fail and the model can produce confidently wrong outputs with no warning signal. That coverage is the hidden assumption that determines whether drift correction or full retraining may be required.
Concept drift, a change in the input-label relationship \(\ConditionalDistribution\) beyond what changed label frequencies explain, forms the second axis. If fraudsters begin making transactions that look like ordinary purchases, the same input now has a different correct answer. When the meaning of the same input changes in this way, the input and prediction distributions can remain unchanged while the predictions themselves grow wrong, so detecting concept drift requires labeled outcomes. The degradation equation (equation 1.1) compares \(\TrainingDistribution\) and \(\CurrentDistribution\), the training-time and serving-time measurements of the data distribution in which these shifts appear.
Operations adds one distinction that the definitions alone do not make. Model decay is the observed decline in prediction quality over time while the model code stays unchanged, and data drift is only one possible cause of it, alongside concept drift and changes in the surrounding pipeline. Monitoring model outputs alone can miss input drift or mistake a benign output change for quality loss, so operations also tracks the input feature statistics behind the divergence \(\StatisticalDivergence\), using the distance measures of feature distribution monitoring (section 14.5.2.1.2). These statistics can warn earlier than labeled performance because ground-truth feedback is often delayed.
The signature of data drift in live telemetry is a feature distribution that moves in step with a quality metric, and three synchronized telemetry tiers aligned over time expose how covariate shift erodes model performance (figure 8). Across the top panel, discrete request samples transition from predominantly green (online sales) to orange (in-store sales). The figure’s “online store” and “offline store” labels name sales channels, not the feature-store tiers of section 14.3.1.1. The middle panel charts this shift as an expanding offline area in the sales_channel feature distribution, directly matching the steep decline of the model accuracy curve in the bottom panel. This temporal alignment motivates comparing input feature distributions with outcome metrics; their co-movement supplies a diagnostic hypothesis rather than establishing the cause by itself.
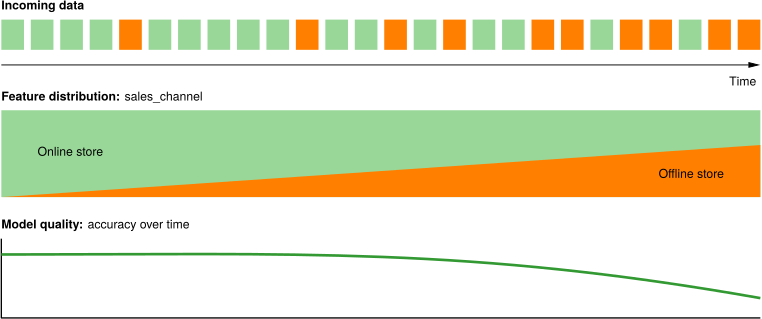
The drift detection delay, how quickly a statistical test can confirm that predictive quality has degraded, limits statistical monitoring. The speed of confirmation is governed by sample arrival rates and statistical power requirements. Low-traffic services may wait days or weeks to accumulate enough labeled outcomes to distinguish genuine performance erosion from stochastic noise. No tooling removes this gap, because a change cannot be confirmed faster than labeled examples arrive. Monitoring architectures must therefore keep the two axes apart. Data drift can be estimated from sufficient unlabeled samples, while concept drift generally requires labeled outcomes. Neither statistical estimate is instantaneous.
Drift detection speed is bounded by the sample rate.
Napkin Math 14.2: The drift detection delay
Problem: A 95 percent-accurate model may fall by 5 percentage-point. The monitoring policy budgets 1,000 labeled examples. A power calculation of the same kind as equation 4 sets the minimum such a test needs. The budget is a policy choice above that floor, adding margin for label noise, dependence between outcomes, and per-slice checks. Calculate the collection duration required across high-rate and low-rate arrival scenarios.
Math:
- Evidence budget: 1,000 labeled examples.
- High-rate case: At 1 labeled outcome per second, collection takes 1,000 seconds ≈ 16.7 minutes.
- Low-rate case: At 100 labeled outcomes per day, collection takes 10 days.
Systems insight: Detection is bounded by labeled-outcome arrival, which may lag far behind traffic. Low-volume or delayed-label domains may need days or weeks, so high-stakes systems supplement statistical monitoring with proactive model audits.
Detection delay has a direct cost. When a silent failure persists until the next review, every day of delay is lost revenue, which is the economic case for automated drift detection.
Napkin Math 14.3: The cost of silent failures
Problem: Is building an automated drift detection system worth the engineering effort?
Scenario: Consider a product recommendation engine generating $50M in annual revenue. Failure mode: A deployment bug causes training-serving skew, dropping recommendation quality by 5 percent. This degrades conversion rate proportionally.
Assumptions: The incident begins immediately after a scheduled check, remains detectable at the next check, and ends with an effective repair immediately after detection. The calculation therefore compares nearly full review-interval delays, rather than expected detection times for incidents arriving throughout an interval. It excludes label delay and diagnosis or recovery time.
Cost analysis:
- Manual ops (monthly review):
- Detection time: ~4 weeks (28 days).
- Revenue loss: $50M \(\times\) 0.05 \(\times\) 28 days/365 days ≈ $191,781.
- Automated MLOps (daily checks):
- Detection time: 1 day.
- Revenue loss: $50M \(\times\) 0.05 \(\times\) 1 day/365 days ≈ $6,849.
Systems insight: Under these timing and recovery assumptions, a single silent failure costs $184,932 more with monthly review. Across this scenario’s 4 incidents/year, daily checks avoid nearly $739,726 in annual loss. An operational budget must instead use the measured time from incident onset to effective recovery, including evidence collection, diagnosis, and mitigation. An earlier alert saves money only when it enables an earlier reduction in harm.
Data quality monitoring
Waiting for labels is not the only option, because many silent failures begin as defects in the inputs themselves and can be caught at the input boundary before a prediction is served. Drift statistics reveal shifted inputs, while outcome metrics establish whether prediction quality has declined, yet by the time downstream business metrics degrade, upstream data corruption may have persisted for days or weeks. Data quality monitoring exposes these input defects before inference occurs, while output and outcome monitoring confirm whether distributional shifts impair prediction accuracy. The first input guardrail is executable validation: listing 3 illustrates schema expectations that reject malformed batches before inference, turning implicit data assumptions into enforceable checks.
schema.require_column("user_id")
schema.require_type("timestamp", "datetime")
schema.require_non_null("feature_a")

schema.require_range("age", min_value=0, max_value=120)
schema.require_mean_between(
    "purchase_amount", min_value=10, max_value=1000
)
Input data validation
Schema validation21 catches structural defects at ingest time. These checks enforce column existence, strict data typing, null-value limits, and numerical boundary invariants.
21 Schema validation: The rules in listing 3 prevent silent data contract violations, such as a feature column changing from an integer to a float. Without this input-level guardrail, downstream model monitoring cannot distinguish a data quality error from a true performance regression, masking the root cause. A schema mismatch in a critical feature can invalidate an otherwise well-formed prediction batch.
Feature distribution monitoring
Schema validation catches structural corruption (missing columns, wrong types, null values) but cannot detect the subtler failure mode where data arrives in the correct format but from a shifted distribution. A feature representing user age can pass every schema check while its mean silently migrates from 32 to 45 over three months as marketing attracts an older demographic. This distributional shift can change model accuracy without producing a structural anomaly; labeled outcomes are needed to determine its effect.
Statistical distance measures quantify this divergence by comparing serving distributions against training baselines, and four are common. The population stability index (PSI)22 suits categorical and binned features, and the Kolmogorov-Smirnov (KS) statistic of the CI/CD distribution screen suits continuous ones. Jensen-Shannon divergence gives a symmetric, bounded comparison of probability distributions, and the Wasserstein distance, also called earth mover’s distance, measures the probability mass that must move, and how far, to turn one distribution into the other. Each needs an alert threshold, and sample size makes that choice harder than it looks.
22 PSI: PSI is widely used in credit-risk scorecard monitoring to compare expected and observed binned populations; Yurdakul and Naranjo analyze its statistical properties (Yurdakul and Naranjo 2020). The common 0.1 and 0.25 bands are useful operational conventions, not universal statistical laws. ML operations adopted PSI because it works on binned categorical or continuous features and provides an interpretable drift score that non-specialists can review.
Yurdakul, Bilal, and Joshua Naranjo. 2020. “Statistical Properties of the Population Stability Index.” The Journal of Risk Model Validation 52. https://doi.org/10.21314/jrmv.2020.227.
Applying those distance measures one feature at a time has a structural blind spot, because feature-by-feature comparisons can miss changes in how inputs occur together. Consider two binary sensor flags. In the training population, equal groups have both flags off or both on; in the serving population, equal groups have one flag on and the other off. Each flag is still equally often on and off, so its individual histogram is unchanged, but the relationship between flags has reversed. Even perfect training-serving feature parity would not detect this population change. Monitoring selected feature combinations, relevant cohorts, or a joint-distribution statistic complements marginal screens; labeled outcomes are still needed to determine whether the change harms predictions.
Whether a monitor tracks marginal features or joint cohorts, setting its alert threshold runs into the sample-size sensitivity noted earlier. In high-throughput production monitoring, statistical significance alone is an inadequate alert policy. With large samples, tests such as the two-sample KS test or the chi-square test (the standard test for differences in categorical frequencies) can detect small genuine differences that have little operational significance. The mechanism is the sample-size term in the test’s critical value. The KS critical value \(\KolmogorovSmirnovCriticalThreshold\) used in the data pipeline’s drift test (Quality through validation and monitoring) scales with \(\sqrt{(\DriftTestSampleSize_0 + \DriftTestSampleSize_t)/(\DriftTestSampleSize_0 \DriftTestSampleSize_t)}\), so it shrinks roughly as \(1/\sqrt{\DriftTestSampleSize}\). A monitor that compares millions of serving requests against a large training sample therefore rejects equality for shifts far smaller than the 0.1 threshold of listing 2. These detections are not necessarily statistical false positives, but paging on each one creates unnecessary alerts. Conversely, small-sample edge telemetry may lack power to detect a meaningful change. Monitoring must consider effect size, sampling uncertainty, and the cost of missed change together.
Production monitoring therefore combines distribution-distance measures with uncertainty and operational thresholds. The population stability index that Data drift detection and response defined for the data pipeline, a symmetric version of KL divergence computed over \(\PopulationStabilityBinCount\) fixed bins of expected (training) and actual (serving) proportions, is a common choice. Operations adds what the definition leaves open, the response, by turning the conventional scorecard bands into an escalation policy. An illustrative policy has three bands:
- \(\text{PSI} < 0.1\): Below this policy’s warning threshold; continue monitoring outcomes and critical slices.
- \(0.1 \le \text{PSI} < 0.25\): Warning range; investigate population changes and upstream pipeline behavior.
- \(\text{PSI} \ge 0.25\): Escalation range; notify the owning team under the service’s calibrated severity policy. Diagnosis determines whether intervention is needed.
Production monitors require a documented zero-bin policy, such as Laplace smoothing (adding a small count to every bin), because any empty bin in the denominator yields an undefined logarithm, and they must preserve fixed bin boundaries across comparison periods. PSI is a drift signal, not an automatic retraining trigger, because divergence alone does not establish that accuracy has changed (principle 10). Every threshold, whether a PSI band or a KS cutoff, must be calibrated per feature against sample size and the cost of missed drift, because a shift that is plainly visible on a histogram can still produce a small aggregate score.
The ranking service monitors user age as an input feature, and a shift toward older cohorts produces the bin-by-bin PSI decomposition shown in table 13:
| Age Bin | Training | Serving | Difference | ln(Serving/Training) | Contribution |
|---|---|---|---|---|---|
| 18–25 | 15% | 12% | -0.03 | -0.223 | 0.0067 |
| 26–35 | 25% | 22% | -0.03 | -0.128 | 0.0038 |
| 36–45 | 20% | 18% | -0.02 | -0.105 | 0.0021 |
| 46–55 | 18% | 20% | +0.02 | +0.105 | 0.0021 |
| 56–65 | 12% | 15% | +0.03 | +0.223 | 0.0067 |
| 66+ | 10% | 13% | +0.03 | +0.262 | 0.0079 |
Summing the six bin contributions yields a total PSI of 0.029. The difference column is in proportion units, so a 3 percentage-point shift appears as \(\pm 0.03\). Whenever a bin’s serving share falls below its training share, both the difference and the log-ratio are negative, so their product remains positive and opposite shifts across age bins cannot cancel each other out. Even with 3 percentage-point shifts in several bins, the aggregate drift is well below the 0.1 warning threshold. Operational action depends on a calibrated threshold, sample size, and business cost.
↪ KL divergence, its asymmetry, and a worked drift example that computes both KL divergence and PSI are collected for reference in Measuring drift.
Data freshness monitoring
Distribution-distance checks catch values that shift, but a frozen upstream pipeline can keep serving valid, in-distribution values that are out of date. Feature stores and data pipelines can become stale without triggering obvious errors. Data freshness monitoring catches that failure mode, and listing 4 shows a configuration that monitors feature freshness and triggers fallback behavior when data becomes stale.
user_purchase_history feature for staleness, alerting operations teams via PagerDuty and Slack and falling back to default values when the feature exceeds the maximum allowed age.
# Example freshness alert configuration
feature: user_purchase_history
max_staleness: 6h
alert_channels: [pagerduty, slack]
on_stale:
  action: fallback_to_default
  default_value: []
A freshness policy turns staleness from a silent data defect into an explicit fallback. The same pairing of a detector with a response must cover every layer of the monitoring stack, including the upstream dependencies feeding the ML system: database replication lag, feature-store ingestion watermarks, and pipeline completion status. In an illustrative incident, a recommendation service detected a material shift in its user_lifetime_value feature within two days, tracing the anomaly to a database migration that silently altered an aggregation window. Without input-layer distribution monitoring, such upstream corruption degrades model predictions for weeks before ground-truth outcome metrics expose the failure.
14.5.3 Monitoring cost model
Every layer of that stack costs money to run, and the first cost is the telemetry itself. Collecting these signals at production scale introduces severe network and storage constraints, because capturing uncompressed telemetry for every request can saturate the very networking fabric that serves the model. These overheads force a deliberate trade-off between monitoring granularity and infrastructure operating expense.
Napkin Math 14.4: The economics of observability
Trade-off: “Measure everything” is economically infeasible at scale. Let \(\TelemetrySeriesCount\) be the expanded series count, the number of distinct time series once each combination of label values (model version, region, user segment) is counted as its own series, \(\TelemetrySamplingFrequency\) the sampling frequency per series, \(\SampleStorageSize\) the bytes per sample, and \(\TelemetryRetentionDuration\) the retention duration. Here \(\IngestionPricePerSample\) and \(\StorageCapacityPrice\) are provider-specific ingestion and storage prices. Equation 5 combines these terms into an operating cost rate: \[ \text{Cost rate} \approx \TelemetrySeriesCount \TelemetrySamplingFrequency\left(\IngestionPricePerSample+ \SampleStorageSize \TelemetryRetentionDuration \StorageCapacityPrice\right) \tag{5}\]
Table 14: Trace Sampling vs. Observability Cost: Retaining one in 60 request traces yields a 60× data-volume difference at 1M req/s, assuming 1 KB per request. Batch intervals do not cause the reduction.
The product is an operating cost rate, not a one-time setup cost.
The full-fidelity and sampled data volumes both follow from the same two-step arithmetic. At full fidelity, every request’s telemetry enters the stream: 1M req/s \(\times\) 1 KB per request = 1 GB/s. Retaining one in 60 request traces reduces average ingest to 16.7 MB/s; batching sampled traces every 60 s changes delivery timing, not the average byte rate. Table 14 places the two regimes side by side with their cost impact.
| Sampling | Granularity | Data Volume (1M req/s) | Cost Impact |
|---|---|---|---|
| All traces | Micro-bursts | ~1 GB/s | High (Requires dedicated cluster) |
| 1-in-60 traces | Trends | ~16.7 MB/s | Lower (Policy-dependent) |
Systems insight: Sample by outcome rather than uniformly. The worked case keeps one trace in 60 regardless of outcome; a production policy keeps 100 percent of errors and only 1 percent of successful requests, because errors are rare and carry most of the diagnostic signal. Monitor aggregate counters every 1 s and compact approximate summaries (sketches) of high-cardinality labels, those with many distinct values such as user IDs, every 60 s. The cost components below turn these choices into a monthly budget for one node.
Sampling policy alone moves telemetry volume by 60× (notebook 14.4), and equation 5 prices the ingestion and storage of that volume. A complete budget must also price dashboard queries and alert evaluation, and then weigh the total against the incidents that monitoring prevents.
Cost components
Monitoring costs break down into four categories. Equation 6 keeps ingestion and storage, the two terms of equation 5, as separate lines and adds the two new ones: \[\text{Monitoring Cost} = \MonitoringIngestionCost+ \MonitoringStorageCost+ \MonitoringComputeCost+ \MonitoringAlertCost \tag{6}\]
The four \(\MonitoringCostComponent\) terms are cost components over the same accounting window: data ingestion, retained storage, query or dashboard compute, and alert-rule evaluation. Separating them matters because each scales with a different control knob. Table 15 provides representative unit-cost assumptions for each component, and translating these unit costs into a concrete budget estimate clarifies the real expense of monitoring even a single production model:
| Component | Illustrative Unit Cost | Scaling Factor |
|---|---|---|
| Metric Ingestion | $0.10–0.50 per million data points | \(\text{Number of metrics} \times \text{sample rate}\) |
| Log Storage | $0.50–2.00 per GB/month | \(\text{Log verbosity} \times \text{retention period}\) |
| Query Compute | $0.01–0.05 per query | \(\text{Dashboard refresh rate} \times \text{users}\) |
| Alert Evaluation | $0.001–0.01 per evaluation | \(\text{Number of alert rules} \times \text{check frequency}\) |
Napkin Math 14.5: Single-model monitoring budget
Problem: Calculate the monthly metric ingestion, time-series storage, and query compute cost required to monitor a single ML node under production assumptions.
Variables:
- one model with 3 deployment variants (production, canary, staging), each emitting 50 metrics
- Metrics sampled every 15 seconds
- Retention requirement: 30 days
- 2 dashboards (model health, infrastructure), 3 team members, 5-minute refresh
Metric ingestion:
- Data points per month: 3 \(\times\) 50 \(\times\) (4 samples/min \(\times\) 60 \(\times\) 24 \(\times\) 30 days) = 25.9M
- Cost at $0.30/million: $7.8/month
Storage:
- At 8 bytes/point compressed: 25.9M \(\times\) 8 bytes = 0.2 GB
- Cost at $1/GB: $0.21/month
Query compute:
- Queries per month: 2 dashboards \(\times\) 3 users \(\times\) (12 queries/hour \(\times\) 8 hours/day \(\times\) 22 days) = 12,672 queries/month
- Cost at $0.02/query: $253.4/month
Total: ~$261.4/month for a single ML node. Alert evaluation and platform overhead are excluded.
Systems insight: Under these assumptions, cost scales linearly with identical nodes; at platform scale, query-cost optimization becomes increasingly important.
Cost optimization strategies
Each cost component in equation 6 maps to a distinct engineering fix. The primary driver of \(\MonitoringIngestionCost\) and \(\MonitoringStorageCost\) is metric cardinality. High-cardinality labels such as user_id or request_id multiply the number of series in time-series indexes, and that growth outweighs raw compute costs. Dropping unnecessary labels or aggregating them into a bounded set of buckets reduces cardinality. Hashing each identifier to another distinct identifier alone does not reduce the number of series. The second driver of storage cost is temporal resolution. Retaining raw 15-second metrics across 30 days is rarely justified. A tiered retention policy (high-resolution telemetry for recent incident debugging, downsampled rollups for historical trend analysis) preserves diagnostic fidelity while reducing retained volume. For \(\MonitoringComputeCost\), dashboard query overhead accumulates through auto-refresh loops across dozens of unattended user sessions; setting conservative refresh intervals and auto-pausing inactive sessions bounds query load. Finally, \(\MonitoringAlertCost\) scales with evaluation frequency. Consolidating overlapping threshold checks into composite multi-condition rules can reduce redundant evaluation and notifications; thresholds, ownership, and actionability still determine alert fatigue.
Cost-benefit framework
A team justifies monitoring investments against incident costs using the monitoring benefit-cost ratio in equation 7: \[\text{Monitoring Benefit/Cost} = \frac{\text{Incidents Prevented} \times \text{Avg Incident Cost}}{\text{Annual Monitoring Cost}} \tag{7}\]
Suppose an average incident costs $50,000 (downtime, engineering time, and reputation) and monitoring prevents 5 incidents annually at $50,000 in monitoring cost:
\[ \text{Benefit/Cost} = \frac{5 \times \$50K}{\$50K} = 5\times \]
This framework helps justify monitoring investments and prioritize which metrics deserve fine-grained observation vs. coarse sampling.
The monitoring systems themselves require resilience planning to prevent operational blind spots. When primary monitoring infrastructure fails (Prometheus experiencing downtime or Grafana becoming unavailable), teams risk operating blind during critical periods. Production-grade MLOps implementations therefore maintain redundant monitoring pathways, such as secondary metric collectors that activate during primary system failures and local logging that persists when centralized systems fail. Robust deployments also monitor the monitor. An external watchdog checks the telemetry pipelines themselves, so a heartbeat check from an independent system catches a dead pipeline and alerts through an alternative notification path. This reduces the risk of undetected simultaneous model and telemetry failures, provided the alternative paths do not share the failed dependency.
Checkpoint 14.3: The monitoring stack
ML monitoring has several layers. The prompts in this checklist test whether each symptom can be traced to the responsible layer.
Layered monitoring converts silent degradation into signals. Infrastructure telemetry shows whether the serving path is compute-, memory-, or I/O-bound, input checks catch malformed or stale data before inference, drift statistics show that inputs have moved, and delayed outcome metrics confirm whether the movement cost accuracy. A signal is not yet a response, however. Confirmation can lag a drift signal by days or weeks, so each signal must reach a named owner with a deadline to investigate, or it waits on a dashboard while the loss accrues. The first decision a quality signal forces is whether to retrain, a choice that weighs the value the drift is costing against the cost of a run. Alerts that point to a fault rather than to drift go to incident response, which follows that decision.
Self-Check: Question
Explain why high-stakes production ML systems (such as medical diagnosis or loan underwriting) experience a ‘verification gap’ and describe how leading indicators mitigate this challenge.
Order the following stages in a single drift-alert workflow where each step depends on the previous one: (1) route the resulting alert to the designated owner for investigation, (2) compare the computed divergence with a calibrated threshold, (3) select and validate the versioned input cohort for analysis, (4) compute divergence against the specified reference distribution.
True or False: An inference server showing 95% GPU busy time and 30% HBM memory bandwidth utilization provides sufficient evidence to prescribe weight quantization as the primary optimization.
A recommendation service’s p99 latency rises from 80 ms to 110 ms overnight, breaching its 100 ms SLO. No model was deployed. Illustrative representative end-to-end request traces show model inference steady at 45 ms, while feature retrieval rose from 25 ms to 55 ms, with the remaining stages roughly unchanged. What is the appropriate first operational response?
- Roll back to the previous model version, because latency regressions are model regressions until proven otherwise
- Quantize the model further to buy back the 30 ms from the inference stage
- Route the incident to the feature-store owners and investigate the retrieval path, because the stage-level budget localizes the regression outside the model
- Raise the SLO to 110 ms, because a drift in total latency indicates a permanent change in workload
In an illustrative PSI rule of thumb, a Population Stability Index value of \(\text{PSI} \ge\) ____ is treated as a severe distribution shift that should trigger investigation.
14.6 Retraining Decisions
A team that retrains the ranking model on every minor PSI spike burns thousands of dollars in accelerator time and risks training on corrupted upstream logs, while a team that waits blindly for a quarterly calendar tick lets accuracy slide 6 points within four weeks, long before the next tick arrives. Retraining is the most expensive response the operations loop can choose, and the easiest to automate badly. Monitoring supplies two kinds of evidence, a divergence that a label-free monitor measures continuously and outcome metrics that arrive later, and the decide step of the operations loop turns them into one of three actions: retrain, roll back, or wait. The decision has three parts, taken in turn below: the candidate strategies and a test of whether a run is worth its cost now, a cadence that sets how often runs should happen, and a policy comparison between a fixed schedule and an evidence trigger. On the ranking service every run is also paid in accelerator-hours on hardware that serves live traffic.
The degradation equation of equation 1.1 turns divergence into a forecast of accuracy when outcome evidence supports one: \[\AccuracyAfterDeployment(\DeploymentAge) \approx \InitialAccuracy - \FittedSensitivity\cdot \DivergenceMeasure(\CurrentDistribution \lVert \TrainingDistribution)\] where \(\FittedSensitivity\) is fitted per deployment from historical degradation data, as the statistical drift diagnostic (principle 10) requires. While not a universal law, tracking distributional divergence \(\DivergenceMeasure(\CurrentDistribution \lVert \TrainingDistribution)\) can provide an earlier warning than delayed outcomes; it does not establish the direction or size of a quality change.
14.6.1 Retraining decision framework
Because distributional divergence warns early without proving how much accuracy was lost, an automated training pipeline still leaves one operational decision open: when to run. Deciding when to retrain a model means balancing accuracy degradation against compute and validation expense across three candidate policies. Table 16 provides illustrative schedules across domains, from daily retraining for rapidly shifting ad click prediction to quarterly updates for stable medical imaging applications:
| Domain | Illustrative Schedule | Rationale |
|---|---|---|
| Ad click prediction | Daily | User interests shift rapidly |
| Fraud detection | Weekly | Attack patterns evolve continuously |
| Demand forecasting | Monthly | Seasonal patterns change slowly |
| Medical imaging | Quarterly | Disease presentations are stable |
Those schedules are starting points, not invariant rules. The ranking service sits between the table’s first two rows. Its users’ interests shift daily, yet the economics below put its optimum at a few days.
In a scheduled retraining policy, pipeline execution runs on a fixed calendar cadence (daily, weekly, or monthly) regardless of incoming performance telemetry. This strategy is simple to automate and guarantees that freshly accumulated training data is integrated periodically. However, it burns accelerator hours during quiet periods and reacts slowly when distribution shifts strike between scheduled intervals.
A triggered retraining policy initiates pipeline execution when monitoring systems detect statistical drift or performance degradation exceeding predefined thresholds. This approach can conserve compute by responding to evidence rather than a fixed schedule, but it relies heavily on low-latency label streams or accurate proxy metrics to prevent delayed responses or false-alarm retraining runs.
A continuous retraining policy updates model weights incrementally as labeled records arrive, using streaming micro-batches or online learning algorithms. While this strategy minimizes staleness lag, it amplifies validation risk, because corrupted, unrepresentative, or adversarial data can poison model parameters before automated anomaly detectors or engineering teams can intervene.
The operating choice among these strategies depends on four physical and operational constraints: retraining compute cost, validation pipeline latency, automated rollback capability, and label arrival delay. Re-optimizing a model on multi-accelerator nodes incurs tangible energy and cluster costs. Triggered policies require statistically reliable proxy signals when true labels arrive with long delays. Every continuous deployment pipeline demands robust canary and rollback mechanisms. The policy should follow from these costs and the label delay, not from habit.
The economic and validation constraints become executable in listing 5. The decision function schedules a run only when the estimated recovered value exceeds the total cost of a run (compute, validation, deployment, and the expected cost of a bad rollout, the four terms that equation 10 formalizes below). It also schedules a run only when fresh validation data are available.
quality_loss = baseline_accuracy - current_accuracy
feature_drift = max(population_stability_index(features))
prediction_shift = distribution_distance(
    baseline_predictions, live_predictions
)

benefit = estimate_value_recovered(
    quality_loss=quality_loss,
    feature_drift=feature_drift,
    prediction_shift=prediction_shift,
)
total_cost = (
    compute_cost + validation_cost + deployment_cost + rollout_risk
)

if benefit > total_cost and validation_data_is_fresh():
    schedule_retraining_run()
The decision rule separates detecting drift from authorizing retraining. Drift contributes to estimated benefit, while fresh validation data and positive net value determine whether automation acts.
14.6.2 Quantitative retraining economics
To turn the trigger rule of listing 5 into a concrete schedule, a team must measure how fast an unretrained model loses value and weigh that loss rate against the fixed cost of a run. When outcome data support a locally exponential fit, the fitted decay rate gives a measurable timescale.23 Its half-life,24 the time for fitted accuracy to fall to half its initial value, states that timescale in intuitive units. The half-life puts deployments that decay at different rates on one scale, but on its own it does not fix the economically optimal interval, which balances the cost of staleness against the cost of a run. The derivation takes three steps: a staleness cost, a retraining cost, and the interval that minimizes their sum per unit time.
23 System entropy: A name for the silent degradation of When ML Systems Fail Silently, in which quality decays while code and weights stay unchanged. The fitted decay rate \(\AccuracyDecayRate\) measures how fast it proceeds. That rate can differ substantially across deployments and must be estimated from outcome data. A shorter decay timescale demands more responsive monitoring, but it does not by itself require continuous training; label delay, validation risk, retraining cost, and rollback capacity determine the operational cadence.
24 Half-life (from nuclear physics, where it measures the time for half of a radioactive sample to decay): In ML operations, the metaphor is a convenient approximation, not a universal law. For the exponential fit in equation 8, derived below, the half-life is \(\ln(2)/\AccuracyDecayRate\). Retraining cadence also depends on traffic, value, retraining cost, and risk; seasonal, abrupt, or adversarial change requires a richer drift process.
The staleness cost function
Model accuracy can degrade over time, creating a staleness cost. For economic planning, a team may fit the observable impact over a stable local regime as an exponential decay process. Here \(\AccuracyDecayRate\) is a temporal decay rate under the assumption that measured degradation accumulates steadily; it is not determined by distribution divergence alone. The exponential model is a simplification that enables closed-form economic analysis. Let \(\AccuracyAfterDeployment(\DeploymentAge)\) represent accuracy at time \(\DeploymentAge\) since last training, and \(\InitialAccuracy\) represent initial accuracy. Equation 8 captures this fitted scenario, where the rate \(\AccuracyDecayRate\) depends on domain volatility and observed outcomes: \[\AccuracyAfterDeployment(\DeploymentAge) = \InitialAccuracy \cdot e^{-\AccuracyDecayRate \DeploymentAge} \tag{8}\]
This temporal model is a time-domain summary of the degradation equation (equation 1.1), which predicts accuracy from divergence, \(\AccuracyAfterDeployment(\DeploymentAge) \approx \InitialAccuracy - \FittedSensitivity \cdot \StatisticalDivergence\), where \(\StatisticalDivergence\) is the divergence \(\DivergenceMeasure(\CurrentDistribution \lVert \TrainingDistribution)\) written as one symbol. If divergence grows at a roughly steady rate over an interval, that equation makes accuracy fall linearly in time at rate \(\FittedSensitivity\) times the growth rate of \(\StatisticalDivergence\). The exponential of equation 8 falls at rate \(\InitialAccuracy\AccuracyDecayRate\) while \(\AccuracyDecayRate \DeploymentAge\) is small. Both rates describe the same falling accuracy, so they must agree, which makes \(\AccuracyDecayRate\) an empirical stand-in for how fast the input distribution moves, scaled by the fitted sensitivity \(\FittedSensitivity\) and divided by \(\InitialAccuracy\).
The retraining interval derived here uses the time-domain \(\AccuracyDecayRate\), because a schedule is set in days. The drift statistics of section 14.5.2 (the population stability index, the KS statistic, and KL divergence) estimate the divergence itself and alert on it directly. Steady divergence growth is an assumption rather than a law, so both forms must be checked against observed outcomes.
A longer-horizon fit would decay toward a floor, such as chance-level accuracy, rather than toward zero. The unshifted form in equation 8 suffices for the intervals that retraining exists to enforce, the early, small-loss regime (\(\AccuracyDecayRate \DeploymentAge\ll 1\)) on which the square-root approximation below also depends.
The cost of staleness accumulates based on the daily query volume \(\DailyQueryVolume\) and the value impact \(\AccuracyPayoffPerQuery\) of a unit change in accuracy fraction. Integrating the instantaneous accuracy loss \((\InitialAccuracy - \AccuracyAfterDeployment(\DeploymentAge))\) over the retraining interval \(\RetrainingInterval\) yields equation 9: \[ \begin{array}{>{\displaystyle}c} \text{Staleness Cost}(\RetrainingInterval) = \int_0^T \DailyQueryVolume\cdot \AccuracyPayoffPerQuery\cdot (\InitialAccuracy - \AccuracyAfterDeployment(\DeploymentAge)) \, d\DeploymentAge= \\ \DailyQueryVolume\cdot \AccuracyPayoffPerQuery\cdot \InitialAccuracy \cdot \left(\RetrainingInterval- \frac{1-e^{-\AccuracyDecayRate \RetrainingInterval}}{\AccuracyDecayRate}\right) \end{array} \tag{9}\]
The integral accumulates cost over time \(\DeploymentAge\) from 0 to \(\RetrainingInterval\), and the closed form follows from substituting equation 8 for \(\AccuracyAfterDeployment(\DeploymentAge)\).
The retraining cost function
Each retraining incurs fixed costs including compute, validation, and deployment overhead. Equation 10 decomposes these: \[\text{Retraining Cost} = \RetrainingComputeCost+ \RetrainingValidationCost+ \RetrainingDeploymentCost+ \RetrainingRiskCost \tag{10}\] where \(\RetrainingComputeCost\) is the cost of the training run itself, \(\RetrainingValidationCost\) is the cost of evaluating the new model before release, \(\RetrainingDeploymentCost\) is the cost of rolling it into production, and \(\RetrainingRiskCost\) is the expected cost of potential regression from the new model. These are the four terms that total_cost sums in listing 5.
Optimal retraining interval
The optimal retraining interval \(\RetrainingInterval^*\) minimizes total cost per unit time, as equation 11 shows: \[\RetrainingInterval^* = \operatorname{arg\,min}_\RetrainingInterval\frac{\text{Staleness Cost}(\RetrainingInterval) + \text{Retraining Cost}}{\RetrainingInterval} \tag{11}\]
Under the assumption \(\AccuracyDecayRate \RetrainingInterval\ll 1\), a Taylor expansion of the exponential yields a closed-form approximation. Specifically, the second-order Taylor approximation \(e^{-\AccuracyDecayRate \RetrainingInterval} \approx 1 - \AccuracyDecayRate \RetrainingInterval+ \frac{1}{2}(\AccuracyDecayRate \RetrainingInterval)^2\) reduces the bracketed staleness term \(\left(\RetrainingInterval- \frac{1-e^{-\AccuracyDecayRate \RetrainingInterval}}{\AccuracyDecayRate}\right)\) to \(\frac{1}{2}\AccuracyDecayRate \RetrainingInterval^2\). Geometrically, when accuracy falls at a nearly constant rate \(\InitialAccuracy \AccuracyDecayRate\) per day, the loss starts at zero right after a retraining run and reaches \(\InitialAccuracy \AccuracyDecayRate \RetrainingInterval\) at the end of the cycle, so the average accuracy loss across the cycle is half that end-of-cycle peak. Dividing total costs by \(\RetrainingInterval\) therefore yields an average daily cost of \(\frac{1}{2} \DailyQueryVolume \AccuracyPayoffPerQuery\InitialAccuracy \AccuracyDecayRate \RetrainingInterval+ \frac{\RetrainingRunCost}{\RetrainingInterval}\), where \(\RetrainingRunCost\) is the Retraining Cost of equation 10. The first term rises linearly with \(\RetrainingInterval\) as average staleness grows, while the second falls as \(1/\RetrainingInterval\) as the fixed cost of a run is spread over more days. Differentiating with respect to \(\RetrainingInterval\) and setting the derivative to zero places the minimum where those two terms meet, yielding the square-root economic interval of equation 12: \[ \RetrainingInterval^* \approx \sqrt{\frac{2 \cdot \RetrainingRunCost}{\DailyQueryVolume\cdot \AccuracyPayoffPerQuery\cdot \InitialAccuracy \cdot \AccuracyDecayRate}} \tag{12}\] An exact optimum requires minimizing equation 11 without the expansion. The interval grows with the cost of a run and shrinks with traffic, value, and decay rate, each under a square root.
The best interval sits where amortized retraining meets accrued staleness.
Napkin Math 14.6: The optimal retraining interval
Problem: How often should the team retrain the model to maximize profit?
Physics: In this fitted scenario, model accuracy \(\AccuracyAfterDeployment(\DeploymentAge)\) decays exponentially at rate \(\AccuracyDecayRate\). Each successful update is assumed to restore initial accuracy with negligible training and rollout delay; traffic and value remain constant.
- \(\DailyQueryVolume\): Daily Query Volume (Traffic).
- \(\AccuracyPayoffPerQuery\): Financial value per query for a unit change in accuracy fraction. With this convention, \(\AccuracyPayoffPerQuery= \$0.50\) means 1 percentage point of accuracy is worth $0.005 per query. The Value per Point of equation 3 is the same quantity accumulated over a decision horizon, \(\AccuracyPayoffPerQuery/100\) per query multiplied by the number of queries in that horizon.
- \(\RetrainingRunCost\): Fixed cost of a retraining run, including compute and operational overhead.
Formula: Equation 12 gives the interval \(\RetrainingInterval^*\) that minimizes the sum of staleness losses and training costs per unit time.
Math: Consider the ranking service in an illustrative scenario (\(\InitialAccuracy\) = 0.94):
- Traffic \((\DailyQueryVolume)\): 1,000,000 ranking requests/day.
- Utility \((\AccuracyPayoffPerQuery)\): $0.50/query for a unit accuracy change.
- Retraining Cost \((\RetrainingRunCost)\): $5,000.
- Drift Rate \((\AccuracyDecayRate)\): 0.24 percent per day. \[ T^* \approx \sqrt{\frac{2 \times 5{,}000}{1{,}000{,}000 \times 0.50 \times 0.94 \times 0.0024}} \approx \mathbf{3}\text{ days} \]
Systems insight: High traffic and valuable accuracy shorten \(\RetrainingInterval^*\), so label availability, validation requirements, and achievable update delay become the limiting factors. If \(\RetrainingInterval^*\) is less than the team’s manual deployment time, the proposed cadence exceeds its operational capacity, and the team must shorten the update path or reconsider the policy and its assumptions.
With the parameters collected in table 17, the approximation places the economic optimum near 3 days. The ranking service’s drift, a 0.24 percent daily decay fitted to its observed four-week slide, is slow enough that a daily run would not yet pay for itself at this run cost. Four times the traffic would bring the optimum to about 1.5 days, close to the daily cadence that table 16 lists for ad click prediction. A slower-moving domain or a costlier run would push the same formula toward the table’s weekly or monthly rows.
| Parameter | Value | Description |
|---|---|---|
| \(\DailyQueryVolume\) | 1,000,000 | Ranking requests per day |
| \(\AccuracyPayoffPerQuery\) | $0.50/query | Value per query for a unit accuracy change |
| \(\InitialAccuracy\) | 0.94 | Initial accuracy |
| \(\AccuracyDecayRate\) | 0.0024 | Daily decay rate (0.24% per day) |
| \(\RetrainingRunCost\) | $5,000 | Total retraining expense |
Sensitivity analysis
Under the square-root approximation, \(\RetrainingInterval^*\) scales with the square root of these parameters. Table 18 shows that a fourfold change in retraining cost, query volume, or decay rate moves the approximated interval twofold. The square root damps error in these inputs, so a rough estimate of run cost or decay rate still yields an interval of the right scale.
| Change | Effect on \(\RetrainingInterval^*\) |
|---|---|
| 4× retraining cost | 2× longer interval |
| 4× query volume | 2× shorter interval |
| 4× decay rate | 2× shorter interval |
Accelerator-hours and contention
The run cost \(\RetrainingRunCost\) bundles the four terms of equation 10, and on the ranking service the accelerator term is the smallest of them. In an illustrative scenario, a run that retrains on the logs gathered since the previous run occupies 4 H100s for 6 hours. Those 24 accelerator-hours cost $96 at an assumed cloud rental price per training accelerator-hour, about 1.9 percent of the $5,000 run. Validation, deployment, and rollout risk make up the rest, which is why automating the validation path (section 14.3.2.3) shortens the economic interval more than faster training would.
The accelerator-hours matter instead as contention. The serving copy of the tables already holds two accelerators. On an eight-accelerator node, a run that holds its own copy and training state on four more leaves room for exactly one further copy of the tables while it executes (figure 9). That copy can be a canary, a shadow, or the hot standby of table 11, but not more than one of them. A team that releases and retrains on the same node must therefore schedule the two so that a retraining run never evicts the copy that makes rollback immediate.
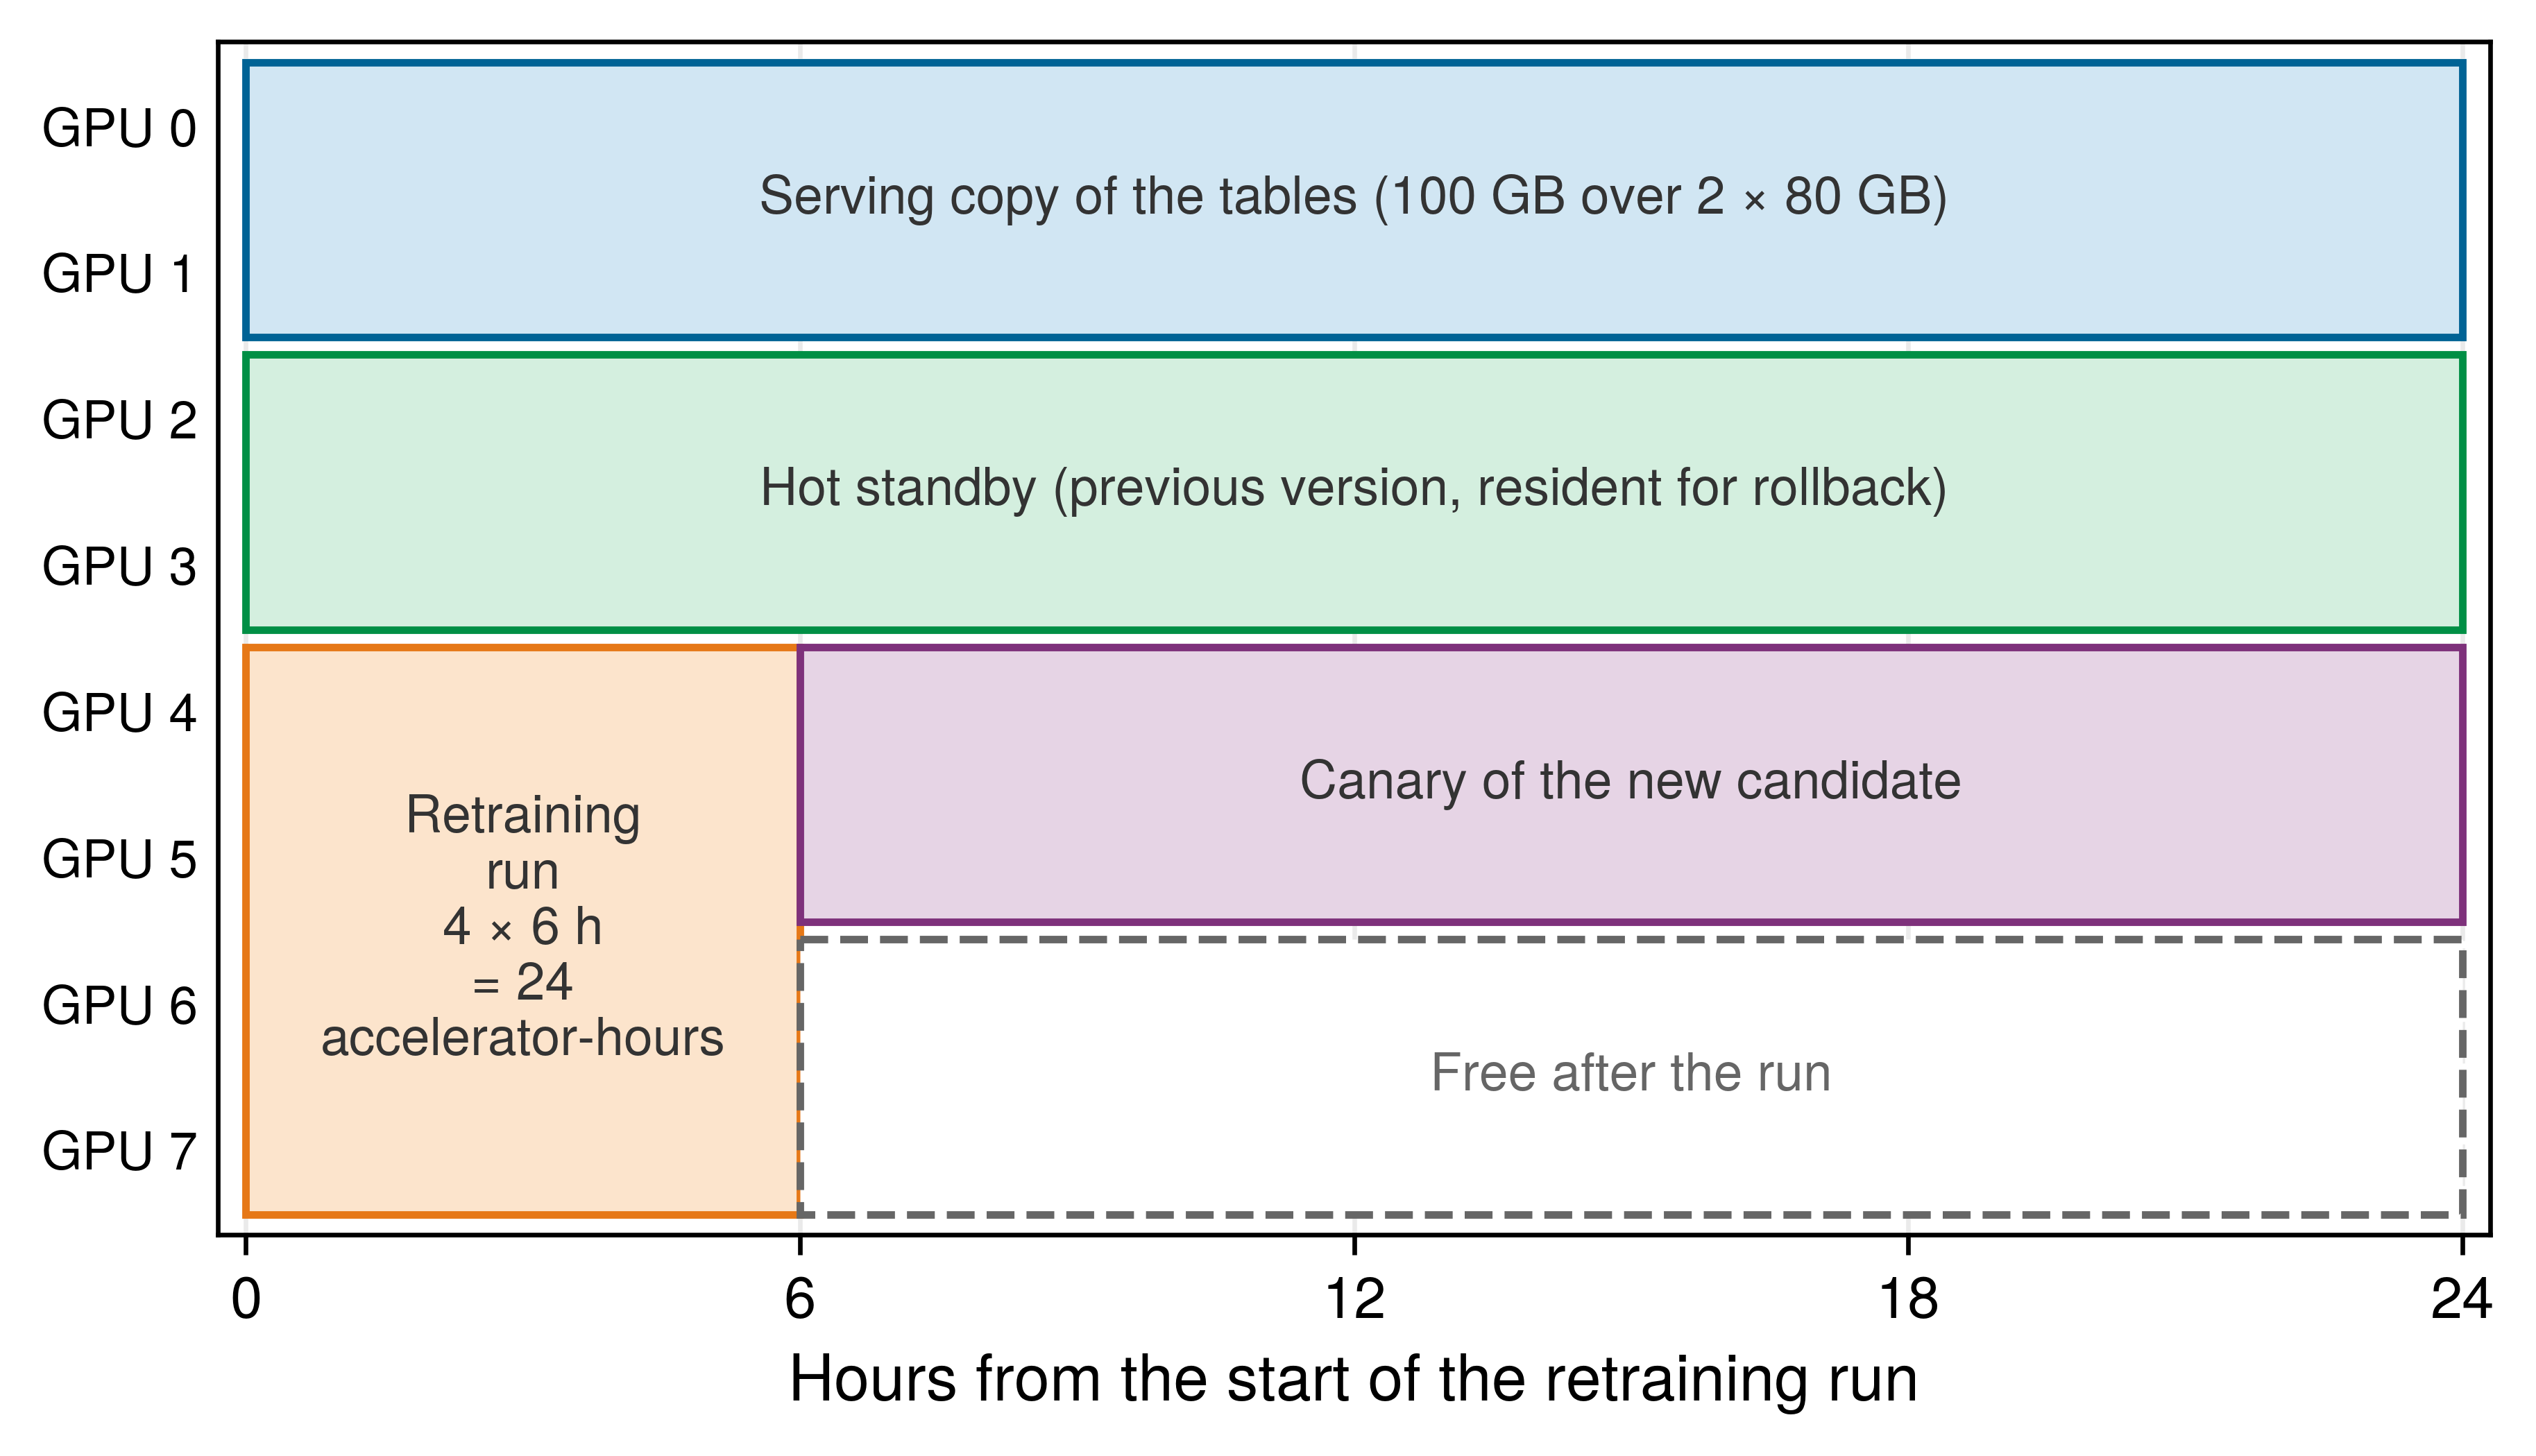
Model limitations
This closed-form framework provides a first-order approximation for operational planning, but its utility depends on several simplifying assumptions. First, the exponential decay formulation presumes gradual drift at a steady rate \(\AccuracyDecayRate\); sudden covariate shifts or acute data outages require immediate statistical change-point detection rather than smooth decay models. Second, the formulation assumes a constant marginal value \(\AccuracyPayoffPerQuery\) per accuracy point, whereas real-world utility often has nonlinear thresholds or asymmetric penalties. Third, the model treats retraining events as independent resets to initial accuracy with negligible delay, setting aside update failures, time spent training and validating, and transfer learning across cycles. Finally, infrastructure costs are modeled as fixed sums, whereas cloud spot pricing, queue contention, and elastic compute availability introduce dynamic variations. Parameters improve through empirical calibration against historical telemetry as operational experience accumulates, and the framework implements cost-aware automation (section 14.1.1) with thresholds grounded in measurable business impact.
14.6.3 Scheduled versus triggered retraining
The interval derived in equation 12 fixes a calendar schedule from average drift, whereas the decision rule of section 14.6.1 lets observed evidence decide when to run. Over a 365-day deployment on the ranking service, the two policies trace different sawtooths against a drift threshold of 0.88 accuracy (figure 10). Under a scheduled policy (orange sawtooth), the model retrains at rigid 90-day intervals, a spacing chosen long enough to make each tooth of the sawtooth visible, repeatedly dipping below the quality floor before each reset. In contrast, a triggered policy (green sawtooth) initiates retraining the moment monitored accuracy touches the threshold, illustrating an idealized instantaneous reset; in practice the trigger is often a divergence or proxy signal calibrated against accuracy. Neither interval is the economic optimum of equation 12, so the figure compares how the two policies respond to the same decay rather than recommending either interval. Both curves are drawn from the temporal decay model of equation 8. In deployment, sample collection, label arrival, training, validation, and rollout delays can carry accuracy below the trigger before recovery; the policy does not guarantee a performance floor.
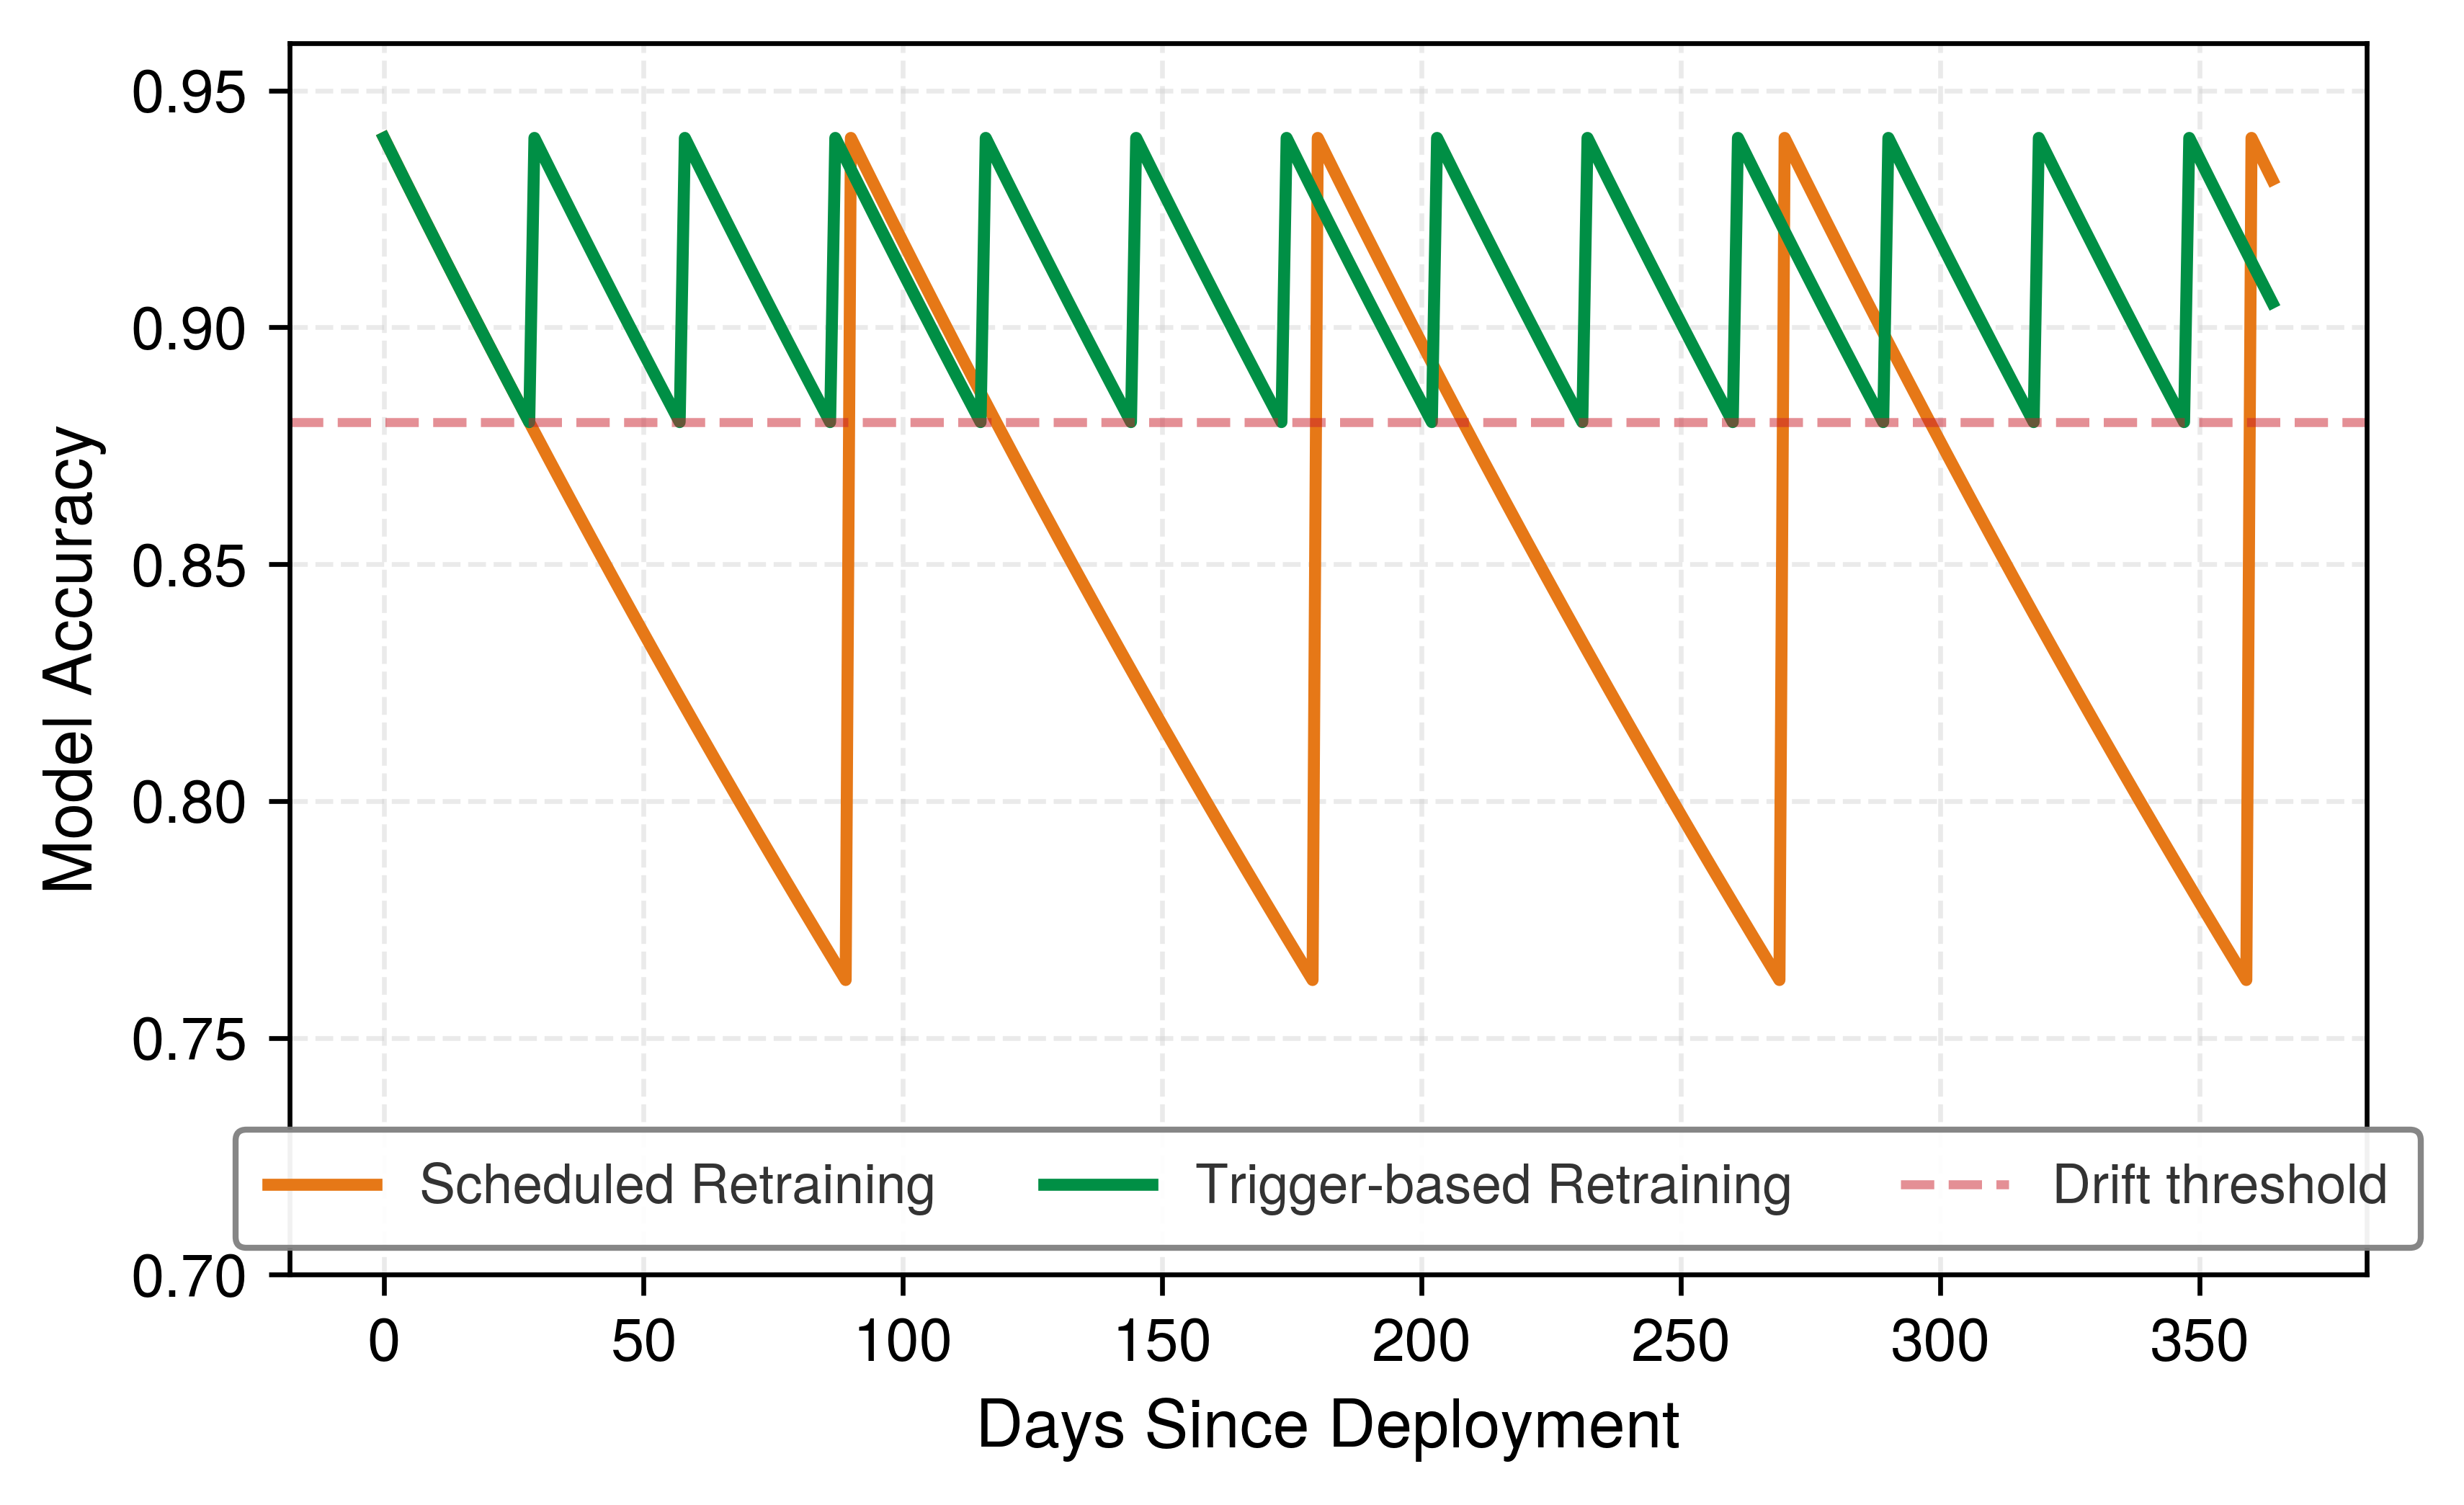
In this zero-delay model, the scheduled policy dips below the floor each cycle and the triggered one does not. Scheduled retraining is easy to plan but can retrain too early or too late, whereas trigger-based retraining requires stronger telemetry but aligns intervention with observed degradation. Whichever policy fires, a retrained replacement or a rollback depends on the registry lineage of section 14.3.1.2. This lineage links each version to the code, data, hyperparameters, and weights that produced it, and so lets a responder return to a known-good checkpoint. Lineage still cannot guarantee bitwise replay if driver versions, CUDA libraries, or nondeterministic reduction kernels vary across the fleet.
Retraining answers gradual drift. A sudden drop with a cause inside the system, such as a broken feature transform, a bad release, or a corrupted upstream table, calls for a different response. The failing layer must be found and contained, often by rollback, long before a retraining run could finish, and that is the work of incident response.
Self-Check: Question
The formal decision criterion governing whether a degraded model should be retrained balances expected accuracy improvement against training compute costs and deployment risk under the principle of ____.
Under the chapter’s simplified economic model (validated retraining resets quality, the square-root approximation applies, costs are fixed, and pipeline delays are ignored), the ranking service serves \(\DailyQueryVolume = 10^6\) queries/day with initial accuracy \(\InitialAccuracy = 0.94\), daily accuracy decay rate \(\AccuracyDecayRate = 0.0024\) (\(0.24\%\) decay per day, fitted to its observed four-week slide), value per query for unit accuracy fraction \(\AccuracyPayoffPerQuery = \$0.50\), and fixed retraining cost \(\RetrainingRunCost = \$5{,}000\). Using the square-root optimal retraining approximation \(\RetrainingInterval^* \approx \sqrt{\frac{2\RetrainingRunCost}{\DailyQueryVolume \cdot \AccuracyPayoffPerQuery \cdot \InitialAccuracy \cdot \AccuracyDecayRate}}\), what is the economically optimal retraining interval \(\RetrainingInterval^*\)?
- Approximately \(1.0\) day
- Approximately \(3.0\) days
- Approximately \(14.5\) days
- Approximately \(30.0\) days
In the optimal retraining formula \(T^* \approx \sqrt{\frac{2C}{Q \cdot V \cdot \text{Accuracy}_0 \cdot \gamma}}\), how does the optimal interval \(T^*\) change if the fixed retraining compute and validation cost \(C\) increases by a factor of 4 while all other parameters remain constant?
- \(T^*\) increases by a factor of 4 (\(4\times\) longer interval), scaling linearly with cost
- \(T^*\) increases by a factor of 2 (\(2\times\) longer interval), because \(T^*\) scales with the square root of retraining cost \(\sqrt{C}\)
- \(T^*\) decreases by a factor of 2 (\(0.5\times\) shorter interval), forcing more frequent retraining
- \(T^*\) remains unchanged, because optimal retraining cadence is governed solely by query traffic and drift rate
14.7 Incident Response and Governance
The ranking service from the opening of this chapter drew attention only in week eight, and a product manager noticed before any system did. Drift monitoring could have raised the alarm by week four, when accuracy had already fallen to 88 percent, but an alert only relocates the problem. Someone must then decide quickly whether the signal is real, which system caused it, and whether to roll back, and the organization must already have decided which models were allowed to ship and who owns them. Incident response supplies the first set of decisions, governance supplies the second, and the ML Test Score, taken up with operational maturity (section 14.8.1), audits whether both are in place before a failure tests them.
14.7.1 Incident response and operational practices
An unowned drift alert that fires on a Friday night without a severity policy, a diagnostic checklist, or rollback authority sits in a Slack channel until Monday while live traffic absorbs the damage. Incident response, debugging, and on-call rotation form the human half of the operations loop, its diagnose and recover steps, turning a statistical signal into an engineering action within a bounded time.
Incident response for ML systems
At 2:00 AM, an on-call engineer receives an alert that the ranking service’s click-through rate has dropped 12 percent over the past hour. There is no stack trace, no error log, no crashed process, just a statistical signal that something has changed. The responder must distinguish among four candidate root causes: an upstream data-pipeline failure, model drift, a seasonal traffic pattern, or statistical noise. This ambiguity is common in ML incidents, whose symptoms may appear as degradation in outcome or predictive-quality metrics rather than explicit errors, so incident response must account for statistical uncertainty.
Severity classification provides the foundation for prioritizing response in this ambiguous landscape. Table 19 gives one recommendation service’s illustrative policy, with response deadlines from 15 minutes to 24 hours. Priority depends on affected traffic, consequences, and the need for containment, not on the size of a raw signal. Because a CTR drop alone shows a change in engagement rather than a model defect, the P1 example also requires replay evidence of a broken feature contract.
| Level | Criteria | Response Time | Example |
|---|---|---|---|
| P0 | Service unavailable across live traffic | 15 minutes | Null predictions prevent recommendation delivery |
| P1 | Broad harmful impact needing containment | 1 hour | CTR falls across major cohorts; replay confirms a broken feature contract, while longer-term outcomes remain pending |
| P2 | Bounded impact with a validated fallback | 4 hours | A localized feature defect is contained; the owner investigates remaining exposure and pending outcomes |
| P3 | No observed impact or immediate exposure | 24 hours | Training is delayed while the current release remains within its measured operating limits |
Once an incident is classified, responders execute a structured response workflow where urgent containment can proceed alongside evidence collection, because the harm keeps accumulating while the cause is unknown:
- Detection identifies which monitoring signal, affected metric, and threshold triggered the alert.
- Impact assessment quantifies the fraction of serving traffic, user cohorts, or downstream services exposed.
- Change correlation audits recent deployments across model weights, serving runtimes, feature transforms, and upstream data pipelines.
- Mitigation evaluates and executes containment options, including traffic shifting, fallback enablement, or rollback to a known-good checkpoint.
- Root cause analysis isolates whether the defect originates in data pipelines, model representations, or serving infrastructure.
For P0 and P1 incidents, postmortem documentation is required. These postmortems analyze timelines, root causes, user impact, and preventive measures, specifically identifying which monitoring gap allowed the issue to reach production and what automated validation would have caught it earlier.
Model debugging: From detection to diagnosis
Incident response triages and mitigates; model debugging identifies root causes. Monitoring detects that something is wrong; debugging determines why. ML debugging must account for probabilistic and data-dependent failures in addition to conventional software defects. An incorrect prediction does not throw an exception or generate a stack trace, making systematic debugging essential for resolving ML incidents efficiently.
The debugging decision tree
The response workflow above orders an incident’s actions; the decision tree orders where to look for the cause. When model performance degrades, its five stages form an ordered list of places to inspect; recent changes and incident severity can alter their priority. Confirming the hypothesis supplies a systematic diagnostic matrix that maps symptoms to D·A·M (Data · Algorithm · Machine) axes.

Production debugging starts on the data axis of D·A·M.
- Data pipeline integrity: Inspect upstream data pipelines for schema changes, missing values, serialization errors, or input distribution shifts. Data integrity is an effective starting boundary because altered inputs, corrupted labels, and upstream feature changes can affect every downstream prediction.
- Training-serving skew: Replay matched requests through the versioned offline and serving transformations and compare feature values, missingness, units, and time cutoffs. KS or PSI separately screen for population divergence; neither verifies that the two paths compute the same value for a given request.
- Subpopulation slicing: Disaggregate performance across operational dimensions (such as geography, client hardware, or user cohorts). Localized degradation isolates data coverage gaps and slice-specific label noise that aggregate metrics conceal.
- Temporal degradation dynamics: Evaluate performance trends across time. Abrupt drops prioritize recent release artifacts and upstream infrastructure outages, whereas gradual degradation motivates checking seasonality and changing predictive relationships.
- Model and representation attribution: After verifying data pipeline integrity and ruling out serving skew, evaluate model-level failure modes through prediction confidence distributions, calibration curves, and feature attribution.
Slice analysis
Walking that decision tree starts with disaggregating the symptom, because performance metrics aggregated across all traffic can mask significant problems in subpopulations. Slice analysis exposes that masking by computing the same metric separately for each segment, and table 20 shows how a healthy overall accuracy can hide severe degradation in one of them. The same comparison guides pipeline and serving-skew investigations by testing whether an apparent system-wide problem is concentrated in a subpopulation.
| User Segment | Traffic % | Accuracy | Impact |
|---|---|---|---|
| Desktop users | 45% | 94% | Nominal |
| Mobile (iOS) | 30% | 92% | Nominal |
| Mobile (Android) | 20% | 88% | Minor degradation |
| Tablet users | 5% | 62% | Severe, investigate |
| Overall | 100% | 91% | Masks tablet problem |
Feature attribution for debugging
↪ Post-hoc feature attribution methods, Shapley value computational costs, and model interpretability boundaries are developed in Explainability requirements.
When slice analysis identifies a problematic segment, feature attribution techniques help identify which features the model relies on within its incorrect predictions. The common choice is SHAP values, feature-attribution scores that estimate how much each input feature contributed to an individual prediction, computed over the mispredicted examples of the failing slice and summarized across them. Their cost and their limits as explanations belong to responsible engineering; for debugging, one caveat governs their use. An attribution summary identifies features the model relied on within the failing slice; it does not establish whether those features caused the errors, so diagnosing stale features, missing coverage, or semantic shift requires checking feature lineage and production distributions. Attribution can also expose a zombie feature (perspective 14.1), an input the model should no longer depend on because nobody maintains it.
Counterfactual analysis
For individual mispredictions, counterfactual analysis identifies the minimal change that would flip the prediction. Consider a churn model that reads the same user_session_length feature as the ranking service. If one of its churn predictions would flip to “engaged” when user_session_length rose from 12 minutes to 45, that sensitivity suggests checking for the definition mismatch illustrated in the skew case study (section 14.3.1.1.2). Matched-input comparisons and feature lineage must establish whether the churn system has the same pipeline defect before the counterfactual can guide a repair. Counterfactuals reveal which feature boundaries drive decisions and whether those boundaries make semantic sense, and counterfactuals that require implausible changes (“user age would need to be -5 years”) often indicate feature engineering problems. Together, the debugging decision tree, slice analysis, feature attribution, and counterfactuals form a unified debugging toolkit that teams codify into a repeatable checklist.
Debugging checklist
The diagnostic lenses identify places to investigate; a six-phase checklist organizes how to test a suspected cause. The ordering is deliberate because each phase narrows the search space for the next:
- Reproduce: An ML failure that appears on logged production inputs but cannot be reproduced on held-out data is often data-dependent, because the same model handles its evaluation inputs and fails only on what live traffic now sends. That pattern redirects investigation toward the D·A·M taxonomy’s data layer.
- Isolate: Once reproduced, identifying the minimal input set that triggers the failure transforms a diffuse “the model is wrong” complaint into a specific, testable condition.
- Bisect: If the failure correlates with a recent deployment, controlled comparisons of versioned model, feature-transform, and runtime artifacts help isolate which change introduced the regression.
- Attribute: Feature attribution applies interpretability techniques to identify which input factors drive the erroneous behavior.
- Validate: Confirming that the hypothesized root cause, when corrected, actually resolves the failure distinguishes genuine fixes from coincidental improvements.
- Prevent: Converting each resolved incident into a monitoring rule or validation check systematically closes the gap between detection and recurrence. This cumulative hardening can reduce repeated failure modes over time because each incident strengthens the observability infrastructure.
Applied to the session-duration defect, these phases end in a specific, bounded finding. Suppose the CTR alert coincides with a serving-transform release on one of the ranking service’s hosts. The model weights, runtime, and offline feature definition are unchanged. Request logs place the new transform on the affected sessions, and replaying those exact inputs reproduces the wall-clock versus foreground-active mismatch. Representative traces show unchanged feature-retrieval and model-execution durations, which weakens a latency-regression explanation. Mature recommendation outcomes for the new release are still pending, so the responder has established a feature-contract violation, not its eventual effect on accuracy or revenue.
The owning engineer restores the prior serving transform and its compatible feature-cache namespace, first checking the rollback on replayed requests and then exposing it through a bounded canary. Matched values agree again, and the same-input scores return to the prior artifact’s outputs within the declared tolerance. Those observations demonstrate recovery of the feature contract; later comparable, mature outcome cohorts must establish whether user outcomes recover. A weights-only rollback leaves the changed feature computation in place, and immediate retraining would teach against the defect rather than repair the contract. The prevention step adds the affected idle-session inputs to parity validation and records the transform, cutoff, and cache versions needed for future replay.
On-call practices for ML systems
The debugging techniques in section 14.7.1.2 assume an engineer investigating during business hours. Production systems fail at 3:00 AM on weekends, and the person responding may not be the one who built the model. On-call practices keep someone with the right expertise available and equipped, and ML adds two difficulties to an ordinary on-call rotation. First, its incidents are ambiguous, because an engineer facing a 3 percent accuracy drop must decide whether it is statistical noise, a changed predictive relationship, or a failure that needs mitigation, which demands statistical context rather than log analysis. Second, its impact is delayed, because a ranking model that began serving slightly worse recommendations on Monday may not move revenue until Friday, by which time the window for easy diagnosis has closed, and the cause often lies in an upstream data system owned by another team.
These challenges motivate tiered escalation structures that match expertise to incident complexity. In one possible structure (table 21), primary responders handle routine issues using standardized runbooks while escalation paths connect to specialists capable of deeper investigation. A parallel data on-call role can reduce time to resolution when the root cause lies in an upstream data system.
| Tier | Responder | Responsibility |
|---|---|---|
| Tier 1 (Primary) | ML Engineer | Initial triage, standard runbooks, escalation decisions |
| Tier 2 (Escalation) | Senior ML Engineer/Data Scientist | Complex debugging, cross-system investigation, model-specific issues |
| Tier 3 (Critical) | ML Platform Lead | Architecture decisions, major incidents, vendor escalation |
| Data On-Call (Parallel) | Data Engineer | Data pipeline issues, feature store problems, upstream dependencies |
Effective on-call depends on runbooks and on alert discipline. Each production model’s runbook records its purpose, owner, and criticality, and the latency, throughput, and accuracy ranges that define healthy behavior. It also lists past incidents and their resolutions, the diagnostic queries for recent predictions, feature distributions, and confidence scores, and the escalation and rollback criteria, including when to roll back without approval.
Alert fatigue, the tendency to dismiss alerts after too many false positives, erodes alert discipline. Teams therefore consolidate related alerts into one notification, use thresholds that follow weekly and seasonal patterns, retire alerts that are rarely actionable, and require a follow-up ticket before any alert is silenced. Structured shift handoffs carry active incidents, recent deployments, scheduled changes, and suppressed alerts across rotations. Limits on consecutive on-call days, compensatory time off after severe incidents, and automation that removes toil keep the rotation sustainable over years of operation. Even so, dashboards fail if no one is responsible for acting on alerts, and runbooks languish if team structures do not support their use. Production ML operations therefore need organizational infrastructure alongside the technical: clear governance, defined roles, and communication patterns that enable cross-functional coordination.
14.7.2 Governance and team coordination
On-call runbooks address real-time operational failures after a model is already serving traffic. Proactive governance sets the behavioral, legal, and ownership rules a candidate must satisfy before a data scientist hands a checkpoint to an infrastructure team for release. Without those pre-release checks, a model can ship into production with no signed feature contract, no subgroup fairness check, and no named owner, producing biased predictions or opaque decisions that neither team has the context to catch. Within an operational pipeline, governance enforces three concrete objectives: transparency through auditable training data lineage and verifiable model weights, fairness through evaluation against the application’s selected and justified criteria, and compliance through adherence to privacy, retention, and auditability rules. While Responsible Engineering details the statistical metrics and interpretability algorithms required for these properties, MLOps provides infrastructure to collect evidence and enforce specified checks across the deployment lifecycle, alongside accountable policy and domain review.
ML governance spans the full lifecycle of the artifact. Automated pipelines record feature schemas, training data provenance, and hyperparameter configurations during development. Prerelease validation checks evaluate out-of-distribution robustness and selected fairness criteria. Production monitors track changes in subgroup metrics alongside aggregate accuracy. Encoding testable governance policies in CI/CD pipelines makes release checks repeatable, while choices about acceptable risk, fairness criteria, and applicable obligations still require accountable review.
Concretely, a model registry can hold a model in staging until it has a signed feature contract, a recorded training-data lineage hash, subgroup metrics above policy thresholds, a canary SLO with automated rollback criteria, and a designated artifact owner. That promotion check turns documented release requirements into assertions enforced by the deployment machinery. Passing those assertions establishes that the specified checks passed, not that every governance obligation has been satisfied.
Governance policies define the release criteria, but operational reliability depends on execution across organizational boundaries. Because machine learning systems span data engineering, statistical modeling, and distributed serving infrastructure, role handoffs represent the most failure-prone interfaces in the operational lifecycle. Versioned experiment stores and centralized model registries provide the shared substrate required for reproducible transitions between research and production engineering. At the data interface, formal schema specifications and lineage DAGs ensure that data scientists and platform engineers share identical assumptions regarding feature semantics, default null handling, and label arrival latency.
Titles and boundaries vary across organizations, but one common decomposition uses the five roles in table 22. The table maps each role to a primary responsibility without implying that every organization needs five separate positions:
| Role | Primary Focus | Key Deliverables | Collaboration Points |
|---|---|---|---|
| Data Scientist | Model development, experimentation, algorithm selection | Trained models, experiment results, performance benchmarks | Hands off to ML Engineer for productionization |
| ML Engineer | Production ML systems, training pipelines, serving infrastructure | Deployed models, training pipelines, serving systems | Receives from Data Scientist; works with Platform Engineer on infrastructure |
| Data Engineer | Data pipelines, feature engineering, data quality | Feature pipelines, data quality systems, feature stores | Provides data to Data Scientist; maintains feature store for ML Engineer |
| Platform Engineer | MLOps infrastructure, tooling, automation | CI/CD pipelines, monitoring systems, compute infrastructure | Enables ML Engineer; maintains shared infrastructure |
| DevOps/SRE | Reliability, incident response, system health | SLOs/SLAs, on-call procedures, runbooks | Supports all roles; owns production health |
Clear role definitions matter most at handoff points, where artifacts transition between specialists. The most failure-prone transition occurs between Data Scientists and ML Engineers. An exploratory notebook script frequently fails in production environments due to undocumented data preprocessing steps, hardcoded local file paths, hidden state execution orders, or unpinned library dependencies. Similarly, the handoff from ML Engineers to SREs (Beyer et al. 2016) requires verified monitoring dashboards, active alerting rules, documented runbooks, and tested rollback procedures. Data Engineers interface with model builders through feature contracts, formal specifications of data schema, freshness SLOs, and distribution invariants that prevent upstream pipeline modifications from surfacing as silent downstream prediction failures weeks later. Teams eliminate these interface risks by requiring standardized container images, hermetic build manifests, and automated reproducibility assertions before any artifact advances to the next stage.
Beyer, Betsy, Chris Jones, Jennifer Petoff, and Niall Richard Murphy. 2016. Site Reliability Engineering: How Google Runs Production Systems. O’Reilly Media.
Stakeholder communication
While cross-functional handoffs govern internal engineering execution, stakeholder communication sets the shared expectations between technical teams and organizational decision-makers. Those expectations are harder to set for an ML system than for conventional software, because a model’s behavior depends on its data and the population it serves, trades accuracy against latency, and can drift. When stakeholders consider only service availability, misalignment can arise regarding expected predictive quality, latency budgets, and maintenance costs.
A frequent communication failure is the unconstrained request to “make the model more accurate.” Model accuracy cannot be scaled independently of system costs. Boosting validation accuracy by two percentage points often requires moving to a significantly larger model architecture, incurring higher FLOP counts per sample, increasing memory bandwidth demands, and violating strict inference latency SLOs. Grounding improvement discussions in the Pareto frontier (principle 5) forces explicit decisions among model accuracy, inference latency budgets, training compute costs, and dataset acquisition expenses.
Translating statistical metrics into operational impact requires mapping errors to their consequences, which are rarely symmetric. Accuracy, ROC-AUC, and F1 treat errors symmetrically. The ranking service’s errors differ in cost only mildly, so a separate illustrative case with a sharper asymmetry carries the argument. In an automated fraud detection pipeline, a false positive creates friction at checkout while a false negative allows unrecoverable theft. With missed fraud ($500 per incident) five times as costly as a blocked legitimate user ($100), the total cost across classification thresholds reaches its minimum near 0.34, well left of the symmetric 0.50 baseline (figure 11).
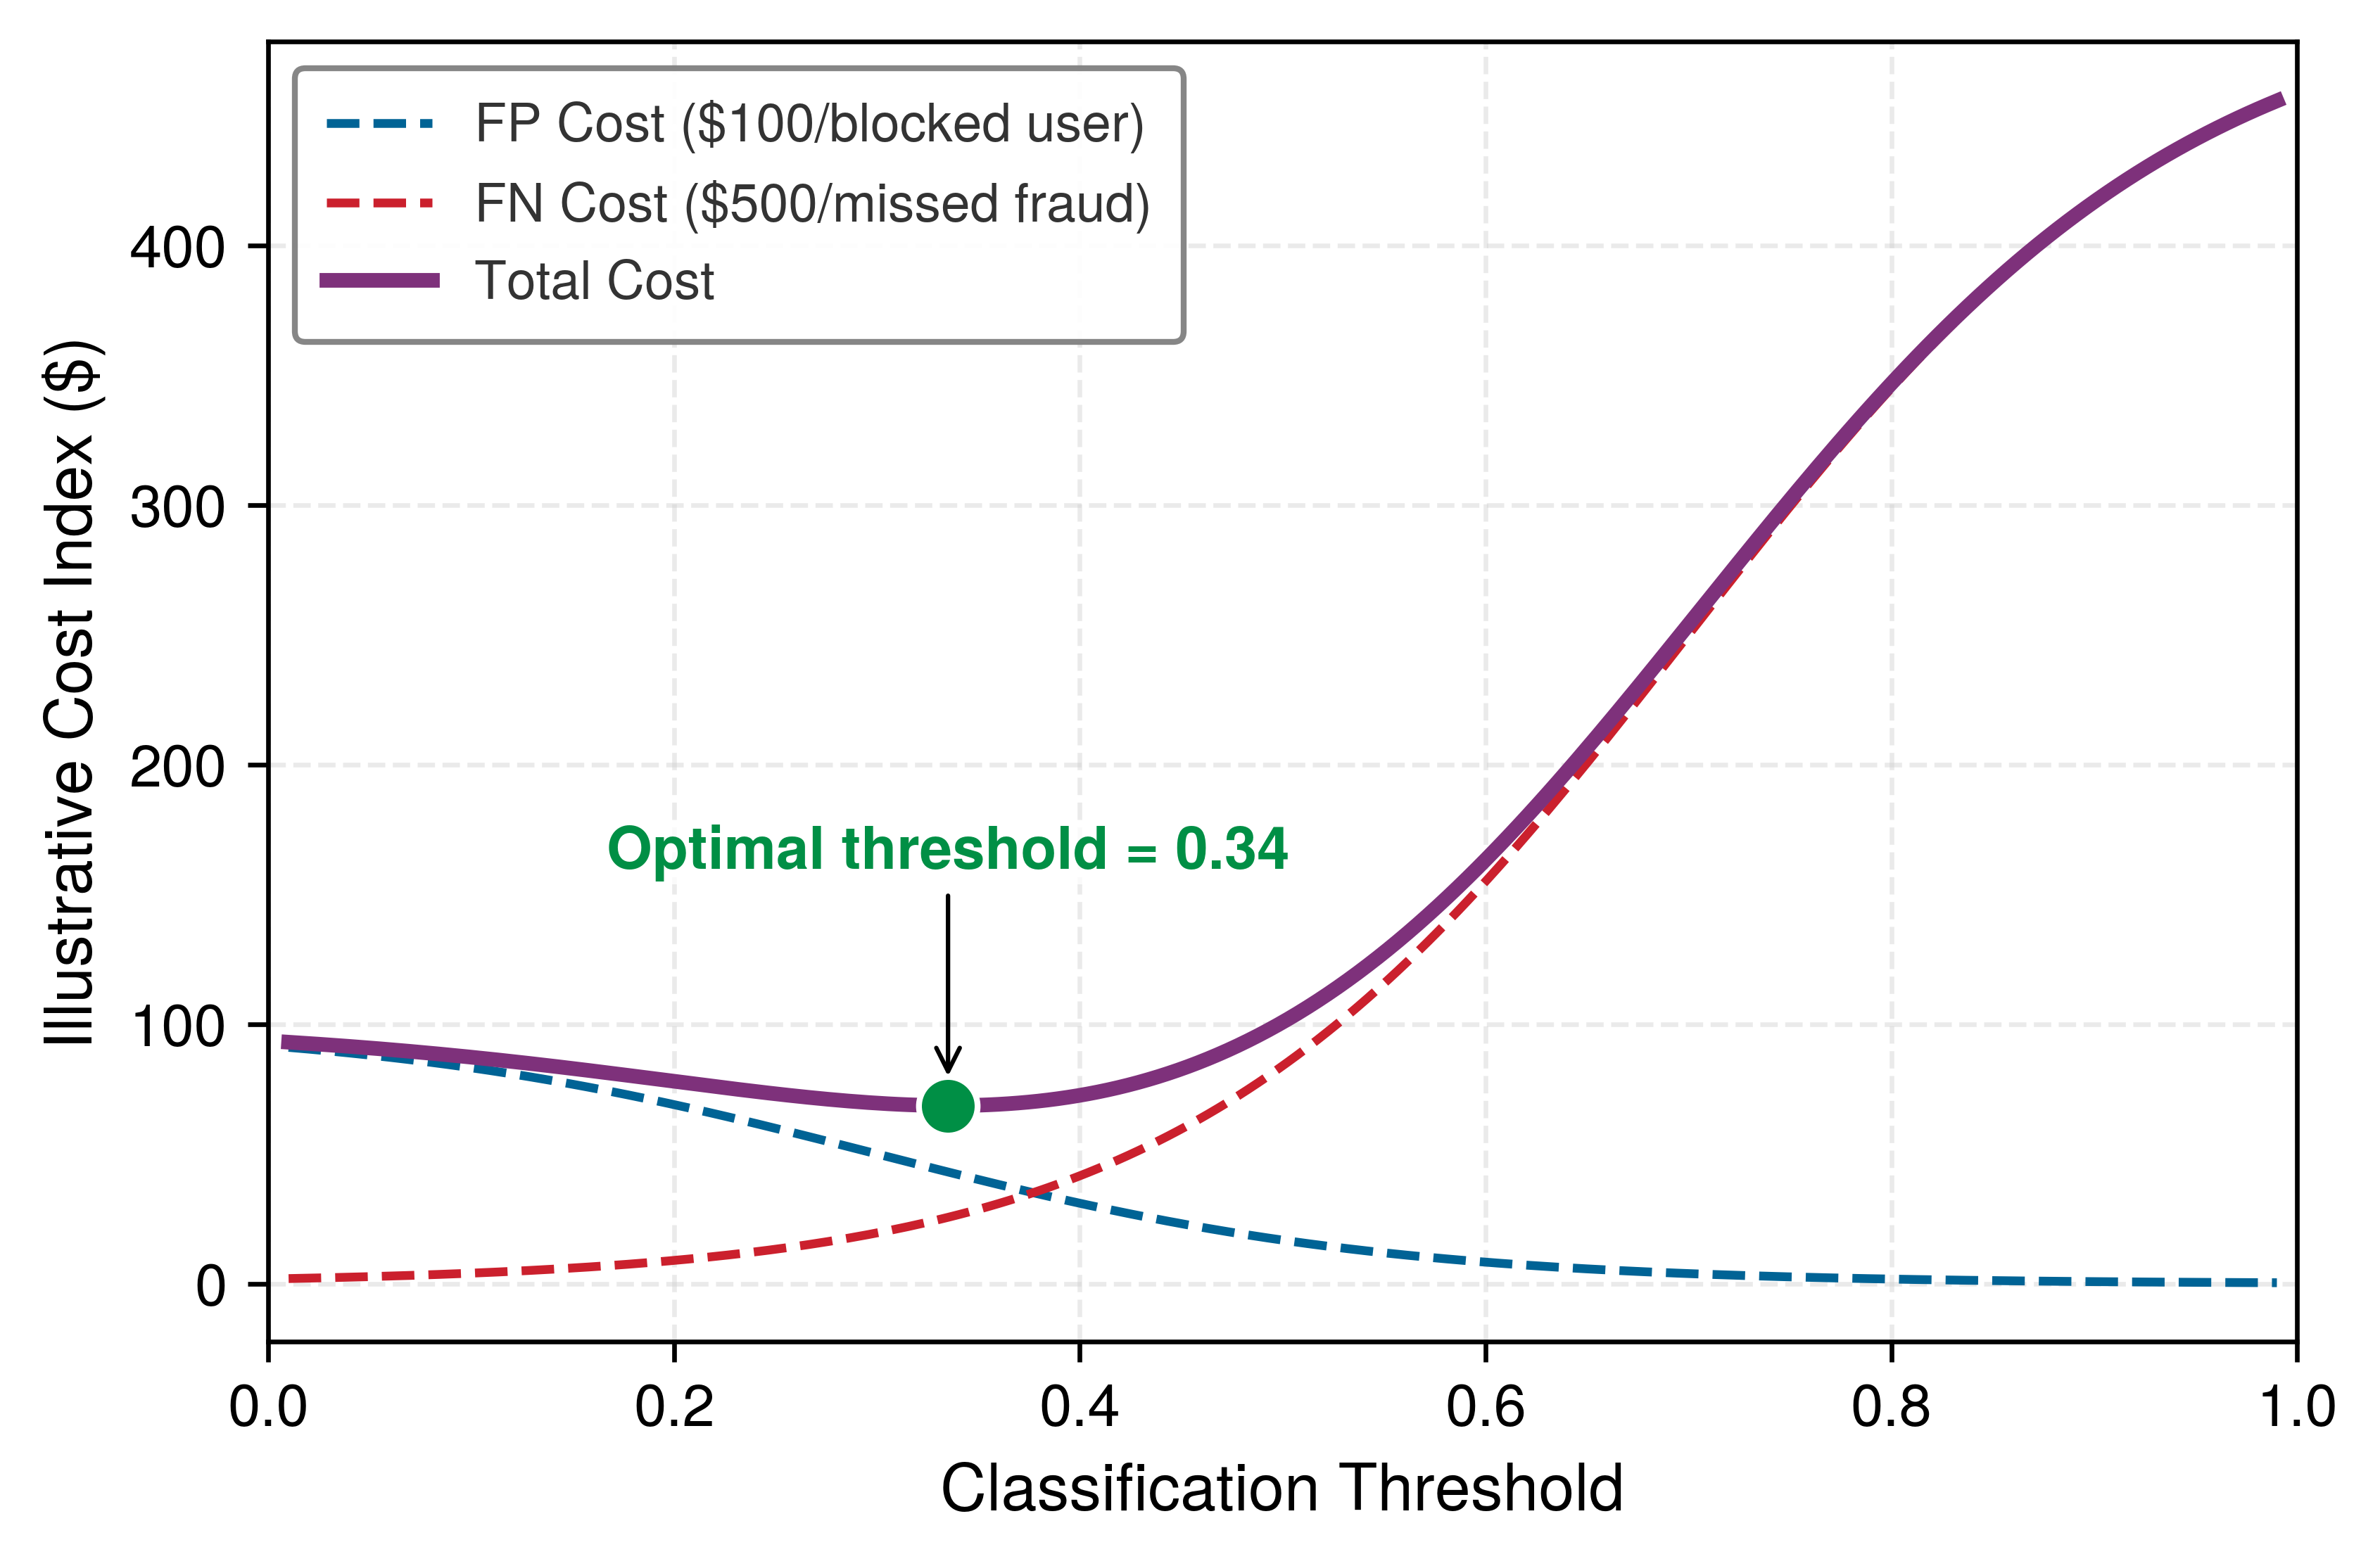
In the same fraud detection case, consider a team evaluating a proposed model upgrade. When stakeholders request improved capture rates, the engineering team frames the initiative as a concrete systems trade-off. Increasing the fraction of fraud dollars captured from 92 percent to 94 percent requires integrating external feature pipelines, extending training duration by two weeks, and accepting 30 percent higher infrastructure costs. In return, the upgrade prevents an estimated $2 million in annual fraud losses while a separate assumption of a 20 percent cut in false-positive alerts removes 50,000 of them per month. Framing model improvements around financial impact, latency budgets, and compute expenditure keeps governance decisions tied to verifiable engineering trade-offs.
A status report to stakeholders must state the evidence directly when monitoring detects distribution drift or an inference regression triggers an automated rollback: the statistical divergence metric, the demographic or tenant cohort affected, the canary rollback target, and the estimated recovery timeline. Dismissing an anomalous output distribution as noise without a hypothesis test lets a silent failure reach production decisions.
Checkpoint 14.4: From alert to accountable action
Incident response, debugging runbooks, and governance checks complete the operations loop for a single model, turning silent statistical alerts into owned engineering actions. Standing up every control in this loop at full fidelity on day one, however, is neither possible nor economical for most teams. Deciding which gaps expose a deployment to silent failure right now, and which control to fund next, requires a structured model of operational maturity.
Self-Check: Question
At 2:00 AM an alert reports that recommendation click-through rate fell 12 percent in the past hour. There is no stack trace and no failed process. Following the chapter’s debugging decision tree, what should the on-call engineer check first?
- Feature attributions for recent mispredictions, to see which inputs the model now relies on
- Upstream data pipelines for schema changes, missing values, or shifted input distributions
- Calibration curves and confidence distributions of the current model version
- Whether a quarterly retraining is due, since gradual concept drift is the most common cause
Explain how a model-registry promotion check turns model governance from a review meeting into a release invariant, and name three conditions such a check can require before a model moves from staging to production.
14.8 Operational Maturity
An organization deploying its initial ML model might rely on a hand-run Jupyter notebook, a scheduled cron job, and minimal monitoring. A mature enterprise runs thousands of models through automated pipelines with drift detection, canary deployments, and continuous validation. Both are doing “MLOps,” yet they differ greatly in reliability, cost efficiency, and deployment velocity. Because production failures cluster around data dependencies, pipeline boundaries, and monitoring blind spots rather than core model architectures (Paleyes et al. 2022), operational maturity provides the systems framework for evaluating how thoroughly a team has fortified those boundaries as it evolves from ad hoc experimentation toward automated operations. Locating a system on this continuum guides resource allocation better than adopting tooling indiscriminately. Placing a system on the continuum starts with an audit of its current practices and then raises three questions in turn: what architecture the next level requires, which organizational and failure-containment patterns keep that architecture working, and how much the move is worth.
Paleyes, Andrei, Raoul-Gabriel Urma, and Neil D. Lawrence. 2022. “Challenges in Deploying Machine Learning: A Survey of Case Studies.” ACM Computing Surveys 55 (6): 1–29. https://doi.org/10.1145/3533378.
14.8.1 ML test score
A team can spend months perfecting offline hyperparameter sweeps and model unit tests while leaving production monitoring and schema checks unbuilt, only to suffer a multi-week silent outage on the first upstream database change. Auditing the debt patterns of table 6 and the controls built to pay them down therefore requires a formal technical debt assessment rubric that turns subjective readiness debates into measurable engineering criteria. The ML Test Score (Breck et al. 2017) structures this evaluation across data, model, infrastructure, and monitoring test suites, with seven tests in each of the four categories (28 in total). A documented manual test whose results are distributed receives 0.5 points, an automated test run repeatedly receives 1 point, and an unperformed test receives 0. Rather than averaging across suites, the rubric sets the composite score to the weakest category, \[\text{ML Test Score} = \min(\text{Score}_{\text{data}}, \text{Score}_{\text{model}}, \text{Score}_{\text{infra}}, \text{Score}_{\text{mon}})\] where each category score \(\text{Score}_{\text{cat}} \in [0, 7]\). A deployment with exhaustive offline model validation (\(\text{Score}_{\text{model}} = 7\)) but absent production telemetry (\(\text{Score}_{\text{mon}} = 0\)) receives an overall score of 0. The min operator is deliberate, because an unmonitored serving path can deliver corrupted predictions despite strong offline benchmark accuracy.
Three of the four suites partition production risk along the D·A·M axes, and the fourth watches all three. The data suite (D) verifies that feature distributions conform to declared schemas, privacy boundaries remain unviolated, and each feature justifies its inference latency and memory footprint. The model suite (A) confirms that architectures and hyperparameter configurations are version-controlled, staleness bounds are enforced, and offline benchmark improvements translate into live metric gains. The infrastructure suite (M) tests training reproducibility under documented execution conditions, serving-path parity between training and inference pipelines, and automated rollback mechanisms. The monitoring suite is the feedback layer across all three axes; it verifies that schema changes, invariant violations, training-serving skew, and stale weights generate actionable alerts that help limit downstream impact. Table 23 summarizes representative tests across each category:
Breck, Eric, Shanqing Cai, Eric Nielsen, Michael Salib, and D. Sculley. 2017. “The ML Test Score: A Rubric for ML Production Readiness and Technical Debt Reduction.” Proceedings of the 2017 IEEE International Conference on Big Data (Big Data), 1123–32. https://doi.org/10.1109/bigdata.2017.8258038.
| Category | Test | Implementation Example |
|---|---|---|
| Data Tests | Feature expectations are captured in schema | Great Expectations, TFX Data Validation |
| All features are beneficial (no unused features) | Feature importance analysis, ablation studies | |
| No feature’s cost exceeds its benefit | Latency/accuracy trade-off analysis | |
| Data pipeline has appropriate privacy controls | PII detection, access logging | |
| Model Tests | Model spec is reviewed and checked into version control | Git-tracked model configs |
| Offline and online metrics are correlated | A/B test validation of offline improvements | |
| All hyperparameters are tuned | Automated HPO with tracked results | |
| Model staleness is measured and bounded | Performance decay monitoring | |
| Infrastructure Tests | Training is reproducible | Fixed seeds, versioned data, locked dependencies |
| Model can be rolled back to previous version | Model registry with versioning | |
| Training and serving code paths are tested for consistency | Feature store integration tests | |
| Model quality is validated before serving | Automated validation checks in CI/CD | |
| Monitoring Tests | Dependency changes result in alerts | Data schema monitoring |
| Data invariants hold in training and serving | Distribution comparison tests | |
| Training and serving features are not skewed | Training-serving skew detection | |
| Model staleness is monitored | Alerts and evidence-based retraining review |
Because the composite score is bounded by the minimum category, reliability audits must prioritize the bottleneck subsystem limiting the system score. Expanding a model test suite from 5 to 6 points while monitoring remains at 1 leaves the composite score unchanged, but can still improve actual coverage. The score highlights the weakest category without quantifying every reliability gain. Regular audits against this rubric reveal whether reliability risks stem from unvalidated input pipelines, offline-online distribution divergence, or uninstrumented serving paths, and so direct refactoring effort toward the debt that most threatens production. Each low category score also names the infrastructure that pays the debt down. A weak data score calls for schema contracts and shared feature definitions, a weak infrastructure score for versioned and reproducible pipelines, and a weak monitoring score for production telemetry.
14.8.2 Maturity levels
While the ML Test Score audits individual verification checks, operational maturity measures how cleanly those practices fit together across data pipelines, model training, and serving hardware (Zaharia et al. 2018). Adopting an experiment tracker such as MLflow while leaving feature extraction in ad hoc notebooks and model rollout to manual file copies raises isolated test counts without reducing production outages. Although operational maturity exists on a continuum, grouping systems into three distinct maturity levels clarifies how workflows evolve from exploratory prototypes into reliable production infrastructure.
Zaharia, Matei, Andrew Chen, Aaron Davidson, Ali Ghodsi, Sue Ann Hong, Andy Konwinski, Siddharth Murching, et al. 2018. “Accelerating the Machine Learning Lifecycle with MLflow.” IEEE Data Engineering Bulletin 41 (4): 39–45.
At the lowest level, workflows are ad hoc. Training runs manually on local workstations, feature extraction is embedded in ephemeral scripts, and deployment relies on manual file transfers. As maturity increases, teams make workflows repeatable by introducing version-controlled pipelines, centralized artifact registries, and scheduled batch jobs. At the highest level, declarative infrastructure-as-code, continuous validation pipelines, and real-time observability make systems scalable by decoupling model iteration from production serving.
Table 24 summarizes this architectural progression from disconnected execution toward unified lifecycle management.
| Maturity Level | System Characteristics | Typical Outcomes |
|---|---|---|
| Ad Hoc | Manual data processing, local training, no version control, unclear ownership | Fragile workflows, difficult to reproduce or debug |
| Repeatable | Automated training pipelines, basic CI/CD, centralized model storage, some monitoring | Improved reproducibility, limited scalability |
| Scalable | Fully automated workflows, integrated observability, infrastructure-as-code, governance | High reliability, rapid iteration, production-grade ML |
Consider how the ranking service evolves across these maturity levels:
- Ad hoc: A data scientist trains a model in a Jupyter notebook, exports it as a pickle file, and hands it to an engineer who deploys it to a single server. When accuracy drops, the data scientist retrains manually by running the notebook again with fresh data. Debugging requires the original data scientist because no one else understands the preprocessing steps.
- Repeatable: The training script is version-controlled, with a scheduled Jenkins job that retrains monthly. Features are computed in a SQL script that engineering maintains separately. The model is deployed via container, with basic accuracy monitoring. When the feature SQL changes, the data scientist must manually verify the model still works.
- Scalable: Training and serving use the same feature store, reducing skew. A CI/CD pipeline opens a drift investigation when PSI exceeds 0.25, retrains when evidence supports it, validates the new model against the baseline, and deploys via canary release. Monitoring tracks per-cohort click-through rate, triggering investigation when specific segments degrade. The entire lineage from raw data to production prediction is auditable.
The ML Test Score and these levels answer different questions, and neither converts into the other. The score reports which category of checks is weakest, and the level reports how far those checks run automatically and share one pipeline. A team places itself by reading table 24 against its own practices, and the weakest practice is a sensible guide to that placement, so a service with automated training but manually verified features belongs at the repeatable level, as the ranking service above does. The weakest score category then names the next control to add.
Moving between maturity levels takes substantial engineering investment, and its return is a lower mean time to recovery (MTTR) and fewer silent failures, which matters most for mission-critical services. Evaluating an organization against this spectrum isolates specific architectural bottlenecks (such as manual data transfers or unversioned preprocessing logic) before they compound into production outages.
14.8.3 System design implications
The repeatable ranking service above already automates training and deployment, yet a change to its separately maintained feature SQL still requires manual validation. More frequent retraining would increase the manual validation burden without removing the mismatch risk. A versioned feature contract and matched-request parity tests address the failure boundary first; a shared feature store becomes useful when maintaining that contract across pipelines warrants the additional infrastructure. Maturity assessment therefore selects the next missing control for each system.
Figure 12 provides a coverage map for that assessment. Service uptime is visible at the tip, while data- and model-health failures can remain hidden below the waterline. For each failure mode, the assessment must identify the evidence that exposes it and the action that contains it.
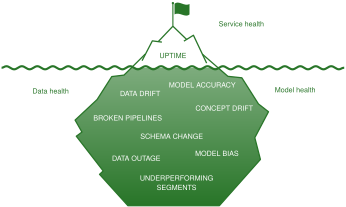
A system that logs all three health domains can still lack a response path. If stale features are detected but no validated fallback exists, containment is the next investment. If quality outcomes are recorded without the served model version, attribution must be repaired before automatic promotion can rely on them. If a canary can exhaust the production worker’s memory, resource isolation takes priority over another dashboard. Each finding identifies a specific capability to add and a failure against which to test it.
14.8.4 Design patterns and anti-patterns
Once the maturity assessment names a missing control, containment depends on an owner with the authority to change the affected system. A centralized MLOps team can maintain shared controls across models, while a federated model places engineers within product teams under shared architectural standards. Either arrangement must resolve the same handoff by specifying who validates a fallback, who can activate it, and who confirms recovery. Buying a commercial feature store or drift dashboard before settling that handoff exemplifies the tool-first anti-pattern, leaving the on-call team watching a failure they have neither the mechanism nor the authority to contain.
Once ownership is explicit, the residual failure determines the technical protection. Broken inputs require a way to stop harmful predictions; competing model versions require resource isolation. The cost of these controls is justified by the exposure they contain, and their effectiveness must be tested against that specific failure.
A circuit breaker automatically routes traffic away from a failing service when its error rate exceeds a threshold, and in ML serving it needs ML-specific trip conditions. Conventional circuit breakers trip when RPC timeouts or HTTP 5xx error rates exceed a set threshold. In an ML serving context, circuit breakers must also monitor invariants whose violation signals broken inputs rather than gradual drift: sudden shifts in feature bounds, missing-feature rates, or output distribution collapse. Gradual drift scores such as PSI open a diagnosis instead of tripping the breaker. When triggered, the circuit breaker bypasses the model to serve predictions from a deterministic heuristic fallback, a cached lookup table, or a simpler baseline model, preventing corrupted inferences from cascading into downstream transactional systems.
Similarly, bulkhead patterns25 isolate candidate or canary models from primary serving paths. For the ranking service, the bulkhead must reserve a canary’s full copy of the tables, 100 GB across two accelerators (table 11), rather than a slice proportional to its traffic share. On multi-tenant accelerator hardware, an unconstrained experimental model suffering an out-of-memory abort, memory leak, or thread-pool exhaustion can crash the shared serving runtime or stall the PCIe bus. Containerized memory limits, isolated worker queues, and supported hardware partitions can contain specific resource failures. Shared memory bandwidth, interconnects, and device-level faults still require explicit isolation analysis and testing.
25 Bulkhead pattern: This pattern partitions system resources to contain failures within isolated zones. In ML serving, a bulkhead allocates fixed accelerator memory, host RAM, and worker thread pools to experimental model versions, so a canary’s resource exhaustion is less likely to terminate the primary serving path; the protection depends on the process and hardware isolation actually enforced.
Redundancy has a hard limit in ML serving. Replicating a model across workers protects against crash faults but not against wrong answers, because replicas trained on the same data with the same architecture share the same blind spots and fail together and silently. Circuit breakers, bulkheads, and replication therefore strengthen an MLOps implementation only when each is applied to the failure class it can actually detect.
These patterns, like every operational practice in this chapter, must also adapt to physical, regulatory, and organizational constraints. A standard CI/CD pipeline may be infeasible without direct host access, monitoring may require indirect signals or on-device anomaly detection, and privacy regulations may limit data collection; these adaptations apply the same principles under constraint. Organizations operating many ML nodes consolidate into platform architectures with shared infrastructure and centralized governance, which raises challenges beyond single-node operations (cross-model resource allocation, system-level observability, and fault tolerance across interdependent pipelines). Sound single-model practices remain prerequisites, because gaps in monitoring, testing, or deployment multiply across the model portfolio, and each control added to close those gaps must earn its engineering and infrastructure cost.
14.8.5 MLOps investment economics
Spending \(\$100\text{K}\) a year on an enterprise feature store and automated retraining pipeline for an internal analytics model that drives \(\$20\text{K}\) in decisions is as much an engineering failure as starving a \(\$50\text{M}\) ranking engine of basic drift checks. Operational controls pay off only when their engineering and infrastructure cost matches the production value at risk.
Earlier sections priced each operational control in isolation, from the daily query loss of training-serving skew (equation 2) and the payback horizon of pipeline automation (notebook 14.1) to net retraining value (equation 3, equation 12), detection-delay exposure (notebook 14.3), and monitoring return (equation 7). Turning those separate figures into a sound investment decision requires combining them within a single accounting boundary rather than summing them naively. Because an unmitigated skew event manifests simultaneously as lost prediction value, an extended silent failure, and a production incident, adding those estimates directly would count the same underlying damage multiple times. Rigorous accounting establishes a common baseline and evaluation horizon, counts each prevented loss exactly once within a primary category, and separates routine deployment labor savings from emergency response hours already captured in incident costs. For a single ML node, the resulting accounting determines whether deployment speed, incident reduction, and monitoring coverage justify the operational spend; for a portfolio, the same discipline scales to justify platform investment.
Single-model MLOps investment
For a single production ML system, the first threshold is the annual cost of making the node observable, deployable, and recoverable. Table 25 summarizes the main cost categories:
| Component | Illustrative Assumption | Justification |
|---|---|---|
| CI/CD pipeline setup | $10–30K one-time | Reduces deployment time from days to hours |
| Monitoring and alerting | $2–10K/year | Shortens detection and response delays |
| Feature store (basic) | $5–20K/year | Reduces one source of training-serving skew |
| Model registry | $0–5K/year | Enables rollback, audit trails |
| Engineering time | 1–2 FTE-months setup | Initial automation and integration |
Single-model ROI calculation
The return threshold then depends on model criticality. A revenue-facing model can justify more operational spend because avoided incidents and deployment-time savings have measurable value. Equation 13 formalizes that single-node calculation by extending the monitoring benefit-cost ratio of equation 7 with a second benefit term, the engineering labor that automation recovers: \[\text{Annual Benefit/Cost} = \frac{\text{Incidents Avoided} \times \text{Avg Incident Cost} + \text{Time Savings} \times \text{Hourly Cost}}{\text{Annual MLOps Investment}} \tag{13}\] where Incidents Avoided is the count of production failures the tooling prevents per year and Avg Incident Cost is the total loss per failure, so their product is the value of avoided incidents. Time Savings is the engineer-hours that automation reclaims per year from routine release and maintenance tasks (strictly distinct from emergency triage labor already subsumed under Avg Incident Cost). Hourly Cost is the loaded labor rate, so Time Savings multiplied by Hourly Cost is the value of recovered deployment labor. The denominator is the annualized investment, including recurring tooling and engineering costs plus setup costs amortized over the chosen planning horizon. The worked investment below applies this non-overlapping accounting boundary. The ratio expresses benefit per dollar invested, not net profit per dollar.
Consider a revenue-facing model with the following annual figures:
- 4 incidents/year avoided (at $25K each) = $100K saved
- 20 hours/month deployment time saved (at $150/hr) = $36K saved
- MLOps investment of $30K/year
\[ \text{Benefit/Cost} = \frac{\$100K + \$36K}{\$30K} = 4.53\times \]
When to invest more
The 4.53× benefit-cost ratio holds because the model is expensive enough that preventing incidents and shortening deployments outweigh the annual platform spend. The returns from single-model MLOps practices compound when teams add additional models. The transition from operating several independent ML nodes to building a centralized platform involves different economics entirely, including shared infrastructure amortization, platform team overhead, and cross-model coordination costs.
For a single model, investment in MLOps should track the model’s criticality. A model driving $10M in annual revenue justifies more operational rigor than an internal analytics model. Monitoring, lineage, and repeatable deployment are often the first investments. A feature store earns its place when shared feature definitions and online-offline parity become material problems, and automated retraining is warranted only when evidence supports the trigger and the validation loop can contain a bad update.
Checkpoint 14.5: Choosing the next investment
Matching operational spend to model criticality settles how much infrastructure a deployment can justify, but the physical and regulatory environment still governs what that infrastructure can measure and change. When the operations loop leaves the data center for a battery-powered microcontroller or a regulated clinical workflow (section 14.9), power budgets and human oversight reshape how the system preserves evidence, validates updates, and recovers from failure.
Self-Check: Question
What fundamental reliability concept is illustrated by the ‘Uptime Iceberg’ metaphor in production machine learning systems?
- Traditional service availability (uptime and low latency) is only the visible tip; hidden failures like feature drift, concept drift, schema corruption, and subpopulation degradation lurk beneath the surface
- Distributed feature retrieval latency over wide-area networks always exceeds local GPU inference execution time
- Data center cooling overhead exceeds the total electrical power consumed by GPU inference accelerators
- Deep neural network weight storage in DRAM requires larger memory allocations than raw training dataset storage
An organization with limited engineering resources is deploying its first production ML model. Based on the chapter’s investment economics framework, which staging sequence provides the most cost-effective path to reliability?
- Construct an enterprise-wide multi-region distributed feature store and autonomous retraining cluster before deploying the initial model
- Invest first in statistical monitoring and basic CI/CD deployment pipelines, then add centralized feature stores and automated retraining as model scale and drift warrant
- Procure an all-in-one commercial MLOps platform suite to eliminate cross-functional on-call rotations
- Defer all monitoring and automation investments until multiple major production outages have occurred
Describe the organizational failure in which one team develops a model and hands it to another team for deployment without shared operational ownership, and explain how a cross-functional or federated MLOps structure resolves it.
An engineering team is assessing the operational maturity of an ML deployment. Place the three operational maturity stages in order from least mature to most mature:
- Repeatable: Version-controlled training scripts, scheduled batch retraining jobs, centralized model registry, and basic performance monitoring.
- Scalable: Shared feature definitions with verified training-serving parity, closed-loop drift detection with automated canary validation, and infrastructure-as-code.
- Ad Hoc: Hand-crafted Jupyter notebooks, local training on developer machines, manual pickle file deployment, and absence of formal versioning.
A team’s ML Test Score audit yields category scores of data 6, model 7, infrastructure 5, and monitoring 1 (each out of 7). Leadership proposes adding two new model tests next quarter. What does the rubric imply about that plan?
- It raises the overall score, because every added test increases the composite total
- It yields no gain in the rubric’s overall score, because the composite score is the minimum category and monitoring bounds it at 1
- It is the right priority, because model tests catch the largest share of production failures
- It lowers the overall score, because an unbalanced rubric penalizes over-investment in one category
14.9 Case Studies
A cloud MLOps playbook fails immediately if applied unmodified to a battery-powered voice trigger that cannot stream audio off the device, or to a clinical decision-support loop where an unreviewed weight update can harm a patient. The chapter’s keyword spotter operates under a milliwatt-scale power budget, kilobytes of on-device memory, and telemetry that must leave the device as aggregates rather than audio. In contrast, regulated AI-enabled medical devices require evidence and change controls appropriate to their intended use. FDA guidance for predetermined change control plans describes planned modifications, validation methods, and impact assessment (U.S. Food and Drug Administration 2025). These contrasting environments dictate how engineering teams manage data pipelines, model artifacts, and hardware execution across the lifecycle. Edge architectures devote most engineering effort to bridging the hardware gap between high-throughput cloud training clusters and microcontrollers, whereas clinical systems devote it to provenance tracking, cohort monitoring, and human-in-the-loop validation reviews.
U.S. Food and Drug Administration. 2025. Marketing Submission Recommendations for a Predetermined Change Control Plan for Artificial Intelligence-Enabled Device Software Functions. Guidance for Industry and Food and Drug Administration Staff. U.S. Department of Health; Human Services.
The edge case in section 14.9.1 follows the keyword spotter from its detection drop through deployment and monitoring, reusing the three-tier partition that a published wearable design makes concrete. The clinical case, ClinAIOps, places clinicians inside the operations loop. Despite their contrasting operating regimes, both deployments must satisfy the same core MLOps disciplines. Table 26 maps these foundational principles across the two environments, demonstrating how physical hardware limits and regulatory mandates alter implementation mechanisms without altering the underlying operational requirements.
| Principle | Keyword-spotting edge design | ClinAIOps |
|---|---|---|
| Reproducibility | Versioned audio datasets, DSP front end, and firmware alongside model weights | Audit trails, decision provenance |
| Separation of concerns | Independent data, training, and serving layers with an edge-specific OTA pipeline | Distinct clinical validation and deployment stages with regulatory compliance isolation |
| Consistency | One feature-extraction kernel shared by training and on-device inference | Standardized clinical data pipelines ensuring training-serving parity |
| Observable degradation | Aggregate on-device proxies (wake rate, false-wake reports, duty cycle) | Cohort-specific monitoring, outcome tracking |
| Cost-aware automation | Updates held until accuracy gain outweighs radio energy, flash wear, rollout risk | Automated model updates with human-in-the-loop review balancing update cost and patient risk |
14.9.1 Keyword spotting at the edge
Six months after launch, the keyword spotter’s detection rate had fallen four percentage points below target because of three silent changes in Operational Data Health. These were a new microphone revision with a different frequency response, evaluation labels revised under new guidelines, and an unannounced change to the device metadata schema. Operations inherits that failure on the chapter’s power-bound case. The fix must reach devices that no one can touch, the evidence must be gathered without uploading audio, and a bad update must be reversible without disabling the device.
Context and motivation
Keyword spotting partitions its computation across three tiers. The microcontroller runs the audio front end and the 200 KB INT8 DS-CNN continuously in its always-on island (the low-power domain of the chip that stays awake while the rest sleeps), a companion device or hub runs a heavier verification model when the detector fires, and the cloud aggregates fleet statistics and retrains.
The partition is not peculiar to keyword spotting. A published sleep-staging wearable, the Oura Ring, uses the same three tiers, and its published evaluation makes the work of each tier concrete (Altini and Kinnunen 2021). The ring captures accelerometry, optical photoplethysmography (PPG)26 for pulse rate and heart-rate variability, and skin temperature, and its 15–22 mAh battery rules out continuous Bluetooth Low Energy (BLE) streaming. Sensor preprocessing and lightweight activity classification run in the ring’s microcontroller firmware, the heavier multi-sensor sleep-stage sequence model runs on the companion phone during periodic synchronization, and historical aggregation and retraining run in the cloud. The versioning, telemetry, over-the-air, and lifecycle controls described later are a design for the keyword spotter informed by that partition, not a reported account of any vendor’s production system.
26 Photoplethysmography (PPG): Optical technique that infers blood-volume changes from variations in detected light after illuminating tissue. For ML operations, PPG introduces a data quality challenge absent in controlled environments. Motion artifacts from wrist movement corrupt the signal, creating a data drift pattern where the same physiological state produces different input distributions depending on user activity. Models must either filter corrupted windows before inference or learn to be robust to motion noise, and monitoring must distinguish genuine physiological changes from artifact-induced distribution shift.
Model development and evaluation
Evaluating an edge model against a reference standard is the same step on which the keyword spotter’s monitoring depends. The ring’s reference labels come from polysomnography (PSG),27 the laboratory-grade multichannel physiological recording used as the clinical reference for sleep staging. The evaluation paired the ring with simultaneous laboratory PSG for 106 participants and 440 nights of data. Under 5-fold cross-validation, four-stage sleep classification reached 57 percent accuracy from movement alone and 79 percent once heart-rate and temperature features were added (Altini and Kinnunen 2021), which is the evidence that justified the ring’s heavier phone-tier model. The reference itself is imperfect, because human PSG scorers agree with each other at only about 82 percent to 83 percent. The 22 percentage-point gain closes roughly 84.6–88 percent of the gap between the movement-only baseline and that human agreement.
27 Polysomnography (PSG): A multi-parameter sleep study that provides the clinical ground truth data for this classification task. This “truth” is inherently noisy; expert human scorers interpreting the same PSG recordings agree with each other at about 82 percent–83 percent reliability (Altini and Kinnunen 2021). Inter-scorer agreement indicates label uncertainty but does not impose an accuracy ceiling against a fixed or adjudicated reference.
Altini, Marco, and Hannu Kinnunen. 2021. “The Promise of Sleep: A Multi-Sensor Approach for Accurate Sleep Stage Detection Using the Oura Ring.” Sensors 21 (13): 4302. https://doi.org/10.3390/s21134302.
The keyword spotter faces the same evaluation problem with a weaker reference. Its labels come from reviewed recordings, and because the device uploads audio only when it wakes, a spoken wake word that the detector misses leaves no recording at all (Data drift detection and response). Measuring the false rejections behind the four-point drop therefore takes a separate, consented collection, and the evaluation set must be versioned by microphone revision so that a hardware change appears as a slice rather than being averaged away. Deploying the retrained model across the tiers then adds requirements that no offline study covers: reproducible quantization, numerical validation of the converted model on the device, and a runtime energy budget.
Key operational insights
Following offline validation, the systems challenge shifts from statistical accuracy to deployment safety and runtime efficiency. The toolchain for the keyword spotter needs an automated quantization pipeline that converts FP32 weights to INT8 with calibrated scale factors, deterministic cross-compilation for the firmware that runs the model, and cryptographically signed release packages for each hardware revision. It also needs fault-tolerant OTA delivery through the dual-bank scheme of section 14.4.4, whose cost is a second 200 KB flash bank (table 11).
Edge MLOps operates under physical constraints distinct from server-side pipelines. Model accuracy must be co-designed with battery life, radio bandwidth, and on-device storage, and real-time ground-truth labels are nearly absent. In the power-bound row of table 5, health monitoring relies on operational proxies (wake rate, duty cycle, false-wake reports, and confidence distributions) rather than verified outcomes. Recovering the four-point detection drop in the field requires configuration management across every execution target (the microphone hardware revision, the DSP front end, the firmware, and the quantized model weights) so that each fielded device’s combination can be traced and receive the right update.
These constraints map directly onto the five principles of table 26. Versioned audio datasets provide reproducibility by linking every deployed model to the recordings, labeling guidelines, and microphone revisions that trained it. Tiered software architecture enforces separation of concerns, isolating the device’s audio drivers and feature extractor from the hub’s verification model and the cloud’s aggregation, so that firmware, model, and fallback behavior can be updated independently. A feature-extraction kernel shared between training and the device reduces implementation divergence, while parity tests verify numerical agreement between the Python pipeline and the device’s DSP routine across firmware versions. Privacy-preserving telemetry keeps degradation observable by sending aggregate diagnostics (per-band energy histograms, wake counts, duty cycle, and battery drain) without streaming audio off the device. Finally, cost-aware automation applies to the over-the-air update, because every update must show that its accuracy gain outweighs the radio energy of reception, the flash rewrite cycles, and the risk of altering software on a device that is always listening.
The keyword spotter shows how milliwatts, kilobytes, and radio bandwidth dictate MLOps design. Moving machine learning from consumer devices into regulated healthcare shifts the primary constraint from hardware physics to patient safety, clinical validation, and algorithmic accountability, the operational domain of ClinAIOps.
14.9.2 ClinAIOps case study
In regulated medical care, an unreviewed model update or an uncalibrated sensor stream in a blood-pressure monitoring system can recommend an unsafe dose before a physician sees the chart. In continuous therapeutic monitoring (CTM),28 wearable sensors stream physiological telemetry to guide personalized medical interventions. General-purpose MLOps frameworks provide lifecycle automation (orchestrating pipelines, tracking artifacts, and monitoring availability). Clinical use adds intended-use-specific evidence, oversight, and authorization requirements because predictions may influence treatment. General-purpose MLOps can incorporate human review steps; a clinical operations framework makes their responsibilities explicit. The case is read here as an operations loop with clinicians inside it, specifying who may change a model, on what evidence, and how a change is reversed. Whether the objectives such a system pursues, and their effects on patients, are the right ones is a question of responsibility that Responsible Engineering develops.
28 Continuous therapeutic monitoring (CTM): Healthcare approach using wearable sensors for real-time physiological data collection and personalized treatment adjustments. CTM forces MLOps to confront constraints absent in typical deployments: feedback loops require oversight appropriate to the intended use, training labels need clinical validation, and model changes must follow applicable authorization and change-control requirements. These constraints reshape every MLOps principle, making CTM a stress test for operational maturity.
The proposed ClinAIOps framework (Chen et al. 2023) adapts MLOps principles to these constraints by formalizing the boundaries between algorithmic inference and clinical authority. Rather than treating human oversight as an external obstacle, ClinAIOps builds multi-party feedback loops directly into the serving architecture. The framework partitions operational control across three actors (patients, clinicians, and machine learning engineers), each operating on distinct timescales with explicit approval steps.
Feedback loops
Three interlocking feedback loops organize the proposed integration of machine learning into clinical practice; their effectiveness and safety require validation in the intended setting. Figure 13 models these three interlocking feedback loops as a triangular protocol among the patient, clinician, and AI developer. Each pair of actors exchanges different information in both directions. The patient streams wearable sensor telemetry and receives clinician-approved therapy alerts. The AI developer provides longitudinal monitoring summaries while accepting physician-defined dosing bounds. The clinician directly governs patient therapy regimens while establishing safety boundaries for algorithmic actuation. The outer cycle connecting all three nodes forms the overarching clinical governance framework.
Each feedback loop operates on a distinct timescale to balance responsiveness against clinical verification. The patient treatment loop executes continuously in real time, capturing sensor telemetry and delivering bounded adjustments for patient self-management. At an asynchronous supervisory cadence, the clinician oversight loop reviews aggregated trends, sets operational boundaries, and validates treatment recommendations before interventions occur. Finally, the developer feedback loop aggregates telemetry and clinician override patterns back to engineering teams, driving offline retraining and interface calibration.
Patient treatment loop
The patient treatment loop executes localized inference over high-frequency physiological streams captured by wearable devices, such as continuous glucose monitors or optical pulse sensors. The edge serving runtime evaluates these incoming feature vectors against recent patient history from electronic health records. In this proposed design, recommendations follow a tiered execution model as one safety control. Minor adjustments that fall strictly within clinician-defined bounds are surfaced directly to the patient. Significant changes, and recommendations generated when model uncertainty exceeds an acceptable margin, are blocked from automated delivery and escalated to the clinician. This structure enables rapid adaptation to dynamic physiological states within validated, authorized operating limits; those limits and the escalation mechanism must be tested.
Clinician oversight loop
The clinician oversight loop provides supervisory control over automated inference. Rather than burdening medical staff with continuous raw sensor telemetry, batch aggregation pipelines distill time-series streams into longitudinal summaries, such as circadian variance, multi-day trends, and signal-quality metrics. When the system generates a therapy recommendation, such as lowering the dose of a blood-pressure medication (an antihypertensive), the clinician evaluates the proposal alongside diagnostic factors unobserved by the wearable model and may approve, modify, or reject the recommendation. This decision is written to an audited event log, which enforces clinical accountability at the point of care and records expert feedback for later review. Approval or override is not by itself a verified patient outcome and using it as training supervision requires a defined label interpretation and validation. Clinicians also update the operational thresholds that govern the patient treatment loop, recalibrating the boundary between automated guidance and mandatory review.
Developer feedback and patient-clinician coordination
Offloading continuous data logging and low-level trend detection to the AI pipeline changes the patient-clinician relationship itself. Consultations shift from routine measurement gathering to targeted clinical evaluation and goal setting, an outcome the patient and clinician loops produce together, while the third loop, developer feedback, links that clinical practice back to engineering infrastructure. Operational telemetry generated during these interactions provides engineering teams with direct visibility into production behavior. Overrides, rejection frequencies, and reported adverse events motivate investigation of model behavior, workflow fit, patient mix, and sensor quality, even though they do not uniquely diagnose covariate shift. Engineers use the resulting evidence to evaluate targeted retraining, refine data validation schemas, and eliminate usability failure modes that induce alert fatigue in clinical staff.
Hypertension case example
In the proposed framework, the three operational loops could coordinate care for hypertension management. Blood pressure fluctuates continuously under exertion, stress, and circadian cycles, requiring individualized, long-term pharmacological adjustments that benefit from continuous therapeutic monitoring.
Data infrastructure
Research systems estimate blood pressure indirectly from wearable pulse signals such as photoplethysmography (PPG) (Zhang et al. 2017). In the illustrative workflow, these signals are augmented by accelerometer streams to identify motion artifacts and self-reported medication logs. Clinical use requires rigorous calibration and prospective validation for the intended task, together with any applicable regulatory authorization; authorization alone does not establish accuracy for every cohort. When properly validated for the target cohort, this multimodal data stream is merged with electronic health records to supply feature context for inference.
Zhang, Qingxue, Dian Zhou, and Xuan Zeng. 2017. “Highly Wearable Cuff-Less Blood Pressure and Heart Rate Monitoring with Single-Arm Electrocardiogram and Photoplethysmogram Signals.” BioMedical Engineering OnLine 16 (1): 23. https://doi.org/10.1186/s12938-017-0317-z.
Loop implementation
The hypertension workflow labels each of its three panels by the two parties in the exchange (figure 14), so the panels do not line up one-to-one with the three loops of figure 13. The patient-AI panel is the patient treatment loop, the clinical-AI panel is the clinician oversight loop, and the patient-clinical panel is the coordination those two loops produce together. The developer feedback loop operates out of band, as described in section 14.9.2.1, and does not appear.
Across the top of the figure, the two AI-assisted loops operate concurrently. The patient-AI panel (upper left) captures continuous blood-pressure telemetry and issues recommendations for bounded dose titrations, while the clinical-AI panel (upper right) alerts the physician to severe hypertensive excursions and accepts updated titration boundaries. Below them, the patient-clinical panel captures the resulting clinical relationship, where routine telemetry offloaded to the AI loop frees consultation appointments for longitudinal trend review, adverse-event evaluation, and shared lifestyle goal setting.
Chen, Emma, Shvetank Prakash, Vijay Janapa Reddi, David Kim, and Pranav Rajpurkar. 2023. “A Framework for Integrating Artificial Intelligence for Clinical Care with Continuous Therapeutic Monitoring.” Nature Biomedical Engineering 9 (4): 445–54. https://doi.org/10.1038/s41551-023-01115-0.
The three panels illustrate a proposed boundary for clinical automation, not an established treatment protocol: routine monitoring and bounded dose recommendations operate within validated, authorized clinician-defined thresholds, while acute escalations, adverse events, and regimen changes require explicit human authorization. That boundary is the point where ordinary MLOps practices require the additional clinical coordination summarized next.
MLOps vs. ClinAIOps comparison
Healthcare deployments such as the hypertension case differ operationally from standard software pipelines. General-purpose MLOps provides technical lifecycle controls such as automated testing, continuous integration, model registries, and drift monitoring. ClinAIOps extends this foundation into regulated clinical environments where outputs directly influence medical interventions. Table 27 compares the two approaches across eight operational dimensions.
| General-purpose MLOps emphasis | ClinAIOps extension | |
|---|---|---|
| Focus | Technical model lifecycle | Human and AI decision-making |
| Stakeholders | ML, data, platform, and operations teams | Adds patients, clinicians, and clinical governance |
| Feedback loops | Monitoring, retraining, and release | Adds treatment, clinician, and developer feedback |
| Objective | Reliable, governed ML operations | Safe, effective, and accountable care support |
| Processes | Automated pipelines and operational controls | Integrates clinical workflows and human review |
| Data considerations | Lineage, quality, freshness, and access control | Adds consent, clinical provenance, and protected data |
| Model validation | Predictive, operational, and slice-level metrics | Adds clinical utility, safety, and cohort outcomes |
| Implementation | Technical integration and operational ownership | Adds clinical accountability and stakeholder incentives |
The table’s central distinction is that clinical deployment alters risk ownership. Statistical accuracy is a prerequisite, but it does not protect against liability when an erroneous prediction drives a medical intervention. The ClinAIOps framework therefore changes the governing constraint from device efficiency to clinical accountability. The model participates in care delivery, but it cannot own clinical decisions. Every recommendation and subsequent clinician action must be traceable to the underlying sensor inputs, model version, and inference metadata; otherwise the system cannot support regulatory audit or retrospective incident analysis. Separation of concerns shifts from an architectural preference to a safety invariant: sensor ingestion, inference scoring, clinical diagnosis, and parameter updates must be decoupled by explicit software interfaces and human approval steps.
The same accountability requirement transforms monitoring. Standardized clinical data pipelines support training-serving parity, but clinical validation requires evaluating model recommendations against standard-of-care outcomes and cohort-specific effects. Observable degradation extends beyond statistical loss and latency to clinical metrics: blood pressure control rates, adverse events, clinician overrides, and subgroup disparities. In this regime, multi-tier feedback loops are not unwanted operational latency; they are deliberate architectural controls that balance automated edge adaptation against legal and ethical accountability. Cost-aware automation operates strictly inside those approval limits. Model refreshes occur only when validated clinical benefits outweigh validation costs and patient risks, and low-confidence predictions trigger deterministic fallback to human clinical review.
14.9.3 Case study synthesis
The keyword spotter and ClinAIOps cases separate stable MLOps principles from the deployment constraints that reshape their implementation. Copying an edge OTA pipeline into a hospital workflow or requiring clinician sign-off on every consumer wake-word update fails because it mistakes a domain-specific tool for the underlying principle. The keyword spotter is a resource-envelope case. Its operations must preserve reproducibility, consistency, and observable degradation while battery, telemetry, and weak ground truth limit what can be measured and updated on the device. ClinAIOps is an accountability-envelope case. The same principles apply, but validation, audit trails, and human review dominate because the model influences clinical action.
The shared engineering lesson is that MLOps maturity is not tool accumulation. It is the ability to identify the governing constraint, choose the operational controls that match it, and preserve evidence when the model changes.
Checkpoint 14.6: Transferring the operational principles
Self-Check: Question
In the keyword-spotting edge design, how do edge hardware constraints (microcontroller memory, battery capacity, intermittent connectivity) reshape the implementation of foundational MLOps principles?
- They eliminate the requirement for artifact versioning because firmware cannot be updated over the air
- They require continuous on-device distributed backpropagation to retrain neural networks nightly
- They favor lightweight on-device feature extraction, OTA deployment with rollback safety, and selective batched telemetry rather than continuous cloud streaming
- They allow the system to bypass training-serving consistency because raw sensor data is processed without filtering
Why does the ClinAIOps clinical AI framework intentionally incorporate clinician-in-the-loop override points as a core architectural feature rather than viewing human review as a failure of automation?
- Because FDA regulations strictly forbid machine learning algorithms from executing in clinical settings
- Because clinical patient distributions never experience covariate shift or demographic drift
- Because human review eliminates the need for regulatory audit trails or data provenance tracking
- Because in healthcare, the asymmetric cost of diagnostic error involves patient harm, making expert oversight an essential risk-mitigation control in cost-aware automation
In the Oura sleep-stage study, multi-sensor enhancement increased four-stage sleep classification accuracy from \(57\%\) (accelerometer baseline) to \(79\%\), while human polysomnography (PSG) inter-scorer agreement is \(82\%\text{--}83\%\). Calculate the fraction of the reference gap closed by the enhanced model and explain the systems lesson of comparing model accuracy against human agreement.
True or False: When transitioning an MLOps architecture from a cloud environment to a battery-constrained edge wearable, the foundational principles of reproducibility and consistency are discarded in favor of battery life.
14.10 Fallacies and Pitfalls
Operating production machine learning systems under conventional software assumptions creates distinct failure modes, each a place where a standard software engineering intuition breaks down against the statistical behavior of deployed models.
Fallacy: MLOps is just applying traditional DevOps practices to machine learning models.
Engineers often assume that standard CI/CD pipelines transfer directly to machine learning. Traditional DevOps automates code builds, testing, and artifact deployment with controls for dependencies and execution environments. In an ML system, code represents only one axis of the D·A·M triad. Model execution depends jointly on code, large evolving datasets, and accelerator compute budgets. As detailed in section 14.3.2.1, ML pipelines introduce stateful retraining, multi-metric validation checks, and immutable artifact registration. Standard CI/CD engines cannot natively track data lineage, orchestrate feature stores, or detect distribution drift. When teams apply DevOps without ML-specific adaptations, they maximize the computational availability of their serving cluster while leaving statistical behavior unmonitored. The system achieves high uptime and low latency, yet silently serves degraded predictions due to unvalidated data shifts and training-serving skew. The cost is concrete. A 1 percent skew rate on 1,000,000 queries/day costs $365,000 a year (equation 2) while every DevOps health check stays green.
Pitfall: Treating model deployment as a one-time event rather than an ongoing process.
Treating deployment as a terminal milestone assumes that deployed weights remain permanently aligned with the production input distribution. Unlike compiled binaries whose execution semantics remain fixed, model quality can change as real-world distributions shift. Monitoring statistical indicators such as PSI (section 14.5.2.1) provides an early signal of feature drift, distinguishing benign variance from actionable distribution change. Crossing a warning threshold requires operational diagnosis rather than unvalidated retraining. As established in section 14.6.2, scheduling updates is an economic balancing problem. The optimal retraining interval \(\RetrainingInterval^* \approx \sqrt{\frac{2\RetrainingRunCost}{\DailyQueryVolume\cdot \AccuracyPayoffPerQuery\cdot \InitialAccuracy \cdot \AccuracyDecayRate}}\) weighs the fixed compute and engineering cost \(\RetrainingRunCost\) against the business losses accumulated from daily query volume \(\DailyQueryVolume\), unit accuracy value \(\AccuracyPayoffPerQuery\), and staleness decay rate \(\AccuracyDecayRate\). For the ranking service, a 0.24 percent daily decay on 1,000,000 requests a day puts that optimum near 3 days (notebook 14.6), a cadence no one-time deployment can meet. Operating a production model demands treating deployment as a continuous control loop that balances monitoring signals against retraining economics.
Fallacy: Automated retraining ensures optimal model performance without human oversight.
Automating pipeline execution does not eliminate the need for operational governance. Closed-loop retraining pipelines operate without semantic awareness; if upstream data ingestion suffers schema anomalies, corrupted labels, or sudden sensor drift, automated retraining bakes those errors directly into updated model weights. In addition, automated validation checks typically evaluate aggregate loss across a held-out test split, which easily conceals severe performance regressions on critical slices or low-frequency edge cases. For instance, retraining a ranking model on weekend traffic can degrade performance on weekday traffic, where user query distributions diverge. An aggregate check would pass it, just as the 91 percent overall accuracy in table 20 conceals a tablet slice at 62 percent. Resilient MLOps architectures decouple automated pipeline execution from automated production promotion, enforcing canary deployments, slice-level regression tests, and human sign-off when validation metrics deviate from expected historical envelopes.
Pitfall: Focusing on technical infrastructure while neglecting organizational and process alignment.
Investing in MLOps tooling without defining organizational interfaces leads to fragmented operational ownership. Machine learning systems bridge two distinct engineering cultures: model developers optimizing offline accuracy metrics and platform engineers managing host-level latency, memory capacity, and throughput budgets. When organizations treat deployment as a handoff between isolated teams, root-cause triage stalls during production incidents. Infrastructure engineers inspect container health and GPU utilization without insight into model prediction distributions, while model authors inspect offline training curves without understanding runtime serving constraints. The ML Test Score (section 14.8.1) makes the gap measurable, because a deployment with a perfect model suite and no production monitoring scores 0 under its minimum-category rule. Tools such as feature stores and registries provide technical scaffolding, but reliability requires institutional alignment: unified SLOs spanning statistical accuracy and serving latency, joint on-call runbooks, and shared accountability for production regressions.
Fallacy: Training and serving environments automatically remain consistent once pipelines are established.
Establishing an initial end-to-end pipeline does not guarantee permanent parity between training and serving. Training-serving skew arises from fundamental architectural divergences between offline and online execution paths. Training typically runs as an offline batch workflow (such as distributed SQL queries or Spark pipelines) optimized for high-throughput scans over historical logs, whereas online serving runs in low-latency microservices under millisecond latency constraints. Maintaining dual implementations of feature transformations across these environments risks numerical disparities, differing missing-value semantics, or lookahead bias in historical joins. On the ranking service, the two paths computed user_session_length with means of 45 and 12 minutes and cost 8 percent of accuracy with no change to model code (section 14.3.1.1.2). As demonstrated in section 14.3.1.1, feature stores alleviate this divergence by unifying transformation logic and synchronizing batch and point-lookup stores. However, software pipelines alone cannot guarantee consistency. Operational verification requires request-keyed value comparisons and schema assertions between offline replays and online inference inputs, alongside separate distribution monitoring to catch divergence before it degrades downstream decisions.
Pitfall: Assuming comprehensive monitoring prevents all production incidents.
Dashboards and alert thresholds cannot prevent production outages caused by silent data failures. Monitoring supplies evidence; reducing harm also requires a response. Input-boundary checks can catch some defects before inference, while statistical quality estimates may arrive after affected predictions have been served. Tracking output metrics alone also leaves critical blind spots along the data pipeline. As shown in section 14.5.2.1, measuring service latency and prediction distributions fails to detect input anomalies such as feature staleness. An inference service can maintain nominal p99 response times and normal prediction ranges while consuming stale user embeddings caused by upstream database replication lag or cache eviction failures. By the time downstream business metrics degrade, corrupted predictions have already impacted users; an input-boundary check acts on the first malformed request, without waiting for labeled outcomes to accumulate. Production reliability requires defensive boundary controls alongside passive observability: strict input schema enforcement, feature freshness assertions, and circuit breakers that fall back to deterministic heuristics when input quality slips below operational tolerances.
Fallacy: Accuracy is the first production signal to monitor, so leading indicators can wait on a dashboard.
Teams often configure accuracy dashboards as their primary operational tripwire, assuming degradation will register there first. When outcome labels arrive late, ground-truth accuracy is a lagging indicator, because in production environments such as fraud detection, ad conversion, or credit underwriting those labels often require weeks or months to accumulate through chargebacks or repayment histories. Relying solely on accuracy dashboards leaves the system operating blind throughout this label-delay window. Even when labels arrive promptly, aggregate accuracy can remain deceptively stable while input distributions diverge across critical sub-populations. As detailed in section 14.5.2.1, monitoring input feature distributions with metrics like PSI or Kullback-Leibler (KL) divergence supplies indicators that can be estimated from sufficient input samples without labels. These statistical signals detect distribution shifts without waiting for labels, often enabling investigation before delayed outcome metrics are available, without guaranteeing that prediction errors have not already occurred.
Waiting for labels is slow, and the delay has a price. The same evidence budget that one labeled outcome per second fills in about 16.7 minutes takes 10 days at 100 outcomes a day. In the silent-failure scenario, each incident detected at monthly rather than daily review costs $184,932 more (notebook 14.3). A leading indicator recovers that time only when it is routed to an owner with a response deadline, an escalation rule, and a diagnostic runbook; drift and freshness warnings parked on an informational dashboard accumulate unnoticed until an emergency forces a response.
Observability in production machine learning extends far beyond passive dashboard telemetry. It requires closed operational loops across the entire D·A·M architecture: enforcing input data integrity and feature stability, bounding model behavior through automated validation checks, and routing leading indicators directly to engineers empowered with diagnostic runbooks to investigate changes and limit harm.
Self-Check: Question
When ground-truth labels arrive days later, why is relying only on accuracy as the first production signal to monitor a dangerous operational fallacy in ML systems?
- Because neural network accuracy cannot be mathematically computed after model weights are converted to ONNX format
- Because accuracy then becomes a lagging indicator that depends on delayed labels, whereas drift proxies such as PSI may provide earlier warning of distribution shifts without guaranteeing harm detection
- Because traditional infrastructure availability (HTTP 200 responses and uptime) guarantees that model accuracy remains static
- Because input feature distributions never change unless model source code is redeployed
Explain why routing leading-indicator alerts (such as feature drift or data freshness violations) to an unowned low-priority chat channel with no review or escalation path, while paging on-call engineers only for HTTP 500 errors, is a critical operational pitfall.
True or False: Unconstrained automated retraining without validation checks or human oversight is guaranteed to maintain optimal model performance in production.
14.11 Summary
MLOps extends software reliability with controls for learned behavior, data dependencies, and statistical uncertainty. A crashed server or network timeout turns availability dashboards red immediately, alerting operators to take corrective action. A degraded model, by contrast, introduces a silent statistical failure mode. The serving infrastructure returns 200 OK responses within latency deadlines, yet prediction quality can deteriorate undetected. Machine learning operations keeps that decay observable by treating model quality as a dynamic runtime variable rather than a static deployment artifact.
The five principles of table 2 provide an evaluation framework that applies regardless of scale or domain, and each now has a home in the operations loop. Reproducibility lives in versioned artifacts and the model registry, and separation of concerns in the boundaries that releases and incidents respect. Consistency lives in shared feature definitions checked by request-keyed parity tests, and observable degradation in layered monitoring. Cost-aware automation lives in the retraining criterion and the interval it implies.
Infrastructure components implement these principles across three operational boundaries. Feature stores and data versioning govern the data-model interface by reducing training-serving inconsistency. CI/CD pipelines and model registries govern the model-infrastructure interface by enforcing reproducibility and enabling rollback. Monitoring systems, incident response frameworks, and on-call practices govern the production-monitoring interface by making degradation observable and actionable while the retraining decision framework connects measured degradation to economic thresholds.
Domain constraints reshape how these principles are implemented without changing which principles matter. The capacity-bound ranking service pays for safe releases in memory, a second resident copy of its embedding tables for every shadow, canary, or standby, and pays for retraining in accelerator-hours that contend with those copies. The power-bound keyword spotter pays in flash, radio energy, and evidence it cannot upload. Similarly, ClinAIOps demonstrates why high-stakes clinical deployments require graceful-degradation and human-oversight controls, with three feedback loops functioning as architectural patterns rather than operational overhead.
The chapter’s operating rules fit on one page (table 28). Together they let an engineer estimate, before an incident forces the question, what a control costs and when it pays for itself.
| Quantity | Formula | Where derived |
|---|---|---|
| Skew cost | \(\text{Skew Cost} = \text{Rate}_{\text{skew}} \times \DailyQueryVolume\times \ErroneousPredictionCost\) | equation 2 |
| Retraining criterion | \(\text{Retrain if: } \FiniteChange\text{Accuracy} \times \text{Value per Point} > \text{Training Cost} + \text{Deployment Risk}\) | equation 3 |
| A/B sample size | \(\RequiredUsersPerVariant= \frac{2(\ConfidenceCriticalQuantile+ \PowerCriticalQuantile)^2 \OutcomeStandardDeviation^2}{\MinimumDetectableEffect^2}\) | equation 4 |
| Detection delay | Evidence budget in labeled examples divided by the labeled-outcome arrival rate | Notebook 14.2 |
| Population stability index | \(\text{PSI} = \sum_{i=1}^{\PopulationStabilityBinCount} (\text{actual}_i - \text{expected}_i) \times \ln\left(\frac{\text{actual}_i}{\text{expected}_i}\right)\) | Data drift detection and response |
| Telemetry cost rate | \(\text{Cost rate} \approx \TelemetrySeriesCount \TelemetrySamplingFrequency\left(\IngestionPricePerSample+ \SampleStorageSize \TelemetryRetentionDuration \StorageCapacityPrice\right)\) | equation 5 |
| Monitoring benefit and cost | \(\text{Monitoring Benefit/Cost} = \frac{\text{Incidents Prevented} \times \text{Avg Incident Cost}}{\text{Annual Monitoring Cost}}\) | equation 7 |
| Accuracy decay | \(\AccuracyAfterDeployment(\DeploymentAge) = \InitialAccuracy \cdot e^{-\AccuracyDecayRate \DeploymentAge}\) | equation 8 |
| Optimal retraining interval | \(\RetrainingInterval^* \approx \sqrt{\frac{2 \cdot \RetrainingRunCost}{\DailyQueryVolume\cdot \AccuracyPayoffPerQuery\cdot \InitialAccuracy \cdot \AccuracyDecayRate}}\) | equation 12 |
Key Takeaways: Perfectly available, perfectly wrong
- ML systems fail silently without outcome monitoring: Model quality may degrade as distributional divergence \(\DivergenceMeasure(\CurrentDistribution \lVert \TrainingDistribution)\) grows, although divergence alone does not determine accuracy loss. Because a serving host can maintain perfect uptime while predictions fail, tracking ground-truth outcomes is essential rather than relying on server health checks alone.
- Training-serving skew corrupts inference without crashing: Feature stores mitigate skew by unifying feature definitions and transformations across environments, but maintaining parity still requires continuous validation across online and offline data pipelines.
- Deploy through graduated rollout with pretested rollback: Canary, blue-green, and shadow deployments partition release risk across production traffic, backed by tiered rollback procedures that must be verified through regular operational drills. For a capacity-bound model, each of these controls holds a full second copy of the model in memory, whatever share of traffic it serves.
- Retraining is an engineering optimization, not a guess: The fitted staleness cost model \((\RetrainingInterval^* \approx \sqrt{2\RetrainingRunCost/(\DailyQueryVolume\cdot \AccuracyPayoffPerQuery\cdot \InitialAccuracy \cdot \AccuracyDecayRate)})\) balances retraining compute against prediction quality decay, connecting update cadence to quantitative economics under its stated assumptions.
- Stage infrastructure investments by system risk: Instrumentation and continuous deployment form the initial operational baseline. High-consequence systems justify greater operational rigor; feature stores and automated retraining should be added as skew and scale demand.
- The five principles transfer across domains: Reproducibility, separation of concerns, consistency, observable degradation, and cost-aware automation remain invariants across applications; domain constraints reshape only their concrete mechanisms and tool implementations.
- Operational maturity is organizational as well as architectural: Managing a single model differs qualitatively from governing a production fleet. While the core principles scale, operational complexity grows with fleet size, making unified incentives and shared on-call rotations as essential as tooling.
This operational discipline distinguishes production ML engineering from development experimentation. When a deployed model degrades, systematic instrumentation enables practitioners to isolate the failure mode: identifying data drift through distribution divergence checked against labeled outcomes (principle 10), training-serving skew through preprocessing parity audits (principle 11), configuration debt through artifact provenance, and feedback loops through temporal output tracking. Treating production ML as a “deploy and forget” exercise ignores these distinct dynamics.
Tracing each failure mode to its source roots ML operations in the D·A·M taxonomy. In an ML system, code, weights, and accelerator hardware can remain unchanged while the data axis moves beneath them, changing the predictive behavior that the system must validate. That exposure is the other side of the bitter lesson. Behavior learned from data rather than written by hand is what lets these systems outperform hand-built rules, and it is also what lets their behavior change whenever the data does, with no line of code recording the change. The match between model and world is not an engineering state reached once at deployment, but an ongoing cost paid continuously through telemetry, validation checks, and cost-calibrated retraining. System reliability must therefore measure prediction outcomes rather than server uptime alone, because the most dangerous failure mode in production is a green dashboard masking a drifting model. That machinery keeps a model faithful to its objective; whether the objective itself was right, and for whom, is the next question.
What’s Next: From reliability to responsibility
A model can track its training target perfectly and still do harm. It can reproduce historical bias, misallocate errors across groups, or mishandle personal data while every reliability check and aggregate accuracy metric stays green. Responsible Engineering takes up that specification gap, extending the monitoring discipline of this chapter from predictive quality to the outcomes a system produces for the people it affects.
14.12 Self-Check Answers
Self-Check: Answer
The chapter’s ranking service keeps its P99 latency inside budget, 99.99% server availability, and zero HTTP error responses. However, over four weeks, its click-prediction accuracy drops from 94% to 88% after a competitor’s promotion shifts what users click. Which operational challenge does this scenario illustrate?
- The hardware compute capacity ceiling between GPU memory and host memory
- The protocol communication overhead between REST endpoints and gRPC streaming
- The operational mismatch between traditional infrastructure availability and statistical predictive correctness
- The serialization throughput bottleneck between CPU preprocessing and accelerator execution
Answer: The correct answer is C. The operational mismatch between traditional infrastructure availability and statistical predictive correctness. Traditional infrastructure monitoring tracks server uptime, request latency, and HTTP status codes, none of which detect statistical decay in model predictions. When user behavior shifted, the model failed silently while all infrastructure dashboards remained green. The choices concerning hardware memory capacity ceilings, serialization bottlenecks, and network communication protocols describe systems and computational constraints rather than the statistical observability gap that motivates MLOps.
Learning Objective: Explain how the operational mismatch between infrastructure availability and statistical predictive correctness motivates MLOps
Which scenario represents a direct failure of the Data-Model Interface in a production ML system?
- An inference container crashes upon startup because the host system has an incompatible CUDA driver
- A candidate model deployment is delayed because previous model weights were not cached in warm standby
- A statistical drift alert is routed to an unmonitored ticketing queue instead of the on-call engineer
- An online inference service computes user_session_duration in seconds while the offline training pipeline calculated it in minutes
Answer: The correct answer is D. An online inference service computes user_session_duration in seconds while the offline training pipeline calculated it in minutes. The Data-Model Interface governs feature consistency and transformation alignment between data pipelines and model training/serving; diverging feature definitions between offline and online systems is a textbook failure of this interface. A container crashing due to CUDA driver incompatibilities or delayed deployments due to lack of warm standby are Model-Infrastructure Interface failures. A misrouted drift alert represents a Production-Monitoring Interface failure.
Learning Objective: Classify operational system failures according to the three critical MLOps interfaces
Explain why MLOps treats a deployed model as a closed-loop control system rather than a terminal release pipeline.
Answer: MLOps treats deployment as a closed-loop control system because the data environment may change after launch, and a model can remain available while its prediction quality degrades or its assumptions stop matching production inputs. The loop continuously gathers telemetry on system health, input distributions, and—when labels or outcomes arrive—prediction quality, then uses that evidence to diagnose whether action is needed. If investigation supports intervention, the team can retrain, validate, and release a new model through staged rollout rather than assuming drift alone automatically authorizes an update.
Learning Objective: Analyze why MLOps uses monitoring and conditional corrective updates to manage changing production conditions over time
True or False: An ML Node is defined solely as the trained neural network weight file packaged inside a container runtime.
Answer: False. An ML Node is the complete, self-contained operational unit for a single machine learning application, encompassing data ingestion pipelines, feature computation, model training, serving infrastructure, and monitoring/telemetry systems. Packaging weights in a container is only a single component of the Model-Infrastructure layer.
Learning Objective: Define the operational scope and architectural components comprising a single ML Node
A production recommendation service processes \(Q = 2 \times 10^6\) queries per day. Due to a feature encoding discrepancy between offline training and online serving, \(\text{Rate}_{\text{skew}} = 0.005\) (\(0.5\%\) of queries) receive incorrect predictions, each causing an estimated business loss of \(C_{\text{error}} = \$0.20\). Using the chapter’s skew-cost equation, what is the annual financial impact of this inconsistency over a 365-day year?
- \(\$730,000\) per year
- \(\$73,000\) per year
- \(\$200,000\) per year
- \(\$36,500\) per year
Answer: The correct answer is A. \(\$730,000\) per year. The skew cost equation is \(\text{Skew Cost} = \text{Rate}_{\text{skew}} \times Q \times C_{\text{error}} \times \text{Days}\). Substituting the parameters: \(\text{Daily Cost} = 0.005 \times (2 \times 10^6) \times \$0.20 = 10,000 \times \$0.20 = \$2,000/\text{day}\). Multiplying across 365 days yields \(\$2,000 \times 365 = \$730,000/\text{year}\). The choice of \(\$73,000\) underestimates the daily volume by a factor of 10, while \(\$36,500\) and \(\$200,000\) fail to reflect the compound product of daily query volume, skew error rate, error cost, and days in a year.
Learning Objective: Calculate the annualized financial impact of training-serving skew using the skew cost equation
Explain how the principle of ‘Separation of Concerns’ across the four MLOps functional layers (Data, Training, Serving, Monitoring) limits the blast radius of operational updates.
Answer: Separation of concerns places the Data, Training, Serving, and Monitoring layers behind modular interfaces so teams can change one layer without automatically rewriting the others. For example, a serving-runtime update or a monitoring-threshold change can often proceed independently, but only if interface contracts remain compatible and integration tests verify that the change did not break adjacent layers. The practical effect is reduced coupling and easier fault isolation, not a guarantee that one layer can never affect another.
Learning Objective: Analyze how separation of concerns reduces coupling and helps isolate faults across MLOps functional layers
Self-Check: Answer
According to Sculley et al. (2015), what additional mechanisms make technical debt in machine learning systems especially hard to detect and manage compared with ordinary code-focused debt?
- Because ML frameworks prevent developers from running unit tests or continuous integration jobs
- Because ML algorithms require more lines of raw mathematical code than supporting infrastructure software
- Because ML debt accumulates through implicit statistical relationships, data dependencies, and feedback loops that can degrade predictive quality silently without throwing runtime exceptions
- Because neural network parameters cannot be serialized to disk or stored in artifact registries
Answer: The correct answer is C. ML systems add debt through implicit statistical relationships, hidden data dependencies, and feedback loops that standard code-level checks may not expose, so predictive quality can degrade even while the service stays up. An answer based on unsupported frameworks or unserializable weights is simply false, and the “more lines of mathematical code” claim misses the chapter’s point that the hard part is the surrounding system and its data couplings.
Learning Objective: Distinguish ML-specific technical debt mechanisms from ordinary code-focused software debt
A data engineering team spends 6 hours per week manually extracting features, executing training runs, and validating a customer churn model. Building an automated CI/CD retraining pipeline requires a one-time upfront investment of 120 engineering hours. In this simplified calculation, assume all 6 weekly hours are saved, automation has no ongoing maintenance cost, and each additional model would impose a similar manual cost if the process scaled linearly. What is the breakeven time for this automation investment, and what long-term capacity risk arises if the team remains manual?
- Breakeven is 6 weeks; manual processes remain more cost-effective for multi-model deployments
- Breakeven is 10 weeks; automated pipelines eliminate the need for future model monitoring
- Breakeven is 40 weeks; manual maintenance has zero ongoing engineering cost after the first year
- Breakeven is 20 weeks; manual maintenance scales linearly with the number of deployed models until routine operations consume a growing share of engineering capacity
Answer: The correct answer is D. The simplified breakeven is \(120\text{ hours} / 6\text{ hours/week} = 20\text{ weeks}\). If the team keeps the workflow manual and each model keeps demanding similar recurring effort, routine maintenance grows roughly linearly with the number of deployed models and can crowd out new development. In practice, real automation upkeep or changing retraining frequency would move the breakeven, so 20 weeks is a model-based estimate rather than a universal rule.
Learning Objective: Calculate a simplified breakeven time for pipeline automation and analyze how recurring manual work can consume engineering capacity as deployments scale
Explain why ‘correction cascades’ create a severe maintenance trap in production ML architectures, and state the primary architectural remedy.
Answer: A correction cascade occurs when downstream models or patches are built to compensate for the residual errors of an upstream model, so changing the upstream component can change the residual distribution those downstream fixes expect. That means an upstream update may force downstream revalidation or retraining, turning one local repair into coordinated maintenance across the chain. The main remedy is to consolidate fixes into a cleaner upstream design when practical; if chained components are unavoidable, explicit versioned dependencies and joint validation are needed to contain the risk.
Learning Objective: Analyze how correction cascades create fragile dependency chains and explain architectural methods to reduce the resulting maintenance risk
True or False: In production ML systems, ‘glue code’ refers to the core machine learning algorithm.
Answer: False. Glue code is the integration code that connects ML libraries, data pipelines, feature processing, and serving infrastructure. It supports the model system around the algorithm rather than being the algorithm itself.
Learning Objective: Evaluate the role of glue code in connecting ML components within a production system
The systemic vulnerability where changing one input feature’s distribution or encoding during retraining can alter model behavior and the contributions of other features elsewhere in the system is known as the ____ principle.
Answer: CACE. The CACE principle—“Change Anything Changes Everything”—warns that learned dependencies can couple features and components, so a local change may propagate into broader behavior changes after retraining.
Learning Objective: Identify the CACE principle as the warning that local retraining changes can propagate through coupled learned dependencies
Self-Check: Answer
A team versions its model training code in Git, but datasets are pulled dynamically from unversioned live database queries and training hyperparameters are passed via ad hoc shell flags. Which foundational MLOps principle is violated, and what formal dependency does this break?
- Observable degradation; it prevents inference proxies from logging P99 latency percentiles
- Reproducibility; it breaks the ability to reconstruct a training run from versioned Code, Data, Config, and Environment artifacts while controlling for or characterizing execution nondeterminism
- Separation of concerns; it couples feature transformation code with neural loss calculation
- Cost-aware automation; it prevents the workload scheduler from executing batch inference
Answer: The correct answer is B. Reproducibility means the team can reconstruct and audit a training run from versioned artifacts: \(\text{Code}_v\), \(\text{Data}_v\), \(\text{Config}_v\), and \(\text{Environment}_v\), while controlling for or characterizing execution nondeterminism. If data snapshots and configurations are unversioned, the run cannot be reliably reproduced for comparison or audit. An answer based on runtime telemetry confuses artifact provenance with production monitoring, while the layer-boundary and scheduler options address different operational concerns.
Learning Objective: Apply the formal reproducibility dependency to identify artifact versioning violations in an ML workflow
Explain how a centralized feature store’s point-in-time (time-travel) query capability prevents data leakage during model training.
Answer: Point-in-time queries reconstruct feature values that were actually available when each training example would have been scored, rather than joining against the current state of the world. For example, a fraud event at 14:02 should not see an account status written at 14:05, even if that later record carries an older event timestamp. The practical consequence is that point-in-time correctness must respect feature availability time as well as event time, and it still depends on correct configuration and versioned pipelines rather than being guaranteed by the feature store alone.
Learning Objective: Explain how point-in-time feature retrieval reduces training data leakage by respecting historical feature availability
Order the following stages in a feature-consistency investigation after a production symptom has already been observed: (1) compare the resulting training-side and serving-side feature values to locate the discrepancy, (2) evaluate whether correcting that discrepancy is worth the expected benefit, implementation cost, and deployment risk, (3) replay the same recorded input through both the training and serving transformations, (4) retrieve the versioned training and serving transformation artifacts for the affected deployment.
Answer: The correct order is: (4) retrieve the versioned training and serving transformation artifacts for the affected deployment, (3) replay the same recorded input through both the training and serving transformations, (1) compare the resulting training-side and serving-side feature values to locate the discrepancy, (2) evaluate whether correcting that discrepancy is worth the expected benefit, implementation cost, and deployment risk. The sequence is causal: the team needs the exact versioned artifacts before it can replay the recorded input faithfully, and it needs the replay outputs before it can compare feature values to identify where they diverge. Only after diagnosing a concrete mismatch does it make sense to evaluate whether correcting that specific discrepancy is worth shipping.
Learning Objective: Sequence a feature-consistency investigation from artifact retrieval through discrepancy diagnosis to evaluation of a targeted correction
**After drift has been investigated and retraining has been approved under policy, an automated MLOps continuous training and delivery pipeline executes. Place the following pipeline stages in their correct execution order:
- Data Validation Check: Run schema and statistical boundary checks on newly ingested data.
- Staged Rollout / Canary Deployment: Route a small percentage of live production traffic to the new model.
- Model Training & Hyperparameter Optimization: Train candidate model weights on the validated dataset.
- Model Evaluation & Guardrail Check: Evaluate candidate model against golden test slices and latency SLOs.
- Model Registry Registration: Tag and store the validated model binary, metadata, and container hash.**
Answer: The correct sequence is: (1) Data Validation Check, (3) Model Training & Hyperparameter Optimization, (4) Model Evaluation & Guardrail Check, (5) Model Registry Registration, (2) Staged Rollout / Canary Deployment. The pipeline must validate the newly ingested data before training on it, evaluate the trained candidate before treating it as an approved artifact, register the validated artifact so the exact version is tracked, and only then expose it to production traffic through a staged rollout. Swapping evaluation with training is impossible because there is no candidate to judge yet, and deploying before registration would weaken rollback and provenance tracking.
Learning Objective: Design the execution sequence of a continuous ML training-and-deployment pipeline after retraining has been approved
True or False: In automated ML pipelines, a ‘reproducibility failure’ and an ‘operational idempotence failure’ describe the exact same defect.
Answer: False. Reproducibility asks whether rerunning with the same artifacts, configuration, environment, and stated tolerance yields consistent results, even if unconstrained nondeterminism may prevent bitwise identity. Operational idempotence asks whether retrying a stage avoids duplicate side effects such as repeated registry entries or duplicate writes.
Learning Objective: Differentiate reproducibility targets from operational idempotence in automated ML workflows
Self-Check: Answer
An engineering team needs to evaluate the live inference latency, resource consumption, and numerical output distribution of a new deep recommender against live production traffic without exposing users to potential prediction quality regressions. Which deployment pattern should they select?
- Canary deployment, routing 5% of user-facing production traffic directly to the candidate model
- Blue-green deployment, performing an immediate router-level cutover of 100% of user traffic
- Shadow deployment, asynchronously duplicating live production traffic to the candidate model while returning only the incumbent model’s predictions to users
- In-place deployment, updating the model weights directly on active production inference servers
Answer: The correct answer is C. Shadow deployment duplicates live traffic to the candidate model while only the incumbent model’s outputs reach users, so the team can compare latency, resource use, and prediction distributions without exposing user-facing decisions to the new model. That does not make shadowing risk-free: duplicated inference still adds cost, can create resource contention, and requires careful isolation and privacy handling. A canary deliberately exposes some users to candidate predictions, while blue-green and in-place approaches do not provide the same live side-by-side observation before user impact.
Learning Objective: Select a deployment pattern that supports live traffic evaluation without serving candidate predictions to users
A two-tower recommender caches precomputed user and item embeddings. Model v2 changed the embedding dimension, and after a regression the team rolls back to v1 by redeploying v1’s weights. Explain why this rollback can still fail, and state what a stateful rollback procedure must include.
Answer: The embeddings cached while v2 was serving live in v2’s vector space (here even a different dimension), so v1 would score queries against incompatible vectors and return nonsense or errors although its own weights are correct. A stateful rollback must invalidate or version those caches atomically with the weight swap, for example through dual-version namespaces, and if v2’s bad predictions polluted feature logs or clickstream data during the degraded window, those records must be quarantined before the next retraining. Clean rollback is an architectural property that must be exercised in advance, not assumed.
Learning Objective: Explain why rollback of stateful ML services requires cache and data handling beyond redeploying earlier weights
True or False: Once an INT8-converted model passes numerical-equivalence tests against the original, upgrading the inference runtime by a minor version needs no revalidation, because the model weights have not changed.
Answer: False. A runtime upgrade can change kernel selection and fusion, and with them both latency and numerical results, in an artifact whose weights never changed. The runtime version is an input to reproducibility, so deployment configurations pin it explicitly and treat any upgrade as a change that must pass the same equivalence and slice-level checks as a new model.
Learning Objective: Justify explicit runtime version pinning as part of validating optimized serving artifacts
Self-Check: Answer
Explain why high-stakes production ML systems (such as medical diagnosis or loan underwriting) experience a ‘verification gap’ and describe how leading indicators mitigate this challenge.
Answer: A verification gap arises because correct model behavior is not established just by successful execution, and in high-stakes ML the strongest correctness signals often depend on sparse, delayed, or noisy real-world labels. For example, loan defaults may take months to observe, so teams cannot measure true error immediately after deployment. Leading indicators—such as feature distribution drift, prediction-confidence shifts, data freshness checks, and schema validation—provide earlier signals that something may have changed and should be investigated. Their practical value is faster diagnosis, but they do not by themselves prove harm, identify the root cause, or guarantee warning before business impact occurs.
Learning Objective: Analyze why delayed, sparse, or noisy labels create a verification gap and explain how leading indicators support earlier investigation without proving correctness loss
Order the following stages in a single drift-alert workflow where each step depends on the previous one: (1) route the resulting alert to the designated owner for investigation, (2) compare the computed divergence with a calibrated threshold, (3) select and validate the versioned input cohort for analysis, (4) compute divergence against the specified reference distribution.
Answer: The correct order is: (3) select and validate the versioned input cohort for analysis, (4) compute divergence against the specified reference distribution, (2) compare the computed divergence with a calibrated threshold, (1) route the resulting alert to the designated owner for investigation. The dependencies are intrinsic: divergence is meaningless until the cohort and reference are fixed, threshold comparison requires a computed divergence value, and routing an alert only makes sense after the threshold test indicates that an alert exists. Swapping threshold comparison ahead of divergence computation or routing before thresholding would break the logic of the alert itself.
Learning Objective: Sequence the data-dependent stages of a drift-alert workflow from validated cohort selection to owner routing
True or False: An inference server showing 95% GPU busy time and 30% HBM memory bandwidth utilization provides sufficient evidence to prescribe weight quantization as the primary optimization.
Answer: False. GPU busy time is not the same as achieved FLOPs efficiency, and 95% busy with 30% HBM utilization is not sufficient by itself to uniquely diagnose the bottleneck. You would still need achieved-ops, stall, and kernel-profile evidence. Quantization can reduce memory traffic, but on supported hardware lower precision can also change compute throughput.
Learning Objective: Evaluate whether coarse GPU busy-time and memory-bandwidth counters are sufficient to prescribe a serving optimization
A recommendation service’s p99 latency rises from 80 ms to 110 ms overnight, breaching its 100 ms SLO. No model was deployed. Illustrative representative end-to-end request traces show model inference steady at 45 ms, while feature retrieval rose from 25 ms to 55 ms, with the remaining stages roughly unchanged. What is the appropriate first operational response?
- Roll back to the previous model version, because latency regressions are model regressions until proven otherwise
- Quantize the model further to buy back the 30 ms from the inference stage
- Route the incident to the feature-store owners and investigate the retrieval path, because the stage-level budget localizes the regression outside the model
- Raise the SLO to 110 ms, because a drift in total latency indicates a permanent change in workload
Answer: The correct answer is C. Route the incident to the feature-store owners and investigate the retrieval path, because the representative stage-level breakdown localizes the latency increase outside the model itself. Inference stayed flat, so rolling back the model or quantizing it further attacks a stage that did not move. Raising the SLO would hide the symptom instead of diagnosing the retrieval regression.
Learning Objective: Use stage-level latency evidence to localize a production regression and route it to the owning component
In an illustrative PSI rule of thumb, a Population Stability Index value of \(\text{PSI} \ge\) ____ is treated as a severe distribution shift that should trigger investigation.
Answer: 0.25. In this illustrative convention, \(\text{PSI} < 0.10\) is below the warning range, \(0.10 \le \text{PSI} < 0.25\) is a warning range, and \(\text{PSI} \ge 0.25\) should trigger escalation. This is an illustrative rule of thumb for interpretation, not a universal threshold or proof of accuracy loss.
Learning Objective: Identify an illustrative PSI threshold for severe shift and distinguish it from a universal drift rule
Self-Check: Answer
The formal decision criterion governing whether a degraded model should be retrained balances expected accuracy improvement against training compute costs and deployment risk under the principle of ____.
Answer: cost-aware automation. This principle frames retraining as a decision about expected benefit versus execution cost, validation effort, and deployment risk. It helps decide when retraining is warranted, but a favorable result still does not by itself authorize production release without validation.
Learning Objective: Identify cost-aware automation as the principle that frames retraining as a conditional cost-benefit decision
Under the chapter’s simplified economic model (validated retraining resets quality, the square-root approximation applies, costs are fixed, and pipeline delays are ignored), the ranking service serves \(\DailyQueryVolume = 10^6\) queries/day with initial accuracy \(\InitialAccuracy = 0.94\), daily accuracy decay rate \(\AccuracyDecayRate = 0.0024\) (\(0.24\%\) decay per day, fitted to its observed four-week slide), value per query for unit accuracy fraction \(\AccuracyPayoffPerQuery = \$0.50\), and fixed retraining cost \(\RetrainingRunCost = \$5{,}000\). Using the square-root optimal retraining approximation \(\RetrainingInterval^* \approx \sqrt{\frac{2\RetrainingRunCost}{\DailyQueryVolume \cdot \AccuracyPayoffPerQuery \cdot \InitialAccuracy \cdot \AccuracyDecayRate}}\), what is the economically optimal retraining interval \(\RetrainingInterval^*\)?
- Approximately \(1.0\) day
- Approximately \(3.0\) days
- Approximately \(14.5\) days
- Approximately \(30.0\) days
Answer: The correct answer is B. Approximately \(3.0\) days. Using the formula, the numerator is \(2 \times 5{,}000 = 10{,}000\), the denominator is \(10^6 \times 0.50 \times 0.94 \times 0.0024 \approx 1{,}128\), and \(\sqrt{10{,}000/1{,}128} \approx \sqrt{8.87} \approx 2.98\) days. That value is the model’s economic optimum under the stated simplifying assumptions; it does not by itself prove that a three-day operational cadence is feasible, because label availability, validation time, and rollout duration still matter.
Learning Objective: Compute the economically optimal retraining interval using the chapter’s simplified retraining-economics approximation
In the optimal retraining formula \(T^* \approx \sqrt{\frac{2C}{Q \cdot V \cdot \text{Accuracy}_0 \cdot \gamma}}\), how does the optimal interval \(T^*\) change if the fixed retraining compute and validation cost \(C\) increases by a factor of 4 while all other parameters remain constant?
- \(T^*\) increases by a factor of 4 (\(4\times\) longer interval), scaling linearly with cost
- \(T^*\) increases by a factor of 2 (\(2\times\) longer interval), because \(T^*\) scales with the square root of retraining cost \(\sqrt{C}\)
- \(T^*\) decreases by a factor of 2 (\(0.5\times\) shorter interval), forcing more frequent retraining
- \(T^*\) remains unchanged, because optimal retraining cadence is governed solely by query traffic and drift rate
Answer: The correct answer is B. \(T^*\) increases by a factor of 2 (\(2\times\) longer interval), because \(T^*\) scales with the square root of retraining cost \(\sqrt{C}\). In the formula, the retraining cost appears under the radical, so replacing \(C\) with \(4C\) gives \(\sqrt{4C} = 2\sqrt{C}\). The linear-scaling answer ignores the square-root relationship, while the shorter-interval and no-change answers contradict the structure of the model.
Learning Objective: Perform sensitivity analysis on the optimal retraining interval with respect to retraining costs
Self-Check: Answer
At 2:00 AM an alert reports that recommendation click-through rate fell 12 percent in the past hour. There is no stack trace and no failed process. Following the chapter’s debugging decision tree, what should the on-call engineer check first?
- Feature attributions for recent mispredictions, to see which inputs the model now relies on
- Upstream data pipelines for schema changes, missing values, or shifted input distributions
- Calibration curves and confidence distributions of the current model version
- Whether a quarterly retraining is due, since gradual concept drift is the most common cause
Answer: The correct answer is B. Upstream data pipelines for schema changes, missing values, or shifted input distributions. The chapter’s debugging workflow starts with data pipeline integrity as the first diagnostic boundary, because many production ML regressions originate in altered inputs or upstream transformations. An abrupt one-hour drop also focuses attention on recent changes or outages, though it does not prove the data pipeline is at fault. Attribution and calibration checks can still matter later in the investigation.
Learning Objective: Apply the chapter’s debugging decision tree to choose an initial investigation step for an ML incident with no explicit software failure
Explain how a model-registry promotion check turns model governance from a review meeting into a release invariant, and name three conditions such a check can require before a model moves from staging to production.
Answer: A promotion check encodes governance requirements into the same release path that promotes artifacts, so configured requirements must be satisfied before the system advances a model from staging to production. For example, the chapter lists a signed feature contract, a recorded training-data lineage hash with linked retained artifacts, subgroup metrics above policy thresholds, a canary SLO with automated rollback criteria, and a designated artifact owner. This does not replace every human review or guarantee complete compliance, but it makes key governance checks repeatable and harder to bypass casually.
Learning Objective: Explain how automated promotion checks enforce selected governance checks as release invariants and identify concrete conditions they can require
Self-Check: Answer
What fundamental reliability concept is illustrated by the ‘Uptime Iceberg’ metaphor in production machine learning systems?
- Traditional service availability (uptime and low latency) is only the visible tip; hidden failures like feature drift, concept drift, schema corruption, and subpopulation degradation lurk beneath the surface
- Distributed feature retrieval latency over wide-area networks always exceeds local GPU inference execution time
- Data center cooling overhead exceeds the total electrical power consumed by GPU inference accelerators
- Deep neural network weight storage in DRAM requires larger memory allocations than raw training dataset storage
Answer: The correct answer is A. Traditional service availability (uptime and low latency) is only the visible tip; hidden failures like feature drift, concept drift, schema corruption, and subpopulation degradation lurk beneath the surface. The Uptime Iceberg illustrates that an ML service can maintain 99.99% uptime and green infrastructure dashboards while serving completely invalid or degraded predictions due to data outages, schema changes, or drift. Comprehensive MLOps must monitor all three tiers: Service Health, Data Health, and Model Health. The alternative choices introduce unrelated network latency, thermodynamic cooling, or memory storage claims.
Learning Objective: Explain why service uptime is an insufficient measure of ML system health using the Uptime Iceberg model
An organization with limited engineering resources is deploying its first production ML model. Based on the chapter’s investment economics framework, which staging sequence provides the most cost-effective path to reliability?
- Construct an enterprise-wide multi-region distributed feature store and autonomous retraining cluster before deploying the initial model
- Invest first in statistical monitoring and basic CI/CD deployment pipelines, then add centralized feature stores and automated retraining as model scale and drift warrant
- Procure an all-in-one commercial MLOps platform suite to eliminate cross-functional on-call rotations
- Defer all monitoring and automation investments until multiple major production outages have occurred
Answer: The correct answer is B. Invest first in statistical monitoring and basic CI/CD deployment pipelines, then add centralized feature stores and automated retraining as model scale and drift warrant. Monitoring provides immediate visibility into silent statistical failure, and CI/CD ensures safe, reproducible releases. Complex infrastructure like enterprise feature stores and closed-loop continuous retraining should be added incrementally as traffic volume, training-serving skew, and model criticality justify the capital investment. Building heavy enterprise infrastructure upfront over-engineers before validating value, while purchasing platforms to avoid on-call rotations represents a tool-first anti-pattern.
Learning Objective: Prioritize staged MLOps infrastructure investments based on ROI and operational risk
Describe the organizational failure in which one team develops a model and hands it to another team for deployment without shared operational ownership, and explain how a cross-functional or federated MLOps structure resolves it.
Answer: This handoff failure occurs when one group develops a model and hands off code, weights, or notebook outputs to another group without shared operational context, ownership, or release discipline. This can leave teams misaligned on feature semantics, latency budgets, runtime dependencies, drift monitoring, and rollback expectations. A cross-functional or federated MLOps structure helps by creating shared ownership across development, deployment, monitoring, and incident response, with clearer interfaces and handoffs. It reduces the coordination gap, though it does not automatically resolve every organizational or technical failure mode.
Learning Objective: Analyze how weak cross-team handoffs create MLOps failure modes and how shared ownership structures mitigate them
**An engineering team is assessing the operational maturity of an ML deployment. Place the three operational maturity stages in order from least mature to most mature:
- Repeatable: Version-controlled training scripts, scheduled batch retraining jobs, centralized model registry, and basic performance monitoring.
- Scalable: Shared feature definitions with verified training-serving parity, closed-loop drift detection with automated canary validation, and infrastructure-as-code.
- Ad Hoc: Hand-crafted Jupyter notebooks, local training on developer machines, manual pickle file deployment, and absence of formal versioning.**
Answer: The correct sequence is: (3) Ad Hoc -> (1) Repeatable -> (2) Scalable. An organization begins with (3) Ad Hoc manual workflows, matures into (1) Repeatable structured pipelines with centralized storage, and reaches (2) Scalable operations with automated closed-loop validation and shared feature infrastructure. The feature store at the scalable stage supports shared feature definitions, but consistency still has to be verified rather than assumed guaranteed.
Learning Objective: Classify organizational ML system practices across the three levels of operational maturity
A team’s ML Test Score audit yields category scores of data 6, model 7, infrastructure 5, and monitoring 1 (each out of 7). Leadership proposes adding two new model tests next quarter. What does the rubric imply about that plan?
- It raises the overall score, because every added test increases the composite total
- It yields no gain in the rubric’s overall score, because the composite score is the minimum category and monitoring bounds it at 1
- It is the right priority, because model tests catch the largest share of production failures
- It lowers the overall score, because an unbalanced rubric penalizes over-investment in one category
Answer: The correct answer is B. It yields no gain in the rubric’s overall score, because the composite score is the minimum category and monitoring bounds it at 1. The ML Test Score uses the minimum across categories, so improving model tests alone does not raise the reported aggregate when monitoring remains the bottleneck. That does not mean extra tests are useless in every broader safety sense, but under this rubric the priority for raising the score is clearly the weakest category.
Learning Objective: Use the min-bounded ML Test Score to identify which category limits the reported readiness score and how that affects investment priority
Self-Check: Answer
In the keyword-spotting edge design, how do edge hardware constraints (microcontroller memory, battery capacity, intermittent connectivity) reshape the implementation of foundational MLOps principles?
- They eliminate the requirement for artifact versioning because firmware cannot be updated over the air
- They require continuous on-device distributed backpropagation to retrain neural networks nightly
- They favor lightweight on-device feature extraction, OTA deployment with rollback safety, and selective batched telemetry rather than continuous cloud streaming
- They allow the system to bypass training-serving consistency because raw sensor data is processed without filtering
Answer: The correct answer is C. In the keyword-spotting edge design, edge constraints favor lightweight on-device feature extraction, OTA deployment with rollback safety, and selective batched telemetry rather than assuming always-on cloud streaming. The alternatives are wrong because edge constraints do not remove the need for versioning, do not imply nightly on-device distributed backpropagation, and do not justify ignoring training-serving consistency.
Learning Objective: Analyze how edge hardware constraints reshape the implementation of foundational MLOps principles in a proposed wearable architecture
Why does the ClinAIOps clinical AI framework intentionally incorporate clinician-in-the-loop override points as a core architectural feature rather than viewing human review as a failure of automation?
- Because FDA regulations strictly forbid machine learning algorithms from executing in clinical settings
- Because clinical patient distributions never experience covariate shift or demographic drift
- Because human review eliminates the need for regulatory audit trails or data provenance tracking
- Because in healthcare, the asymmetric cost of diagnostic error involves patient harm, making expert oversight an essential risk-mitigation control in cost-aware automation
Answer: The correct answer is D. Because in healthcare, the asymmetric cost of diagnostic error involves patient harm, making expert oversight an essential risk-mitigation control in cost-aware automation. In the chapter’s proposed ClinAIOps framework, human oversight is built in because the consequences of bad recommendations are high and accountability matters. That oversight reduces risk but does not guarantee safety, and it does not remove the need for provenance or audit mechanisms. The other answers either overstate regulation or deny that clinical distributions can change.
Learning Objective: Evaluate why human oversight remains a core risk-control mechanism in proposed clinical AI operations frameworks
In the Oura sleep-stage study, multi-sensor enhancement increased four-stage sleep classification accuracy from \(57\%\) (accelerometer baseline) to \(79\%\), while human polysomnography (PSG) inter-scorer agreement is \(82\%\text{--}83\%\). Calculate the fraction of the reference gap closed by the enhanced model and explain the systems lesson of comparing model accuracy against human agreement.
Answer: Using human agreement as a reference comparison, the gap from the \(57\%\) baseline to \(82\%\text{--}83\%\) is \(25\) to \(26\) percentage points, and the enhanced model recovers \(79 - 57 = 22\) percentage points. That means it closes \(22/26 \approx 84.6\%\) to \(22/25 = 88.0\%\) of the reference gap. The systems lesson is that human agreement is useful context for interpreting progress and label uncertainty, but it is not a hard accuracy ceiling or an automatic stopping rule because cohort, task, and scoring differences can make the comparison only approximate.
Learning Objective: Calculate the fraction of a reference gap closed and interpret human agreement as context rather than as a strict performance ceiling
True or False: When transitioning an MLOps architecture from a cloud environment to a battery-constrained edge wearable, the foundational principles of reproducibility and consistency are discarded in favor of battery life.
Answer: False. The five foundational MLOps principles (reproducibility, separation of concerns, consistency, observable degradation, cost-aware automation) remain universal across domains; edge constraints reshape how they are implemented (e.g., using OTA firmware versioning and quantized preprocessing parity) without discarding the principles themselves.
Learning Objective: Compare how domain constraints alter the technical implementation of universal MLOps principles
Self-Check: Answer
When ground-truth labels arrive days later, why is relying only on accuracy as the first production signal to monitor a dangerous operational fallacy in ML systems?
- Because neural network accuracy cannot be mathematically computed after model weights are converted to ONNX format
- Because accuracy then becomes a lagging indicator that depends on delayed labels, whereas drift proxies such as PSI may provide earlier warning of distribution shifts without guaranteeing harm detection
- Because traditional infrastructure availability (HTTP 200 responses and uptime) guarantees that model accuracy remains static
- Because input feature distributions never change unless model source code is redeployed
Answer: The correct answer is B. When labels arrive days later, accuracy is a lagging indicator because it cannot be computed until that delayed ground truth appears. Drift, freshness, and confidence proxies may provide earlier signals that something has changed, even though they do not by themselves prove accuracy has already declined or guarantee warning before user harm.
Learning Objective: Differentiate delayed-label accuracy metrics from earlier proxy signals used in production ML monitoring
Explain why routing leading-indicator alerts (such as feature drift or data freshness violations) to an unowned low-priority chat channel with no review or escalation path, while paging on-call engineers only for HTTP 500 errors, is a critical operational pitfall.
Answer: Leading indicators only help if someone owns them and knows when to act. If drift or freshness alerts go to an unowned low-priority channel with no review or escalation path, teams can miss early signs of schema breakage, stale features, or shifting inputs until downstream symptoms become more expensive to diagnose. Low priority is not inherently wrong for every alert, but ownership, severity rules, and response runbooks are what turn an early warning into an operational control.
Learning Objective: Analyze why unowned alert-routing paths undermine the value of leading indicators in ML operations
True or False: Unconstrained automated retraining without validation checks or human oversight is guaranteed to maintain optimal model performance in production.
Answer: False. Unconstrained automated retraining can perpetuate self-reinforcing feedback loops and entrench bias, or retrain on corrupted data during transient data pipeline glitches, deploying degraded models that pass naive aggregate loss checks.
Learning Objective: Identify failure modes of unconstrained automated retraining and explain the necessity of validation checks