12 Benchmarking
Purpose
Architecture stack focus for this chapter.
How can ML systems be compared fairly when hardware, models, data, and deployment all interact?
Every optimization claim must eventually face deployment-representative conditions, and many do not survive the encounter. Each decision targets one dimension (latency, accuracy, throughput, or energy), but an ML system is the product of all these dimensions simultaneously: a pruned model may run faster on one accelerator yet slower on another, while a larger batch size improves accelerator utilization at the cost of violating a latency service-level agreement. Similarly, an edge device may advertise peak throughput that thermal throttling sharply reduces within minutes of sustained load, and a speedup measured on a warm, idle machine with synthetic inputs can vanish or reverse once real requests, cold caches, and competing jobs share the hardware. The challenge is not whether a local metric improves but whether the combined system improves under conditions that actually matter. Benchmarking makes such comparisons systematic rather than anecdotal. It requires defining what to measure, at what granularity (a single kernel, a full model, an end-to-end pipeline), and under which conditions (batch size, input distribution, thermal state, concurrent load). Without this structure, teams compare numbers that were never measured on the same terms, and decisions that looked sound in a spreadsheet collapse under production workloads. Choosing hardware, a model, or a deployment configuration on such numbers can commit an organization to millions of dollars of infrastructure that delivers a fraction of the capacity it was bought to provide. Benchmarking validates each optimization, bringing claims into contact with evidence and quantifying the gap between promise and delivery. In D·A·M terms, benchmarking holds co-design to account by revealing whether Data, Algorithm, and Machine were matched or merely assembled.
Learning Objectives
- Explain the benchmark–production gap and benchmarking as D·A·M validation that tests whether optimization claims hold under representative conditions
- Design a benchmark that turns an optimization claim into a test by fixing its task, data, model, metrics, harness, and run rules
- Select micro, macro, or end-to-end granularity based on the engineering decision being tested, and compare a roofline prediction with a measurement
- Compare training and inference benchmarks using standardized run rules, time to quality, throughput, and latency percentiles
- Measure energy per inference and average power with matched measurement boundaries, windows, and duty cycles
- Determine whether a measured difference exceeds noise using repeated runs, paired tests, and confidence intervals
- Evaluate model and data quality with confidence calibration, robustness, representativeness, and slice-level metrics, and diagnose benchmark–production gaps caused by drift, thermal throttling, and dynamic load
12.1 The Benchmark–Production Gap
A model quantized to INT8 may benchmark 2\(\times\) faster on a synthetic workload and show no improvement under real traffic with variable input sizes and concurrent requests; a pruned model may hold its accuracy on the test set and fail on the edge cases the benchmark never covered. Every engineering claim about speed, size, or energy is a number measured somewhere: on a warm accelerator or a cold one, at a batch of 256 or a batch of one, on curated test images or on whatever a camera returns at night. The benchmark–production gap is the difference between how a machine learning system performs under the conditions a measurement fixed and how it performs under the conditions it meets in deployment. Benchmarking is the engineering discipline that measures this gap before a deployment pays for it, and that narrows it by making the measured conditions match the deployed ones.
Hardware Acceleration ended on predictions. Its roofline placed ResNet-50’s layers against an accelerator’s compute and bandwidth ceilings, and at INT8 the doubled ridge point moved some of those layers off the compute roof. Before it, Model Compression produced an INT8 artifact a quarter of the FP32 size, and Data Selection reached target accuracy on fewer examples. Each is a favorable local number, computed for one stage in isolation, and the stages interact once they run together on a real machine under real load. Benchmarking measures which of those numbers survive. It comes before serving and operations because every later decision, from how many accelerators to provision to when to roll a model back, rests on measurements made the way this chapter prescribes.
Definition 12.1: Machine learning benchmarking
Machine learning benchmarking is the empirical measurement of ML workloads under specified conditions, used to test claims about components, models, or end-to-end systems against representative evidence rather than peak specifications alone.
- Significance: The gap between peak and sustained performance can be large. An H100 delivers 989 TFLOP/s of dense FP16 arithmetic at peak, yet ResNet-50 training at the MLPerf per-accelerator throughput of about 5,000 images/s sustains about 123 TFLOP/s of model arithmetic, a model FLOPs utilization (MFU, achieved model FLOP/s divided by the hardware’s peak FLOP/s) of about 12.4 percent. Memory-bound layers, the input pipeline, and launch and synchronization overhead account for the difference. Benchmarking quantifies the actual \(\EfficiencyHw\) gap for a workload; vendor spec sheets do not.
- Distinction: ML benchmarking spans multiple scopes. Micro-benchmarks isolate operations such as matrix multiplication, model-level benchmarks evaluate complete training or inference workloads, and end-to-end benchmarks include surrounding work such as data loading, preprocessing, optimization, checkpoint I/O, or serving infrastructure. The scope must match the engineering claim.
- Common pitfall: A frequent misconception is that benchmark numbers are stable references. Both the workload (new model architectures) and the hardware (new GPU generations) evolve, so a result that leads a benchmark under one version often becomes the baseline under a later version, making year-over-year comparisons meaningful only when the benchmark version is held constant.
The iron law predicts how long a workload should take, and a benchmark measures how long it does; the difference between the two is the benchmark–production gap made quantitative. For bandwidth-bound workloads, the gap between peak and sustained performance follows from the memory wall. Compute-bound workloads can approach peak, yet ResNet-50’s training step shows how much of a nominally compute-bound workload still falls outside the arithmetic. Every later section that quotes a peak number is measured against this gap.
↩︎ The iron law, whose utilization term \(\EfficiencyHw\) benchmarks measure against peak, is established in Iron Law of ML Systems.
Systems Perspective 12.1: The fallacy of peak performance
A long-standing computer architecture quip calls peak performance “the performance the manufacturer guarantees you will not exceed.” For ML systems, the gap can be wide because of the memory wall. A bandwidth-bound model leaves much of the advertised FLOP/s unreachable no matter how fast the arithmetic units run. Standardized benchmarks like MLPerf require systems to run specified models and data, revealing sustained performance at a documented operating point rather than a universal rate for every workload.
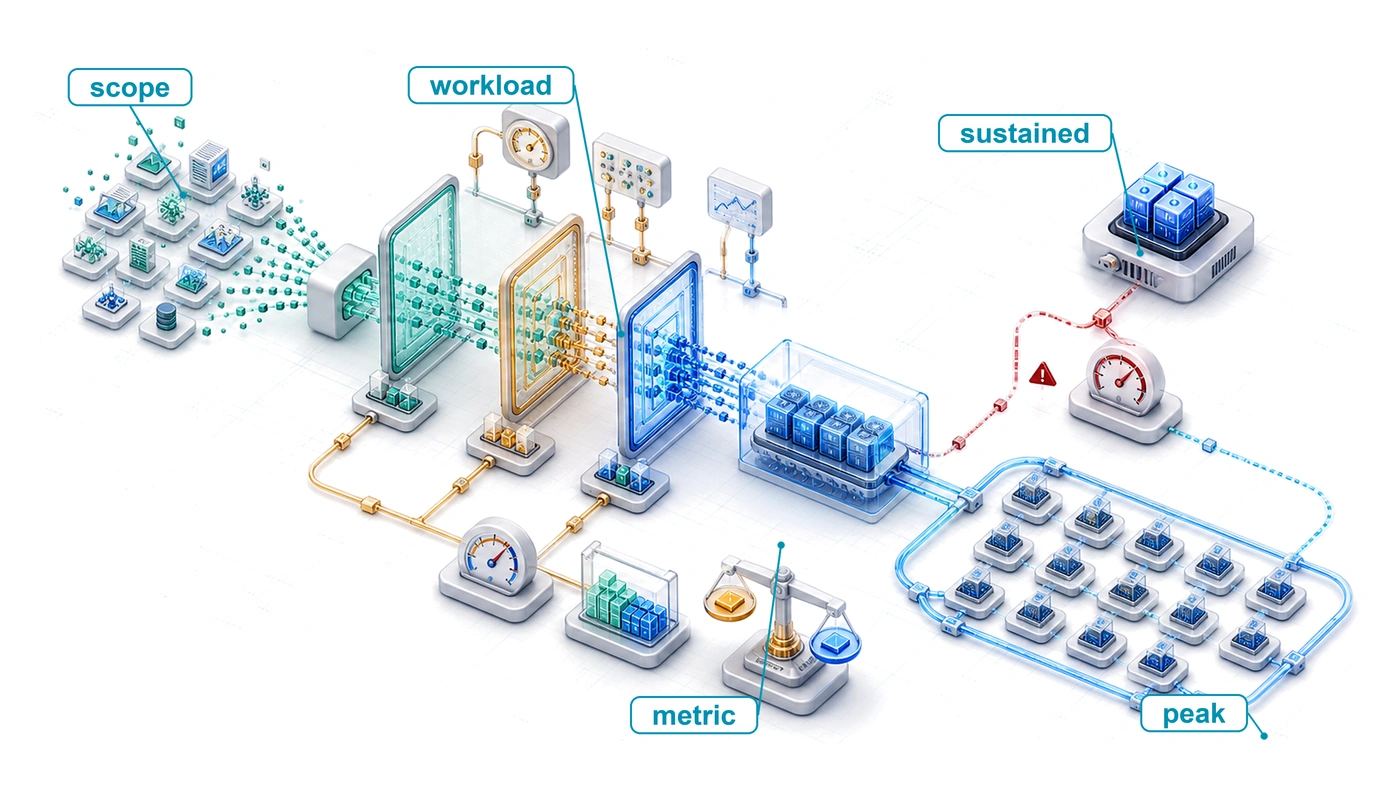
ML benchmarking operates across three interdependent dimensions that map directly to the components of any deployed system. System benchmarking measures whether the hardware delivers promised performance under realistic workloads or whether memory bandwidth saturation and software dispatch overhead erode the gains. Model benchmarking measures whether optimization techniques preserve model quality across the full input distribution, not just on curated test sets. Data benchmarking measures whether the model generalizes to real-world data with all its noise, bias, and distributional shift. Each dimension can independently reveal problems invisible to the others, and a system that passes all three provides far stronger deployment confidence than one evaluated along any single axis. The three dimensions do not receive equal space. System benchmarking carries most of the chapter, because its measurement problems (how a benchmark is built, at what granularity it measures, which standardized suite it follows, and how it measures training, inference, and power) also shape how models and data are evaluated. Model and data evaluation follow once that machinery is in place, and the summary asks whether all three survive live traffic.
Systems Perspective 12.2: Benchmarks as moving targets
In traditional systems (for example, SPEC CPU), the benchmark is a rigid specification. A sorting algorithm is correct if it sorts the list. Correctness is absolute and unchanging. In ML systems, the benchmark is a soft specification: correctness is defined by a finite set of examples (ImageNet), and the world moves. A model that scores highly on ImageNet can still underperform on user photos taken years after the benchmark was created.
In computer architecture, engineers design for the benchmark because the benchmark represents the workload. In ML engineering, designing solely for the benchmark is overfitting. Robustness comes from acknowledging that the benchmark is only a proxy for a shifting reality.
Two lighthouse workloads carry the chapter, one per half, each chosen because it sits in a home regime and arrives with claims from the preceding chapters. ResNet-50, the book’s compute-bound lighthouse, carries the measurement and training half. It is the MLPerf Training reference workload, with a published quality target (75.9 percent top-1 on ImageNet) and a published per-accelerator throughput, and its INT8 profile is the one Model Compression modeled and Hardware Acceleration placed on the roofline. MobileNetV2, compute-bound in its efficient regime, carries the deployment half. It runs on one edge board in a labeled composite scenario, a wildlife camera trap whose low-power host CPU and attached INT8 accelerator must classify each frame within its deadline on battery power, and the measurements made on that board recur from the harness through the energy budget. Keyword spotting (KWS), the power-bound lighthouse, carries the power section, where the question is the energy a wake-word detector spends listening rather than how fast it answers. Table 1 lists each workload’s operations and bytes, the quantities every later benchmark either confirms or refutes.
| Workload | Parameters | Forward FLOPs | Weights (FP32) | Weights (INT8) | Training state (16 B/param) |
|---|---|---|---|---|---|
| ResNet-50 | 25.6M | 8.2 GFLOP | 102.4 MB | 25.6 MB | 409.6 MB |
| MobileNetV2 | 3.5M | 600 MFLOP | 14 MB | 3.5 MB | 56.1 MB |
| KWS (DS-CNN) | 200K | 20 MFLOP | 800 KB | 200 KB | 3.2 MB |
The table already separates the halves of the chapter. ResNet-50 does 13.7× MobileNetV2’s arithmetic per image, so its training benchmarks are about whether an accelerator sustains its rate; MobileNetV2’s INT8 weights fit in a few megabytes, so its deployment benchmarks are about latency, sustained thermal state, and energy on a small board.
↩︎ MobileNetV2, the lighthouse model for edge latency, is established in Depthwise separable convolutions.
Lighthouse 12.1: MobileNetV2 deployment validation
MobileNetV2 serves as the lighthouse example for validating the complete optimization pipeline. MobileNetV2 refines v1’s depthwise separable design with inverted residuals and linear bottlenecks while maintaining a similar parameter scale (Sandler et al. 2018). It exemplifies the deployment challenges where benchmarking determines success or failure: compression can reduce model size, hardware acceleration can reduce inference latency, and only benchmarking can determine whether those gains survive the full deployment pipeline.
- Model compression (Model Compression): INT8 quantization reduces this MobileNetV2 worked example from 14 MB to 3.5 MB (4× compression)
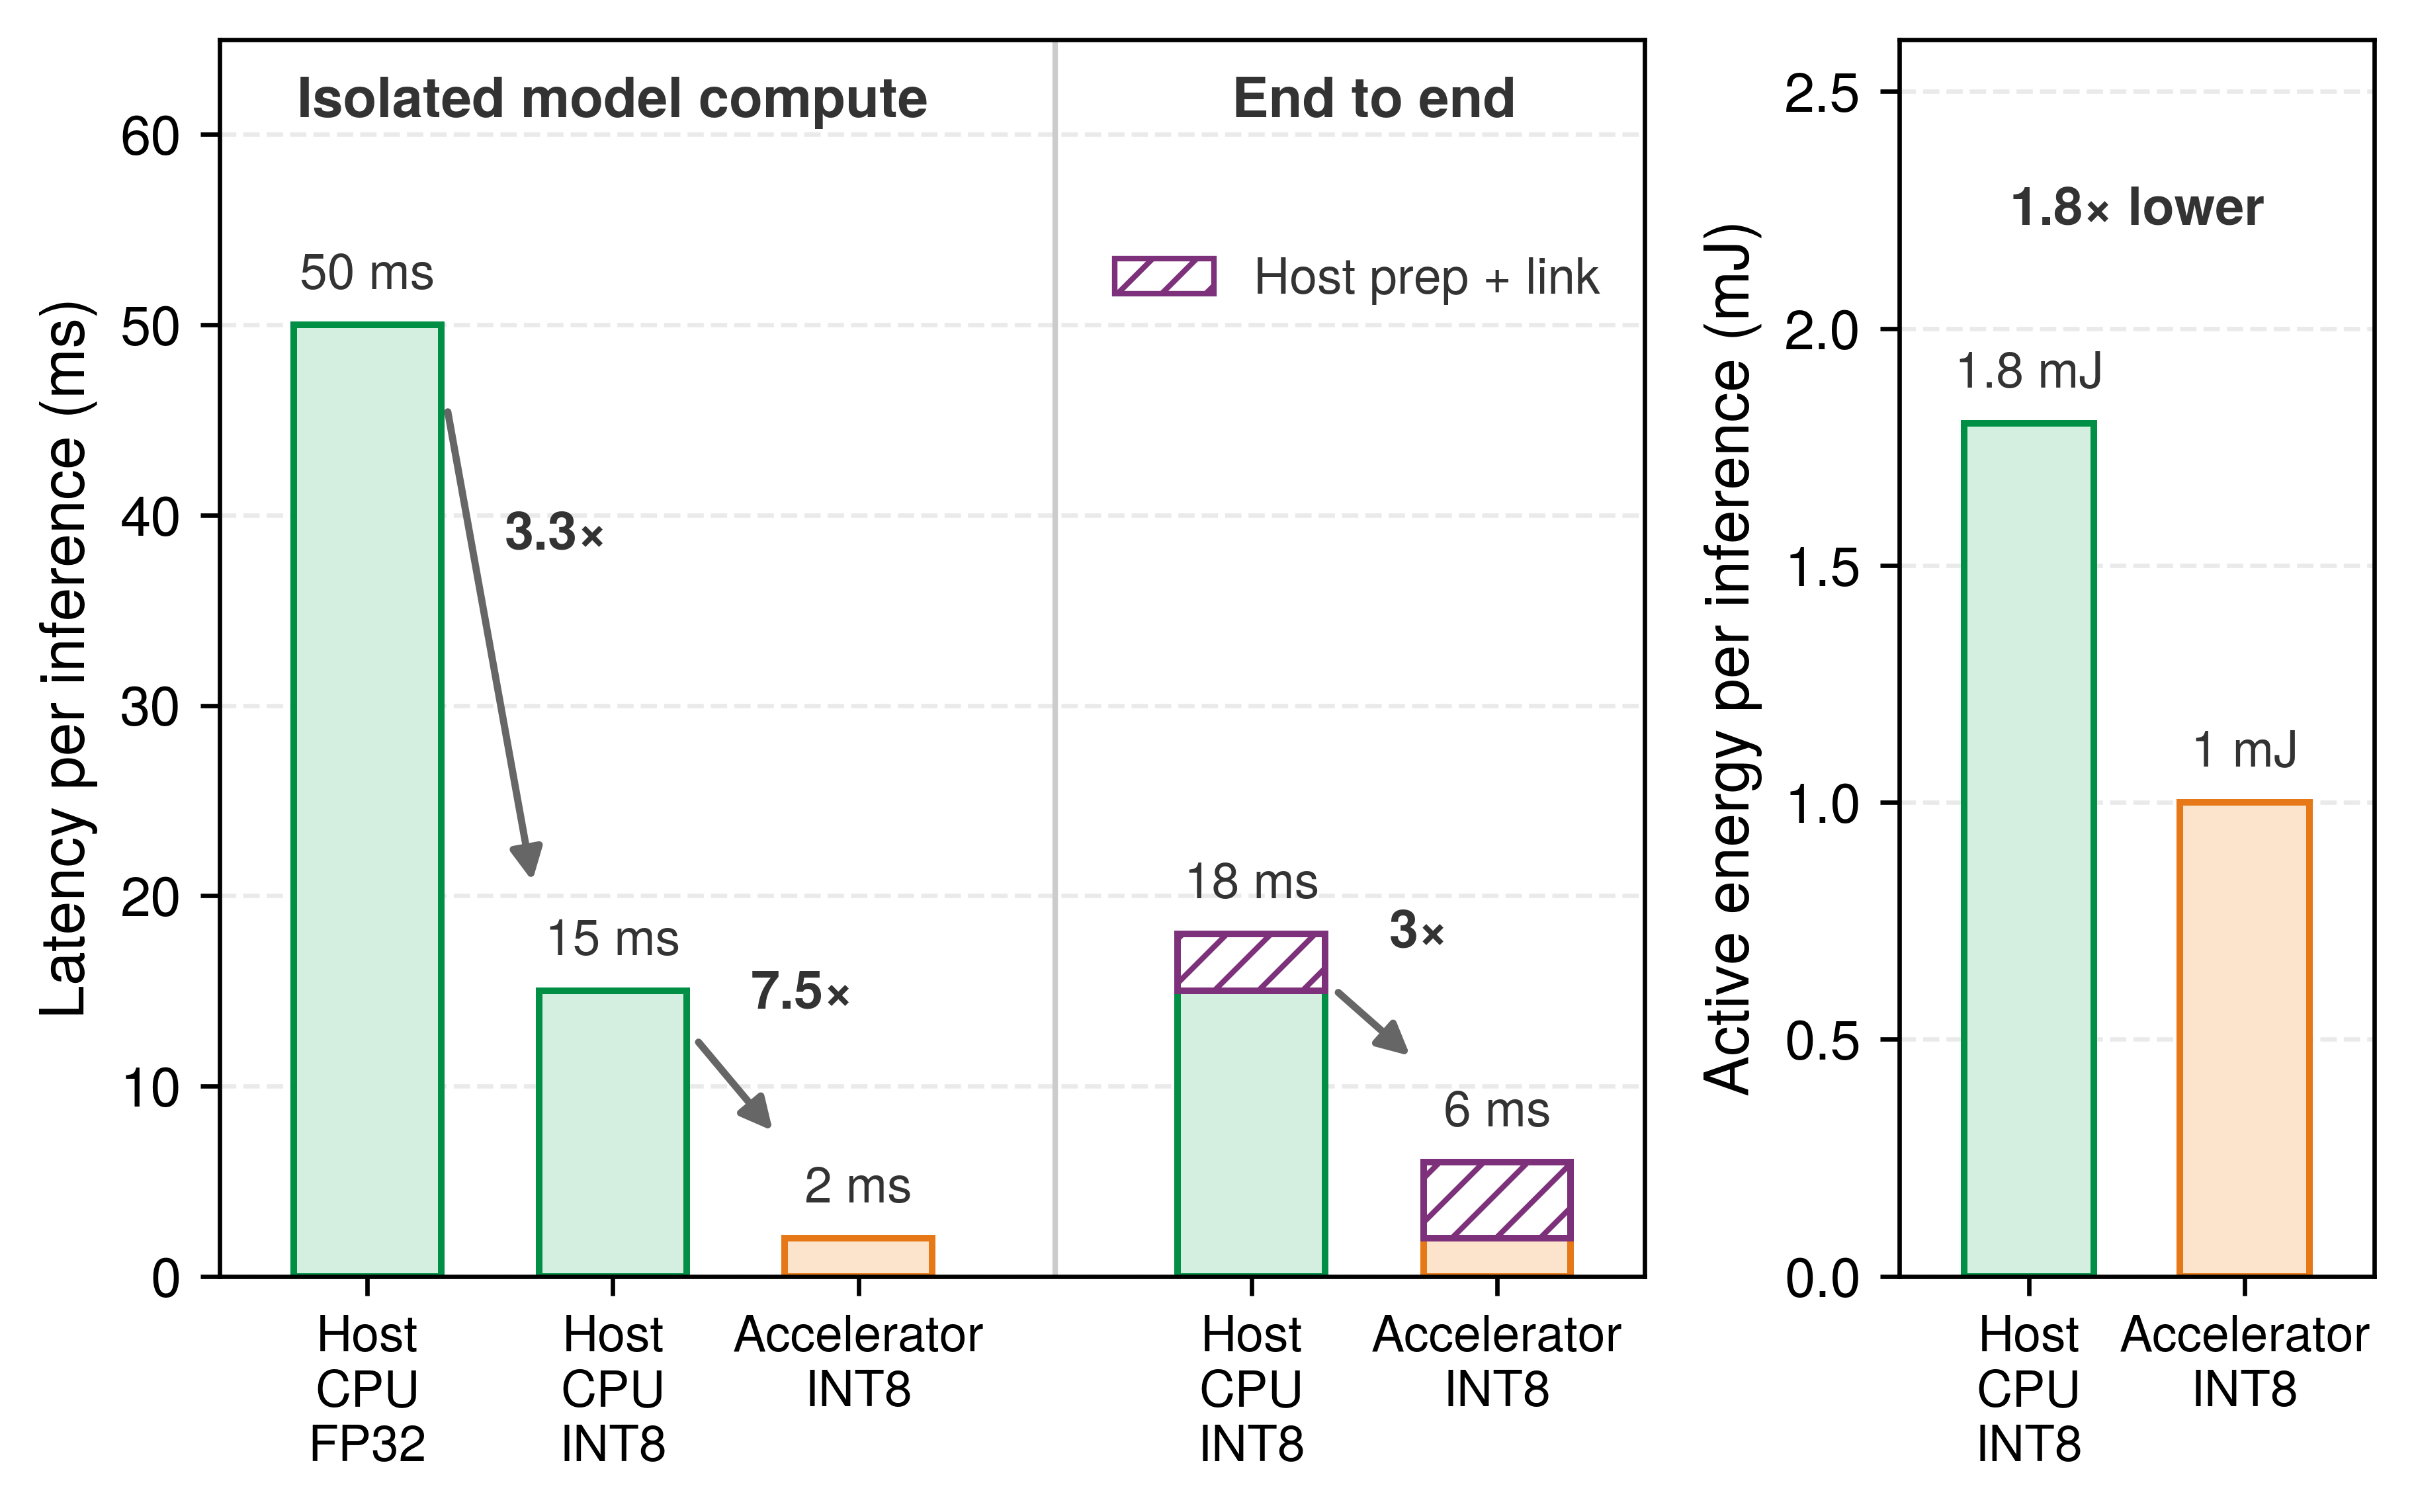
- Hardware acceleration (Hardware Acceleration): in this illustrative scenario the board’s attached INT8 accelerator runs inference in 2 ms against 15 ms on its host CPU
- Benchmarking validation: Verify the pipeline delivers in practice
A systematic evaluation isolates the accelerator’s latency from preprocessing and data transfer overhead, confirms INT8 quantization preserves accuracy on edge cases such as unusual lighting, and verifies that throughput holds on the camera trap’s own frames rather than on curated ImageNet test images alone.
Each stage of that pipeline arrives with a favorable number from its own chapter, such as a smaller model file or a faster kernel. The benchmarking question is which of those local numbers still hold once the stages run together on the target device, and three principles guide how the chapter answers it.
First, benchmarks are proxies, not truth. Every benchmark measures specific conditions that may not match the target deployment. A system can achieve high sample throughput in Offline mode (bulk throughput with all inputs available) and much lower queries per second (QPS) in Server mode (latency-constrained requests arriving over time). The critical question is always what the benchmark does not measure.
Second, Goodhart’s Law governs benchmark rankings.1 “When a measure becomes a target, it ceases to be a good measure.” Teams that optimize for benchmark rankings often produce systems that excel in evaluation but fail in production. Benchmark-specific optimizations frequently degrade characteristics that matter for deployment: robustness, calibration, and efficiency.
1 Goodhart’s law: Goodhart (1984) articulated the original 1975 Bank of England observation on monetary policy; Strathern (1997) generalized it into the form quoted above. The original context was macroeconomics: once a monetary aggregate became an official policy target, banks changed behavior to game the metric, destroying its predictive value. In ML, the same failure mode recurs structurally: BLEU rewards n-gram overlap (Papineni et al. 2002), ImageNet rewards performance on a fixed visual distribution (Deng et al. 2009; Recht et al. 2019), and benchmark leaderboards can incentivize test-set-specific tuning.
Goodhart, Charles A. E. 1984. “Problems of Monetary Management: The UK Experience.” In Monetary Theory and Practice. Palgrave. https://doi.org/10.1007/978-1-349-17295-5_4.
Strathern, Marilyn. 1997. “‘Improving Ratings’: Audit in the British University System.” European Review 5 (3): 305–21. https://doi.org/10.1002/(SICI)1234-981X(199707)5:3<305::AID-EURO184>3.0.CO;2-4.
Deng, Jia, Wei Dong, Richard Socher, Li-Jia Li, Kai Li, and Li Fei-Fei. 2009. “ImageNet: A Large-Scale Hierarchical Image Database.” 2009 IEEE Conference on Computer Vision and Pattern Recognition, 248–55. https://doi.org/10.1109/cvpr.2009.5206848.
Recht, Benjamin, Rebecca Roelofs, Ludwig Schmidt, and Vaishaal Shankar. 2019. “Do ImageNet Classifiers Generalize to ImageNet?” Proceedings of the 36th International Conference on Machine Learning (ICML), 5389–400.
Third, end-to-end beats component metrics. A component speedup is diluted by every stage of the request it does not touch, and the dilution follows Amdahl’s law; section 12.3 quantifies it on a vision pipeline. These principles reappear throughout the methodology and return as misconceptions in section 12.10.
Two terms recur from here on. A service-level objective (SLO) is the target a deployed service commits to meet for a measured quantity, such as answering 99 percent of requests within a stated time; section 12.6.2.1 defines it formally. The 99th-percentile latency (p99) is the response time that 99 percent of requests meet or beat, so it describes the slowest 1 percent of requests rather than the typical one.
The chapter builds the measurement before it applies it (table 2). Benchmark carpentry turns a claim into a test that fixes the task, data, model, metrics, harness, and run rules. Granularity decides how much of the system a test spans, from one kernel to the whole request path, and it is where the roofline’s prediction for ResNet-50 meets a measurement. Benchmark suites standardize those choices across organizations. The training and inference sections apply them to ResNet-50 and to MobileNetV2 on its edge board, and power measurement adds the joules, with keyword spotting as the case. Best practices supply the statistics that decide whether a measured difference is real, and model and data evaluation test the two dimensions that a hardware result cannot certify. The fallacies and the summary close by asking whether the evidence survives production traffic.
| Section | Claim it tests | What is measured | Granularity | Unit | Trap it guards against |
|---|---|---|---|---|---|
| Benchmark Carpentry | ResNet-50 at INT8 is faster than at FP32 | The claim restated as task, data, model, metric, harness, and run rules | Set by the claim | Stated per metric | A number reported without its conditions |
| Benchmarking Granularity | A kernel speedup speeds up the request | Kernel, model, and request-path time; predicted against measured roofline | Micro, macro, end to end | s, FLOP/s, B/s | A component speedup diluted by untouched stages |
| Benchmark Suites | Two vendors’ numbers are comparable | A reference workload under shared divisions, scenarios, and run rules | Model and system | Time to quality, QPS | Favorable conditions chosen separately by each vendor |
| Training Benchmarks | More accelerators train a model proportionally faster | Time to target accuracy, throughput, scaling efficiency, MFU | Model on one to eight accelerators | s, images/s, percent | Throughput that never reaches the quality target |
| Inference Benchmarks | MobileNetV2 meets its frame deadline on the board | Latency percentiles, throughput, memory, cold start | End to end on one board | ms (p50, p99), FPS, B | A mean that hides the tail; a burst that hides throttling |
| Power and Energy Measurement | The device lasts on its battery | Energy over a matched window; average power across the duty cycle | Device or system boundary | J per inference, W | Efficiency quoted at an operating point the device never holds |
| Benchmarking Best Practices | A measured difference is real | Repeated runs, paired tests, confidence intervals | Any | Interval | A one-point gap inside sampling noise |
| Model and Data Evaluation | The compressed model is still right on deployed data | Confidence calibration, slices, coverage, label quality, shift | Model and dataset | ECE, percent per slice | Aggregate accuracy that hides calibration and subgroup loss |
Knowing what to measure is only half of the problem. Measuring incorrectly, with the wrong workload, a biased baseline, or an uncontrolled variable, produces numbers that look precise and mislead the decision they inform. The history of computing benchmarks2 is full of technically sound metrics applied with flawed methodology, from compiler-gamed Whetstone scores to throughput claims that predict nothing about sustained workloads (section 12.4.1). The defense is construction. A benchmark must be built so that it measures what its claim says, and that construction is where the chapter begins.
2 Benchmark: From surveying, where a “bench mark” was a horizontal cut in stone serving as a fixed elevation reference. The term entered computing in the 1970s to describe standardized comparison points, and the surveying metaphor carries a systems lesson. Just as an elevation measurement is meaningless without a calibrated reference, an ML throughput number is meaningless without controlled workloads, thermal state, and precision settings.
Self-Check: Question
In the three-dimensional ML benchmarking framework, what distinct failure mode does system benchmarking isolate compared to model and data benchmarking?
- Whether hardware accelerators, memory subsystems, and software runtimes deliver expected computational throughput and latency under workload execution patterns
- Whether model compression techniques preserve confidence calibration and accuracy on rare edge cases
- Whether the training dataset contains sufficient coverage, demographic balance, and resistance to covariate drift
- Whether human labeling errors and noisy annotations degrade model convergence rates
True or False: Because ML benchmarks provide standardized datasets and metric formulas, a top-ranking benchmark score represents a permanent, universal verification of a model’s operational capability in production.
When benchmarkers compute useful model FLOPs per elapsed second and divide by the matching numerical-path peak throughput of the hardware, the resulting metric is abbreviated as ____.
Explain how Goodhart’s Law applies to ML systems benchmarking, and describe a concrete scenario where optimizing exclusively for a benchmark metric degrades real-world deployment quality.
12.2 Benchmark Carpentry
A claim that ResNet-50 runs faster at INT8 than at FP32 can reverse depending on whether timing starts at a JPEG on storage or at a preprocessed tensor in accelerator memory, or whether the quantized weights drop accuracy below the target floor. Benchmark carpentry is the craft of building a benchmark that measures what its claim says. It fixes the task, data, model, metrics, harness, system specification, and run rules so that the number the benchmark produces answers the engineering question and no other. A synthetic matrix-multiplication loop, a ResNet-50 training run over ImageNet, and a full serving pipeline all need these specifications, and changing one component changes what the next can measure. The components follow the D·A·M taxonomy. The problem definition fixes the input representation (Data), the dataset and task objective bound the feasible models (Algorithm), and the target hardware’s memory, energy envelope, and deadlines bound how the model may execute (Machine).
Evaluating an ML system requires coupling statistical task metrics with physical efficiency metrics. Quantization and pruning reduce parameter footprint and memory bus traffic, but they alter numerical representations and risk degrading task accuracy. A benchmark that records execution latency without statistical accuracy (such as area under the ROC curve (AUC) or classification error) rewards aggressive approximations that produce invalid outputs; conversely, reporting accuracy without latency or memory consumption conceals whether the model satisfies the target system’s physical constraints.
The measurement harness and run rules provide the experimental controls that make these evaluations reproducible. The protocol follows the question being tested. A controlled steady-state experiment can use warm-up iterations, fixed processor clocks, and pinned host memory to isolate execution differences. A deployment benchmark instead retains the relevant dynamic voltage and frequency scaling (DVFS) policy, cold starts, and competing workloads, documenting their effects. Recording tail latency distributions (p95, p99) alongside the mean exposes delays hidden by averages. Each component is built here on the claim the chapter inherited, that ResNet-50 runs faster at INT8 than at FP32, and MLPerf Tiny’s anomaly-detection benchmark at the end shows every component fixed at once on a small embedded model.
12.2.1 Turning a claim into a test
Every benchmark begins as a claim. The claim from the preceding chapters, that ResNet-50 at INT8 runs faster than at FP32 without unacceptable accuracy loss, is not yet testable, because it names neither the inputs, the output, nor the conditions under which faster must hold. Fixing those boundaries is the first act of carpentry. Without an explicit task specification, hardware and software optimizations cannot be evaluated on equivalent terms: altering an input resolution, a numerical datatype, or a latency deadline changes how much work the machine does. For ResNet-50 the input is a decoded \(224{\times}224\) RGB image and the output is one of a thousand ImageNet class labels. Whether the task is natural language processing (Hirschberg and Manning 2015) or computer vision (Everingham et al. 2009; Lin et al. 2014), a complete problem definition establishes three specifications: an input specification, an output specification, and a performance specification.
Hirschberg, Julia, and Christopher D. Manning. 2015. “Advances in Natural Language Processing.” Science 349 (6245): 261–66. https://doi.org/10.1126/science.aaa8685.
Everingham, Mark, Luc Van Gool, Christopher K. I. Williams, John Winn, and Andrew Zisserman. 2009. “The Pascal Visual Object Classes (VOC) Challenge.” International Journal of Computer Vision 88 (2): 303–38. https://doi.org/10.1007/s11263-009-0275-4.
The input and output specifications fix the data each run must move and define the exact scope of timed execution. The input specification fixes tensor dimensions, batching behavior, numerical representations (such as FP16 or INT8), and ingestion rates. For the ResNet-50 claim, it decides whether timing starts at a JPEG on storage or at a preprocessed tensor already in accelerator memory, a choice that can change the measured time more than the precision change being tested. Conversely, the output specification defines the termination boundary of the computation. Benchmarks frequently introduce measurement bias by timing only accelerator forward passes while ignoring the CPU post-processing required to turn raw tensor outputs into usable decisions. A robust output specification defines whether the system emits raw logits, intermediate embeddings, or final class labels, accounting for any downstream thresholding or reduction kernels that consume host memory bandwidth.
The performance specification defines the operational envelope that governs whether an optimization is viable. Unconstrained throughput numbers are meaningless if statistical accuracy degrades below acceptable thresholds, and high average throughput cannot rescue a system that violates a latency service-level agreement (SLA). For the ResNet-50 claim, the performance specification couples a quality floor (MLPerf Training requires 75.9 percent top-1, and an INT8 deployment might permit at most one percentage point of loss against FP32) with hardware execution limits: a tail-latency ceiling, sustained throughput matching the arrival rate of images, and a resident memory footprint that leaves room for activations at the chosen batch size. By defining these three boundaries up front, the benchmark ensures that the later stages, from dataset construction to measurement harness configuration, evaluate system optimizations against the true operational constraints of deployment.
12.2.2 Task and dataset
A task definition is only as rigorous as the data used to evaluate it. Standardized datasets enforce identical evaluation conditions across competing approaches, preventing teams from cherry-picking private slices that obscure comparative weaknesses. In computer vision, ImageNet (Deng et al. 2024, 2009), COCO (Lin et al. 2014), and CIFAR-10 (Krizhevsky 2009) establish reference tasks across classification and detection; in natural language processing, SQuAD3 (Rajpurkar et al. 2016), GLUE4 (Wang et al. 2018), and WikiText (Merity 2016; Merity et al. 2016) fulfill equivalent roles by standardizing comprehension, classification, and language modeling across diverse textual domains.
Lin, Tsung-Yi, Michael Maire, Serge Belongie, James Hays, Pietro Perona, Deva Ramanan, Piotr Dollár, and C. Lawrence Zitnick. 2014. “Microsoft COCO: Common Objects in Context.” In European Conference on Computer Vision (ECCV). Springer. https://doi.org/10.1007/978-3-319-10602-1_48.
3 SQuAD (Stanford question answering dataset): Introduced in 2016 with more than 100,000 question-answer pairs from Wikipedia (Rajpurkar et al. 2016). AI systems exceeded the SQuAD 1.1 human baseline of 91.2 percent F1 by 2018 (Devlin et al. 2019), but the “superhuman” result reflects a benchmarking failure mode. The task’s extractive format (answers are text spans within the passage) makes it easier than open-ended question answering, inflating perceived capability relative to production NLP systems.
Rajpurkar, Pranav, Jian Zhang, Konstantin Lopyrev, and Percy Liang. 2016. “SQuAD: 100,000+ Questions for Machine Comprehension of Text.” Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing, 2383–92. https://doi.org/10.18653/v1/d16-1264.
4 GLUE (general language understanding evaluation): Introduced in 2018 as a broad language-understanding benchmark (Wang et al. 2018), GLUE was quickly saturated by systems such as BERT (Devlin et al. 2019). Once GLUE became a target, leaderboard optimization reduced its discriminating power, as Goodhart’s Law predicts. The pattern motivated harder follow-on evaluations such as SuperGLUE and BIG-bench.
Wang, Alex, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. 2018. “GLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding.” Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP, 353–55. https://doi.org/10.18653/v1/w18-5446.
Devlin, Jacob, Ming-Wei Chang, Kenton Lee, and Kristina Toutanova. 2019. “BERT: Pre-Training of Deep Bidirectional Transformers for Language Understanding.” Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, 4171–86. https://doi.org/10.18653/v1/n19-1423.
Merity, Stephen. 2016. The WikiText Long Term Dependency Language Modeling Dataset.
Merity, Stephen, Caiming Xiong, James Bradbury, and Richard Socher. 2016. “Pointer Sentinel Mixture Models.” arXiv Preprint arXiv:1609.07843.
Dataset selection is the first place a benchmark can lose contact with deployment reality. ImageNet’s validation set fixes ResNet-50’s quality target, but its curated, centered photographs are not the frames a camera trap returns at dusk, a gap that section 12.9.2 returns to. A benchmark dataset must be representative enough to expose deployment failures and hard enough to separate models.
12.2.3 Model and metrics
With the task and dataset fixed, the benchmark must specify the model architecture and its baseline implementations. In systems benchmarking, the model defines the execution workload. Its computational graph determines arithmetic intensity, memory footprint, and communication topology. Selecting the benchmark model determines whether measured performance variations reflect architectural efficiency, software runtime optimizations, or raw accelerator capacity. Evaluating an architectural modification requires holding the runtime and hardware target constant. Conversely, evaluating hardware platforms or software execution engines requires standardizing on a fixed, representative model graph so that throughput differences isolate execution efficiency rather than mathematical changes to the workload.
Baseline models establish the empirical reference point for a target domain. Rather than toy algorithms, systems benchmarks rely on canonical workloads whose computational profiles and memory access patterns are well-characterized. In vision, ResNet-50 plays this role, which is why the chapter’s claim is stated on it. In language processing, BERT5 serves as a standard baseline because its multi-head self-attention and dense feed-forward blocks exercise both compute-bound matrix multiplications and memory-bandwidth-bound reduction operations. However, a baseline specification cannot stop at the mathematical graph. Two implementations of the identical architecture across different frameworks or runtimes often behave differently at runtime. Differences in kernel fusion (such as fusing normalization and activation functions directly into general matrix multiply (GEMM) output epilogues to avoid round-trips to high-bandwidth memory (HBM)), kernel launch overhead, and memory allocator behavior can exceed the performance impact of minor architectural variations. A comparison that isolates hardware must control the runtime implementation alongside the mathematical model; a runtime comparison instead names that implementation as the intervention and documents both stacks.
5 BERT (bidirectional encoder representations from transformers): BERT-Large (340M parameters) is a language-processing workload in MLPerf Inference. The benchmark fixes the task, data, quality target, and applicable execution scenarios so systems can be compared on the same workload. BERT latency still depends on sequence length, batching, and implementation.
A benchmark must select the operational regime relevant to its engineering question. In training, memory capacity and interconnect bandwidth can be binding constraints, because storing forward activations, backward gradients, and optimizer states across multiple accelerators limits batch size and demands high-bandwidth collective communication. Training benchmarks therefore measure time-to-accuracy under fixed convergence criteria rather than raw iteration speed alone. In inference, backward passes and optimizer states disappear. Evaluation instead emphasizes the serving objective, such as tail latency under SLAs, while low-batch autoregressive decode often faces bandwidth pressure. Transitioning a model to production frequently requires precision reduction, quantizing FP32 or BF16 weights and activations to INT8 or FP8. Moving eligible tensors from a 16-bit to an 8-bit format halves their raw storage and can reduce traffic or raise supported arithmetic throughput. Whole-model gains depend on the execution path, and validation must establish whether numerical error stays within the quality target. A development-to-deployment comparison may need both regimes because efficient training does not establish serving feasibility; a deployment decision for a fixed pretrained model can focus on inference.
Evaluation metrics6 translate raw model behavior into numbers that can be compared, ranked, and used to make engineering decisions. The difficulty lies in choosing the right numbers. A metric that captures accuracy but ignores latency may declare the winner to be a model too slow for production; one that rewards throughput but ignores energy may optimize for a deployment budget that does not exist. Table 3 categorizes evaluation measures by the failure mode each exposes and the deployment context it serves.
6 Metric: In mathematics, a metric is a distance function satisfying strict axioms including the triangle inequality. ML borrows the term loosely for quantitative measures such as BLEU and perplexity, which are scoring rules rather than mathematical metrics. Leaderboard rankings can change when the evaluation protocol, dataset slice, or metric weighting changes, making the choice of metric an engineering decision that shapes which system wins, not just how performance is measured.
| Category | Metric | Unit | Primary Use Case |
|---|---|---|---|
| Accuracy | Top-1/Top-5 Accuracy | Percentage | Classification |
| mAP (mean Average Precision) | 0–1 score | Object detection | |
| BLEU/ROUGE | 0–100 score | NLP generation | |
| Perplexity | Score (lower = better) | Language modeling | |
| Throughput | Samples/second | Samples/s | Batch inference |
| Token throughput | tokens/s | LLM inference | |
| Time-to-train | Hours/days | Training benchmarks | |
| Latency | p50 latency | Milliseconds | Median response time |
| p99 latency | Milliseconds | Tail latency (SLA) | |
| First-token latency | Milliseconds | LLM responsiveness | |
| Efficiency | Samples/second/watt | Samples/s/W | Energy efficiency |
| Accuracy/FLOP | percent/PFLOP | Algorithmic efficiency | |
| TCO per inference | $/inference | Economic efficiency |
The metrics in table 3 expose physical trade-offs governed by the accelerator architecture. Throughput measures aggregate processing capacity, whereas latency measures individual request completion time. These two objectives conflict directly at the hardware boundary. Maximizing throughput requires aggregating requests into larger batches to amortize weight-loading memory bandwidth across multiple inputs, raising arithmetic intensity on tensor units. That batching mechanism inflates per-sample latency, because individual requests wait in arrival queues while a batch forms, and larger matrix operations take longer to complete. Furthermore, arithmetic mean latency masks tail behavior. Queuing jitter, memory allocation stalls, and accelerator thermal throttling cause execution times to diverge; a system with a 10 ms mean latency can still suffer a 500 ms p99 latency that violates service-level agreements. Benchmarks must therefore report distribution percentiles (p50, p95, p99) rather than averages. Compound metrics such as samples/second/watt compress multiple dimensions into a single scalar, simplifying high-level comparisons but obscuring where bottlenecks reside. Reporting atomic metrics (latency distributions, throughput, and power draw) alongside compound figures isolates which physical constraint limits the system.
↪ The batch size at which waiting for a batch to form pushes latency past its budget is measured with a batch-size sweep in Formation delay and the latency-throughput frontier.
7 BLEU (bilingual evaluation understudy): Introduced by IBM in 2002, BLEU measures translation quality through modified n-gram precision with a brevity penalty against reference translations (Papineni et al. 2002). BLEU is a canonical example of Goodhart’s Law in ML, because optimizing for n-gram matches can reward surface-level word overlap even when meaning, fluency, or deployment usefulness diverges from the target.
Papineni, Kishore, Salim Roukos, Todd Ward, and Wei-Jing Zhu. 2002. “Bleu: A Method for Automatic Evaluation of Machine Translation.” Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL ’02, 311–18. https://doi.org/10.3115/1073083.1073135.
Task-specific metrics evaluate the algorithmic dimension, quantifying whether the model solves the statistical problem. Classification workloads evaluate accuracy (the fraction of correct predictions), precision, recall, and the F1 score (Sokolova and Lapalme 2009). Precision and recall isolate true positive rates from false alarms, which is essential when class distributions are imbalanced. Continuous estimation tasks rely on Mean Squared Error (MSE) or Mean Absolute Error (MAE), while sequence generation uses specialized scoring rules such as BLEU7 to measure modified n-gram precision against human reference translations (Papineni et al. 2002).
Task metrics evaluate algorithmic quality in isolation, but deployment viability depends on physical machine constraints. Model capacity, measured in parameter count and memory footprint, determines whether weights fit into on-chip SRAM or accelerator memory, or whether they spill across high-latency interconnects. Per-inference execution latency dictates whether a system meets real-time deadlines, while energy consumption per inference (measured in joules or millijoules) bounds thermal dissipation and battery life.
Benchmarks must also account for measurement sensitivity across software runtimes. As established in Model Training, different frameworks handle loss computation, kernel fusion, and gradient accumulation differently, altering reported benchmark numbers. Subtle implementation differences, such as whether batch normalization is configured to use stored running statistics or current mini-batch statistics during evaluation, or how non-associative floating-point additions are reordered in reduction kernels, shift measured accuracy and latency enough to invert benchmark rankings when candidate models differ by narrow margins.
12.2.4 Benchmark harness
Metrics define what to measure; the benchmark harness determines how to measure it. The harness is the software and instrumentation scaffold that feeds inputs to the system under test, coordinates execution, collects timing and power traces, and enforces reproducibility. In an ML system, measuring execution down to the metal requires accounting for the asynchronous execution boundary between the host CPU and the accelerator. When host software initiates an inference or training step, the framework runtime merely enqueues commands onto an accelerator work queue (such as a CUDA stream or hardware command buffer) and returns control immediately. A naive timer wrapping the host-level call measures only this sub-microsecond queue dispatch latency rather than actual device execution. A rigorous harness inserts explicit device synchronization barriers (such as torch.cuda.synchronize()) or queries on-device timestamp events (such as torch.cuda.Event), ensuring that recorded timings reflect complete kernel execution and memory transfers across the bus rather than mere host enqueue overhead.
Harness architecture must align with the operational regime of the deployment target. In server environments, the harness generates concurrent request traffic using an open-loop load generator, often parameterizing inter-arrival times with a Poisson distribution.8 An open-loop harness issues requests according to an independent arrival schedule regardless of server responsiveness. This decoupling exposes queuing delays and tail latency (such as p99 response times) when arrival bursts saturate available compute.
8 Poisson distribution: Named after Siméon Denis Poisson, who formalized it in 1837 while modeling wrongful conviction rates in French courts. The distribution models independent events at a constant average rate \((\ArrivalRate)\) and is a common baseline for server request arrivals. Real ML serving traffic often violates its assumptions through burstiness, correlation, and time-varying rates. A Poisson harness can therefore misestimate tail latency unless traces or stress cases cover those production patterns.
In contrast, a naive benchmarking client often employs a closed-loop pattern: sending a request, blocking until the response arrives, and only then issuing the next request. This design introduces the severe measurement distortion known as coordinated omission. Consider a server that experiences a transient 500 ms garbage collection pause or memory reallocation stall. In an open-loop production environment, independent users continue submitting queries, causing dozens of requests to accumulate in the server’s ingress queue; once the pause ends, every queued query suffers inflated tail latency. In a closed-loop benchmark, however, the client blocks idly during the entire 500 ms pause, sending zero traffic while the server is struggling. The benchmark records a single slow query and zero queue backlog. By coordinating request generation with server responsiveness, the closed-loop harness artificially paces traffic, systematically erasing the very queue collapse and p99 latency spikes it was constructed to measure. Conversely, offline batch processing eliminates arrival scheduling entirely; the harness pre-stages large input batches in memory to saturate accelerator execution units, maximize memory bandwidth utilization, and measure peak sustained throughput.
In embedded and edge deployments, workloads are neither stochastic network streams nor unconstrained batch queues. Instead, inputs arrive sequentially from physical sensors (such as an audio analog-to-digital converter or an image sensor) governed by fixed hardware sampling clocks. The harness must inject these sensor streams through direct memory access into limited on-chip SRAM buffers, verifying that each inference completes within the inter-sample arrival deadline to prevent buffer overflow. Furthermore, edge harnesses must integrate physical instrumentation, such as shunt resistors or external power analyzers, to sample voltage and current across active execution cycles and low-power sleep states, capturing the true energy consumed per inference.
Reproducibility requires specifying which runtime and environmental conditions are controlled and which are part of the workload. Warm-up matters at every scale, from a single kernel to a whole run, because modern accelerators and runtime frameworks have substantial cold-start transients. Initial inference passes trigger on-demand memory allocations, dynamic just-in-time (JIT) compilation, driver initialization, and weight transfers from secondary storage into accelerator memory. For steady-state measurements, the harness executes unmeasured warm-up iterations until caches populate, memory allocators stabilize, and the intended thermal operating state is reached. Controlled experiments may fix clocks and remove competing processes; deployment tests retain and report the relevant DVFS policy and contention. Cold-start measurements time initialization separately instead of discarding it. Finally, telemetry logging must minimize the probe effect by recording execution timestamps and performance counters into non-blocking, pre-allocated memory buffers. The remaining instrumentation overhead should be checked against a minimally instrumented run.
12.2.5 Specifications and run rules
Complementing the harness that controls execution conditions, system specifications record the computational environment, the physical hardware and software stack that establishes the Machine (\(\text{M}\)) boundaries of the system, and run rules govern how the benchmark runs on it. Without both, a reported throughput or latency measurement cannot be interpreted. An execution metric reflects the interaction between an algorithm’s arithmetic intensity and a machine’s physical limits: peak arithmetic throughput, memory hierarchy bandwidth, and interconnect latency. A throughput figure reported without accelerator model, memory bandwidth, or operating clocks conceals whether an observed speedup stems from algorithmic efficiency or upgraded silicon, and a result reported without its seed policy conceals whether it is reproducible at all, because the stochastic processes catalogued in section 12.4.2 mean that two runs on identical hardware can produce different numbers. A protocol may fix seeds and data order when isolating system effects, or require repeated runs and quality thresholds when stochastic variation is part of the workload. Table 4 lists what a reproducible report records.
| Item | What the report records | Why the result depends on it |
|---|---|---|
| Accelerator | Microarchitecture, active core count, base and boost clocks, power limit (TDP) | Sets the peak arithmetic rate and how long boost clocks persist |
| Device memory | Capacity, bus width, peak bandwidth | Sets the bandwidth ceiling and the largest batch that fits |
| Multi-accelerator topology | Host interface (PCIe lanes) and accelerator links (NVLink or shared PCIe switches) | All-reduce time is bounded by link bandwidth and topology |
| Software stack | Operating system, driver, compute runtime (CUDA or ROCm), math libraries (cuBLAS, CUTLASS) | Kernel selection, tiling, and reduction order change with library version |
| Framework layer | Framework version, eager or compiled execution (torch.compile), fusion settings |
Separates framework overhead from model cost |
| Power and thermal | Sustained board power, throttling events, energy per sample or token | A speedup from transient clock boosting does not persist |
| Randomness | Seed policy, data order, known nondeterministic kernels | Two runs on identical hardware can produce different numbers |
| Configuration | Every hyperparameter, including the learning-rate schedule | A learning-rate change shifts convergence and final accuracy |
| Data | Dataset version, splits, preprocessing; any privacy or licensing limit on sharing | Different splits or preprocessing define a different workload |
| Code | Version of model, preprocessing, training, and evaluation code; container image | Lets another team inspect and, where access permits, reproduce the run |
Reference suites may distribute containerized environments that encapsulate dependencies and configurations, while experimental logs retain training metrics, checkpoints, and any mid-run adjustments. Together, these records turn a one-time measurement into evidence another team can inspect and, when access permits, reproduce.
12.2.6 Interpreting results
Producing raw benchmark numbers requires only execution; interpreting them requires understanding the conditions that produced them, the statistical confidence behind them, and the operational boundaries that determine whether the numbers translate to production behavior. A single reported metric, such as latency or accuracy, rarely reveals whether an optimization succeeds in deployment.
Translating benchmark numbers into engineering decisions requires two methodological checks: a defined intervention and statistical rigor. First, state what changes and what remains comparable. ResNet-50 versus MobileNet can be a valid architecture comparison at matched task and quality requirements; FP32 versus INT8 can be a valid precision comparison on a supported execution path. Hold the other relevant conditions fixed or report their changes, including batch size, hardware, runtime, input distribution, and service targets. Second, distinguish steady-state execution from initialization, using the harness’s warm-up protocol (section 12.2.4). A single run conflates cold-start overhead (kernel compilation, page faults, and cache warming) with sustained throughput, while a prolonged stress test may instead capture the thermal throttling examined for edge devices in section 12.6.4. Report cold-start and steady-state results according to the deployment question, and record variation across repeated trials. Whether a measured difference exceeds that variation is a statistical question, answered with the interval and paired-test rules of section 12.8.1.
Systems Perspective 12.3: Interpreting a benchmark claim
A vendor claims “Our system achieves 10,000 inferences/second on ResNet-50.” Taken alone, the number cannot support deployment planning because the conditions that determine its meaning are unstated.
Four unstated conditions determine what the claim means:
- Batch size: Large batches amortize weight transfers and maximize compute utilization but inflate queuing delay; batch 1 minimizes latency but leaves execution units underutilized.
- Precision: INT8 execution exploits higher-throughput integer pipelines and cuts memory traffic, but requires quantization-range calibration that can compromise numerical fidelity.
- Measurement boundary: The measurement window must state whether it isolates pure accelerator kernel execution or includes host-to-device transfers, JPEG decoding, and tensor format conversions.
- Accuracy: The claim must state whether the optimized model retains baseline validation accuracy (such as 76.1 percent Top-1 on ImageNet) or trades task quality for raw execution speed.
Example: “10,000 inferences/second on ResNet-50 at batch size 32, INT8 precision, 76 percent Top-1 accuracy, including JPEG decoding, on NVIDIA H100 at 700 W thermal design power (TDP).”
Systems insight: A throughput figure lacking batch size, precision, measurement scope, and accuracy targets is a marketing metric rather than an engineering specification.
A claim whose workload boundary, precision, and excluded costs cannot be reconstructed should be rejected. Marketing phrases compress such omissions into a few words, usually reporting the most favorable operating point without saying so; table 5 translates common ones into the technical caveats behind each.
| Vendor Claim | What It Often Means |
|---|---|
| “Up to 10,000 images/sec” | Peak throughput at maximum batch size, INT8, without preprocessing |
| “Sub-millisecond latency” | Accelerator compute only, excluding data transfer |
| “5\(\times\) more efficient” | Per-operation efficiency, not total system efficiency |
| “Optimized for AI” | May only accelerate specific operations or precisions |
Which metric governs viability depends on the deployment. In safety-critical applications such as medical imaging or autonomous driving, a 1 percent accuracy gain justifies substantial computational cost; in interactive search or speech transcription, tail latency within a tight service-level agreement dominates, so a minor accuracy gain is irrelevant if it breaches the latency budget. Systems evaluation must also guard against benchmark overfitting, in which an optimization targets the idiosyncratic computational patterns of a standardized suite at the expense of production workloads. For example, aggressive kernel fusion or operator tiling tuned exclusively for fixed sequence lengths in a benchmark harness can degrade throughput when deployed against dynamic, variable-length user requests. Robust interpretation requires validating performance across diverse input distributions, perturbed batch sizes, and representative operational duty cycles.
Checkpoint 12.1: Decoding vendor benchmark claims
When evaluating hardware or software based on vendor-reported benchmarks, check whether the claim identifies the workload, measurement boundary, and operating conditions.
12.2.7 A complete reference benchmark
MLPerf Tiny’s anomaly-detection benchmark shows every component fixed at once on one small embedded model. The multi-stage pipeline in figure 1 traces this industrial audio benchmark across nine sequential phases, carrying the task from problem definition in the top chevrons through spectrogram extraction, autoencoder training, and INT8 quantization down to embedded deployment on an ARM mbed OS microcontroller. Each stage fixes boundary conditions for the next: the problem definition dictates the acoustic sampling rate and input representation (Data); the dataset properties and task objective determine feasible model architectures (Algorithm); and the microcontroller’s hardware limits (SRAM capacity, energy envelope, and real-time latency deadlines) dictate INT8 quantization and memory-efficient kernel compilation (Machine). Here every choice constrains the next, so a benchmark that measures only classification accuracy or only raw inference latency misses cross-stage interactions, where an engineering decision at any stage narrows the feasible design space downstream.
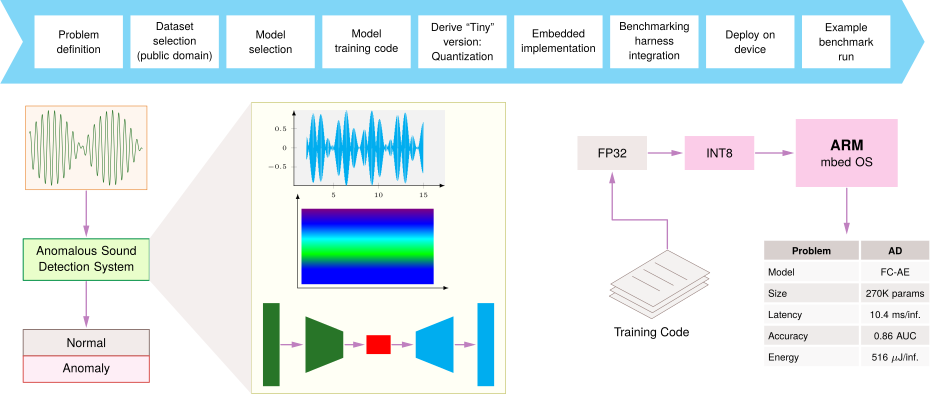
Its problem definition fixes the same three specifications that the ResNet-50 claim needed. The input is single-channel audio streamed at 16 kHz in fixed one-second windows, which sets a rigid ingestion rate and memory buffer requirement before feature extraction begins. The output is a binary “Normal” or “Anomaly” flag, including any thresholding that turns a reconstruction error into that decision. The performance specification couples a quality metric, area under the ROC curve (AUC), with execution limits: a per-inference latency that keeps pace with the one-second input windows, sustained throughput matching the arrival rate, and a resident footprint that avoids out-of-memory faults on the microcontroller.
At the dataset selection stage (the second chevron), the benchmark pipeline ingests representative audio waveform samples of normal machine operation alongside anomalous conditions before spectrogram feature extraction. Domain-specific collections cover different audio tasks: ToyADMOS9 (Koizumi et al. 2019) supports controlled anomaly-detection research, while Google Speech Commands (Warden 2018) supports keyword recognition. Simplified datasets like ToyADMOS are valuable for methodological development but may not capture the full complexity of production environments.
9 ToyADMOS: Developed by NTT Communications in 2019 for acoustic anomaly detection, containing audio recordings from toy car, toy conveyor, and related miniature-machine operating sounds (Koizumi et al. 2019). The “toy” prefix is intentional: the controlled environment enables reproducible benchmarking but can create a domain gap when models are moved to noisier industrial environments with different machines, sensors, vibration, and background sound.
Koizumi, Yuma, Shoichiro Saito, Hisashi Uematsu, Noboru Harada, and Keisuke Imoto. 2019. “ToyADMOS: A Dataset of Miniature-Machine Operating Sounds for Anomalous Sound Detection.” 2019 IEEE Workshop on Applications of Signal Processing to Audio and Acoustics (WASPAA), 313–17. https://doi.org/10.1109/waspaa.2019.8937164.
Warden, Pete. 2018. “Speech Commands: A Dataset for Limited-Vocabulary Speech Recognition.” arXiv Preprint arXiv:1804.03209, ahead of print. https://doi.org/10.48550/arXiv.1804.03209.
This interdependence between statistical quality and hardware constraints is evident in anomaly detection. In industrial monitoring, extreme class imbalance renders raw accuracy deceptive. If anomalies constitute only 0.1 percent of operating samples, a trivial model that constantly predicts normal operation achieves 99.9 percent accuracy while failing to detect any faults. The benchmark must instead report AUC, which scores how well the model ranks anomalous samples above normal ones across every decision threshold, alongside physical resource metrics.
This multi-metric evaluation approach governs the anomaly detection pipeline, which balances four simultaneous constraints: a model size of 270K parameters whose stored representation and runtime buffers must fit the embedded SRAM budget, a processing latency of 10.4 ms per inference to maintain real-time sampling, a detection accuracy of 0.86 AUC, and an energy consumption of 516 µJ per inference within the target battery budget. Evaluating across all four axes prevents declaring a model superior when its accuracy gain stems from an architecture too large to fit in memory or too power-hungry to survive sustained deployment.
The deployed anomaly detection workflow in figure 1 records the four measurements from section 12.2.3 in its terminal reporting table (lower right). For the fully connected autoencoder (FC-AE) on the ARM mbed OS target, each certifies something different. Parameter count and per-inference latency certify computational resources, the AUC certifies task effectiveness, and energy per inference certifies operational efficiency.
On a microcontroller, each metric governs a different failure: energy per inference sets battery life on untethered devices, model size decides whether weights fit in fast on-chip SRAM or spill into off-chip DRAM, and latency determines whether streaming audio is processed without dropped frames. The metrics trade against one another: reducing model size below 270K parameters can reduce memory traffic and execution time on a supported path, but risks degrading the 0.86 AUC detection accuracy. Whether these measurements constitute a passing benchmark depends on the operational envelope; the benchmark specification standardizes the evaluation protocol, but application requirements dictate the acceptance thresholds.
The reference flow fixes the task, data, model, and measurement boundary, but it measures one model on one device at one scope. Before choosing that scope, a benchmark should pass three methodological checks.
Checkpoint 12.2: Benchmarking methodology
Three practices distinguish rigorous benchmarks from misleading ones:
A benchmark that passes those checks has still made a second choice, often implicitly. It decides how much of the system it measures. A single kernel, the whole model, and the request path around the model each answer a different question, and each fails in a different way.
Self-Check: Question
Which core benchmark component is responsible for documenting the exact hardware model, CPU core pinning, GPU driver version, CUDA toolkit, compiler flags, and OS kernel version required to ensure experimental reproducibility?
- System specifications
- Dataset split definition
- Evaluation metric formula
- Problem definition
When designing a benchmark suite for an edge computer vision model deployed on a battery-powered security camera with passive cooling, which set of evaluation metrics provides the most complete assessment of deployment viability?
- Peak offline throughput in FP32 without thermal monitoring
- Energy per inference (mJ), active vs. idle power consumption across the device duty cycle, memory footprint (SRAM/DRAM usage), sustained latency under thermal equilibrium, and deployed-model quality on representative and critical input slices
- Only the model parameter file size on disk in megabytes
- Top-1 validation accuracy measured on an uncompressed server GPU
True or False: When evaluating model compression techniques (such as INT8 quantization or structured pruning), validating that the compressed model achieves a \(4\times\) reduction in file size with \(<0.5\%\) top-1 accuracy loss is sufficient to guarantee proportional speedups and energy savings on any target deployment hardware.
In standardized benchmarking suites, the formal component that defines the mandatory execution constraints, convergence thresholds, warmup requirements, and statistical aggregation procedures to ensure fair cross-platform comparisons is called the ____.
Order the following execution steps of a standardized benchmark harness protocol from beginning to end for a controlled steady-state measurement workflow: (1) Execute the timed measurement loop while collecting high-resolution hardware timestamps, (2) Apply the selected environment controls, such as CPU affinity pinning and any documented clock policy, (3) Compute summary statistics (mean, median, p90, p99, standard deviation) and confidence intervals, (4) Execute unmeasured warm-up iterations to load model weights and warm instruction/data caches, (5) Perform verification check to ensure model output predictions match ground truth quality thresholds
A vendor publishes a marketing claim stating their new AI accelerator achieves ‘\(120\text{ TFLOP/s}\) on Transformer inference.’ Which combination of parameters is essential to make this throughput figure technically actionable and reproducible?
- Only the silicon process node (e.g., \(4\text{ nm}\)) and the data center room temperature
- Numerical path (e.g., FP32 vs. FP16), batch size, sequence length, software/compiler stack version, and sustained thermal operating state
- The brand of server power supply and the serial number of the host CPU
- Only the parameter count of the model, without specifying batch size or precision
12.3 Benchmarking Granularity
A kernel that runs 3\(\times\) faster in isolation may deliver no end-to-end speedup if the data pipeline cannot keep the accelerator fed. In an illustrative request, a 3× inference speedup applied to a 10 ms model stage inside a 50 ms request yields only about a 1.2× end-to-end improvement, or less if the optimization increases memory pressure. The dilution makes the measurement boundary a design choice. Carpentry specifies how a measurement is built, while benchmarking granularity specifies what physical boundary it measures. System validation spans multiple architectural scales, from individual tensor operations to complete production pipelines, with each granularity diagnosing distinct bottlenecks:
- Micro benchmarks isolate individual components: kernel execution time, memory bandwidth utilization, and single-layer numerical behavior. These diagnose where low-level hardware inefficiencies occur.
- Macro benchmarks evaluate composed model subsystems: full model training convergence, inference pipeline throughput, and dataset accuracy metrics. These reveal what architectural trade-offs exist across layer compositions.
- End-to-end benchmarks measure complete operational pipelines: client request-to-response latency including preprocessing, training time-to-accuracy including storage I/O, and model robustness on production data distributions. These show whether the combined system satisfies real-world service-level objectives.
Component speedup rarely survives as end-to-end benchmark speedup.
Optimization techniques operate across distinct granularities: kernel fusion targets micro-level execution, structured pruning alters macro-level parameter structures, and data curation determines end-to-end generalization. System validation must align with these respective boundaries. An isolated micro-benchmark may show substantial kernel speedup, yet a macro-benchmark can reveal that increased activation memory footprints force smaller batch sizes that degrade overall throughput. Similarly, an end-to-end benchmark exposes storage or host deserialization stalls that remain completely invisible at the accelerator kernel level.
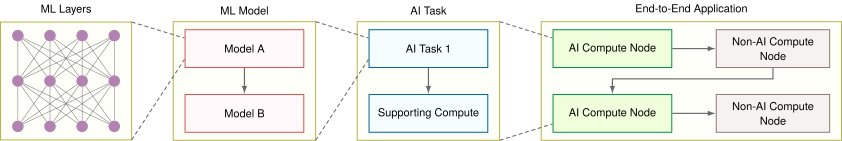
Measurement perimeters widen from left to right in figure 2, and the figure inserts one tier between macro and end-to-end. Micro-benchmarks isolate kernel layers (ML Layers) and macro-benchmarks evaluate composed models (ML Model). An application benchmark then adds the supporting host compute around the model (AI Task), and the end-to-end benchmark adds the non-AI compute nodes the request also traverses. The three granularities in this section fold the application tier into end-to-end, but the four-tier view shows where bottlenecks migrate as the boundary widens: out of the accelerator and into the host systems around it.
12.3.1 Micro benchmarks
While end-to-end metrics govern service-level agreements, optimizing an accelerator pipeline requires isolating the specific mathematical operations that consume execution time and energy. Micro-benchmarks serve this diagnostic role by evaluating individual tensor operations in isolation, measuring the accelerator’s hardware primitives directly. When profiling a slow inference service, macro-benchmarks report aggregate latency violations, but only micro-benchmarks reveal whether execution time is dominated by matrix multiplications, self-attention projections, memory copies across the host-accelerator interconnect, or elementwise activation kernels.
↩︎ The compute primitives that micro-benchmarks isolate, vector and matrix operations and special function units, are established in Compute Primitives.
10 cuDNN (CUDA deep neural network library): Released by NVIDIA in 2014, cuDNN provides hand-tuned kernel implementations for convolutions, pooling, and normalization. The benchmarking implication: reported inference latencies depend heavily on which cuDNN version and algorithm autotuner settings were used, making cuDNN version a mandatory element of any reproducible benchmark specification.
Chetlur, Sharan, Cliff Woolley, Philippe Vandermersch, Jonathan Cohen, John Tran, Bryan Catanzaro, and Evan Shelhamer. 2014. “cuDNN: Efficient Primitives for Deep Learning.” arXiv Preprint arXiv:1410.0759.
Baidu Research. 2016. DeepBench: Benchmarking Deep Learning Operations on Different Hardware.
Tensor operations constitute the primary target of micro-benchmarking because matrix multiplications and convolutions dominate the arithmetic budget of deep neural networks. Highly optimized runtime libraries such as cuDNN10 (Chetlur et al. 2014) provide hand-tuned kernel implementations tailored to specific microarchitectures. Micro-benchmarks also evaluate standalone activation functions (such as ReLU, Sigmoid, and GELU) and structural submodules (such as multi-head attention projections or transformer feed-forward blocks) across standardized input shapes. Benchmark suites such as Baidu’s DeepBench (Baidu Research 2016) formalized this methodology by evaluating raw GEMM, convolution, and collective communication primitives across diverse hardware platforms, isolating silicon-level execution efficiency from higher-level framework dispatch overhead.
Measuring isolated kernels requires rigorous experimental control. Without disciplined measurement protocols, dynamic hardware frequency scaling, asynchronous execution queues, and cache state introduce transient artifacts that distort kernel runtime.
Systems Perspective 12.4: Micro-benchmarking rules
Five rules keep a micro-benchmark measuring the kernel rather than a hardware artifact:
- The warm-up rule: Do not measure cold-start iterations as steady-state performance. Modern hardware uses DVFS (dynamic voltage and frequency scaling) and dynamic frequency boosting; caches, kernels, and clocks need warm-up before the measured loop represents sustained behavior.
- The variance rule: Report the coefficient of variation (CV) \((\text{CV} = \RepeatedRunStandardDeviation/ \RepeatedRunMean)\), where \(\RepeatedRunStandardDeviation\) and \(\RepeatedRunMean\) are the standard deviation and mean across repeated runs. Investigate values above the protocol’s workload-specific tolerance; common causes include background OS jitter, thermal throttling, and memory contention, and 5 percent is not a universal cutoff.
- The “speed of light” (SOL) check: Compare the achieved throughput against the roofline. If a kernel achieves 10 TFLOP/s on an H100 (peak ~989 TFLOP/s FP16, or ~1,979 TFLOP/s FP8 dense), the diagnostic step is to identify the cause of low utilization (often kernel launch latency from too many small kernels) before optimizing the code itself.
- The cache-state rule: Set cache state to match the claim. Flush or exceed the L2 cache when measuring cold dynamic random-access memory (DRAM) bandwidth; preserve a warmed cache when measuring steady-state reuse. Otherwise a nominal DRAM result may instead reflect cache bandwidth (~5 TB/s–10 TB/s) rather than DRAM bandwidth (~1 TB/s–2 TB/s).
- The synchronization barrier rule: Accelerator kernel launches are asynchronous on the host CPU. Timing GPU operations using CPU clocks without an explicit device barrier (such as
torch.cuda.synchronize()) measures host enqueue latency rather than kernel execution; always place synchronization barriers immediately before and after the timed region, or use GPU-side timestamp events (cudaEventRecord).
The roofline model11 of Performance Bounds, which plots the bound of the arithmetic intensity law (principle 6), is a prediction, and a benchmark is the measurement that tests it. The roofline bounds where a kernel can sit; a benchmark determines where it does sit, and the gap between the two is the diagnostic. A kernel far below its predicted ceiling is losing time to something the model omits (launch overhead, poor coalescing, synchronization), which is exactly what profiling looks for. Making the prediction requires the workload’s arithmetic intensity at a named memory interface and the target’s matching compute and bandwidth limits. For an NVIDIA H100 with 989 TFLOP/s of dense FP16 Tensor Core performance (FP32 is 67 TFLOP/s)12 and 3.35 TB/s of memory bandwidth, the ridge point (peak compute divided by peak bandwidth, the intensity at which the two ceilings meet) falls at 295 FLOP/byte. Below it, bandwidth sets the lower ceiling; above it, compute does (Hardware ridge points derives the threshold).
11 Roofline model: Williams et al. (2009) introduced the Berkeley model, named for the visual shape of its performance ceiling. Its ridge point (peak FLOP/s divided by peak bandwidth) separates bandwidth-limited from compute-limited ceilings, suggesting which interventions to test against measured execution.
Williams, Samuel, Andrew Waterman, and David Patterson. 2009. “Roofline: An Insightful Visual Performance Model for Multicore Architectures.” Communications of the ACM 52 (4): 65–76. https://doi.org/10.1145/1498765.1498785.
12 FLOP/s (floating-point operations per second): The gap between advertised peak FLOP/s and achieved FLOP/s is the central tension in hardware benchmarking. The H100 advertises 989 TFLOP/s of dense FP16 Tensor Core arithmetic, but real workloads achieve different fractions of peak depending on arithmetic intensity, memory access patterns, precision, and runtime overhead. Reporting peak FLOP/s without utilization context is the most common benchmarking distortion.
↪ The H100 ridge point, with a compute-bound matrix multiplication and a memory-bound element-wise kernel placed on either side of it, is collected for reference in A concrete example: The H100 analysis.
A profiler translates these measurement rules into physical diagnostics by decomposing kernel execution time into the three governing terms of the iron law: data movement, compute throughput, and latency overhead. Comparing the measured utilization of each resource against hardware limits reveals which term dominates the trace.
Systems Perspective 12.5: Measuring the iron law terms
Moving from theory to trace means mapping the iron law equation onto a profiler timeline (like Nsight Systems or PyTorch Profiler).
Measuring the data term \(\left(\frac{\DataVolume}{\Bandwidth}\right)\)
- Signal: Look for the “Memory Throughput” or “DRAM Bandwidth” line.
- Formula: \(\AchievedKernelBandwidth = \frac{\DataVolume}{\KernelExecutionTime}\).
- Diagnosis: If \(\AchievedKernelBandwidth \approx \PeakMemoryBandwidth\) (for example, close to the H100’s 3.35 TB/s peak), bandwidth pressure is a strong candidate bottleneck. Test whether reducing traffic or increasing bandwidth improves time; a high bandwidth reading alone does not establish that changing compute (\(\Operations\)) has no effect.
Measuring achieved compute throughput \((\PeakRate \cdot \EfficiencyHw)\)
- Signal: Distinguish “SM Active,” the fraction of time the GPU’s Streaming Multiprocessors (SMs), its parallel execution cores, have work resident, from executed-operation throughput. A busy multiprocessor does not imply high useful-model FLOP/s.
- Formula: \(\PeakRate \cdot \EfficiencyHw = \frac{\Operations}{\KernelExecutionTime}\), reported in TFLOP/s.
- Diagnosis: If \(\EfficiencyHw \ll 1\) AND \(\AchievedKernelBandwidth \ll \PeakMemoryBandwidth\), neither quoted peak is being approached. Kernels too small to amortize launch latency or too few threads to occupy the SMs are candidate explanations, but low aggregate rates alone do not exclude dependency stalls or an inefficient memory-access path. Separate inter-kernel gaps from in-kernel stalls, then inspect the corresponding dispatch, dependency, occupancy, or memory-access evidence before selecting an optimization.
Measuring the latency term \((\Latency)\)
- Signal: Look for gaps (empty space) between colored kernel bars on the timeline.
- Formula: \(\text{Kernel gap fraction} = \frac{\InterKernelGapTime}{\KernelExecutionTime+ \InterKernelGapTime}\).
- Diagnosis: A “Sawtooth” pattern (Compute, Gap, Compute, Gap) suggests exposed waiting; correlate CPU dispatch, dependencies, and transfers before attributing it to software overhead. If dispatch dominates, candidates include kernel fusion, covered in Kernel fusion on the accelerator, or the CUDA Graphs of Graph capture and JIT compilation, which capture a repeated sequence of GPU launches so the runtime can replay it with less CPU dispatch overhead.
Profilers supply the measurements this mapping needs. A framework profiler such as the PyTorch Profiler isolates the dominant layer on the step timeline, and a kernel profiler such as NVIDIA Nsight Compute explains it from on-chip performance counters, the top-down method developed on a training step in Identifying Bottlenecks. Counter collection and kernel replay perturb timing, so diagnostic traces are compared against a minimally instrumented run. The benchmarking use is narrower, confirming or refuting a prediction.
↩︎ The feeding problem, the wall-clock time an accelerator loses waiting on input I/O, is established in The feeding problem.
These granular measurements enable precise kernel optimization, but they cannot reveal how components interact when assembled into complete models. Macro-benchmarks address this gap.
12.3.2 Macro benchmarks
Micro-benchmarks verify that isolated operators achieve high compute or memory efficiency. Macro-benchmarks determine whether those gains persist when layers are composed into a complete model. Composing layers introduces physical interactions that isolated benchmarks cannot observe: intermediate activation tensors expand peak memory footprint, sequential kernel launches expose CPU driver dispatch overhead, and memory access streams from preceding operations evict shared cache lines before downstream kernels can reuse them.
Macro-benchmarks serve a central engineering objective: evaluating model architectures and runtime configurations under standardized workloads. Model-level evaluation captures the trade-offs that emerge from layer composition: generalization accuracy on unseen validation data, dynamic memory allocation across batch sizes and context lengths, and aggregate throughput across varied request arrival patterns. These dimensions interact directly. An architecture that achieves higher accuracy may require an activation footprint that forces a smaller batch size under device memory constraints, collapsing the computational throughput that justified its adoption. ResNet-50’s training step tests the roofline’s prediction at exactly this granularity, because the prediction is made layer by layer and the measurement is made on the composed model.
Napkin Math 12.1: ResNet-50 on the roofline: Predicted versus measured
Problem: The roofline predicts the fastest an H100 can train ResNet-50, and MLPerf measures how fast it does. How large is the gap, and what does it say about where the time goes?
Prediction: One training image costs about 24.6 GFLOP, three times the 8.2 GFLOP forward pass, because the backward pass computes gradients with respect to both activations and weights. At training batch sizes, the convolution layers reuse each weight across hundreds of images and sit above the 295 FLOP/byte ridge, so the roofline places the step on the compute roof. Dividing the 989 TFLOP/s peak by the work per image gives a ceiling of about 40,200 images/s.
Measurement: The MLPerf Training per-accelerator result for H100-class systems is about 5,000 images/s, which delivers about 123 TFLOP/s of model arithmetic, 12.4 percent of peak.
Diagnosis: The measurement sits 8.0× below the prediction. The roofline did not err; it bounded the convolutions and omitted the rest of the step. Normalization and elementwise layers have intensities far below the ridge and run on the bandwidth slope, the host must decode and augment thousands of JPEG images every second, and every step pays launch and synchronization overhead. The prediction cannot say which of these dominates. A profiler attributes the gap among them (perspective 12.5), and Identifying Bottlenecks works that attribution for a training step.
Systems insight: A prediction and a measurement together locate a bottleneck; either alone does not. The roofline says ResNet-50 could train 8.0× faster on this accelerator, and the measurement says something other than arithmetic is setting its pace.
The claim the chapter inherited, that ResNet-50 runs faster at INT8 than at FP32, needs a different measurement from this training one. An inference run under MLPerf Inference rules settles it directly. The ResNet-50 Offline scenario, run at INT8 and at the higher-precision baseline on the same accelerator with each required to hold the reference top-1 accuracy within the benchmark’s quality gate, reports both throughputs under one set of rules. The chapter’s own deployment measurement moves to MobileNetV2 on the camera-trap board, where the full path from claim to delivered speedup can be traced on one device.
Evaluating complete models requires standardized datasets, fixed reference tasks, and reproducible metric definitions. In computer vision, standard benchmarks evaluate models on ImageNet (Deng et al. 2024), measuring top-1 classification accuracy alongside inference latency across fixed batch sizes. In natural language processing, standardized tasks evaluate sequence-to-sequence translation and autoregressive generation, quantifying output quality against token generation rate across defined context lengths.
Deng, Jia, Wei Dong, Richard Socher, Li-Jia Li, Kai Li, and Li Fei-Fei. 2024. ImageNet.
Ignatov, Andrey, and Radu Timofte. 2024. AI Benchmark.
Several industry-standard suites establish reproducible model-level comparisons across platforms. The MLPerf suite standardizes evaluation across data centers, edge appliances, mobile devices, and microcontrollers, as detailed in section 12.6.3. For resource-constrained embedded targets, EEMBC’s MLMark quantifies inference throughput and energy consumption under strict memory budgets, while the AI-Benchmark (Ignatov and Timofte 2024) suite evaluates mobile systems-on-chip across heterogeneous compute units.
12.3.3 End-to-end benchmarks
End-to-end benchmarks encompass the entire production pipeline, capturing every stage required to ingest raw data, generate model predictions, and deliver results to downstream clients. While micro- and macro-benchmarks focus on accelerator execution, real-world serving pipelines frequently find their primary bottlenecks outside the model itself.
Data preprocessing forms the initial phase of the pipeline, converting raw external inputs into model-ready tensor representations. In computer vision pipelines, image ingestion requires decoding compressed file formats (such as JPEG decompression), resizing, cropping, and color normalization. When executed on host CPUs without hardware acceleration, these preprocessing steps can take several times longer than model inference on a modern accelerator, leaving high-throughput tensor cores idle while waiting for host memory transfers. Similarly, in natural language pipelines, subword tokenization and dynamic sequence padding on the host CPU often bound serving throughput. Postprocessing introduces analogous latency bottlenecks: object detection pipelines require non-maximum suppression (NMS) and bounding-box coordinate transformations, which create sequential execution stalls if not integrated efficiently into the execution graph.
Distributed infrastructure components introduce further performance constraints beyond the compute fabric. Remote storage systems bound training throughput when reading large multimodal datasets, and network interface card (NIC) saturation in distributed clusters throttles collective communication. End-to-end benchmarks must measure pipeline throughput under realistic network latencies, concurrent query arrival patterns, and actual storage I/O constraints to ensure reproducible evaluation of the deployment as an integrated system.
Public benchmark suites rarely measure storage, networking, and compute within a single unified protocol. While MLPerf Training and Inference evaluate end-to-end scenarios more closely than isolated operator tests, their closed divisions deliberately standardize input data loading to isolate accelerator performance from storage and network variability. Consequently, production end-to-end benchmarking remains primarily an internal engineering practice, evaluated through distributed tracing and production telemetry on live query distributions.
12.3.4 End-to-end vs. component latency
Measured at the request, the critical distinction is between component latency (time spent in model computation) and end-to-end latency (total time from request arrival to response delivery). Many benchmarks report only model inference time, obscuring the remaining overhead that determines actual user experience. The overhead is not marginal: serialization, network hops, and queue wait time can dominate total request time, making model-only optimizations yield diminishing returns.
Clipper’s designers measured exactly this effect. For lightweight models, CPU-side JSON deserialization and interprocess data copying took more wall-clock time than the accelerator’s model execution (Crankshaw et al. 2017). Reporting model latency alone would have hidden the largest component, a serialization cost that The serialization bottleneck develops for serving systems.
Crankshaw, Daniel, Xin Wang, Guilio Zhou, Michael J. Franklin, Joseph E. Gonzalez, and Ion Stoica. 2017. “Clipper: A Low-Latency Online Prediction Serving System.” 14th USENIX Symposium on Networked Systems Design and Implementation (NSDI 17), 613–27.
Table 6 gives an illustrative latency breakdown for an inference request. The model inference stage that vendors report as their “benchmark” number spans 5 to 100 ms, yet the queue wait time it sits behind ranges from 0 to over 1,000 ms. Under load, the single component a benchmark measures is dwarfed by one it never sees, so the reported number can be a small slice of what the user actually experiences.
| Component | Example Range | Notes |
|---|---|---|
| Network round-trip | 10–100 ms | Varies by region |
| Request parsing | 0.1–1 ms | JSON/protobuf |
| Input preprocessing | 1–50 ms | Tokenization, image resize |
| Queue wait time | 0–1000+ ms | Load-dependent |
| Model inference | 5–100 ms | The “benchmark” |
| Output postprocessing | 0.5–10 ms | Decoding, format |
| Response serialization | 0.1–1 ms | JSON/protobuf |
These component-level contributions explain why optimizing any single stage yields diminishing returns on end-to-end performance, an optimization ceiling formalized by Amdahl’s Law (principle 8). The bound itself appears as equation 11.1, where hardware acceleration states it for an accelerated path; the notebook below applies it to a measured pipeline.
Napkin Math 12.2: Amdahl's Law: Optimization ceiling
Problem: A vision pipeline spends 8 ms on preprocessing (JPEG decode, resize, normalize) and 10 ms on inference. If inference alone is optimized by 5×, how much does end-to-end latency actually improve?
Math: Assume fixed work, sequential stages, and unchanged preprocessing, with no queueing feedback. Optimizing inference from 10 ms to 2 ms reduces total latency from 18 ms to only 10 ms, a 1.8× improvement rather than 5×. Amdahl’s Law formalizes this ceiling: if inference, the part being accelerated, is fraction \(\ParallelFraction\) of total latency, then even infinitely fast inference yields at most \(1/(1-\ParallelFraction)\) speedup, because the preprocessing fraction \(1-\ParallelFraction\) remains. With preprocessing at 44.4 percent of total latency, the remaining fraction \(1-\ParallelFraction\) is 0.444, which yields a maximum achievable speedup \(1/(1-\ParallelFraction)\) of 2.25×, regardless of model optimization.
Systems insight: Aggressive model optimization yields disappointing end-to-end results whenever the nonmodel fraction dominates. Any component speedup quoted in isolation shrinks once the untouched stages are measured alongside it, and the shortfall grows as those stages take a larger share of the pipeline. Comprehensive benchmarks must either include preprocessing in measurements or state explicitly that reported speedups apply only to the inference component.
A latency report that supports a deployment decision therefore states which components it includes, the load it was measured under, and whether each figure is a component or an end-to-end number. Choosing that boundary is the trade-off between isolating a component bottleneck and measuring what the user experiences.
12.3.5 Granularity trade-offs and selection criteria
Table 7 contrasts the diagnostic focus, scope, and engineering trade-offs across the three benchmarking granularities. Micro-benchmarks isolate low-level operations to guide kernel optimization and hardware selection, macro-benchmarks evaluate complete models to guide architectural choices, and end-to-end benchmarks measure full pipelines to ensure production deployments satisfy real-world service requirements.
| Component | Micro Benchmarks | Macro Benchmarks | End-to-End Benchmarks |
|---|---|---|---|
| Focus | Individual operations | Complete models | Full system pipeline |
| Scope | Tensor ops, layers, activations | Model architecture, training, inference | Extract, transform, load; model; infrastructure |
| Example | Conv layer performance on cuDNN | ResNet-50 on ImageNet | Production recommendation system |
| Advantages | Precise bottleneck identification, Component optimization | Model architecture comparison, Standardized evaluation | Realistic performance assessment, System-wide insights |
| Challenges | May miss interaction effects | Limited infrastructure insights | Complex to standardize, Often proprietary |
| Typical Use | Hardware selection, Operation optimization | Model selection, Research comparison | Production system evaluation |
Selecting a single granularity level is rarely sufficient because benchmarking presents an inherent trade-off between diagnostic isolation and production fidelity. Along the descending diagonal in figure 3, evaluation regimes trade diagnostic power for operational realism: micro-benchmarks (the red point at the top left) isolate kernel-level memory bandwidth and warp occupancy at the expense of end-to-end context, macro-benchmarks (the blue center point) capture composed model topologies, and end-to-end benchmarks (the green point at the bottom right) encompass live production traffic but obscure the root causes of latency spikes. Effective evaluation requires strategically combining all three tiers to verify that kernel speedups survive full-system deployment.
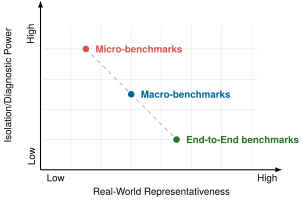
This trade-off maps directly onto the D·A·M taxonomy. Micro-benchmarks assess the physical capability of the Machine (\(\text{M}\)) executing a primitive Algorithm (\(\text{A}\)). Macro-benchmarks evaluate how the Algorithm (\(\text{A}\)) orchestrates tensor data flow across composed layers on the Machine (\(\text{M}\)). End-to-end benchmarks evaluate how raw Data (\(\text{D}\)) ingestion from external storage and network infrastructure interacts with both Algorithm and Machine under production load. Systematic performance engineering requires evaluating all three tiers to ensure local kernel optimizations translate into global system speedups.
Carpentry and granularity let one team build a trustworthy measurement. Comparing that measurement with another team’s, or with a vendor’s, requires that both were built the same way, and that agreement is what standardized benchmark suites provide.
Self-Check: Question
An e-commerce search service reports that production query latency has increased by \(40\%\), violating its SLA. Which benchmarking workflow represents the most effective top-down diagnostic strategy?
- Immediately rewrite all GEMM kernels in CUDA assembly without measuring the higher layers
- Run isolated microbenchmarks on the GPU memory bus to determine peak DRAM bandwidth
- Start with an end-to-end pipeline benchmark to isolate latency contributions across database lookup, tokenization, model inference, and reranking; next run macrobenchmarks on the slowest stage; then use microbenchmarks and kernel profilers to optimize the specific bottleneck operator
- Benchmark only the isolated tokenization library on CPU and assume the rest of the pipeline is unaffected
Consider the following three benchmarking tasks:
- Timing a single \(4096 \times 4096\) FP16 matrix multiplication in cuBLAS.
- Measuring the forward-pass execution time of a complete ResNet-50 model on a single GPU.
- Measuring total latency for an image upload, server decompression, feature extraction, neural network classification, and database metadata write. How are tasks (I), (II), and (III) classified by benchmarking granularity?
- End-to-end, (II) Micro, (III) Macro
- Macro, (II) Micro, (III) End-to-end
- Micro, (II) End-to-end, (III) Macro
- Microbenchmark, (II) Macrobenchmark (model-level), (III) End-to-end system benchmark
Compare microbenchmarks, macrobenchmarks, and end-to-end benchmarks along the axes of diagnostic isolation and real-world representativeness.
True or False: If an optimized FlashAttention kernel achieves a \(4\times\) microbenchmark speedup over a standard attention implementation, the complete language model inference service hosting that model is mathematically guaranteed to run \(4\times\) faster end-to-end.
In roofline analysis, an accelerator has a peak compute performance of \(989\text{ TFLOP/s}\) (dense FP16) and a memory bandwidth of \(3.35\text{ TB/s}\), yielding a machine ridge point of \(\RooflineRidgePoint \approx 295\text{ FLOP/byte}\). When serving a Transformer model with batch size \(b=1\), the arithmetic intensity is only \(I = 4.8\text{ FLOP/byte}\). What is the roofline upper bound on achieved throughput as a fraction of peak compute throughput for this workload?
- Approximately \(1.6\%\) of peak compute throughput (memory-bandwidth bound)
- Exactly \(100\%\) because modern tensor cores execute batch \(b=1\) at peak speed
- Approximately \(50\%\) due to pipeline bubbles and kernel launches
- Approximately \(85\%\) because matrix-vector multiplications are compute-bound
An image classification inference pipeline takes \(18\text{ ms}\) per request in a serial CPU baseline: \(8\text{ ms}\) in image decoding/preprocessing and \(10\text{ ms}\) in neural network execution. If only the model execution is migrated to a specialized NPU that accelerates the neural network by \(5\times\) (reducing inference time from \(10\text{ ms}\) to \(2\text{ ms}\)), with the other \(8\text{ ms}\) unchanged and no added transfer or queueing effects, what is the resulting end-to-end pipeline latency and speedup?
- \(2.0\text{ ms}\) latency and \(9.0\times\) speedup
- \(3.6\text{ ms}\) latency and \(5.0\times\) speedup
- \(10.0\text{ ms}\) latency and \(1.8\times\) speedup
- \(16.0\text{ ms}\) latency and \(1.1\times\) speedup
12.4 Benchmark Suites
A team evaluating edge deployment hardware must compare five candidate system-on-chip (SoC) designs for the camera trap’s next board. Vendor A reports 8 TOPS at INT8; Vendor B reports 15 TOPS at INT4; Vendor C reports inference latency on a proprietary model; Vendor D cites MLPerf scores from two generations ago; Vendor E provides only peak throughput at maximum batch size. None of these figures can be directly compared. The team cannot make an informed procurement decision because each vendor isolates a favorable metric under idiosyncratic conditions, obscuring true operating trade-offs. Benchmarking suites resolve this fragmentation by enforcing uniform measurement harnesses and standardized evaluation rules.
Each generation of benchmark suites arose to close a gap of exactly this kind, when the metrics of the day stopped predicting what users experienced. Their history explains the rules modern suites enforce.
12.4.1 From Whetstone to MLPerf
Three shifts mark that history: from isolated kernels to representative application suites, from single-metric throughput to multi-objective energy profiles, and from generic compute metrics to domain-specific execution constraints. The earliest computing benchmarks were open to benchmark gaming. Whetstone (Curnow and Wichmann 1976) used a synthetic mix of scientific operations, while LINPACK (Dongarra et al. 1979) measured dense linear-system solving. Because both relied on predictable computational loops, compiler and hardware vendors could optimize for the benchmark kernels (unrolling synthetic loops, or tailoring cache tiling to exact matrix dimensions) without improving general application performance. SPEC CPU (1989) addressed this by evaluating complete, portable software suites that stressed integer branching, irregular memory hierarchies, and floating-point pipelines (Dixit 1993). The same vulnerability applies to ML, since model-specific kernel tuning can overfit a single workload. Model compression claims therefore require validation on representative tasks such as ResNet-50 and BERT across the full software runtime.
Curnow, H. J., and B. A. Wichmann. 1976. “A Synthetic Benchmark.” The Computer Journal 19 (1): 43–49. https://doi.org/10.1093/comjnl/19.1.43.
Dongarra, J. J., J. R. Bunch, C. B. Moler, and G. W. Stewart. 1979. LINPACK Users’ Guide. SIAM. https://doi.org/10.1137/1.9781611971811.
Dixit, Kaivalya M. 1993. “Overview of the SPEC Benchmarks.” In The Benchmark Handbook for Database and Transaction Systems, 2nd ed., edited by Jim Gray. Morgan Kaufmann.
Coleman, Cody, Deepak Narayanan, Daniel Kang, Tian Zhao, Jian Zhang, Luigi Nardi, Peter Bailis, Kunle Olukotun, Christopher Ré, and Matei Zaharia. 2019. “Analysis of DAWNBench, a Time-to-Accuracy Machine Learning Performance Benchmark.” ACM SIGOPS Operating Systems Review 53 (1): 14–25. https://doi.org/10.1145/3352020.3352024.
13 MLPerf: Launched in 2018 by a consortium of industry and academic institutions, MLPerf takes its name from “ML” combined with “Perf” (performance), echoing SPEC’s benchmarking tradition. MLPerf’s design principles (representative workloads, full-system measurement, and open submission) directly address the gaming that plagued Whetstone and LINPACK. Vendors who could previously report peak kernel throughput on cherry-picked problem sizes must now report end-to-end system performance on standardized tasks (Mattson et al. 2020; Reddi et al. 2019).
Mattson, Peter, Christine Cheng, Cody Coleman, Greg Diamos, Paulius Micikevicius, David Patterson, Hanlin Tang, et al. 2020. “MLPerf Training Benchmark.” Proceedings of Machine Learning and Systems (MLSys) 2: 336–49.
Distributed computing added a further lesson, that component-level microbenchmarks fail to predict cluster-level throughput when interconnect latency, serialization, and collective communication dominate wall-clock time, as they do in distributed ML training. To capture these interactions, DAWNBench (Coleman et al. 2019) pioneered time-to-accuracy evaluation, tying hardware throughput to algorithmic convergence. Maximizing samples per second has no engineering value if numerical instability or poor batch sizing prevents the model from reaching its target validation accuracy. MLPerf13 (2018) combined these lessons and institutionalized full-system measurement, multi-objective constraints, and representative workloads spanning vision, language, and recommendation (Mattson et al. 2020; Reddi et al. 2019).
Energy followed the same path. SPEC Power (2007) (Lange 2009) and Green500 (2007) (Feng and Cameron 2007) made performance per watt a ranking metric for servers and supercomputers, and MLPerf Power (MLCommons 2024b) carried it to ML workloads, whose rapid power swings and shared host components demand calibrated instruments and explicit measurement boundaries (section 12.7.4).
Feng, Wu-chun, and Kirk W. Cameron. 2007. “The Green500 List: Encouraging Sustainable Supercomputing.” Computer 40 (12): 50–55. https://doi.org/10.1109/MC.2007.445.
MLCommons. 2024b. MLPerf Power Measurement.
Howard, Andrew G., Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, and Hartwig Adam. 2017. “MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications.” CoRR abs/1704.04861.
Energy benchmarking also exposes algorithmic efficiency. Compression and efficient architectures such as MobileNet (Howard et al. 2017; Sandler et al. 2018) save energy by reducing operations and off-chip traffic. Traffic reduction is a primary lever, because a DRAM read costs orders of magnitude more energy than an arithmetic operation (Where precision saves energy).
As specialized accelerators emerged, generic benchmarks failed to capture domain-specific execution constraints. Data center training clusters optimize aggregate throughput within rack-level power envelopes, mobile AI operates within thermal limits (typically under 5 watts), and embedded microcontrollers function within milliwatt budgets, which decides whether a benchmark prioritizes samples per second or joules per inference. Application requirements add functional constraints such as calibration for clinical models, hard tail-latency cutoffs for trading systems, and bounded worst-case latency for autonomous vehicles.
Because ML workloads couple tensor execution units, memory bandwidth, and communication fabrics, no single metric or workload can characterize a system. MLPerf therefore splits into distinct deployment suites: MLPerf Training evaluates multi-node scaling and high-bandwidth interconnects under time-to-quality targets (Mattson et al. 2020); MLPerf Inference measures throughput and latency percentiles under SLAs across server and client systems (Reddi et al. 2019); MLPerf Tiny tests ultra-low-power microcontrollers operating with tight memory constraints (Banbury et al. 2021); and the cross-cutting MLPerf Power track measures useful work per watt across each environment. Reading the constraint column of table 8 from top to bottom, cluster-scale interconnect bandwidth gives way to latency percentiles at the edge, and finally to strict memory footprints on microcontrollers.
| MLPerf Variant | Target Domain | Key Constraints | Primary Metrics |
|---|---|---|---|
| MLPerf Training | Data center | Multi-node scaling, high bandwidth interconnects | Time-to-quality, throughput (samples/sec) |
| MLPerf Inference | Server/Edge | Latency SLAs, throughput requirements | QPS, latency percentiles, accuracy preservation |
| MLPerf Tiny | MCU/IoT | Ultra-low-power inference, limited memory | Latency, accuracy, energy per inference |
| MLPerf Power | Cross-cutting | Energy budgets, thermal constraints | Performance/W, energy per query |
Table 9 summarizes the progression from early synthetic loops to multi-dimensional ML systems evaluation; each row’s lesson survives as a rule that modern suites enforce. Those rules become even more demanding in machine learning, where training and inference add variability that deterministic software benchmarks never faced.
| Benchmark | Year | Primary Focus | Key Metric(s) | Lesson for ML Benchmarking |
|---|---|---|---|---|
| Whetstone | 1976 | Synthetic floating-point operations | MWIPS | Gaming synthetic tests undermines evaluation validity |
| LINPACK | 1979 | Linear algebra (matrix operations) | FLOP/s | Isolated operations miss system-level complexity and bottlenecks |
| SPEC CPU | 1989 | Real application workloads | SPECrate, SPECspeed | Representative workloads reveal true deployment performance |
| SPEC Power | 2007 | Server energy efficiency | ssj_ops/W across load levels | Energy efficiency requires multi-load evaluation, not just peak performance |
| Green500 | 2007 | HPC energy efficiency | GFLOP/s per watt | Efficiency rankings complement raw performance rankings |
| MLPerf | 2018 | ML systems (training + inference) | Time-to-quality, QPS, latency, accuracy | Synthesizes all lessons: representative workloads + multi-objective + system |
12.4.2 ML measurement challenges
Three lessons from benchmark history (representative workloads, multi-objective evaluation, and integrated system measurement) converge on a requirement unique to machine learning: managing statistical approximation. Traditional computing benchmarks specify correctness checks, which may require exact outputs or permit stated numerical tolerances. In ML systems, low-level engineering choices routinely alter numerical output: aggressive weight quantization, kernel pruning, or reduced-precision accumulators trade accuracy for execution speed and lower memory bandwidth pressure. Consequently, an ML benchmark cannot evaluate execution time in isolation; output accuracy serves as an inviolable operational constraint.
Evaluating an ML system therefore means testing the coupled Data, Algorithm, and Machine (D·A·M) choices together rather than measuring raw compute throughput. A suite earns trust by solving three problems. It must produce valid measurements despite run-to-run noise, finite test sets, unrepresentative workloads, and misaligned metrics. It must then isolate what the hardware-software stack contributes, which is the job of a system benchmark and its roofline diagnostic. Finally, it must make results comparable across organizations, which is the job of community standardization.
ML systems combine several sources of measurement variability that classical software benchmarks were not designed to evaluate together. These fluctuations originate at both the machine and algorithmic layers. On the machine side, sustained execution pushes accelerators against thermal and power envelopes, triggering dynamic voltage and frequency scaling (DVFS) that throttles processor clocks mid-run. Host operating-system activity (thread scheduling jitter, memory paging, and PCIe bus contention during batch staging) further introduces latency variance across runs. On the algorithmic side, floating-point addition is non-associative, so reduction orders that change across parallel execution threads shift results slightly, while mini-batch shuffling, pseudo-random augmentations, stochastic dropout masks, and weight initialization perturb the trajectory that stochastic gradient descent takes across a non-convex loss surface.
Distinguishing a genuine systems optimization from background measurement noise requires isolating these overlapping sources of variance with repeated runs, paired comparisons, and confidence intervals. Those statistical controls apply to every benchmark in the chapter, so section 12.8.1 collects them in one place, including how large a test set must be before it can resolve a one-point accuracy difference.
Beyond run-to-run variance, benchmark validity depends on workload representativeness. Synthetic microbenchmarks generate uniform, statically sized tensors directly in accelerator HBM. By executing continuous, compute-bound GEMM operations in an isolated loop, microbenchmarks measure theoretical peak arithmetic throughput. However, they conceal the memory hierarchies and scheduling bottlenecks that dominate production deployments. Synthetic workloads bypass host-to-device PCIe data transfers, input decoding pipelines, dynamic memory allocation churn, and GPU cache evictions. In contrast, trace-based benchmarking replays timestamped request logs recorded from live serving clusters. Production traces capture Poisson and bursty request arrival distributions, variable sequence lengths, and concurrent query streams. Replaying live traces forces the serving infrastructure to manage dynamic batching (grouping requests that arrive within a short time window into one batch), key-value (KV) cache allocation under memory pressure, and queuing delays, stress-testing the system under operational conditions that synthetic steady-state loops obscure.
↩︎ The key-value (KV) cache, the per-request attention state that grows with every generated token, is established in System implications.
A representative workload can still mislead if the evaluation metric fails to reflect deployment constraints. When an engineering team optimizes a single algorithmic figure of merit (such as an offline BLEU score, top-1 classification accuracy, or token perplexity) in isolation from system SLOs, the metric ceases to measure genuine operational fitness. This divergence is the chapter’s second principle, Goodhart’s Law, operating inside a single team’s choice of metric, and once the proxy becomes the sole optimization target it stops reporting overall system health. In neural machine translation, an offline accuracy optimization can break the serving deadline outright.
Example 12.1: Goodhart's Law in action
Scenario: An engineering team optimizes a neural machine translation model for offline BLEU score, increasing the beam search size (the number of candidate partial translations kept at each decoding step) from 1 to 10.
Diagnosis: The larger beam search achieves a 0.5-point BLEU gain on paper but increases candidate evaluations by 10×, increasing inference latency from 50 ms to 200 ms (4× slowdown), exceeding the serving deadline.
Systems lesson: Optimizing offline accuracy without latency constraints invites Goodhart’s Law failures. Production benchmarks must enforce strict SLOs for serving latency (e.g., latency < 100 ms).
The translation example shows an algorithmic change (a tenfold wider beam) multiplying computational load and memory traffic for a marginal quality gain while violating a hardware latency deadline. Fixed benchmarks also assess execution under an unvarying input distribution, which conceals how systems degrade under production distribution shifts. Model and data evaluation must test those distribution limits. System comparisons address a separate question by isolating infrastructure execution efficiency from model architecture and dataset variation. Standardized suites like MLPerf establish reference workloads, datasets, quality targets, and permitted implementation changes, enabling reproducible comparisons of hardware-software execution efficiency within a specified benchmark version and division.
12.4.3 System benchmarks
Hardware specifications advertise peak arithmetic rates that application workloads do not sustain—the gap between an H100’s dense FP16 peak and the model arithmetic ResNet-50 training actually achieves (section 12.1). System benchmarks expose that gap by running standardized ML workloads across hardware architectures, memory systems, and interconnects rather than relying on spec-sheet peaks alone.
The underlying hardware, whether CPUs, GPUs, Tensor Processing Units (TPUs),14 and application-specific integrated circuits (ASICs),15 determines ML-system speed, efficiency, and scale. System benchmarks provide standardized methods for comparing hardware across AI workloads by computational throughput, memory bandwidth, power efficiency, operator coverage, and scaling (Reddi et al. 2019; Mattson et al. 2020).
14 TPU (tensor processing unit): Google’s custom ASIC for neural network workloads. A TPU v4 pod (4,096 chips) delivers 1.1 exaFLOP/s peak BF16 (Jouppi et al. 2023), but benchmarking TPUs requires caution: their systolic-array architecture favors regular tensor operations, so peak FLOP/s overstate performance on irregular workloads like sparse attention or dynamic control flow.
Jouppi, Norm, George Kurian, Sheng Li, Peter Ma, Rahul Nagarajan, Lifeng Nai, Nishant Patil, et al. 2023. “TPU v4: An Optically Reconfigurable Supercomputer for Machine Learning with Hardware Support for Embeddings.” Proceedings of the 50th Annual International Symposium on Computer Architecture, 1–14. https://doi.org/10.1145/3579371.3589350.
15 ASIC (application-specific integrated circuit): An ASIC’s peak TOPS number applies only to the specific operators it was designed for. An unsupported layer may require a host fallback or a different implementation, adding transfer and coordination costs. This makes operator coverage an early question in any ASIC benchmark: workload compatibility can explain part of the gap between peak and achieved throughput.
System benchmarks serve two functions. For practitioners, they enable informed hardware selection by providing comparative data across configurations. For manufacturers, they quantify generational improvements and guide accelerator development. Both functions require separating what the hardware contributed from what the model and data contributed.
Definition 12.2: Machine learning system benchmarks
Machine learning system benchmarks are standardized evaluation protocols that hold the workload and quality target constant while varying the hardware-software stack, measuring \(\EfficiencyHw = \SustainedComputeRate/ \PeakRate\) (the measured sustained rate \(\SustainedComputeRate\) over the peak rate) and \(\Latency\) to isolate infrastructure efficiency from algorithmic improvements.
- Significance: The same ResNet-50 model can report the same ImageNet Top-1 accuracy while delivering very different throughput across hardware stacks, precision formats, batch sizes, and compiler configurations. Only a system benchmark exposes that gap.
- Distinction: Unlike algorithmic benchmarks (which vary the Data and Algorithm factors, \(\text{Samples/Task}\) and \(\text{FLOPs/Sample}\), to improve convergence or accuracy), system benchmarks hold the algorithm and quality target fixed and vary the implementation (kernel libraries, quantization formats, batch sizes, and hardware generations) to measure how efficiently the hardware-software stack executes the workload, lowering the iron law’s realized Machine factor (\(\text{Seconds/FLOP}\)) across compute (\(\Operations/(\PeakRate \cdot \EfficiencyHw)\)), data movement (\(\DataVolume/\Bandwidth\)), and fixed latency (\(\Latency\)).
- Common pitfall: A frequent misconception is that a system benchmark result generalizes across workloads. An accelerator that achieves high utilization on ResNet-50 (a compute-friendly vision workload) may achieve much lower utilization on a recommendation system, whose embedding lookups are bound by memory capacity and bandwidth rather than arithmetic. System benchmarks are workload-specific; no single metric characterizes a hardware platform.
System benchmarks evaluate performance across scales, ranging from single-chip configurations to large distributed systems and covering both training and inference. The ImageNet challenge shows why separating the hardware’s contribution from the model’s is hard to do after the fact. Between 2010 and 2014, top-5 error (the blue line in figure 4) fell from 28.2 percent to 7.3 percent while GPU-accelerated entries (the green bars) rose from zero to over 100, with the steepest single drop at AlexNet’s arrival in 2012 (Krizhevsky et al. 2012; Russakovsky et al. 2015; Gray 2015). These paired series plot contemporaneous empirical trends, not a causal attribution of how much accuracy gain stemmed from hardware throughput versus algorithmic design, training schedules, or dataset expansion. A system benchmark avoids that ambiguity by construction: it fixes the model and quality target so that any change in the result belongs to the hardware-software stack.
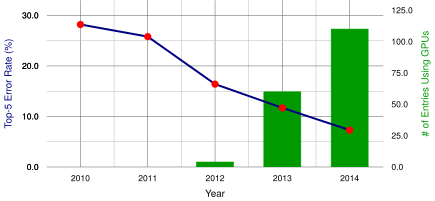
Krizhevsky, Alex, Ilya Sutskever, and Geoffrey E. Hinton. 2012. “ImageNet Classification with Deep Convolutional Neural Networks.” Advances in Neural Information Processing Systems (NeurIPS) 25.
Gray, Allison. 2015. NVIDIA and IBM Cloud Support ImageNet Large Scale Visual Recognition Challenge. NVIDIA Technical Blog.
While section 12.9.1 evaluates model compression against task accuracy baselines, system benchmarking isolates the execution efficiency of the hardware-software stack under a fixed model. Modern accelerators rarely sustain theoretical peak throughput because physical execution depends on the coupling between tensor shapes and memory hierarchies; ResNet-50 training, which the roofline places on the compute roof, sustains about 12.4 percent of an H100’s peak (notebook 12.1). Parameter-heavy transformer decodes and activation-heavy convolutional passes stress entirely different levels of the memory subsystem, causing achievable throughput to diverge across precision formats.
Measuring sustained utilization rather than peak capability establishes two critical scope boundaries. First, energy consumption scales with execution efficiency, because performance per watt varies widely across hardware platforms, and an underutilized accelerator draws substantial static power for minimal computational output. Second, multi-accelerator execution introduces communication boundaries. While multi-node cluster scaling involves network-topology effects beyond this book’s single-node scope, intra-node benchmarking must account for interconnect bandwidth, memory sharing across accelerators, and gradient synchronization over NVLink or PCIe.
12.4.4 Community-driven standardization
Without shared measurement boundaries, utilization numbers cannot be compared. If one benchmark includes host-side preprocessing and PCIe transfers while another measures only device kernel execution, or if one power meter reads only the accelerator voltage rail while another includes host processors and chassis fans, the resulting figures reflect incompatible boundaries rather than architectural efficiency. No single vendor can resolve this discrepancy, because each has a commercial incentive to draw the boundary around its own hardware strengths. Formal standards bodies move too slowly for hardware and model structures that change every year, so consortia such as MLCommons maintain living benchmark suites. These pair open-source reference implementations with compliance rules so that numbers from different laboratories describe comparable workloads under the same version, division, quality target, and scenario.
Standardizing system benchmarks requires formalizing the D·A·M taxonomy so that evaluations isolate the Machine without confounding changes to the Algorithm or Data. The MLPerf Training benchmark enforces this separation by measuring time-to-train to a specified quality target rather than raw floating-point throughput or epoch duration (Mattson et al. 2020). High TFLOP/s from aggressive low-precision scaling helps only if faster steps outweigh any extra work needed to reach the target, and a run that misses the target is invalid. MLPerf splits submissions into two divisions. In the closed division, every submitter must run the reference model and reach the same quality target, so differences in time-to-train belong to the system; the open division permits model and algorithm changes, so its results compare whole solutions rather than machines. Within the closed division, the rules constrain the workload while permitting specified tunable hyperparameters and approved numerical formats. Quality and compliance checks establish which hardware, compiler, and training-configuration improvements constitute valid submissions.
The MLPerf Inference benchmark applies this discipline to production deployment constraints (Reddi et al. 2019). An accelerator cannot simply report peak throughput under infinite batching if interactive serving requires guaranteed responsiveness. The benchmark therefore fixes how queries arrive, through execution scenarios matched to physical operating regimes: one query at a time for a single interactive user, randomly arriving queries under a tail-latency bound for a shared service, and all inputs supplied upfront for bulk throughput. By standardizing these execution boundaries, community benchmarks account for queueing delays and host-to-device PCIe transfers, making the tested load and timing boundary explicit when interpreting a throughput claim.
MLPerf execution scenarios
The same hardware can report dramatically different benchmark numbers depending on how requests arrive, which explains why vendor claims often fail to predict production performance. Classic MLPerf Inference defines four execution scenarios that characterize distinct traffic patterns, each requiring different optimization strategies (Reddi et al. 2019). Current client and generative-AI benchmark variants also include interactive measurements for latency-sensitive large language model (LLM) workloads, where time to first token and time per output token, the two measured quantities defined in section 12.6.2.2, become central (MLCommons 2026b).
SingleStream
SingleStream processes one request at a time, measuring latency for sequential inference. This scenario models mobile and embedded applications where a single user interacts with the device: a smartphone camera app classifying images, a voice assistant processing speech, or a wearable detecting gestures. The key metric is a tail percentile of per-query latency (the 90th percentile in MLPerf’s rules), and inter-request batching is unavailable because the next query arrives after the previous one completes. Optimization focuses on preprocessing efficiency and power consumption rather than throughput.
MultiStream
MultiStream processes multiple synchronized input streams simultaneously, modeling scenarios like autonomous vehicles with multiple cameras that must be processed together for spatial fusion. The application motivation is synchronized processing, but the benchmark rule is version-specific: current MultiStream rules issue a group of samples per query, wait for its completion before the next query, and report a specified latency percentile. Earlier versions used fixed arrival intervals. Grouped-query latency helps assess multi-input execution; it does not establish a hard-deadline guarantee for a vehicle planning loop.
Server
Server generates requests following a Poisson distribution, simulating cloud API traffic where requests arrive independently and unpredictably. This scenario models web services handling millions of queries from different users. Unlike SingleStream’s guaranteed sequential arrival, Server traffic creates queuing dynamics where multiple requests compete for resources. The key metrics are throughput (queries per second) and the workload’s tail-latency bound, typically set at the 99th percentile, and dynamic batching can improve efficiency by grouping requests that arrive within a time window. Optimization balances throughput against latency SLOs.
Offline
Offline provides all inputs upfront, measuring maximum throughput when latency constraints are removed. This scenario models batch processing pipelines: overnight data processing, scientific computing, or precomputing recommendations. With no per-query latency requirement, systems can tune batch size for sustained throughput within memory and execution limits. The key metric is pure throughput (samples per second), and optimization focuses entirely on hardware efficiency. Table 10 maps the classic execution scenarios, plus the newer Interactive LLM-oriented case, to their deployment contexts and optimization strategies.
| Scenario | Context | Strategy | Focus |
|---|---|---|---|
| SingleStream | Mobile apps, embedded devices | No batching (batch = 1) | Preprocessing, power efficiency |
| MultiStream | Autonomous driving, video analytics | Synchronized sensor fusion | Grouped-query latency percentile |
| Server | Cloud APIs, web services | Dynamic batching with timeout | Throughput-latency trade-off tuning |
| Offline | Batch processing, data pipelines | Maximum batch size | Throughput, hardware utilization |
| Interactive | Chat, agents, local generative AI | Token streaming, KV-cache management | Time-to-first-token, time-per-output-token |
Community standards fix the workload, the divisions, and the arrival pattern. The training and inference sections apply those rules to the chapter’s two lighthouse workloads, beginning with the one that consumes the most arithmetic per result: training ResNet-50 to its quality target.
Self-Check: Question
Why did computing benchmark methodology historically transition away from synthetic instruction-mix microbenchmarks (such as Whetstone and Dhrystone) to representative application suites (such as SPEC CPU)?
- Synthetic microbenchmarks required too much memory bandwidth to execute on modern microprocessors
- Representative application suites were easier to implement and did not require source code compilation
- Synthetic benchmarks lacked realistic memory access patterns and branch behavior, allowing optimizing compilers to artificially game scores via dead-code elimination and loop unrolling
- Hardware vendors refused to publish floating-point operations per second for synthetic loops
How do the constraints and primary evaluation metrics differ across the domain-specific variants of the MLPerf benchmark suite?
- All MLPerf variants evaluate identical metrics (pure TFLOPS) across different hardware form factors
- MLPerf Training focuses on latency SLAs, while MLPerf Inference evaluates multi-node interconnect bandwidth
- MLPerf Tiny measures data center power consumption, while MLPerf Power evaluates floating-point peak throughput
- MLPerf Training targets time-to-quality on fixed workloads, MLPerf Inference evaluates scenario-defined latency and throughput across server and edge settings, MLPerf Tiny targets embedded memory, latency, and energy constraints on microcontrollers, and MLPerf Power measures useful throughput per watt or useful work per joule within a stated measurement boundary
True or False: The introduction of energy-efficiency benchmarks like SPECpower and Green500 replaced raw throughput benchmarks, because computing systems are now evaluated solely on Joules per operation.
Explain why a single benchmark run is insufficient to characterize ML system performance, identifying at least two distinct hardware or runtime sources of execution variance.
Compare the primary objectives and constraints of the MLPerf Closed Division versus the Open Division.
Explain how community-driven benchmarking consortia discourage vendor gaming, help detect it, and establish commensurable evidence for hardware procurement.
12.5 Training Benchmarks
Training and inference fail in opposite ways on the same accelerator. A training run stalls when synchronizing gradients across accelerators saturates the interconnect; a serving deployment violates its SLO when request bursts build a queue. The two regimes also measure different resources. Training iteratively refines parameters over billions of samples and must hold parameters, gradients, optimizer state, and the activations retained for the backward pass, a footprint that can far exceed the weights alone (table 1 gives ResNet-50’s); its figure of merit is wall-clock time to a target accuracy. Inference evaluates fixed parameters against arriving queries, discards the backward graph and optimizer state, and is judged by latency percentiles and throughput under bursty load. A training result and an inference result on the same accelerator therefore measure different resources and cannot stand in for each other, which is why MLPerf maintains separate Training and Inference suites (Mattson et al. 2020; Reddi et al. 2019). This chapter measures training on ResNet-50 and serving on MobileNetV2 (section 12.6).
↩︎ The training memory budget of weights, gradients, optimizer state, and retained activations is established in Reducing optimizer memory.
In an illustrative procurement failure, a team purchases a larger GPU cluster expecting proportional training-speed gains, only to discover that communication overhead and memory bottlenecks limit the actual speedup. Training benchmarks exist to catch this kind of gap before procurement. Training benchmarks span six dimensions (table 12), anchored by three: convergence metrics that measure learning progress, throughput metrics that measure computational efficiency, and scalability metrics that measure distributed performance.
Definition 12.3: ML training benchmarks
ML training benchmarks are machine learning system benchmarks that measure the time to reach a target quality metric (for example, a specified validation accuracy or loss threshold) on a fixed dataset and model, quantifying the rate of convergence per unit of resource.
- Significance: Training benchmarks reveal large gaps invisible to hardware specs. Holding the model and quality target fixed, the time to convergence can vary widely across hardware-software stacks because training performance depends on the full pipeline: data loading \((\DataVolume/\Bandwidth)\), compute utilization \((\EfficiencyHw)\), gradient synchronization \((\Bandwidth, \Latency)\), and fault recovery overhead. A peak FLOP/s spec sheet captures none of these interactions.
- Distinction: Unlike inference benchmarks, which measure per-query latency and throughput under load, training benchmarks measure time-to-accuracy across the full optimization loop: data loading, forward pass, backward pass, gradient synchronization, and optimizer step. As scale increases, communication \((\Bandwidth)\) can displace compute \((\PeakRate)\) as the binding constraint; profiling establishes the transition for a particular workload.
- Common pitfall: A frequent misconception is that training benchmarks measure “how fast the GPU runs.” At large scale, interconnect bandwidth \((\Bandwidth)\) for gradient synchronization and fault tolerance overhead (checkpoint I/O, straggler mitigation) often dominate the benchmark result more than peak FLOP/s.
Training benchmarks validate whether hardware acceleration delivers promised training throughput. Accelerators and multi-chip systems all claim dramatic speedups, and training benchmarks reveal which claims hold under realistic workloads. They evaluate how hardware configurations, data loading mechanisms, and distributed training strategies perform when training production-scale models. These benchmarks are vital because training represents the largest capital expenditure in ML systems, and only rigorous time-to-accuracy measurement reveals whether that capital delivers proportional value rather than dissipating into scaling inefficiencies, memory bottlenecks, or communication overhead. The metrics themselves (time-to-accuracy, scaling efficiency, utilization, checkpoint overhead) are defined and worked at the scale of one machine with one to eight accelerators, the scale of the scaling-efficiency notebook below.
12.5.1 Training benchmark motivation
MLPerf Training (Mattson et al. 2020; MLCommons 2024c) provides the standardized framework for this time-to-quality measurement. The longitudinal scaling curves in figure 5 track cumulative relative performance gains across nine model workloads between 2018 and 2024 against the orange Moore’s Law baseline. Every workload curve outpaces cumulative transistor scaling (which reaches 6.6\(\times\) by mid-2024), led by Mask R-CNN climbing to 48.8\(\times\) and ResNet reaching 34\(\times\) as distributed scaling and compiler optimizations compound hardware improvements (Tschand et al. 2024). This trajectory documents improvements in the full hardware-software system beyond transistor scaling alone; the plotted results do not isolate the contribution of competitive pressure from other causes.
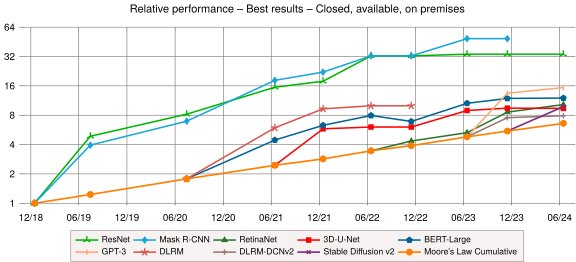
Training benchmarks also expose inefficiencies such as slow data loading, underutilized accelerators, excessive memory overhead, and communication bottlenecks that erode scaling efficiency. Advertised hardware capability (for example, accelerator TFLOP/s) becomes a training speedup only to the extent that a benchmark verifies it under realistic conditions.
Training benchmarks serve four interconnected functions. First, they enable hardware and software optimization by providing vendor-neutral comparisons across accelerator architectures and frameworks (TensorFlow, PyTorch) on standardized tasks, guiding hardware selection for data centers and cloud environments. Software optimizations including mixed-precision training16 and memory-efficient data loading are similarly quantified. Second, they evaluate scalability: adding GPUs should reduce training time proportionally, but communication overhead, synchronization latency, and memory bottlenecks limit scaling efficiency in practice. Training benchmarks quantify these losses, revealing whether infrastructure investments deliver proportional returns. Third, they provide cost and energy accountability: with a single large-scale training run consuming energy on the scale of the GPT-3 estimate in section 12.5.2.4, benchmarks that track cost per training run and power consumption per unit of progress help organizations balance computational power with sustainability goals. Finally, standardized evaluation criteria, controlled randomness, submission rules, and audits make comparisons more reproducible and constrain implementation-specific shortcuts.
16 Mixed-precision training: Uses lower precision for most arithmetic while preserving higher-precision accumulation where needed (Micikevicius et al. 2018). The benchmarking consequence: mixed-precision and full-precision runs are not directly comparable because reduced memory traffic and larger feasible batch sizes can change convergence dynamics. MLPerf addresses this by fixing the accuracy target, making time-to-accuracy the comparable quantity regardless of precision strategy.
Micikevicius, Paulius, Sharan Narang, Jonah Alben, Gregory Diamos, Erich Elsen, David Garcia, Boris Ginsburg, et al. 2018. “Mixed Precision Training.” International Conference on Learning Representations (ICLR).
12.5.2 Training metrics
From a systems perspective, training benchmarks assess the rate of convergence toward a verified quality threshold rather than the raw processing speed of an execution loop. Metrics such as sample throughput and scaling efficiency become meaningful only when the workload reaches target convergence; without that operational constraint, raw throughput rewards numerical instability and divergence. MLPerf Training formalizes this requirement by coupling wall-clock time directly to task-specific validation targets across each standardized workload.
Time and throughput
A training cluster that processes twice as many images per second by doubling the minibatch or dropping precision has not sped up training if the run requires twice as many epochs to converge—or never reaches the quality floor at all. That is why the primary metric for evaluating training efficiency is the time required to reach a predefined accuracy threshold. Training time \((\TrainingTime)\) measures how long a model takes to converge to an acceptable performance level, reflecting the overall computational efficiency of the system. Let \(\text{Accuracy}_{\text{val}}(\TimeInstant)\) be the model’s validation accuracy at training time \(\TimeInstant\), and let the target accuracy be the benchmark-specific threshold (for example, 75.9 percent top-1 accuracy for ResNet-50 on ImageNet in MLPerf). Equation 1 formally defines this metric, keeping the benchmark focused on how quickly a system achieves meaningful results: \[\TrainingTime= \inf \big\{\TimeInstant\geq 0 : \text{Accuracy}_{\text{val}}(\TimeInstant) \geq \text{target accuracy} \big\} \tag{1}\]
A run that never reaches the target has no finite time-to-accuracy, preventing raw training speed from rewarding a system that fails the benchmark’s quality criterion.
Throughput,17 often expressed as the number of training samples processed per second, provides an additional measure of system performance. Let \(\ProcessedSampleCount\) be the total number of training samples processed and \(\TrainingTime\) the training time from equation 1. Equation 2 makes the rate explicit by dividing processed samples by training time: \[\text{Throughput} = \frac{\ProcessedSampleCount}{\TrainingTime} \tag{2}\]
17 Throughput: Originating in manufacturing to measure units produced per unit time, the term entered computing in the 1960s batch-processing era. The manufacturing origin carries a systems lesson: throughput and latency are inherently opposed, because batching increases throughput (more units per hour) at the cost of individual item wait time. In ML serving, this manifests as the batch-size trade-off: larger batches improve GPU utilization but increase per-request latency.
MLCommons. 2024c. MLPerf Training Benchmark.
Throughput alone cannot certify system capability. A platform may sustain high sample rates using aggressive low-precision formats or enormous minibatches, yet fail to reach target accuracy because of gradient divergence or poor generalization. In MLPerf Training, for instance, a ResNet-50 benchmark on ImageNet is valid only if the model achieves the required 75.9 percent top-1 validation accuracy (Mattson et al. 2020; MLCommons 2024c). Evaluating throughput strictly as the rate of progress toward convergence ensures that reported gains reflect genuine learning productivity rather than wasted arithmetic cycles.
Scalability and parallelism
Scalability measures how effectively training performance improves as resources are added. Ideally, doubling GPU count should halve training time. In practice, communication overhead, memory bandwidth limits, and parallelization inefficiencies constrain scaling well below linear.
Napkin Math 12.3: Scaling efficiency calculation
Problem: A team trains an image classifier on a fixed dataset. Single-GPU training takes 24 hours. With 8 GPUs, training takes 4 hours. Is this good scaling? Where did the efficiency go?
Table 11: Scaling Efficiency Loss Sources: Illustrative decomposition of the missing efficiency budget into measurable overhead categories and the corresponding measurement signal used to attribute each loss. Actual percentages depend on model, interconnect, storage, batch schedule, and framework implementation.
Step 1: Define scaling efficiency. For strong scaling (fixed problem size, more processors), let \(\Time(1)\) be the training time on a single GPU, and \(\Time(\AcceleratorCount)\) the training time on \(\AcceleratorCount\) GPUs. Equation 3 defines efficiency: \[\text{Eff}_{\text{scaling}}(\AcceleratorCount) = \frac{\Time(1)}{\AcceleratorCount \times \Time(\AcceleratorCount)} \times 100\% \tag{3}\]
Step 2: Calculate efficiency. \(\text{Eff}_{\text{scaling}}(8) = \frac{24\,\text{hours}}{8 \times 4\,\text{hours}} \times 100\%\) = 24/32 = 75 percent
With perfect scaling, 8 GPUs would complete in 3 hours (24 hours/8 GPUs). The actual 4 hours represents 75 percent efficiency.
Step 3: Investigate the efficiency loss. The two elapsed times establish the “missing” 25 percent, but do not attribute it. Table 11 lists illustrative contributions and profiling signals for gradient synchronization, memory copy, load imbalance, and batch-size effects. Strong-scaling comparisons hold total work fixed; time-to-quality comparisons must also account for any change in steps to convergence.
In multi-accelerator data-parallel training (such as 2, 4, or 8 GPUs connected over PCIe or NVLink within a host), each accelerator computes gradients on its own local slice of the minibatch, and the AllReduce collective of Data parallelism must sum them so every worker receives the identical global gradient average before the next step. Gradient tensors have one entry per trained parameter, but their byte payload equals weight storage only when their representations match. Moving them across interconnects adds communication whose cost depends on topology, the collective algorithm, and overlap. With fixed total work and ideal partitioning, compute time per step shrinks (\(\IronLawComputeTime \propto 1/\AcceleratorCount\)), while communication may shrink more slowly or grow. Exposed synchronization then occupies a larger fraction of the step; traces determine how much of the observed scaling loss it explains.
| Source | Example Contribution | Measurement |
|---|---|---|
| Gradient synchronization | 10–15% | AllReduce time per step |
| Memory copy (CPU\(\leftrightarrow\)GPU) | 3–5% | Data transfer profiling |
| Load imbalance | 2–5% | Per-GPU step time variance |
| Batch size effects | 2–5% | Larger batches converge differently |
Step 4: The systems insight. Scaling efficiency can decrease as \(\AcceleratorCount\) grows when exposed communication and other overheads fail to shrink with per-GPU compute. In this worked example, eight GPUs reach 75 percent efficiency; at larger scales, the same arithmetic makes clear why sophisticated communication and input-pipeline optimization become necessary.
MLPerf reports raw performance, while scaling efficiency can be calculated across matched submissions: a system achieving 2\(\times\) throughput at 50 percent efficiency may be worse than 1.5\(\times\) throughput at 90 percent efficiency, depending on cost constraints.
↩︎ The AllReduce collective that averages gradients across data-parallel workers is established in Data parallelism.
Parallelism strategies (data, model, and pipeline parallelism) and the synchronization each requires are developed in Data parallelism; within one machine of two to eight accelerators, data parallelism is the common case. A benchmark’s job is narrower: to report how much of the added capacity a configuration converts into speedup without degrading convergence. That conversion is scaling efficiency. While strong scaling evaluates whether adding processors reduces training time on a fixed total workload, weak scaling scales the problem size proportionally with processor count to keep the per-device workload constant, measuring whether the system can train larger models or ingest larger datasets within a fixed time budget without communication bottlenecks dominating.
Resource utilization
Training efficiency depends on learning speed, cluster scalability, and how effectively the hardware resources are used. Compute utilization requires an explicit numerator. Model FLOPs utilization (MFU), the metric of definition 8.3, compares the useful model operation rate with the matching hardware peak; activity counters instead report whether units are busy. MFU contrasts with hardware FLOPs utilization (HFU), which counts all executed operations including activation recomputation; recomputation adds executed FLOPs without adding useful model FLOPs for the same step. Comparing them separates useful model work from work expended to relieve memory capacity limits. Low utilization may indicate bottlenecks in data movement, memory access, or inefficient workload scheduling.
For instance, when training ResNet-50, decoding and augmenting thousands of JPEG images per second on the host can limit throughput even when the accelerators have compute to spare, the crossing from compute-bound to input-bound that Data pipeline traces. If storage retrieval or preprocessing cannot keep up, the accelerators wait. Profiling resource utilization identifies the bottleneck, and optimizations such as prefetching, caching, and more parallel input processing can improve sustained performance.
Memory bandwidth is another limiting factor, as deep learning models require frequent access to large volumes of data during training. If memory bandwidth saturates, increasing compute power alone will not improve training speed. Benchmarks assess how well models use available memory, ensuring that data transfer rates between storage, main memory, and processing units do not become performance bottlenecks.
I/O performance also plays a direct role in training efficiency, particularly when working with large datasets that cannot fit entirely in memory. Benchmarks evaluate the efficiency of data loading pipelines, including preprocessing operations, caching mechanisms, and storage retrieval speeds. Systems that fail to optimize data loading can experience large slowdowns, regardless of computational power.
Energy efficiency and cost
Training GPT-3 was estimated to consume 1,287 MWh of electricity (Patterson et al. 2021). At that scale, energy efficiency metrics quantify the power usage of training workloads so teams can identify systems that reach target accuracy without wasted energy. Fewer iterations reduce energy only when their total energy cost is lower; a more expensive step can offset the reduced count, so suites such as MLPerf Training measure total energy over the complete run to the same quality target. The same power accounting governs inference, where precision is one potential energy lever; section 12.7 works through why INT8 quantization cuts per-inference energy by attacking both memory traffic and arithmetic cost.
Cost considerations extend beyond electricity usage to include hardware expenses, cloud computing costs, and infrastructure maintenance. Training benchmarks provide insights into the cost-effectiveness of different hardware and software configurations by measuring training time in relation to resource expenditure. Organizations can use these benchmarks to balance performance and budget constraints when selecting training infrastructure.
Fault tolerance and robustness
Training workloads often run for extended periods, sometimes spanning days or weeks, making fault tolerance an essential consideration. A resilient system must handle unexpected failures (hardware malfunctions, network disruptions, and memory errors) without compromising accuracy convergence.
Production systems checkpoint for fault tolerance, periodically saving progress so a failure does not restart the run. On a single host, a benchmark records the save interval, the state written, and the pause each save exposes to training. Model weights and optimizer states consume storage bandwidth, and any pause extends wall-clock time to the quality target. Asynchronous saving can overlap I/O with computation, but its staging buffers and competing storage traffic remain part of the measured workload. Cluster recovery and parallel file systems extend this problem beyond the local machine; the local benchmarking lesson is to include the intended saving behavior in sustained performance measurements. MLPerf Training primarily measures time-to-quality under standardized workloads and does not benchmark failure recovery directly.
Training runs are also where reproducibility is hardest, because stochastic processes interact with hardware-specific behavior over many hours. What a training report must preserve to make its result reproducible, the full run envelope rather than the random seed alone, is collected with the other statistical controls in section 12.8.2.
12.5.3 Training performance evaluation
A comprehensive training benchmark considers multiple dimensions of system behavior because each dimension identifies a different way hardware investment can fail to become convergence. Table 12 summarizes the core categories and associated metrics commonly used to benchmark system-level training performance, providing a framework for understanding how training systems behave under different workloads and configurations.
| Category | Key Metrics | Example Benchmark Use |
|---|---|---|
| Training Time and Throughput | Time-to-accuracy (seconds, minutes, hours); Throughput (samples/sec) | Comparing training speed across different GPU architectures |
| Scalability and Parallelism | Scaling efficiency (percent of ideal speedup); Communication overhead (latency, bandwidth) | Analyzing distributed training performance for large models |
| Resource Utilization | Compute utilization (percent GPU/TPU usage); Memory bandwidth (GB/s); I/O efficiency (data loading speed) | Optimizing data pipelines to improve GPU utilization |
| Energy Efficiency and Cost | Energy consumption per run (MWh, kWh); Training throughput per watt (FLOP/s/W) | Evaluating energy-efficient training strategies |
| Fault Tolerance and Robustness | Checkpoint overhead (time per save); Recovery success rate (percent) | Assessing failure recovery in cloud-based training systems |
| Reproducibility and Standardization | Variance across runs (percent difference in accuracy, training time); Framework consistency (TensorFlow vs. PyTorch vs. JAX) | Ensuring consistency in benchmark results across hardware |
The scaling notebook supplies a concrete interpretation of table 12. The measured completion times establish a speedup and a resource-efficiency cost, but they do not identify which overhead caused the difference. A procurement decision therefore uses the time-to-quality result first, then the utilization and communication measurements to decide whether additional hardware or a different execution configuration would address the limiting resource.
Across matched runs, GPU boost-clock18 behavior and thermal state must follow the same protocol; otherwise a short fast run can be mistaken for a durable improvement. The repeated-run controls in section 12.8.1 determine whether the difference exceeds experimental uncertainty.
18 GPU boost clock: Dynamic frequency scaling raises clocks above base when thermal and power headroom permit. Short benchmark runs can capture this burst performance, while sustained training may settle to a different operating point. The benchmark must document the measured thermal state and clock policy.
In the worked case, 8 GPUs reach 75 percent scaling efficiency. If the required quality target and completion deadline are met, the configuration clears the time constraint, but the remaining scaling overhead still matters for cost. If the deadline is missed, the efficiency ratio alone does not justify buying more accelerators. The next experiment must measure exposed synchronization, input stalls, and per-device work under the intended batch and checkpoint schedule before choosing an intervention. If convergence changes between configurations, compare complete time-to-quality runs rather than interpreting the difference as pure strong-scaling loss.
A training report can therefore support a configuration choice without claiming that every measured overhead has already been explained. Its acceptance gates concern learning; an efficiently trained model still needs separate evidence that it can serve requests under deployment constraints.
Checkpoint 12.3: Measuring a training claim
The first half of the chapter built the measurement and applied it to training. Before moving to deployment, you should be able to:
Self-Check: Question
How do the primary benchmarking objectives and resource bottlenecks fundamentally differ between training systems and inference serving systems?
- Training is latency-critical with millisecond deadlines, whereas inference is throughput-oriented over weeks
- Training memory footprint is dominated solely by static weights, whereas inference requires large optimizer states
- Training optimizes for sustained throughput (samples/sec) and time-to-quality across accelerator systems with large memory demands (weights, gradients, optimizer states, activations), whereas inference optimizes for latency percentiles (p50, p99), QPS, and energy per query under serving constraints
- Training and inference have identical memory access patterns and evaluate the exact same metrics
Why does MLPerf Training mandate time-to-accuracy (or time-to-quality) as its primary benchmark metric instead of raw throughput measured in samples per second?
- Samples per second cannot be measured accurately with digital timers
- Time-to-accuracy is easier to simulate without running actual GPUs
- Hardware vendors do not know the batch size used during training
- Raw sample throughput can be artificially inflated by using aggressive low precision or extreme batch sizes that destabilize training, whereas time-to-accuracy ensures throughput optimizations actually converge to the required model quality
A deep learning model trains on a single GPU in \(24\text{ hours}\). With the same total optimizer work, the same training schedule, and the same quality target on the same fixed total dataset (strong scaling), the run completes in \(4\text{ hours}\) on \(8\text{ GPUs}\). What is the strong scaling efficiency, and does this timing result by itself identify the cause of the missing speedup?
- \(75\%\) efficiency; profiling is still required to identify the cause of the missing speedup
- \(100\%\) efficiency; the run achieved linear speedup because \(24 / 4 = 6\)
- \(50\%\) efficiency; GPU memory bandwidth is cut in half whenever multiple GPUs are connected
- \(12.5\%\) efficiency; training time only decreased by a factor of 6
Explain why a reduced-precision training configuration (such as FP8 or BF16) that achieves a \(1.8\times\) step-level throughput gain could result in a longer wall-clock time-to-accuracy than standard FP32 training.
In distributed training benchmarks, the scaling regime where the total workload remains constant as the number of accelerator nodes increases is known as ____.
Order the following operational stages of an illustrative successful ML training time-to-accuracy benchmark run from start to finish: (1) Halt training execution and log total elapsed wall-clock time-to-accuracy, (2) Execute distributed forward-backward iterations with gradient synchronization across nodes, (3) Initialize model parameters and data loaders using the run’s documented seed and standardized preprocessing, (4) Check whether the validation accuracy meets or exceeds the declared target quality threshold, (5) Perform periodic evaluation on the held-out validation dataset at predefined intervals
12.6 Inference Benchmarks
A camera trap running MobileNetV2 on an edge board must classify each frame within a 33-millisecond deadline to keep up with a 30-frame-per-second video stream. If an unbenchmarked garbage collection pause, dynamic batching timeout, or kernel launch hiccup stretches the p99 latency well past that deadline, frames are dropped, and an animal that crosses the field of view in under a second may go unrecorded, no matter how high the board’s average throughput. An autonomous vehicle’s perception loop runs against the same deadline arithmetic with far higher stakes. Training benchmarks measure how quickly a system learns; inference benchmarks measure how reliably it serves under real-world operational constraints. The two regimes differ in what they tolerate: training tolerates variable iteration times as long as gradient descent converges, but inference enforces service-level objectives where every delayed prediction compromises the application.
Inference is also where the optimization chapters converge, because the accelerated hardware runs the compressed models to deliver real-time predictions. Inference benchmarks reveal whether those theoretical speedups become actual latency reductions under realistic deployment conditions. Their central quantity is end-to-end request latency \(\EndToEndRequestLatency\), the full time from a request’s arrival to its response, including queueing, preprocessing, model execution, and postprocessing. It is distinct from the iron law’s latency term \(\Latency\), which counts only the fixed overhead (orchestration, serialization, dispatch) that one execution pays regardless of how much data it moves or arithmetic it performs; queueing delay, which grows with load, belongs to \(\EndToEndRequestLatency\) but not to \(\Latency\).
Definition 12.4: ML inference benchmarks
ML inference benchmarks are machine learning system benchmarks that quantify a system’s ability to meet latency constraints \((\EndToEndRequestLatency)\) at specified throughput levels, measuring scenario-defined latency statistics, throughput (queries per second), and power efficiency across representative serving scenarios.
- Significance: Inference benchmarks expose the workload- and system-specific gap between unconstrained throughput and throughput while meeting a service-level objective (SLO), such as a p99 latency target. Queuing delays push tail latency above the target at high load, and only a benchmark that enforces the target at each throughput level shows it.
- Distinction: Unlike training benchmarks, which measure time-to-accuracy over a fixed dataset, inference benchmarks measure per-query response time under realistic load patterns, capturing queuing effects, batching trade-offs, and cold-start overhead that determine real-world serving economics.
- Common pitfall: A frequent misconception is that average latency is a sufficient benchmark. A low mean can coexist with a long p99 tail, and at high request rates the slowest 1 percent becomes a large number of affected users. The benchmark must report the statistic the service objective names.
12.6.1 Inference benchmark motivation
Large-scale benchmark training commonly runs on dedicated data center hardware, whereas inference spans dramatically different deployment scenarios, from real-time applications like autonomous driving and conversational AI to mobile devices, IoT systems, and embedded processors. This diversity extends to hardware: while GPUs and TPUs dominate large-scale training, inference workloads often use specialized accelerators like NPUs, field-programmable gate arrays, and dedicated inference chips such as Google’s Edge TPU.19 Inference benchmarks evaluate how well hardware selection, model optimization, and data pipeline design work together across these deployment environments.
19 Edge TPU (tensor processing unit): Google’s fixed-function edge AI accelerator. It illustrates a benchmarking constraint specific to fixed-function accelerators: its headline throughput applies only to quantized TensorFlow Lite models with supported operator types, so models requiring unsupported operators fall back to the host CPU or need graph rewrites before the accelerator result is meaningful.
Deployment differences of this breadth motivate inference benchmarks, which evaluate the bottlenecks that emerge when models transition from development to production serving. The motivating factors parallel those for training (hardware optimization, scalability, cost, fair comparison) but differ in specifics. Software optimization frameworks apply inference-specific techniques such as kernel fusion, precision calibration, and kernel tuning, whose impact on latency, throughput, and power efficiency must be measured under realistic conditions to confirm they deliver real improvements without degrading accuracy. Auto-tuning compilers add a hidden variable: the compiler itself can require hours of optimization per model-hardware pair, meaning benchmark results reflect the tuning budget as much as the hardware capability, and comparing results across submissions requires normalizing for compiler optimization time.
Scalability concerns also shift character. Training scales by adding GPUs to reduce time-to-accuracy on a fixed workload, whereas inference must scale dynamically in response to fluctuating user demand, handling traffic spikes without violating latency guarantees. Applications that load models on demand, such as serverless deployments, also expose the model’s loading time, its cold start, directly to users.
The cost and energy profile of inference differs sharply from training. Training concentrates cost in discrete runs that may recur as data, objectives, or models change; inference cost accumulates continuously with production traffic. Running an inefficient model at scale can multiply cloud compute expenses, and on battery-powered devices, excessive computation directly affects usability. Benchmarks that measure cost per inference request and efficiency per watt help organizations optimize for both performance and sustainability across deployment platforms.
MLPerf Inference extends the standardized comparison principles established for training benchmarks to deployment scenarios, defining evaluation criteria for tasks such as image classification, object detection, and speech recognition across different hardware platforms, so that inference comparisons remain reproducible under deployment constraints such as latency requirements and energy efficiency (Reddi et al. 2019).
12.6.2 Inference metrics
A camera trap must classify each frame before the next one arrives, a voice assistant must respond quickly enough that users do not perceive lag, and a recommendation engine must score enough candidates to keep pace with user scrolling. These constraints (latency and throughput) define the performance envelope within which all serving optimizations must operate. Inference metrics formalize these real-world demands into measurable quantities, and they differ from training metrics in kind, not just degree, because the optimization target shifts from convergence rate during training to latency predictability during serving. Training optimizes for throughput and time-to-accuracy; inference optimizes for latency consistency, resource efficiency, and service-level predictability, spanning cloud data centers handling millions of requests to edge devices operating under strict power constraints.
Latency and tail latency
An inference service that averages 10 ms per request can still time out for thousands of users every hour if queueing bursts or garbage-collection pauses push the slowest 1 percent of requests past its deadline. Latency measures the time for an inference system to process an input and produce a prediction, and because averages conceal those high-percentile delays, benchmarks also report tail latency20—commonly the 95th percentile (p95) or 99th percentile (p99), the time within which 95 percent or 99 percent of inferences complete. Applications with hard deadlines require explicit deadline-miss or worst-case analysis beyond these percentiles. These measurements form the basis for SLOs and SLAs, which formalize performance expectations.
20 Tail latency: A high-percentile response time, such as p95 or p99, determines production SLO or SLA compliance only when that objective or agreement specifies the percentile. Dean and Barroso (2013) showed that in fan-out architectures (common in recommendation systems), even 1 percent slow responses compound: a request touching 100 backend shards has about a 63 percent chance that at least one shard hits its 1 percent tail. Benchmarks reporting only mean latency hide this failure mode.
Dean, Jeffrey, and Luiz André Barroso. 2013. “The Tail at Scale.” Communications of the ACM 56 (2): 74–80. https://doi.org/10.1145/2408776.2408794.
Definition 12.5: SLOs and SLAs
SLOs and SLAs are performance commitment specifications for production ML serving systems: a service-level objective (SLO) is a target value or range for a service-level indicator, while an SLA is a contract that specifies service objectives and the consequences of failing to meet them.
- Significance: A latency SLO bounds end-to-end request latency \(\EndToEndRequestLatency\) by setting a target for a specified latency indicator, and the iron law’s \(\Latency\) is only the fixed-overhead part of that budget. Request queueing and transient spikes consume part of that budget.
- Distinction: An SLO has no contractual consequence by itself, while missing an SLA objective triggers the consequences specified in the agreement, which may include credits or penalties. Teams commonly set the internal SLO tighter than the external agreement to leave operational headroom, though the definition does not require it.
- Common pitfall: A frequent misconception is that meeting average latency satisfies a tail-latency SLO. SLOs can use averages, percentiles, rates, or other indicators; when the objective is defined at p99 or p99.9, an excellent mean does not establish compliance.
Engineering teams optimize toward SLOs while the business commits to SLAs. A usable latency objective also fixes the request population, the offered load, and the measurement window. Otherwise, two teams can report the same percentile threshold over different traffic mixes and reach incompatible conclusions about compliance.
Checkpoint 12.4: Metric selection
The metric shapes the optimization.
Apply three rules before finalizing metric selection:
At production scale, small p99 degradations affect many users. If 1 percent of requests take 10\(\times\) longer (for example, 1000 ms instead of 100 ms), 10,000 requests per million are slow enough to risk timeouts and customer churn. Search engines and recommendation systems demonstrate this sensitivity: Google’s search-latency experiments found measurable reductions in daily searches per user after 100–400 ms server-side delays (Brutlag 2009), which is why interactive services often treat sub-100 ms response times as a practical design target. Because occasional slow responses weigh heavily on user satisfaction, such services define percentile-based objectives, and large-scale systems may track deeper tails such as p99.9.
Brutlag, Jake. 2009. Speed Matters for Google Web Search. Google Research Blog.
↪ Provisioning serving capacity so that p99 latency meets its SLO under peak load is developed in Tail latency.
The challenge of meeting these tail latency targets is that the source of the tail is often architectural, not algorithmic. A garbage-collected runtime, a shared kernel driver, or a priority-inversion bug in the serving stack can inject latency spikes that no model optimization will remove.
Discord’s Read States service shows the effect outside machine learning. Periodic garbage-collection pauses in its Go implementation spiked p99 latency every two minutes until a rewrite in Rust removed the pauses (Howarth 2020). A managed runtime in a feature store or retrieval path can impose the same floor on an ML service’s tail, and no model optimization removes it, which is why the complete serving stack belongs inside a production latency benchmark. Tail latency develops the mechanisms that shape the tail under load.
Howarth, Jesse. 2020. “Why Discord Is Switching from Go to Rust.”
Token latency: TTFT and TPOT
Generative models are served one token at a time, so their latency splits into two measured quantities. Time to first token (TTFT) is the interval from a request’s arrival to its first output token, dominated by prefill, the pass that processes the whole prompt in parallel. Time per output token (TPOT) is the mean interval between subsequent tokens, set by autoregressive decode. The gap between any two successive tokens is the inter-token latency (ITL), so TPOT is the average of a request’s ITLs, and the ITL distribution exposes the individual stalls that the average hides. A benchmark that reports a single aggregate throughput hides both: a model can achieve high throughput in tokens per second while still feeling sluggish if the first token arrives late, or it can minimize TTFT while generating subsequent text too slowly for interactive reading.
Token throughput translates these generation rates into user-perceived wall-clock time: for a response of 750 tokens, a generation rate of 25 tokens/s requires 30 seconds, whereas 100 tokens/s finishes in 7.5 seconds. Time-to-first-token and inter-token latency must therefore be reported together: one captures initial responsiveness, and the other captures sustained delivery speed. This latency split reflects contrasting computational regimes: time-to-first-token is governed by prompt prefill, which processes tokens in parallel and is typically compute-bound, whereas inter-token latency is governed by autoregressive decoding, where low-batch execution often streams weights and accesses a growing KV cache with limited reuse. The resulting bandwidth pressure depends on model residency, context length, batch size, and the execution path. Performance metrics: TTFT and TPOT builds serving policies on these two measurements; the benchmarking requirement is that both are reported, under the same offered load, for every generative workload.
Throughput and resource metrics
Latency is only half of the serving envelope. Throughput counts how many inference requests a system completes per second, typically expressed as queries per second (QPS) or frames per second (FPS), and it is meaningful only together with the latency at which it was measured. Batching raises throughput by processing several inputs at once while adding wait time to each, so a throughput figure reported without its latency percentile and offered load says nothing about whether a serving deadline is met. A benchmark therefore reports batch throughput and per-request latency as a pair at the same offered load. Choosing the batch size that balances them is a serving policy (Formation delay and the latency-throughput frontier); the benchmark’s job is to measure both sides of that trade.
Speed alone is insufficient because inference optimizations can change model behavior. Reducing numerical precision can accelerate computation while cutting memory and energy, as the simplified MobileNetV2 energy estimate worked out in the power section shows (section 12.7.1), but lower-precision calculations can introduce accuracy degradation. Inference benchmarks therefore evaluate how well models perform under different numerical settings, such as FP32, FP16, and INT8.21 Model compression techniques22 further improve efficiency, but their impact on model accuracy varies depending on the task and dataset. Benchmarks help determine whether these optimizations are viable for deployment, ensuring that improvements in efficiency do not come at the cost of unacceptable accuracy loss.
21 INT8 (8-bit integer): INT8 sits at the aggressive end of the precision hierarchy (FP32 baseline, FP16 halves raw weight storage, INT8 quarters it), and each step demands increasing care to preserve accuracy. Post-training INT8 quantization normally fits its value ranges on a representative calibration dataset (quantization-range calibration, distinct from the confidence calibration of section 12.9.1.2); accuracy depends on the model, operator coverage, quantization method, and how well the calibration data represent deployment inputs. INT8 benchmarks must specify whether they use post-training quantization or quantization-aware training and document any range-calibration procedure.
22 Model compression benchmarking: Compression impact must be measured across four dimensions simultaneously: accuracy degradation, inference speedup, memory reduction, and energy savings. A technique achieving 10\(\times\) size reduction with 1 percent accuracy loss may still be unsuitable if latency misses the deployment target; unstructured pruning, for example, leaves dense execution unchanged unless a compatible sparse representation and kernel exploit the zeros.
23 Cold-start latency: The initialization time from idle state includes storage reads, host-to-accelerator transfer, and framework setup. For a 7B-parameter model in FP16 (~14 GB) already resident in host memory, PCIe 4.0 transfer at 25 GB/s effective bandwidth alone takes ~560 ms; storage and initialization add to it. This lower bound makes cold-start mitigation (model caching, speculative loading) a systems design requirement.
24 Serverless AI: Deployment paradigm where models scale from zero instances on demand. Cold-start time varies with the model, runtime, storage path, hardware allocation, and provider. Benchmarks for intermittent workloads must report whether initialization and model loading are included, because warm-instance latency alone can understate user-perceived latency.
Beyond speed and accuracy, table 15 lists the resource terms an inference benchmark must also report, and each exists because a system can pass the latency test and still fail to deploy. Memory footprint decides whether the model fits the device’s budget at all, since inference rarely spans accelerators the way training can. Cold-start performance, the load time plus first-request latency,23 exposes initialization cost to the requesting user. It dominates in serverless AI environments24 and on devices that evict models to free memory. When provisioning, model transfer, runtime initialization, and the first response lie on the user request path, the benchmark must include them; a warm-instance result answers a different question. Scalability records whether added accelerators or concurrent models raise throughput or collide on memory bandwidth, and energy per inference (joules per inference, or QPS/W in the cloud) sets battery life on mobile devices and operating cost in data centers.
12.6.3 MLPerf inference benchmarks
MLPerf Inference turns that balance among latency, throughput, memory, energy, and accuracy into scored scenarios, and it matters because deployment context changes what a result means. The benchmark, developed by MLCommons,25 provides a standardized framework for evaluating machine learning inference performance across a range of deployment environments. MLPerf began with training benchmarks in 2018; MLPerf Inference was added later to standardize deployment-time evaluation across scenarios. The family of MLPerf inference benchmarks maps each benchmark to a deployment setting, so a score can be interpreted against the latency, throughput, memory, and power constraints the system will face.
25 MLCommons: Launched in 2020 as a nonprofit consortium evolving from the 2018 MLPerf effort, MLCommons includes members across industry and academia (MLCommons 2026a). Requiring published system specifications improves result comparability, but it does not prevent submitters from selecting which systems or workloads to enter. Published results reveal large performance differences between vendors on identical workloads, making MLCommons the closest the field has to SPEC-style like-for-like hardware comparison.
MLCommons. 2026a. MLCommons: About Us.
MLPerf Inference
MLPerf Inference (Reddi et al. 2019) is the baseline inference benchmark, defining standardized scenarios for deployment-time evaluation across data-center and edge settings. Submissions follow the closed and open divisions defined in section 12.4.4. Its workloads span image classification, object detection, natural language processing, and recommendation, and its results are a common reference point for comparing accelerators and CPUs when the submission rules and scenario match the intended deployment. On recommendation workloads, scores on DLRM26 can inform choices between accelerator generations, although the size of the gain depends on workload, software stack, and system configuration. At the same time, the cost of comprehensive benchmarking limits who can participate and how thoroughly systems are evaluated.
26 DLRM (deep learning recommendation model): Facebook’s 2019 recommendation architecture combines embedding tables for categorical features with multilayer perceptrons for continuous features (Naumov et al. 2019). DLRM stresses benchmarks differently than vision or language models: its embedding tables can be large enough that memory capacity and bandwidth dominate compute throughput. That makes DLRM the book’s capacity-bound workload in MLPerf-style inference evaluation, revealing hardware limitations invisible to compute-bound benchmarks (Reddi et al. 2019).
Naumov, Maxim, Dheevatsa Mudigere, Hao-Jun Michael Shi, Jianyu Huang, Narayanan Sundaraman, Jongsoo Park, Xiaodong Wang, et al. 2019. “Deep Learning Recommendation Model for Personalization and Recommendation Systems.” arXiv Preprint arXiv:1906.00091.
Reddi, Vijay Janapa, Christine Cheng, David Kanter, Peter Mattson, Guenther Schmuelling, Carole-Jean Wu, Brian Anderson, et al. 2019. “MLPerf Inference Benchmark.” 2020 ACM/IEEE 47th Annual International Symposium on Computer Architecture (ISCA), 446–59. https://doi.org/10.1109/isca45697.2020.00045.
Systems Perspective 12.6: The cost of comprehensive benchmarking
Submitting to MLPerf can require dedicated engineering effort, hardware access, tuning, validation, and careful documentation across the relevant configurations. The cost depends heavily on workload and scope, but it is high enough that submissions are dominated by major technology companies and hardware vendors, while smaller organizations rely on published results rather than conducting their own comprehensive evaluations. That barrier motivates the need for more lightweight, internal benchmarking practices that organizations can use to make informed decisions without the expense of full-scale standardized benchmarking.
The rest of the MLPerf inference family narrows that baseline by deployment context. MLPerf Mobile (MLCommons 2024a) evaluates whether a model stays responsive within smartphone power and memory limits (Janapa Reddi et al. 2022). MLPerf Client (MLCommons 2026b) asks whether consumer devices can run local generative-AI workloads, which makes CPUs, discrete GPUs, and integrated NPUs part of the benchmarked system. MLPerf Tiny (Banbury et al. 2021) covers embedded and ultra-low-power systems, such as IoT devices, wearables, and microcontrollers. Each variant keeps the same benchmark discipline while changing the binding resource.
MLCommons. 2024a. MLPerf Mobile Benchmark.
Janapa Reddi, Vijay et al. 2022. “MLPerf Mobile V2. 0: An Industry-Standard Benchmark Suite for Mobile Machine Learning.” Proceedings of Machine Learning and Systems (MLSys) 4: 806–23.
MLCommons. 2026b. MLPerf Client Benchmark.
12.6.4 Mobile and edge benchmarks
Unlike data centers with kilowatt-scale power delivery and active cooling infrastructure, mobile and edge deployments operate within strict milliwatt- to watt-scale power envelopes and passive thermal dissipation limits. Benchmarking these systems means reporting power consumption, inference latency, and model accuracy together, because gains in one usually come at the expense of another. Table 13 contrasts these operational constraints against cloud environments.
| Constraint | Cloud Impact | Edge Impact |
|---|---|---|
| Power | Operational cost | Device energy budget |
| Latency | Service-level target | Local response deadline |
| Accuracy | Task-quality target | Balanced with power/latency |
Consider a smartphone camera executing real-time object detection at 30 frames per second within a 3 W to 5 W thermal envelope. In this setting, an efficient architecture such as MobileNet serves as a realistic benchmark target where a larger ResNet model would violate thermal limits, despite the larger model’s superior accuracy in cloud evaluations. An edge benchmark must therefore evaluate accuracy jointly with sustained power and thermal dissipation. The peak-versus-sustained gap (section 12.1) is especially acute at the edge, because a passively cooled device sheds heat poorly. As junction temperatures rise, the dynamic thermal management (DTM) controller scales down operating voltage and clock frequency, causing sustained throughput to drop sharply below burst-mode peaks. That thermal mechanism makes the cooling configuration part of the benchmark specification.
Example 12.2: Benchmarking the edge
Scenario: An edge engineering team benchmarks a candidate chip for the camera trap’s board with a vendor-advertised “1 W AI” power specification.
Diagnosis: Early burst-mode testing matches vendor claims, but continuous inference loop execution builds up junction heat, triggering thermal throttling and dropping steady-state throughput.
Systems lesson: Short burst benchmarks obscure long-term thermal throttling. Benchmarking edge ML workloads requires continuous, sustained execution testing to reflect true operational hardware limits.
Burst benchmark FPS collapses once thermal throttling sets in.
Throttling is the most visible way a short measurement flatters edge hardware. Idle power, duty cycle, and the data movement around the accelerator can distort a headline number too, so each needs checking before a vendor claim informs a design decision.
Systems Perspective 12.7: Edge benchmark reality check
When evaluating edge hardware claims, four factors determine whether vendor numbers translate to real-world performance:
- Peak vs. sustained: A vendor may advertise 45 TOPS peak throughput while a sustained thermal run delivers closer to 20 TOPS. In this scenario, use a sustained run longer than 30 s and verify thermal stabilization; also test the deployment duty cycle.
- Power at idle vs. active: In this scenario, a device consuming 50 mW idle and 2 W active could report active draw for marketing, but if the application runs inference 1 percent of the time, effective power draw is ~69.5 mW, not 2 W.
- Thermal envelope: Edge devices often operate inside a narrow TDP envelope. Exceeding it triggers throttling, so benchmark reports omitting thermal conditions are incomplete.
- End-to-end vs. accelerator-only: NPU benchmarks often exclude data transfer overhead. Moving image data from camera to NPU and back can exceed inference time for small models.
A modern mobile SoC packages CPUs, GPUs, digital signal processors (DSPs), and neural processing units (NPUs) on one die that shares system memory and a common thermal budget, so an edge benchmark must measure the pipeline across those engines rather than one engine’s kernel throughput. Single-engine benchmarks miss three costs that fall between the engines: waking an accelerator from a deep sleep state, contention when several engines access shared DRAM, and converting tensor layouts between the formats different engines require. Heterogeneous SoC Design develops how these SoCs partition work.
12.6.5 Building the edge-board benchmark
The camera trap’s board is the case for the inference measurements above. It pairs a low-power host CPU with an attached INT8 accelerator, and the claim inherited from the compression and acceleration chapters is that INT8 MobileNetV2 on the accelerator meets the camera’s frame deadline at a fraction of the host’s energy. The benchmark is built in the order a careful engineer would follow: precision on the host first, then the accelerator, then the gates that decide whether the result can ship. The labeled composite values below are illustrative, not measurements of a named product.
Example 12.3: Benchmarking a vision model for edge deployment
Scenario: An edge AI team evaluates MobileNetV2 on the camera trap’s host CPU, first at FP32 and then at INT8, under strict latency and model size limits (Sandler et al. 2018).
Diagnosis: FP32 execution yields 50 ms latency (20 FPS) and 14 MB size. INT8 quantization speeds up inference by 3.3× to 15 ms (66.7 FPS) and reduces model size by 4×, at a cost of 0.9 percentage points Top-1 accuracy.
Systems lesson: Edge model benchmarking requires evaluating multi-dimensional trade-offs across latency, accuracy, and memory payload. Quantization enables high-throughput edge execution when modest accuracy drops meet product requirements.
Lighthouse 12.2: MobileNetV2 on the edge accelerator
Extending lighthouse 12.1, the hardware-acceleration claim is evaluated using an illustrative SingleStream-style edge-inference scenario (Reddi et al. 2019; Banbury et al. 2021).
Table 14: Edge Accelerator vs. Host CPU MobileNetV2 Scenario: Illustrative SingleStream-style latency, power, and energy values show how measurement boundaries alter comparative ratios. While end-to-end latency captures host preprocessing and link transfer overhead, the power and energy rows reflect active component execution alone rather than whole-system draw; these are illustrative values rather than controlled laboratory measurements.
Hardware acceleration claim: In this illustrative edge-accelerator scenario, assume INT8 MobileNetV2 inference takes ~2 ms on the accelerator, approximately 7.5× faster than the same board’s low-power host CPU (~15 ms). The host CPU column is the INT8 host result of example 12.3, so both measurements describe the same board. Actual results depend on operator coverage, clock frequency, thermal state, and implementation.
Table 14 reports the illustrative SingleStream-style scenario assumptions across distinct measurement scopes.
| Metric | Measurement Scope | Host CPU | Accelerator | Comparative Ratio |
|---|---|---|---|---|
| Inference latency | Isolated model compute | ~15 ms | ~2 ms | 7.5× faster (isolated headline) |
| End-to-end latency | Full request path (prep + link + exec) | ~18 ms | ~6 ms | ~3× faster (system-level) |
| Active power | Component during inference execution | ~120 mW | ~500 mW | ~4.2× higher (component active) |
| Active energy per inference | Component active energy (\(P \times t_{\text{inference}}\)) | ~1.8 mJ | ~1 mJ | ~1.8× more efficient (component active) |
What this reveals: Under these assumptions, the 7.5× inference speedup narrows to ~3× end to end because preprocessing runs on the host CPU in both cases (figure 6). The accelerator path incurs additional latency copying each input across the host-accelerator link and retrieving the result, a transfer overhead the CPU-only path never pays.
Furthermore, the 1.8× energy advantage applies specifically to the active inference interval (\(P \times t_{\text{inference}}\)), measuring component-level efficiency rather than total system consumption. This metric excludes host CPU preprocessing energy, interconnect transmission power, and baseline idle draw during non-inference phases. Because end-to-end latency improves by only 3×, host baseline power consumed during these non-accelerated phases narrows the whole-system battery efficiency gain.
Workload arrival patterns determine whether component-level energy efficiency translates to extended battery life. For intermittent duty cycles, the lower active inference energy favors the accelerator, but total battery drain depends on sleep power, wake-up latency and energy overhead, host transfer costs, and any standby leakage the accelerator draws while awaiting work. For continuous streaming workloads such as video analytics, the accelerator’s lower active energy per inference dominates cumulative energy consumption.
The SingleStream result illustrates why benchmarking requires matching the MLPerf scenario to the deployment context: SingleStream emphasizes latency, while Offline benchmarks would optimize for bulk throughput rather than latency bounds.
Banbury, Colby, Vijay Janapa Reddi, Peter Torelli, Jeremy Holleman, Nat Jeffries, Csaba Kiraly, Pietro Montino, et al. 2021. “MLPerf Tiny Benchmark.” arXiv Preprint.
The board’s INT8 results support further evaluation, but they do not establish that the camera trap’s service objective has been met. The decision requires the request population, latency statistic, quality floor, and memory and energy budgets to be specified together.
Table 15 identifies the remaining evidence. A camera pipeline needs sustained completion times under its input cadence; an intermittent application also needs initialization and sleep-state costs. For either application, the candidate must retain the required model quality on representative inputs. The same model-level speedup can therefore support one deployment and fail another.
| Category | Key Metrics | Example Benchmark Use |
|---|---|---|
| Latency and Tail Latency | Mean latency (ms/request); Tail latency (p95, p99, p99.9) | Evaluating interactive and soft real-time performance |
| Throughput and Efficiency | Queries per second (QPS); Frames per second (FPS); Batch throughput | Comparing large-scale cloud inference systems |
| Numerical Precision Impact | Accuracy degradation (FP32 vs. INT8); Speedup from reduced precision | Balancing accuracy vs. efficiency in optimized inference |
| Memory Footprint | Model size (MB/GB); RAM usage (MB); Memory bandwidth utilization | Assessing feasibility for edge and mobile deployments |
| Cold-Start and Load Time | Model load time (s); First inference latency (s) | Evaluating responsiveness in serverless AI |
| Scalability | Efficiency under load; Multi-model serving performance | Measuring robustness for dynamic, high-demand systems |
| Power and Energy Efficiency | Power consumption (W); Performance per W (QPS/W) | Optimizing energy use for mobile and sustainable AI |
The acceptance decision can reject a candidate on any binding constraint. A lower model-only latency does not establish an end-to-end gain if preprocessing dominates, and a smaller weight file does not establish that runtime buffers fit the device. The latency decomposition and Amdahl calculation in section 12.3.4 specify which additional measurements the MobileNetV2 comparison needs.
Because physical constraints differ across environments, no single metric ordering governs all systems. Benchmarking requires establishing a priority hierarchy derived directly from the deployment specification. Table 16 illustrates how metric priorities shift across five operational contexts, mapping hardware and operational constraints to optimization targets.
| Deployment Context | Primary Priority | Secondary Priority | Tertiary Priority | Key Design Constraint |
|---|---|---|---|---|
| Real-Time Applications | Latency | Reliability | Memory Footprint | User experience demands immediate response |
| Cloud-Scale Services | Throughput (QPS) | Cost Efficiency | Average Latency | Business viability requires massive scale |
| Edge/Mobile Devices | Power Consumption | Memory Footprint | Latency | Battery life and resource limits dominate |
| Training Workloads | Training Time | GPU Utilization | Memory Efficiency | Research velocity enables faster experimentation |
| Scientific/Medical | Accuracy | Reliability | Explainability | Correctness cannot be compromised for performance |
A metric that dictates architectural success in one deployment context may be irrelevant in another. Latency ranks first for autonomous robotics, where sensor-processing pipelines must complete within strict execution deadlines to maintain vehicle stability, whereas cloud batch services accept higher queuing latency in exchange for lower operational cost per query. A 2\(\times\) throughput gain represents substantial economic value in a hyperscale cloud cluster, but it provides little benefit on a battery-powered device such as the camera trap, where a 20 percent power reduction extends operational lifetime.
For the camera example, use the required deadline or percentile as the timing gate, the runtime peak allocation as the capacity gate, and the permitted quality loss as the model gate. If any gate lacks a measurement, the decision remains unresolved even when the reported inference speedup is large. A protocol should identify the missing evidence rather than treating the favorable metric as approval. An on-demand deployment adds a fourth gate, cold-start latency, measured on the user request path as section 12.6.2.3 specifies.
Beyond initialization delays, inference benchmarks become misleading when operational metrics are reported without functional validation. Numerical precision optimization introduces a significant comparability trap across accelerator platforms. Accelerators provide substantially higher INT8 operation throughput27 than baseline FP32 floating-point rates, but these peak figures are meaningful only when the benchmark verifies accuracy retention under quantization noise, confirms hardware support across all model operators, and enforces equivalent operation definitions across architectures.
27 TOPS (tera operations per second): A measure of raw computational throughput (trillions of operations/second). The H100 delivers 1979 TOPS INT8 vs. the Apple M2 Neural Engine at 15.8 TOPS and Edge TPU at 4 TOPS, but these numbers conflate different operation types (multiply-accumulate, accumulate, or activation). TOPS comparisons across vendors are meaningful only when the operation definition, precision, and sparsity assumptions are identical, conditions rarely met in vendor specifications.
Once a candidate clears quality and capacity gates, varying offered load tests how far its timing result transfers. A runtime can sustain a favorable latency with one request in flight yet miss the target when queues and shared memory fill. The relevant outcome is the supported load under the declared latency bound, measured with the same input mix and power policy, rather than an isolated peak throughput.
The board now has a latency, a throughput, and a memory footprint. What it lacks is the number that decides whether a battery-powered camera trap lasts a season in the field: the energy each frame costs.
Self-Check: Question
In a distributed serving architecture, assume a user request is dispatched simultaneously to \(10\) backend ML model services, the overall response waits for all \(10\) replies, other latency is negligible, and each service independently has a \(1\%\) probability of exceeding \(20\text{ ms}\) on that request. What is the approximate probability that the user request exceeds \(20\text{ ms}\)?
- Exactly \(1.0\%\)
- Approximately \(9.6\%\) (nearly \(1\) in every \(10\) user requests)
- Exactly \(0.1\%\)
- 0% because parallel aggregation hides individual service latency spikes
A cloud provider is deploying an interactive web translation API where independent user requests arrive randomly according to a Poisson process, and the service is evaluated by the throughput it can sustain while meeting a strict tail-latency objective such as \(p99 \le 15\text{ ms}\) (which does not mean every single response must be at or below \(15\text{ ms}\)). Which MLPerf Inference scenario most directly matches this arrival-and-metric regime?
- Offline scenario
- SingleStream scenario
- MultiStream scenario
- Server scenario
In serverless and on-demand inference systems, the latency penalty incurred on the first request after an idle period when the runtime has been unloaded or lazily initialized—caused by loading weights into memory and compiling compute kernels—is termed a ____.
Explain why reporting an accelerator-only inference time (e.g., \(2\text{ ms}\) on an edge NPU) fails to predict actual mobile application performance, identifying at least two real-world system bottlenecks.
Order the following stages of an illustrative MLPerf Inference Server-scenario evaluation workflow, where this workflow first validates accuracy and then performs a warm, timed performance run:
- LoadGen generates queries according to a Poisson arrival distribution at a target query-per-second (QPS) rate
- SUT receives queries, may apply dynamic batching, executes neural network inference, and returns responses
- Warm up the System Under Test (SUT) with representative queries to populate weights and compile execution graphs
- Validate separately that model output accuracy meets the required reference quality threshold under the specified protocol
- Record end-to-end timestamps for each query and compute the empirical latency distribution (\(p50\), \(p90\), \(p99\)) to verify SLA compliance
12.7 Power and Energy Measurement
A chip vendor advertises “10 TOPS at 0.5 W,” but under sustained inference load, thermal throttling drops actual throughput to 3 TOPS at 2 W—a 13.3× efficiency gap between the datasheet and reality that goes undetected until deployment unless power is measured under load. Energy is the one benchmark quantity that cannot be read off a clock: it must be integrated over a stated measurement boundary and window, and for a duty-cycled device it depends on how the device spends the time between inferences. KWS, the book’s power-bound lighthouse, carries the measurement of energy, because a wake-word detector is judged by how long it listens on a battery rather than by how fast it answers; the edge board’s frames and the data center’s racks appear as contrasts.
This efficiency dimension matters directly because Anatomy of an Accelerator defines acceleration by its compute-density and performance-per-watt gains, making TOPS/W a primary design objective alongside raw TOPS. Power benchmarks validate whether efficiency-optimized accelerators deliver their promised energy savings. TOPS/W is particularly susceptible to gaming precisely because it is a ratio of two separately quotable peaks: a vendor can read the numerator (operations) at the batch size and precision that maximize throughput and the denominator (watts) at a near-idle operating point, so the advertised efficiency describes a state the chip never occupies under real load. Power benchmarks close that loophole by fixing the workload and the measurement window, forcing the numerator and denominator to be read at the same operating point.
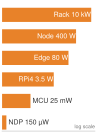
Datasheet TOPS/W overstates sustained efficiency by 13.3×.
Measuring power differs from measuring execution time because power is not a single timestamped interval: instantaneous power (supply voltage times current) fluctuates continuously across microsecond execution phases and drifts over minutes as silicon heats up, increasing temperature-dependent leakage current. ML deployments also span a wide physical range. The dumbbell plot in figure 7 isolates this disparity on a logarithmic power scale, plotting minimum (blue) and maximum (red) envelopes across four deployment tiers: TinyML systems (5.6 mW to 167 mW), edge hardware (3.9 W to 1.1 kW), data center inference nodes (267 W to 6.3 kW), and large-scale training clusters (5.5 kW to 498 kW). Spanning about eight orders of magnitude from the TinyML floor to the training-cluster ceiling, this spectrum explains why no single efficiency metric serves all deployment contexts. A figure of merit optimized for multi-rack data center throughput becomes meaningless for a battery-powered keyword spotter governed by milliwatt budgets.
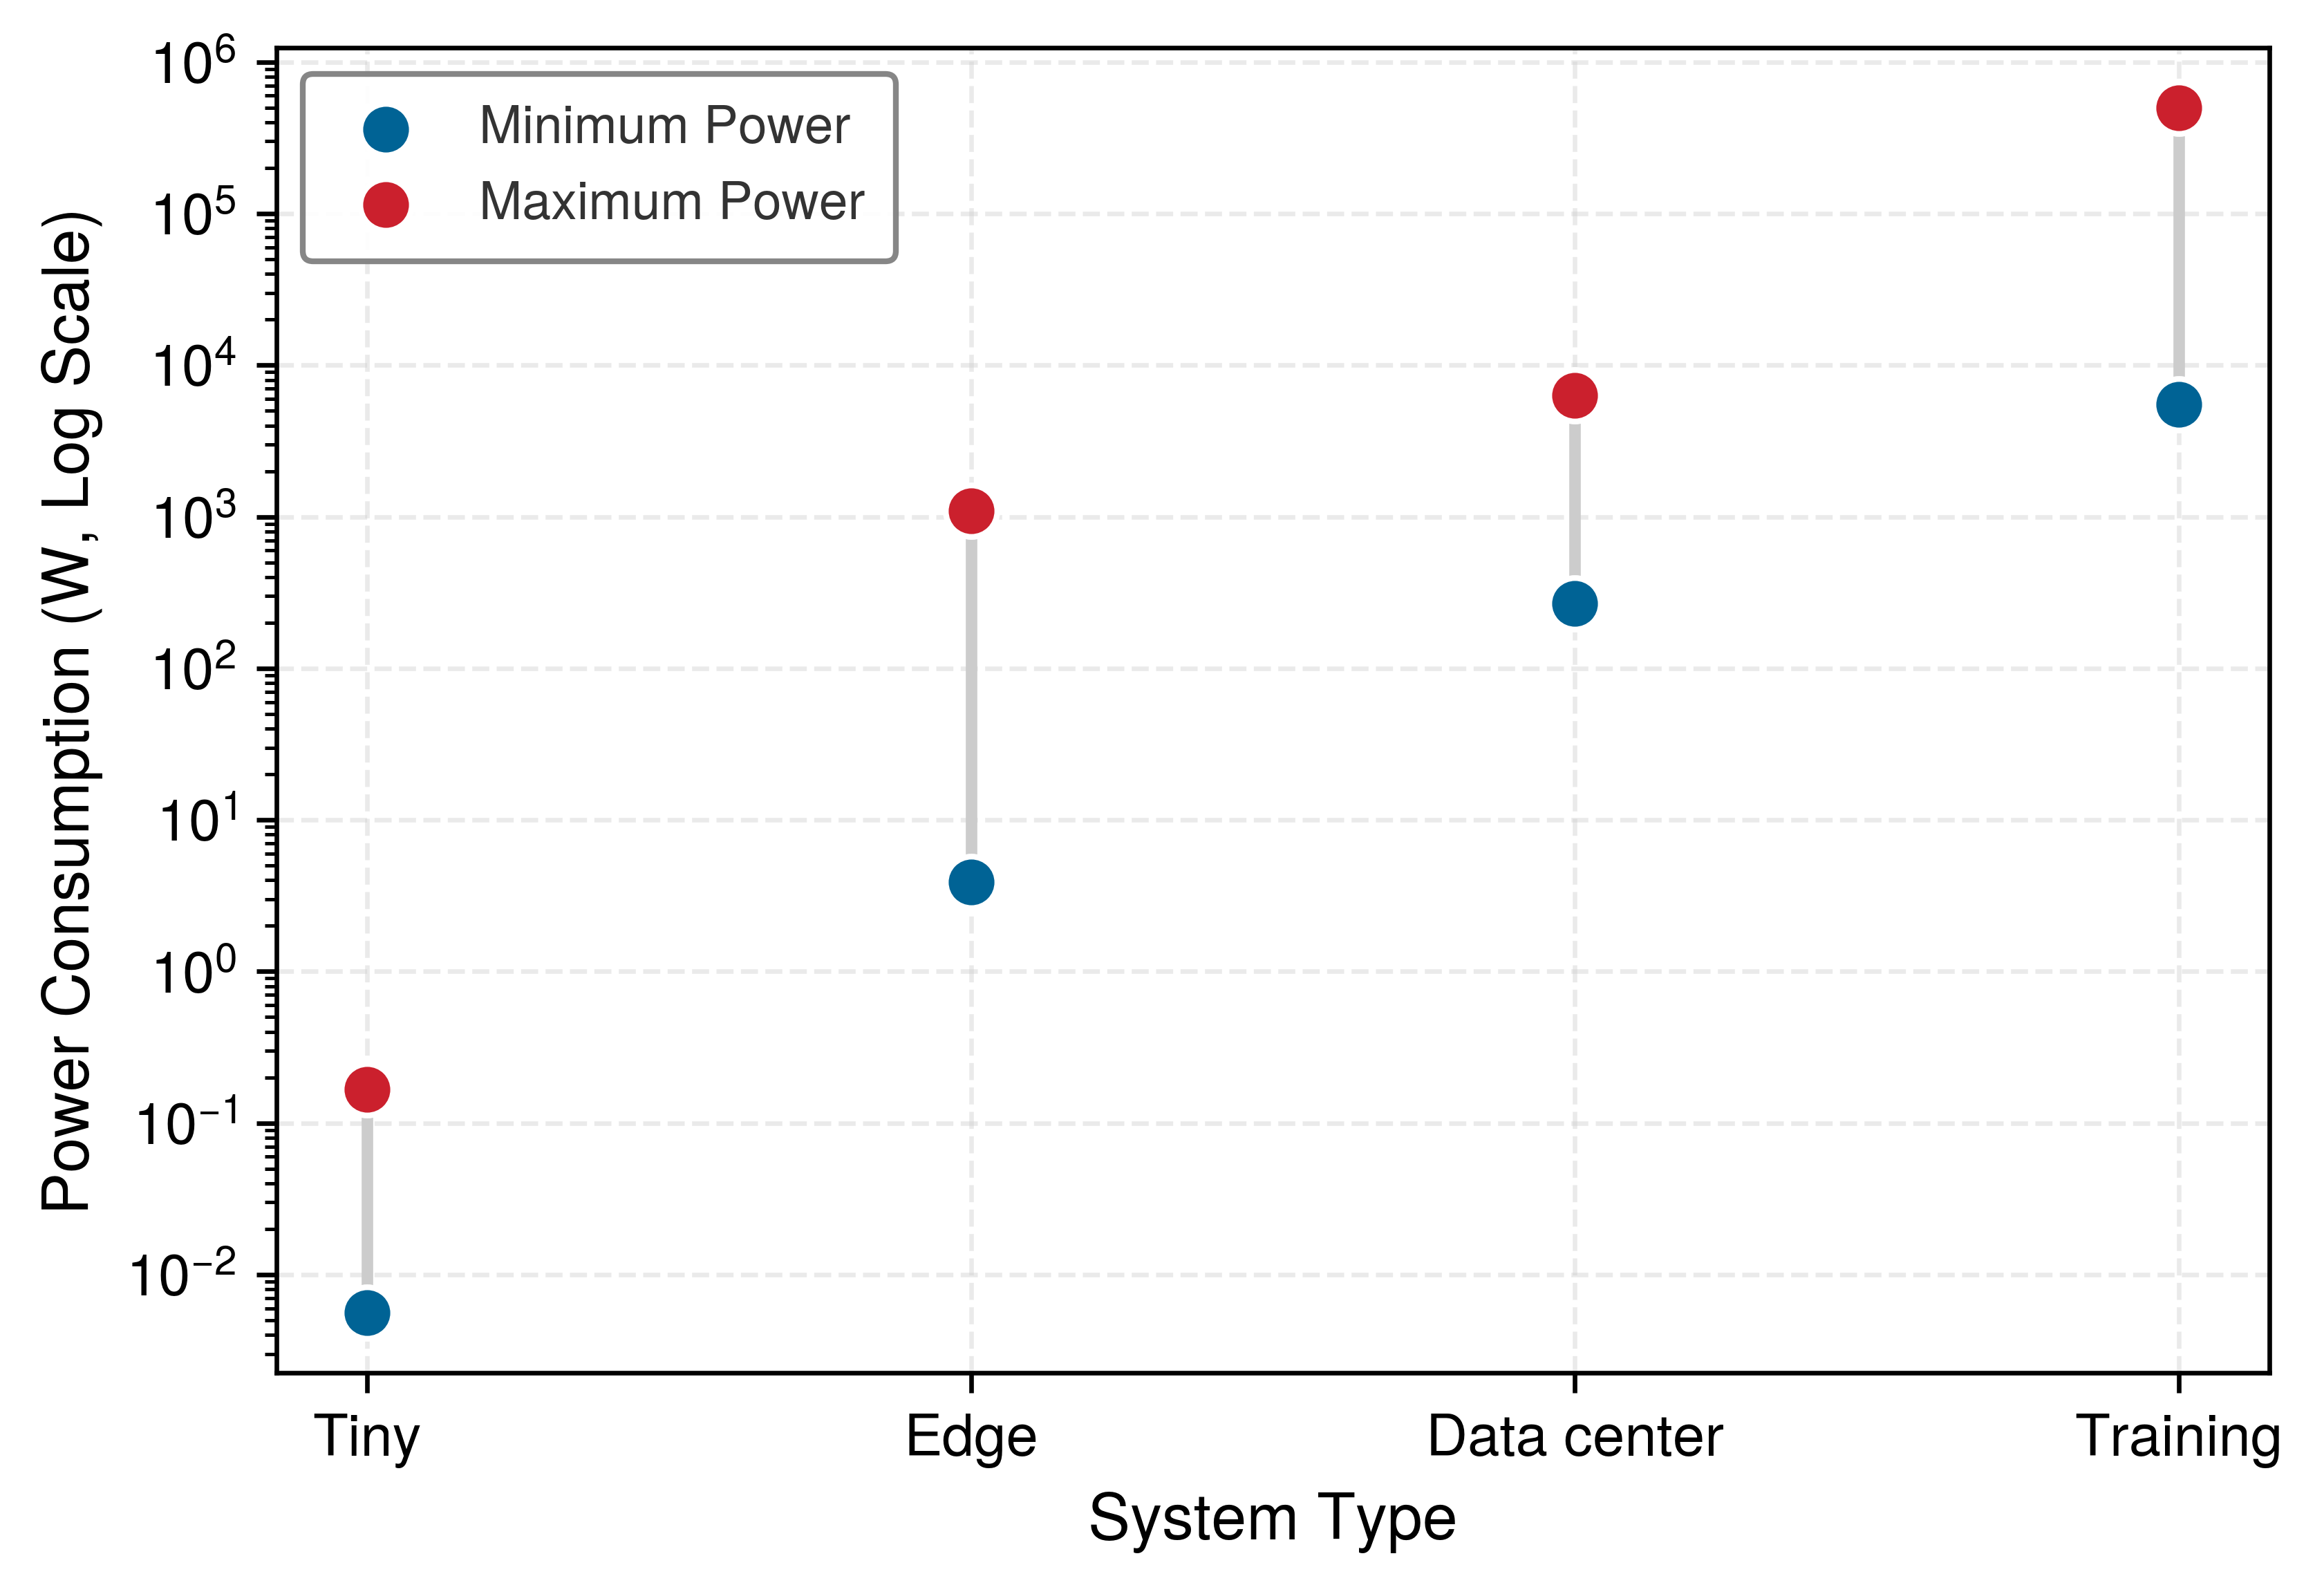
Because measured power spans from milliwatts to hundreds of kilowatts, no single instrument or measurement protocol applies everywhere. Benchmarking an always-on keyword spotter requires measuring microampere currents at millivolt rails, whereas benchmarking a server rack requires measuring high-voltage three-phase alternating current at the power distribution unit. This divergence forces benchmarking standards to establish precise physical boundaries for what hardware is included in the measured energy.
Energy accounting follows contrasting regimes across training and inference. Training energy is a capital investment amortized across the operational lifetime of the model; a large training run can consume on the order of a thousand megawatt-hours (section 12.5.2.4) (Patterson et al. 2021). Inference energy accumulates continuously with request volume, dominating total lifecycle cost as query counts scale into millions. For an isolated inference window containing one completed request, energy obeys the identity \(\InferenceEnergy= \ActiveInferencePower\times \InferenceLatency\), with \(\ActiveInferencePower\) the average accelerator power during that window and \(\InferenceLatency\) its duration; the duty-cycle form used for battery accounting appears in section 12.7.2. With batching or concurrent requests, integrate energy over a common measurement window and divide by completed requests; multiplying total device power by each request’s overlapping serving latency would double-count energy. For example, if measured average accelerator power during the inference window is 300 W, a 10 ms inference uses \(\text{300 W} \times \text{0.01 s} = \text{3 J}\), or about 0.0008 Wh; at 100 ms, that becomes about 0.0083 Wh. An accelerator’s TDP rating represents a cooling ceiling rather than dynamic power consumption, making empirical runtime power measurement essential for accurate benchmarking.
Patterson, David, Joseph Gonzalez, Quoc Le, Chen Liang, Lluis-Miquel Munguia, Daniel Rothchild, David So, Maud Texier, and Jeff Dean. 2021. “Carbon Emissions and Large Neural Network Training.” arXiv Preprint arXiv:2104.10350.
12.7.1 Power measurement boundaries
Where an engineer draws the system boundary dictates what counts as efficient. If a benchmark measures only the accelerator core, it ignores the host CPU driving the PCIe bus, the off-chip DRAM holding weights, and the cooling fans dissipating heat. Figure 8 partitions these measurement perimeters across three deployment tiers (Tiny, Inference, and Training), where solid olive enclosures demarcate measured components and red dashed boxes isolate excluded infrastructure such as remote storage and data-center chillers (Tschand et al. 2024).
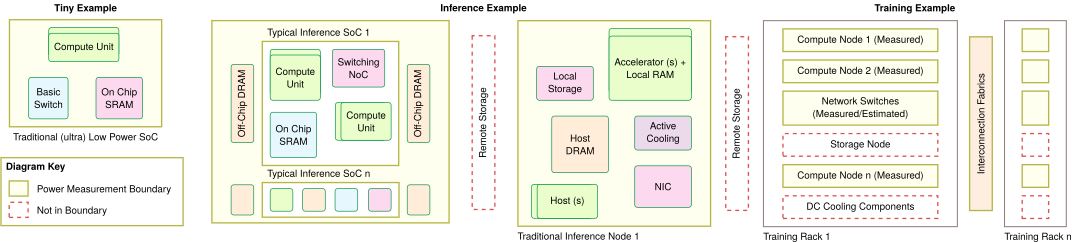
The three architectural tiers in figure 8 (Tiny Example, Inference Example, and Training Example) reflect distinct physical instrumentation points. In TinyML deployments, the entire low-power SoC, including compute cores, internal SRAM, and power management units, falls inside the boundary, measured directly at the DC power rail. Dedicated inference nodes expand this perimeter to include host CPUs, accelerator cards, PCIe buses, local storage, and on-chassis active cooling fans, while excluding remote storage networks. Multi-rack training deployments measure compute nodes and top-of-rack interconnect switches, but exclude centralized data center chillers, facility-level power distribution units (PDUs), and disaggregated storage clusters.
The excluded components can more than double the reported energy. Google measured the energy of the median text prompt served by its Gemini assistant under two boundaries (Elsworth et al. 2025). Counting only the active accelerators, on prompts served by its most efficient data centers, gave 0.10 Wh. Counting everything the service draws to answer that prompt gave 0.24 Wh, about 2.4× more. Of that total, the active accelerators drew 58 percent and the host CPUs and DRAM that feed them 25 percent; the remaining 17 percent went to machines held idle in reserve for traffic spikes and to facility overhead such as cooling and power conversion. An accelerator-only figure therefore understates what a deployed service consumes, and two figures measured under different boundaries are not comparable. Utilization also moves the figure, because the narrow measurement came from the most efficiently used machines. Open benchmark suites such as ML.ENERGY measure energy under realistic serving conditions so that their results reflect deployed utilization rather than an idealized run (Chung et al. 2025).
Elsworth, Cooper, Keguo Huang, David Patterson, Ian Schneider, Robert Sedivy, Savannah Goodman, Ben Townsend, et al. 2025. “Measuring the Environmental Impact of Delivering AI at Google Scale.” arXiv Preprint arXiv:2508.15734.
Chung, Jae-Won, Jeff J. Ma, Ruofan Wu, Jiachen Liu, Oh Jun Kweon, Yuxuan Xia, Zhiyu Wu, and Mosharaf Chowdhury. 2025. “The ML.ENERGY Benchmark: Toward Automated Inference Energy Measurement and Optimization.” Advances in Neural Information Processing Systems (NeurIPS), Datasets and Benchmarks Track.
Boroumand, Amirali, Saugata Ghose, Youngsok Kim, Rachata Ausavarungnirun, Eric Shiu, Rahul Thakur, Daehyun Kim, et al. 2018. “Google Workloads for Consumer Devices: Mitigating Data Movement Bottlenecks.” Proceedings of the Twenty-Third International Conference on Architectural Support for Programming Languages and Operating Systems, ASPLOS ’18, 316–31. https://doi.org/10.1145/3173162.3173177.
The measurement boundary determines which components are counted; workload composition determines where their energy is spent. On mobile devices running TensorFlow Mobile, data movement accounts for 57.3 percent of total inference energy (Boroumand et al. 2018), exposing why operation counts alone fail to predict power consumption; under the energy-movement principle (7), total energy depends on how many events of each kind occur and what each one costs, not on arithmetic alone. The worked example in notebook 12.4 decomposes MobileNetV2 inference energy to demonstrate how moving from FP32 to INT8 attacks both the memory-movement bottleneck and arithmetic switching costs.
Napkin Math 12.4: Why INT8 saves energy
Problem: Under the stated 45 nm component-energy model, how much does replacing FP32 with INT8 reduce MobileNetV2 weight-read and arithmetic energy?
Moving data costs far more energy than computing on it (principle 7, grounded in Horowitz’s energy estimates (Horowitz 2014)). Understanding why quantization reduces energy consumption requires decomposing energy into its physical sources. Two dominant factors determine inference energy: compute operations and memory access.
Narrower datatypes require less switching and storage energy per operation, and off-chip memory costs far more than either. In the 45 nm component model that Precision and energy tabulates (INT8 versus FP32 Energy per Operation), an 8-bit multiplier uses about 18.5× less energy than a 32-bit floating-point multiplier, and reading one byte from DRAM, about 160 pJ/byte, costs over 1,600× more than a register access (Horowitz 2014). Absolute values and ratios vary with circuit design and process technology.
Math: Component energy follows the energy corollary, with a load term \(\DataVolume \times \EnergyPerByteMoved\) (model bytes times DRAM energy per byte) and a compute term \(\Operations\times \EnergyPerOperation\) (operations times energy per operation). The FP32 terms sum as 2243 µJ + 2,220 µJ = 4,463 µJ; the INT8 terms sum as 561 µJ + 120 µJ = 681 µJ. Dividing the totals gives a 6.6× reduction under this simplified model.
Table 17 combines the two effects in a deliberately simplified MobileNetV2 model. It counts one DRAM read per weight and charges every cataloged FLOP at the listed multiplier energy, while excluding activation traffic, cache behavior, additions as a distinct cost, control overhead, and static power:
| Component | FP32 (14 MB) | INT8 (3.5 MB) | Savings |
|---|---|---|---|
| One weight read from DRAM | 2243 µJ | 561 µJ | 4× |
| Compute (600 MFLOP) | 2,220 µJ | 120 µJ | 18.5× |
| Total | 4,463 µJ | 681 µJ | 6.6× |
Systems insight: Within this simplified model, the weight read and the arithmetic contribute comparable FP32 energy (2243 µJ and 2,220 µJ), and INT8 reduces both, taking the total from 4,463 µJ to 681 µJ. The decomposition explains the physical mechanism behind potential savings, but battery-life or per-inference claims require controlled whole-device power measurements.
Horowitz, Mark. 2014. “1.1 Computing’s Energy Problem (and What We Can Do about It).” 2014 IEEE International Solid-State Circuits Conference Digest of Technical Papers (ISSCC), 10–14. https://doi.org/10.1109/isscc.2014.6757323.
Barroso, Luiz André, Urs Hölzle, and Parthasarathy Ranganathan. 2019. The Datacenter as a Computer: Designing Warehouse-Scale Machines. Synthesis Lectures on Computer Architecture. Springer International Publishing. https://doi.org/10.1007/978-3-031-01761-2.
Kim, Wonyoung, Meeta S. Gupta, Gu-Yeon Wei, and David Brooks. 2008. “System Level Analysis of Fast, Per-Core DVFS Using on-Chip Switching Regulators.” IEEE International Symposium on High-Performance Computer Architecture (HPCA), HPCA ’08, 123–34. https://doi.org/10.1109/hpca.2008.4658633.
Beyond individual server nodes, large-scale deployments introduce shared infrastructure that complicates boundary definition. In data centers, cooling systems and power delivery account for 20 to 30 percent of total facility electricity consumption (Barroso et al. 2019). This facility-level overhead is captured by power usage effectiveness (PUE): \[\text{PUE} = \frac{\text{Total Facility Energy}}{\text{IT Equipment Energy}}\] PUE values range from approximately 1.1 in hyperscale facilities using direct-to-chip liquid cooling to over 2.0 in legacy facilities relying on computer room air conditioning (Barroso et al. 2019). When an evaluation reports only server-plug energy, it excludes this facility multiplier. Furthermore, dynamic voltage and frequency scaling (DVFS) continuously modulates processor power and heat dissipation during execution (Kim et al. 2008), creating thermal feedback loops that alter the cooling overhead itself.
12.7.2 Battery and thermal benchmarking
Battery drain depends on total energy consumed over time rather than peak instantaneous power. Computational photography bursts consume multiple watts for hundreds of milliseconds during image capture, whereas background sensor processing must remain within a milliwatt-scale budget to deliver multi-day battery life. Characterizing battery impact requires measuring the total energy consumption \(\TotalEnergy = \int \DevicePower(\TimeInstant)\,d\TimeInstant\) across representative operational profiles, where \(\DevicePower(\TimeInstant)\) is the instantaneous power the device draws at time \(\TimeInstant\).
The dominant operational variable is the workload duty cycle \(\InferenceDutyCycle\), defined as the fraction of time the accelerator actively runs inference. For an active power draw \(\ActiveInferencePower\) and standby power draw \(\StandbyPower\), the average power is: \[\AveragePower= \InferenceDutyCycle \ActiveInferencePower+ (1 - \InferenceDutyCycle) \StandbyPower\] For intermittent workloads such as the camera trap waiting for motion (\(\InferenceDutyCycle\ll 0.01\)), standby power \(\StandbyPower\) and memory retention power dictate battery lifetime, making active inference efficiency secondary. For continuous pipelines like video analytics (\(\InferenceDutyCycle\approx 1.0\)), active inference energy \(\InferenceEnergy= \ActiveInferencePower\cdot \InferenceLatency\) dominates. Furthermore, elevated operating temperatures increase semiconductor leakage current, causing static power dissipation to climb as the device heats up. Benchmarking battery impact therefore requires measuring both active and standby power across the operational duty cycle while monitoring junction temperature over extended multi-minute runs.
Keyword spotting makes the point concrete. Run DS-CNN (Zhang et al. 2017), the MLPerf Tiny keyword-spotting reference at 20 MFLOP per inference, on an ESP32-S3-class microcontroller board with one inference per one-second audio window. At the board’s peak INT8 rate an inference takes about 8.3 ms, a duty cycle of about 0.8 percent, and costs about 3.3 mJ at the board’s 0.4 W active power. Between inferences the board idles at 50 mW. Average power is therefore about 52.9 mW, and 94 percent of it is spent waiting. A benchmark that reports only energy per inference describes the remaining 6 percent of the battery drain. Active energy would overtake the idle floor only if inference occupied more than about 11 percent of the time, and real kernels running below peak raise the active share without changing the conclusion. This is why always-on audio moves to dedicated low-power silicon whose idle draw is microwatts, and why a power benchmark for a duty-cycled device must specify the duty cycle along with the inference.
Zhang, Yundong, Naveen Suda, Liangzhen Lai, and Vikas Chandra. 2017. Hello Edge: Keyword Spotting on Microcontrollers.
12.7.3 Computational efficiency vs. power consumption
Power in CMOS logic is dynamic switching power plus static leakage power, and over the range where supply voltage tracks clock frequency, dynamic power grows roughly with the cube of frequency (Power and thermal management derives both). Two measurement consequences follow. A measured efficiency belongs to the operating point at which it was measured, because a few percent of clock frequency moves power far more than throughput, so a boost-clock burst and a sustained run report different efficiencies for the same chip. Leakage rises with temperature, so a warm device is less efficient than a cold one at the same clock, which is why the power protocol below requires a warm-up to the intended thermal state. Across hardware generations, computations per kilowatt-hour historically doubled approximately every 1.5 years, a long-run trend known as Koomey’s law (Koomey et al. 2011), so an efficiency comparison across devices must also state which generation each one represents.
Koomey, Jonathan, Stephen Berard, Marla Sanchez, and Henry Wong. 2011. “Implications of Historical Trends in the Electrical Efficiency of Computing.” IEEE Annals of the History of Computing 33 (3): 46–54. https://doi.org/10.1109/mahc.2010.28.
Wu, Hao, Patrick Judd, Xiaojie Zhang, Mikhail Isaev, and Paulius Micikevicius. 2020. “Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation.” arXiv Preprint arXiv:2004.09602 abs/2004.09602.
Gholami, Amir, Sehoon Kim, Zhen Dong, Zhewei Yao, Michael W. Mahoney, and Kurt Keutzer. 2021. “A Survey of Quantization Methods for Efficient Neural Network Inference.” arXiv Preprint arXiv:2103.13630 abs/2103.13630.
Because frequency scaling quickly hits TDP ceilings, system designers optimize efficiency across the Data, Algorithm, and Machine axes. On the algorithm and data side, reduced-precision arithmetic (INT8 or FP8) directly reduces the capacitance switched in the ALUs and compresses memory traffic across interconnect buses, potentially cutting dynamic energy when the chosen format preserves the required model quality (Jacob et al. 2018; Wu et al. 2020; Gholami et al. 2021). On the machine side, the energy-delay product (EDP) measures one trade-off between energy and completion time. Its minimum need not coincide with minimum energy or maximum throughput per watt. Battery-constrained devices and power-limited data centers must choose operating points against their own latency, throughput, and energy requirements, measuring leakage and whole-system power alongside switching power.
12.7.4 Standardized power measurement
General-purpose power benchmarks such as SPECpower_ssj2008 measure server power across stepped load levels (0 to 100 percent in 10 percent increments) using steady-state transactional workloads (Lange 2009). In contrast, ML workloads swing rapidly in power: instantaneous draw alternates between compute-bound matrix multiplications (where systolic arrays or Tensor Cores draw peak current) and memory-bound stalls or token transfers (where execution units stall waiting for DRAM or interconnect fetches).
Lange, Klaus-Dieter. 2009. “Identifying Shades of Green: The SPECpower Benchmarks.” IEEE Computer 42 (3): 95–97. https://doi.org/10.1109/mc.2009.84.
Characterizing these fluctuations requires calibrated physical instrumentation. Software interfaces such as Intel RAPL and NVIDIA NVML expose counters or telemetry with device-specific accuracy, update rates, and polling overhead. The instrument must match the measurement boundary and required uncertainty. MLPerf power protocols use external calibrated analyzers for inference systems, while training and HPC measurements can use validated node or power-distribution telemetry; Tiny measurements use instrumentation suited to low-power devices (Tschand et al. 2024).
Resolving an individual transient requires instrument bandwidth and internal sampling appropriate to its duration; a kilohertz log cannot resolve arbitrary microsecond kernel events. Total run energy instead depends on accurate integration over the matched measurement window, which an analyzer may perform internally at a different rate from its exported readings: \[\TotalEnergy = \int_{t_{\text{start}}}^{\MeasurementWindowEnd} \DevicePower(\TimeInstant) \, d\TimeInstant\] For a steady-state energy comparison, the harness separates initialization from the timed workload through three protocol stages:
- A warm-up phase runs unmeasured inferences until caches, buffers, and temperature reach the intended operating state.
- A sustained measurement window executes repeated inferences across minutes to average over microarchitectural phase shifts and thermal drift.
- Hardware-to-software synchronization aligns power and workload timestamps so integrated energy and completed requests cover the same window. Cold-start or intermittent deployments require additional measurements that include initialization, sleep, and wake-up costs.
Workload structure further alters the power profile. In low-batch Transformer execution, decode often has less weight reuse than prefill and can face a lower bandwidth ceiling; their measured power profiles depend on shapes, kernels, and operating policy. DLRM embedding lookups can make memory traffic a substantial energy contributor, which must be measured alongside dense computation and static power. Batch sizing creates another trade-off: larger batches amortize parameter reads over more inputs and can lower energy per inference, while also changing activation traffic, execution time, and instantaneous power. At the edge, the duty cycle governs the outcome through the duty-cycle average power of section 12.7.2, where the keyword-spotting case shows the idle floor setting battery life.
12.7.5 MLPerf power case study
MLPerf Power (Tschand et al. 2024) translates raw electrical measurements into standardized efficiency metrics: completed inferences per second per watt under a rigorously defined system boundary. This protocol applies uniform measurement principles across data center, edge, and tiny inference scenarios, where the binding constraint shifts from rack cooling and operating cost to battery runtime and microwatt energy harvesting.
Standardizing the boundary prevents misleading comparisons across architectural families. By specifying instrumentation, measurement boundaries, matched logging windows, and the applicable workload constraints, MLPerf Power makes efficiency results interpretable within the tested scenario.
Over successive benchmark submission rounds from 2021 to 2024, standardized measurements capture how architectural improvements, compiler optimizations, and lower-precision arithmetic translate into production efficiency gains. Tracking normalized energy efficiency (samples per joule) across eight submission cycles from v1.0 to v4.1, figure 9 charts diverging efficiency trajectories across seven distinct MLPerf Inference workloads.
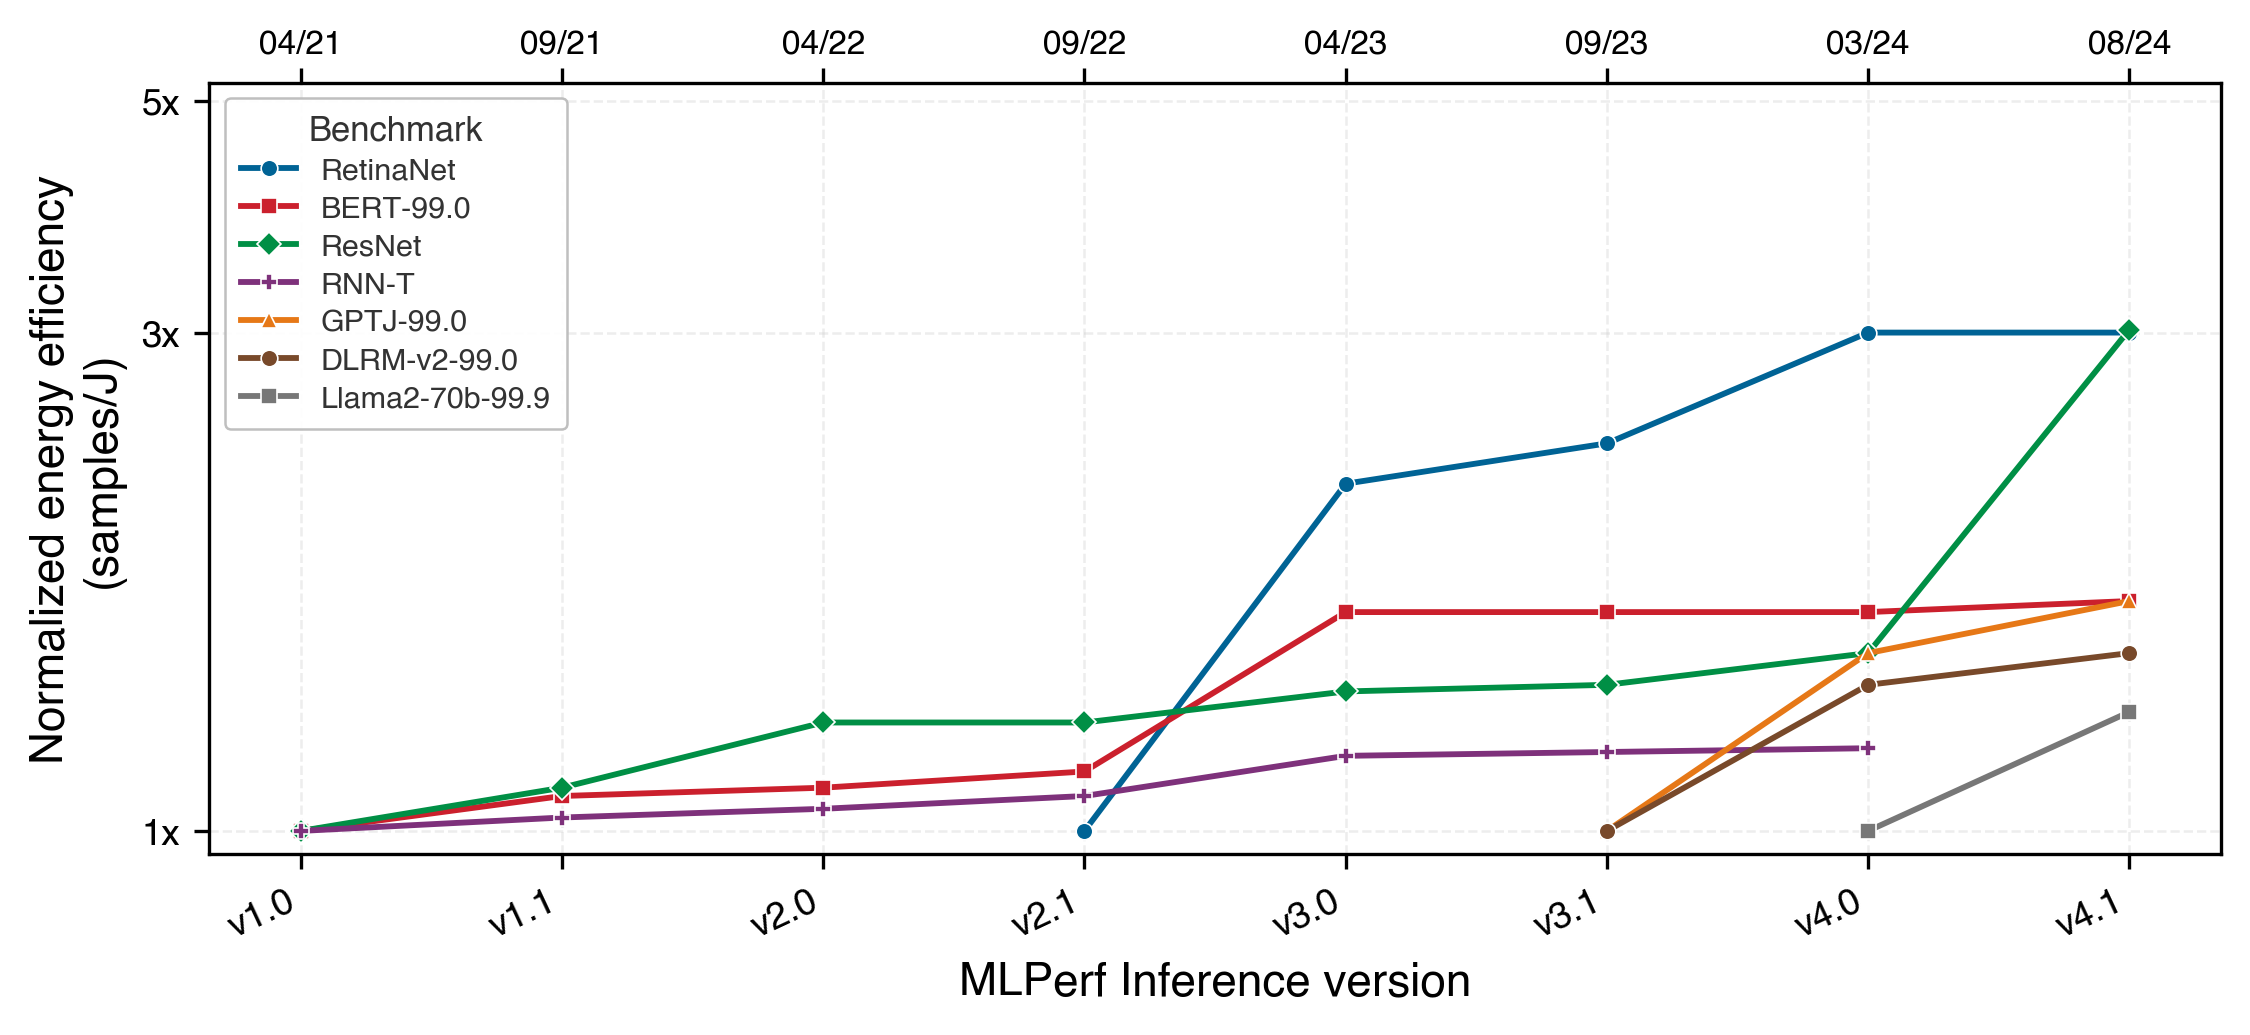
Tschand, Arya, Arun Tejusve Raghunath Rajan, Sachin Idgunji, Anirban Ghosh, Jeremy Holleman, Csaba Kiraly, Pawan Ambalkar, et al. 2024. “MLPerf Power: Benchmarking the Energy Efficiency of Machine Learning Systems from \(\mu\)Watts to MWatts for Sustainable AI.” 2025 IEEE International Symposium on High Performance Computer Architecture (HPCA), 1201–16. https://doi.org/10.1109/hpca61900.2025.00092.
RetinaNet and ResNet show the largest plotted gains, each reaching 3\(\times\) its initial normalized efficiency. BERT and GPT-J reach about 1.9\(\times\), while DLRM-v2 reaches about 1.7\(\times\), Llama 2 about 1.5\(\times\), and RNN-T about 1.3\(\times\). These trajectories combine changes in hardware, software, numerical formats, and submitted configurations. Static convolutional shapes can benefit from supported low-precision kernels and fusion; low-batch decoding and sparse embedding lookups often give memory improvements greater importance. The plotted ratios alone do not isolate how much each mechanism contributed.
Timing protocols and power instrumentation provide the raw data for benchmarking. Raw data alone, however, does not guarantee sound conclusions. Converting measurements into meaningful comparisons requires understanding the systematic sources of error, bias, and misalignment that can make even carefully collected benchmark numbers misleading.
Self-Check: Question
A vendor advertises an AI accelerator as delivering ‘\(10\text{ TOPS}\) at \(0.5\text{ W}\)’ from a core-only measurement, while a matched measurement of the same workload on the full deployed system shows \(4.5\text{ W}\) of active power at the wall socket. What benchmarking issue most directly explains the difference?
- The vendor drew an isolated power measurement boundary around the compute core silicon only, omitting DRAM interfaces, PCIe host transfers, voltage regulators, CPU preprocessing, and cooling fans
- The electrical wall outlet was defective and provided improper alternating current
- Power consumption in digital circuits is inherently non-deterministic and varies by \(10\times\) between runs
- The vendor measured power during sleep mode rather than active compute
Assume switching activity and capacitance stay fixed. An accelerator raises clock frequency by \(5\%\), and useful inference throughput also rises by \(5\%\), but doing so requires a \(15\%\) increase in supply voltage. Using the dynamic-power model \(P \propto V^2 f\), the dynamic power rises by about \(1.15^2 \times 1.05 \approx 1.389\) (\(38.9\%\)). What follows for dynamic performance per watt at this operating point in a power-constrained edge deployment?
- It is an optimal trade-off because throughput is always the only metric that matters
- It represents a severe dynamic energy-efficiency regression, reducing dynamic performance-per-watt to about \(0.756\) of baseline
- Performance-per-watt increases because higher frequency reduces static leakage
- The device will operate cooler because inferences finish \(5\%\) sooner
Explain why one instantaneous power reading during an ML inference workload produces misleading results, and describe how standardized protocols calculate total energy.
True or False: In standardized ML power benchmarking, measuring the power draw of the arithmetic compute units (ALUs and tensor cores) is sufficient because the energy required to read and write data from DRAM is negligible in comparison.
Order the following steps in an illustrative steady-state ML power measurement workflow from start to finish, where this protocol records an idle baseline before warm-up and then measures a matched active window:
- Integrate instantaneous power readings over the matched active measurement window (\(E = \int P(t) \, dt\)) and compute Joules per inference
- Establish the physical measurement boundary and connect a calibrated power analyzer to the appropriate measurement points
- Execute unmeasured warm-up iterations until the device achieves thermal equilibrium (steady-state junction temperature)
- Measure and record the baseline idle/quiescent power consumption while the system is waiting for requests
- Execute the synchronized inference benchmark workload while logging power over the matched measurement window
12.8 Benchmarking Best Practices
An inference stack that passes a steady-state lab run can still miss latency targets when production traffic arrives in bursts, or when the input mix shifts toward expensive examples. Training throughput, inference latency, and power efficiency each have established measurement protocols validated through MLPerf, but knowing what to measure is insufficient without understanding what benchmarks cannot capture and why this gap causes production deployments to violate their service-level objectives.
Benchmarks make simplifying assumptions that enable standardized comparison but diverge from production reality. Training suites freeze datasets and tightly specify randomness even though production data and retraining conditions evolve continuously, while inference suites emphasize a defined steady-state scenario even though production traffic arrives in bursts with variable sequence lengths, and power benchmarks control thermal environments where deployed accelerators instead face variable ambient temperatures and sustained thermal loads. Four categories of limitations (statistical, deployment-related, system design, and organizational) determine whether benchmark results translate to deployment success.
12.8.1 Statistical and methodological issues
A one-point accuracy drop on 1,000 test images or a 2 percent latency improvement between single benchmark runs can sit entirely inside sampling and system noise. Telling a genuine change from a fluke requires the same statistical apparatus for every benchmark in the chapter, from a kernel timing to an accuracy comparison.
To isolate run-to-run variability, benchmark protocols require repeated experimental trials across controlled pseudo-random seeds. The number of runs must satisfy explicit statistical-power targets, specifying the probability of detecting a stated real effect, rather than opportunistic sampling. Reporting must extend beyond single best-of-\(\RepeatedRunCount\) scores or isolated arithmetic means: reporting sample variance, standard deviations, or confidence intervals quantifies stability and establishes whether an observed speedup exceeds background system jitter. Without these controls, benchmarking yields misleading conclusions. In reinforcement learning, reported performance advantages frequently evaporate into the statistical noise of random weight initializations and environment dynamics (Henderson et al. 2018). Similarly, unstandardized evaluations of generative adversarial networks produce rank reversals across random seeds, demonstrating that uncharacterized variance undermines comparative claims (Lucic et al. 2018).
Lucic, Mario, Karol Kurach, Marcin Michalski, Sylvain Gelly, and Olivier Bousquet. 2018. “Are GANs Created Equal? A Large-Scale Study.” Advances in Neural Information Processing Systems (NeurIPS) 31.
Even when run-to-run execution variance is fully controlled, benchmarking encounters a structural constraint in the evaluation dataset itself: test-set measurement capacity. A test set operates as a measurement instrument with a finite resolution limit. Because accuracy on a finite sample is a binomial proportion, empirical scores carry intrinsic sampling variance that scales inversely with sample size. When an optimization alters accuracy by one or two percentage points, the sample size and paired pattern of disagreements determine whether the test can distinguish a genuine algorithmic effect from sampling fluctuation. As analyzed in the accompanying notebook, marginal accuracy scores on a thousand-sample test set are insufficient to establish the significance of a fine-grained difference without examining the paired outcomes.

At most 26 disagreements reveal a regression; the disagreement count decides.
Napkin Math 12.5: The statistical confidence trap
Problem: A baseline classifier scores 95 percent, while a compressed version scores 94 percent on the same 1,000 images. Does this one-point drop establish a regression?
Math:
Expected errors: The scores correspond to 50 errors and 60 errors. Under the baseline binomial model, the error count has a standard deviation of about 7 errors.
Difference interval (95 percent): The same-image comparison requires paired outcomes, which the two marginal scores do not supply. For comparison, suppose the models instead achieved these scores on independent test sets sampled from the same population. Let \(\EstimatedAccuracy_1\) and \(\EstimatedAccuracy_2\) denote their accuracy estimates, and let \(\EvaluationSampleCount\) be the number of images evaluated for each model. Under that independent-set assumption, the standard error of their difference is
\[ \operatorname{SE}(\EstimatedAccuracy_1-\EstimatedAccuracy_2) = \sqrt{\frac{\EstimatedAccuracy_1(1-\EstimatedAccuracy_1)}{\EvaluationSampleCount} + \frac{\EstimatedAccuracy_2(1-\EstimatedAccuracy_2)}{\EvaluationSampleCount}}. \]
The observed 1 percentage point difference has an approximate interval from -1 percentage point to 3 percentage points, which includes zero. Treated as independent samples, the one-point drop is indistinguishable from sampling noise. Pairing can change that verdict, because images that both models classify the same way cancel out of the comparison.
Paired test on the same images: The stated problem uses one test set, so the decisive evidence is where the two models disagree. Let \(\BaselineOnlyCorrectCount\) count images only the baseline classifies correctly and \(\CompressedOnlyCorrectCount\) count images only the compressed model classifies correctly. Images both models get right or both get wrong carry no information about which is better, and McNemar’s test (McNemar 1947) discards them. The scores fix the difference \(\BaselineOnlyCorrectCount- \CompressedOnlyCorrectCount\) at 10 (the compressed model’s extra errors) but not the sum. The test statistic, without continuity correction, is
\[ \McnemarTestStatistic= \frac{(\BaselineOnlyCorrectCount- \CompressedOnlyCorrectCount)^2}{\BaselineOnlyCorrectCount+ \CompressedOnlyCorrectCount}, \]
and the drop is significant at 95 percent when \(\McnemarTestStatistic\) exceeds 3.84. That happens only when the models disagree on at most 26 images.
Implication: The marginal scores cannot answer the question; the disagreement count decides it. If the compressed model’s 10 extra errors are nearly its only disagreements with the baseline, the paired test supplies evidence of a regression at the stated significance threshold. If the models disagree on many more images, the test leaves the same one-point gap unresolved. Nonsignificance does not establish equivalence or compliance with a permitted quality-loss tolerance. A benchmark report must therefore keep per-image outcomes, not only the two accuracies; the interval-based decision rule below separates an unresolved difference from a supported improvement.
Systems insight: A small test set limits what a benchmark can resolve. The test set, viewed as a measurement instrument, must be sized to match the precision of the change it is meant to detect. A single accuracy estimate alone needs about 1,825 images for ±1 percentage point precision, and that sample size does not by itself power a comparison between two models.
McNemar, Quinn. 1947. “Note on the Sampling Error of the Difference Between Correlated Proportions or Percentages.” Psychometrika 12 (2): 153–57. https://doi.org/10.1007/BF02295996.
The same paired logic governs timing comparisons. Suppose an engineer measures baseline and candidate mean latency under the same request mix, offered load, and timing boundary. Each experimental trial pairs a complete baseline run with a complete candidate run, following the same warm-up and thermal-state protocol and randomizing their execution order to limit drift bias. The comparison assumes that separately repeated run pairs are independent, with persistent background load or thermal drift controlled or accounted for. Requests within one run can share queues, caches, and thermal conditions and therefore cannot automatically count as independent trials. The report states the interval method and confidence level and uses the run pairs as the repeated observations. A request-latency p99 describes the slow end of the observed request population. It is neither a confidence interval for mean latency nor a measure of uncertainty in the estimated p99.
Suppose the report supplies an uncertainty interval for the mean latency reduction, defined as baseline latency minus candidate latency. If the interval extends from a negative reduction to a positive reduction, it includes no change, and the experiment cannot resolve whether the candidate is faster. That conclusion does not establish that the implementations perform identically. If a subsequent adequately controlled comparison yields an interval entirely above zero, it supports a latency reduction under the tested conditions. Deployment still requires a prespecified minimum useful reduction, reflecting the cost of adopting the candidate. An interval entirely above zero but extending below that threshold supports a gain without establishing that the gain justifies adoption; an interval entirely above the threshold supports both claims, provided the quality and resource gates also pass.
Two further issues undermine reliability even when runs are repeated and compared correctly. Incomplete problem coverage occurs when a benchmark exercises only a narrow operating point of a system. Controlled datasets such as CIFAR-10 (Krizhevsky 2009) constrain inputs to uniform, low-resolution images (\(32{\times}32\) pixels) with small per-image input footprints. This constrained input shape may exercise memory differently from production images, but the complete working set still depends on the model and batch size, and allocation or kernel-launch overheads remain. A model that achieves high accuracy and throughput on a uniform, downscaled benchmark can stall in deployment when exposed to variable image resolutions, arbitrary aspect ratios, and sensor noise that force frequent kernel recompilations or fallback execution paths.
Krizhevsky, Alex. 2009. Learning Multiple Layers of Features from Tiny Images. University of Toronto.
Statistical insignificance arises when evaluations rely on too few trials to distinguish algorithmic improvements from measurement noise, particularly when the evaluation medium introduces variance. Large language model evaluation exemplifies this vulnerability: whether scoring candidate generations against a reference via human preference ratings or an LLM-as-judge protocol, scores vary substantially based on prompt phrasing, judge model alignment, and response ordering. A reported two-point win can vanish under an alternative prompt template or judge configuration. Rigorous evaluation demands paired hypothesis tests and bootstrap confidence intervals over hundreds of independent prompt pairings. Omitting these confidence bounds obscures whether a reported margin reflects a genuine architectural advance or stochastic evaluation noise.
12.8.2 Reproducibility
Reproducibility studies have repeatedly shown that modest benchmark gains can disappear when random seeds, hardware, framework versions, or implementation details change (Henderson et al. 2018). The stochastic processes that section 12.4.2 identified as measurement noise interact, over a long training run, with hardware-specific behaviors (floating-point rounding, memory layout, compiler optimizations) to produce results that can vary meaningfully across environments.
Henderson, Peter, Riashat Islam, Philip Bachman, Joelle Pineau, Doina Precup, and David Meger. 2018. “Deep Reinforcement Learning That Matters.” Proceedings of the AAAI Conference on Artificial Intelligence 32 (1): 3207–14. https://doi.org/10.1609/aaai.v32i1.11694.
A deeper layer of non-determinism comes from the parallel hardware itself. Operations such as parallel atomic additions, used during gradient accumulation for sparse embeddings in models like Graph Neural Networks, execute in non-deterministic order across threads when concurrent updates target the same memory location. The resulting floating-point summation order changes across runs, and because floating-point addition is not associative (Reproducibility and system artifacts), a different order produces bit-for-bit different gradients even with identical inputs and seeds. Enforcing bit-exact reproducibility in these cases requires a deterministic reduction path, which can reduce training throughput, a direct trade-off between reproducibility and performance that benchmark protocols must explicitly address. Without explicit controls for all these sources of variability, benchmark numbers reflect a specific confluence of conditions rather than a system’s genuine capability.
MLPerf Training addresses this through standardized data preprocessing, target-quality rules, and repeated accepted runs that characterize stochastic variation (Mattson et al. 2020). The point is not merely to produce a fast run, but to show that the reported performance reflects system capability rather than a favorable combination of stochastic factors.
For a training benchmark, reproducibility is therefore the full run envelope, not the random seed alone. A credible report must preserve the model commit, dataset checksum, preprocessing pipeline, seed plan, framework and compiler versions, precision policy, batch schedule, hardware topology, thermal and power limits, and checkpoint behavior. It must also report the distribution of accepted runs rather than a single best run. Only then can the benchmark separate a real system improvement from a favorable interaction among software version, hardware state, and stochastic training path.
Reproducibility also limits comparisons across software environments. A compiler or library revision can change kernel tiling, memory access, and reduction order, so an unexplained version change is a second intervention in the experiment. The run envelope above must accompany the result; matching a model name and seed alone does not make two stacks equivalent.
12.8.3 System design challenges
Statistical rigor ensures that benchmark measurements are precise, but precise measurements of the wrong operational regime still lead to production failures. Benchmark suites must align with the physical constraints of deployment, and the mismatch is sharpest where a standardized scenario meets live serving traffic. Misalignment with real-world goals persists even when a standardized benchmark is measured correctly. Offline throughput and Server throughput answer different questions, and the Server scenario still specifies only one arrival distribution. A production trace with correlated bursts or a different input mix can produce a different queue and memory footprint. The experiment must state which operating conditions its conclusion covers, and production qualification tests those boundaries before release. The summary returns to these gaps as a release problem once model and data evaluation are in place.
Beyond deployment alignment, a further category of limitations stems directly from the physical hardware executing the workload. Accelerator behavior fluctuates with thermal conditions, operating system resource contention, and underlying microarchitectural topology.
Environmental controls must match the claim being tested. Fixed clocks, CPU affinity, and isolated memory allocations can reduce noise in a comparison of implementations, while a deployment test must retain the relevant contention and thermal policy. The sustained-state mechanisms in section 12.6.4 apply to servers as well as edge devices. A result obtained under tighter isolation supports an implementation comparison, but does not by itself establish production capacity.
The hardware lottery28 (Hooker 2021) compounds this physical variation by coupling algorithmic viability to specialized hardware support. Modern accelerators allocate most of their silicon area to dense matrix multiplication units (such as Tensor Cores or systolic arrays) backed by wide vector units and high-bandwidth memory hierarchies. Algorithmic architectures such as dense Transformers achieve high arithmetic intensity by reusing weights across batched tokens, sustaining a large fraction of peak theoretical FLOP/s. Conversely, architectures that rely on dynamic control flow, fine-grained sparsity, or graph message passing suffer from uncoalesced memory transactions and thread divergence, underutilizing available compute silicon. Algorithmic performance on a benchmark often reflects how naturally a model’s computation graph maps onto dominant accelerator execution units rather than intrinsic mathematical superiority. The lottery is how the bitter lesson shows up on a leaderboard. General methods win by riding growth in computation, but the computation that grows is the dense form the dominant accelerators supply, so the winning methods are also the ones shaped to fit it.
28 Hardware lottery: Coined by Hooker (2021) to describe how algorithmic success depends on alignment with available hardware and software. Transformer workloads benefit from dense matrix operations that map efficiently to modern accelerators, while graph neural networks and sparse mixture-of-experts models can be harder to evaluate when available silicon and software stacks favor dense kernels. Hardware-specific leaderboards therefore favor architectures aligned with the measured platform and may obscure alternatives that would fare differently under other hardware assumptions.
Hooker, Sara. 2021. “The Hardware Lottery.” Communications of the ACM 64 (12): 58–65. https://doi.org/10.1145/3467017.
↩︎ The bitter lesson, that general methods which scale with computation outrun hand-built structure, is established in The Bitter Lesson.
Hardware compatibility dependence introduces systematic biases when evaluating models across heterogeneous execution targets. An architecture optimized for GPU execution may underperform on an embedded CPU, DSP, or custom edge accelerator with differing vector widths, cache hierarchies, and quantization support. Across five hardware targets on a Google Pixel 4, figure 10 charts how the latency–accuracy Pareto frontier reshuffles between CPU float, CPU uint8, GPU, EdgeTPU, and DSP execution. The diagonal purple arrow links MobileNetV3 Large at roughly 75 percent top-1 accuracy, from approximately 20 ms on CPU float to 4.5 ms on the DSP. Multi-MAX reaches roughly 75 percent accuracy at 2.2 ms on EdgeTPU and 3.4 ms on DSP; its points at higher accuracy carry higher latency. Comparisons must therefore match both the model variant and the accuracy operating point. The shifted frontiers show why model selection requires measurements on the target execution path rather than a latency ranking inherited from another processor.
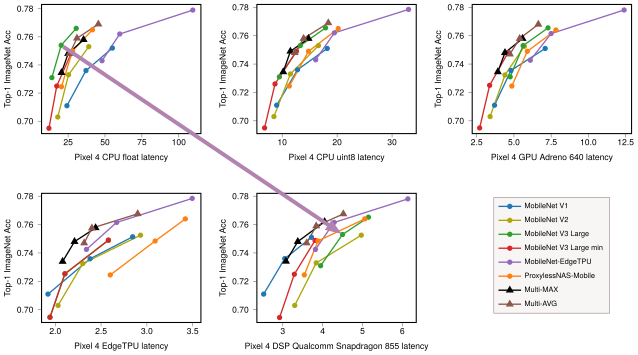
Chu, Grace, Okan Arikan, Gabriel Bender, Weijun Wang, Achille Brighton, Pieter-Jan Kindermans, Hanxiao Liu, Berkin Akin, Suyog Gupta, and Andrew Howard. 2021. “Discovering Multi-Hardware Mobile Models via Architecture Search.” 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW), 3016–25. https://doi.org/10.1109/cvprw53098.2021.00337.
Without benchmarking across heterogeneous hardware configurations, system designers risk selecting architectures solely because they conform to existing accelerator memory hierarchies and instruction sets. Evaluating models across diverse execution engines ensures that architectural decisions reflect computational efficiency rather than platform-specific co-design artifacts.
12.8.4 Organizational and strategic issues
The statistical, deployment, and hardware limitations concern measurement mechanics. A distinct category of failure comes from human incentives, because commercial procurement and academic leaderboards reward a high score more directly than a representative one, and those incentives bias how benchmarks are executed and reported.
Benchmark engineering
While the hardware lottery is an unintended consequence of hardware specialization, benchmark engineering is the deliberate practice of tailoring models or systems to exploit the idiosyncrasies of specific benchmark harnesses. This practice yields inflated performance metrics that collapse under production conditions.
Benchmark engineering occurs when developers tune hyperparameters, preprocessing pipelines, or execution paths specifically to maximize benchmark scores rather than generalizable performance. Legitimate optimization respects the run rules and declared workload; misleading benchmark engineering exploits restricted test conditions while making broader claims that the evidence cannot support. For example, an inference pipeline might hardcode input tensor dimensions and pad batches specifically to match the memory stride of an accelerator’s GEMM tile configuration, achieving peak throughput on fixed benchmark shapes while triggering costly kernel fallbacks and memory reallocations on arbitrary production inputs. Similarly, fine-tuning an evaluation pipeline to match the formatting biases of an automated evaluation model produces high leaderboard rankings that fail when interacting with unstructured human dialogue.
Procurement contracts and marketing claims reward exactly this tuning. It is Goodhart’s Law (section 12.1) acting on an organization rather than on a single team’s choice of metric.
To keep this benchmark gaming from corrupting procurement and engineering evaluations, standardized suites enforce strict run rules backed by reference implementations, submission audits, and division boundaries. Their rules forbid three classes of non-generalizable shortcuts:
- Precision truncation without disclosure: A compiler silently lowers numerical precision (for instance, executing intermediate activations in FP8 or INT8 instead of BF16) to inflate arithmetic throughput, without disclosing the reduced dynamic range or verifying whether the lower precision degrades numerical stability on production workloads.
- Work pruning and operator elimination: An execution engine exploits fixed benchmark test sets to skip operations required by general production inputs, such as bypassing dynamic padding removal, masking out-of-bounds tokens, or skipping input boundary validation.
- Benchmark fingerprinting: A runtime inspects input tensor dimensions, dataset hash fingerprints, or memory layout patterns to identify the benchmark suite, executing hardcoded, pre-tuned execution graphs and bespoke kernel configurations that are inaccessible to arbitrary user workloads.
MLPerf detects and deters these shortcuts through its submission divisions (defined in section 12.4.4), reference-equivalence checks, and peer-reviewed code audits. The closed division permits reproducible runtime optimizations, memory layout transformations (such as converting NCHW to NHWC), hardware-generalizable kernel fusion, and approved low-precision formats with documented, verifiable output quality, while non-generalizable shortcuts remain prohibited. Broader architectural alterations belong in the open division.
Bias and over-optimization
System engineers evaluating benchmark results must distinguish legitimate architectural gains from benchmark engineering, and several practices expose the difference. Submissions that publish complete compiler flags, kernel configurations, and execution traces let independent evaluators separate general efficiency gains from harness-specific tuning. Paired results from controlled benchmarks and uncurated production traces expose discrepancies in latency distributions and memory use, and evaluating across several independently maintained suites raises the barrier against overfitting, because an optimization tailored to the quirks of one harness rarely transfers to others.
Third-party verification adds accountability. Independent audits check whether reported speedups reproduce on identical hardware, as in MLPerf’s reference-versus-submission validation (section 12.8.4.1), and application-specific stress tests probe failure modes that static benchmarks omit, such as vision models under adverse imaging conditions or inference engines under skewed request traffic.
Benchmark evolution
Benchmarks are not static standards; they must evolve alongside model architectures and hardware capabilities. A benchmark that effectively separates system capabilities in one architectural generation becomes obsolete when models saturate its accuracy ceiling or when hardware innovations shift the primary system bottleneck. Stale benchmarks incentivize over-optimizing legacy computational kernels rather than advancing system efficiency.
Early deep learning benchmarks evaluated image classification and object detection on convolutional networks. As workloads expanded to large language models, recommendation systems, and generative AI, those vision benchmarks failed to capture long-context attention, autoregressive decoding, and sparse expert routing, and community benchmarks moved to language understanding (Wang et al. 2018, 2019) and foundation model capabilities (Liang et al. 2022). How saturation erodes a static benchmark’s discriminating power is a data question, taken up in section 12.9.2.
Wang, Alex, Yada Pruksachatkun, Nikita Nangia, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. 2019. “SuperGLUE: A Stickier Benchmark for General-Purpose Language Understanding Systems.” arXiv Preprint arXiv:1905.00537.
Benchmark evolution also expands the dimensions of measurement. While early benchmarks focused on throughput and accuracy, contemporary systems require multi-objective evaluation across energy efficiency, memory footprint, and tail latency under resource constraints. Scientific instruments provide a further constraint regime in figure 11. Its shaded “Fast ML for Science” envelope places high-throughput trigger pipelines outside typical mobile and IoT operating points (Duarte et al. 2022). The distance between these operating points is why a benchmark must match its application.
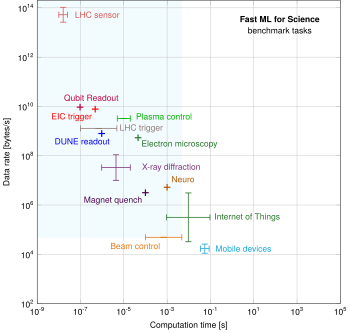
Duarte, Javier, Nhan Tran, Ben Hawks, Christian Herwig, Jules Muhizi, Shvetank Prakash, and Vijay Janapa Reddi. 2022. “FastML Science Benchmarks: Accelerating Real-Time Scientific Edge Machine Learning.” arXiv Preprint arXiv:2207.07958.
Managing benchmark evolution introduces a direct trade-off between longitudinal stability and architectural relevance. Benchmarks must remain fixed long enough to allow rigorous cross-generation hardware and software comparisons. If benchmarks change too frequently, tracking historical progress becomes impossible. Conversely, freezing a benchmark indefinitely leads to metric stagnation and over-specialization. Modern benchmarking consortia balance this trade-off by operating on fixed release cycles that introduce new representative workloads while deprecating obsolete suites.
Even the most rigorous system benchmarks validate only one dimension of deployment readiness. Achieving record throughput and energy efficiency on an MLPerf workload confirms that the hardware and runtime stack can deliver high computational efficiency, but it cannot determine whether the deployed model generalizes to real-world distributions or whether the underlying dataset represents the operational population. In the D·A·M taxonomy, hardware throughput (Machine) is a necessary foundation, but algorithmic fidelity (Algorithm) and dataset integrity (Data) must hold simultaneously. Validation therefore continues with the model and the data.
Self-Check: Question
An image classification model achieves \(95\%\) accuracy on the CIFAR-10 benchmark test set, but when deployed on a mobile robot operating in a warehouse, its accuracy drops to \(70\%\). Assume the warehouse images are verified to use the same class definitions and preprocessing contract but differ substantially in lighting, motion blur, and camera noise. Which benchmarking limitation most plausibly explains the gap?
- The mobile robot CPU lacked 64-bit floating-point registers
- The CIFAR-10 evaluation used too few random seeds during training
- Incomplete benchmark coverage and distributional narrowness: the benchmark dataset contained clean, centered, low-resolution images that failed to represent warehouse camera noise, lighting variations, and motion blur
- The benchmark harness executed the test set in the wrong order
Which set of governance and methodological rules does the MLPerf consortium implement to discourage and detect benchmark gaming through benchmark-specific shortcuts?
- Allowing submitters to create proprietary synthetic test datasets that are kept secret from competitors
- Permitting compilers to silently lower numerical precision below IEEE standards without reporting the accuracy impact
- Evaluating systems solely on peak theoretical arithmetic operations per second without measuring execution time
- Enforcing strict Closed Division rules (requiring reference-equivalent workloads under defined allowances), prohibiting benchmark detection code branching, and requiring open peer-review log audits
What is the core insight of the ‘Hardware Lottery’ concept (coined by Sara Hooker in 2021) regarding the relationship between ML benchmarks and research progress?
- An algorithmic research idea often succeeds not because it is universally superior, but because existing hardware accelerators and software compilers happen to be highly optimized for its specific computational pattern (such as dense GEMM)
- Hardware performance is purely random and cannot be measured with scientific accuracy
- Researchers should purchase computer hardware using randomized government lotteries
- Deep neural networks perform identically across all hardware architectures regardless of compiler support
True or False: If a benchmark measurement is conducted with flawless statistical rigor—using 1,000 independent runs, narrow confidence intervals, and controlled thermal states—its results are guaranteed to predict real-world production system performance.
The structural phenomenon where a machine learning algorithm achieves prominence primarily because specialized hardware and software compilers were already co-optimized for its execution pattern is called the ____.
Explain the fundamental tension between benchmark stability and benchmark evolution, and describe how benchmark consortia manage this trade-off.
12.9 Model and Data Evaluation
A compressed model running on accelerated hardware, such as the camera trap’s INT8 MobileNetV2, can still fail if it was trained on unrepresentative data. System benchmarks can confirm that hardware delivers promised training throughput, inference latency, and power efficiency, but hardware validation alone cannot ensure deployment success. The optimization pipeline from Part III also included model compression and data selection, each requiring its own validation. The framework’s other two dimensions address this gap: model benchmarks verify that compression preserved accuracy and essential model properties, while data benchmarks verify that training data enables robust generalization.
12.9.1 Model benchmarking
A pruned model can maintain ImageNet top-1 accuracy while losing robustness to adversarial inputs; a quantized model can preserve average-case performance while degrading on rare edge cases; a distilled model can match its teacher’s accuracy while losing confidence calibration. Model benchmarks validate whether compression preserved the properties that matter for deployment beyond top-line accuracy. Historically, benchmarks focused almost exclusively on accuracy, but compression makes multi-dimensional evaluation essential.
↩︎ Pruning, quantization, and distillation, the compression techniques these benchmarks validate, are established in Model Compression.
29 ResNet (residual network): Introduced by He et al. (2016), skip connections enabled deep residual networks and achieved 3.57 percent top-5 ImageNet error (ensemble), surpassing the estimated human error rate in the ImageNet challenge context (Russakovsky et al. 2015).
He, Kaiming, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. 2016. “Deep Residual Learning for Image Recognition.” 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR), 770–78. https://doi.org/10.1109/cvpr.2016.90.
Russakovsky, Olga, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, et al. 2015. “ImageNet Large Scale Visual Recognition Challenge.” International Journal of Computer Vision 115 (3): 211–52. https://doi.org/10.1007/s11263-015-0816-y.
Evaluating a compressed model requires comparing its behavior against an uncompressed reference baseline. In computer vision, standard network architectures establish the accuracy and resource baselines against which compression techniques are judged: a pruned or quantized model must demonstrate how much task accuracy it sacrifices for a given reduction in latency, memory footprint, or energy consumption. Canonical reference models such as ResNet-5029 serve as standard MLPerf workloads precisely because their moderate scale (25.6M parameters) and well-understood compute profile (8.2 GFLOP per image) make them sensitive to both hardware and software optimizations without requiring distributed multi-node setups (He et al. 2016; Mattson et al. 2020).
Accuracy metrics and their blind spots
The most common model metrics (accuracy, precision, recall, F1) each reveal different aspects of model behavior while hiding others, and understanding their blind spots is essential for compression validation. Top-\(\TopClassCount\) accuracy measures whether the correct label appears in the model’s top-\(\TopClassCount\) predictions. Top-1 accuracy is strict; top-5 is lenient. The gap between them reveals ranking behavior: a model with 75 percent top-1 but 95 percent top-5 accuracy often ranks the correct class among its leading candidates without placing it first. These rank statistics do not establish whether its confidence scores are calibrated. For deployment, the acceptable gap depends on whether downstream systems can use ranked predictions or require single answers.
Precision and recall matter when classes are imbalanced or errors have asymmetric costs (Sokolova and Lapalme 2009). A camera-trap classifier with 99 percent accuracy might have 10 percent recall on a rare species (catching only one in 10 frames that contain it), an unacceptable outcome despite high accuracy. Precision (the fraction of predicted positives that are correct) and recall (the fraction of actual positives identified) expose failures that aggregate accuracy conceals.
Sokolova, Marina, and Guy Lapalme. 2009. “A Systematic Analysis of Performance Measures for Classification Tasks.” Information Processing &Amp; Management 45 (4): 427–37. https://doi.org/10.1016/j.ipm.2009.03.002.
Buolamwini, Joy, and Timnit Gebru. 2018. “Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification.” Conference on Fairness, Accountability and Transparency, 77–91.
Aggregate metrics also conceal subgroup failures. A model achieving 95 percent overall accuracy might achieve 60 percent on a critical demographic subgroup. The Gender Shades project (Buolamwini and Gebru 2018) revealed commercial gender-classification systems for facial analysis performing substantially worse on darker-skinned women than on lighter-skinned men, a disparity invisible to aggregate benchmarks. Disaggregated evaluation across deployment-relevant subgroups is essential.
↪ Disaggregated evaluation as a release gate, with the slices, metrics, and thresholds that decide whether a model ships, is developed in Measure: Fairness criteria as release gates.
Confidence calibration
For many deployment scenarios, how confident the model is matters as much as what it predicts. A well-calibrated30 model’s confidence scores correspond to actual correctness probability: among 100 predictions made with 80 percent confidence, about 80 should be correct in expectation.
30 Calibration: From Arabic qalib (a mold for casting metal) via Latin calibrare, originally describing the adjustment of measuring instruments against known standards. In ML, calibration ensures predicted probabilities match empirical frequencies; Guo et al. (2017) formalize this concern for modern neural networks and show that temperature scaling is a simple effective post-hoc correction. The etymology is apt: just as an uncalibrated instrument produces precise but inaccurate measurements, an uncalibrated model produces confident but unreliable predictions, causing downstream systems that threshold on confidence scores to make systematically wrong decisions.
Guo, Chuan, Geoff Pleiss, Yu Sun, and Kilian Q. Weinberger. 2017. “On Calibration of Modern Neural Networks.” International Conference on Machine Learning (ICML) 70: 1321–30.
Calibration failures create severe operational hazards in automated pipelines. An overconfident model automates catastrophic errors that it should defer to human review (for example, reporting 95 percent confidence but failing 30 percent of the time). Conversely, an underconfident model floods manual review queues with decisions it could safely automate (reporting 60 percent confidence while being correct 98 percent of the time).
To quantify calibration across a dataset, predictions are partitioned into \(\CalibrationBinCount\) confidence bins \(\text{bin}_1, \text{bin}_2, \dots, \text{bin}_{\CalibrationBinCount}\) (such as ten intervals of width 0.1 from 0 to 1). For each \(\text{bin}_\CalibrationBinIndex\), the evaluator computes the empirical accuracy \(\text{acc}(\text{bin}_\CalibrationBinIndex)\) (the fraction of correct predictions in that bin) and the average predicted confidence \(\text{conf}(\text{bin}_\CalibrationBinIndex)\). Expected calibration error (ECE) (Pakdaman Naeini et al. 2015) measures the weighted average difference between confidence and accuracy in equation 4: \[\text{ECE} = \sum_{\CalibrationBinIndex=1}^{\CalibrationBinCount} \frac{|\text{bin}_\CalibrationBinIndex|}{\EvaluationSampleCount} \left| \text{acc}(\text{bin}_\CalibrationBinIndex) - \text{conf}(\text{bin}_\CalibrationBinIndex) \right| \tag{4}\] where \(\EvaluationSampleCount\) is the total sample count and \(|\text{bin}_\CalibrationBinIndex|\) is the sample count in bin \(\CalibrationBinIndex\). A measured \(\text{ECE} = 0\) means confidence and accuracy agree within the chosen finite-sample bins. Population calibration implies agreement in expectation; a zero estimate does not prove calibration at every confidence level or on another distribution.
Pakdaman Naeini, Mahdi, Gregory Cooper, and Milos Hauskrecht. 2015. “Obtaining Well Calibrated Probabilities Using Bayesian Binning.” Proceedings of the AAAI Conference on Artificial Intelligence 29: 2901–7. https://doi.org/10.1609/aaai.v29i1.9602.
Compression frequently disrupts calibration even when preserving aggregate accuracy, a central concern when validating quantization techniques from Numerical Precision: Changing How Values Are Stored. When floating-point weights and activations are quantized to 8-bit integers, discrete rounding alters the numerical geometry and relative separation of final-layer logits. Often, headline top-1 accuracy barely moves, but the model becomes severely overconfident, assigning extreme probabilities to inputs where it is genuinely uncertain. Post-hoc techniques such as temperature scaling can improve calibration when fitted on separate calibration data and evaluated on an untouched representative holdout (Guo et al. 2017).
Compression benchmarks
Neural network compression (pruning, quantization, knowledge distillation, and architecture optimization) requires specialized benchmarks because compression reshapes the trade-off landscape: every byte saved or operation eliminated must be weighed against potential accuracy loss and hardware compatibility. The most basic compression metric is raw size reduction: parameter count, memory footprint in bytes, and compressed storage requirements. Size alone, however, is misleading. On ImageNet, MobileNetV2 achieves approximately 72 percent top-1 accuracy with 3.5M parameters vs. ResNet-50’s 76 percent accuracy with 25.6M parameters, about 7.3× fewer parameters at comparable accuracy (Sandler et al. 2018; He et al. 2016).
Li, Hao, Asim Kadav, Igor Durdanovic, Hanan Samet, and Hans Peter Graf. 2017. “Pruning Filters for Efficient ConvNets.” International Conference on Learning Representations (ICLR).
Pruning benchmarks must distinguish structured from unstructured sparsity, because they produce qualitatively different results on real hardware, as the storage and execution break-even of Storage and execution break-even shows. Structured pruning yields smaller dense operations that conventional kernels exploit (Li et al. 2017). Unstructured pruning can reach very high sparsity but realizes speedups only with specialized sparse computation support, so protocols must specify hardware platform and software implementation (Han et al. 2015; Gale et al. 2019).
Quantization benchmarks evaluate precision reduction across data types. In the illustrative MobileNetV2 scenario, INT8 reduces raw weight storage by 4\(\times\) and the assumed latency values yield the speedup in example 12.3; realized performance depends on the hardware and implementation. The precision-accuracy trade-off (Jacob et al. 2018) is worked in lighthouse 12.3 and the energy implications in section 12.7.1. Mixed-precision assignment, which keeps sensitive layers at FP16 while computation-heavy layers use INT8 or INT4, multiplies the configurations a benchmark must name. Knowledge distillation (Knowledge distillation) adds a smaller student whose benchmark must verify that it generalizes rather than merely memorizing the teacher’s outputs (Hinton et al. 2015).
Acceleration factors vary across hardware platforms because sparse models, reduced-precision models, and efficient architectures need compatible kernels, memory layouts, and accelerator support. Current benchmark suites like MLPerf focus primarily on standardized reference models, while production deployments often use compressed or hardware-specific variants. A compression report must therefore name its representation and execution path before an efficiency-quality comparison can establish whether the variant is deployable.
Compression validation: The efficiency-quality frontier
A compression report identifies the representation and hardware path, but deployment acceptance requires deciding whether their measured gains justify changes in model behavior. Size, latency, and energy improvements must be evaluated against the quality properties and limits the application depends on.
Pareto frontier31 evaluation (principle 5) determines whether a compressed model represents a good trade-off. Plotting accuracy against the target efficiency metric (latency, model size, energy) reveals the trade-off frontier. Models on the Pareto frontier cannot improve one metric without degrading the other; models below the frontier are dominated by better alternatives.
31 Pareto frontier: Named after economist Pareto (1896), the frontier contains all solutions where improving one objective requires degrading another. In compression benchmarking, the trade-off between adjacent candidates must be interpreted using the named axes and units. A candidate is dominated when another is at least as good on every objective and strictly better on one; frontier membership still does not establish that deployment thresholds are met.
Pareto, Vilfredo. 1896. Cours d’économie Politique. F. Rouge.

A dominated model is matched or beaten on both accuracy and latency by a frontier model.
Han, Song, Jeff Pool, John Tran, and William J. Dally. 2015. “Learning Both Weights and Connections for Efficient Neural Networks.” Advances in Neural Information Processing Systems 28 (NeurIPS 2015), 1135–43.
Gale, Trevor, Erich Elsen, and Sara Hooker. 2019. “The State of Sparsity in Deep Neural Networks.” arXiv Preprint arXiv:1902.09574.
Hinton, Geoffrey, Oriol Vinyals, and Jeff Dean. 2015. “Distilling the Knowledge in a Neural Network.” arXiv Preprint.
Different compression techniques make different efficiency-quality trade-offs: quantization reduces precision while often preserving aggregate accuracy (Jacob et al. 2018), pruning induces sparsity while retaining varying levels of test performance (Han et al. 2015; Gale et al. 2019), and distillation transfers knowledge from a larger teacher or ensemble into a smaller model (Hinton et al. 2015). Because these aggregate results do not establish preserved calibration or tail behavior, validation must evaluate those properties directly (Guo et al. 2017).
Evaluating calibration during compression requires a standardized protocol. Expected calibration error (ECE) compares predicted confidence with empirical accuracy, but it has no universal thresholds. The metric depends on the binning scheme, bin count, sample size, and prediction distribution. A benchmark protocol must therefore freeze the estimator and evaluate degradation relative to the uncompressed baseline under a fixed task tolerance.
Pareto optimality identifies nondominated choices, but it does not establish that any choice clears the deployment’s absolute quality floor. Acceptable degradation depends on deployment context: a 2 percent accuracy drop might be acceptable for a recommendation system where users tolerate imperfect suggestions, but unacceptable for medical diagnosis where every false negative carries severe consequences. Production acceptance gates must define absolute accuracy thresholds before compression, evaluating aggregate accuracy, calibration stability, and deployment-critical slices simultaneously. The MobileNetV2 lighthouse makes this multi-dimensional validation protocol concrete.
Lighthouse 12.3: MobileNetV2 INT8 compression
Returning to lighthouse 12.1, consider an illustrative validation protocol for INT8 quantization, grounded in MobileNetV2’s architecture (Sandler et al. 2018) and post-training quantization practice (Jacob et al. 2018). The values in table 18 are assumed. For this example, acceptance permits less than one percentage point of loss on either top-one or top-five accuracy and requires no regression in ECE or critical edge-case accuracy under the same evaluation protocol:
Precompression baseline: MobileNetV2 achieves 71.8 percent top-1 accuracy on ImageNet at 3.5M parameters (14 MB FP32).
In table 18, aggregate accuracy barely changes after INT8 quantization to 3.5 MB, but calibration error and edge-case accuracy reveal substantial degradation. The INT8 model’s ECE rises from 0.031 to 0.089, failing this example’s no-regression criterion under the fixed ECE protocol.
| Metric | FP32 | INT8 | Acceptable? |
|---|---|---|---|
| Top-1 accuracy | 71.8% | 70.9% | ✓ (0.9 pp drop; below 1 percentage-point threshold) |
| Top-5 accuracy | 91% | 90.4% | ✓ (below the stated accuracy-loss threshold) |
| Calibration ECE | 0.031 | 0.089 | No (degraded) |
| Edge-case accuracy | 68.2% | 61.4% | No (drop of 6.8 pp) |
Edge-case definition: Images with \(>\) 50 percent occlusion, \(<\) 100 lux lighting, or \(>\) 30° rotation from training distribution (approximately 5 percent of real-world inputs).
What this reveals: Under these assumptions, average-case accuracy looks acceptable (0.9 percentage-point drop), but calibration degrades and edge-case accuracy drops 6.8 percentage points. If the deployment uses confidence thresholds (for example, “only act if confidence > 85 percent”) or encounters many edge cases (unusual lighting, partial occlusions), INT8 MobileNetV2 could fail despite passing aggregate benchmarks.
Fix: Evaluate temperature scaling as a post-hoc calibration candidate (Guo et al. 2017). Fit a positive scalar \(\CalibrationTemperature\) on separate calibration data to divide logits before softmax: \(\text{softmax}(\OutputLogit_i/\CalibrationTemperature)\). Validate on an untouched holdout. This rescaling preserves the top-one ranking, so edge-case classification errors require separate diagnosis of quantization and data coverage, followed by correction and testing on reserved edge-case examples.
Jacob, Benoit, Skirmantas Kligys, Bo Chen, Menglong Zhu, Matthew Tang, Andrew Howard, Hartwig Adam, and Dmitry Kalenichenko. 2018. “Quantization and Training of Neural Networks for Efficient Integer-Arithmetic-Only Inference.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 2704–13. https://doi.org/10.1109/cvpr.2018.00286.
Sandler, Mark, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, and Liang-Chieh Chen. 2018. “MobileNetV2: Inverted Residuals and Linear Bottlenecks.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 4510–20. https://doi.org/10.1109/cvpr.2018.00474.
Frankle, Jonathan, and Michael Carbin. 2019. “The Lottery Ticket Hypothesis: Finding Sparse, Trainable Neural Networks.” International Conference on Learning Representations (ICLR).
Pruning trade-offs are also nonlinear. Iterative pruning finds subnetworks that match the dense network’s accuracy up to a critical sparsity and degrade sharply beyond it (Frankle and Carbin 2019), the evidence behind the lottery ticket hypothesis of Lottery ticket hypothesis (optional depth). Compression validation must therefore establish empirical trade-off curves for each specific model and architecture, identifying where the model sits on the Pareto frontier and whether further pruning yields hardware efficiency or merely degrades accuracy.
Large language model benchmarks
The compression evaluation framework applies cleanly when the task has a stable label, such as classification accuracy, detection mAP, or segmentation IoU. Large language models break that pattern. A team can choose a model because it scores well on a public benchmark, then discover in deployment that the model recognizes multiple-choice facts but cannot generate a grounded answer, responds too slowly for an interactive product, or produces confident unsafe text that the benchmark never stressed. LLM benchmarking therefore starts by naming the deployment failure that a score is meant to rule out.
The metric taxonomy in table 19 organizes evaluation around those failure modes rather than leaderboard rankings. Its rows use Massive Multitask Language Understanding (MMLU),32 HELM (Holistic Evaluation of Language Models),33 and perplexity34 as examples of scores that answer distinct deployment questions, while the responsiveness row is measured as time to first token and time per output token, defined with the other inference metrics in section 12.6.2.2:
32 MMLU (massive multitask language understanding): Introduced by Hendrycks et al. (2020) with 15,908 multiple-choice questions across fifty-seven subjects. MMLU’s benchmarking limitation is its format: multiple-choice recognition is not the same task as open-ended generation, so an MMLU score should not be read as direct evidence that a model can produce grounded free-form answers in production.
Hendrycks, Dan, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, and Jacob Steinhardt. 2020. “Measuring Massive Multitask Language Understanding.” arXiv Preprint.
33 HELM (holistic evaluation of language models): Stanford’s 2022 evaluation framework tested a broad set of models across seven dimensions (accuracy, calibration, robustness, fairness, bias, toxicity, efficiency) (Liang et al. 2022). HELM’s contribution is methodological: by evaluating models that score similarly on accuracy but diverge on calibration or toxicity, it demonstrates that single-metric leaderboards systematically hide failure modes that matter for production deployment.
Liang, Percy, Rishi Bommasani, Tony Lee, Dimitris Tsipras, Dilara Soylu, Michihiro Yasunaga, Yian Zhang, et al. 2022. “Holistic Evaluation of Language Models.” arXiv Preprint arXiv:2211.09110.
34 Perplexity: From Latin perplexus (entangled); in information theory, \(2^{\ShannonEntropy(\NextTokenDistribution)}\) where \(\ShannonEntropy\) is entropy. A perplexity of 10 means the model is “10-way confused” on average. The systems consequence is interpretive rather than direct memory accounting: perplexity measures held-out next-token prediction on a corpus, while serving memory pressure is governed by context length, batch size, model shape, and decoding state; KV-cache management is a separate serving problem (Kwon et al. 2023).
Kwon, Woosuk, Zhuohan Li, Siyuan Zhuang, Ying Sheng, Lianmin Zheng, Cody Hao Yu, Joseph Gonzalez, Hao Zhang, and Ion Stoica. 2023. “Efficient Memory Management for Large Language Model Serving with PagedAttention.” Proceedings of the 29th Symposium on Operating Systems Principles, 611–26. https://doi.org/10.1145/3600006.3613165.
| Deployment failure to rule out | Metric or benchmark family | What the score reveals | What the score cannot prove |
|---|---|---|---|
| The model recognizes facts poorly | MMLU (Massive Multitask Language Understanding) | Broad factual and disciplinary knowledge across fifty-seven subjects, with scores interpretable against chance-level multiple-choice performance | Whether the model can generate grounded open-ended answers rather than choose among multiple-choice options |
| The model is capable but unsafe | HELM (Holistic Evaluation of Language Models) | Accuracy alongside calibration, robustness, fairness, bias, toxicity, and efficiency | Whether one aggregate score captures the deployment risk; a model can be strong on accuracy and weak on calibration, safety, cost, or prompt stability |
| The model predicts its corpus well | Perplexity | Held-out next-token prediction on the same corpus; a perplexity of 10 means the model is “10-way confused” on average | Whether generated answers are helpful, safe, or grounded outside that corpus |
| The model feels slow in use | First-token latency, inter-token latency, and token throughput | Prompt-processing delay before generation starts and decode speed after generation begins | Whether a single throughput number hides poor interactive responsiveness, especially when batching improves throughput but worsens first-token latency |
A final failure mode is that a benchmark score may reflect training-data memorization rather than general capability. Benchmark contamination is especially difficult to audit in LLMs because web-scale pretraining corpora may contain benchmark questions, inflating scores through memorization rather than skill (Xu et al. 2024). Leakage detection reframes this risk as something benchmark designers can test for rather than merely suspect. Temporal holdouts use content published after the training cutoff, dynamic benchmarks generate fresh instances continuously, and contamination tests check whether the model recalls verbatim benchmark phrasing. These techniques keep the benchmark aligned with the deployment question instead of rewarding pretraining exposure to the evaluation set.
Xu, Ruijie, Zengzhi Wang, Run-Ze Fan, and Pengfei Liu. 2024. “Benchmarking Benchmark Leakage in Large Language Models.” arXiv Preprint arXiv:2404.18824.
12.9.2 Data benchmarking
Model benchmarks validate whether compression preserved model quality. Model quality, however, depends on the data alongside the architecture and training procedure, and that dependency creates a failure mode that neither system nor model benchmarks can see. A perfectly preserved model trained on biased or unrepresentative data can still fail in production. Data benchmarks validate whether the efficiency strategies from Data Selection (active learning, curriculum design, data augmentation, and synthetic data generation) produced training sets that enable reliable deployment. This is often the last validation to fail and the hardest to diagnose: a model achieving excellent accuracy on held-out test data may collapse on production inputs that the training data never adequately represented.
Within the D·A·M taxonomy, optimizing the Algorithm and the Machine cannot compensate for structural deficiencies in the Data. An accelerator cluster operating at peak arithmetic intensity only computes incorrect representations faster when training distributions are defective. A data benchmark therefore begins with an operational protocol rather than an aggregate score. The protocol defines the deployment slice the model must serve, reserves a leakage-resistant holdout, verifies duplicate and near-duplicate separation across partitions, sets minimum coverage for rare classes and subgroups, audits label quality, and establishes drift thresholds that determine when the benchmark no longer represents production. Only after those gates are explicit do aggregate metrics become interpretable.
Coverage metrics
The first question data benchmarking must answer is whether the training distribution covers the operational domain the model will encounter in production. Generalization to poorly represented input regimes is uncertain and requires direct evaluation; the mechanisms through which training coverage fails are often subtle.
Class balance is the most apparent failure mode. In a camera-trap dataset where 99 percent of frames are empty or show common species and 1 percent show the rare species the study exists to count, a degenerate model that predicts the majority class unconditionally achieves 99 percent accuracy while failing its operational purpose. Mitigating severe class imbalance requires loss reweighting, targeted oversampling, or decision threshold calibration. More insidious is subgroup imbalance within classes: a dataset may have balanced positive and negative classes in the aggregate, yet draw negative examples disproportionately from a specific demographic cohort or geographic region. Aggregate accuracy metrics mask these systematic localized failures. When systems interact with human populations, auditing representation across demographic dimensions (such as age, geography, or dialect) is essential, though missing or noisy demographic metadata frequently complicates detection.
Feature coverage extends beyond discrete class labels into the continuous space of operational variations. While class balance is verified directly from label statistics, feature coverage requires mapping the physical parameters of the deployment environment. A vision pipeline trained exclusively on daytime captures fails under low-light sensor noise; a voice processing pipeline trained on clean studio signals degrades under acoustic reverberation and ambient noise. These environmental variations (differing sensor hardware, lighting conditions, and rare operational edge cases) fall outside discrete label distributions. Benchmarking feature coverage therefore requires specifying concrete bounds on the input space alongside domain experts before evaluating model performance.
Quality metrics
Even when a training dataset spans the operational domain, annotation errors corrupt the supervisory signal. Label errors, which average about 3 percent across ten canonical test sets and approach 6 percent on ImageNet’s validation set (Northcutt et al. 2021), do not act as benign noise. Supervised optimization treats incorrect labels as ground truth. When an evaluation set contains corrupted labels, a model that learns the true underlying distribution is penalized, while a model that memorizes the annotation artifacts receives an inflated score.
Northcutt, Curtis G., Anish Athalye, and Jonas Mueller. 2021. “Pervasive Label Errors in Test Sets Destabilize Machine Learning Benchmarks.” arXiv Preprint arXiv:2103.14749 34: 19075–90. https://doi.org/10.48550/arxiv.2103.14749.
For small corpora, manual audits over stratified random samples provide baseline error estimates. At scale, confident learning identifies label errors algorithmically by estimating the joint distribution of noisy annotations and true latent labels using out-of-sample predicted probabilities. When a model consistently assigns high confidence to a class that conflicts with the assigned label, the discrepancy isolates candidate annotation errors from typical optimization uncertainty. Flagging these candidates enables targeted relabeling or filtering, circumventing the prohibitive cost of exhaustive human review.
Inter-annotator agreement measures consistency across annotators prior to model training. The statistics are the ones data engineering already uses to monitor label quality in production; a data benchmark applies them once, to certify the evaluation set itself. Cohen’s kappa for two raters and Fleiss’ kappa for multiple raters quantify agreement above chance expectation (Cohen 1960; Fleiss 1971). When agreement metrics fall below established thresholds on tasks with objective ground truth, the failure points to ambiguous labeling taxonomies, rater fatigue, or inconsistent guidelines. While Landis and Koch’s qualitative kappa bands provide a historical reference (Landis and Koch 1977), production pipelines require agreement thresholds calibrated directly to application-specific risk tolerance.
Cohen, Jacob. 1960. “A Coefficient of Agreement for Nominal Scales.” Educational and Psychological Measurement 20 (1): 37–46. https://doi.org/10.1177/001316446002000104.
Fleiss, Joseph L. 1971. “Measuring Nominal Scale Agreement Among Many Raters.” Psychological Bulletin 76 (5): 378–82. https://doi.org/10.1037/h0031619.
Landis, J. Richard, and Gary G. Koch. 1977. “The Measurement of Observer Agreement for Categorical Data.” Biometrics 33 (1): 159–74. https://doi.org/10.2307/2529310.
↩︎ Cohen’s kappa, its chance-agreement correction, and label quality drift are established in Label quality drift.
The structural form of label noise determines its downstream impact. Random label noise dilutes gradient signals across classes, increasing sample complexity but rarely teaching coherent false representations. In contrast, systematic errors, such as consistently mislabeling an underrepresented subclass or coupling a label with an environmental artifact, inject structured bias into model weights. If images of wolves photographed against snow are consistently labeled as dogs, the model learns to associate snow with the target class. In the presence of systematic label error, collecting more training data under the same labeling protocol does not correct the bias; it merely reinforces the spurious association with higher parameter certainty.
Distribution alignment
Data benchmarking must ultimately evaluate whether a model generalizes from training conditions to deployment environments. Standard evaluation protocols assume that training, validation, and test splits are independent and identically distributed (i.i.d.). In production systems, this assumption fails routinely: temporal drift alters consumer behavior, sensor degradation shifts hardware characteristics, and geographic expansion introduces unmodeled subpopulations. When the i.i.d. assumption breaks down, held-out validation accuracy may become a poor predictor of operational performance. The direction and size of the change depend on the shifted population. A finite evaluation certifies behavior only on the population it sampled, and only within the uncertainty its sample size allows; that limit is the verification gap (principle 9).
This train-to-production alignment gap is quantified systematically by the WILDS35 benchmark (Koh et al. 2021), which evaluates models across distribution shifts spanning hospital systems, camera trap locations, and satellite passes. On Camelyon17-WILDS, the reported ERM baseline achieved 93.2 percent in-distribution average accuracy and 70.3 percent out-of-distribution average accuracy across unseen clinical sites. This performance drop occurs despite holding the architecture, hyperparameters, and training compute constant, demonstrating a distribution-dependent performance gap for that fixed model and training procedure. The comparison does not isolate which capacity, representation, or data changes would close it.
35 WILDS: Stanford’s 2021 benchmark of ten datasets with real-world distribution shifts: hospital changes (Camelyon17), wildlife camera location shifts (iWildCam), and satellite imagery temporal drift (PovertyMap). For the reported Camelyon17-WILDS ERM baseline, average accuracy fell from 93.2 percent in-distribution to 70.3 percent out-of-distribution, demonstrating that standard held-out evaluation can overestimate performance when the i.i.d. assumption fails.
Koh, Pang Wei, Shiori Sagawa, Henrik Marklund, Sang Michael Xie, Marvin Zhang, Akshay Balsubramani, Weihua Hu, et al. 2021. “WILDS: A Benchmark of in-the-Wild Distribution Shifts.” In Proceedings of the 38th International Conference on Machine Learning, ICML 2021, 18-24 July 2021, Virtual Event, edited by Marina Meila and Tong Zhang, vol. 139. Proceedings of Machine Learning Research. PMLR.
The same benchmark’s iWildCam split is the camera trap’s version of the problem. Models trained on images from one set of camera-trap locations are evaluated on traps they have never seen, where background, lighting, and the mix of species all change (Koh et al. 2021). A MobileNetV2 that meets every latency and energy gate on the board can still fail this test, and no system benchmark would reveal it.
To detect changes that warrant investigation, serving pipelines can apply the statistical shift tests and the covariate, label, and concept shift taxonomy of Data drift detection and response to incoming inference streams; the benchmarking use is to decide when the evaluation set has stopped representing production. Two-sample hypothesis tests such as the Kolmogorov-Smirnov test (Berger and Zhou 2014) for univariate features and maximum mean discrepancy (Gretton et al. 2012) for multivariate embeddings detect changes in the marginal input distribution \(\InputDistribution\). Establishing covariate shift also requires the conditional target distribution \(\ConditionalDistribution\) to remain stable; input-only tests cannot verify that condition without label evidence. Prediction entropy and confidence distributions provide additional warning signals, but shifted inputs can still produce confident predictions. Validate alert thresholds and fallback policies against labeled deployment samples; these signals alone do not guarantee detection before quality degrades.
Berger, Vance W., and YanYan Zhou. 2014. “Kolmogorov–Smirnov Test: Overview.” In Wiley StatsRef: Statistics Reference Online. Wiley. https://doi.org/10.1002/9781118445112.stat06558.
Gretton, Arthur, Karsten M. Borgwardt, Malte J. Rasch, Bernhard Schölkopf, and Alexander Smola. 2012. “A Kernel Two-Sample Test.” Journal of Machine Learning Research 13 (25): 723–73.
↪ Live covariate shift detectors feed the statistical distance monitoring and automated drift alerts developed in Feature distribution monitoring.
Distribution alignment challenges highlight a persistent tension in ML development between two paradigms: fixing the data and iterating on models, or fixing the model and iterating on data. The side-by-side schematics in figure 12 isolate this divergence through the placement of the padlock and feedback path. In the model-centric panel, the dataset is locked while the feedback loop iteratively refines model parameters on the CPU; in the data-centric panel, the model architecture is locked while the loop routes back to enhance training data quality, diversity, and labeling. As the bidirectional red arrow emphasizes, the two paradigms are complementary engineering strategies rather than mutually exclusive philosophies.
Data-centric AI reflects an important shift in understanding that challenges the “more data is always better” assumption: dataset composition matters alongside scale. Initiatives like DataPerf (Mazumder et al. 2023) and DataComp36 have emerged to evaluate how dataset construction affects model performance systematically. In DataComp’s compute-controlled setting, a baseline that retained the top 30 percent of the candidate pool by CLIP-based filtering outperformed the unfiltered-pool baseline on aggregate downstream evaluation (Gadre et al. 2023). The result establishes the value of curation for that protocol, not a universal optimal fraction.
Mazumder, Mark, Colby Banbury, Xiaozhe Yao, Bojan Karlaš, et al. 2023. “DataPerf: Benchmarks for Data-Centric AI Development.” Advances in Neural Information Processing Systems 36.
36 DataComp: Introduced in 2023, DataComp fixes the model family, training code, and compute budget while participants vary dataset construction. Its filtering track isolates the effect of selecting examples from a common candidate pool, making curation strategies comparable without attributing every gain to additional training compute.
Gadre, Samir Yitzhak, Gabriel Ilharco, Alex Fang, Jonathan Hayase, Georgios Smyrnis, Thao Nguyen, Ryan Marten, et al. 2023. “DataComp: In Search of the Next Generation of Multimodal Datasets.” Advances in Neural Information Processing Systems (NeurIPS) 36: 27092–112. https://doi.org/10.52202/075280-1179.
Dataset saturation and dynamic benchmarks
Even when coverage, quality, and distribution alignment protocols are satisfied, static benchmarks encounter the problem of dataset saturation. As models approach empirical upper bounds on fixed test suites, leaderboard deltas compress, making it difficult to distinguish genuine capability advances from over-optimization to benchmark-specific artifacts. The capability trajectories in figure 13 plot this exhaustion over two decades, showing AI scores rising from normalized baselines (-100) to cross the zero line marking human performance (Maslej et al. 2024). While handwriting and speech recognition required over a decade to reach human parity (the green shaded region), reading comprehension and language understanding surged across the threshold in under two years between 2016 and 2020, rapidly exhausting the discriminating headroom of static suites.
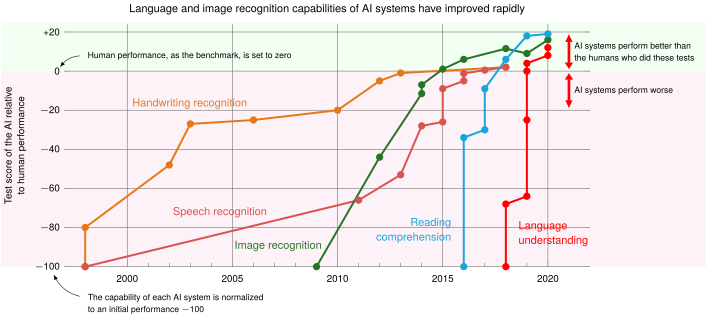
Maslej, Nestor, Loredana Fattorini, C. Raymond Perrault, Vanessa Parli, Anka Reuel, Erik Brynjolfsson, John Etchemendy, et al. 2024. “Artificial Intelligence Index Report 2024.” In CoRR, abs/2405.19522. https://doi.org/10.48550/ARXIV.2405.19522.
Once a static benchmark saturates, high leaderboard accuracy can mask brittle heuristics. MNIST digit recognition (LeCun et al. 1998) demonstrated early that models can exploit dataset-specific capture artifacts rather than invariant features, a concern that eventually prompted researchers to re-examine whether ImageNet had reached the end of its useful diagnostic lifetime (Beyer et al. 2020). When the evaluation distribution remains frozen, iterative model selection risks overfitting to idiosyncratic test artifacts rather than improving generalizable task capability.
LeCun, Yann, Léon Bottou, Yoshua Bengio, and Patrick Haffner. 1998. “Gradient-Based Learning Applied to Document Recognition.” Proceedings of the IEEE 86 (11): 2278–324. https://doi.org/10.1109/5.726791.
Beyer, Lucas, Olivier J. Hénaff, Alexander Kolesnikov, Xiaohua Zhai, and Aäron van den Oord. 2020. “Are We Done with ImageNet?” arXiv Preprint arXiv:2006.07159.
37 Dynabench: Facebook AI Research’s 2021 platform for dynamic benchmark generation, where humans craft adversarial inputs that fool current best models. Dynabench addresses the saturation problem, where very high accuracy on static benchmarks may reflect test-set familiarity rather than robust capability, but introduces its own trade-off: dynamic benchmarks are harder to compare across time because the evaluation set changes. Static and dynamic benchmarks serve complementary diagnostic roles.
Kiela, Douwe, Max Bartolo, Yixin Nie, Divyansh Kaushik, Atticus Geiger, Zhengxuan Wu, Bertie Vidgen, et al. 2021. “Dynabench: Rethinking Benchmarking in NLP.” Proceedings of the 2021 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies 9: 4110–24. https://doi.org/10.18653/v1/2021.naacl-main.324.
Dynamic benchmarking frameworks such as Dynabench37 (Kiela et al. 2021) address saturation by continuously evolving evaluation data. In this paradigm, human annotators generate adversarial inputs targeting the failure modes of current top-performing models, ensuring that the benchmark continues to exercise representational limits. However, dynamic benchmarks introduce a direct systems trade-off: because the evaluation distribution changes across iterations, longitudinal comparisons across model generations become difficult to calibrate. Static and dynamic benchmarks therefore serve complementary roles: static suites ensure longitudinal reproducibility on standardized tasks, while dynamic benchmarks identify newly emergent error boundaries.
12.9.3 Holistic system-model-data evaluation
Passing system, model, and data benchmarks independently is not enough. A system benchmark can validate hardware performance, a model benchmark can verify that compression preserved quality, and a data benchmark can assess training set representativeness, yet the deployed system can still fail because the three dimensions interact. Real-world AI performance emerges from that interaction, and optimizing one dimension can expose weaknesses in another.
Consider a concrete failure cascade, a composite drawn from the chapter’s camera trap: an engineering team achieves target throughput on MLPerf Inference by deploying an INT8-quantized vision model on a specialized accelerator. System benchmarks pass. However, because the quantization scale factors and zero points were fitted (quantization-range calibration) strictly against ImageNet validation samples, deploying the model in the camera trap’s night-time infrared frames reveals severe accuracy degradation. Infrared frames produce activation ranges that exceed the calibrated clipping thresholds, truncating feature activations. A targeted model quality benchmark across varied exposure levels would have exposed this numerical sensitivity. Tracing the failure upstream reveals that the training pipeline contained no night-time infrared imagery, a data distribution gap that no amount of accelerator optimization or runtime kernel tuning can resolve.
Cross-dimensional coupling means that a passing benchmark in one domain can be invalidated by an unmeasured failure in another. When system benchmarks succeed alongside a model failure, the hardware delivers its promised throughput while aggressive compression degrades accuracy below deployment thresholds; when they succeed alongside a data failure, fast inference executes on benchmark inputs while training data bias causes severe accuracy disparities across demographic subgroups. Conversely, a model success paired with a system failure produces accurate predictions whose tail latency variance under concurrent load violates service-level agreements, whereas a model success paired with a data failure yields high accuracy on held-out test sets that silently degrades under production distribution shift.
These failure modes map onto the pairwise intersections of the D·A·M taxonomy (The D·A·M Intersection Landscape), though benchmark evaluation lenses do not align one-to-one with isolated physical vertices. Data benchmarks evaluate input distribution quality and coverage (\(\text{D}\)); model benchmarks assess learned algorithmic representations and numerical robustness (\(\text{A}\)); and system benchmarks expose hardware execution, kernel efficiency, and memory-interconnect traffic (\(\text{M}\)). Holistic evaluation validates the pairwise and central intersections where these domains meet, ensuring that optimizations across the Part III pipeline (data selection \(\rightarrow\) model compression \(\rightarrow\) hardware acceleration) do not introduce hidden cross-axis regressions.
↩︎ The D·A·M taxonomy and its pairwise intersections are established in Defining ML Systems.
The D·A·M taxonomy provides a diagnostic framework for systematically identifying which axis limits performance. Table 20 formalizes this approach by crossing each D·A·M axis with compute, memory, and I/O constraints.
| Component | Compute Constraint | Memory Constraint | I/O Constraint |
|---|---|---|---|
| Data | Host preprocessing saturates compute | Capacity: working set exceeds RAM | Storage delivery cannot keep the accelerator fed |
| Algorithm | Required operations exceed the compute-time budget | Capacity: activations restrict feasible batch size | Exposed gradient synchronization limits step time |
| Machine | Useful operation rate approaches the compute roof | Bandwidth: traffic approaches the interface limit | Exposed transfers approach the interconnect limit |
Applying this matrix organizes hypotheses when system telemetry diverges from theoretical hardware peaks. If an accelerator achieves only 30 percent GPU utilization during training, an engineer might prematurely blame the model architecture (Algorithm row) and attempt model surgery. Profiling often reveals instead that host-side data workers saturating CPU cores on image augmentation or tokenization cannot feed batches fast enough across PCIe (Data row, Compute Constraint column). The accelerator stalls not from algorithmic inefficiency, but from input pipeline starvation. The matrix guides investigation; traces and controlled interventions establish which physical subsystem is binding.
↪ A production troubleshooting matrix that maps common failure symptoms to a candidate D·A·M axis and the measurement that confirms it is collected for reference in Confirming the hypothesis.
Validation under controlled laboratory conditions differs from validation in production. A laboratory protocol may fix data, simplify arrivals, or isolate execution to answer a controlled question. In production, all three assumptions can break simultaneously: data drifts, traffic spikes unpredictably, and concurrent workloads compete for shared hardware. The recurring misconceptions that follow are the ways teams forget that difference.
Self-Check: Question
An image classifier deployed in an autonomous vehicle achieves \(94\%\) top-1 accuracy on ImageNet. After post-training INT8 quantization, consider a bin of predictions to which the model assigns about \(0.99\) confidence on average, but whose observed accuracy is materially lower. Which model evaluation metric directly quantifies this divergence between predicted probability and empirical accuracy?
- Peak Signal-to-Noise Ratio (PSNR)
- Expected Calibration Error (ECE)
- Top-5 classification error
- Hardware FLOPs Utilization (HFU)
A clinical risk prediction model achieves an outstanding \(0.92\) ROC-AUC score on a held-out test split from Hospital A’s electronic health records. When deployed at Hospital B in a different city, its ROC-AUC drops to \(0.61\). Assume the implementation and evaluation protocol are matched across sites, and Hospital B differs in patient mix, lab workflows, and clinical protocols. What benchmarking limitation is the best hypothesis for why the standard held-out test failed to predict this deployment failure?
- Hospital B used GPUs with different floating-point rounding modes
- The ROC-AUC metric is mathematically invalid for clinical applications
- The held-out test split shared the same underlying distribution as the training environment, so it could not expose failure under covariate and concept shift at the new site
- The training algorithm suffered from underfitting on Hospital A’s dataset
True or False: If an ML deployment passes both system benchmarking (achieving target throughput and low latency) and model benchmarking (preserving validation accuracy and calibration), data benchmarking is unnecessary because software execution and model mathematics are fully verified.
The metric that partitions model prediction confidences into discrete bins and calculates the weighted average difference between confidence and accuracy across all bins is called ____.
Explain why compression evaluation should be framed as a multi-objective Pareto frontier across accuracy, latency, model size, and memory footprint, rather than a single scalar delta.
A team deploys an INT8-quantized vision model to an edge TPU for factory defect detection. The deployment passes MLPerf Inference benchmarks and ImageNet validation, but in production, defect detection accuracy collapses from \(98\%\) to \(74\%\). Use the three-dimensional benchmarking framework (System, Model, Data) to propose plausible failure hypotheses and the tests that would distinguish them.
12.10 Fallacies and Pitfalls
Benchmarking creates false confidence when standardized measurement obscures deployment realities. Teams assume controlled evaluations predict production performance, but real systems face variability, resource constraints, and multi-objective trade-offs that benchmarks cannot capture, wasting engineering effort on systems optimized for evaluation rather than deployment.
Fallacy: Benchmark performance directly translates to real-world application performance.
The apparent clarity of isolated benchmark numbers leads teams to assume that measuring a model’s forward pass predicts user-facing response times. It does not. In research benchmarks, a model’s raw inference pass might execute in 5–10 ms. However, inside a production serving microservice, request deserialization, tokenization, feature retrieval, and network transmission overhead expand the total response time to 50–100 ms. In an illustrative model-only test, the team reports mean latency under synthetic, evenly spaced inputs (15 ms). Under the scenario’s production traffic, arrival bursts and queueing backlog raise p99 tail latency to 150–200 ms (10–13.3× gap from the model-only mean). This contrast changes the statistic, measurement boundary, and traffic conditions; quantifying a slowdown requires matched end-to-end statistics under stated workload conditions. In the same illustrative comparison, a model achieving 92 percent benchmark accuracy drops to 78–82 percent when confronted with real-world distribution shifts such as noisy text and uncurated sensor inputs. Evaluating an isolated neural network kernel cannot substitute for benchmarking the complete end-to-end serving pipeline.
In this scenario, the model-only mean understates the production tail by an order of magnitude.
Pitfall: Optimizing exclusively for benchmark metrics without considering broader system requirements.
Benchmark leaderboards incentivize aggressive optimization, but the optimizations that climb rankings often degrade the very characteristics production demands. This exemplifies Goodhart’s Law (section 12.1), whose organizational form section 12.8.4 examined. In one illustrative scenario, a team reduces inference latency from 12 ms to 8 ms through aggressive quantization, improving MLPerf ranking by 15 positions while degrading calibration such that prediction confidence scores become unreliable for downstream decision-making. Another team improves ImageNet accuracy by 2.1 percentage points through extensive hyperparameter tuning, yet the optimized model consumes 40 percent more energy and suffers 25 percent worse performance on out-of-distribution images from production cameras.
Fallacy: Single-metric evaluation provides sufficient insight into system performance.
A single-number claim appears deceptively simple (“94 percent accurate” or “1,200 QPS fast”), yet production success requires balancing multiple competing objectives that any single metric obscures. Modern inference systems demand evaluation across accuracy, latency, throughput, energy, and robustness dimensions (section 12.6.2). In an illustrative trade-off, a recommendation model achieving 94 percent accuracy with 180 ms p99 latency fails service-level objectives requiring p99 < 100 ms despite excellent accuracy. Conversely, a system optimized for 1,200 QPS throughput achieves this rate while consuming 4.2 W vs. 1.8 W for a slightly slower system at 1,000 QPS (2.3× power difference). For battery-powered edge devices, the 17 percent throughput loss enables 2.3× longer operation time. Different stakeholders prioritize different metrics: ML engineers focus on accuracy, infrastructure teams on throughput and cost, product managers on latency percentiles.
Pitfall: Using outdated benchmarks that no longer reflect deployment challenges and requirements.
Benchmarks have inertia: teams continue reporting on established benchmarks after the results cease to provide useful discrimination. Saturation occurs when multiple approaches achieve near-identical performance, eliminating useful comparison. ImageNet top-5 classification error decreased from 28.2 percent in 2010 (Russakovsky et al. 2015) to 3.57 percent by 2015 (He et al. 2016), sharply compressing the headroom measured by that metric. As gaps narrow, the statistical confidence intervals discussed in section 12.8.1 and the result’s deployment relevance matter more than leaderboard rank. Changing deployment contexts compound the problem: benchmarks designed for server hardware become misleading for edge devices with 10× less memory and 100× lower power budgets. Effective benchmarking requires retiring saturated benchmarks and developing evaluation frameworks matching target deployment realities.
Fallacy: Research benchmarks predict production behavior under real traffic.
A short, isolated laboratory run can miss the thermal and architectural constraints of sustained production execution. First, laboratory runs frequently suffer from initialization errors: omitting warmup runs conflates one-time JIT compilation, GPU runtime initialization, and memory allocator page faults with steady-state execution. Second, short laboratory bursts (e.g., 30 seconds) capture transient boost clock frequencies. Under sustained production load, heat accumulates faster than cooling infrastructure can dissipate it; the hardware governor triggers dynamic voltage and frequency scaling (DVFS), downclocking silicon to protect junction temperatures. As a result, a system achieving 800 QPS throughput in short burst benchmarks sustains only 400–500 QPS under continuous load with 90 percent utilization (37.5–50 percent degradation).
Self-Check: Question
What is the primary fallacy in using an accelerator’s peak advertised TFLOP/s to estimate the serving capacity of an ML inference deployment?
- Peak TFLOP/s assumes a specific arithmetic path, precision, and favorable shapes, while ignoring memory bandwidth bottlenecks, runtime overhead, non-model pipeline stages, and batch-shape variation
- Peak TFLOP/s is an obsolete metric that is no longer measured by hardware vendors
- Accelerators always run at exactly 50% of their peak TFLOP/s due to hardware safety limiters
- Peak TFLOP/s applies only to CPU floating-point units and has no meaning for GPUs or TPUs
An engineering team modifies an inference server configuration, increasing throughput from \(1,000\text{ QPS}\) at \(1.8\text{ W}\) to \(1,200\text{ QPS}\) at \(4.2\text{ W}\) for the same quality target and measurement boundary. What is the systems consequence of this change?
- It is an unambiguous improvement because throughput is \(20\%\) higher
- The system suffered a \(48.6\%\) reduction in energy efficiency (dropping from \(556\text{ QPS/W}\) to \(286\text{ QPS/W}\)), which is a major regression under power-constrained objectives
- The system will run cooler because queries complete faster
- Operating cost is reduced because higher throughput always decreases data center power bills
True or False: If a newly released open-source model ranks #1 on a public benchmark leaderboard, an enterprise can deploy it into production with confidence that it will outperform existing models on company workloads.
Explain why an accuracy-saturated capability benchmark becomes less discriminative as a progress indicator for ML systems, and describe which complementary evaluations can preserve its usefulness as a regression baseline.
Explain how Goodhart’s Law manifests when teams optimize exclusively for benchmark scores, using a concrete systems example where metric chasing degrades production quality.
12.11 Summary
Benchmarking completes Part III’s optimization pipeline by validating whether the efficiency gains from data selection, model compression, and hardware acceleration deliver in practice. The three benchmark lenses examine system execution, model behavior, and data representativeness separately, then test whether their assumptions survive when the complete system runs under deployment conditions. Every row of table 2 began as a claim and now has a measurement: ResNet-50’s INT8 claim became a test with stated conditions, its roofline ceiling met an MLPerf throughput that sits 8.0× below it, MobileNetV2’s accelerator speedup narrowed once the whole frame path on the edge board was timed, and keyword spotting showed that idle power, not inference, sets a duty-cycled device’s battery life.
The lenses reveal different failure modes: system benchmarks expose underdelivered throughput, tail latency, and thermal behavior; model benchmarks test accuracy, calibration, robustness, and other properties that an optimization may alter; and data benchmarks examine coverage, label quality, leakage, and alignment with deployment. Standardized suites such as MLPerf Training and Inference provide comparable system evidence, whereas model and data protocols supply the quality and representativeness evidence that a hardware result cannot establish.
Optimization claims need measured execution rather than analytical proxies: wall-clock timing captures DRAM bandwidth saturation, kernel launch serialization, and host-device transfer overhead that FLOP counts omit; percentile profiling under concurrent load exposes queuing delays and thermal throttling that arithmetic means conceal; and evaluating workloads against production-representative data reveals dynamic shape variations and memory churn that uniform synthetic inputs never trigger.
A candidate release can pass the hardware, model, and data tests yet still lack evidence for the workload it will serve. A service with bursty requests needs load validation, and a camera trap deployed under changing illumination needs labeled examples from those conditions. Laboratory benchmarks establish behavior under specified conditions; a release decision must identify which of those conditions remain valid in the target deployment and test the ones that change. Timing and memory telemetry can expose overload, while silent predictive degradation requires labels or validated quality proxies, and when labels arrive late the release protocol must name that delay. A research benchmark remains useful for comparing algorithms, but a release gate for a serving system must also include load tests, tail-latency measurements, data-quality checks, failure drills, and rollback criteria. Table 21 pairs each simplifying benchmark assumption with the production condition that violates it and the validation step that closes the gap.
| Benchmark Assumption | Production Reality | Validation Approach |
|---|---|---|
| Uniform request arrival | Bursty traffic patterns | Load test with production trace replay |
| Clean, preprocessed inputs | Variable quality inputs | Evaluate on production data sample |
| Warm system state | Cold starts, cache misses | Measure cold-start performance |
| Isolated execution | Resource contention | Benchmark under realistic system load |
| Fixed model version | A/B testing, gradual rollout | Establish baseline for comparison |
Once a model is live, benchmarking becomes a rolling comparison against those baselines: whether the input distribution remains close to the benchmark distribution, whether latency and throughput stay inside the measured envelope, and whether model quality moves outside its expected range. Serving systems turn this measurement loop into staged rollouts, shadow evaluation (running the new model beside production without serving its outputs), and automated rollback. Benchmarking defines the performance envelope and failure thresholds; production monitoring tests live telemetry against them.
↪ Shadow, canary, and blue-green releases and the rollback tiers that act on these thresholds are developed in Model deployment.
The chapter’s measurement formulas fit on one page (table 22). Together they let an engineer state, before running a benchmark, what it will measure and what result would refute the claim.
| Quantity | Formula | Where derived |
|---|---|---|
| Time to accuracy | \(\TrainingTime= \inf \big\{\TimeInstant\geq 0 : \text{Accuracy}_{\text{val}}(\TimeInstant) \geq \text{target accuracy} \big\}\) | equation 1 |
| Training throughput | \(\text{Throughput} = \frac{\ProcessedSampleCount}{\TrainingTime}\) | equation 2 |
| Scaling efficiency | \(\text{Eff}_{\text{scaling}}(\AcceleratorCount) = \frac{\Time(1)}{\AcceleratorCount \times \Time(\AcceleratorCount)} \times 100\%\) | equation 3 |
| Hardware utilization | \(\EfficiencyHw = \SustainedComputeRate/ \PeakRate\) | section 12.4.3 |
| Amdahl ceiling | \(1/(1-\ParallelFraction)\) for an accelerated fraction \(\ParallelFraction\) of latency | section 12.3.4 |
| Energy per inference | \(\InferenceEnergy= \ActiveInferencePower\times \InferenceLatency\) | section 12.7 |
| Duty-cycle average power | \(\AveragePower= \InferenceDutyCycle \ActiveInferencePower+ (1 - \InferenceDutyCycle) \StandbyPower\) | section 12.7.2 |
| Energy over a window | \(\TotalEnergy = \int_{t_{\text{start}}}^{\MeasurementWindowEnd} \DevicePower(\TimeInstant) \, d\TimeInstant\) | section 12.7.4 |
| Paired-test statistic | \(\McnemarTestStatistic= \frac{(\BaselineOnlyCorrectCount- \CompressedOnlyCorrectCount)^2}{\BaselineOnlyCorrectCount+ \CompressedOnlyCorrectCount}\) | section 12.8.1 |
| Expected calibration error | Bin-weighted mean of the gap between confidence and accuracy | equation 4 |
Key Takeaways: Measuring what matters
- Benchmarks validate co-design: System, model, and data benchmarks expose hardware underdelivery, compression quality loss, and distribution mismatch. A system that passes only one axis can still fail when Data, Algorithm, and Machine constraints meet under production load.
- A claim becomes a test only when its conditions are fixed: Benchmark carpentry restates a claim such as “ResNet-50 is faster at INT8” as a task, dataset, model, metric, harness, specification, and run rules. A number reported without those conditions cannot be reproduced, compared, or refuted.
- A prediction and a measurement together locate a bottleneck: The roofline places ResNet-50 training on the compute roof, yet the measured MLPerf throughput sustains only 12.4 percent of peak. The gap says time is going somewhere other than arithmetic, and profiling attributes it.
- Proxy numbers need boundaries: Standardized run rules make comparisons honest, but fixed workloads are still proxies. Batch size, thermal state, input distribution, concurrency, and service-deadline windows decide whether a lab result survives the benchmark–production gap.
- Granularity trades diagnosis for realism: Micro-benchmarks isolate kernels, macro-benchmarks expose model-level costs, and end-to-end benchmarks capture user-visible behavior. Effective measurement stacks all three so teams can see both the symptom and the layer that caused it.
- Tail latency often decides pass or fail: Interactive services with percentile-based SLOs can violate their latency target while mean latency remains acceptable. Reporting percentile latency under representative load prevents a benchmark from approving a system whose mean passes while its worst-served requests violate the SLO.
- A component speedup is diluted across the pipeline stages it does not touch: In the chapter’s vision pipeline, unchanged preprocessing at 44.4 percent of latency turns a 5× inference speedup into 1.8× end to end, and Amdahl’s law (equation 11.1) caps even an infinitely fast model at 2.25×. Benchmark the whole request path before celebrating kernel speedups.
- Energy follows the duty cycle: For always-on keyword spotting on a microcontroller board, the idle floor accounts for 94 percent of average power, so energy per inference alone misdescribes battery life. A power benchmark states its boundary, its window, and the duty cycle.
- A difference is real only beyond its noise: Paired tests on per-image outcomes and intervals over repeated run pairs decide whether a one-point accuracy gap or a measured latency reduction is a finding. A test set is a measurement instrument with finite resolution.
- Efficiency still needs quality evidence: INT8 may cut raw weight storage 4\(\times\); the simplified component model estimates an energy reduction of about 6.6×, but whole-device measurement, confidence calibration, subgroup robustness, and edge-case behavior decide whether the compressed model is deployable.
Each chapter in this part promised fewer FLOPs, a smaller model, or higher throughput. Benchmarking tests those promises against the complete system. The gap between a claimed improvement and a measured one reveals where Data, Algorithm, and Machine were assembled rather than matched. Applied to a measured pipeline, Amdahl’s law shows why an infinitely fast model can still leave the pipeline bounded by everything outside it, while tail latency shows why an average can pass even as the worst-served requests fail.
What’s Next: From lab to live
The serving protocols in this chapter specified the arrival process through a load generator. Production supplies its own changing traffic, and the serving system must respond within its declared operating envelope. Part IV leaves the controlled benchmark environment, beginning with Model Serving. Engineering for arrivals no one schedules reorders the priorities that training optimized, putting per-request latency and spare headroom ahead of raw throughput.
12.12 Self-Check Answers
Self-Check: Answer
In the three-dimensional ML benchmarking framework, what distinct failure mode does system benchmarking isolate compared to model and data benchmarking?
- Whether hardware accelerators, memory subsystems, and software runtimes deliver expected computational throughput and latency under workload execution patterns
- Whether model compression techniques preserve confidence calibration and accuracy on rare edge cases
- Whether the training dataset contains sufficient coverage, demographic balance, and resistance to covariate drift
- Whether human labeling errors and noisy annotations degrade model convergence rates
Answer: The correct answer is A. System benchmarking focuses on execution behavior: whether the hardware-software stack delivers the expected throughput, latency, and utilization on the workload being run. Model and data benchmarks examine different lenses, such as calibration loss after compression or coverage gaps in the dataset. These lenses are complementary diagnostics for the same deployed system, not perfectly isolated root causes.
Learning Objective: Compare how system, model, and data benchmarking provide complementary diagnostic lenses for different failure modes in deployed ML systems.
True or False: Because ML benchmarks provide standardized datasets and metric formulas, a top-ranking benchmark score represents a permanent, universal verification of a model’s operational capability in production.
Answer: False. Unlike traditional computing specifications (such as sorting algorithms where correctness is absolute), ML benchmarks are soft specifications and proxy measurements captured at a specific point in time. As real-world data distributions drift and production traffic patterns vary, a static benchmark score degrades in predictive value, and designing solely to maximize benchmark leaderboards leads to benchmark overfitting.
Learning Objective: Evaluate whether ML benchmark scores represent permanent performance baselines or time-stamped proxy measurements.
When benchmarkers compute useful model FLOPs per elapsed second and divide by the matching numerical-path peak throughput of the hardware, the resulting metric is abbreviated as ____.
Answer: MFU. MFU measures useful model FLOPs per elapsed second divided by the matching numerical-path peak throughput of the hardware. It is more informative than a generic busy counter because it focuses on achieved model computation rather than all executed FLOPs or mere device activity.
Learning Objective: Explain Model FLOPs Utilization (MFU) as useful model FLOPs per second relative to the matching hardware peak.
Explain how Goodhart’s Law applies to ML systems benchmarking, and describe a concrete scenario where optimizing exclusively for a benchmark metric degrades real-world deployment quality.
Answer: Goodhart’s Law states that ‘when a measure becomes a target, it ceases to be a good measure.’ In ML benchmarking, benchmarks are imperfect proxies for deployment reality. When engineering teams optimize exclusively to maximize a single benchmark metric (such as top-1 validation accuracy or peak offline throughput), they incentivize shortcuts—such as aggressive quantization that damages confidence calibration, or fixed-batch optimizations that spike tail latency under variable traffic. For example, a vision model compressed to maximize ImageNet top-1 accuracy may exploit dataset-specific lighting artifacts while failing completely on real-world factory camera images with novel shadows, demonstrating how optimizing a proxy metric can anti-correlate with production reliability.
Learning Objective: Justify why benchmarks act as proxies rather than ground truth and explain how Goodhart’s Law distorts single-metric optimization.
Self-Check: Answer
Which core benchmark component is responsible for documenting the exact hardware model, CPU core pinning, GPU driver version, CUDA toolkit, compiler flags, and OS kernel version required to ensure experimental reproducibility?
- System specifications
- Dataset split definition
- Evaluation metric formula
- Problem definition
Answer: The correct answer is A. System specifications define the complete hardware and software environment—including CPU/GPU architectures, interconnect topology, OS version, kernel drivers, compiler flags, and library versions—necessary for third parties to replicate results. Dataset splits define training/validation partitioning; evaluation metrics define scoring mathematics; problem definitions specify the high-level task and domain objectives.
Learning Objective: Analyze which benchmark component captures the software and hardware execution environment necessary for reproducibility.
When designing a benchmark suite for an edge computer vision model deployed on a battery-powered security camera with passive cooling, which set of evaluation metrics provides the most complete assessment of deployment viability?
- Peak offline throughput in FP32 without thermal monitoring
- Energy per inference (mJ), active vs. idle power consumption across the device duty cycle, memory footprint (SRAM/DRAM usage), sustained latency under thermal equilibrium, and deployed-model quality on representative and critical input slices
- Only the model parameter file size on disk in megabytes
- Top-1 validation accuracy measured on an uncompressed server GPU
Answer: The correct answer is B. Edge deployment viability depends on more than speed: battery capacity, passive thermal limits, memory budget, and task quality all matter. A complete benchmark therefore needs energy, duty-cycle power, memory footprint, sustained latency after thermal stabilization, and quality on representative or critical slices. Peak offline throughput ignores thermal collapse and task quality, while file size or server-GPU accuracy alone misses the operational constraints of the deployed device.
Learning Objective: Design an edge benchmark metric set that covers energy, thermal behavior, memory limits, latency, and deployed-model quality.
True or False: When evaluating model compression techniques (such as INT8 quantization or structured pruning), validating that the compressed model achieves a \(4\times\) reduction in file size with \(<0.5\%\) top-1 accuracy loss is sufficient to guarantee proportional speedups and energy savings on any target deployment hardware.
Answer: False. Model size reduction does not guarantee proportional latency speedups or energy savings on hardware. Unstructured sparsity, non-standard quantization precisions, or unsupported operator layouts can trigger CPU fallbacks, memory realignment stalls, or inefficient execution on edge NPUs that lack specialized hardware acceleration, sometimes making a compressed model slower than the dense baseline.
Learning Objective: Evaluate why compression benchmarking requires multi-objective Pareto analysis rather than single-metric compression ratios.
In standardized benchmarking suites, the formal component that defines the mandatory execution constraints, convergence thresholds, warmup requirements, and statistical aggregation procedures to ensure fair cross-platform comparisons is called the ____.
Answer: run rules. Run rules specify how the benchmark must be executed and reported so results remain comparable across systems. They matter because identical models or datasets can still produce incommensurable numbers if the timing window, warmup policy, or acceptance criteria differ.
Learning Objective: Explain the function of benchmark run rules in enforcing fair and reproducible execution across submissions.
Order the following execution steps of a standardized benchmark harness protocol from beginning to end for a controlled steady-state measurement workflow: (1) Execute the timed measurement loop while collecting high-resolution hardware timestamps, (2) Apply the selected environment controls, such as CPU affinity pinning and any documented clock policy, (3) Compute summary statistics (mean, median, p90, p99, standard deviation) and confidence intervals, (4) Execute unmeasured warm-up iterations to load model weights and warm instruction/data caches, (5) Perform verification check to ensure model output predictions match ground truth quality thresholds
Answer: The correct order is: (2) Apply the selected environment controls, such as CPU affinity pinning and any documented clock policy, (4) Execute unmeasured warm-up iterations to load model weights and warm instruction/data caches, (1) Execute the timed measurement loop while collecting high-resolution hardware timestamps, (5) Perform verification check to ensure model output predictions match ground truth quality thresholds, (3) Compute summary statistics (mean, median, p90, p99, standard deviation) and confidence intervals. In this controlled steady-state workflow, environment controls are set first so the run reflects the intended operating policy. Warm-up comes before timing so initialization effects do not contaminate the steady-state claim. Output verification must complete before aggregating and reporting the final numbers for this workflow, because the statistics are only meaningful if the measured run produced valid results.
Learning Objective: Order the stages of a controlled steady-state benchmark harness workflow from environment setup through validated statistical reporting.
A vendor publishes a marketing claim stating their new AI accelerator achieves ‘\(120\text{ TFLOP/s}\) on Transformer inference.’ Which combination of parameters is essential to make this throughput figure technically actionable and reproducible?
- Only the silicon process node (e.g., \(4\text{ nm}\)) and the data center room temperature
- Numerical path (e.g., FP32 vs. FP16), batch size, sequence length, software/compiler stack version, and sustained thermal operating state
- The brand of server power supply and the serial number of the host CPU
- Only the parameter count of the model, without specifying batch size or precision
Answer: The correct answer is B. Throughput depends strongly on the numerical path, batch size, sequence length, software stack, and sustained operating state. Those factors determine arithmetic intensity, kernel selection, memory traffic, and whether throttling appears. Process node and room temperature alone do not reconstruct the workload, and model size without precision or batching leaves the execution path undefined.
Learning Objective: Evaluate the minimum workload and execution context needed to interpret a vendor throughput claim.
Self-Check: Answer
An e-commerce search service reports that production query latency has increased by \(40\%\), violating its SLA. Which benchmarking workflow represents the most effective top-down diagnostic strategy?
- Immediately rewrite all GEMM kernels in CUDA assembly without measuring the higher layers
- Run isolated microbenchmarks on the GPU memory bus to determine peak DRAM bandwidth
- Start with an end-to-end pipeline benchmark to isolate latency contributions across database lookup, tokenization, model inference, and reranking; next run macrobenchmarks on the slowest stage; then use microbenchmarks and kernel profilers to optimize the specific bottleneck operator
- Benchmark only the isolated tokenization library on CPU and assume the rest of the pipeline is unaffected
Answer: The correct answer is C. A disciplined top-down diagnostic workflow starts at the end-to-end level to isolate which pipeline stage caused the SLA violation, zooms into macrobenchmarks (subgraphs/models) for that component, and finally uses microbenchmarks and kernel profilers (e.g. Nsight) to identify the specific hardware or algorithmic bottleneck. Rewriting kernels blindly wastes effort on non-bottlenecks; testing memory bus bandwidth in isolation does not pinpoint where time is spent in the request path; testing tokenization alone ignores interactions with database retrieval and model execution.
Learning Objective: Design a multi-granularity benchmarking strategy that combines end-to-end, macro, and micro evaluations to diagnose system bottlenecks.
**Consider the following three benchmarking tasks:
- Timing a single \(4096 \times 4096\) FP16 matrix multiplication in cuBLAS.
- Measuring the forward-pass execution time of a complete ResNet-50 model on a single GPU.
- Measuring total latency for an image upload, server decompression, feature extraction, neural network classification, and database metadata write. How are tasks (I), (II), and (III) classified by benchmarking granularity?**
- End-to-end, (II) Micro, (III) Macro
- Macro, (II) Micro, (III) End-to-end
- Micro, (II) End-to-end, (III) Macro
- Microbenchmark, (II) Macrobenchmark (model-level), (III) End-to-end system benchmark
Answer: The correct answer is D. Task (I) isolates an individual mathematical operator (microbenchmark); Task (II) evaluates a complete neural network architecture (macrobenchmark); Task (III) exercises the complete production data pipeline including networking, I/O, preprocessing, model execution, and storage (end-to-end system benchmark). The other combinations scramble these standardized granularity levels.
Learning Objective: Classify benchmark scenarios into micro, macro, and end-to-end granularity levels based on workload scope.
Compare microbenchmarks, macrobenchmarks, and end-to-end benchmarks along the axes of diagnostic isolation and real-world representativeness.
Answer: Benchmarking granularity exists on a fundamental trade-off curve between diagnostic isolation and real-world representativeness:
Microbenchmarks (e.g., isolated GEMM kernels) offer high diagnostic isolation—pinpointing exact hardware execution bottlenecks or compiler code generation efficiency—but low real-world representativeness because they ignore framework overhead, memory transfers, and surrounding pipeline stages.
Macrobenchmarks (e.g., full ResNet or Transformer forward passes) offer moderate diagnostic power and moderate representativeness, evaluating model architecture and framework execution while excluding external I/O.
End-to-end benchmarks (e.g., full serving pipelines with network ingestion, preprocessing, inference, and database writes) offer high real-world representativeness—capturing true user experience—but low diagnostic isolation because a latency spike could stem from network congestion, garbage collection, data loading, or compute.
Learning Objective: Compare the diagnostic power and real-world representativeness across micro, macro, and end-to-end benchmarks.
True or False: If an optimized FlashAttention kernel achieves a \(4\times\) microbenchmark speedup over a standard attention implementation, the complete language model inference service hosting that model is mathematically guaranteed to run \(4\times\) faster end-to-end.
Answer: False. A kernel-level speedup does not guarantee the same service-level speedup. Under fixed serial fractions and no queueing feedback, Amdahl’s Law limits end-to-end improvement by the fraction of time spent in that kernel. In a loaded service, queueing and batching can also change, so the actual effect may differ from the simple fixed-fraction estimate in either direction.
Learning Objective: Evaluate why a microbenchmark speedup does not by itself determine end-to-end service speedup.
In roofline analysis, an accelerator has a peak compute performance of \(989\text{ TFLOP/s}\) (dense FP16) and a memory bandwidth of \(3.35\text{ TB/s}\), yielding a machine ridge point of \(\RooflineRidgePoint \approx 295\text{ FLOP/byte}\). When serving a Transformer model with batch size \(b=1\), the arithmetic intensity is only \(I = 4.8\text{ FLOP/byte}\). What is the roofline upper bound on achieved throughput as a fraction of peak compute throughput for this workload?
- Approximately \(1.6\%\) of peak compute throughput (memory-bandwidth bound)
- Exactly \(100\%\) because modern tensor cores execute batch \(b=1\) at peak speed
- Approximately \(50\%\) due to pipeline bubbles and kernel launches
- Approximately \(85\%\) because matrix-vector multiplications are compute-bound
Answer: The correct answer is A. Because \(\ArithmeticIntensity < \RooflineRidgePoint\), the workload is memory-bandwidth bound in the roofline model. The throughput upper bound is \(3.35\text{ TB/s} \times 4.8\text{ FLOP/byte} \approx 16.1\text{ TFLOP/s}\), and \(16.1 / 989 \approx 1.6\%\). This is a roofline bound on throughput relative to the matching arithmetic peak, not an observed MFU or a generic busy-utilization reading. The compute-bound answers ignore that the arithmetic intensity sits far below the ridge point.
Learning Objective: Apply roofline model principles to estimate the throughput ceiling at low arithmetic intensity relative to peak compute capability.
An image classification inference pipeline takes \(18\text{ ms}\) per request in a serial CPU baseline: \(8\text{ ms}\) in image decoding/preprocessing and \(10\text{ ms}\) in neural network execution. If only the model execution is migrated to a specialized NPU that accelerates the neural network by \(5\times\) (reducing inference time from \(10\text{ ms}\) to \(2\text{ ms}\)), with the other \(8\text{ ms}\) unchanged and no added transfer or queueing effects, what is the resulting end-to-end pipeline latency and speedup?
- \(2.0\text{ ms}\) latency and \(9.0\times\) speedup
- \(3.6\text{ ms}\) latency and \(5.0\times\) speedup
- \(10.0\text{ ms}\) latency and \(1.8\times\) speedup
- \(16.0\text{ ms}\) latency and \(1.1\times\) speedup
Answer: The correct answer is C. The unchanged preprocessing still costs \(8\text{ ms}\), and the accelerated model execution becomes \(10\text{ ms}/5 = 2\text{ ms}\). The new serial end-to-end latency is therefore \(8+2=10\text{ ms}\), and the system-level speedup is \(18/10=1.8\times\). The \(5\times\) gain applies only to the model stage, not to the whole pipeline.
Learning Objective: Calculate end-to-end speedup in a serial pipeline when only the model-execution stage is accelerated and other latency remains fixed.
Self-Check: Answer
Why did computing benchmark methodology historically transition away from synthetic instruction-mix microbenchmarks (such as Whetstone and Dhrystone) to representative application suites (such as SPEC CPU)?
- Synthetic microbenchmarks required too much memory bandwidth to execute on modern microprocessors
- Representative application suites were easier to implement and did not require source code compilation
- Synthetic benchmarks lacked realistic memory access patterns and branch behavior, allowing optimizing compilers to artificially game scores via dead-code elimination and loop unrolling
- Hardware vendors refused to publish floating-point operations per second for synthetic loops
Answer: The correct answer is C. Synthetic benchmarks contained artificial, repetitive loops that optimizing compilers could easily recognize, unroll, or eliminate, inflating scores without providing real-world application speedups. SPEC CPU solved this by using complete, realistic application programs (like compilers, ray tracers, and fluid dynamics simulations) that exercised complex instruction flows, cache hierarchies, and memory subsystems. Memory bandwidth requirements were not the primary historical driver; representative application suites are substantially more complex to standardize and compile; hardware vendors actively published synthetic results until their lack of correlation with real software forced an industry transition.
Learning Objective: Analyze why the transition from synthetic microbenchmarks to representative application suites was necessary to prevent compiler gaming.
How do the constraints and primary evaluation metrics differ across the domain-specific variants of the MLPerf benchmark suite?
- All MLPerf variants evaluate identical metrics (pure TFLOPS) across different hardware form factors
- MLPerf Training focuses on latency SLAs, while MLPerf Inference evaluates multi-node interconnect bandwidth
- MLPerf Tiny measures data center power consumption, while MLPerf Power evaluates floating-point peak throughput
- MLPerf Training targets time-to-quality on fixed workloads, MLPerf Inference evaluates scenario-defined latency and throughput across server and edge settings, MLPerf Tiny targets embedded memory, latency, and energy constraints on microcontrollers, and MLPerf Power measures useful throughput per watt or useful work per joule within a stated measurement boundary
Answer: The correct answer is D. MLPerf splits into variants because different deployment regimes have different constraints. Training centers on time-to-quality, not just raw device speed. Inference measures latency and throughput under named serving scenarios. Tiny targets embedded memory and energy limits on microcontrollers, and Power adds a cross-cutting efficiency measurement with an explicit system boundary. The other choices either collapse the suites into one metric or swap their purposes.
Learning Objective: Compare the primary constraints and evaluation metrics across the MLPerf Training, Inference, Tiny, and Power variants.
True or False: The introduction of energy-efficiency benchmarks like SPECpower and Green500 replaced raw throughput benchmarks, because computing systems are now evaluated solely on Joules per operation.
Answer: False. Energy-efficiency benchmarks were established to complement raw performance rankings, not replace them. Modern evaluation frameworks employ multi-objective evaluation where performance (throughput/latency) and efficiency (performance-per-watt) are reported together, allowing practitioners to analyze trade-offs along an efficiency-performance Pareto frontier rather than collapsing evaluation to a single metric.
Learning Objective: Evaluate how energy-efficiency benchmarks (SPECpower, Green500) integrated with existing performance rankings rather than replacing them.
Explain why a single benchmark run is insufficient to characterize ML system performance, identifying at least two distinct hardware or runtime sources of execution variance.
Answer: A single run can reflect transient conditions rather than typical behavior. For example, boost clocks may inflate early throughput before steady-state thermal throttling appears, and runtime effects such as lazy memory allocation, background OS scheduling, or asynchronous launch timing can perturb results. For steady-state claims, benchmarks should include warmup and repeated runs that characterize variability with summary statistics or confidence intervals; if cold start is part of the claim, measure it separately instead of warming it away.
Learning Objective: Explain why benchmark protocols use repeated runs and workload-appropriate warmup or cold-start measurement to characterize performance uncertainty.
Compare the primary objectives and constraints of the MLPerf Closed Division versus the Open Division.
Answer: The Closed Division is meant for more comparable system-level evaluation: submitters must preserve the reference task, model equivalence requirements, and quality targets, while only making changes allowed by that benchmark’s rules, such as specified numerical formats, quantization paths, and implementation optimizations. The Open Division allows broader algorithmic and model changes, provided they are documented and reported with the achieved quality and performance. The practical consequence is that Closed results are better for like-for-like platform comparison, while Open results show what broader co-design can achieve.
Learning Objective: Compare how the MLPerf Closed and Open divisions trade off comparability against freedom to modify the model and execution stack.
Explain how community-driven benchmarking consortia discourage vendor gaming, help detect it, and establish commensurable evidence for hardware procurement.
Answer: Community-driven consortia such as MLCommons reduce gaming by publishing reference code, run rules, and audit procedures that discourage undisclosed shortcuts and make suspicious results easier to detect. They also require common workload definitions, measurement boundaries, and reporting formats, so performance claims become more commensurable than vendor marketing numbers alone. The practical consequence is better procurement evidence, although benchmarks still need human interpretation to judge transfer to the target deployment.
Learning Objective: Justify how community benchmark rules and audits discourage gaming and improve comparability for hardware evaluation.
Self-Check: Answer
How do the primary benchmarking objectives and resource bottlenecks fundamentally differ between training systems and inference serving systems?
- Training is latency-critical with millisecond deadlines, whereas inference is throughput-oriented over weeks
- Training memory footprint is dominated solely by static weights, whereas inference requires large optimizer states
- Training optimizes for sustained throughput (samples/sec) and time-to-quality across accelerator systems with large memory demands (weights, gradients, optimizer states, activations), whereas inference optimizes for latency percentiles (p50, p99), QPS, and energy per query under serving constraints
- Training and inference have identical memory access patterns and evaluate the exact same metrics
Answer: The correct answer is C. Training is dominated by the optimization loop, so benchmarks care about sustained throughput and time-to-quality while accounting for weights, gradients, activations, and optimizer state. Inference removes the backward pass and optimizer state, shifting attention toward serving metrics such as latency percentiles, throughput, cold-start behavior, and energy per query. The other choices either swap the regimes or ignore the extra state and distinct objectives that training introduces.
Learning Objective: Compare the primary benchmark objectives, memory demands, and serving constraints that distinguish training from inference.
Why does MLPerf Training mandate time-to-accuracy (or time-to-quality) as its primary benchmark metric instead of raw throughput measured in samples per second?
- Samples per second cannot be measured accurately with digital timers
- Time-to-accuracy is easier to simulate without running actual GPUs
- Hardware vendors do not know the batch size used during training
- Raw sample throughput can be artificially inflated by using aggressive low precision or extreme batch sizes that destabilize training, whereas time-to-accuracy ensures throughput optimizations actually converge to the required model quality
Answer: The correct answer is D. Measuring throughput (samples/sec) in isolation creates an optimization trap: a system could double sample throughput by using numerical shortcuts (e.g., aggressive low precision or excessive learning rates) that cause divergence or require \(3\times\) more iterations to reach the target loss. Time-to-accuracy ties computational speed directly to algorithmic convergence, ensuring that reported performance gains translate into reduced wall-clock training time. Digital timers measure throughput accurately; time-to-accuracy requires full execution rather than simple simulation; batch sizes are fully defined in benchmark configurations.
Learning Objective: Analyze why time-to-accuracy is the primary benchmark metric for training systems rather than raw sample throughput.
A deep learning model trains on a single GPU in \(24\text{ hours}\). With the same total optimizer work, the same training schedule, and the same quality target on the same fixed total dataset (strong scaling), the run completes in \(4\text{ hours}\) on \(8\text{ GPUs}\). What is the strong scaling efficiency, and does this timing result by itself identify the cause of the missing speedup?
- \(75\%\) efficiency; profiling is still required to identify the cause of the missing speedup
- \(100\%\) efficiency; the run achieved linear speedup because \(24 / 4 = 6\)
- \(50\%\) efficiency; GPU memory bandwidth is cut in half whenever multiple GPUs are connected
- \(12.5\%\) efficiency; training time only decreased by a factor of 6
Answer: The correct answer is A. The speedup is \(S = T_1 / T_8 = 24 / 4 = 6\times\), so strong scaling efficiency is \(E = S / N = 6 / 8 = 0.75\) (\(75\%\)). That establishes sublinear scaling, but the elapsed times alone do not uniquely diagnose why the missing \(25\%\) was lost. Profiling is needed to separate communication from other causes such as serial work, input-pipeline limits, or load imbalance. The other answers either miscompute the efficiency or assert a causal mechanism the arithmetic does not support.
Learning Objective: Calculate strong-scaling efficiency and recognize why profiling is required to attribute sublinear speedup to specific bottlenecks.
Explain why a reduced-precision training configuration (such as FP8 or BF16) that achieves a \(1.8\times\) step-level throughput gain could result in a longer wall-clock time-to-accuracy than standard FP32 training.
Answer: Faster steps do not guarantee faster convergence. Reduced precision can change optimization behavior enough that the model needs more update steps to reach the same quality target; if it needs \(2.5\times\) more steps, the total training time becomes about \(2.5 / 1.8 \approx 1.39\times\) longer despite the per-step speedup. For example, an FP8 path may require extra stabilization or lose numerical fidelity on a sensitive workload, while BF16 usually preserves FP32’s exponent range but still changes mantissa precision. The practical consequence is that training benchmarks must compare time-to-quality, not step throughput alone.
Learning Objective: Analyze how reduced precision can improve per-step throughput yet still worsen total time-to-quality when convergence changes.
In distributed training benchmarks, the scaling regime where the total workload remains constant as the number of accelerator nodes increases is known as ____.
Answer: strong scaling. Strong scaling keeps the total work fixed while more processors are added, so the question is whether elapsed time falls in proportion. It matters because any gap from ideal scaling exposes communication, serial work, or imbalance that extra hardware does not remove.
Learning Objective: Explain the distinction between strong scaling and weak scaling in distributed ML training evaluation.
Order the following operational stages of an illustrative successful ML training time-to-accuracy benchmark run from start to finish: (1) Halt training execution and log total elapsed wall-clock time-to-accuracy, (2) Execute distributed forward-backward iterations with gradient synchronization across nodes, (3) Initialize model parameters and data loaders using the run’s documented seed and standardized preprocessing, (4) Check whether the validation accuracy meets or exceeds the declared target quality threshold, (5) Perform periodic evaluation on the held-out validation dataset at predefined intervals
Answer: The correct order is: (3) Initialize model parameters and data loaders using the run’s documented seed and standardized preprocessing, (2) Execute distributed forward-backward iterations with gradient synchronization across nodes, (5) Perform periodic evaluation on the held-out validation dataset at predefined intervals, (4) Check whether the validation accuracy meets or exceeds the declared target quality threshold, (1) Halt training execution and log total elapsed wall-clock time-to-accuracy. Initialization must happen before any training work. Validation can only occur after training has advanced, and the target check depends on having a validation result to inspect. In this successful run, training stops only after the declared quality threshold is satisfied and the elapsed time can be recorded under the run rule.
Learning Objective: Order the stages of an illustrative successful time-to-accuracy training run from initialization through target-quality termination.
Self-Check: Answer
In a distributed serving architecture, assume a user request is dispatched simultaneously to \(10\) backend ML model services, the overall response waits for all \(10\) replies, other latency is negligible, and each service independently has a \(1\%\) probability of exceeding \(20\text{ ms}\) on that request. What is the approximate probability that the user request exceeds \(20\text{ ms}\)?
- Exactly \(1.0\%\)
- Approximately \(9.6\%\) (nearly \(1\) in every \(10\) user requests)
- Exactly \(0.1\%\)
- 0% because parallel aggregation hides individual service latency spikes
Answer: The correct answer is B. Under the stated independence assumption, the probability that all \(10\) services finish within \(20\text{ ms}\) is \(0.99^{10} \approx 0.9044\). Therefore the probability that at least one service exceeds \(20\text{ ms}\), making the overall request exceed \(20\text{ ms}\) because it waits for all \(10\), is \(1-0.99^{10} \approx 0.0956\). The \(1.0\%\) answer ignores fan-out amplification, and \(0.1\%\) treats the event as though all services must be slow simultaneously.
Learning Objective: Analyze how fan-out across independent backend services amplifies tail-latency risk in a waits-for-all distributed inference pipeline.
A cloud provider is deploying an interactive web translation API where independent user requests arrive randomly according to a Poisson process, and the service is evaluated by the throughput it can sustain while meeting a strict tail-latency objective such as \(p99 \le 15\text{ ms}\) (which does not mean every single response must be at or below \(15\text{ ms}\)). Which MLPerf Inference scenario most directly matches this arrival-and-metric regime?
- Offline scenario
- SingleStream scenario
- MultiStream scenario
- Server scenario
Answer: The correct answer is D. The Server scenario models independently arriving requests and evaluates the maximum sustainable throughput subject to a scenario-defined tail-latency constraint. Offline removes online arrivals entirely, SingleStream issues one query at a time, and MultiStream evaluates grouped-query latency percentiles rather than the general cloud-API regime described here.
Learning Objective: Compare MLPerf Inference scenarios by matching their arrival patterns and latency/throughput objectives to a deployment regime.
In serverless and on-demand inference systems, the latency penalty incurred on the first request after an idle period when the runtime has been unloaded or lazily initialized—caused by loading weights into memory and compiling compute kernels—is termed a ____.
Answer: cold start. A cold start is the extra initialization latency paid before the first request can run, and it matters when platforms scale to zero or delay model and runtime setup until demand arrives.
Learning Objective: Explain the cause and impact of cold start latency in on-demand serverless inference deployments.
Explain why reporting an accelerator-only inference time (e.g., \(2\text{ ms}\) on an edge NPU) fails to predict actual mobile application performance, identifying at least two real-world system bottlenecks.
Answer: Accelerator-only timing measures just the model kernel path, not the full request path. Real mobile performance can also depend on CPU-side preprocessing or postprocessing, data movement and synchronization between system components, and sustained thermal behavior under repeated use. For example, a camera pipeline may still spend milliseconds on image decode, resize, and output formatting even if the NPU executes the network quickly; on some integrated SoCs copies may be small or avoided, but the benchmark still must state whether those costs are included. The practical consequence is that end-to-end latency, not accelerator-only latency, determines whether the application feels responsive.
Learning Objective: Evaluate why accelerator-only inference times fail to predict end-to-end mobile performance when preprocessing, data movement, and sustained operating conditions are part of the workload.
**Order the following stages of an illustrative MLPerf Inference Server-scenario evaluation workflow, where this workflow first validates accuracy and then performs a warm, timed performance run:
- LoadGen generates queries according to a Poisson arrival distribution at a target query-per-second (QPS) rate
- SUT receives queries, may apply dynamic batching, executes neural network inference, and returns responses
- Warm up the System Under Test (SUT) with representative queries to populate weights and compile execution graphs
- Validate separately that model output accuracy meets the required reference quality threshold under the specified protocol
- Record end-to-end timestamps for each query and compute the empirical latency distribution (\(p50\), \(p90\), \(p99\)) to verify SLA compliance**
Answer: The correct order is: (4) Validate separately that model output accuracy meets the required reference quality threshold under the specified protocol, (3) Warm up the System Under Test (SUT) with representative queries to populate weights and compile execution graphs, (1) LoadGen generates queries according to a Poisson arrival distribution at a target query-per-second (QPS) rate, (2) SUT receives queries, may apply dynamic batching, executes neural network inference, and returns responses, (5) Record end-to-end timestamps for each query and compute the empirical latency distribution (\(p50\), \(p90\), \(p99\)) to verify SLA compliance. In this stated workflow, separate quality validation happens before the warm, timed run. Warm-up precedes timed traffic so measurements reflect a ready system. Query generation must precede query handling, and latency statistics can only be computed after responses are returned.
Learning Objective: Classify and order the stages of an illustrative MLPerf Inference Server-scenario evaluation workflow, distinguishing separate quality validation from timed performance measurement.
Self-Check: Answer
A vendor advertises an AI accelerator as delivering ‘\(10\text{ TOPS}\) at \(0.5\text{ W}\)’ from a core-only measurement, while a matched measurement of the same workload on the full deployed system shows \(4.5\text{ W}\) of active power at the wall socket. What benchmarking issue most directly explains the difference?
- The vendor drew an isolated power measurement boundary around the compute core silicon only, omitting DRAM interfaces, PCIe host transfers, voltage regulators, CPU preprocessing, and cooling fans
- The electrical wall outlet was defective and provided improper alternating current
- Power consumption in digital circuits is inherently non-deterministic and varies by \(10\times\) between runs
- The vendor measured power during sleep mode rather than active compute
Answer: The correct answer is A. The two numbers use different measurement boundaries: one is core-only, while the other is a full-system active power measurement for the same workload. That boundary difference can include memory interfaces, interconnect activity, power-delivery losses, host-side work, and cooling. The discrepancy alone does not reveal every omitted component exactly, but it does show that quoting a narrow subsystem number is not comparable to wall-socket system power.
Learning Objective: Analyze why explicit power-measurement boundaries are necessary when comparing core-only efficiency claims with full-system power measurements.
Assume switching activity and capacitance stay fixed. An accelerator raises clock frequency by \(5\%\), and useful inference throughput also rises by \(5\%\), but doing so requires a \(15\%\) increase in supply voltage. Using the dynamic-power model \(P \propto V^2 f\), the dynamic power rises by about \(1.15^2 \times 1.05 \approx 1.389\) (\(38.9\%\)). What follows for dynamic performance per watt at this operating point in a power-constrained edge deployment?
- It is an optimal trade-off because throughput is always the only metric that matters
- It represents a severe dynamic energy-efficiency regression, reducing dynamic performance-per-watt to about \(0.756\) of baseline
- Performance-per-watt increases because higher frequency reduces static leakage
- The device will operate cooler because inferences finish \(5\%\) sooner
Answer: The correct answer is B. Under the stated model, useful throughput rises to \(1.05\) while dynamic power rises to \(1.389\), so dynamic performance per watt becomes \(1.05/1.389 \approx 0.756\), about a \(24\%\) drop from baseline. Under the stated assumptions, this is a poor dynamic-efficiency trade. The model here excludes static leakage and other system components, so the conclusion is limited to dynamic performance per watt rather than a full verdict on total power, battery life, or thermals.
Learning Objective: Evaluate how a voltage-frequency operating point can reduce dynamic performance per watt even when throughput increases modestly.
Explain why one instantaneous power reading during an ML inference workload produces misleading results, and describe how standardized protocols calculate total energy.
Answer: One instantaneous reading captures only a momentary operating state, while ML workloads move through phases with different power draw. A prefill-like compute burst, a memory-bound phase, and an idle gap can all have different instantaneous power even within one request. Standardized energy measurement instead matches a measurement window to the workload interval, records or integrates power over that whole window with appropriate instrumentation, and computes total energy as \(E=\int P(t)\,dt\). If the goal is energy per inference, the total energy is then divided by the number of completed inferences in that same window.
Learning Objective: Explain why time-varying execution phases require integrated energy measurement over a matched workload window rather than a single instantaneous power reading.
True or False: In standardized ML power benchmarking, measuring the power draw of the arithmetic compute units (ALUs and tensor cores) is sufficient because the energy required to read and write data from DRAM is negligible in comparison.
Answer: False. Data movement can consume large energy per transfer, but whether it dominates depends on how many such transfers occur, the workload regime, and the rest of the measured system. A benchmark must account for memory events and other relevant components rather than assuming arithmetic units alone determine total energy.
Learning Objective: Evaluate why memory movement and measurement boundaries must be included when assessing ML system energy consumption.
**Order the following steps in an illustrative steady-state ML power measurement workflow from start to finish, where this protocol records an idle baseline before warm-up and then measures a matched active window:
- Integrate instantaneous power readings over the matched active measurement window (\(E = \int P(t) \, dt\)) and compute Joules per inference
- Establish the physical measurement boundary and connect a calibrated power analyzer to the appropriate measurement points
- Execute unmeasured warm-up iterations until the device achieves thermal equilibrium (steady-state junction temperature)
- Measure and record the baseline idle/quiescent power consumption while the system is waiting for requests
- Execute the synchronized inference benchmark workload while logging power over the matched measurement window**
Answer: The correct order is: (2) Establish the physical measurement boundary and connect a calibrated power analyzer to the appropriate measurement points, (4) Measure and record the baseline idle/quiescent power consumption while the system is waiting for requests, (3) Execute unmeasured warm-up iterations until the device achieves thermal equilibrium (steady-state junction temperature), (5) Execute the synchronized inference benchmark workload while logging power over the matched measurement window, (1) Integrate instantaneous power readings over the matched active measurement window and compute Joules per inference. In this illustrative protocol, the boundary and instrumentation must be set first, and the idle baseline is recorded before warm-up because that ordering is part of the stated workflow. Warm-up precedes the timed active window so the measurement reflects steady-state behavior, and integration can only occur after the active measurement window has been collected.
Learning Objective: Classify and order the steps of an illustrative steady-state ML power measurement workflow, including boundary setup, optional idle baseline, warm-up, matched-window measurement, and energy integration.
Self-Check: Answer
An image classification model achieves \(95\%\) accuracy on the CIFAR-10 benchmark test set, but when deployed on a mobile robot operating in a warehouse, its accuracy drops to \(70\%\). Assume the warehouse images are verified to use the same class definitions and preprocessing contract but differ substantially in lighting, motion blur, and camera noise. Which benchmarking limitation most plausibly explains the gap?
- The mobile robot CPU lacked 64-bit floating-point registers
- The CIFAR-10 evaluation used too few random seeds during training
- Incomplete benchmark coverage and distributional narrowness: the benchmark dataset contained clean, centered, low-resolution images that failed to represent warehouse camera noise, lighting variations, and motion blur
- The benchmark harness executed the test set in the wrong order
Answer: The correct answer is C. Given the stated assumptions that the task definition and preprocessing contract are aligned, the most plausible explanation is that the benchmark distribution was too narrow to represent the deployment environment. Clean, centered benchmark images do not prepare the model for warehouse-specific variation such as blur, noise, and lighting changes. Hardware details or seed choices can matter in some cases, but they are not the best explanation for the stated benchmark-to-deployment mismatch.
Learning Objective: Analyze how distributional narrowness in a benchmark dataset can make strong held-out accuracy fail to transfer to a different deployment environment.
Which set of governance and methodological rules does the MLPerf consortium implement to discourage and detect benchmark gaming through benchmark-specific shortcuts?
- Allowing submitters to create proprietary synthetic test datasets that are kept secret from competitors
- Permitting compilers to silently lower numerical precision below IEEE standards without reporting the accuracy impact
- Evaluating systems solely on peak theoretical arithmetic operations per second without measuring execution time
- Enforcing strict Closed Division rules (requiring reference-equivalent workloads under defined allowances), prohibiting benchmark detection code branching, and requiring open peer-review log audits
Answer: The correct answer is D. MLPerf uses reference-equivalent workloads and quality targets in the Closed Division, bans benchmark-specific detection or special-case code paths, and requires audit and review procedures that make shortcuts easier to catch. These mechanisms discourage and detect gaming, even though no governance process can guarantee perfect prevention. Secret datasets, silent undisclosed precision changes, and peak-only reporting would recreate the very benchmarking failures MLPerf was designed to reduce.
Learning Objective: Evaluate how MLPerf uses run rules, reference equivalence, and audits to discourage and detect benchmark-specific gaming.
What is the core insight of the ‘Hardware Lottery’ concept (coined by Sara Hooker in 2021) regarding the relationship between ML benchmarks and research progress?
- An algorithmic research idea often succeeds not because it is universally superior, but because existing hardware accelerators and software compilers happen to be highly optimized for its specific computational pattern (such as dense GEMM)
- Hardware performance is purely random and cannot be measured with scientific accuracy
- Researchers should purchase computer hardware using randomized government lotteries
- Deep neural networks perform identically across all hardware architectures regardless of compiler support
Answer: The correct answer is A. The Hardware Lottery describes how research directions are heavily shaped by hardware availability: algorithms that match prevailing hardware architectures (e.g. dense matrix multiplications on GPUs) achieve high benchmark scores and attract funding, while alternative algorithms (e.g. dynamic sparse graphs, spiking networks) appear slow simply because hardware and software ecosystems are not optimized for them. Claiming hardware performance is random misinterprets the metaphor; lotteries for purchasing hardware is a literal confusion; algorithms vary drastically across hardware architectures.
Learning Objective: Explain how the hardware lottery influences AI research trajectories and architectural preferences.
True or False: If a benchmark measurement is conducted with flawless statistical rigor—using 1,000 independent runs, narrow confidence intervals, and controlled thermal states—its results are guaranteed to predict real-world production system performance.
Answer: False. Narrow confidence intervals quantify uncertainty under the benchmark protocol, but they do not guarantee that the measurement is unbiased, internally valid, or representative of production. A benchmark can be highly repeatable and still miss the real workload, arrival pattern, or input distribution.
Learning Objective: Evaluate why statistical rigor and repeatability do not by themselves guarantee valid or deployment-representative benchmark conclusions.
The structural phenomenon where a machine learning algorithm achieves prominence primarily because specialized hardware and software compilers were already co-optimized for its execution pattern is called the ____.
Answer: hardware lottery. The hardware lottery is the structural advantage enjoyed by methods that align well with the dominant hardware and software stack, even when alternative algorithms might fare better under different execution assumptions.
Learning Objective: Explain the concept of the hardware lottery as a structural bias favoring algorithms that align with prevailing hardware architectures.
Explain the fundamental tension between benchmark stability and benchmark evolution, and describe how benchmark consortia manage this trade-off.
Answer: Benchmark design faces an inherent tension: (1) Benchmark stability is required to enable longitudinal tracking, allowing engineers to compare new hardware generations against historical baselines over multiple years; (2) Benchmark evolution is necessary because static benchmarks eventually saturate (models reach ceiling accuracy), get gamed by over-specialized compilers, and become obsolete as model architectures evolve (e.g., from CNNs to Transformers). Consortia like MLCommons manage this by maintaining fixed benchmark version numbers (e.g., MLPerf v3.0 vs v4.0) with deprecation schedules, retiring saturated tasks, and introducing new representative workloads in scheduled versioned releases.
Learning Objective: Justify the trade-off between benchmark stability for historical comparison and benchmark evolution to reflect modern workloads.
Self-Check: Answer
An image classifier deployed in an autonomous vehicle achieves \(94\%\) top-1 accuracy on ImageNet. After post-training INT8 quantization, consider a bin of predictions to which the model assigns about \(0.99\) confidence on average, but whose observed accuracy is materially lower. Which model evaluation metric directly quantifies this divergence between predicted probability and empirical accuracy?
- Peak Signal-to-Noise Ratio (PSNR)
- Expected Calibration Error (ECE)
- Top-5 classification error
- Hardware FLOPs Utilization (HFU)
Answer: The correct answer is B. Expected Calibration Error (ECE) measures how far predicted confidence and observed accuracy diverge across confidence bins. The scenario describes a calibration problem: the model is assigning very high confidence to a set of predictions whose empirical correctness is lower than that confidence suggests. Top-5 error tracks ranking, not confidence reliability; PSNR is an image-reconstruction metric; and HFU is a hardware-efficiency metric.
Learning Objective: Analyze how Expected Calibration Error quantifies confidence reliability independently of top-1 accuracy.
A clinical risk prediction model achieves an outstanding \(0.92\) ROC-AUC score on a held-out test split from Hospital A’s electronic health records. When deployed at Hospital B in a different city, its ROC-AUC drops to \(0.61\). Assume the implementation and evaluation protocol are matched across sites, and Hospital B differs in patient mix, lab workflows, and clinical protocols. What benchmarking limitation is the best hypothesis for why the standard held-out test failed to predict this deployment failure?
- Hospital B used GPUs with different floating-point rounding modes
- The ROC-AUC metric is mathematically invalid for clinical applications
- The held-out test split shared the same underlying distribution as the training environment, so it could not expose failure under covariate and concept shift at the new site
- The training algorithm suffered from underfitting on Hospital A’s dataset
Answer: The correct answer is C. A standard held-out split tests in-distribution generalization because it is drawn from the same environment as training. Under the stated assumptions, the most informative explanation for the collapse at Hospital B is that deployment changed the input and labeling conditions in ways the held-out test never represented. The other options are weaker fits to the described evidence: ROC-AUC remains a valid metric here, and while implementation details or underfitting can matter in general, they are not the best explanation for this matched-protocol, cross-site shift scenario.
Learning Objective: Evaluate why a held-out test set from the training environment can miss deployment failures caused by covariate and concept shift.
True or False: If an ML deployment passes both system benchmarking (achieving target throughput and low latency) and model benchmarking (preserving validation accuracy and calibration), data benchmarking is unnecessary because software execution and model mathematics are fully verified.
Answer: False. A system can execute at peak hardware efficiency and achieve high benchmark accuracy, yet fail catastrophically in deployment if the training dataset contained systematic label noise, demographic bias, or distributional blind spots that unrepresentative validation sets failed to expose.
Learning Objective: Evaluate whether independent success on system and model benchmarks guarantees deployment readiness without data validation.
The metric that partitions model prediction confidences into discrete bins and calculates the weighted average difference between confidence and accuracy across all bins is called ____.
Answer: expected calibration error. Expected calibration error is a finite-bin empirical measure of how closely predicted confidences match observed correctness frequencies across the evaluation set.
Learning Objective: Explain the concept and calculation of Expected Calibration Error across partitioned confidence bins.
Explain why compression evaluation should be framed as a multi-objective Pareto frontier across accuracy, latency, model size, and memory footprint, rather than a single scalar delta.
Answer: Compression changes several deployment-relevant quantities at once, so one scalar summary can hide an important regression. Quantization can cut FP32-to-INT8 raw weight storage by \(4\times\), yet total memory, latency, and quality effects still depend on activations, runtime support, and hardware behavior. A Pareto frontier helps identify nondominated candidates within the compared set, while separate acceptance gates still enforce minimum quality or latency requirements. The practical consequence is that teams choose configurations that match a deployment budget rather than optimizing one metric blindly.
Learning Objective: Compare compression candidates using a Pareto-frontier view that separates nondominated trade-offs from absolute deployment acceptance gates.
A team deploys an INT8-quantized vision model to an edge TPU for factory defect detection. The deployment passes MLPerf Inference benchmarks and ImageNet validation, but in production, defect detection accuracy collapses from \(98\%\) to \(74\%\). Use the three-dimensional benchmarking framework (System, Model, Data) to propose plausible failure hypotheses and the tests that would distinguish them.
Answer: The framework says not to assume a single cause from the production drop alone. On the System axis, check whether the deployed pipeline matches the benchmarked one by measuring end-to-end preprocessing, operator coverage, fallback paths, and numeric execution on the target hardware. On the Model axis, compare FP32 and INT8 on a held-out factory dataset to test whether quantization changes classification on the defect task specifically, and evaluate calibration separately with confidence-versus-frequency reliability analysis rather than treating it as the same question. On the Data axis, inspect whether factory images differ from development data in lighting, blur, camera viewpoint, or defect frequency. Diagnosis should proceed through these discriminating tests rather than through a single invented explanation.
Learning Objective: Apply the system-model-data framework to generate discriminating hypotheses and validation tests for a benchmark-to-production accuracy collapse.
Self-Check: Answer
What is the primary fallacy in using an accelerator’s peak advertised TFLOP/s to estimate the serving capacity of an ML inference deployment?
- Peak TFLOP/s assumes a specific arithmetic path, precision, and favorable shapes, while ignoring memory bandwidth bottlenecks, runtime overhead, non-model pipeline stages, and batch-shape variation
- Peak TFLOP/s is an obsolete metric that is no longer measured by hardware vendors
- Accelerators always run at exactly 50% of their peak TFLOP/s due to hardware safety limiters
- Peak TFLOP/s applies only to CPU floating-point units and has no meaning for GPUs or TPUs
Answer: The correct answer is A. Peak TFLOP/s is a ceiling for a particular arithmetic path under favorable execution conditions, not a prediction of whole-service throughput. Real serving capacity also depends on memory traffic, launch and dispatch overhead, preprocessing and postprocessing, and the actual batch and shape regime. The other answers are wrong because vendors do publish TFLOP/s, there is no universal 50% limiter, and GPUs and TPUs absolutely use throughput units of this form.
Learning Objective: Analyze why peak arithmetic-throughput specifications do not directly predict sustained serving capacity.
An engineering team modifies an inference server configuration, increasing throughput from \(1,000\text{ QPS}\) at \(1.8\text{ W}\) to \(1,200\text{ QPS}\) at \(4.2\text{ W}\) for the same quality target and measurement boundary. What is the systems consequence of this change?
- It is an unambiguous improvement because throughput is \(20\%\) higher
- The system suffered a \(48.6\%\) reduction in energy efficiency (dropping from \(556\text{ QPS/W}\) to \(286\text{ QPS/W}\)), which is a major regression under power-constrained objectives
- The system will run cooler because queries complete faster
- Operating cost is reduced because higher throughput always decreases data center power bills
Answer: The correct answer is B. Energy efficiency fell from \(1{,}000/1.8 = 555.6\text{ QPS/W}\) to \(1{,}200/4.2 = 285.7\text{ QPS/W}\), a \(48.6\%\) drop. That is a clear regression if the deployment is constrained by battery, power, or thermal limits. A team might still choose the new operating point for capacity or latency reasons, but the efficiency trade-off must be stated explicitly rather than hidden behind the throughput increase.
Learning Objective: Calculate how a throughput increase can still represent an efficiency regression when power rises disproportionately under a fixed quality target and measurement boundary.
True or False: If a newly released open-source model ranks #1 on a public benchmark leaderboard, an enterprise can deploy it into production with confidence that it will outperform existing models on company workloads.
Answer: False. Leaderboard rankings reflect performance under specific, static benchmark conditions that often reward test-set overfitting, excessive compute scaling, and uncalibrated predictions. Production deployments operate under different data distributions, strict latency SLAs, cost constraints, and safety requirements that public leaderboards do not capture.
Learning Objective: Evaluate whether high rankings on public benchmark leaderboards guarantee superior production performance.
Explain why an accuracy-saturated capability benchmark becomes less discriminative as a progress indicator for ML systems, and describe which complementary evaluations can preserve its usefulness as a regression baseline.
Answer: Once a static benchmark becomes saturated, small score differences become less informative about real capability because they can reflect benchmark-specific tuning, narrow artifacts, or limited remaining headroom. For example, a leaderboard gain on a mature benchmark may say less about deployment robustness than about optimization to a familiar test set. The practical response is not to discard static benchmarks entirely, since they remain useful for stable latency or energy regression tracking, but to complement them with dynamic benchmarks, robustness and distribution-shift evaluations, and multi-objective measurements that include system costs.
Learning Objective: Explain why saturated capability benchmarks become less discriminative and why they should be complemented with dynamic, robustness, and systems-oriented evaluations.
Explain how Goodhart’s Law manifests when teams optimize exclusively for benchmark scores, using a concrete systems example where metric chasing degrades production quality.
Answer: Goodhart’s Law appears when the benchmark metric stops acting as a proxy for the real deployment goal and becomes the goal itself. For example, a serving team can tune for high offline batch throughput by using very large batches when all benchmark inputs are already available upfront. If the same batching policy is imposed on live arrivals, requests must wait for batch assembly before execution, which can worsen user-visible latency even though the offline throughput score improved. The benchmark must preserve the deployment’s latency objective instead of rewarding throughput in isolation.
Learning Objective: Explain how optimizing a benchmark metric in isolation can degrade the deployment objective it was supposed to approximate.