
8 Model Training
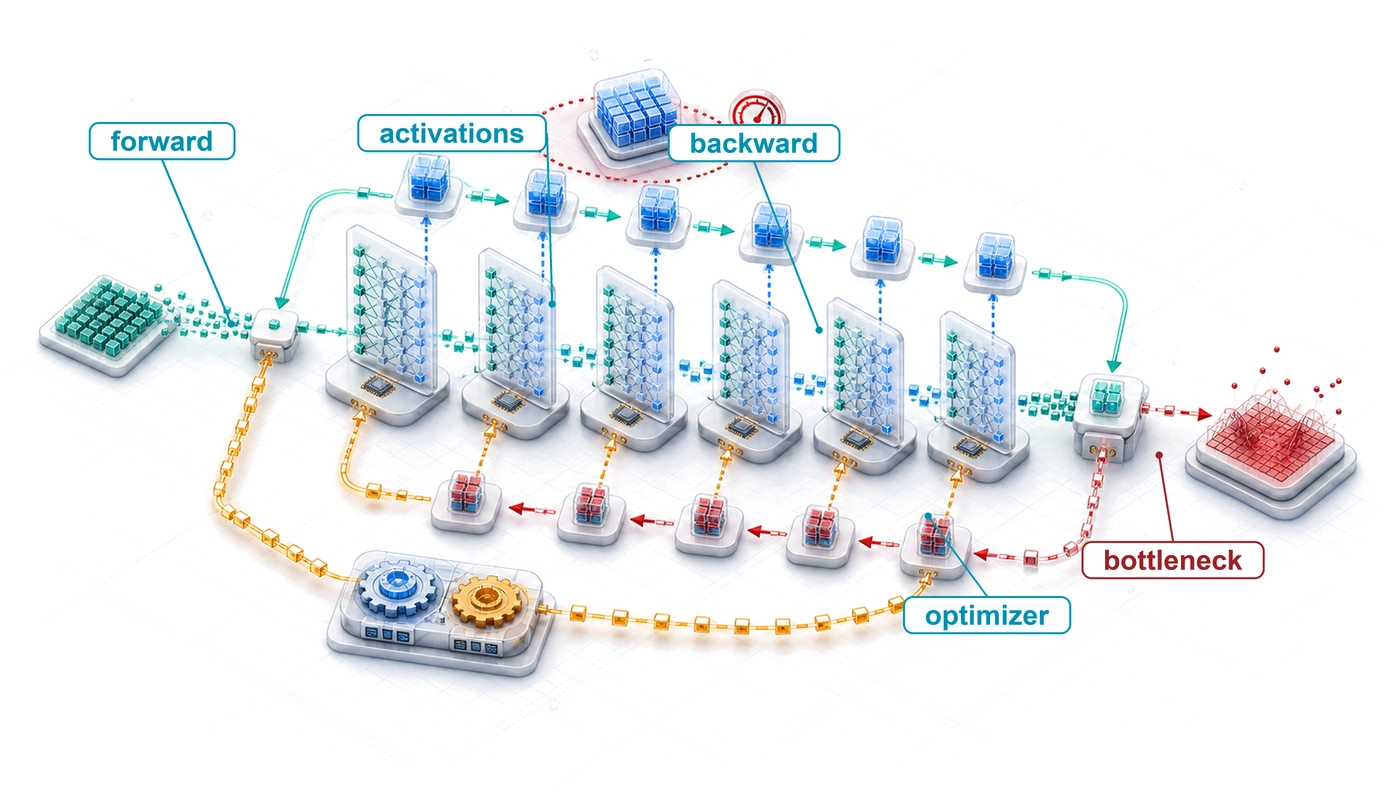
Purpose
Architecture stack focus for this chapter.
Why can training a model cost orders of magnitude more than one inference?
Inference computes a forward pass as data flows through the network and a prediction emerges. Training adds a backward pass and an optimizer step, retains intermediate state, and repeats that work across many examples and optimization steps. Optimizers may also maintain momentum and variance estimates whose storage exceeds the model weights, so memory rather than arithmetic often decides what fits on a device. The ratio depends on the model, workload, training duration, and inference volume, but one training run commonly costs orders of magnitude more than one inference. A lab that trains in three days can explore many more designs than one that takes a month. Over a year, that difference is more than a hundred iterations against about a dozen, and each result informs the next design while the slower lab waits weeks for every answer. A faster step is not faster training if it delays convergence, so throughput matters only relative to time to target quality. Across repeated experiments, even modest changes in convergence or utilization compound into substantial schedule and cost differences. The central systems challenge is to keep accelerators supplied with data and useful arithmetic without exhausting memory or losing time to synchronization. Which intervention helps depends on the binding compute, memory, data, or communication constraint, so profiling must precede scaling or optimization. Batch size, numerical precision, checkpointing, data loading, and parallelism must therefore be treated as coupled decisions rather than independent tuning knobs. For the systems engineer, training is where hardware and parallelism determine whether a run fits within memory, schedule, and budget, and whether the repeated optimization loop accelerates or stalls. In D·A·M terms, each precision and parallelism decision trades the mathematics of optimization against the physics of execution.
Learning Objectives
- Explain training cost asymmetry using forward, backward, optimizer-state, data, and iteration costs
- Calculate FLOPs, run time, energy, activation memory, optimizer state, and dollar cost for full training and fine-tuning
- Compare SGD, Adam, and AdamW by convergence behavior, memory overhead, and compute cost
- Design single-machine training pipelines with prefetching, overlap, batching, and checkpointed training state
- Diagnose compute-, memory-, and data-bound training bottlenecks with profiling evidence and model FLOPs utilization
- Apply mixed precision, FlashAttention, gradient accumulation, and activation checkpointing to fit accelerator memory and throughput limits
- Evaluate single-machine multi-accelerator configurations using memory, duration, communication, energy, and cost constraints, and recognize when a workload exceeds the node boundary
8.1 From One Step to a Training Run
A training run is one training step repeated millions of times, so every byte a step holds and every millisecond it spends is multiplied by the length of the run. Each step reads a batch of examples, computes a forward pass and a loss, propagates gradients backward, and updates every parameter, and the run repeats that sequence until the model reaches its quality target. The anatomy of a training step in Anatomy of a Training Step traced one such step for a two-layer MNIST classifier, a smaller sibling of the three-layer network of Neural Computation: 101,770 parameters, about 19.5 MFLOP per batch of 32 images by the dense-training rule (somewhat less in that chapter’s exact trace, which skips the gradient of the raw input), and 1.6 MB of weights, gradients, and optimizer state. One step of GPT-2 XL over 32 sequences of 1,024 tokens costs about 295 TFLOP, roughly 15 million times the classifier’s arithmetic, and its weights, gradients, and optimizer state occupy 24 GB before a single activation is stored. The framework mechanisms that made the small step possible leave every decision about the large run open: which intermediate activations to keep when high-bandwidth memory (HBM) runs out, how large a batch the memory permits, how to keep the accelerator supplied with data, and when one accelerator stops being enough. Running a model once and training it from scratch sit at opposite ends of the operational spectrum, and the size of that gap defines the discipline of training systems.
In 2019, training a GPT-2-scale model required approximately $50,000 in compute resources, whereas pretraining a frontier architecture such as GPT-4 reached an estimated $100M.1 Although neither figure represents an audited financial disclosure, the more than three-order-of-magnitude gulf between them highlights the economic reality of deep learning. This training cost asymmetry reflects the gap between running a trained model on a single query and repeating the forward-backward-update loop across an entire corpus.
1 Training cost scaling: The roughly 2,000\(\times\) ratio between this chapter’s two cost anchors illustrates how parameter counts, training-token budgets, hardware generations, and accelerator fleets can compound; it is not a controlled comparison of disclosed training bills. OpenAI’s GPT-2 report documents the model and training setup but does not disclose training cost (Radford et al. 2019). Exact GPT-4 training details were also not disclosed, so the GPT-4-class figure is explicitly an industry estimate supported by public reporting and independent infrastructure analysis (Knight 2023; Patel and Wong 2023).
Radford, Alec, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, and Ilya Sutskever. 2019. Language Models Are Unsupervised Multitask Learners. OpenAI.
Knight, Will. 2023. OpenAI’s CEO Says the Age of Giant AI Models Is Already over. WIRED.
Patel, Dylan, and Gerald Wong. 2023. GPT-4 Architecture, Infrastructure, Training Dataset, Costs, Vision, MoE. SemiAnalysis Blog.
For GPT-2, a single forward token evaluation consumes roughly 3.00 × 10⁹ floating-point operations, derived from standard transformer architectural accounting (Radford et al. 2019). Pretraining the full model across its WebText corpus required a cumulative budget of 1.50 × 10²¹ FLOPs, equivalent to approximately 167 billion token evaluations when forward and backward passes are evaluated together.
Definition 8.1: Training systems
Machine learning training systems are software-hardware systems that execute the iterative optimization loop (forward pass, loss computation, backward pass, and parameter update) to minimize a loss function over a training dataset.
- Significance: Training holds far more state per parameter than inference. In the common mixed-precision recipe with the Adaptive Moment Estimation (Adam) optimizer, gradients and optimizer state raise the per-parameter footprint to 8× the FP16 weights an inference server stores, before any activation is counted (section 8.3.2.3 derives the multiplier). This multiplier is a major reason a model that serves on one accelerator needs several for training.
- Distinction: Unlike inference systems, which execute a single forward pass and discard intermediate activations, standard backpropagation stores the tensors needed by the backward pass, creating a footprint that grows with model depth and batch size.
- Common pitfall: A frequent misconception is that training failures are compute problems. A common failure is an out-of-memory (OOM) error, a memory-management problem: tensors saved for backpropagation accumulate during the forward pass and can exhaust memory before the first gradient is computed.
Three characteristics distinguish training workloads from general-purpose computing, and each demands a targeted systems intervention. First, computational intensity dominates the schedule: spreading the 1.50 × 10²¹ FLOPs budget over days of wall-clock time requires sustained PFLOP/s-scale throughput from hardware whose realized large-model throughput is often far below theoretical peak (Narayanan et al. 2021; Chowdhery et al. 2022), pushing the system toward higher arithmetic utilization and lower-precision numeric formats. Second, memory pressure compounds across four state tensors: storing 1.5B weights requires 6 GB in FP32, the Adam optimizer adds two state tensors per parameter that consume another 12 GB, and activation memory adds a workload-dependent footprint governed by architecture, sequence length, batch size, precision, and checkpointing. Because the combined state can exceed a single accelerator’s capacity, training systems rely on gradient checkpointing,2 which trades redundant arithmetic for reduced activation storage, and mixed-precision training,3 which halves activation storage by casting activations to 16-bit formats while retaining FP32 master weights and optimizer moments for numerical stability.
2 Gradient checkpointing (activation checkpointing): Backpropagation retains the forward values required by each backward rule. Checkpointing saves selected values and recomputes others during backward, trading additional work for lower activation memory. The \(\sqrt{\LayerCount}\) checkpoint placement and its associated recomputation cost describe the classical schedule analyzed by Chen et al. (2016) rather than every checkpointing implementation. Section 8.6.5.2 works through that schedule for GPT-2’s layer count.
Chen, Tianqi, Bing Xu, Chiyuan Zhang, and Carlos Guestrin. 2016. “Training Deep Nets with Sublinear Memory Cost.” arXiv Preprint arXiv:1604.06174.
3 Mixed-precision training: Uses lower precision for selected computation and storage while retaining higher precision where accumulation or numerical range requires it. A common FP16 recipe maintains FP32 master weights and uses loss scaling to reduce gradient underflow (Micikevicius et al. 2018). BF16 (“Brain Floating Point,” from Google Brain (Wang and Kanwar 2019)) matches FP32’s 8-bit exponent range and therefore usually avoids dynamic loss scaling, though the exact state and accumulation precision depend on the optimizer and implementation.
Micikevicius, Paulius, Sharan Narang, Jonah Alben, Gregory Diamos, Erich Elsen, David Garcia, Boris Ginsburg, et al. 2018. “Mixed Precision Training.” International Conference on Learning Representations (ICLR).
Wang, Shibo, and Pankaj Kanwar. 2019. BFloat16: The Secret to High Performance on Cloud TPUs.
Third, sequential data dependencies tie each gradient update to the result of the previous one, limiting how much parallelism the system can exploit across steps. Hiding the non-compute work inside each step therefore requires pipeline architectures that overlap I/O and communication with computation so that execution units do not stall waiting for input. The analysis here establishes the execution baseline on single-machine and single-node multi-GPU topologies; scaling across distributed network boundaries introduces multi-node communication fabrics and fault-tolerance protocols treated in advanced distributed systems texts.
↩︎ The feeding problem, in which data delivery must keep pace with accelerator consumption, is established in The feeding problem.
8.1.1 Running cases: GPT-2 XL and ResNet-50
GPT-2 is the book’s bandwidth-bound lighthouse. Generating one token at a time reads every weight for little arithmetic, so in inference its home regime is the bandwidth-bound one. Training changes that profile. A batch of long sequences reuses each weight across thousands of token positions, so the same model now presses on arithmetic throughput and, through activations and optimizer state, on memory capacity. The chapter uses it to test each training cost and optimization.
↩︎ GPT-2’s home regime in inference, bandwidth-bound because each generated token rereads every weight, is established in Workload archetypes.
Lighthouse 8.1: Lighthouse example: Training GPT-2
Context: GPT-2 (1.5 billion parameters) serves as the primary case study because it is large enough to expose meaningful compute, activation, and optimizer-state constraints while remaining easier to analyze than frontier-scale models. Whether it requires distributed training depends on precision, optimizer state, activation memory, hardware capacity, and the target training time. Table 1 maps each model property to the systems constraint it creates:
Table 1: GPT-2 (1.5 Billion Parameters) Lighthouse Model Specifications: Parameter count, architecture depth, dataset size, and total training compute mapped to their systems implications. Each row pairs a model property with the engineering constraint it creates: memory footprint for weights, activation pressure from pipeline depth, I/O throughput requirements, and parallelization demand.
| Property | Specification | Systems Implication |
|---|---|---|
| Parameters | 1.5B (XL) | Requires ~3 GB (FP16) or ~6 GB (FP32) for weights alone. |
| Architecture | 48 Layers, 1600 Dim | Deep pipeline creates heavy activation memory pressure. |
| Dataset | WebText (40 GB) | Preprocessing, shuffling, and delivery must sustain the selected training configuration. |
| Compute | ~ 1.50 × 10²¹ FLOPs | Training duration depends on achieved throughput and accelerator count. |
Mechanism: In dense transformer models, the arithmetic work per token is directly proportional to parameter count \(\Parameters\). In the forward pass, each parameter participates in one multiply-accumulate operation (\(1\text{ MAC} = 2\text{ FLOPs}\)), consuming \(2\Parameters\text{ FLOPs/token}\). Backpropagation computes two matrix products per parameter: one to propagate gradients backward with respect to activations (\(2\Parameters\text{ FLOPs}\)), and another to calculate weight gradients for the optimizer (\(2\Parameters\text{ FLOPs}\)). The backward pass therefore requires twice the compute of the forward pass (\(4\Parameters\text{ FLOPs/token}\)), yielding a total work factor of \(2\Parameters + 4\Parameters = 6\Parameters\text{ FLOPs/token}\). Across a dataset of \(\DatasetSize\) tokens, total training work is \(\Operations \approx 6 \cdot \Parameters \cdot \DatasetSize\), or 1.50 × 10²¹ FLOPs.
Training GPT-2 couples this operation count with the four-term training-memory budget of equation 5.29, \(\TotalMemoryFootprint =\WeightMemory + \GradientMemory + \OptimizerStateMemory + \ActivationMemory\). Balancing execution time \(\TrainingTime= \frac{\Operations}{\PeakRate \times \EfficiencyHw}\) requires orchestrating data ingestion, activation memory, and compute throughput within accelerator HBM capacity.
ResNet-50, the book’s compute-bound lighthouse, carries the chapter’s input pipeline. Its home regime is compute-bound because a convolution reuses each weight at every spatial position, so one \(224{\times}224\) image costs about 8.2 GFLOP in the forward pass and about 24.6 GFLOP once the backward pass is added, for only 25.6 million parameters. Training it on a current data-center accelerator moves the binding term upstream. Each image must be read, decoded, and augmented on the host before the accelerator sees it, and the data pipeline (section 8.4.2) shows the accelerator consuming images faster than the host processors can prepare them. The two cases therefore cross regimes in opposite directions. GPT-2 leaves its bandwidth-bound home for arithmetic and memory capacity, while ResNet-50 leaves its compute-bound home for an input-bound one.
Every number in the chapter uses one reference machine, an NVIDIA H100 with 80 GB of HBM delivering 3.35 TB/s and a dense 16-bit arithmetic peak of 989 TFLOP/s. The H100 is a point-in-time instance of the data-center accelerator class whose design Hardware Acceleration develops; its successors change the constants, not the reasoning.
The chapter follows GPT-2 XL’s run from estimate to execution (table 2). The first half converts the run’s operation count into time and energy, accounts for the arithmetic and bytes of one step, and assembles the pipeline that executes it, including the checkpoints that let a long run survive failure. The second half diagnoses a measured step, removes its binding term one technique at a time until GPT-2 XL trains on a single accelerator, and closes with when and how to add accelerators.
| Section | Question it answers | Law term or constraint it moves | Running case |
|---|---|---|---|
| Training-Time Law | How long, and how much energy, a run takes | All terms of \(\TrainingTime = \Operations/(\PeakRate \times \EfficiencyHw)\) | GPT-2 XL run on one H100 |
| Computation and Memory Costs of Training | What one step costs in FLOPs and in bytes | \(\Operations\) per step; the memory constraint | GPT-2 XL step; Llama 3 8B fine-tuning |
| Pipeline Architecture | How data, compute, updates, and saved state flow through a step | \(\EfficiencyHw\) lost between stages | ResNet-50 input feed; GPT-2 XL step |
| Identifying Bottlenecks | Which stage limits a measured step | \(\EfficiencyHw\), diagnosed | GPT-2 XL profile |
| Pipeline Optimizations | Which technique removes the binding term | \(\PeakRate\) (precision), \(\EfficiencyHw\) (overlap, IO), memory (accumulation, checkpointing) | GPT-2 XL on one H100 |
| Scaling Training Systems | When to add accelerators, and what synchronization costs | \(\PeakRate \times \EfficiencyHw\) across devices, less communication | GPT-2 XL on an eight-H100 node |
Self-Check: Question
A 7-billion-parameter model uses 14 GB of FP16 weights for inference and fits comfortably on a single 40 GB accelerator. Switching the same model to standard mixed-precision Adam training causes immediate out-of-memory failures even before activations are accounted for. Using the mixed-precision Adam accounting that the section previews, which factor is most directly responsible?
- Adam internally re-runs the forward and backward passes, so the same weights must be stored several extra times during each step.
- Adam adds 14 GB of FP16 gradients, 28 GB of FP32 master weights, and 56 GB of FP32 first- and second-moment state, pushing the static training state to about 112 GB before activations.
- Adam requires the full training corpus to be cached in accelerator memory so batches can be reused across optimizer steps.
- Adam forces all model tensors into FP64 during backpropagation, which multiplies the weight footprint beyond device capacity.
True or False: Sudden NaN loss spikes during mixed-precision training are usually the same failure mode as an out-of-memory error, because both come from the GPU running out of memory during backpropagation.
In machine learning frameworks, the technique of discarding selected intermediate forward activations and recomputing them on demand during the backward pass to reduce peak memory is known as activation ____ (or gradient checkpointing).
8.2 Training-Time Law
Every later estimate in the chapter starts from how long the run takes, and the training-time law fixes that first. GPT-2 XL’s run needs about 1.50 × 10²¹ FLOPs. Converting that operation count into days on an accelerator, and every loss of time into a factor engineering can recover, requires a decomposition of training time into its physical constituents in which wasted time appears as a lower utilization factor.
The iron law of ML systems (principle 3) supplies that decomposition directly once specialized to training. In its multiplicative D·A·M form, a training run processes \(\DatasetSize\) tokens (Data) at roughly \(6\Parameters\) forward-and-backward FLOPs per token (Algorithm), for \(\Operations = 6 \cdot \Parameters \cdot \DatasetSize\) total operations, at a realized machine pace of \(1/(\PeakRate \times \EfficiencyHw)\) seconds per FLOP (Machine). This training-time form of the iron law, which this chapter shortens to the training-time law, keeps that macroscopic product as the organizing equation so that every optimization technique maps to one of its factors.
Definition 8.2: The training-time law
The training-time law expresses training time through the workload’s operation count and its effective achieved throughput: \[\TrainingTime= \frac{\Operations}{\PeakRate \times \EfficiencyHw} \tag{1}\]
Here \(\Operations\) counts useful model forward-and-backward FLOPs, excluding rematerialization. Additional execution work is reflected in effective throughput. The factor \(\EfficiencyHw\) is an effective end-to-end utilization factor, the achieved model-operation rate divided by the relevant hardware peak. Data stalls, communication, synchronization, launch overhead, and inefficient kernels all reduce this factor. Prefetching and overlap can hide part of those costs but do not guarantee their removal.
- Significance: In the D·A·M taxonomy, these terms map directly to the three multiplicative factors. The numerator \(\Operations = (\text{Samples/Task}) \times (\text{FLOPs/Sample})\) is governed by Data (training token count \(\DatasetSize\)) and Algorithm (model architecture or compression methods such as pruning and distillation), while the Machine factor \(\text{Seconds/FLOP} = 1/(\PeakRate \times \EfficiencyHw)\) combines hardware execution units at the chosen numerical precision (\(\PeakRate\)) with effective systems utilization (\(\EfficiencyHw\), the primary engineering target, where Narayanan et al. (2021) measured 44 to 52 percent of theoretical peak throughput across GPT models trained on A100 clusters). Model Compression defines the compression techniques; here they serve only to show where such methods enter the accounting.
- Distinction: The training-time law (equation 1) is the macroscopic D·A·M product form of the iron law, folding every non-arithmetic delay into \(\EfficiencyHw\). When \(\EfficiencyHw\) is low, the unpacked three-term iron law exposes data movement (\(\DataVolume/\Bandwidth\)), kernel computation, and fixed latency (\(\Latency\)) separately to diagnose which underlying bottleneck is responsible.
- Common pitfall: A frequent misconception is that \(\EfficiencyHw\) is fixed by hardware. It is a pipeline property, so diagnosing which factor dominates requires profiling rather than reading hardware specs.
Equation 1 reveals three levers for improvement: reduce total operations through data curation or algorithmic innovation, increase peak throughput through hardware selection and precision formats, or improve utilization through pipeline orchestration. Memory does not appear in the law at all. It acts as a feasibility constraint, because a configuration whose state does not fit runs at no speed. The chapter map (table 2) shows which section works on which factor, and table 8 places each optimization technique against the factor it moves, with its memory effect listed separately.
The training-time law focuses on execution efficiency, how fast the hardware processes a given workload. It does not predict how data quality, dataset size, or curriculum design determines the total operations \(\Operations\) needed to reach a target accuracy; that workload must be supplied or estimated separately. A cleaner dataset or a better data mix can reduce the number of epochs required, shrinking \(\Operations\) without touching hardware at all. Holding the workload fixed, the question is how to execute it as fast as possible.
↪ Data selection, which shrinks total operations (\(\Operations\)) by keeping the examples that return the most learning per unit of compute, is developed in The Data Wall.
Actual training throughput remains below the arithmetic peak whenever kernels, data delivery, or communication leave resources idle. Scaling to multiple accelerators introduces additional communication overhead, a trade-off quantified in section 8.7.
For GPT-2 XL on the reference H100, the law becomes a schedule. At the accelerator’s 989 TFLOP/s dense 16-bit peak and a utilization \(\EfficiencyHw\) of 50 percent, the high end of what large training runs sustain (Narayanan et al. 2021), the run takes about 35 days on one accelerator, about 5.1 million steps of 0.60 s each over 32 sequences of 1,024 tokens. Time converts directly into energy. Energy is power integrated over time, \(\TotalEnergy = \DevicePower \times \TrainingTime\) at constant power, so at the H100’s 700 W thermal design power the run draws about 590 kWh at the accelerator alone, about 417 J per step. Every technique that shortens the run at constant power removes energy in the same proportion, which is why the utilization factor matters to an energy budget as much as to a schedule.
↩︎ The iron law’s first estimate of a training run, the same operation-count-to-days conversion applied to a GPT-3-class model on an accelerator cluster, is established in Iron Law of ML Systems.
The same conversion scales to runs far larger than GPT-2. A 70B-parameter Llama 2 model trained on 2T tokens across a 1,024-accelerator H100 cluster at the same utilization takes about 19.2 days and $1.89M of rented accelerator time, while buying that cluster costs as much as about 16.3 such runs before networking, facilities, power, and staff are counted (Total cost of ownership develops the full cost model).
Not every training workload is bound by arithmetic. DLRM, the book’s capacity-bound lighthouse, holds 100B to 10T parameters, mostly in embedding tables, so its first training problem is fitting those tables in memory at all, whereas dense models such as GPT-2 meet arithmetic and activation-memory limits first.
Checkpoint 8.1: The physics of training
Training speed is governed by the utilization of hardware peaks.
Utilization gap
Each milestone in the history of deep learning moved the binding constraint from one factor of this law to another. Backpropagation, popularized for multilayer networks in 1986 (Rumelhart et al. 1986), made the operation count \(\Operations\) of a deep network computable at all. AlexNet’s five-to-six-day ImageNet run on two GPUs in 2012 (Krizhevsky et al. 2012) showed that this arithmetic mapped onto the far higher \(\PeakRate\) of graphics hardware. Transformers from 2017 onward (Vaswani et al. 2017) concentrated the work into large dense matrix multiplications with large activation footprints. GPT-3’s roughly \(3.14 \times 10^{23}\) FLOPs in 2020 (Brown et al. 2020) made utilization \((\EfficiencyHw)\) the difference between an affordable run and an unaffordable one, and IO-aware kernels such as FlashAttention later raised \(\EfficiencyHw\) by attacking attention’s memory traffic.
Vaswani, Ashish, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N. Gomez, Lukasz Kaiser, and Illia Polosukhin. 2017. “Attention Is All You Need.” Advances in Neural Information Processing Systems (NeurIPS) 30: 5998–6008.
The history follows the bitter lesson. Backpropagation supplied a general recipe, and each later step let that recipe absorb more computation, more parameters, and more data. If capability tracks the computation a general method can absorb, then every point of \(\EfficiencyHw\) lost to stalls, and every gigabyte of memory that forces a smaller model or batch, is capability forgone at a fixed budget. The first obligation of a training system is therefore to convert its compute budget into useful operations as completely as the hardware allows.
↩︎ The bitter lesson, that general methods which absorb more computation outperform encoded human expertise, is established in The Bitter Lesson.
Goto, Kazushige, and Robert A. van de Geijn. 2008. “Anatomy of High-Performance Matrix Multiplication.” ACM Transactions on Mathematical Software 34 (3): 1–25. https://doi.org/10.1145/1356052.1356053.
Hennessy, John L., and David A. Patterson. 2017. Computer Architecture: A Quantitative Approach. 6th ed. Morgan Kaufmann.
The law takes a run’s operation count and its achieved rate as given, and both come from the costs of individual operations. Every bottleneck traces back to specific mathematical operations: compute-intensive matrix multiplications governed by peak throughput (Goto and Geijn 2008), low-intensity normalization layers governed by memory bandwidth, and optimizer state tensors that inflate the static memory footprint. Modern accelerators have compute-to-bandwidth ratios (roofline ridge points) that far exceed the arithmetic intensity of many neural network layers, leaving memory-bound kernels starved for operands (Hennessy and Patterson 2017). Software frameworks expose these physical boundaries as configurable switches, such as mixed-precision autocasting contexts or activation checkpointing flags, and each switch must be set against the machine’s measured limits rather than tuned blindly. Optimizing a training system therefore begins with what each operation costs in FLOPs and bytes.
Self-Check: Question
A training run has confirmed that input delivery and communication are off the critical path. The model FLOP count and the peak-throughput convention are being held fixed, yet profiling still reports only 38 percent effective end-to-end utilization relative to the stated peak. Under the training-time law \(T_{\text{train}} = \frac{O}{R_{\text{peak}} \times \eta_{\text{hw}}}\), which lever is the most direct target for the next round of profiling?
- Hardware utilization \(\eta_{\text{hw}}\), because with \(O\) and the relevant \(R_{\text{peak}}\) convention fixed, the remaining gap points to how efficiently kernels are being executed end to end.
- Peak throughput \(R_{\text{peak}}\), because low effective end-to-end utilization relative to the stated peak automatically means the hardware peak specification is too small for the workload.
- Total operations \(O\), because once data and communication are hidden, utilization is no longer relevant to training time.
- Dataset size, because shrinking the number of tokens directly raises effective end-to-end utilization relative to the stated peak even when execution efficiency is unchanged.
When a team transitions a model from FP32 training to mixed-precision (FP16/BF16) on Tensor Core accelerators without changing the model architecture, batch size, or dataset, which term of the training-time law (\(T_{\text{train}} = \frac{O}{R_{\text{peak}} \times \eta_{\text{hw}}}\)) is most directly improved?
- Total operations \(O\), because lower numerical precision halves the number of multiplications required in each matrix multiplication.
- Hardware utilization \(\eta_{\text{hw}}\), because mixed precision automatically eliminates all GPU pipeline bubbles and CPU data stalls.
- Peak throughput \(R_{\text{peak}}\), because Tensor Cores provide a substantially higher theoretical FLOP/s ceiling for reduced-precision matrix operations compared to standard FP32 execution units.
- Data volume \(D_{\text{tokens}}\), because lower precision requires fewer training tokens for the loss to converge.
Explain the scope conditions under which the simplified training-time law \(T_{\text{train}} = \frac{O}{R_{\text{peak}} \times \eta_{\text{hw}}}\) is useful, and identify why the formula alone cannot diagnose a slow small-batch debugging run.
True or False: All large deep learning models are primarily compute-bound, so training speed is always governed mainly by Tensor Core TFLOP/s.
Place the following milestones in chronological order, reflecting how training-system constraints evolved: (1) Transformers shift sequence modeling toward high-throughput dense matrix multiplication and large activation footprints. (2) Backpropagation is popularized for multilayer neural networks. (3) Large-scale foundation models such as GPT-3 make utilization and multi-accelerator scaling central engineering concerns. (4) AlexNet demonstrates that deep neural network training maps effectively to GPUs. (5) IO-aware FlashAttention appears as a response to attention memory-bandwidth limits.
8.3 Computation and Memory Costs of Training
In a model such as GPT-2, the tensors participating in a single training step far exceed the 30 to 50 MB of on-chip SRAM available on a modern accelerator, so executing a layer’s matrix multiplication \(\PreactivationMatrix= \ActivationMatrix\WeightMatrix\) requires staging matrix tiles continuously across two levels of the physical memory hierarchy. Off-chip global device memory (HBM or GDDR) offers large storage capacity (typically 16 to 96 GB) to hold weights, optimizer states, and large activation tensors, whereas on-chip SRAM (registers and shared memory) sits directly on the processor die adjacent to the arithmetic execution units. Because the external memory bus bounds HBM traffic to roughly \(1.5\text{--}3.5\text{ TB/s}\) while on-chip SRAM delivers roughly \(15\text{--}20\text{ TB/s}\) across its 30 to 50 MB capacity, performance depends on how much work a kernel performs for every byte it fetches from HBM.
Dense matrix multiplications have high arithmetic intensity, amortizing the cost of moving bytes from HBM into SRAM over many operations and enabling specialized execution units such as Tensor Cores4 to achieve high compute utilization. In contrast, surrounding elementwise operations (activations, normalizations, and residual additions) have low arithmetic intensity and remain bounded by memory bandwidth, creating opportunities for kernel fusion to eliminate redundant round-trips to HBM. Neural Computation established what neural network operations compute and why they enable learning; the systems question is what they cost in FLOPs, memory, and bandwidth when those operations execute at scale.
4 Tensor Core: A specialized matrix-multiply-accumulate unit that supports reduced-precision inputs and higher-precision accumulation. Supported tile shapes, alignment constraints, and peak-throughput ratios vary by architecture, dtype, sparsity mode, and library kernel.
Four dimensions structure this cost analysis: the FLOP counts of the matrix operations that dominate dense neural-network training, the optimizer state (the fixed bytes per parameter that every update reads and writes), the activation memory (the batch-dependent bytes that backpropagation must keep), and the arithmetic intensity that classifies each operation as compute-bound or memory-bound against the hardware’s ridge point. Together, these four dimensions provide the vocabulary for analyzing the computational intensity, memory pressure, and data dependencies introduced in section 8.1.
8.3.1 Forward and backward computation
Every forward matrix multiplication in a training step must be followed by two backward matrix multiplications (one to propagate error gradients to the preceding layer and one to compute weight gradients) while intermediate activations sit in device memory waiting for their backward consumer. Although each layer applies only a linear transformation and a nonlinear activation, repeating that forward-and-backward pair across dozens of layers and millions of steps dominates modern training infrastructure. The introduction of backpropagation5 by Rumelhart et al. (1986) and the development of efficient matrix computation libraries such as Basic Linear Algebra Subprograms (BLAS)6 (Dongarra et al. 1988) laid the groundwork for modern training architectures.
5 Backpropagation provenance: The algorithm was independently derived by Linnainmaa (1970) for automatic differentiation of computer programs and by Werbos (1974) in a Harvard PhD thesis on economic modeling, over a decade before Rumelhart et al. (1986) popularized it for neural networks. A framework’s backward pass traverses the computational graph in reverse topological order and applies the chain rule; independent subgraphs may expose parallel work during that traversal.
Linnainmaa, Seppo. 1970. “The Representation of the Cumulative Rounding Error of an Algorithm as a Taylor Expansion of the Local Rounding Errors.” Master's thesis, University of Helsinki.
Werbos, Paul. 1974. “Beyond Regression: New Tools for Prediction and Analysis in the Behavioral Sciences.” PhD thesis, Harvard University.
Rumelhart, David E., Geoffrey E. Hinton, and Ronald J. Williams. 1986. “Learning Representations by Back-Propagating Errors.” Nature 323 (6088): 533–36. https://doi.org/10.1038/323533a0.
6 BLAS (basic linear algebra subprograms): The original BLAS specification standardized reusable Fortran-callable vector operations (Lawson et al. 1979); later BLAS extensions added matrix-vector and matrix-matrix routines, giving the familiar Level 1, Level 2, and Level 3 hierarchy (Dongarra et al. 1988). Training is dominated by Level 3 operations precisely because their high arithmetic intensity, \(\mathcal{O}(\SquareGemmDimension)\) FLOP/byte, can sustain high compute utilization. Frameworks commonly dispatch dense matrix multiplication to optimized libraries such as cuBLAS and oneDNN or to compiler-generated kernels.
Lawson, Charles L., Richard J. Hanson, David R. Kincaid, and Fred T. Krogh. 1979. “Basic Linear Algebra Subprograms for Fortran Usage.” ACM Transactions on Mathematical Software 5 (3): 308–23. https://doi.org/10.1145/355841.355847.
Dongarra, Jack J., Jeremy Du Croz, Sven Hammarling, and Richard J. Hanson. 1988. “An Extended Set of FORTRAN Basic Linear Algebra Subprograms.” ACM Transactions on Mathematical Software 14 (1): 1–17. https://doi.org/10.1145/42288.42291.
Forward propagation, in its simplest case, involves two operations: matrix multiplication and activation function application. Matrix multiplication implements the linear transformation at each layer. At layer \(\ell\), the computation can be written in row-vector form, with one example per row: \[ \ActivationMatrix^{(\ell)} = \ActivationFunction\left(\ActivationMatrix^{(\ell-1)}\WeightMatrix^{(\ell)} + \BiasVector^{(\ell)}\right) \] where:
- \(\ActivationMatrix^{(\ell-1)}\) represents the activations from the previous layer (or the input layer for the first layer), with each row being a sample in the batch,
- \(\WeightMatrix^{(\ell)} \in \mathbb{R}^{\LayerWidth_{\ell-1} \times \LayerWidth_\ell}\) is the weight matrix at layer \(\ell\), which contains the parameters learned by the network,
- \(\BiasVector^{(\ell)}\) is the bias vector for layer \(\ell\),
- \(\ActivationFunction(\cdot)\) is the activation function applied elementwise (for example, ReLU, sigmoid) to introduce nonlinearity.
Matrix operations
Matrix multiplication formulation established that forward propagation reduces to chains of matrix multiplications. Every architecture also shares a small set of building blocks, from dense projections and residual paths to normalization, each with its own cost to the machine. Training amplifies these patterns: each operation executes not once but billions of times, and each forward pass is paired with a backward pass that costs roughly twice the forward pass, tripling the work per step. Understanding which matrix operations dominate, and how their shapes change between forward and backward passes, reveals why specific system designs and optimizations emerged for training.
↩︎ The building blocks every architecture shares, and what each costs the machine, are established in Shared building blocks.
NVIDIA. 2024. cuBLAS: CUDA Basic Linear Algebra Subprograms.
The predominance of matrix multiplication has shaped both linear algebra software and accelerator architecture. Early implementations relied on general-purpose CPU libraries, but modern training scale requires tiled, accelerator-native libraries such as cuBLAS (NVIDIA 2024) and oneDNN that partition operands to fit cache hierarchies and feed systolic arrays.
This dense computational workload motivates blocked algorithms that parallelize across thousands of execution cores while aligning with the memory access patterns of forward and backward passes. Because backpropagation requires simultaneous access to weight matrices, incoming gradients, and stored activations, hardware architects have prioritized high memory bandwidth alongside raw arithmetic throughput. Evaluating one layer of the GPT-2 lighthouse model illustrates the scale and distribution of these operations.
Napkin Math 8.1: GPT-2 attention layer computation
Each GPT-2 layer performs attention computations that exemplify dense matrix multiplication demands. For one GPT-2 transformer layer (all heads combined) with batch size \(\BatchSize\) = 32, sequence length \(\SequenceLength\) = 1024, and hidden dimension \(\HiddenDimension\) = 1600:
Query, Key, Value Projections (the three linear transformations that create attention inputs, 3 separate matrix multiplications): \[\begin{gather*} O_{\text{QKV}} = 2 \times 3 \times (B \times S \times d \times d) \\ = 2 \times 3 \times (32 \times 1024 \times 1600 \times 1600) \approx 503 \text{ billion FLOPs} \end{gather*}\] Attention matmuls (\(\AttentionQueryMatrix\AttentionKeyMatrix^T\) and the product of the attention probabilities with \(\AttentionValuesMatrix\)): \[\begin{gather*} O_{\text{QK}} = 2 \times B \times \NumberOfAttentionHeads \times S \times S \times \AttentionHeadDimension = 107.4 \text{ billion FLOPs} \\ O_{\text{AV}} = O_{\text{QK}};\quad \text{pair total} \approx 214.8 \text{ billion FLOPs} \end{gather*}\] Output projection (attention output \(\rightarrow\) hidden): \[ \OutputProjectionOperations= 2 \times \BatchSize\times \SequenceLength\times \HiddenDimension\times \HiddenDimension\approx 168 \text{ billion FLOPs} \] Feed-Forward Network (Two linear transformations with expansion factor 4): \[ \FeedForwardOperations\approx 16 \times \BatchSize\times \SequenceLength\times \HiddenDimension^2 \] Computation Scale
- Per-layer forward total (QKV 503 + attention 214.8 + output proj 168 + FFN 1,342 billion): ~2,228 GFLOP
- With 48 layers in GPT-2: ~320.8 TFLOP per training step, forward and backward. This exceeds the 295 TFLOP of the six-FLOPs-per-parameter rule used elsewhere in the chapter mostly because it adds the attention score and weighted-sum products, about 31 TFLOP per step, which grow with the square of sequence length and which that rule leaves out; the rule’s parameter count also includes embedding weights that this per-layer tally omits
- Across this illustrative 50,000 steps scenario: ~16,042 PFLOP
Systems insight: The reference H100 (989 TFLOP/s dense peak with Tensor Cores, 67 TFLOP/s without) would require 0.32 s for the modeled attention-plus-FFN training step at 100 percent utilization. If the target is a step of about 200 ms, ideal arithmetic alone needs about two accelerators, and at the 30 to 50 percent utilization large runs sustain the requirement grows to 4 to 6 before communication and pipeline overhead are counted.
These FLOP counts are the compute term of the iron law made concrete, and they explain why training cost scales as a predictable function of model architecture and sequence length rather than as an unpredictable emergent property.
Matrix-vector and batched operations
Not all neural network layers execute as dense matrix-matrix multiplications. Normalization layers, bias additions, and autoregressive recurrent updates execute matrix-vector operations, which use each loaded weight once and leave a massively parallel accelerator waiting on memory. Batching turns those matrix-vector products (GEMV) into general matrix multiplications (GEMM) that reuse each loaded weight across \(\BatchSize\) examples, the same conversion that raised the running dense network’s arithmetic intensity at batch 32 in Implementation and optimization considerations. For training, the trade-off is an immediate expansion of working memory: every additional sample in the batch scales the intermediate activation volume that must reside in device memory during backpropagation. Hardware design directly mirrors this progression. Google’s first Tensor Processing Unit (TPU) integrated dedicated two-dimensional systolic matrix units that required batched execution to achieve efficiency (Jouppi et al. 2017), while large-scale models such as GPT-3 use distributed clusters specifically to execute the massive GEMM patterns exposed by large global batches (Brown et al. 2020).
Brown, Tom B., Benjamin Mann, Nick Ryder, Melanie Subbiah, Jared Kaplan, Prafulla Dhariwal, Arvind Neelakantan, et al. 2020. “Language Models Are Few-Shot Learners.” Advances in Neural Information Processing Systems 33: 1877–901. https://doi.org/10.48550/arxiv.2005.14165.
Matrix multiplication’s dominance also explains the shape of training hardware. Its independent output elements map onto thousands of parallel arithmetic lanes, dedicated matrix units such as Tensor Cores run lower-precision matrix products several times faster than scalar arithmetic, and blocked computation keeps reused operands in on-chip memories rather than refetching them from HBM. Mixed-precision training (section 8.6.3) exploits the second property, and the realized gain of any of them still depends on the nonmatrix work, memory traffic, and input and communication costs around the matrix products.
↪ Why accelerators devote their silicon to dense matrix units, and how those units are fed, is developed in Compute Units.
Matrix multiplications dominate training compute, but neural networks require more than linear transformations. Between each layer’s matrix operations, activation functions introduce the nonlinearity that enables networks to learn complex patterns. These functions appear computationally trivial compared to matrix multiplication, yet their implementation characteristics affect training efficiency in ways that matter at scale.
Activation functions
Nonlinear activation functions established what sigmoid, tanh, ReLU, and softmax compute, why the S-curves saturate, and why a ReLU comparison costs far less silicon than an exponential. At training scale, what matters is that their arithmetic rarely sets throughput. A standalone elementwise activation performs only 1 to 4 FLOPs per element while moving 8 bytes (an FP32 read and write), roughly \(0.125\text{--}0.5\text{ FLOP/byte}\), so its latency is set by memory bandwidth rather than by which function it computes. GPT-2’s activation, the Gaussian Error Linear Unit (GELU), shows what remains of the arithmetic choice, an exact form against a cheaper approximation.
Systems Perspective 8.1: The GELU activation choice
Beyond the foundational activation functions (Sigmoid, Tanh, ReLU), modern architectures increasingly adopt smoother alternatives. GPT-2 uses a GELU activation (Radford et al. 2019), the Gaussian Error Linear Unit introduced by Hendrycks and Gimpel (2016) and often implemented with the common tanh-based approximation from that formulation. Its exact definition is: \[
\text{GELU}(\ActivationInput) = \ActivationInput\cdot \StandardNormalCumulativeDistribution(\ActivationInput) = \ActivationInput\cdot \frac{1}{2}\left[1 + \text{erf}\left(\frac{\ActivationInput}{\sqrt{2}}\right)\right]
\] where \(\StandardNormalCumulativeDistribution(\ActivationInput)\) is the cumulative distribution function of the standard normal distribution.
GELU applies a smooth, input-dependent scaling rather than ReLU’s hard threshold. It is deterministic despite its formulation in terms of a Gaussian cumulative distribution. Whether it improves model quality relative to another activation is an empirical property of the architecture and training recipe, not a universal guarantee.
Exact GELU uses erf, while common implementations use a tanh-based approximation such as listing 1. The approximation changes arithmetic cost and introduces a small numerical difference from the exact function. Its end-to-end cost depends mainly on whether the compiler fuses the activation into the preceding matrix multiplication, which removes the memory round-trip that dominates a standalone activation kernel.
Hendrycks, Dan, and Kevin Gimpel. 2016. “Gaussian Error Linear Units (GELUs).” arXiv Preprint arXiv:1606.08415.
# Fast GELU approximation used in production systems
# Avoids expensive erf() computation while
# preserving activation properties
gelu_approx = (
    0.5 * x * (1 + tanh(sqrt(2 / pi) * (x + 0.044715 * x**3)))
)
Forward-pass matrix multiplications dominate floating-point operations, while activation functions stress memory bandwidth. Transforming these forward activations into model convergence requires propagating error gradients backward through the graph to update parameter tensors. That optimization step introduces state storage, update scheduling, and numerical stability constraints that govern training efficiency.
↩︎ The memory wall that bounds elementwise activation kernels, and kernel fusion as the framework’s response to it, are established in The memory wall and kernel fusion.
8.3.2 Optimizers and their memory
Every parameter update reads gradients, mutates persistent state tensors in High Bandwidth Memory (HBM), and writes updated weights back across the memory bus. Because modern optimizers keep one or two auxiliary state values per parameter, optimizer state often consumes more HBM capacity than the weights themselves while executing as a bandwidth-bound elementwise pass. In the D·A·M taxonomy, the choice of optimization algorithm couples the mathematical trajectory (Algorithm) directly to the working-set footprint and memory traffic (Machine).
Gradient-based optimization methods
At hardware scale, updating parameters along the steepest-descent direction collides with two physical limits: HBM capacity restricts how many activations and optimizer states remain resident, and memory bandwidth restricts how rapidly parameters update once gradients arrive. The mathematical formulation of gradient descent assumes modest networks on a single device, where neither limit binds.
↩︎ Gradient descent and its parameter-update rule are established in Gradient descent and parameter updates.
Gradient descent
In a training system, each gradient descent iteration is a chain of dependent operations (forward pass, loss, backward pass, parameter update), none of which can start before its predecessor finishes. Full-batch gradient descent, which computes each update from the entire training set, need not hold the dataset in memory at once, because examples can stream through the accelerator in micro-batches; its cost is time rather than memory. With one million training examples, every update waits for a million examples of forward and backward work, and the parameters stay frozen throughout, reducing the rate at which the model can learn from data.
Mini-batch processing
Mini-batch gradient descent (definition 5.2) sits between full-batch and single-example updates, computing each update over a batch small enough to fit in memory and large enough to keep the accelerator busy (Dean et al. 2012). Single-example updates (stochastic gradient descent with a batch of one) return dense layers to the bandwidth-limited matrix-vector regime of section 8.3.1.2 and rewrite every parameter once per example. Averaging over \(\BatchSize\) independent examples shrinks the standard deviation of the gradient estimate approximately as \(1/\sqrt{\BatchSize}\), and the batch size becomes a key system parameter, influencing both computational efficiency and memory requirements.
Dean, Jeffrey, Greg Corrado, Rajat Monga, Kai Chen, Matthieu Devin, Quoc V. Le, Mark Z. Mao, et al. 2012. “Large Scale Distributed Deep Networks.” In Advances in Neural Information Processing Systems (NeurIPS), edited by Peter L. Bartlett, Fernando C. N. Pereira, Christopher J. C. Burges, Léon Bottou, and Kilian Q. Weinberger, vol. 25. Curran Associates.
The choice of batch size \(\BatchSize\) directly governs accelerator memory allocation. The partial decomposition in equation 2 separates fixed parameter and gradient storage from the batch-dependent activation working set; optimizer states, any master weights, and runtime workspaces must also enter the full budget: \[ \text{Memory Required} = \WeightMemory + \GradientMemory + \ActivationMemory, \qquad \ActivationMemory \propto \BatchSize \tag{2}\]
Because the activation term scales with \(\BatchSize\) while parameter and gradient memory stay fixed, doubling the batch doubles the activation working set, and a model that fits comfortably at a small batch can exhaust the 80 GB of HBM on the reference H100 once the batch grows. Section 8.4.3.2 works through an illustrative ResNet-50 budget.
Sharing each loaded weight across the batch lets a larger batch move dense feedforward and attention projections toward the compute-bound regime; shape and the hardware ridge point determine whether compute throughput becomes limiting. Throughput and convergence follow separate curves, however. Goyal et al. (2017) trained ResNet-50 on ImageNet at \(\BatchSize=8{,}192\) by scaling the learning rate linearly with batch size and adding a warmup period, a configuration-specific recipe rather than evidence of a universal critical batch size; its useful range depends on the model, data, optimizer, and target accuracy.
⇄ Contrast: Training packs large batches to amortize weight transfers and saturate arithmetic units, whereas online serving inverts the priority to per-request latency under stochastic arrivals, as analyzed in The Serving Inversion.
When the batch size necessary to saturate execution units or ensure stable convergence exceeds physical memory capacity, systems decouple the physical micro-batch size (\(\MicrobatchSize\)) from the algorithmic batch size by accumulating gradients over several micro-batches before invoking the optimizer, which keeps peak activation storage to that of one micro-batch. Section 8.6.5 develops this gradient accumulation and the conditions under which it reproduces the large-batch gradient.
Adaptive and momentum-based optimizers
Basic mini-batch stochastic gradient descent (SGD) applies a uniform scalar learning rate to every parameter tensor, which can stall training when loss curvature differs by orders of magnitude across dimensions. Momentum smooths updates using directional gradient history, RMSprop adapts individual step sizes using squared-gradient magnitudes, and Adam combines first-moment tracking with adaptive second-moment scaling (Kingma and Ba 2015). While these algorithmic enhancements can reduce the total optimization steps required to converge, they do so by introducing persistent auxiliary state that directly increases accelerator memory pressure and memory-bus traffic.
Kingma, Diederik P., and Jimmy Ba. 2015. “Adam: A Method for Stochastic Optimization.” 3rd International Conference on Learning Representations (ICLR).
Momentum-based methods
Momentum methods7 (Polyak 1964) address SGD’s oscillation problem by accumulating a velocity vector across iterations, damping high-frequency oscillations along steep ravines. In hardware, this smoothing requires allocating and maintaining a persistent velocity tensor matching the exact shape and precision of the model parameters. Parameters and this auxiliary state together occupy \(2\times\) the parameter footprint before gradients and activations are counted.
7 Momentum: Borrowed from physics, where momentum (mass \(\times\) velocity) describes an object’s tendency to continue moving. The metaphor explains the design because accumulated velocity smooths noisy gradients and can reduce the iterations needed for convergence. The systems cost is one additional velocity value per parameter, while Adam maintains two moment values per parameter.
Polyak, Boris T. 1964. “Some Methods of Speeding up the Convergence of Iteration Methods.” USSR Computational Mathematics and Mathematical Physics 4 (5): 1–17. https://doi.org/10.1016/0041-5553(64)90137-5.
Adaptive learning rate methods
While momentum smooths gradient direction, it does not address the different scales of gradients across parameters. RMSprop8 solves this by maintaining a moving average of squared gradients for each parameter, automatically reducing step sizes for parameters with historically large gradients. Adapting step sizes per parameter requires maintaining a running average of squared gradients \(\RmspropSquaredGradientAverage_t\), imposing a \(2\times\) static memory overhead equivalent to momentum. Furthermore, computing this running average introduces elementwise square and square-root kernels during each parameter update.
8 RMSprop: Proposed by Geoffrey Hinton in Lecture 6e of his 2012 Coursera course and never published in a peer-reviewed paper. Its per-parameter squared-gradient average is what Adam inherits as its second moment \(\AdamSecondMoment_t\), directly contributing to Adam’s 3\(\times\) memory overhead described in section 8.3.2.3.
Adam optimization
Adam9 combines the benefits of both momentum and RMSprop: momentum’s gradient smoothing addresses noisy updates, while RMSprop’s adaptive scaling handles parameter-specific step sizes. This combination maintains two moving averages for each parameter. Here \(\AdamFirstMoment_t\) and \(\AdamSecondMoment_t\) are the first- and second-moment buffers, \(\AdamMomentDecayRate_1\) and \(\AdamMomentDecayRate_2\) are their decay factors, \(\LearningRate\) is the learning rate, and \(\NumericalStabilityConstant\) is the numerical-stability constant in the denominator: \[\begin{gather*} m_t = \beta_1 m_{t-1} + (1-\beta_1)\nabla \LossFunction(\ModelParameters_t) \\[0.5ex] v_t = \beta_2 v_{t-1} + (1-\beta_2)\big(\nabla \LossFunction(\ModelParameters_t)\big)^2 \\[0.5ex] \hat{m}_t = \frac{m_t}{1-\beta_1^t}, \qquad \hat{v}_t = \frac{v_t}{1-\beta_2^t} \\[0.5ex] \ModelParameters_{t+1} = \ModelParameters_t - \LearningRate \frac{\hat{m}_t}{\sqrt{\hat{v}_t} + \NumericalStabilityConstant} \end{gather*}\]
9 Adam (adaptive moment estimation): The two moving averages are the first moment (momentum) and second moment (uncentered variance) of the gradients, stored for every model parameter. For a 7B model, Adam’s FP32 moment tensors alone consume 56 GB; the full standard mixed-precision training state before activations is 112 GB once FP16 weights, FP16 gradients, FP32 master weights, and Adam moments are counted together.
Maintaining both moment buffers triples the parameter-plus-optimizer-state footprint: the training system must allocate two persistent state tensors (\(\AdamFirstMoment_t\) and \(\AdamSecondMoment_t\)) alongside the parameter tensors. For a 100M-parameter model, those auxiliary vectors alone add 800 MB beyond weight storage.
System cost of optimizer state
Auxiliary state memory increases progressively from SGD (zero auxiliary state) through Momentum and RMSprop (one state vector per parameter) to Adam (two state vectors per parameter), as quantified in table 3. These memory footprints establish a trade-off against convergence rate.10 Adam often achieves target loss in fewer optimization steps, but its static memory footprint restricts the batch size that fits in accelerator HBM and increases memory-bus traffic on every update. At GPT-2 scale, this overhead becomes a first-order memory constraint.
10 Convergence: A run reaches its stopping criterion when the selected training or validation metric no longer improves enough to justify additional work. The required steps depend on the model, data, optimizer, schedule, batch size, and target quality. Fewer steps can reduce wall-clock time and cost, but adaptive optimizers add state whose memory and traffic must be included in the system budget.
| Property | SGD | Momentum | RMSprop | Adam |
|---|---|---|---|---|
| Memory Overhead | None | Velocity terms | Squared gradients | Both velocity and squared gradients |
| Parameter + optimizer state | 1\(\times\) | 2\(\times\) | 2\(\times\) | 3\(\times\) |
| Dense State Access | Parameters and gradients | Adds velocity | Adds squared-gradient state | Adds first- and second-moment state |
| Update Work | Lowest auxiliary work | Adds momentum update | Adds adaptive scaling | Adds moment updates and bias correction |
| Hardware Efficiency | Varies | Varies | Varies | Varies |
| Convergence Behavior | Varies | Varies | Varies | Varies |
Three multipliers for Adam’s memory appear in this chapter, and they differ only in what they count and what they divide by. The table’s 3\(\times\) counts FP32 weights plus two FP32 moments against the FP32 weights alone, 12 bytes per parameter against 4. Adding FP32 gradients gives the 16 bytes per parameter of plain FP32 Adam. The standard mixed-precision recipe also lands at 16 bytes (2 for FP16 weights, 2 for FP16 gradients, 4 for FP32 master weights, 8 for the moments), and it is that same 16 bytes, measured against the 2 bytes of FP16 inference weights, that the definition of training systems reports as 8×.
The costs quantified in table 3 create a design tension. Adam’s two moment buffers may improve optimization for a given workload, but their memory can reduce the model size or batch size that fits on an accelerator. AdamW11 (Loshchilov and Hutter 2019) decouples weight decay from Adam’s adaptive gradient update without adding another per-parameter state tensor.
11 AdamW (Adam with decoupled weight decay): Standard \(\ell_2\) regularization enters the gradient and is therefore rescaled by Adam’s adaptive update. AdamW applies weight decay as a separate parameter update, restoring the intended distinction between adaptive gradient scaling and decay (Loshchilov and Hutter 2019). It uses the same moment-buffer structure as Adam, though its effect on model quality remains workload dependent.
Loshchilov, Ilya, and Frank Hutter. 2019. “Decoupled Weight Decay Regularization.” Proceedings of the International Conference on Learning Representations (ICLR).
Napkin Math 8.2: GPT-2 optimizer memory requirements
A representative GPT-2 XL training configuration uses the Adam optimizer with five hyperparameters:
- \(\AdamMomentDecayRate_1 = 0.9\) (momentum decay)
- \(\AdamMomentDecayRate_2 = 0.999\) (second moment decay)
- Learning rate: Warmed up from 0 to 2.5e-4 over first 500 steps, then cosine decay
- Weight decay: 0.01
- Gradient clipping: Global norm clipping at 1.0
Math:
For GPT-2’s 1.5B parameters in FP32 (4 bytes each), the memory breaks down across four components:
- Parameters: 1.5B \(\times\) 4 bytes = 6 GB
- Gradients: 1.5B \(\times\) 4 bytes = 6 GB
- Adam State (\(\AdamFirstMoment_t\), \(\AdamSecondMoment_t\)): 1.5B \(\times\) 8 bytes = 12 GB
- Total static memory: 24 GB
This static training state alone, 24 GB for GPT-2, takes about 28 percent of an H100’s 80 GB before any activation is stored, and how much room the activations need depends on batch size and sequence length. The activation notebook below adds the batch-dependent term at batch 32, and the pipeline optimizations then remove it piece by piece until the walkthrough (section 8.6.6) fits the step on one accelerator.
System Decisions Driven by Optimizer
- Mixed precision training (FP16) reduces operation precision but requires keeping FP32 master weights, so the static footprint stays at ~24 GB, the same 16 bytes per parameter as FP32 Adam.
- Gradient accumulation (section 8.6.5) builds an effective batch of \(\BatchSize=512\) from micro-batches that fit in memory.
Systems insight: This illustrative configuration shows how Adam’s moment buffers constrain capacity. Any convergence benefit relative to SGD or momentum must be measured under a matched model, data, schedule, batch size, and stopping criterion.
The optimizer step
Optimizer memory, once quantified, fixes what each update must read and write. In the training loop, optimizer.zero_grad() and optimizer.step() bracket each update. Gradients accumulate across backward() calls until they are cleared, and step() consumes them and mutates the optimizer’s persistent state (Anatomy of a Training Step traces both calls through the framework). The accumulation behavior later becomes useful for building large effective batches, but only when the loop manages that boundary deliberately. For Adam optimization, step() performs momentum estimation, squared-gradient tracking, bias correction, and the parameter update, and algorithm 1 makes that hidden state explicit so the memory cost remains visible rather than disappearing behind an API call.
Parameters (P) and gradients (G) take one share each, and Adam’s moment buffers m and v add two more in this simplified static-state view.
Steps 1 and 2 keep two persistent moment buffers per parameter, so parameters plus optimizer state reach roughly 3\(\times\) the parameter memory before gradients, activations, and FP32 master weights are counted. Beyond capacity, the optimizer step imposes a severe memory-bandwidth bottleneck. The update consists of elementwise operations with an arithmetic intensity below \(1\text{ FLOP/byte}\). In FP32, updating each parameter requires reading four tensors (\(\LossGradient_t, \ModelParameters_t, \AdamFirstMoment_{t-1}, \AdamSecondMoment_{t-1}\)) and writing three (\(\AdamFirstMoment_t, \AdamSecondMoment_t, \ModelParameters_{t+1}\)), streaming 28 bytes across the memory bus for roughly a dozen arithmetic operations. Because matrix execution units (such as Tensor Cores) sit idle during this memory-bound phase, high-performance training systems use fused optimizer kernels to combine moment updates, bias correction, and weight writes into a single kernel launch per parameter group, minimizing round-trips through device memory.
Reducing optimizer memory
Because optimizer tensors remain resident between updates, reducing their footprint can make a larger micro-batch feasible even when the optimizer is not the longest phase of the step. At billion-parameter scale, optimizer state becomes a first-order, batch-independent term in the memory budget. As quantified in the GPT-2 worked example (section 8.3.2.3), a 1.5B model requires 12 GB for Adam optimizer state alone in FP32, in addition to parameters and gradients, before accounting for activations. This challenge has motivated memory-efficient optimizer variants: Adafactor factorizes second-moment state (Shazeer and Stern 2018), 8-bit optimizers quantize optimizer statistics (Dettmers et al. 2022), and GaLore computes updates in a low-rank space (Zhao et al. 2024).
Shazeer, Noam, and Mitchell Stern. 2018. “Adafactor: Adaptive Learning Rates with Sublinear Memory Cost.” International Conference on Machine Learning (ICML), Proceedings of machine learning research, vol. 80: 4596–604.
Dettmers, Tim, Mike Lewis, Sam Shleifer, and Luke Zettlemoyer. 2022. “8-Bit Optimizers via Block-Wise Quantization.” International Conference on Learning Representations (ICLR).
Zhao, Jiawei, Zhenyu Zhang, Beidi Chen, Zhangyang Wang, Anima Anandkumar, and Yuandong Tian. 2024. “GaLore: Memory-Efficient LLM Training by Gradient Low-Rank Projection.” arXiv Preprint.
To attribute a memory saving to the optimizer, hold the model, batch size, precision, and activation policy fixed and compare the complete memory budget. Low-rank projection buffers and other temporary state belong in that budget. A smaller optimizer-state term does not guarantee that the full training recipe fits, nor that it reaches the same validation quality in less time.
Learning rate schedules
The framework’s learning rate scheduling hook changes the optimizer’s trajectory without adding per-parameter state. It adjusts the learning rate \(\LearningRate\) during training, letting the system shape convergence behavior while leaving the underlying optimizer equations intact.
Schedules such as cosine annealing (Loshchilov and Hutter 2017), exponential decay, or step-wise reductions implement that trajectory by changing the step size over time. A scheduler tracks lightweight scalar state (current step, epoch, warmup phase) that must be serialized into checkpoints alongside optimizer states to resume the schedule (section 8.4.5). Reproducing the training trajectory also requires the relevant random-number and data-position state and compatible execution settings. This separation lets the systems engineer combine base optimization algorithms (SGD, Adam) with scheduling strategies (cosine annealing, linear warmup) without modifying the underlying tensor update rules.
Loshchilov, Ilya, and Frank Hutter. 2017. “SGDR: Stochastic Gradient Descent with Warm Restarts.” Proceedings of the International Conference on Learning Representations (ICLR).
Time to target quality
A faster update is valuable only if the recipe reaches the required validation quality sooner. Optimizer state and numerical precision affect the price of each update, while the optimizer and schedule affect how many updates the run needs. Both quantities enter a time-to-target decision.
Consider two precision-and-optimizer recipes for the same model, dataset, effective batch, machine, and validation target. Both fit in memory. Table 4 supplies hypothetical observations for their first accepted checkpoint and calculates the total elapsed time from them.
| Quantity | Recipe A | Recipe B |
|---|---|---|
| End-to-end update time | 2 s | 1.5 s |
| Updates to the same validation target | 6,000 | 10,000 |
| Update time × update count | 200 min | 250 min |
| Separate evaluation and checkpoint time | 10 min | 10 min |
| Total time to accepted checkpoint | 210 min | 260 min |
Recipe A reaches the target sooner. At its shorter step duration, Recipe B would tie A’s total time if it reached the target at 8,000 updates under the stated overhead. Its assumed 10,000 updates exceed that budget. On the same allocated machine, shorter total time also means fewer billed accelerator-hours.
A profile measures the cost of an update; validation measures how many updates the required quality takes. Comparing optimizers, precision, or batch schedules requires both measurements under a common acceptance criterion. A real experiment must also account for run-to-run variation and any change in evaluation frequency; an apparent crossing of the target is not evidence that a recipe reliably meets it.
Optimizer rules specify how parameters move once gradient vectors are in hand, yet computing those gradients dominates both arithmetic and memory in a billion-parameter network. The mechanics of gradient generation, rather than the optimizer update itself, therefore govern the training memory budget and step time.
8.3.3 Backpropagation and activation memory
Backpropagation evaluates parameter gradients by traversing the network’s computational graph in reverse topological order, applying the chain rule layer by layer (Gradient computation and backpropagation). Each backward rule reads values from the forward pass, either saved or recomputed, so tensors that inference would release after their last forward consumer stay alive until the backward pass reaches them (Saved tensors and the memory-compute trade-off). Computing \(\frac{\partial \LossFunction}{\partial \WeightMatrix^{(\LayerIndex)}}\) requires the layer’s forward input, and the retention of those inputs creates the training memory equation that gradient checkpointing later exploits. At the scale of GPT-2 XL, the question is what that retention costs in memory capacity and arithmetic throughput, because retained activations in HBM can become the binding memory constraint of the run.
The arithmetic side of that cost follows from the derivative equations of Derivative calculation process. Backpropagation through a linear layer \(\PreactivationMatrix= \ActivationMatrix\WeightMatrix\) evaluates two matrix products, the activation gradient \(\nabla_{\ActivationMatrix}\LossFunction = (\nabla_{\PreactivationMatrix}\LossFunction)\WeightMatrix^T\) that carries the error signal upstream and the parameter gradient \(\nabla_{\WeightMatrix}\LossFunction = \ActivationMatrix^T(\nabla_{\PreactivationMatrix}\LossFunction)\) that the optimizer consumes. Each permutes the forward matrix dimensions while keeping the forward product’s leading FLOP count, so backward costs about twice forward and a complete step about three times the forward FLOPs. At the scale of a transformer, that same factor of three turns the \(2\Parameters\) forward FLOPs per token into the \(6\Parameters\) per token behind the lighthouse budget. The memory side of the cost has no such fixed ratio, because it depends on which forward values the backward rules must read.
The three-layer MNIST classifier (784 → 128 → 64 → 10) of Neural Computation needed only kilobytes of activation storage. GPT-2 processing a single batch of 32 sequences of 1024 tokens requires approximately 286.9 GB of saved activations. Adding parameters, gradients, master weights, and optimizer state raises the estimated training footprint to 310.9 GB, about 3.6× the H100’s 80 GB before temporary workspace is counted. Training memory puts a number on each term of the full training memory equation (\(\TotalMemoryFootprint = \WeightMemory + \GradientMemory + \OptimizerStateMemory + \ActivationMemory\)) for GPT-2. Modern ML frameworks automate gradient evaluation through automatic differentiation, but managing the resulting memory footprint and arithmetic schedule remains an unavoidable systems engineering responsibility.
Activation memory requirements
The four-term training-memory budget of equation 5.29 partitions training state into saved forward activations required by backward derivative rules, model parameters, parameter gradients, and optimizer state (including any higher-precision master weights), and only the first category grows with the batch. Consider a batch of training examples passing through a network. The forward pass computes and stores: \[\begin{gather*} \mathbf{Z}^{(\LayerIndex)} = \mathbf{A}^{(\LayerIndex-1)}\mathbf{W}^{(\LayerIndex)} + \mathbf{b}^{(\LayerIndex)} \\ \mathbf{A}^{(\LayerIndex)} = f(\mathbf{Z}^{(\LayerIndex)}) \end{gather*}\]
To compute the parameter gradient \(\nabla_{\WeightMatrix^{(\LayerIndex)}}\LossFunction = (\ActivationMatrix^{(\LayerIndex-1)})^T(\nabla_{\PreactivationMatrix^{(\LayerIndex)}}\LossFunction)\), the backward rule must read the layer’s input activations \(\ActivationMatrix^{(\LayerIndex-1)}\). To propagate the error signal upstream through the nonlinear activation function via \(\nabla_{\PreactivationMatrix^{(\LayerIndex)}}\LossFunction = (\nabla_{\ActivationMatrix^{(\LayerIndex)}}\LossFunction) \odot \ActivationFunction'(\PreactivationMatrix^{(\LayerIndex)})\), the kernel requires either the pre-activation tensor \(\PreactivationMatrix^{(\LayerIndex)}\) (as in GELU) or the post-activation output \(\ActivationMatrix^{(\LayerIndex)}\) (when \(\ActivationFunction'\) can be computed from the output, as in sigmoid, or via a 1-bit boolean mask in ReLU). Fused kernels and selective recomputation can compress this saved footprint. Nevertheless, because activations scale with batch size \(\BatchSize\) and sequence length \(\SequenceLength\), their storage demands grow with the data dimension, whereas parameter and optimizer memory remain fixed by the model architecture. The GPT-2 calculation in notebook 8.3 decomposes this memory pressure across attention blocks, feed-forward sublayers, and optimizer states.
Napkin Math 8.3: GPT-2 activation memory breakdown
For GPT-2 with batch size \(\BatchSize\) = 32, sequence length \(\SequenceLength\) = 1024, hidden dimension \(\HiddenDimension\) = 1600, and 48 layers:
Math:
- Attention activations: \(\BatchSize \times \SequenceLength \times \HiddenDimension \times 4\) (Q, K, V, output) = 32 \(\times\) 1024 \(\times\) 1600 \(\times\) \(4 \times 2\) bytes (FP16) = 419.4 MB
- FFN activations: \(\BatchSize \times \SequenceLength \times (4\HiddenDimension)\) (intermediate expansion) = 32 \(\times\) 1024 \(\times\) 6400 \(\times\) 2 bytes = 419.4 MB
- Attention scores: \(5 \times \AttentionHeadCount \times \SequenceLength^2 \times \BatchSize\) bytes, because each element of a head’s \(\SequenceLength{\times}\SequenceLength\) attention matrix is saved three times for backward: 2 bytes for the FP16 softmax probabilities, 1 byte for the dropout mask, and 2 bytes for the probabilities after dropout. With 25 heads, this term reaches 4194.3 MB per layer. It is the dominant term, quadratic in sequence length, and exactly what selective recomputation discards
- Layer norm states: Minimal (~10 MB per layer)
- Total per layer: ~5043.2 MB (attention + FFN + attention scores + layer norm states)
Result:
- Line items across all layers: 5043.2 MB \(\times\) 48 layers ≈ 242.1 GB
- Total activation memory (library estimate): 286.9 GB, about 44.8 GB more than the line items because it also counts saved tensors the list omits, such as the inputs to each linear and normalization layer, the GELU output, and the dropout masks
- Parameters (FP16): 3 GB
- Gradients: 3 GB
- Master weights (FP32): 6 GB
- Adam moment state (FP32): 12 GB
- Peak memory during training: ~310.9 GB
This exceeds a single H100’s 80 GB capacity.
Solutions:
- Selective activation recomputation: Discard attention intermediates and recompute them during backward, reducing this modeled activation term by 70.2 percent to ~85.6 GB; the additional work depends on the implementation
- Activation CPU offloading: Store some activations in CPU RAM, transfer during backward pass
- Mixed precision: FP16 activations (already applied) vs. FP32 (would be 573.8 GB)
- Reduced micro-batch size and gradient accumulation: Build a larger effective batch from multiple memory-feasible forward/backward passes
Systems insight: Even after selective recomputation, the modeled activations plus static state total about 109.6 GB, still above the H100’s 80 GB before workspace and allocator overhead. Selective recomputation removes 70.2 percent of the activations, the same quadratic attention term that FlashAttention never stores; the segment schedule in notebook 8.8 goes further by retaining only segment inputs between passes, and the walkthrough composes these techniques until the batch-32 step fits.
This breakdown illustrates the practical engineering decisions required when accelerator memory falls short. The same trade-off between stored activations, recomputation, and batch size drives the memory-computation analysis that follows.
Memory-computation trade-offs
Training systems must balance memory usage against computational efficiency. Each forward pass generates values that backward rules may request. For a simplified network model with \(\LayerCount\) layers, let \(\LayerIntermediateStateMemory\) denote the bytes of saved intermediate state per example at layer \(\LayerIndex\) and \(\ActivationMemory^{(\ell)}\) the bytes of saved activation outputs per example. Under this per-example convention, their storage scales linearly with batch size and is approximated by equation 3:
\[ \ActivationMemory = \BatchSize \times \sum_{\LayerIndex=1}^{\LayerCount} \left(\LayerIntermediateStateMemory + \ActivationMemory^{(\LayerIndex)}\right) \tag{3}\]
This memory requirement compounds with the weights, gradients, and optimizer memory discussed in section 8.3.2.3. Together they form the same four-term budget that equation 5.29 established and the lighthouse callout applied to GPT-2, labeled here once as equation 4 so that later sections can point to it: \[ \TotalMemoryFootprint = \WeightMemory + \GradientMemory + \OptimizerStateMemory + \ActivationMemory \tag{4}\]
The runtime peak can exceed this sum because temporary workspaces, communication buffers, allocator behavior, and framework bookkeeping also occupy memory. To reduce the activation term, training systems can recompute intermediate values during backward rather than storing them. This increases computational work but can enable deeper networks or larger batches on memory-constrained hardware (Chen et al. 2016). Activation checkpointing, which keeps activations only at selected layers and rebuilds the rest during the backward pass, is developed in section 8.6.5.1.2, with its optimal spacing and its cost for GPT-2 in section 8.6.5.2.
Jouppi, Norman P., Cliff Young, Nishant Patil, David Patterson, Gaurav Agrawal, Raminder Bajwa, Sarah Bates, et al. 2017. “In-Datacenter Performance Analysis of a Tensor Processing Unit.” Proceedings of the 44th Annual International Symposium on Computer Architecture, ISCA ’17, 1–12. https://doi.org/10.1145/3079856.3080246.
Paszke, Adam, Sam Gross, Francisco Massa, Adam Lerer, James Bradbury, Gregory Chanan, Trevor Killeen, et al. 2019. “PyTorch: An Imperative Style, High-Performance Deep Learning Library.” Advances in Neural Information Processing Systems (NeurIPS) 32: 8024–35.
Capacity is only one of two physical constraints imposed by memory; the other is bandwidth. Accelerators provide high matrix compute throughput, but shuttling intermediate activation tensors between off-chip High Bandwidth Memory (HBM) and on-chip SRAM frequently saturates the memory bus (Jouppi et al. 2017). Even when activations fit comfortably within HBM capacity, the time required to read and write them can dwarf the arithmetic execution time. To relieve this memory bus pressure, modern training engines fuse elementwise operations directly into preceding matrix multiplications and stage gradient computations through on-chip SRAM tiles rather than global memory. At the runtime level, framework caching allocators track tensor lifetimes across the computation graph, recycling memory blocks as soon as an activation’s final backward consumer completes (Paszke et al. 2019).
Fine-tuning memory on one accelerator
GPT-2 XL’s static state leaves most of an H100 for activations. One size class up, the memory constraint changes the training recipe itself. Llama 3 8B (Dubey et al. 2024), the larger member of the book’s bandwidth-bound language-model family, is usually adapted to a new task rather than trained from scratch, and whether that adaptation fits on one accelerator depends on which parameters it trains.
Dubey, Abhimanyu, Abhinav Jauhri, Abhinav Pandey, Abhishek Kadian, et al. 2024. The Llama 3 Herd of Models. arXiv preprint arXiv:2407.21783.
Training scope changes which terms of the memory budget are populated. Let \(\Parameters\) count all resident model parameters, including any added head or adapters. Inference retains their weights but has \(\GradientMemory = \OptimizerStateMemory = 0\), because it neither computes parameter gradients nor updates weights. Full fine-tuning allocates gradients and optimizer state for all \(\Parameters\) parameters, following the chosen precision recipe. Head-only adaptation keeps the frozen backbone resident but allocates gradients, master weights when used, and optimizer moments only for the trainable head. Adapters, small trainable modules inserted into a frozen network, similarly restrict these update buffers to the added parameters. Their weight-memory term still includes both the frozen base and the adapters; storing fewer trainable parameters does not remove the base weights.
Saved activation memory follows the backward path rather than the trainable parameter count. When a frozen feature extractor runs without gradient recording and supplies its output as a constant to a trainable head, the head retains that boundary input and its own required backward values; the backbone has no saved backward activations. Inference also avoids saved backward state, although live forward intermediates and workspaces still consume memory. Adapters distributed through the network create a different topology. Gradients must traverse intervening frozen operations to reach earlier adapters, so those operations may still require saved tensors or recomputation. Setting requires_grad=False on base weights suppresses their parameter gradients, but disabling recording across that path would also cut the gradients the adapters need.
↩︎ Gradient-recording and detachment controls for frozen feature extractors are established in Saved tensors and the memory-compute trade-off.
The comparison therefore separates a residency decision from a differentiation decision. Subtracting \(\WeightMemory + \GradientMemory + \OptimizerStateMemory\) from device capacity gives the space available for activations and runtime overhead. A head-only configuration may fit where full fine-tuning does not, provided it meets the task’s quality target; an adapter configuration must still budget the activations on its backward path. If those activations exceed the remaining space, checkpointing or a smaller micro-batch may still be necessary despite the small optimizer state. For a fixed training scope, only activation memory scales approximately linearly with batch size (equation 3); model parameters and optimizer state remain fixed. The Llama 3 8B case puts numbers on both decisions.
Napkin Math 8.4: Fine-tuning Llama 3 8B on one H100
Problem: Can a 8.0B-parameter Llama 3 model be fine-tuned on one H100 with 80 GB (85.9 GB in decimal units) of HBM, first with every parameter trained and then with low-rank adapters?
Given: The mixed-precision Adam recipe of section 8.3.2, a batch of 4 sequences of 2,048 tokens, and attention that never stores the quadratic score matrix.
Math:
- Full fine-tuning, static state: FP16 weights 16 GB + FP16 gradients 16 GB + FP32 master weights 32 GB + Adam moments 64 GB = 128 GB, already beyond one accelerator before any activation is stored.
- Activations: The per-layer estimate of section 8.3.3.1, without the quadratic attention term, gives 36.5 GB at this batch, so full fine-tuning needs about 165 GB in all.
- Low-rank adapters: Low-rank adaptation (LoRA) (Hu et al. 2021) freezes the base weights and trains a pair of small matrices beside each adapted projection. Rank-16 adapters on every query and value projection add 6.8 million trainable parameters, 0.08 percent of the model, whose gradients, master copies, and moments occupy 0.11 GB.
- Adapter total: Frozen BF16 weights 16 GB + adapter state 0.11 GB + activations 36.5 GB ≈ 53 GB, leaving about 33 GB for workspaces and allocator overhead.
Systems insight: Full-parameter training of this model does not fit one accelerator; it requires partitioning its state across devices with fully sharded data parallelism (FSDP) or ZeRO, which section 8.7.1.1 develops, or offloading state to host memory. Adapters change which terms of the memory budget are populated: the frozen weights stay resident, but gradients and optimizer state shrink to the adapters, and activations still follow the backward path through every frozen layer. Storing the frozen base weights in a 4-bit format shrinks the largest remaining term further (Dettmers et al. 2023), a recipe distinct from the full-parameter mixed-precision training above.
Dettmers, Tim, Artidoro Pagnoni, Ari Holtzman, and Luke Zettlemoyer. 2023. “QLoRA: Efficient Finetuning of Quantized LLMs.” Advances in Neural Information Processing Systems (NeurIPS) 36: 10088–115.
Hu, Edward J., Yelong Shen, Phillip Wallis, Zeyuan Allen-Zhu, Yuanzhi Li, Shean Wang, Lu Wang, and Weizhu Chen. 2021. “LoRA: Low-Rank Adaptation of Large Language Models.” arXiv Preprint arXiv:2106.09685.
Forward propagation, gradient computation, and parameter updates define what training systems must compute. An operation’s name alone, however, does not reveal where the system stalls. Matrix shape, kernel fusion, numerical precision, and the memory hierarchy determine whether arithmetic throughput or data movement binds execution. Arithmetic intensity provides the analytical tool to quantify that balance.
8.3.4 Arithmetic intensity
During a single training step on the reference H100, a large dense matrix multiplication runs near the chip’s Tensor Core peak while a standalone softmax or LayerNorm kernel stalls waiting for bytes from HBM. Arithmetic intensity explains that split by comparing the operations a kernel performs to the bytes it moves across the memory bus: \[ \ArithmeticIntensity = \frac{\Operations}{\DataVolume} \]
Within the roofline model, operations above the hardware ridge point have a compute-throughput ceiling, while those below it have a memory-bandwidth ceiling. Launch overhead, limited parallelism, and imperfect execution can keep measured performance below either ceiling. Performance Bounds develops the roofline model and the hardware ridge point, and The Roofline model works through the derivation.12
12 Ridge point and precision: The roofline ridge point, the arithmetic intensity threshold separating memory-bound from compute-bound operations, shifts with numerical precision. On the same accelerator, a lower-precision Tensor Core path can expose much more arithmetic throughput at roughly the same memory bandwidth, raising the ridge point substantially. Switching from TF32-style execution to BF16 mixed precision can therefore change which optimization technique yields returns, making precision selection inseparable from roofline analysis.
↩︎ Arithmetic intensity, the ridge point, and the memory-bound and compute-bound regimes they separate are established informally in Matching workloads to hardware.
Table 5 summarizes common tendencies rather than fixed measurements. Dense matrix multiplication can reuse operands enough to reach high arithmetic intensity, while standalone elementwise and reduction kernels often perform less work per byte moved. The target hardware’s ridge point determines the resulting regime.
| Operation | Arithmetic-intensity tendency | Classification condition |
|---|---|---|
| Dense MatMul (large) | High when shapes and tiling provide substantial operand reuse | Compute-bound only when intensity exceeds the ridge |
| Activation functions | Usually low as standalone elementwise kernels | Often memory-sensitive unless fusion removes traffic |
| LayerNorm/BatchNorm | Reduction and elementwise work with multiple tensor passes | Depends on fusion, shape, and target ridge point |
| Attention softmax | Reduction and normalization over the attention axis | Depends on materialization, tiling, and fusion |
Hardware efficiency during model training depends directly on kernel arithmetic intensity. Figure 1 bounds attainable throughput across training kernels on the H100’s roofline, contrasting memory-bandwidth-bound operators (softmax, LayerNorm) along the sloped ceiling against compute-bound operators (dense MatMul) on the flat 989 TFLOP/s peak.
On the reference machine the ridge in figure 1 sits at 295.2 FLOP/byte, the H100’s 989 TFLOP/s peak divided by its 3.35 TB/s of HBM bandwidth. The operation points in this diagram are illustrative placements that show how to interpret the model, not measured GPT-2 coordinates.
Consider a GPT-2 attention layer that materializes the \(\SequenceLength{\times}\SequenceLength\) attention-score matrix. For each head, the \(\AttentionQueryMatrix\AttentionKeyMatrix^T\) product costs approximately \(2\SequenceLength^2\AttentionHeadDimension\) FLOPs, while writing the FP16 score matrix and reading it back moves about \(4\SequenceLength^2\) bytes. Counting only that score-matrix traffic gives the approximation \(\AttentionHeadDimension/2\). For GPT-2 Small (\(\HiddenDimension=\) 768 across 12 heads, so \(\AttentionHeadDimension=\) 64), this restricted accounting yields 32 FLOP/byte. The lighthouse GPT-2 XL gives the same answer, because its head dimension is also 64 and the ratio depends only on \(\AttentionHeadDimension\). A complete kernel analysis must also count Q and K traffic, softmax work, additional reads and writes, cache reuse, and fusion. The \(\mathcal{O}(\SequenceLength^2)\) materialized score traffic remains the term that FlashAttention targets.
At 295.2 FLOP/byte, the H100’s ridge sits far to the right of the 32 FLOP/byte materialized attention estimate, so low-intensity operations such as attention softmax remain memory bound even when large matrix multiplications on the same device are compute bound.
Systems Perspective 8.2: Peak FLOP/s vs. sustained performance
Peak TFLOP/s is an arithmetic ceiling rather than a prediction of sustained application performance. For an implementation that is strictly bandwidth bound, raising only the arithmetic ceiling does not improve the roofline bound. Mixed-precision training can both enable faster arithmetic paths and reduce traffic for tensors actually stored and transferred at lower precision. The realized gain depends on kernel support, conversion overhead, numerical requirements, and which resource is binding. Roofline-guided optimization therefore measures the implementation before choosing fusion, precision changes, or additional compute.
Batch size also moves an operation along the intensity axis, because a larger batch spreads each weight load over more examples. Where the transition from memory-bound to compute-bound execution falls depends on the operation’s shape, its precision, and the hardware.
This analysis guides optimization strategy selection. For memory-bound operations, reducing data movement through kernel fusion, reduced precision, or algorithmic improvements like FlashAttention provides the largest gains. For compute-bound operations, increasing throughput through Tensor Cores and parallel execution matters more. The first case asks how to move fewer bytes, and the second asks how to keep more arithmetic units busy.
The trajectory vector in figure 1 illustrates how FlashAttention13 can shift transformer attention toward, and for favorable shapes across, the 295.2 FLOP/byte ridge line onto the compute ceiling. By never materializing the full \(\SequenceLength{\times}\SequenceLength\) attention matrix in HBM and instead processing tiles that fit in fast SRAM (tiling, the general technique developed in Tiling), FlashAttention reduces auxiliary attention memory from \(\mathcal{O}(\SequenceLength^2)\) to \(\mathcal{O}(\SequenceLength)\) and sharply reduces HBM traffic. The original work reports up to 3\(\times\) speedups on evaluated workloads (Dao et al. 2022), with gains depending on tensor shape, hardware, and baseline. The algorithm and the conditions under which it applies are examined in detail in section 8.6.4.
13 FlashAttention: The core mechanism processes attention in small tiles that fit within the accelerator’s fast on-chip SRAM, avoiding writes of the full intermediate \(\SequenceLength{\times}\SequenceLength\) matrix to slower HBM. The exact HBM IO bound depends on tile size and SRAM capacity, but the practical effect is a large reduction in memory traffic and auxiliary activation storage.
Arithmetic-intensity analysis is how the silicon contract (principle 4) is checked in training. The silicon contract names the resource a workload is built to exploit; the analysis determines which physical resource actually constrains a particular implementation. Dense matrix multiplication reaches the compute-bound regime when tensor shapes provide sufficient data reuse, while standalone normalization and elementwise activation kernels remain memory bandwidth bound.
Optimizing individual operations is necessary but insufficient. A perfectly tuned matrix multiplication achieves nothing if the accelerator sits idle waiting for the next batch of data. Isolated operation costs (dense matrix multiplication FLOPs, memory-bound activations, and optimizer state allocations) compound within the execution loop. Sustained throughput requires orchestrating these discrete operations into a balanced pipeline where upstream data delivery and downstream parameter updates prevent accelerator starvation.
Self-Check: Question
Why do batched matrix-matrix multiplications (GEMM, BLAS Level 3) usually achieve much higher accelerator utilization in neural network training than matrix-vector operations (GEMV, BLAS Level 2)?
- Matrix-matrix operations avoid gradient computation during backpropagation, so they save both memory traffic and arithmetic work.
- Under the ideal traffic model in the section, GEMM reuses loaded operands across many outputs, so arithmetic intensity can grow with matrix size, whereas GEMV offers much less reuse and tends to stay near constant arithmetic intensity.
- Matrix-vector operations cannot run efficiently on GPUs because every layer result must be synchronized back to the CPU before the next layer starts.
- Batched matrix-matrix operations reduce the model’s parameter count, which is why they keep more of the network in HBM.
A team trains a 7-billion-parameter model on accelerators with 80 GB of HBM each. Weights, gradients, activations, and common workspaces already occupy 64 GB per accelerator, and this total already includes any FP32 master weights if the recipe uses them. The model is unsharded per device. Using the section’s optimizer-memory accounting, explain the systems trade-off between choosing plain SGD and Adam for this run.
The point on a roofline model curve where the memory-bandwidth-bound diagonal ceiling intersects the flat peak-compute ceiling, defined mathematically as \(\text{Peak FLOP/s} / \text{Memory Bandwidth}\), is known as the ____ point.
Order the following events in a standard backpropagation training step to reflect their strict causal and data dependencies:
- Compute scalar objective loss by evaluating predictions against ground-truth labels.
- Update model parameters using gradient-based optimization rules (such as Adam or SGD).
- Execute forward propagation through successive layers while caching intermediate activations.
- Evaluate the chain rule backward from the loss through layers to compute parameter and activation gradients.
- Fetch and preprocess the training mini-batch on the host and transfer it to device memory.
For a transformer with hidden dimension \(d_{\text{model}} = 768\) and 12 heads (\(d_{\text{head}} = 64\)), the section’s restricted accounting gives the materialized attention-score computation an arithmetic intensity of about \(d_{\text{head}}/2 = 32\text{ FLOP/byte}\). If the target accelerator is the reference H100, whose ridge point is about \(295\text{ FLOP/byte}\), what does that imply and what optimization direction best matches the section?
- The kernel is compute-bound, so increasing peak TFLOP/s is the main expected lever under this model.
- The kernel is latency-bound, so shrinking the batch is the main way to move it onto the compute roof.
- The kernel is network-bound, so the right first response is a faster inter-node AllReduce fabric.
- The kernel falls on the memory-bandwidth side of the roofline under this accounting, so reducing materialized score traffic through IO-aware tiling is the appropriate optimization direction.
8.4 Pipeline Architecture
A training step is not a single operation but a sequence of dependent stages: data must be loaded before computation can begin, forward passes must complete before backward passes start, and gradients must be computed before parameters can update. The speed of the slowest stage determines the speed of the entire system. Without pipelining, these stages serialize, idling the accelerator while the host prepares data or transfers batches across the bus.
While model execution graphs govern arithmetic on the accelerator, sustained training requires feeding those kernels across physical machine boundaries. Host CPUs ingest raw records from storage and apply preprocessing in host DRAM, while accelerators execute matrix multiplications in HBM. Data must cross the interconnect, typically a PCIe link whose bandwidth is an order of magnitude lower than device memory bandwidth. When upstream data preparation or bus transfer exceeds the duration of the forward and backward passes, the accelerator compute engines starve, reducing the hardware utilization factor \(\EfficiencyHw\) in the training-time law.
The training system divides into three subsystems. The data pipeline handles ingestion, transformation, and batching on the host; the training loop coordinates forward passes, backward passes, and parameter updates on the accelerator; and the evaluation pipeline periodically assesses model quality on held-out data. The three subsystems decouple across the training lifecycle (figure 2): processed batches flow into the core forward/backward training loop while metrics stream to an asynchronous evaluation pipeline. The interfaces between them form critical synchronization boundaries where I/O latency, interconnect transfers, or synchronous validation pauses can throttle accelerator utilization. The data pipeline supplies two of the three terms of the pipeline bottleneck model defined later (equation 6), host preprocessing and host-to-accelerator transfer, the accelerator training loop supplies the third through matrix compute, and periodic evaluation claims shared execution time from that loop.
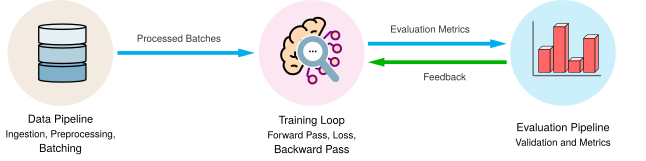
8.4.1 Pipeline stages and accelerator bubbles
A training step passes through four stages, a staged system pipeline rather than a monolithic loop. If one stage is slower than the rest, the others wait:
- Data Loading & Preprocessing (CPU/Storage): Fetching raw bytes from Non-Volatile Memory Express (NVMe) storage, decoding samples, and executing transformations on CPU cores.
- Host-to-Device Transfer (PCIe): Moving the preprocessed batch across the PCIe bus into GPU memory via direct memory access (DMA).
- Forward/Backward Pass (Accelerator): Propagating activations forward and gradients backward through layer kernels on the GPU.
- Parameter Synchronization (Interconnect, present only when multiple accelerators train the model): Exchanging gradients between accelerators across the available interconnect fabric. NVLink provides up to 900 GB/s in the H100 configuration examined later, while alternative architectures rely on PCIe switches or scale-out network fabrics.
Any throughput mismatch among these stages creates accelerator bubbles, idle windows during which compute units stall while waiting for upstream dependencies. These bubbles stem from imbalances within the per-step pipeline. A systems engineer eliminates them through asynchronous prefetching and pipeline overlapping, staging the next batch into high-bandwidth memory before the active step completes. The first three stages form the analytical basis for the pipeline execution model in equation 6, where the slowest stage dictates end-to-end iteration throughput, and section 8.5 provides the profiling methods required to isolate that bottleneck.
Across the three decoupled subsystems of figure 2, each stage occupies a distinct hardware domain: host storage and CPU cores ingest and preprocess data, accelerator compute engines execute the model loop, and evaluation pipelines periodically preempt execution to calculate validation metrics. Any latency imbalance among them therefore becomes idle accelerator cycles. At the ingestion boundary, the data pipeline stages raw records from persistent storage into host memory, applies transformations such as augmentation and normalization (LeCun et al. 2012), and packs tensors into dense batches. These batches transfer over the host-accelerator interconnect (such as PCIe) into accelerator memory. At the validation boundary, the evaluation pipeline periodically runs held-out data through the model without computing gradients. Because validation occupies the same accelerator cores needed for training, its invocation frequency represents a direct trade-off between monitoring resolution and overall training throughput.
LeCun, Yann, Leon Bottou, Genevieve B. Orr, and Klaus-Robert Müller. 2012. “Efficient BackProp.” In Neural Networks: Tricks of the Trade, vol. 7700. Lecture Notes in Computer Science. Springer Berlin Heidelberg. https://doi.org/10.1007/978-3-642-35289-8_3.
Within the accelerator, the training iteration forms a closed feedback loop governed by strict data and memory dependencies. Figure 3 traces this cyclic sequence across three stages (predict, gradients, and update), showing how predictions, the loss, and parameter gradients feed the optimizer before returning updated weights to the next iteration.
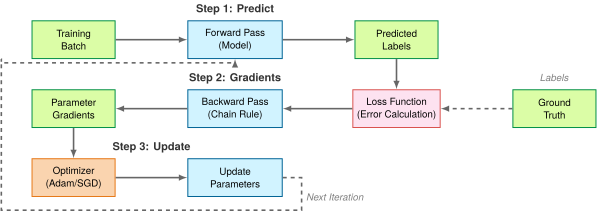
While section 8.3 counted the FLOPs and bytes of each operator in this cycle, memory residency and data dependencies govern how the hardware executes them. During the forward pass, intermediate activation tensors must remain resident in accelerator HBM because the backward pass requires them to evaluate chain-rule derivatives. Once gradients are computed, the optimizer reads both the parameters and accumulated gradients to apply the update rule, producing new weights for the subsequent iteration. The memory capacity required to hold activations, weights, and optimizer states establishes the memory floor for the entire training step.
This execution loop repeats across batches and epochs until the optimization converges. Maximizing accelerator arithmetic efficiency requires overlapping these pipeline stages across the system hierarchy. Host CPU threads prefetch and stage batch \(\BatchIndex+1\) into page-locked (pinned) host memory while the accelerator executes batch \(\BatchIndex\), so the DMA engine can stream it across PCIe asynchronously (Devices and memory explains why pinning is required). This concurrent staging hides storage latency and bus transfer time behind matrix-multiplication compute kernels. When this concurrency breaks down, because an I/O-bound data pipeline starves the device of input tensors or frequent evaluation stalls the update loop, the accelerator idles, degrading effective throughput.
8.4.2 Data pipeline
Keeping an accelerator’s arithmetic units saturated requires streaming training examples from persistent storage into device memory at or above the model’s consumption rate. Data engineering posed this as the feeding problem (The feeding problem) and measured the throughput lost when a slow storage path cannot keep up; training is where that loss is paid on every step. ResNet-50 is the chapter’s input-pipeline case, because its images are far heavier for the host to prepare than GPT-2’s token IDs. The stage trace below starts with GPT-2 XL under a scenario assumption, on-the-fly single-core tokenization (production runs usually pre-tokenize), and the system implications then turn to ResNet-50. Upstream data engineering prepares and partitions datasets on storage media, while the runtime data pipeline executes concurrently with model computation on the host CPU.
The data pipeline bridges raw storage and accelerator execution across the machine boundary. Figure 4 partitions this data movement across three physical zones: staging raw files from persistent storage into host memory, formatting and augmenting tensors across CPU worker threads, and streaming batched inputs over the interconnect to parallel GPU accelerators.
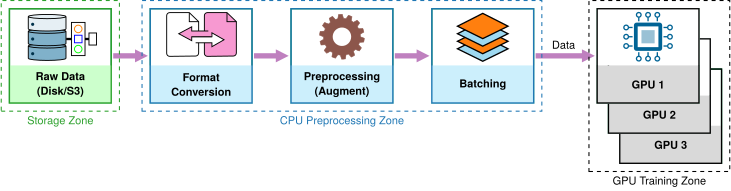
In the storage zone, raw records reside on local NVMe drives or networked storage systems. In the CPU preprocessing zone, host worker threads decode raw bytes, apply transformations such as tokenization or data augmentation, and collate individual records into dense mini-batch tensors. In the GPU training zone, accelerators transfer those tensors across the PCIe bus and execute forward and backward passes. Because these three zones form a strict pipeline, the slowest stage dictates end-to-end training throughput. In the pipeline model developed below, the storage and CPU zones together set the preprocessing term, the PCIe crossing sets the transfer term, and the GPU zone sets the compute term.
Core components
Data pipeline throughput originates at the storage subsystem. Upstream layout decisions, such as sequential chunking in columnar or container formats (Parquet, TFRecord, Arrow), dictate the physical I/O patterns presented to the operating system.
↩︎ How file format and storage layout set the data term of the iron law is established in Storage tiers and cost.
Storage throughput is bounded by the slower of two hardware constraints, \(\StorageThroughput= \min(\DiskBandwidth, \NetworkBandwidth)\), where \(\DiskBandwidth\) is the physical disk bandwidth and \(\NetworkBandwidth\) represents the network bandwidth for distributed storage systems. In practice, training workloads rarely achieve this theoretical maximum because data shuffling can turn large sequential reads into smaller, less efficient accesses. Effective storage throughput can be modeled as \(\EffectiveStorageThroughput= \StorageThroughput\times \StorageAccessFactor\), where \(\StorageAccessFactor\) depends on record size, file layout, caching, and storage hardware. When unbuffered random reads degrade \(\StorageAccessFactor\), storage bandwidth drops by an order of magnitude, transforming an I/O system that appears sufficient on paper into a primary training bottleneck.
GPT-2’s 40 GB WebText corpus fits in the host memory of a single training server, so once cached it can be served from system RAM without repeated storage reads, although preprocessing and transfer costs remain. A corpus that exceeds local memory must instead be streamed, and the system must orchestrate storage reads, preprocessing, caching, and delivery throughout training. Whether multiple workers, prefetching, local caches, or distributed storage pay off then depends on which of those stages limits throughput.
Preprocessing
Once retrieved from storage, raw bytes require CPU transformation into model-ready tensors. While static feature extraction can run offline, dynamic transformations such as on-the-fly tokenization and image augmentation execute during training. Under ideal independent-worker scaling, the CPU worker pool delivers transformation capacity according to equation 5: \[\PreprocessingThroughput= \frac{\WorkerCount}{\WorkerTransformTime} \tag{5}\] where \(\WorkerCount\) parallel processing threads each perform transformations requiring \(\WorkerTransformTime\) seconds per batch. Training architectures employ multiple workers to ensure transformation keeps pace with accelerator consumption rates.
However, transforming records assumes that storage delivers raw bytes fast enough to keep worker queues filled. Under overlapped host staging, the achieved host preparation rate cannot exceed the slower of storage retrieval and CPU transformation. Dividing effective storage throughput \(\EffectiveStorageThroughput\) by the raw bytes retrieved per batch yields the storage delivery rate in batches per second. When storage delivery lags behind worker demand, additional CPU threads sit idle waiting on disk I/O, capping host throughput regardless of \(\WorkerCount\). The complete host preparation rate is therefore bounded by the lesser of the storage delivery rate and the worker transformation capacity \(\WorkerCount / \WorkerTransformTime\).
Preprocessed data must then transfer across the host-accelerator interconnect before computation can begin. End-to-end training throughput is consequently constrained by the slowest of three sequential stages, as formalized in equation 6. In this three-stage pipeline model, the host preparation rate \(\PreprocessingThroughput\) captures the joint bound of storage delivery and CPU worker transformation, while the remaining terms capture host-to-device bus transfer and device execution: \[\TrainingThroughput=\min\left(\PreprocessingThroughput, \frac{\HostTransferBandwidth}{\BatchDataVolume}, \frac{\SustainedComputeRate}{\BatchOperations}\right) \tag{6}\] where \(\HostTransferBandwidth\) is the host-to-accelerator transfer bandwidth, \(\BatchDataVolume\) is the input bytes per batch transferred to the device, and \(\BatchOperations\) is the forward-backward work per batch in FLOPs. Every term is therefore expressed in batches per second before the minimum is taken.
Example 8.1: GPT-2 language model data pipeline
Scenario: Quantifying storage access, CPU tokenization, and PCIe host-to-device transfers supplying one H100 training GPT-2 XL at batch 32. The device service interval is the step time the training-time law gives at the chapter’s utilization, about 596 ms per batch; fitting that batch in memory requires the techniques of section 8.6, but the input path does not depend on which ones are used.
Stage trace:
- Raw text storage: The WebText corpus contributes about 40 GB of raw text. Sequential reads from NVMe SSD storage reach 7 GB/s. Under document sampling with access factor 0.1, random-access storage bandwidth drops to 0.70 GB/s, giving \(\StorageReadTime= \DataVolume / \EffectiveStorageThroughput\approx 0.1\text{ ms}\).
- Tokenization: A BPE tokenizer (50,257 vocabulary) converts text into token IDs. For batch size \(\BatchSize=32\) and sequence length \(\SequenceLength=1024\) (32.8K tokens total), a single CPU core processing 50K tokens/s takes \(\TokenizationTime\approx\) 655.4 ms per batch.
- Batching and padding: Padding and packing generate an int64 tensor of shape 32 sequences \(\times\) 1,024 tokens, producing 262.1 KB per batch.
- PCIe transfer: Transferring the tensor across the H100’s PCIe Gen5 x16 link (64 GB/s bandwidth) takes \(\BatchTransferTime=\) 0.004 ms, making bus transfer negligible.
Systems insight: Single-core CPU preparation (\(\HostPreparationTime \approx\) 655.4 ms) exceeds the accelerator service interval (\(\AcceleratorBatchTime \approx\) 596 ms), so a serial pipeline pays both costs on every step and the device service stage occupies only about 48 percent of the serial step. Slower preparation increases the exposed input wait. Scaling to 8 parallel worker processes reduces the ideal average interval between prepared batches to \(\TokenizationTime / \WorkerCount \approx\) 81.9 ms, while prefetching overlaps \(\HostPreparationTime\) with \(\AcceleratorBatchTime\) to keep the device stage supplied throughout ideal steady-state execution, delivering 54 sequences per second on one H100. The service interval is a modeled step time, not a measurement of hardware busy time. Keeping inputs available does not establish useful FLOP utilization, which requires a separate useful-work count and measured step time. Parallel workers need not shorten the latency of an individual batch, and contention or imperfect overlap can reduce the modeled throughput.
This min-of-three relationship governs training pipeline design because system throughput equals bottleneck throughput. An accelerator with 989 TFLOP/s of compute capacity delivers zero useful work while waiting for data. Conversely, a perfectly optimized data pipeline provides no benefit if the accelerator is already compute-saturated. Balanced pipeline design aligns preprocessing capacity, transfer bandwidth, and compute throughput so that no single stage dominates iteration time. Under that scenario, the GPT-2 workload shows CPU tokenization, rather than storage retrieval or bus transfer, forming the primary throughput barrier unless parallel workers and prefetching conceal host preparation latency.
Data pipeline throughput is not the only flow that can starve the accelerator. Multi-GPU training adds a second stream of traffic: the gradient synchronization required after every step. Once synchronization time exceeds compute time, communication becomes the limiting factor. Section 8.7.2 quantifies that network wall at the point where training crosses the node boundary.
System implications
Comparing supply with demand requires both in the same unit. Grouping the two host-side terms of equation 6 into a single pipeline rate \(\InputPipelineRate\), in batches per second, and writing the accelerator’s consumption rate as \(\AcceleratorConsumptionRate= \SustainedComputeRate/\BatchOperations\), also in batches per second (where \(\SustainedComputeRate\) stays in FLOP/s), leaves a coupled system whose throughput is \(\min(\InputPipelineRate, \AcceleratorConsumptionRate)\). When \(\InputPipelineRate< \AcceleratorConsumptionRate\), the accelerator sits idle waiting for data, and its busy-time fraction drops proportionally in this ideal supply model, as equation 7 shows. Busy time counts every moment the accelerator is executing, so it is an upper bound on, and distinct from, the model-FLOP utilization defined later in the chapter: \[\text{Accelerator Utilization} = \min\left(1, \frac{\InputPipelineRate}{\AcceleratorConsumptionRate}\right) \times 100\% \tag{7}\]
ResNet-50 shows how quickly that drop arrives on current hardware. One training image costs about 24.6 GFLOP, so the H100’s dense 16-bit peak could consume about 40,200 images/s. A well-tuned training step sustains only part of that ceiling; at the 25 percent fraction implied by the 3,200 images/s that The feeding problem assumed for the previous-generation A100, the H100 consumes about 10,100 images/s. A host worker that decodes and augments 375 images/s would need 28 workers per accelerator to keep up, but an eight-accelerator H100 server provides 112 host cores, 14 per accelerator. Those workers supply about 5,250 images/s, so by equation 7 the accelerator is busy only about 52 percent of the time. The same host fed an A100 with 9 workers and cores to spare. Upgrading the accelerator raised its appetite 3× without changing the host, which moves ResNet-50 from its home compute-bound regime into an input-bound one. Faster arithmetic adds nothing until the input pipeline is rebalanced, with more host cores per accelerator, decoding on the accelerator, or cached decoded data, and section 8.6.2 takes up the overlap that hides what remains.
Data flows
Training data traverses three memory tiers on its way from disk to accelerator, and the bandwidth gap between these tiers, spanning roughly two orders of magnitude, is the central challenge of data pipeline design. For equal byte volumes at each tier, the effective transfer rate is bounded by \(\min(\StorageBandwidth, \SystemMemoryBandwidth, \AcceleratorMemoryBandwidth)\), the same minimum as equation 6 applied to bandwidth tiers. When decoding, tokenization, or reuse changes the bytes handled per batch, each bandwidth must first be divided by its own per-batch byte volume so that the rates are comparable.
Bandwidth steps up the storage to DRAM to HBM hierarchy.
Local NVMe storage provides 7 GB/s, system memory delivers 50 GB/s, and the H100’s HBM delivers 3350 GB/s. Each tier is roughly an order of magnitude or more faster than the one below it, which means data that flows freely within accelerator memory creates a severe bottleneck when it must be fetched from disk. Stated in time rather than rate, the pipeline model says that when stages overlap correctly (fetching the next batch from storage while preprocessing the current one and transferring the previous one to the accelerator), the steady-state input service interval, denoted here by iteration time, is governed by the maximum of the stage times, \(\PipelineIterationTime= \max(\BatchFetchTime, \BatchProcessingTime, \BatchTransferTime)\), rather than their sum. This overlap is what prefetching seeks to achieve, with each tier operating concurrently on different batches. End-to-end training must also include accelerator compute and any exposed synchronization or evaluation time.
Practical architectures
An NVMe device rated at 7 GB/s would sustain 3.50 GB/s if a workload achieved half of peak. Small random reads and shuffling can reduce throughput further; the penalty depends on access size, queue depth, file layout, and caching.
To keep accelerators fed despite this bandwidth reduction, pipeline architectures maintain multiple data buffers simultaneously: prefetch buffers loading future batches, processing buffers holding data under transformation, and transfer buffers staging data for accelerator consumption. The total host memory required scales with the per-batch memory footprint \(\BatchBufferMemory\) according to equation 8: \[\PipelineBufferMemory= (\PrefetchBufferCount+ \ProcessingBufferCount+ \TransferBufferCount) \times \BatchBufferMemory \tag{8}\]
To avoid starving the accelerator, the average preprocessing service time per batch across all workers must not exceed the compute time per batch (\(\PreprocessingServiceTime\leq \IronLawComputeTime\)), which restates the preprocessing term of equation 6 in time. If preprocessing takes 40 ms per batch on one worker while the accelerator consumes a batch every 10 ms, ideal scaling requires at least four workers; actual worker requirements depend on storage throughput, CPU contention, and transformation cost, which section 8.6.2 examines through prefetching and parallel workers.
8.4.3 Forward and backward pass
The operation counts in section 8.3.1.1 become a scheduling problem once a prepared batch reaches the forward pass: the runtime must launch kernels with enough parallel work, stage their operands, and keep the values required by backward execution.
Compute operations
A dense layer’s FLOP count is already fixed by its input width, output width, and batch size. Its execution time also depends on how that work fills the accelerator. A layer with dimensions of \(512 \times 1024\) at batch 64 supplies 33.6 million MACs, or 67.1 MFLOP; the kernel must divide this work among execution units without leaving a long, mostly empty final wave.
Accelerators execute these parallel workloads by grouping execution threads into fixed-size units: warps14 of 32 threads on NVIDIA architectures, or wavefronts of 64 threads on AMD architectures. Hardware execution efficiency depends on aligning tensor dimensions and tile shapes with the thread-block geometry and the operand matrix dimensions required by specialized units like Tensor Cores.
14 Warp: From textile weaving, where a “warp” is the set of threads held taut on a loom while a shuttle weaves across them. NVIDIA adopted the term because GPU threads within a warp execute the same instruction in lockstep, analogous to parallel threads moving together on the loom. An NVIDIA warp contains 32 threads.
Systems Perspective 8.3: Wave quantization and tail effects
A common mistake in ML systems is ignoring the fixed execution granularity of GPU kernels. GPU execution is quantized into waves of work, but the relevant unit is the kernel’s thread or tile mapping, not necessarily one sample per thread.
Table 6: Illustrative Warp-Tail Arithmetic: Under a one-work-item-per-thread mapping, counts just above a 32-thread boundary launch a partially filled warp, so 33 items use two warps while 64 fill the same two warps. Actual training kernels map tensors to threads and tiles in implementation-specific ways, often assigning many threads to each sample, so these values cannot be inferred from batch size alone. Profiling must identify the kernel’s real mapping and wave boundaries.
Warps make the granularity concrete. In the illustrative special case where one independent work item maps to one thread, 32 items fill one warp while 33 items require a second, mostly empty warp. Neural-network kernels usually map each sample to many threads, so batch size alone does not determine this utilization.
On a large GPU such as the NVIDIA H100 with 132 Streaming Multiprocessors (SMs), where each SM schedules groups of warps, the hardware processes thousands of threads in a single wave. If the total workload slightly exceeds a wave boundary (for example, 1.01 waves), the hardware must execute a second, nearly empty wave to completion before the next task begins.
Table 6 quantifies that one-item-per-thread illustration. It is not a general batch-size performance model.
| Independent Work Items | Warps Needed | Lane Utilization | Relative Time |
|---|---|---|---|
| 32 | 1 | 100% | 1\(\times\) |
| 33 | 2 | 51.6% | ~2× |
| 64 | 2 | 100% | 1\(\times\) |
| 65 | 3 | 67.7% | ~1.5× |
Systems insight: The table teaches the shape of the penalty, not its size for any real kernel. The actionable rule is to choose batch, sequence, and hidden dimensions that are multiples of the kernel’s tile size and that divide into whole waves across the SMs, then benchmark the neighboring candidates. Profiling reveals partially filled warps or waves; batch size alone cannot.
Beyond dense matrix multiplication, distinct neural architectures introduce specialized computational patterns. Convolutional networks, for instance, slide spatial filters across multichannel input tensors. Consider an input tensor of dimensions \(64 \times 224 \times 224 \times 3\) (batch size \(\times\) height \(\times\) width \(\times\) channels) processed by \(7 \times 7\) kernels. Each position requires 147 multiply-accumulate operations, and with 64 filters operating across \(218 \times 218\) spatial dimensions, the arithmetic work reaches hundreds of millions of multiply-accumulate operations per image. Accelerators execute these spatial convolutions by either lowering them into dense GEMMs through column unfolding (im2col) or applying Winograd minimal filtering, which reduces multiplications at the cost of extra additions and transform workspace.
The other operator families impose different scheduling constraints. Attention alternates batched matrix products with row-wise reductions, while normalization requires statistics before normalized outputs can be produced. The arithmetic-intensity analysis in section 8.3.4 explains their traffic cost; the runtime must additionally respect these reduction dependencies and choose which intermediates can remain inside a fused kernel.
Optimized operator libraries such as cuDNN (Chetlur et al. 2014) implement multiple computational algorithms for each layer type, dynamically selecting among them based on tensor dimensions, scratchpad memory limits, and hardware capabilities. For example, cuDNN chooses between direct convolution, GEMM-based lowering, fast Fourier transform (FFT) convolution, and Winograd transforms by evaluating the trade-off between workspace memory overhead and arithmetic operations (NVIDIA Corporation 2023a). These hardware utilization patterns reinforce the coupling between batch size and hardware efficiency established in section 8.3.2.1: larger batch sizes saturate accelerator compute units and amortize memory transfers, but increase intermediate activation storage.
Chetlur, Sharan, Cliff Woolley, Philippe Vandermersch, Jonathan Cohen, John Tran, Bryan Catanzaro, and Evan Shelhamer. 2014. “cuDNN: Efficient Primitives for Deep Learning.” arXiv Preprint arXiv:1410.0759.
NVIDIA Corporation. 2023a. NVIDIA cuDNN Developer Guide, Version 8.9.6.
Memory management
Memory management binds during the forward pass, when intermediate activations must be retained in high-bandwidth memory for gradient computation during backpropagation. How quickly that retained state grows depends on the architecture, as a convolutional network shows.
Consider ResNet-50 processing images at 224 \(\times\) 224 resolution with a batch size of 32. The initial convolutional layer produces activation maps of dimension 112 \(\times\) 112 \(\times\) 64; per image at single-precision (4 bytes), this requires approximately 3.2 MB. For an illustrative capacity budget, assume retained forward activations total 8 GB, the backward pass adds another 4 GB of activation working set (a supplied scenario assumption, distinct from stored parameter gradients), and model parameters consume 102.4 MB. This 12.1 GB subtotal excludes parameter gradients, optimizer state, and additional runtime workspace; those terms must be added before deciding whether training fits.
Under the same linear-scaling assumption, doubling the batch size to 64 doubles activation storage: forward activations reach 16 GB and the backward activation working set reaches 8 GB, raising this subtotal to 24.1 GB. In vision models with large spatial resolutions, activations dominate the memory footprint while parameter storage (102.4 MB) is negligible. For large language models, the balance inverts: GPT-3 (175B parameters) requires approximately 700 GB just for parameters in FP32 (350 GB in FP16), exceeding single-accelerator capacity before allocating any activation memory or optimizer state.
Because accelerator memory (80 GB on the reference H100) must hold activations, parameters, gradients, and optimizer states simultaneously, memory capacity rather than compute throughput frequently caps the feasible batch size. Two system-level techniques relieve this capacity bottleneck: activation checkpointing discards intermediate activations during the forward pass and recomputes them during the backward pass, trading redundant arithmetic for reduced storage; and mixed-precision training halves storage per value for tensors represented in 16-bit formats instead of FP32. Master weights and optimizer state may remain in FP32, so the saving must be calculated for each term of the memory budget. Both techniques are analyzed in detail in section 8.6.
During backpropagation (section 8.3.3), the backward pass traverses the network in reverse order, consuming retained forward activations to compute parameter and activation gradients at roughly twice the arithmetic cost of the forward pass. Memory requirements shift dynamically across layers. In ResNet-50, mid-network layers expand to 256 filters from the initial 64, where reduced spatial map dimensions partly compensate for higher channel depth. Peak memory footprint reflects retained forward activations, active gradient buffers, temporary workspaces, and the runtime allocation schedule rather than the width of a single layer alone.
8.4.4 Parameter updates
Once backward execution populates the gradient buffers, the optimizer consumes them and updates the persistent state defined in algorithm 1. The important pipeline boundary is the weight mutation: the next forward pass must observe the completed update. Listing 2 shows that boundary at the framework interface.
loss.backward()  # Compute gradients
optimizer.step()  # Update parameters
The optimizer’s memory traffic is exposed on this dependency path. The FP32 Adam update, which moves 28 bytes per parameter in section 8.3.2.4, must finish before the next forward pass reads those weights. Fusing moment updates and weight writes can shorten this interval by reducing passes over HBM, even when the forward and backward matrix products already use the arithmetic units efficiently.
Batch size and parameter updates
Increasing batch size improves accelerator utilization by raising the arithmetic intensity of matrix multiplications and reducing synchronization frequency, but it also alters optimization dynamics. Scaling batch size without retuning the learning-rate schedule can degrade convergence, creating an optimization gap where hardware efficiency comes at the expense of model quality. Figure 5 isolates this dynamic across synthetic loss trajectories: holding the learning rate fixed while expanding from batch 32 to batch 256 leaves an acute optimization gap (dashed silver curve), whereas linearly scaling the learning rate brings convergence close to the baseline path (green curve).

For a fixed token budget, doubling the global batch size halves the number of parameter updates per epoch. To traverse a comparable distance in parameter space with fewer updates, the linear scaling rule of the large-batch ResNet-50 recipe in section 8.3.2.1.2 scales the learning rate proportionally with batch size (\(\ScaledLearningRate = \BaseLearningRate \times \ScaledBatchSize/\BaseBatchSize\)). Although effective across moderate batch ranges when combined with learning-rate warmup, linear scaling does not guarantee equivalent convergence or generalization. Beyond a critical batch size, gradient noise is largely eliminated, and further batch expansion yields diminishing returns per training sample while escalating memory pressure.
Beyond convergence dynamics, batch size dictates communication frequency in distributed systems. A larger global batch reduces the number of optimizer steps and gradient synchronizations per epoch. Because the communication payload of dense all-reduce synchronizations depends on parameter count rather than batch size, larger batches amortize interconnect latency over more compute FLOPs. In distributed settings, local micro-batch size and global batch size jointly determine the maximum degree of data parallelism. When memory capacity constrains the local micro-batch, gradient accumulation (section 8.6.5) decouples the effective batch size from per-device activation memory, accumulating gradients across multiple forward-backward passes before triggering an optimizer step.
8.4.5 Training state and checkpoints
A run that takes 35 days on one accelerator does not run uninterrupted. Hardware fails, jobs are preempted, and numerical instabilities corrupt weights, so a training system must save the run’s state to storage at intervals and restore it exactly. That saved state is a different mechanism from the activation checkpointing of section 8.6.5.1.2, which recomputes values inside one step; a training checkpoint is a file that carries the run across steps.
Resuming requires restoring model weights and optimizer state in lockstep: first-moment vectors, second-moment variance estimates, and step counters. In the mixed-precision Adam recipe of section 8.3.2.3, a checkpoint holds the FP16 working weights (2 bytes per parameter), the FP32 master weights (4 bytes), and the two FP32 moments (8 bytes), 14 bytes per parameter. The FP16 gradients, which every step recomputes, are left out of the 16 bytes per parameter that training holds in device memory. For GPT-2 XL the checkpoint payload is therefore about 21 GB (3 GB + 6 GB + 12 GB), 7× the FP16 weights alone, and writing it to a local NVMe drive at 7 GB/s takes about 3 s. Checkpoint volume governs how long a save stalls the run and how long recovery takes, connecting fault tolerance to the iron law’s \(\DataVolume\) term.
At the framework level, optimizers expose internal state dictionaries via state_dict() for serialization. Listing 3 demonstrates accessing optimizer state dictionaries, and listing 4 shows saving and restoring model parameters and optimizer states. Reproducing the training trajectory also requires the relevant random-number state, data position, learning-rate scheduler, and gradient-scaler state.
import torch
import torch.nn as nn
import torch.optim as optim

model = nn.Linear(10, 5)
optimizer = optim.Adam(model.parameters(), lr=0.001)

# After training steps, optimizer accumulates state
loss = model(torch.randn(3, 10)).sum()
loss.backward()
optimizer.step()

# Access state for checkpointing
state = optimizer.state_dict()
# Contains: {'state': {...}, 'param_groups': [{'lr': 0.001, ...}]}# Saving checkpoint
checkpoint = {
"epoch": epoch,
"model_state_dict": model.state_dict(),
"optimizer_state_dict": optimizer.state_dict(),
}
torch.save(checkpoint, "checkpoint.pt")
# Resuming training
checkpoint = torch.load("checkpoint.pt")
model.load_state_dict(checkpoint["model_state_dict"])
optimizer.load_state_dict(checkpoint["optimizer_state_dict"])A checkpoint holds only persistent state. During a training step, the FP16 gradients rejoin that state in device memory and the saved activations from reverse-mode automatic differentiation sit on top of it, so device memory must hold more than the checkpoint file suggests. Notebook 8.5 works through the full comparison for a billion-parameter model.
Napkin Math 8.5: Training memory beyond the checkpoint
The frameworks chapter’s ResNet-50 breakdown (Recording the backward graph) already showed training memory several times the size of the stored weights. The following scenario extends the comparison to gradients, optimizer state, and saved activations at billion-parameter scale.
Problem: Calculate the memory that gradients, optimizer states, and forward activations add beyond raw model weights in this billion-parameter training scenario.
Math:
- Model weights (FP16): 2 GB.
- Gradients (FP16): 2 GB (same size as weights).
- Master weights (FP32): 4 GB, the full-precision copy that mixed-precision training updates.
- Optimizer states (Adam): 8 GB (momentum and variance in FP32, 4\(\times\) the FP16 weight memory).
- Activations: For a batch size of 32 and a 100-layer network, reverse-mode automatic differentiation retains the operation-dependent values required by derivative rules; activation checkpointing can omit selected values and recompute them during the backward pass. \[ \ActivationMemory \approx \BatchSize \times \LayerCount \times \SequenceLength \times \HiddenDimension \times \LayerSavedTensorCount\times \ElementStorageSize \] For a 1024-token sequence, 1024-wide hidden state, 1 saved tensor per layer, and \(\ElementStorageSize = 2\) bytes for FP16: \(32 \times 100 \times 1024 \times 1024 \times 1 \times 2 \approx \text{\textbf{6.7}}\,\text{GB}\). Materialized attention terms can add a separate \(\BatchSize \times \AttentionHeadCount \times \SequenceLength^2\) component, which is why memory-efficient attention kernels matter.
Systems insight: A 2 GB model carries 16 GB of steady-state training state once gradients and optimizer buffers have been allocated, 8× its FP16 weights (16 bytes per parameter in the mixed-precision Adam recipe), while its checkpoint file holds 14 bytes per parameter. During a training step, batch-dependent activations add another 6.7 GB, raising the peak to about 20.7 GB beyond the weights. During training, data movement includes saving and retrieving these activations.
Checkpoint cadence decides how much work a failure discards. Because every update depends on the one before it, a single unmitigated numerical explosion does not cost one step; it can invalidate every step taken since the last good checkpoint, which at frontier scale means thousands of accelerator-hours.
War Story 8.1: The PaLM loss spikes (2022)
Context: PaLM’s 540-billion-parameter run used 6,144 TPU v4 chips across two 3,072-chip Pods connected through Google’s data-center network and suffered severe training-instability spikes absent from smaller runs (Chowdhery et al. 2022).
Failure mode: The training loss spiked roughly 20 times despite gradient clipping. The spikes occurred at highly irregular intervals, sometimes late in training, never appeared in smaller models, and had no identified principled mitigation.
Impact: Each recovery discarded recent progress on an expensive 6,144-chip run, so reproducible checkpoints and repeatable data order were prerequisites for replay.
Response: Engineers restarted training from an uncorrupted checkpoint roughly 100 steps prior to each spike and skipped approximately 200–500 data batches around the failure window.
Systems lesson: Every step discarded in a recovery is paid for again in cluster time, so operational fault tolerance decides how much of the hardware’s time turns into lasting progress. Automated loss-spike detection, checkpoint cadence, and batch skipping are core system mechanisms for keeping that lost fraction small.
PaLM’s recoveries kept 6,144 chips busy on steps that were later thrown away, so the cluster’s time was spent without the run advancing. In the training-time law that discarded work appears as a lower utilization factor \(\EfficiencyHw\), which makes checkpoint cadence a throughput decision as well as a reliability one. Frequent saves stall the run for the write time above, while sparse saves lengthen the replay after each failure.
Decomposing the training pipeline exposes the mechanics of data loading, forward and backward execution, parameter updates, and saved training state, while the computation and memory costs in section 8.3 quantify the FLOPs, memory footprint, and bandwidth each phase demands. Yet knowing how stages execute does not reveal where a specific training workload stalls. A pipeline is only as fast as its slowest stage. In an overlapped pipeline where data loading takes 120 ms and computation takes 100 ms, a 20 percent faster kernel saves nothing, because the step still takes 120 ms. Before applying optimization techniques, systems engineers must profile the execution timeline to determine whether compute, memory bandwidth, storage I/O, or network synchronization binds performance.
Checkpoint 8.2: Costing a step and building its pipeline
The first half of the chapter costed one training step and assembled the pipeline that runs it. Check that each piece can be computed before moving on to diagnosis and optimization.
Cost of a step
Pipeline
Self-Check: Question
Which set of subsystems defines the chapter’s high-level training system architecture, and what systems engineering advantage does this decomposition provide?
- Storage controller, compiler intermediate representation, and runtime execution engine; this separates hardware target code generation from storage layout.
- Data pipeline, training loop, and evaluation pipeline; this separates distinct resource profiles (CPU/storage I/O, accelerator compute/memory, and periodic validation) so bottlenecks can be isolated at subsystem interfaces.
- Tokenizer, hyperparameter optimizer, and model registry; this organizes the model deployment lifecycle around developer interfaces.
- Gradient aggregator, parameter server, and checkpoint restorer; this decomposes cloud service microservices.
In a profiled training pipeline, CPU data preprocessing sustains \(4\text{ GB/s}\) on the same logical batch representation that host-to-device transfer and GPU consumption are being compared against. Host-to-device PCIe transfer sustains \(32\text{ GB/s}\), and GPU compute consumes data at an equivalent rate of \(12\text{ GB/s}\). Under the section’s ideal-overlap pipeline model, what determines end-to-end throughput, and what is the best first engineering action?
- The average of the three rates, so the effective throughput is \(16\text{ GB/s}\) and all stages should be tuned evenly.
- The PCIe transfer rate, because every batch must cross the bus before any compute can happen.
- The minimum rate, \(4\text{ GB/s}\) from preprocessing, so the first action is to reduce the input-side bottleneck before tuning faster stages.
- The GPU compute rate, because training pipelines are ultimately limited by accelerator execution speed rather than host stages.
Explain why CPU-side tokenization and data augmentation can severely bottleneck GPU training even when the resulting tensor transfer across PCIe takes less than one millisecond.
True or False: Scaling the training batch size by \(8\times\) while keeping the learning rate and schedule unchanged guarantees the same model quality in less wall-clock time.
To enable fast, asynchronous Direct Memory Access (DMA) transfers from host RAM to GPU memory without intermediate CPU staging copies, host memory buffers must be allocated as page-locked or ____ memory.
In the chapter’s staged system pipeline framework, what constitutes an “accelerator bubble” and what is the primary diagnostic step to resolve it?
- An intentional synchronization barrier inserted by automatic differentiation to ensure memory coherence across gradient passes; resolved by disabling graph checks.
- An on-chip SRAM cache eviction event caused by large transformer sequence lengths; resolved by switching to smaller embedding tables.
- A loss of arithmetic intensity when batch sizes fall below the hardware ridge point; resolved by forcing FP64 accumulation.
- Silicon idleness where accelerator ALUs wait for data loading, host-to-device PCIe transfer, or parameter synchronization; resolved by profiling the four pipeline stages to identify and overlap the slowest stage.
8.5 Identifying Bottlenecks
An accelerator can report near-100 percent activity in nvidia-smi while spending half its cycles stalled on memory traffic, padding, or recomputing discarded activations. Knowing what each operation costs on paper does not show which resource actually saturates during a run, and raw device busy-time percentages cannot separate useful training arithmetic from overhead. Model FLOPs utilization (MFU)15 supplies that comparison by measuring achieved model arithmetic against the hardware’s peak rate.
15 Model FLOPs utilization (MFU): The PaLM paper (Chowdhery et al. 2022) defined MFU as observed throughput divided by the theoretical maximum throughput at peak FLOPs. Its 540-billion-parameter run reported 46.2 percent MFU on 6,144 TPU v4 chips. The remainder is not credited by the model-FLOP numerator, and MFU alone does not identify how much came from memory traffic, communication, pipeline bubbles, recomputation, or other work.
Chowdhery, Aakanksha, Sharan Narang, Jacob Devlin, Maarten Bosma, Gaurav Mishra, Adam Roberts, Paul Barham, et al. 2022. “PaLM: Scaling Language Modeling with Pathways.” arXiv Preprint arXiv:2204.02311.
Definition 8.3: Model FLOPs utilization (MFU)
Model FLOPs utilization (MFU) is the efficiency metric \(\ModelFlopsUtilization = \ModelStepOperations/ (\PeakRate \cdot \TrainingStepTime)\), where \(\ModelStepOperations\) is the useful per-step model FLOP count (forward plus backward, excluding rematerialization) and \(\TrainingStepTime\) is the measured wall-clock time per training step, expressing what fraction of peak hardware throughput is doing useful model computation.
- Significance: MFU makes the effective-throughput term in the iron law concrete. For GPT-2 XL (1.5B parameters) processing 32,768 tokens per step on an H100 (989 TFLOP/s dense FP16/BF16 Tensor Core peak), a 0.60 s step gives model FLOPs divided by the available peak-rate FLOP budget of approximately 0.50 (50 percent). The remaining 50 percent is not credited as model FLOPs and can reflect memory traffic, communication, bubbles, non-model operations, or idle time. Diagnosing that gap requires a profile rather than a universal threshold.
- Distinction: Hardware utilization reports whether device engines are active, whereas MFU credits the analytical model-FLOP estimate used in its numerator. It can therefore exclude recomputation and padding even when those operations keep the device busy. Comparisons across accelerators remain sensitive to the selected peak-throughput specification and FLOP-counting convention.
- Common pitfall: A frequent misconception is that 100 percent MFU is a realistic sustained target. Memory traffic, communication, and non-matrix work keep end-to-end runs below peak. Reported values depend on the model, precision, batch shape, hardware, and MFU definition, and can improve with FlashAttention and careful tuning.
Three distinct metrics are commonly referred to as “utilization” in training systems, and each addresses a different operational question. The hardware efficiency factor \(\EfficiencyHw\) in the training-time law (equation 1) represents the end-to-end fraction of theoretical peak compute converted into useful model arithmetic across an entire run, whereas MFU measures this same ratio over an individual training step as the direct empirical estimator for \(\EfficiencyHw\). In contrast, the accelerator busy-time fraction of equation 7, the metric reported by standard operating-system and vendor monitoring utilities such as nvidia-smi, indicates only whether execution cores are active, without distinguishing useful matrix products from memory-stall cycles, padding overhead, or rematerialization. Consequently, busy-time utilization serves only as an upper bound on MFU: a data-starved pipeline has a low busy-time fraction, whereas a well-fed but memory-stalled workload shows near-100 percent busy-time utilization alongside low MFU.
Training bottlenecks can be investigated through three categories aligned with the D·A·M taxonomy (Data, Algorithm, Machine). Table 7 connects each axis to a common training bottleneck, its observable symptoms, and relevant optimization techniques. The axis names where the remedy usually lives rather than what the bottleneck is. Compute-bound and memory-bound execution are both mismatches between an algorithm and a machine, as the ridge point showed, but a compute-bound kernel is most often relieved by asking for less or cheaper arithmetic (Algorithm), a memory-bound kernel by changing how the machine stages and moves bytes (Machine), and an input stall by repairing the data path (Data). These are diagnostic starting points, not exclusive mappings.
↪ The full D·A·M diagnostic framework, with its troubleshooting matrix and scorecard, is collected for reference in The D·A·M Taxonomy.
| D·A·M Axis | Bottleneck | Symptoms | Primary Solutions |
|---|---|---|---|
| Algorithm | Compute-bound | High arithmetic-unit activity; additional bandwidth does not improve throughput; arithmetic throughput is limiting | Reduced precision, more efficient algorithms, faster compute hardware |
| Machine | Memory-bound | High memory-bandwidth use relative to arithmetic throughput; kernels stall on data movement | Kernel fusion, memory-efficient attention, reduced precision formats |
| Data | Data-bound | Periodic accelerator utilization drops to near-zero; CPU fully busy during gaps; pipeline cannot feed GPU fast enough | Prefetching, pipeline overlap, faster storage, DataLoader parallelism |
Among these three regimes, data-bound stalls are the most frequently misdiagnosed because they manifest on the accelerator as idle gaps rather than saturated execution units. When host-side ingestion, decoding, or preprocessing cannot sustain the throughput demanded by device memory buses, the accelerator starves.
Example 8.2: The GIL-locked GPU
Scenario: An engineering team builds a PyTorch data-loading pipeline using standard Python
threading for CPU-bound image preprocessing that holds the global interpreter lock (GIL).
Diagnosis: The GIL serializes these Python-level preprocessing threads, making host preparation time (\(\HostPreparationTime\approx 250 \text{ ms}\)) far exceed GPU execution time (\(\AcceleratorBatchTime\approx 12 \text{ ms}\)), reducing the accelerator busy-time fraction to about 4.6 percent in this serial preparation-and-compute model. Here the fraction measures time spent computing, not arithmetic efficiency relative to peak throughput.
Systems lesson: Python CPU work that holds the GIL can serialize threads and starve GPUs; native operations may release it. Process workers (num_workers > 0) avoid interpreter serialization, while the NVIDIA Data Loading Library (DALI) can move eligible work off the host.
In the execution timeline captured by figure 6, wide white intervals separate brief GPU stream activity bursts, marking periods where accelerator compute engines idle while CPU-side Python threads assemble the next batch.
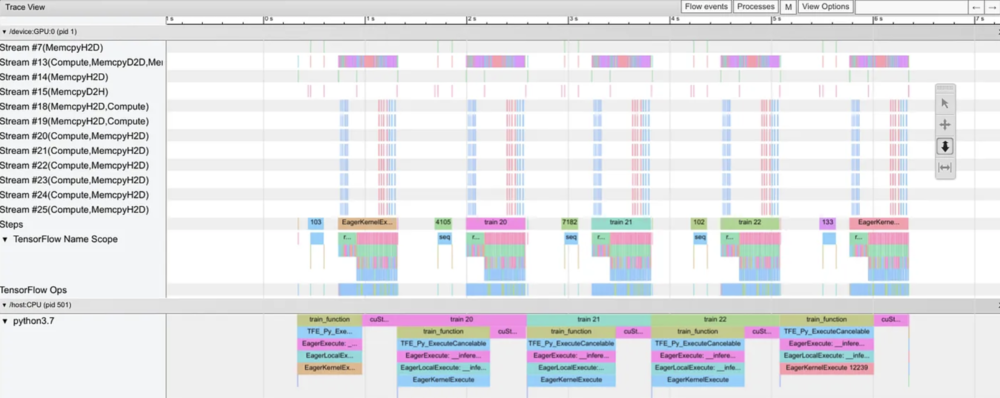
Two classes of tools expose these signatures. Framework-level profilers record a timeline of operations, memory allocations, and input-pipeline stalls, which locates idle gaps and attributes them to host work. System- and kernel-level GPU profilers record kernel execution, memory transfers, synchronization points, and per-kernel counters such as achieved memory throughput and arithmetic-unit occupancy, which explains why a kernel that runs is slow. The method below uses the first class to find where time goes and the second to explain it.
↪ How profilers and benchmark harnesses turn these measurements into reproducible results is developed in Training Benchmarks.
A disciplined profiling workflow proceeds top-down from system timelines to kernel-level performance counters, mapping observable profiler traces to the D·A·M taxonomy in table 7. First, timeline visualization locates idle intervals between kernel invocations. Correlating these gaps with batch preparation, transfers, host dispatch, and synchronization establishes what prevents the next kernel from running. When input starvation is confirmed, remedies include asynchronous prefetching, multi-process workers, or offloading preprocessing to the accelerator to overlap data movement with compute. Second, when kernels execute contiguously without host-induced gaps, memory throughput relative to peak bandwidth distinguishes memory-bound from compute-bound execution. If HBM traffic saturates while arithmetic units idle, the workload is memory-bound; kernel fusion and memory-efficient attention relieve this constraint by retaining intermediate tensors in on-chip SRAM rather than writing them back to global memory. Finally, if tensor cores operate near theoretical capacity and memory buses have spare bandwidth, the workload is compute-bound, where throughput gains require lower numerical precision, such as BF16 or FP8, to increase peak arithmetic throughput.
Applied to the chapter’s two running cases, the method gives two different first moves. Before profiling anything, the FP32 GPT-2 XL step at batch 32 does not fit in an H100’s memory, a capacity limit that the memory techniques below must address first. Once it fits, the timeline shows the input gaps. With single-core tokenization, host preparation takes about 655.4 ms per batch against a device step of about 596 ms (example 8.1), so a serial pipeline keeps the device stage busy only about 48 percent of each step, a Data-axis diagnosis that no kernel optimization can fix. ResNet-50 on the H100 reaches the same axis by a different route: the host cores available per accelerator supply too few decoded images, leaving the accelerator busy only about 52 percent of the time. A diagnosis names the binding resource; it does not remove it. These two profiles, read against the training-time law and the memory constraint, determine which intervention to apply first and which ones would change nothing.
Self-Check: Question
Why is Model FLOPs Utilization (MFU) a more reliable metric than raw GPU busy percentage (reported by tools like
nvidia-smi) when evaluating training systems efficiency?- MFU is measured directly from host CPU clock cycles, eliminating GPU driver instrumentation overhead.
- MFU is mathematically fixed to 100% on any healthy accelerator cluster regardless of software overhead.
- MFU counts only the theoretical forward and backward FLOPs required by the model architecture divided by the product of peak hardware throughput and measured step time, whereas raw GPU busy percentage also counts time spent on recomputation, padding, and memory stalls outside that model-FLOP numerator.
- MFU measures training loss convergence speed per dollar rather than floating-point operations.
An engineer profiles two training workloads. Workload A shows 92 percent GPU busy time, near-saturated HBM bandwidth, low CPU activity, and continuous kernel timelines. Workload B shows 20 percent GPU busy time with regular 50 ms idle gaps, low HBM bandwidth, and 100 percent CPU utilization. Apply the D·A·M taxonomy to classify each workload’s likely bottleneck and state the next optimization category for each.
Order the steps of the systematic training optimization workflow recommended in the chapter:
- Classify the primary performance constraint (Data-, Memory-, or Compute-bound) using the D·A·M taxonomy.
- Run a representative training run with framework and system profilers enabled to capture CPU, PCIe, and GPU timeline traces.
- Re-profile the system to evaluate MFU improvement and identify whether the bottleneck has shifted to a new pipeline stage.
- Apply a targeted optimization technique specifically addressing the identified binding constraint.
An engineering team suspects that an individual custom LayerNorm kernel has poor arithmetic intensity and low register occupancy, while another team suspects their DataLoader is causing host-to-device PCIe transfer stalls. Which combination of profiling tool classes from the chapter is best suited to investigate each respective issue?
- A kernel-level GPU profiler with per-kernel counters for the arithmetic intensity and occupancy analysis; a framework-level or system-level timeline profiler for the DataLoader and PCIe transfers.
nvidia-smifor kernel-level arithmetic intensity; TensorBoard loss curves for DataLoader PCIe transfer stalls.- NVIDIA Nsight Compute for cluster-wide inter-node network bandwidth; PyTorch Profiler for register allocation analysis.
- Linux
topcommand for GPU kernel instruction analysis; NVIDIA Nsight Systems for CPU register spill tracking.
A team’s profiler shows the GPU at 18 percent utilization with periodic drops to zero, while one CPU core is pinned near 100 percent and the PCIe link is mostly idle. Using the section’s staged-pipeline framework, explain how to diagnose the bubble’s source and what fix should be targeted.
8.6 Pipeline Optimizations
Even well-designed training pipelines rarely approach hardware peak throughput without targeted optimization: at a typical model-FLOP utilization of 30 percent to 50 percent, an H100 rated at 989 TFLOP/s delivers only 296.7 TFLOP/s–494.5 TFLOP/s of useful model arithmetic. These derived scenario values reflect the gaps between peak and realized throughput reported across published large-model systems (Narayanan et al. 2021; Chowdhery et al. 2022). Systems such as SuperNeurons show one version of this problem, in which memory-management bottlenecks prevent larger networks from training efficiently unless the runtime actively optimizes activation storage and transfer (Wang et al. 2018). Closing that utilization gap requires matching a targeted systems intervention to the specific resource that profiling shows is saturated: data movement, arithmetic throughput, or memory capacity. Table 8 extends the D·A·M bottleneck classification of table 7 by matching each bottleneck to the technique that removes it, the term of the training-time law that the technique moves, and its effect on memory, which decides feasibility rather than appearing in the law.
Narayanan, Deepak, Mohammad Shoeybi, Jared Casper, Patrick LeGresley, Mostofa Patwary, Vijay Korthikanti, Dmitri Vainbrand, et al. 2021. “Efficient Large-Scale Language Model Training on GPU Clusters Using Megatron-LM.” Proceedings of the International Conference for High Performance Computing, Networking, Storage and Analysis, 1–15. https://doi.org/10.1145/3458817.3476209.
Wang, Linnan, Jinmian Ye, Yiyang Zhao, Wei Wu, Ang Li, Shuaiwen Leon Song, Zenglin Xu, and Tim Kraska. 2018. “SuperNeurons: Dynamic GPU Memory Management for Training Deep Neural Networks.” Proceedings of the 23rd ACM SIGPLAN Symposium on Principles and Practice of Parallel Programming, 41–53. https://doi.org/10.1145/3178487.3178491.
| Bottleneck the profile shows | Technique | Law term moved | Memory effect | Developed in |
|---|---|---|---|---|
| Accelerator idle while input is prepared | Prefetching and overlap | \(\EfficiencyHw\) ↑ | Prefetch buffers ↑ in host or device memory | section 8.6.2 |
| Arithmetic rate at FP32 | Mixed precision (FP16/BF16) | \(\PeakRate\) ↑; bytes moved ↓ | Activations ↓; static state unchanged | section 8.6.3 |
| Attention’s quadratic HBM traffic | FlashAttention (IO-aware tiling) | \(\EfficiencyHw\) ↑; same model FLOPs | Attention scores ↓ from quadratic to linear | section 8.6.4 |
| Batch too large for memory | Gradient accumulation | \(\EfficiencyHw\) may ↓ at smaller micro-batches | Activations ↓ to one micro-batch | section 8.6.5.1.1 |
| Activations exceed memory | Activation checkpointing | \(\EfficiencyHw\) ↓ (recomputation adds work) | Activations ↓ to segment boundaries | section 8.6.5.1.2 |
| Kernel launches and intermediate traffic | Kernel fusion | \(\EfficiencyHw\) ↑ | Intermediates ↓ | The memory wall and kernel fusion |
Because training throughput is governed by the system’s binding constraint, applying an optimization to a nonbinding subsystem yields no end-to-end speedup. Accelerating tensor arithmetic with lower precision or FlashAttention cannot reduce step time if compute pipelines remain stalled waiting for batches from the host. Conversely, expanding prefetch buffers provides no benefit when execution is bound by HBM capacity or backward-pass recomputation. Profiling must therefore identify whether the workload is bound by input supply, memory capacity, memory bandwidth, or arithmetic throughput before an intervention is selected.
Although the governing constraint shifts with system scale (a 100 GB model faces capacity and interconnect limits that never bind a 1 GB model), identifying and mitigating each bottleneck follows consistent physical principles. Data movement latency emerges when host storage I/O and PCIe transfers cannot stage batches fast enough to keep accelerator compute units saturated. Computational throughput falls below peak hardware rates when operations execute in FP32 instead of using lower-precision Tensor Cores, or when non-fused kernels repeatedly transfer intermediate activations across the memory bus. Memory capacity constraints bind execution because accelerator HBM must simultaneously hold model parameters, optimizer states, gradients, and forward activations. Exhausting this memory caps both model depth and per-device batch size.
Because system resources are tightly coupled, relieving one constraint often exposes another. This is the conservation-of-complexity heuristic from the opening of Part I, which holds that complexity tends to move among Data, Algorithm, and Machine rather than disappear. For example, resolving host I/O stalls by aggressively prefetching batches consumes host memory; separately staged device queues also consume accelerator memory. Conversely, shrinking per-device batch sizes to fit within HBM limits lowers the arithmetic intensity of matrix multiplications, shifting execution from compute-bound matrix math into memory-bandwidth stalls. For GPT-2 XL, the profile above already ranks the first moves. If counters confirm that attention is bandwidth limited, IO-aware attention tiling (FlashAttention) targets that constraint; asynchronous prefetching hides data ingestion behind computation, and mixed precision accelerates eligible tensor operations while reducing storage for activations retained in the lower-precision format. The optimization challenge is to diagnose the governing bottleneck from execution profiles and apply targeted interventions without creating a more severe constraint elsewhere.
8.6.1 Systematic optimization framework
Tuning a training pipeline without a profile wastes work on resources that are not limiting step time or shifts the bottleneck to a neighbor. A disciplined optimization pass therefore proceeds in three steps: profile the step to locate the binding constraint, pick an intervention that relieves that specific limit, and check how combined interventions compete for shared memory and bandwidth.
First, profiling tools such as PyTorch Profiler, TensorFlow Profiler, or NVIDIA Nsight Systems record timestamps and hardware counters across each iteration. Traces capture kernel execution times on accelerator execution units, DMA transfers across PCIe or NVLink buses, and host CPU thread scheduling. Comparing elapsed time across these lanes isolates which subsystem sets the critical path. When data-loading intervals lie on the critical path and coincide with accelerator input waits, as in the GPT-2 XL profile above, the run is data-starved; speeding up matrix multiply kernels yields almost no wall-clock gain until input delivery keeps up.
Second, each diagnosed bottleneck points to a specific remedy. When the accelerator idles waiting for batches, asynchronous prefetching and double-buffering over PCIe overlap host data preparation with device compute. When kernel runtimes are bound by HBM bandwidth rather than arithmetic, kernel fusion and tiled algorithms such as FlashAttention keep intermediate activations in on-chip SRAM. When HBM capacity runs out, activation checkpointing discards and recomputes activations during the backward pass, or gradient accumulation splits each batch across sequential micro-batches to cap peak allocation. Finally, when streaming multiprocessors saturate with dense matrix math, 16-bit formats (FP16 or BF16) move eligible operations onto Tensor Cores, multiplying peak matrix throughput several-fold over FP32 CUDA cores (table 9) while halving the bytes moved per operand.
Third, combining interventions requires checking their side effects on shared hardware resources. Asynchronous prefetching hides data movement latency behind computation, but double-buffered batch queues consume pinned host memory and device HBM. Other pairs reinforce one another: combining 16-bit mixed precision with activation checkpointing cuts activation memory enough to admit a larger per-device batch size, raising the arithmetic intensity of matrix multiplications on underfed Tensor Cores. After each change, a fresh profile verifies that the secondary resource cost has not created a new bottleneck.
Figure 7 formalizes this diagnostic playbook into a triage flowchart, using low accelerator activity and high memory allocation as signals for further investigation. Idle gaps require tracing input preparation, host work, and synchronization; capacity pressure motivates memory-saving techniques. When neither signal explains a missed target, kernel profiling distinguishes bandwidth, arithmetic, and launch limits.
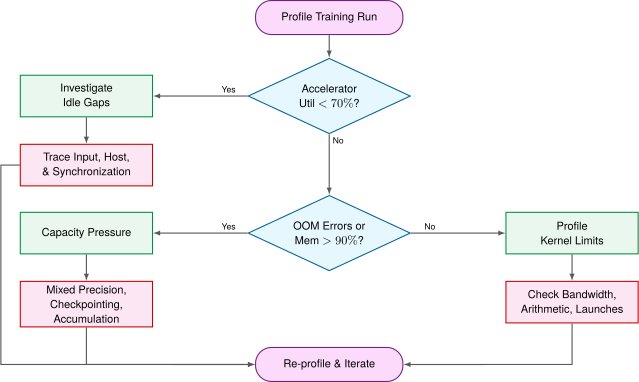
Each fix moves the bottleneck, so optimization is iterative and governed by Amdahl’s law: a speedup applied to one stage is capped by the share of step time that stage occupies, the bound that equation 11.1 formalizes. Resolving input starvation through asynchronous prefetching, for instance, drives accelerator utilization upward until memory bandwidth or compute saturation limits step time. Each intervention requires re-profiling to identify the newly emerged critical path, continuing the cycle until accelerator execution units operate near peak theoretical throughput or application performance targets are achieved.
8.6.2 Data prefetching and overlapping
Prefetching and overlapping put the systematic framework to work on the bottleneck the data pipeline left open. ResNet-50’s host workers prepare images more slowly than the H100 consumes them, so the accelerator is busy only about 52 percent of the time (section 8.4.2). That figure already assumes the host prepares the next batch while the accelerator computes the current one. Run serially, preparation and computation add, and the accelerator would be busy only about 34 percent. Overlap recovers the difference by hiding host work behind computation, but it cannot raise the supply rate itself, so closing the rest of the gap for ResNet-50 requires more host workers or decoding on the accelerator. The techniques below are most effective when profiling shows computational units idle while waiting for data.
In ML training, a “Read” stage is rarely a simple disk fetch. For image workloads it encompasses JPEG decoding, random crops, and color jitter applied on CPU cores before the tensor is ready to transfer; for language workloads it encompasses tokenization, subword encoding, and sequence padding. The Gantt schedule in figure 8 isolates the serial bottleneck of unbuffered ingestion. The GPU Train row remains completely idle during file-open intervals (Open 1, Open 2) and read stages (Read 1, Read 2), stretching the two-epoch schedule out to 01:35 because compute steps cannot begin until host-side decoding and transfer finish.
Prefetching addresses these inefficiencies by loading data into memory before its scheduled computation time. During the processing of the current batch, framework data pipelines such as tf.data load and prepare subsequent batches, maintaining a consistent supply of ready data (Murray et al. 2021).
Murray, Derek G., Jiřı́ Šimša, Ana Klimovic, and Ihor Indyk. 2021. “Tf.data: A Machine Learning Data Processing Framework.” Proceedings of the VLDB Endowment 14 (12): 2945–58. https://doi.org/10.14778/3476311.3476374.
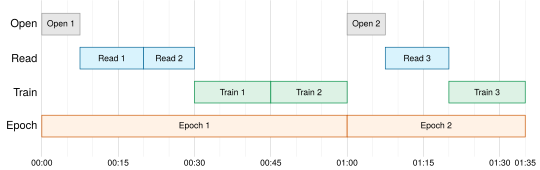
Overlapping extends prefetching by coordinating multiple pipeline stages to execute concurrently. As the system processes the current batch on the accelerator, background host threads load and preprocess subsequent batches. Aligning the serial schedule of figure 8 against the overlapped timeline in figure 9 demonstrates this latency hiding: concurrent staging of Open 2 and Read 3 behind active execution eliminates idle bubbles between training blocks (Train 1 through Train 3), compressing total wall-clock duration from approximately 95 min down to 65 min (a 31.6 percent reduction). Actual gains depend on stage balance and available concurrency.
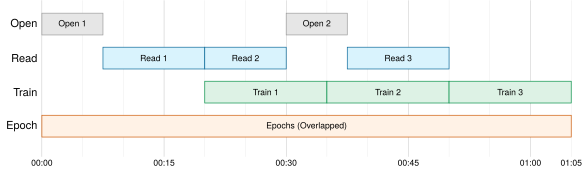
Prefetching mechanics
The overlapped schedule requires enough host workers and buffering to make the next batch ready before the device requests it. Worker count controls preparation capacity; queue depth absorbs variation in preparation time. Neither changes the slowest-stage bound established by equation 6.
Machine learning frameworks expose the control variables for this trade-off. Listing 5 demonstrates PyTorch’s DataLoader configuration, where num_workers = 4 sets preprocessing parallelism and prefetch_factor = 2 maintains a buffer of 8 batches ready for accelerator consumption.
loader = DataLoader(
    dataset, batch_size=32, num_workers=4, prefetch_factor=2
)
The parameters num_workers and prefetch_factor are not generic performance toggles. They determine CPU parallelism and buffer depth, which means they shift pressure from accelerator idle time to host memory and CPU scheduling. The third knob, pin_memory=True, lets host-to-device copies overlap accelerator execution through DMA; its cost is page-locked host memory that the rest of the system can no longer page.
↩︎ The DataLoader’s three knobs, worker count, prefetch depth, and pinned memory for DMA transfers, are established in Data loading.
Buffer management is the main trade-off. A buffer that is too small causes the GPU to wait for data preparation, reintroducing the idle time prefetching was meant to remove. An overly large host-side buffer consumes memory that could otherwise support input processing and other host work. The right configuration coordinates CPU preparation, storage I/O, and GPU computation so each resource has work ready at the moment it can use it. These techniques yield the greatest benefit when storage access is slow, preprocessing is complex, or datasets are large.
Practical considerations
Prefetch buffers and overlap depth are tunable, so the same machinery adapts to whichever stage binds, whether slow storage, limited network bandwidth, or computational throughput. Prefetching and overlapping deliver the greatest gains when preprocessing lies on the critical path but can run concurrently with model computation. In an illustrative image pipeline, random cropping (10 ms), color jittering (15 ms), and normalization (5 ms) total 30 ms per batch. Overlap can hide up to the concurrent accelerator-computation time; any excess remains on the critical path. NLP workloads similarly benefit when tokenization and subword processing would otherwise block the training loop.
The primary trade-off is memory: prefetch buffers consume host memory, or device memory when a separate device-side queue is used, in proportion to buffer depth and batch size. With batch size 256 high-resolution images (\(1024\times 1024\) pixels), one buffered batch requires approximately 3.2 GB. With num_workers = 4 and prefetch_factor = 2, the 8-batch prefetch window can hold about 25.8 GB. Tuning these parameters requires empirical testing because excessive workers contend for CPU, storage, and memory resources, while insufficient buffering reintroduces data stalls. Start with a modest worker count, increase it while measuring throughput and memory, and stop when additional workers no longer reduce accelerator idle time. When the input pipeline already exceeds compute demand, deeper prefetching adds complexity without improving throughput.
8.6.3 Mixed-precision training
Running a modern training job entirely in 32-bit floating point (FP32) leaves the accelerator’s 16-bit Tensor Cores idle and doubles the byte footprint of every forward activation kept in HBM. Mixed-precision training removes both bottlenecks by executing matrix multiplications and storing activations in a 16-bit format while retaining 32-bit precision for sensitive accumulations and parameter updates. Floating-point formats compares FP32, FP16, BF16, FP8, and INT8 precision-range trade-offs. A training recipe commonly combines FP32 with either FP16 or BF16; it does not ordinarily use FP16 and BF16 interchangeably in the same path. The resulting speed, memory, and accuracy effects depend on the workload and hardware (Micikevicius et al. 2018; Wang and Kanwar 2019; Kalamkar et al. 2019).
A neural network’s stored FP32 weights require 4 bytes per parameter, while FP16 and BF16 weights use 2 bytes. For a model with \(10^9\) parameters, the working copy of the weights shrinks from 4 GB to 2 GB. That saving does not carry over to the static training state. The common FP16 recipe keeps FP32 master weights and FP32 Adam moments, so it spends 2 + 2 + 4 + 8 = 16 bytes per parameter on weights, gradients, master copy, and moments, exactly what FP32 Adam spends on its 4 + 4 + 8. Mixed precision’s memory benefit therefore comes from the tensors that really are stored in 16 bits, above all the activations, together with the halved bytes moved for every 16-bit read, write, and gradient exchange.
Mixed precision’s throughput benefit is larger than its memory benefit. Figure 10 plots peak dense throughput by number format across four generations of data center accelerators. From V100 to B200 the FP32 rate grew 4.8×, the FP16/BF16 tensor rate grew 18×, and the lowest supported format, 4-bit floating point (FP4) on B200, delivers 72× the V100’s FP16 tensor rate. Hardware gains now arrive almost entirely through tensor units built for lower precision. On B200 the FP16/BF16 tensor path is 30× faster than FP32, so a training job that stays in FP32 leaves nearly all of the chip’s arithmetic idle.

NVIDIA Corporation. 2020b. NVIDIA V100 Tensor Core GPU Datasheet. NVIDIA product documentation.
NVIDIA Corporation. 2021. NVIDIA A100 Tensor Core GPU Datasheet. NVIDIA product documentation.
NVIDIA Corporation. 2023b. NVIDIA H100 Tensor Core GPU: Product Specifications. Https://www.nvidia.com/en-us/data-center/h100/.
NVIDIA Corporation. 2024. NVIDIA Blackwell Architecture. NVIDIA product documentation.
The numerical differences between these formats shape their use cases. Table 9 shows that BF16’s 8-bit exponent gives it approximately the same normal exponent range as FP32, while FP16’s 5-bit exponent gives a minimum positive normal value of about \(6.1 \times 10^{-5}\) and a maximum finite value of \(65{,}504\). FP16 subnormals extend toward \(6 \times 10^{-8}\), although their treatment depends on the operation and hardware mode. FP32 provides about seven decimal digits of precision, FP16 about three, and BF16 about two to three. BF16 therefore trades mantissa precision for the exponent range that often simplifies deep-learning training.
| Property | FP32 | FP16 | BF16 |
|---|---|---|---|
| Exponent bits | 8 | 5 | 8 |
| Mantissa bits | 23 | 10 | 7 |
| Min normal value | \(10^{-38}\) | \(6.1 \times 10^{-5}\) | \(10^{-38}\) |
| H100 peak throughput ratio | 1\(\times\) | 15× | 15× |
The choice between formats depends on model characteristics and hardware support. BF16’s wider exponent range reduces overflow and underflow concerns, while FP16 provides more mantissa bits but often requires loss scaling. Framework autocast policies and fused kernels choose higher-precision accumulation for numerically sensitive operations when needed; loss reduction, softmax, normalization, and optimizer updates are common candidates, but their exact execution dtype is implementation-dependent.
Figure 11 traces this conventional FP16 execution cycle across six numbered stages: FP32 master weights are downcast to FP16 for the forward pass, loss scaling shifts small gradient values into representable range before backpropagation, and the resulting scaled gradients are unscaled and cast back to FP32 prior to the parameter update. Modern framework implementations may store or accumulate particular tensors differently, and BF16 recipes commonly omit loss scaling because of their wider exponent range.
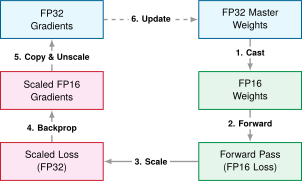
Modern accelerator architectures pair dense matrix execution units with reduced-precision numerical formats to maximize arithmetic throughput. NVIDIA introduced Tensor Cores for FP16 operations in the Volta architecture (NVIDIA 2017) and added native BF16 execution in Ampere (NVIDIA Corporation 2020a), matching the native BF16 support Google developed for Tensor Processing Units (Wang and Kanwar 2019). These specialized functional units execute low-precision matrix multiply-accumulate operations at four to sixteen times the rate of standard 32-bit floating-point ALUs.
NVIDIA. 2017. Training with Mixed Precision.
NVIDIA Corporation. 2020a. NVIDIA A100 Tensor Core GPU Architecture. NVIDIA Whitepaper, V1.0.
Mixed-precision training turns those hardware capabilities into a split numerical policy. Eligible matrix multiplications and convolutions execute in FP16 or BF16 on tensor units, while reductions, accumulations, and parameter updates retain higher precision. The performance gain comes from both arithmetic throughput and data movement: lower-precision units pack more multiply-accumulates into each cycle and each unit of silicon area, while narrower tensors halve data transfer volumes across caches and high-bandwidth memory. Higher precision remains necessary where wide reductions, small parameter updates, or sensitive normalizations can accumulate rounding error. Framework autocast policies enforce this split dynamically, selecting lower-precision execution for compute-intensive matrix multiplications while preserving FP32 for numerically fragile operations.
Loss scaling
FP16’s 5-bit exponent limits its representable dynamic range, creating severe underflow hazards during backpropagation. When computing gradients across deep networks, successive chain-rule multiplications frequently produce gradient magnitudes smaller than FP16’s minimum positive normal value (\(2^{-14} \approx 6.1 \times 10^{-5}\)). While IEEE 754 FP16 defines subnormal numbers down to \(\approx 6 \times 10^{-8}\), hardware accelerators often flush subnormal inputs and outputs to zero to prevent pipeline stalls. When gradients underflow to zero, weight updates stall and training fails to converge.
Loss scaling counters underflow by exploiting the linearity of differentiation: \(\nabla_{\ModelParameters} (\LossScaleFactor \cdot \LossFunction) = \LossScaleFactor \cdot \nabla_{\ModelParameters} \LossFunction\). Multiplying the scalar loss \(\LossFunction\) by a large scaling factor \(\LossScaleFactor\) (such as \(2^{10}\) or \(2^{15}\)) prior to backpropagation shifts the gradient distribution rightward into FP16’s normal representable range. Once backpropagation completes, the accumulated gradients are divided by \(\LossScaleFactor\) (unscaled) before applying the optimizer update.
Deep learning frameworks automate this process through dynamic loss scaling; Mixed-precision training support describes the GradScaler machinery that scales the loss, unscales the gradients, and skips any step whose gradients overflow. The training decision is how the scale factor adapts. Because gradient norms fluctuate during training, a static scale factor risks either underflow (if \(\LossScaleFactor\) is too small) or numerical overflow past FP16’s maximum finite value of \(65{,}504\) (if \(\LossScaleFactor\) is too large). A dynamic scaler therefore skips each overflowing step so that nonfinite gradients never reach the FP32 master weights, halves \(\LossScaleFactor\) at each skip, and doubles \(\LossScaleFactor\) after a configurable growth window without overflow (such as 2,000 consecutive steps). Together these adjustments keep gradients near the upper end of the dynamic range without saturating.
Mixed-precision benefits
Mixed-precision training delivers gains across three interacting system dimensions: memory footprint, arithmetic throughput, and communication volume. Halving operand width cuts the storage of every 16-bit tensor by 50 percent, so a one-billion-parameter model’s working weights drop from 4 GB to 2 GB. As the 16-bytes-per-parameter accounting above showed, FP32 master weights and moments give that saving back in the static state, so the footprint that actually shrinks is the activations. Computationally, reduced precision routes dense matrix multiplication kernels to high-throughput Tensor Core pipelines (section 8.6.3.3). In distributed topologies, transferring 16-bit rather than 32-bit gradients halves collective AllReduce traffic across the interconnect. These effects compound: reclaimed activation memory permits larger micro-batches, Tensor Cores accelerate kernel execution, and narrower tensors reduce gradient exchange latency. The following case study evaluates these memory effects on GPT-2 XL at batch 32, the configuration the activation notebook left far over the H100’s capacity.
Napkin Math 8.6: GPT-2 mixed precision memory savings
Problem: What does mixed precision save when GPT-2 XL (1.5B parameters) trains at batch 32 and sequence length 1,024 on one H100, and what does it leave unchanged?
FP32 baseline:
- Parameters and gradients (FP32): 12 GB (6 GB parameters + 6 GB gradients)
- Activations: ~574 GB
- Optimizer states (Adam first and second moments in FP32): 12 GB
- Total: ~598 GB
FP16 mixed precision:
- Parameters (FP16): 1.5B parameters at 2 bytes each = 3 GB
- Activations (FP16): ~287 GB
- Gradients (FP16): 3 GB
- FP32 master weights: 6 GB (for precise optimizer updates)
- Optimizer states (Adam first and second moments in FP32): 12 GB
- Total: ~311 GB, about 3.6× the H100’s 80 GB
Systems insight: Mixed precision halves the activations and leaves the static state unchanged at 24 GB. At batch 32 the remaining activations still dominate, and most of them are the quadratic attention-score matrices, which FlashAttention (section 8.6.4) removes next.
Memory savings alone do not guarantee stable training. In the FP16 training recipe used here, maintaining FP32 master weights is necessary because parameter updates \(\FiniteChange \ModelWeight= -\LearningRate \cdot \LossGradient\) (learning rate times gradient) are typically orders of magnitude smaller than the weight values \(\ModelWeight\). In FP16, where the 10-bit mantissa provides roughly three decimal digits of precision, adding an update that is more than \(2^{11} \approx 2048\) times smaller than the weight magnitude results in arithmetic swamping: the updated weight rounds back to its original value. This loss of an increment through rounding is distinct from the update value itself underflowing. Retaining master weights in FP32 preserves these incremental updates across thousands of optimizer steps, casting to 16 bits only when staging weights for the forward pass. Autocast policies similarly isolate wide reductions, layer normalizations, and softmax layers in FP32 to prevent catastrophic cancellation.
Once numerical stability is established, reduced-precision arithmetic and reduced memory traffic can shorten execution when they reduce work on the critical path. Comparing complete training recipes does not isolate the contribution of precision alone; model quality, batch size, optimizer representation, and activation policy must be accounted for. The following scenario models these compound throughput, schedule, and infrastructure cost gains for a GPT-2 XL training run.
Napkin Math 8.7: GPT-2 mixed precision throughput and cost
Problem: Holding utilization fixed, how much faster and cheaper is GPT-2 XL’s run on one H100 when its matrix products run in BF16 instead of in 32-bit formats?
Peak rates by path: FP32 on scalar units 67 TFLOP/s; TF32 on Tensor Cores 494 TFLOP/s; BF16 on Tensor Cores 989 TFLOP/s.
Run time and cost at 50 percent utilization and $4/hour per accelerator:
- FP32: about 518 days, $49,751
- TF32: about 70 days, $6,748
- BF16: about 35 days, $3,370
Quality gate: The comparison is valid only if a controlled validation run shows that the BF16 recipe meets the same acceptance criteria as the 32-bit baseline. The scenario does not assume a particular perplexity difference.
Systems insight: The peak ratios, 2× over TF32 and 15× over FP32, bound the gain rather than predict it. Holding utilization fixed assumes that every part of the step speeds up with the matrix units, but elementwise kernels, optimizer updates, and input waits do not run on Tensor Cores, so by Amdahl’s law the measured speedup is smaller. A real decision requires measured throughput, billing, and quality validation for the target workload.
Realizing these speedups requires empirical profiling rather than assuming automatic acceleration. For small models or memory-bound workloads not dominated by large matrix multiplications, data type casting and kernel launch overheads can offset the arithmetic throughput advantage. Furthermore, whether an accelerator supports native BF16 or requires FP16 loss scaling depends on the underlying microarchitecture.
Mixed-precision hardware support
Specialized matrix execution units deliver the wall-clock speedup of mixed precision by spending fewer bits per operand. Accelerators pair these low-precision multiply units with higher-precision accumulation registers to maintain numerical stability during dense matrix reductions.
The Volta-generation Tensor Cores introduced earlier in this section perform \(4{\times}4\) matrix multiply-accumulate operations in a single clock cycle, a datapath that Tensor Cores examines in detail. For FP16 inputs, a single Tensor Core executes: \[ \TensorCoreOutputMatrix= \TensorCoreLeftInput\times \TensorCoreRightInput+ \TensorCoreAccumulatorMatrix\] where \(\TensorCoreLeftInput\) and \(\TensorCoreRightInput\) are FP16 inputs and \(\TensorCoreAccumulatorMatrix\) and \(\TensorCoreOutputMatrix\) may use FP32 accumulation. Higher-precision accumulation reduces rounding error, although it does not eliminate numerical error or cancellation.
Hardware peak specifications define the theoretical ceiling on this acceleration. The reference H100 exposes 67 TFLOP/s of FP32 throughput on standard CUDA cores and 989 TFLOP/s of dense FP16 or BF16 Tensor Core throughput, a 15× peak ratio, and adds FP8 Tensor Cores at 1,979 TFLOP/s without sparsity, about 2× its FP16/BF16 rate. These figures represent hardware ceilings rather than end-to-end training guarantees: matrix multiplications map directly to Tensor Cores, but data movement, non-Tensor-Core kernels, communication, loss scaling, and optimizer updates remain. While the batched matrix multiplication \(\AttentionQueryMatrix\AttentionKeyMatrix^T\) in transformer self-attention (\(2 \times \BatchSize\times \AttentionHeadCount \times \SequenceLength^2 \times \AttentionHeadDimension\) FLOPs) maps directly to these tensor units, Amdahl’s law dictates that the remaining memory-bound elementwise operations, communication collectives, and optimizer updates bound the realized end-to-end speedup.
Brain Float 16 (BF16) maintains FP32’s 8-bit exponent while reducing the mantissa to 7 bits. This design choice prioritizes dynamic range preservation over precision, which matters for gradient-based learning where values span many orders of magnitude. Google’s TPUs natively support BF16, while NVIDIA’s Ampere architecture (A100) and newer provide full hardware support.
The range advantage of BF16 appears exactly where loss scaling was needed for FP16. A gradient below FP16’s smallest normal value of \(6.1 \times 10^{-5}\), which some hardware flushes to zero, is still an ordinary normal number in BF16, whose smallest normal value of about \(10^{-38}\) matches FP32’s exponent range. BF16 therefore usually avoids the loss scaling needed by FP16, although accumulation precision and rounding still matter.
NVIDIA’s Hopper architecture (H100) adds FP8 Tensor Core paths for 8-bit floating-point values (1.98 PFLOP/s on H100 dense vs. 0.99 PFLOP/s for FP16 dense, without sparsity); FP8’s two bit layouts and the per-tensor scaling they require are developed in Numerical formats. Table 10 summarizes when each precision is appropriate:
| Precision | When to Use | Hardware Requirement |
|---|---|---|
| FP8 | Throughput-oriented training with validated scaling | Supported FP8 hardware |
| BF16 | Wide exponent range without FP16 loss scaling | Supported BF16 accelerator |
| FP16 | Higher mantissa precision with managed loss scaling | Supported FP16 accelerator |
| FP32 | Higher precision or unsupported lower-precision path | GPU |
In addition to accelerating compute-bound matrix operations, reduced precision relieves memory bandwidth bottlenecks by altering operational arithmetic intensity. On modern accelerators, large matrix multiplications reside in the compute-bound regime of the roofline model, whereas elementwise operations (such as bias additions, layer normalization, and residual connections) reside firmly in the memory-bound regime. The H100 illustrates the physical imbalance between arithmetic capability and memory bandwidth: its HBM3 bus supplies 3,350 GB/s, whereas sustaining its 67 TFLOP/s of FP32 throughput without operand reuse would demand 268 TB/s if every FLOP required fresh data from memory. Although operand reuse reduces actual traffic for dense matrix multiplications, operations with low arithmetic intensity remain strictly bandwidth-limited.
For memory-bound kernels, execution time is determined by bytes transferred across the memory bus rather than arithmetic clock cycles. Converting 32-bit operands to 16-bit FP16 or BF16 halves the byte volume transferred across the HBM bus, doubling the theoretical throughput of memory-bound operations even without engaging Tensor Cores. Realized bandwidth gains depend on cache hit rates, kernel fusion, and format conversion costs.
Mixed-precision training support describes how autocast and GradScaler implement the split between 16-bit and FP32 operations inside the framework. The policy decision that remains for the training recipe is which format to run, and listing 6 makes it a single switch: the FP16 path enables gradient scaling, and the BF16 path disables it.
import torch

model = TransformerModel().cuda()
optimizer = torch.optim.Adam(model.parameters(), lr=1e-4)
amp_dtype = (
    torch.float16
)  # torch.bfloat16 usually does not need loss scaling
scaler = torch.amp.GradScaler(
    "cuda", enabled=(amp_dtype == torch.float16)
)

for inputs, targets in dataloader:
    optimizer.zero_grad()

    # Automatic precision selection per operation
    with torch.amp.autocast("cuda", dtype=amp_dtype):
        output = model(inputs)
        loss = criterion(output, targets)

    # Scale loss to prevent gradient underflow
    scaler.scale(loss).backward()

    # Unscale gradients before optimizer step
    scaler.step(optimizer)
    scaler.update()  # Adjust scaling factor dynamically
Because hardware support for low-precision formats evolved across accelerator generations, the optimal mixed-precision recipe depends on the target architecture. Table 11 outlines the precision trade-offs across three generations of NVIDIA GPUs.
| Architecture | Recommended Precision | Key Considerations |
|---|---|---|
| V100 (Volta) | FP16 with loss scaling | No native BF16 Tensor Core path; clipping depends on the training recipe |
| A100 (Ampere) | BF16 or FP16 | BF16 avoids FP16 loss scaling; TF32 can accelerate eligible FP32 matrix operations |
| H100 (Hopper) | BF16, FP16, or validated FP8 | FP8 requires an FP8-aware recipe; 1,979 TFLOP/s is a peak ceiling |
Throughput gains across these generations came from new tensor execution units built for narrower formats, and measured speedups also reflect software stacks, kernels, and batch dimensions that changed alongside the hardware. The peak-rate ratios in Notebook 8.7 bound what a format switch can deliver on one H100. In practice, BF16 is the default where the hardware supports it, and FP16 with loss scaling is the fallback.
8.6.4 FlashAttention: IO-aware attention optimization
Mixed-precision training addresses two bottlenecks, compute throughput because Tensor Cores run faster on 16-bit operands, and memory capacity because each value uses fewer bytes. For transformer models, a third bottleneck often dominates, and the roofline analysis has already located it. Counting only its score-matrix traffic, materialized attention in GPT-2 Small reaches about 32 FLOP/byte, well left of the H100 ridge point in figure 1, because its quadratic intermediate matrices are written to HBM during the forward pass and read back during backpropagation. Halving the bytes per value does not change that quadratic traffic, so even with reduced precision the compute units can sit idle while the processor waits for data.
The same quadratic term dominates GPT-2 XL’s memory. At batch 32 and 1,024 tokens, the stored score, probability, and dropout matrices account for about 201 GB of the 287 GB of mixed-precision activations, about 70 percent. An attention kernel that never stores them leaves 85.6 GB of activations; with the static state the step needs 109.6 GB, still about 24 GB more than the H100’s 80 GB (85.9 GB in decimal units), so removing attention’s traffic is necessary but not sufficient.
FlashAttention (Dao et al. 2022) addresses this bandwidth bottleneck by treating attention as an IO problem. Processing attention in SRAM-sized tiles avoids materializing the full \(\SequenceLength{\times}\SequenceLength\) matrix in HBM and reduces traffic without changing the mathematical output, which is how the roofline preview moved attention rightward toward, and for favorable shapes past, the ridge.
The standard attention memory bottleneck
Standard self-attention materializes an \(\SequenceLength{\times}\SequenceLength\) score matrix and an \(\SequenceLength{\times}\SequenceLength\) probability matrix in off-chip HBM for every attention head, turning long-sequence training into a memory-bandwidth and capacity bottleneck:
\[ \text{Attention}(\AttentionQueryMatrix, \AttentionKeyMatrix, \AttentionValuesMatrix) = \text{softmax}\left(\frac{\AttentionQueryMatrix\AttentionKeyMatrix^T}{\sqrt{\AttentionHeadDimension}}\right)\AttentionValuesMatrix \tag{9}\]
Here, \(\AttentionQueryMatrix\), \(\AttentionKeyMatrix\), and \(\AttentionValuesMatrix\) are the query, key, and value matrices for a sequence of length \(\SequenceLength\), and \(\AttentionHeadDimension\) is the key-vector dimension used to scale the dot products before softmax. Because the intermediate product \(\AttentionQueryMatrix\AttentionKeyMatrix^T\) is written out to HBM before softmax and read back immediately afterward, attention becomes an I/O problem even when the matrix products themselves map cleanly onto Tensor Cores.
The memory bottleneck emerges from materializing the \(\SequenceLength{\times}\SequenceLength\) intermediate matrices for scores and probabilities. For a sequence length of 4,096 with head dimension \(\AttentionHeadDimension =\) 64 (typical for a single attention head), the attention score matrix alone requires \(4{,}096^2 \times 4\) bytes = 67.1 MB in FP32. This section counts FP32 scores throughout, since autocast policies commonly keep softmax in FP32; at FP16 every figure halves, as in the roofline estimate, while the quadratic growth stays the same. With 16 heads, this grows to 1.1 GB just for intermediate attention matrices, not including the keys, queries, values, or output tensors.
GPU memory hierarchy creates the opportunity for I/O-aware attention. HBM offers large off-chip capacity, while much smaller on-chip SRAM has substantially higher bandwidth and lower latency. Attention implementations that materialize the quadratic intermediates in HBM must write and later read them during backpropagation. Because that traffic grows with the square of sequence length, it takes a growing share of step time as sequences lengthen.
The backward pass requires the information represented by the attention probabilities, but an implementation may either save those intermediates or recompute them. For \(\AttentionWeightMatrix = \text{softmax}(\AttentionScoreMatrix)\) and \(\AttentionScoreMatrix = \AttentionQueryMatrix\AttentionKeyMatrix^T/\sqrt{\AttentionHeadDimension}\), one gradient expression is: \[ \frac{\partial \LossFunction}{\partial \AttentionQueryMatrix} = \frac{1}{\sqrt{\AttentionHeadDimension}} \cdot \text{dsoftmax}\!\left(\frac{\partial \LossFunction}{\partial \AttentionWeightMatrix},\, \AttentionWeightMatrix\right) \cdot \AttentionKeyMatrix\] where \(\text{dsoftmax}\) denotes the softmax Jacobian-vector product. A conventional implementation may save the probability matrix for this computation; saving both probabilities and raw scores is not mathematically required. FlashAttention instead saves compact normalization statistics and recomputes tiled score and probability blocks during backward propagation, avoiding full quadratic intermediates in HBM.
IO-aware attention through tiling
FlashAttention eliminates the need to materialize full \(\SequenceLength{\times}\SequenceLength\) attention matrices in HBM by computing attention incrementally through tiling. Instead of computing the entire attention matrix at once, the algorithm partitions \(\AttentionQueryMatrix\), \(\AttentionKeyMatrix\), and \(\AttentionValuesMatrix\) into tiles small enough to fit in fast SRAM, computes attention scores for these tiles, and incrementally accumulates results.
The key algorithmic insight relies on the structure of equation 9. Softmax normalizes each row of scores by a sum over the entire row, which seems to require the whole row before any output can be formed, yet the online softmax algorithm removes that requirement. Ordinary softmax, \(\text{softmax}(\SoftmaxInputVector)_i = e^{\SoftmaxInputVector_i} / \sum_j e^{\SoftmaxInputVector_j}\), is computed stably by first subtracting the row maximum. The online form instead keeps two running statistics per row as blocks of scores arrive: the largest score seen so far, \(\SoftmaxRunningMaximum\), and the sum of exponentials taken relative to that maximum, \(\SoftmaxNormalizer\). When a new block raises the maximum from \(\SoftmaxRunningMaximum\) to \(\UpdatedSoftmaxRunningMaximum\), everything accumulated so far was exponentiated relative to the old maximum, and multiplying it by \(e^{\SoftmaxRunningMaximum-\UpdatedSoftmaxRunningMaximum}\) re-expresses it relative to the new one. The same factor rescales the partially accumulated output. After the last block, dividing the output by \(\SoftmaxNormalizer\) gives exactly the softmax-weighted result, as if the whole row had been seen at once.
Algorithm 2 decomposes this computation by partitioning the queries and the keys/values into tiles small enough to fit in SRAM, then streaming over the key/value tiles while maintaining the running softmax statistics needed to assemble each output tile, without ever forming the full score matrix.
FlashAttention swaps the full attention matrix for small SRAM tiles.
No full \(\SequenceLength{\times}\SequenceLength\) score or probability matrix is written to HBM. A \(128{\times}128\) FP32 score tile, for example, occupies 65.5 KB compared with 67.1 MB for a \(4096{\times}4096\) matrix. Other inputs, outputs, and running statistics remain, so the tile is not necessarily the largest tensor in the entire kernel.
Memory and IO complexity analysis
FlashAttention improves both activation memory and memory IO, which are the limiting costs in bandwidth-bound attention. Standard attention requires \(\mathcal{O}(\SequenceLength^2)\) memory to store score matrices \(\AttentionScoreMatrix\) and attention-probability matrices \(\AttentionWeightMatrix\) across all sequence positions. FlashAttention reduces the stored activation footprint to \(\mathcal{O}(\SequenceLength)\) by keeping only input and output tensors \((\AttentionQueryMatrix, \AttentionKeyMatrix, \AttentionValuesMatrix, \AttentionHeadOutput)\) plus a small SRAM buffer for the current tile.
For \(\SequenceLength = 4096\), \(\AttentionHeadDimension = 64\), one materialized FP32 score matrix occupies \(4096^2 \times 4\) bytes = 67.1 MB per head. The three FP32 input tensors occupy \((3 \times 4096{\times}64) \times 4\) bytes ≈ 3.1 MB per head, a component-size ratio of 21.3× between one quadratic intermediate and the inputs. The comparison that decides memory is the whole per-head footprint each algorithm keeps for the backward pass. The conventional baseline assumed here stores the inputs, the output, and both the score and probability matrices, about 138.4 MB. FlashAttention stores the inputs, the output, and two numbers per row (the running maximum and sum), about 4.2 MB, roughly 32.7× smaller, and the gap widens as \(\SequenceLength\) grows because only the standard footprint is quadratic.
These stored-tensor totals exclude gradient buffers, temporary workspace, and the live SRAM tile, so they are not estimates of peak training memory. Implementations may also retain fewer quadratic intermediates than the conventional baseline assumed here.
The IO pattern changes for the same reason. Standard attention reads \(\AttentionQueryMatrix\), \(\AttentionKeyMatrix\), and \(\AttentionValuesMatrix\) from HBM, writes score, probability, and output matrices during the forward pass, then rereads those stored matrices during the backward pass before writing the gradients \(d\AttentionQueryMatrix\), \(d\AttentionKeyMatrix\), and \(d\AttentionValuesMatrix\) (shorthand for \(\partial \LossFunction/\partial \AttentionQueryMatrix\) and its counterparts). The resulting HBM traffic includes the same \(\mathcal{O}(\SequenceLength^2)\) term that made the activation footprint large. FlashAttention forms score and probability blocks in SRAM and never writes the full \(\SequenceLength \times \SequenceLength\) tensors to HBM. In the backward pass, it recomputes the needed blocks rather than reading stored full matrices. The exact HBM IO complexity depends on tile size and available SRAM because key and value blocks are streamed repeatedly across query blocks, so the bound is not simply \(\mathcal{O}(\SequenceLength \cdot \HiddenDimension)\).
Both approaches require \(\mathcal{O}(\SequenceLength^2 \HiddenDimension)\) asymptotic FLOPs for dense attention, so FlashAttention’s gain comes from traffic, not arithmetic. The resulting reduction in HBM traffic can shift the kernel toward compute-bound execution and produce a net speedup, but the final bottleneck remains shape- and hardware-dependent.
Implementation and hardware utilization
FlashAttention’s performance gains materialize through careful exploitation of GPU memory hierarchy. Modern frameworks can dispatch eligible attention operations among fused and fallback implementations based on hardware, inputs, and layouts; profiling verifies which path ran and whether it helped. Listing 7 contrasts standard and optimized attention implementations.
import torch
import torch.nn.functional as F


# Standard attention (materializes n-by-n matrix)
def standard_attention(q, k, v):
    # q, k, v: [batch, heads, seq_len, head_dim]
    scores = torch.matmul(q, k.transpose(-2, -1)) / (
        q.size(-1) ** 0.5
    )
    attn = F.softmax(scores, dim=-1)  # n-by-n matrix in HBM
    output = torch.matmul(attn, v)
    return output


# FlashAttention (no n-by-n materialization)
def flash_attention(q, k, v):
    # Can use FlashAttention when inputs and hardware are eligible
    output = F.scaled_dot_product_attention(q, k, v)
    return output


# Explicit FlashAttention 2 (flash-attn library)
from flash_attn import flash_attn_func


def flash_attn_2(q, k, v):
    # q, k, v: [batch, seq_len, heads, head_dim]
    # Different layout for optimized memory access
    output = flash_attn_func(q, k, v)
    return output
Dao et al. (2022) reports end-to-end GPT-style training speedups and separate attention-kernel benchmarks showing that IO-aware attention reduces memory traffic and improves runtime. Runtime and memory savings depend on batch size, head count, sequence length, precision, and the kernel implementation, and a capacity threshold still requires the complete training memory budget, including the state outside attention. Later versions refine the same idea: FlashAttention-2 (Dao 2023) reports a further 1.5–2\(\times\) speedup through better parallelism, and FlashAttention-3 (Shah et al. 2024) adds asynchronous memory operations and FP8 support on Hopper GPUs.
Dao, T., D. Y. Fu, S. Ermon, A. Rudra, and C. Ré. 2022. “FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness.” Advances in Neural Information Processing Systems (NeurIPS) 35: 16344–59. https://doi.org/10.52202/068431-1189.
Dao, Tri. 2023. “FlashAttention-2: Faster Attention with Better Parallelism and Work Partitioning.” arXiv Preprint arXiv:2307.08691.
Shah, Jay, Ganesh Bikshandi, Ying Zhang, Vijay Thakkar, Pradeep Ramani, and Tri Dao. 2024. “FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-Precision.” Advances in Neural Information Processing Systems 37 (NeurIPS), 68658–85. https://doi.org/10.52202/079017-2193.
When to use FlashAttention
For transformer training with long sequences, FlashAttention is usually the first attention implementation to test. It often becomes essential once sequence length pushes standard attention into an HBM-capacity or HBM-bandwidth bottleneck, especially around the multi-thousand-token regime where the \(\SequenceLength{\times}\SequenceLength\) attention matrices dominate memory. A100- and H100-class GPUs with fast on-chip SRAM benefit most. The returns diminish for short sequences where tiling overhead is not worthwhile, on older GPU architectures without comparable SRAM bandwidth, and for nonattention architectures such as convolutional neural networks and multilayer perceptrons.
In practice, deep learning frameworks handle much of FlashAttention’s integration, but the decision still depends on layout, precision, and memory budget. PyTorch’s scaled_dot_product_attention can dispatch to FlashAttention when hardware, inputs, and backend constraints permit; hand-written attention must use an eligible primitive. Three practical checks determine whether the fast path actually runs and pays off: tensor layouts must match library expectations (contiguous memory and the expected dimension ordering), execution must use FP16 or BF16 (because FlashAttention kernels target mixed precision), and gradient checkpointing should be combined with FlashAttention whenever additional activation-memory savings are needed beyond the attention scores.
The integration is often a single-line change, swapping a manual attention call for F.scaled_dot_product_attention, as listing 7 shows. The engineering decision is still the same one established by the roofline analysis: use the optimized primitive when the bottleneck is HBM traffic, and let the library manage the tiling and SRAM scheduling needed to remove it.
IO-aware design beyond attention
FlashAttention is an instance of IO-aware algorithm design: because modern accelerators are compute-abundant relative to memory bandwidth, traffic governs runtime for a bandwidth-bound kernel even when FLOPs do not change. This principle extends beyond attention. In IO-aware matrix multiplication, tiling algorithms like those in CUTLASS minimize DRAM traffic by maximizing data reuse in fast caches. A naive \(\SquareGemmDimension{\times}\SquareGemmDimension\) matrix multiply performs \(\mathcal{O}(\SquareGemmDimension^3)\) FLOPs and, without reuse, \(\mathcal{O}(\SquareGemmDimension^3)\) memory traffic; blocking keeps tiles in fast memory and moves traffic toward the \(\mathcal{O}(\SquareGemmDimension^2)\) lower bound.
The same byte-movement principle reappears in communication-efficient distributed training, where gradient compression trades extra computation (compression/decompression) for reduced network bandwidth consumption. Low-power edge devices with limited memory bandwidth benefit even more from IO-aware algorithms. Trading 10 percent more arithmetic to halve memory traffic approaches a 2\(\times\) energy reduction in the limit where data movement accounts for the entire budget, and falls short of that bound whenever arithmetic carries a meaningful share, because halving one additive term of a sum cannot more than halve the sum.
Eliminating off-chip materialization of the \(\mathcal{O}(\SequenceLength^2)\) attention matrices reclaims accelerator memory across three architectural trade-offs. First, it enables longer sequence contexts on fixed hardware, with the workable context boundary determined by the complete training recipe. Second, freeing activation memory allows larger micro-batch sizes that improve hardware arithmetic saturation, provided gradient dynamics remain stable. Third, the contracted activation footprint permits deeper transformer stacks within a given memory budget, although end-to-end multi-billion-parameter feasibility continues to depend on parameter sharding, optimizer states, and remaining layer activations.
FlashAttention performs the same arithmetic but moves fewer bytes, which is why counting bytes before FLOPs is the first step on any bandwidth-bound kernel. Bandwidth is not the only memory limit, however. The capacity required to hold activations and optimizer states at the same time can still exceed the accelerator, and when models or batch sizes outgrow device memory, two complementary techniques trade computation for memory.
8.6.5 Gradient accumulation and checkpointing
FlashAttention left GPT-2 XL’s batch-32 step about 24 GB over the H100’s capacity, and the excess now consists of ordinary activations, the layer inputs, projections, and feed-forward intermediates that backpropagation must read. Two techniques remove it without adding hardware. Gradient accumulation builds the batch from smaller micro-batches that each fit, and activation checkpointing keeps fewer activations and recomputes the rest during the backward pass. Both were named earlier, accumulation with mini-batch processing (section 8.3.2.1.2) and recomputation with activation memory (section 8.3.3.2). Using them correctly requires knowing when accumulated gradients equal the large-batch gradient, what each technique costs in time, how checkpoints are placed (the \(\sqrt{\LayerCount}\) schedule), and which loss-normalization errors most often break accumulation.
Gradient accumulation and checkpointing mechanics
Gradient accumulation changes how many examples contribute to one update; checkpointing changes which activations remain resident between the forward and backward passes.
Gradient accumulation
To execute large batch training on memory-constrained accelerators, systems split an effective logical batch across smaller sequential micro-batches. Three consecutive micro-batches evaluate independent losses (\(\LossFunction_1, \LossFunction_2, \LossFunction_3\)) and gradients (\(\MicrobatchGradient_1, \MicrobatchGradient_2, \MicrobatchGradient_3\), where \(\MicrobatchGradient_j = \nabla_{\ModelParameters}\LossFunction_j\)), accumulating into a single unified tensor (\(\MicrobatchGradient_1 + \MicrobatchGradient_2 + \MicrobatchGradient_3\)) before triggering the optimizer step (figure 12).
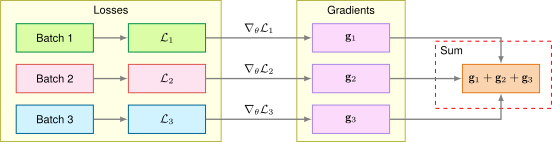
In PyTorch, gradient accumulation is usually implemented by dividing each micro-batch loss by the number of accumulation steps and calling optimizer.step() only after processing the entire effective batch. Under that averaging convention, no learning-rate adjustment is needed solely because of accumulation. The implementation follows five steps:
- Perform the forward pass for a micro-batch.
- Compute the gradients during the backward pass.
- Accumulate the gradients into a buffer without updating the model parameters.
- Repeat steps 1–3 for all micro-batches in the effective batch.
- Update the model parameters using the accumulated gradients after all micro-batches are processed.
Gradient accumulation can reproduce the gradient of a larger batch under controlled assumptions. For an effective batch size \(\BatchSize= \AccumulationStepCount\times \MicrobatchSize\) where \(\AccumulationStepCount\) is the number of accumulation steps and \(\MicrobatchSize\) is the micro-batch size, equation 10 confirms that the accumulated gradient equals the true batch gradient: \[ \nabla \FullBatchLoss = \frac{1}{\BatchSize}\sum_{i=1}^{\BatchSize} \nabla \LossFunction_i = \frac{1}{\AccumulationStepCount}\sum_{j=1}^{\AccumulationStepCount}\left(\frac{1}{\MicrobatchSize}\sum_{i \in \MiniBatchSet_j} \nabla \LossFunction_i\right) \tag{10}\]
This equivalence holds when each example’s computation is identical and the loss is averaged consistently. The right-hand side shows that averaging \(\AccumulationStepCount\) micro-batch gradients (each computed over \(\MicrobatchSize\) examples) produces the same result as computing the gradient over all \(\BatchSize= \AccumulationStepCount \MicrobatchSize\) examples at once. Stateful layers such as BatchNorm, stochastic operations such as dropout and data augmentation, finite-precision accumulation order, and step-indexed schedules can break exact equivalence, so large-batch accumulation still requires validation.
Gradient accumulation exchanges memory capacity for computation time. Table 12 separates the memory benefit from the compute and scheduling costs that remain.
| Dimension | Effect |
|---|---|
| Memory | \(\mathcal{O}(\MicrobatchSize)\) instead of \(\mathcal{O}(\BatchSize)\), yielding a \(\AccumulationStepCount\times\) reduction in activation memory |
| Computation | Unchanged total FLOPs, as all \(\BatchSize\) examples are still processed |
| Time | \(\AccumulationStepCount\) micro-batch forward and backward passes precede each optimizer step; smaller micro-batches can reduce utilization and add launch overhead |
Accumulation preserves the total example-level arithmetic but can change efficiency because smaller micro-batches use the accelerator differently and launch kernels more often. With distributed no_sync() accumulation, one gradient synchronization occurs after the \(\AccumulationStepCount\) local micro-batches rather than after each one. The model in equation 11 gives the per-update time: \[
\AccumulatedUpdateTime= \sum_{j=1}^{\AccumulationStepCount} \MicrobatchPassTime+ \AccumulatedSyncTime+ \OptimizerStepTime \tag{11}\]
Here \(\MicrobatchPassTime\) is the measured forward/backward time for micro-batch \(\MicrobatchIndex\), \(\AccumulatedSyncTime\) is the synchronization time paid for the accumulated update, and \(\OptimizerStepTime\) is the optimizer-step time. In distributed data-parallel training, standard framework wrappers automatically fire asynchronous gradient-synchronization hooks during every backward pass. When accumulating gradients across \(\AccumulationStepCount\) micro-batches, leaving these hooks active would trigger redundant AllReduce operations on every micro-batch; wrapping the first \(\AccumulationStepCount-1\) micro-batches in a model.no_sync() context suppresses this communication, synchronizing gradients only on the final \(\AccumulationStepCount\)-th step. That synchronization boundary may contain several bucketed AllReduce calls.
The wall-clock penalty relative to processing the effective batch at once is workload-dependent and must be measured rather than inferred from the memory-reduction factor. When gradient accumulation is combined with distributed data parallelism across multiple machines, additional considerations arise for gradient synchronization timing and effective batch size calculation across the cluster; advanced distributed systems texts treat these patterns in depth.
Activation checkpointing
Activation checkpointing reduces activation memory by trading additional FLOPs for lower HBM occupancy during backpropagation. Only selected boundary tensors are retained in device memory; intermediate activations are dropped during the forward pass and recomputed on demand as the backward pass traverses in reverse (figure 13, where retained tensors are solid green, dropped ones dashed gray, and recomputed ones orange). Algorithm 3 states the schedule layer by layer.
In this segment schedule, recomputed intermediate values remain available until their backward consumers finish; recomputing a segment afresh for each layer would add more work. For layers with comparable activation sizes and forward costs, spacing checkpoints uniformly every \(\sqrt{\LayerCount}\) layers reduces peak activation memory from \(\mathcal{O}(\LayerCount)\) to \(\mathcal{O}(\sqrt{\LayerCount})\) at the cost of one additional forward pass of arithmetic per training step (Chen et al. 2016). This increases executed step computation from roughly \(3\times\) to \(4\times\) the forward-pass FLOPs, trading extra arithmetic operations for a substantially reduced activation footprint. The useful model FLOP count \(\Operations\) is unchanged, so the additional work enters the training-time law through effective utilization \(\EfficiencyHw\). Actual fit and wall-clock overhead still depend on the full memory budget and execution profile. Section 8.6.5.2 derives why \(\sqrt{\LayerCount}\) spacing minimizes this footprint and works out its cost for GPT-2’s 48 layers.
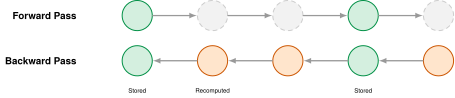
Frameworks like PyTorch provide tools such as torch.utils.checkpoint that split a model into segments and manage the recomputation, but the recompute cost remains. Checkpointing is most effective for deep architectures with dozens or hundreds of layers, such as transformers or large convolutional networks, where activation storage exceeds the GPU’s capacity before arithmetic throughput is exhausted.
The two techniques address different terms. Gradient accumulation bounds the activation memory tied to batch size, while checkpointing bounds the memory held by each layer’s intermediate activations, so together they widen the range of models that fit on available hardware.
Optimal checkpoint placement strategy
Algorithm 3 stated the \(\sqrt{\LayerCount}\) schedule without justifying it. For a network with \(\LayerCount\) layers of comparable activation size and recomputation cost, each storing \(\ActivationMemory^{(\LayerIndex)}\) bytes of activations, table 13 quantifies how the number and placement of checkpoints determines the memory-compute trade-off. Sub-linear checkpointing strategies can reduce memory consumption from \(\mathcal{O}(\LayerCount)\) to \(\mathcal{O}(\sqrt{\LayerCount})\) with additional forward arithmetic; the resulting wall-clock overhead depends on execution, while the reduced footprint can enable deeper models on existing hardware.
| Strategy | Memory Cost | Recompute Cost |
|---|---|---|
| No checkpointing | \(\LayerCount \times \ActivationMemory^{(\ell)}\) | 0 forward ops |
| One checkpoint (\(\ActivationCheckpointCount=1\)) | \(\ActivationMemory^{(\ell)} + \LayerCount \times \ActivationMemory^{(\ell)}\) | \((\LayerCount-1)\) forward ops |
| \(\ActivationCheckpointCount\) checkpoints | \(\ActivationCheckpointCount\times \ActivationMemory^{(\ell)} + (\LayerCount/\ActivationCheckpointCount)\times \ActivationMemory^{(\ell)}\) | \((\LayerCount-\ActivationCheckpointCount)\) forward ops |
The memory column counts two things, the stored checkpoints and the one segment that must be rematerialized at a time during backward, which holds \(\LayerCount/\ActivationCheckpointCount\) layers of activations. The one-checkpoint row shows why both terms matter. With a single checkpoint the only segment spans the whole network, so backward rebuilds all \(\LayerCount\) layers of activations at once and the peak is no lower than storing everything. Checkpoints pay off only when they are spread out so that each recomputed segment is short. The recompute column counts layer forwards. Every layer that is not itself a checkpoint is run forward once more, \((\LayerCount - \ActivationCheckpointCount)\) layer forwards in all, which is nearly one full forward pass when \(\ActivationCheckpointCount\) is much smaller than \(\LayerCount\).
Setting the derivative of total memory cost \((\ActivationCheckpointCount\times \ActivationMemory^{(\ell)} + (\LayerCount/\ActivationCheckpointCount) \times \ActivationMemory^{(\ell)})\) with respect to the checkpoint count \(\ActivationCheckpointCount\) to zero yields the analytical optimum at \(\ActivationCheckpointCount= \sqrt{\LayerCount}\). In the standard \(\sqrt{\LayerCount}\) checkpointing scheme, this costs roughly one extra forward pass, about one-third more total step compute, in exchange for minimizing activation footprint under this analytical model. For GPT-2 with forty-eight transformer layers, the operational difference is substantial: uncheckpointed training requires \(48 \times \ActivationMemory^{(\ell)}\) in full activation storage, whereas uniform checkpointing (\(\sqrt{48} \approx 7\) checkpoints) requires \(7 \times \ActivationMemory^{(\ell)} + (48/7) \times \ActivationMemory^{(\ell)} \approx 14 \times \ActivationMemory^{(\ell)}\), saving 71 percent activation memory for approximately 33 percent additional total step computation (by recomputing one forward pass over the uncheckpointed layers during backpropagation).
The GPT-2 notebook below uses eight equal segments of six layers. It applies the same boundary-plus-live-segment accounting with unequal storage costs: a segment input contains only the hidden tensor, whereas the reconstructed layer state also includes attention and feed-forward intermediates. The equal-state optimum above is therefore a useful baseline, not an optimality claim for that transformer schedule. Counting the two components separately produces the candidate memory budget without assuming a reduction factor.
Napkin Math 8.8: GPT-2 segment checkpointing
Problem: With mixed precision and FlashAttention-style attention, can a segment schedule fit GPT-2 XL’s batch-32 step on one H100, and what does it cost in arithmetic?
Schedule: Partition the 48 transformer layers into 8 contiguous segments of 6 layers. During forward execution, retain each segment’s input and discard its internal backward state. During backward execution, reconstruct one segment, retain its internal state while differentiating that segment, then free it before reconstructing the preceding segment. Each layer therefore executes one additional forward pass; against a forward-plus-backward step costing about three forward passes, the extra arithmetic is about one-third. This is work accounting, not a wall-clock penalty.
Math: Each retained segment input has shape batch \(\times\) sequence length \(\times\) hidden width, 32 \(\times\) 1,024 \(\times\) 1600 \(\times\) 2 bytes. Keep all 8 inputs resident while adding the complete saved-state estimate for the 6 layers of one reconstructed segment. This deliberately counts the active segment’s input in both terms, making the estimate conservative rather than omitting a live boundary.
- Retained segment inputs: 0.84 GB
- Live reconstructed segment: 10.7 GB
- Activation allowance: 11.5 GB, against 85.6 GB without checkpointing (7.4× smaller)
- Static state plus activations: 35.5 GB, leaving about 50 GB of the H100’s capacity
Systems insight: Checkpointing admits the batch-32 step by replacing retained layer interiors with small boundary tensors and one live reconstructed segment. The remaining capacity must still hold output and loss buffers, temporary backward workspaces, and allocator overhead, which a runtime peak-memory measurement confirms. Gradient accumulation offers the alternative trade, keeping every activation of a smaller micro-batch and paying in update frequency instead of recomputation.
Not all operations are equally expensive to recompute, which motivates selective checkpointing: the practical rule is to spend recomputation on high-memory layers rather than on operations whose activations are already cheap to retain. Table 14 compares where activation memory is large enough to justify recomputation.
| Layer type | Memory cost | Recompute cost | Checkpointing strategy |
|---|---|---|---|
| Attention blocks | Shape-dependent; materialized attention can add quadratic intermediates | High and sequence-length-dependent | Checkpoint block boundaries when saved state justifies recomputation |
| Feed-forward blocks | Often dominated by expanded hidden activations | High and width-dependent | Checkpoint when expanded activations dominate memory |
| Normalization | Small standalone outputs | Low | Usually handled within a larger checkpointed block |
Memory and computational benefits
Both techniques reduce activation-memory requirements without adding hardware, though each targets a different dimension of the activation footprint. Gradient accumulation produces an effective batch larger than the resident micro-batch without storing all of its activations simultaneously; while a larger effective batch reduces sampling variance, it does not by itself guarantee faster convergence or better generalization. Conversely, activation checkpointing reduces the per-layer memory footprint of intermediate activations by discarding and recomputing them as needed, freeing capacity for deeper models, additional layers, or higher-resolution inputs. For lighthouse 8.1, accumulation provides a direct way to reach a chosen effective batch size while keeping the resident micro-batch within one H100’s memory.
Napkin Math 8.9: GPT-2 gradient accumulation strategy
This GPT-2-scale scenario uses the lighthouse’s one-accelerator run time and a registry rental price to show gradient accumulation; it does not reconstruct GPT-2’s historical training bill.
Memory Constraints
- With FlashAttention-style attention and no checkpointing, a micro-batch of \(\MicrobatchSize=\) 16 needs about 67 GB, within one H100’s 80 GB.
- A resident effective batch of \(\BatchSize=\) 512 would therefore require 512 ÷ 16 = 32 accelerators.
Accumulation Configuration
- Use 8 accelerators and accumulate 4 micro-batches of 16 sequences each.
- Each accelerator processes 16 \(\times\) 4 = 64 sequences per update, giving a global effective batch of 8 accelerators \(\times\) 64 = 512.
A distributed no_sync() context can defer AllReduce until the final micro-batch.
Trade-off Analysis
- Idealized wall-clock time: 4× longer (105 hours against 26 hours) because fewer accelerators perform the same arithmetic work
- Memory overhead: accumulation normally reuses parameter-gradient buffers, although bookkeeping and temporary storage remain
- Communication: both configurations synchronize once per 512-sequence update, but participant count and topology differ
- Equal-work cost: $3,370 either way at $4/hour per accelerator, before utilization and communication effects
Why this works: Under the equivalence conditions stated above, averaged per-example gradients are additive. Each accelerator first accumulates a local gradient over its 64 examples: \[ \frac{1}{4}\sum_{j=1}^{4} \left[\frac{1}{16}\sum_{i=1}^{16} \nabla \mathcal{L}(x_{ji})\right] \]
AllReduce then averages those local gradients across 8 accelerators, producing the global effective batch: \[ \frac{1}{8}\sum_{r=1}^{8} \nabla \mathcal{L}_{\text{local}}^{(r)}, \qquad B = 8 \times 64 = 512 \]
Operational comparison
Resident configuration:
- 32 accelerators \(\times\) 16 sequences = 512 resident sequences per update
- Gradient synchronization spans 32 accelerators
- Hourly cost: $128/hour
Accumulated configuration:
- 8 accelerators \(\times\) (16 sequences \(\times\) 4 micro-batches) = 512 sequences per update
- Gradient synchronization occurs once per update across 8 accelerators, all within one server
- Hourly cost: $32/hour
- Hourly reduction: $96/hour, or 75 percent
Quality gate
- Match the examples and their order, loss normalization, optimizer state and step schedule, and stochastic-layer behavior.
- Compare held-out loss or perplexity and the optimization trajectory across repeated runs rather than assuming that the effective batch alone guarantees equivalent quality.
- Expect small round-off differences from the changed summation order; require convergence within a declared tolerance rather than bitwise identity. No perplexity result is assumed here.
Systems insight: Accumulation lowers accelerator count and hourly burn, but ideal scaling preserves accelerator-hours; actual cost depends on utilization and communication.
Listing 8 places one AllReduce after 4 local micro-batches, making the synchronization boundary explicit.
optimizer.zero_grad()
for step in range(4):  # Accumulation steps
    micro_batch = next(dataloader)  # 16 sequences
    loss = model(micro_batch) / 4  # Average effective-batch loss
    loss.backward()  # Accumulate gradients
# Now gradients represent 64 local sequences
all_reduce(gradients, op=SUM)  # Sum across 8 accelerators
gradients /= 8  # Convert the sum to the global mean
optimizer.step()  # Update with effective batch=512
Practical considerations
Gradient accumulation is most valuable when optimal batch sizes exceed GPU memory capacity. Transformer language models often use effective batches of hundreds of thousands to millions of tokens; if memory only permits a smaller number of sequences per device, accumulation bridges the gap without requiring additional hardware. Activation checkpointing complements this by enabling deeper architectures and is commonly used in transformer-scale training.
Both techniques introduce explicit trade-offs. Activation checkpointing recomputes discarded activations during backward propagation; with ordinary segment checkpointing, each discarded activation is typically reconstructed once, while recursive schedules may behave differently. Gradient accumulation reduces parameter-update frequency because each update follows \(\AccumulationStepCount\) micro-batches. When each micro-batch loss is divided by \(\AccumulationStepCount\), the accumulated gradient follows the effective-batch mean convention. If losses are summed instead, the gradients must be rescaled before the optimizer step or the learning-rate convention changed accordingly. Framework and codebase conventions differ, making normalization a common source of subtle bugs.
8.6.6 GPT-2 optimization walkthrough
Training GPT-2 XL at batch 32 on a single H100 exposes the physical boundaries that govern large-model optimization. The tensor allocation first exceeds accelerator memory, and once it fits, a naive input pipeline starves the execution engines. Each step below fixes whatever blocks the next, memory feasibility first and execution evidence second, before any accelerator is added.
Napkin Math 8.10: GPT-2 optimization on one H100
Step 1: Establish the baseline memory footprint.
Table 15: GPT-2 XL on One H100: Memory figures are calculated from the model shape; the busy-time result follows from the tokenization and step-time scenario; run time, energy, cost, and carbon follow from the assumed utilization, the accelerator’s thermal design power, and registry values for facility overhead, electricity price, and grid carbon intensity. The FP32 baseline does not fit, so it has no run to measure.
The trace starts with GPT-2 XL at batch 32 and sequence length 1,024, FP32 tensors throughout, standard attention, and a single-threaded synchronous data loader. Weights, gradients, and Adam moments take 24 GB, and FP32 activations take 574 GB, so the step needs 598 GB, about 7× the H100’s 80 GB (85.9 GB in decimal units). The run fails the machine constraint before throughput matters.
Step 2: Apply mixed precision.
The first intervention targets memory feasibility rather than speed. Mixed precision (notebook 8.6) halves the activations and leaves the static state unchanged, reducing the step to 311 GB. The allocation still exceeds the accelerator.
Step 3: Replace standard attention with FlashAttention.
Never storing the quadratic score matrices removes most of the remaining activations and brings the step to 109.6 GB, still above capacity. With this kernel, the largest batch that stays resident is about 23 sequences, so the configuration overflows somewhere between batch 16 and batch 32.
Step 4: Fit the batch.
Two techniques close the gap. Accumulating two micro-batches of 16 keeps the same arithmetic per update and needs 66.8 GB. Segment checkpointing (notebook 8.8) keeps all 32 sequences resident in 35.5 GB but adds about 33 percent more arithmetic per step. The walkthrough takes accumulation, because the batch it needs fits without recomputation; checkpointing is the choice when a larger resident micro-batch matters more than arithmetic. Runtime measurement must still verify that backward workspaces, output and loss buffers, and allocator overhead fit in the remaining capacity.
Step 5: Read the profile.
Fitting the model resolves capacity but does not guarantee efficient execution. With single-core tokenization, host preparation takes longer than the device’s step (example 8.1), so a serial pipeline keeps the accelerator busy only about 48 percent of the time (equation 7). The diagnostic focus shifts from machine memory capacity (M) to the data pipeline (D) in D·A·M terms: reducing accelerator memory further would not touch the dominant exposed delay.
Step 6: Apply prefetching and parallel preparation.
Eight worker processes, page-locked (pinned) host memory for asynchronous DMA transfers, and a prefetch queue overlap host preparation with accelerator computation, and the parallel preparation interval falls well inside the device’s step. In the ideal overlapped model the accelerator is then busy for the whole step. A busy accelerator is not yet an efficient one; MFU measures how much of that busy time does useful model arithmetic, and re-profiling must establish whether memory bandwidth, arithmetic throughput, or another stage now limits execution.
Result: At the assumed 50 percent utilization, one step takes 0.60 s, the accelerator processes about 55,000 tokens/s, and the run takes about 35 days on one accelerator (about 47 days with segment checkpointing at the same executed rate). Table 15 collects the result.
| Metric | FP32 baseline | Optimized | Technique applied |
|---|---|---|---|
| Static training state | 24 GB | 24 GB | Unchanged at 16 bytes per parameter |
| Activations per step | 574 GB | 42.8 GB | FP16, FlashAttention, two micro-batches of 16 |
| Total memory | 598 GB | 66.8 GB | 9× smaller |
| Fits one H100 | No | Yes | Capacity 80 GB (85.9 GB) |
| Accelerator busy time | N/A | Whole step (ideal) | Prefetching, eight workers |
| Throughput | N/A | 55,000 tokens/s | At the assumed utilization |
| Run time | N/A | 35 days | One accelerator |
| Facility energy | N/A | 661 kWh | Accelerator power \(\times\) PUE 1.12 |
| Electricity cost | N/A | $79 | At $0.12/kWh |
| Carbon | N/A | 0.28 t | Average grid intensity |
Systems insight: The order of interventions follows a dependency, not a preference. Memory feasibility comes first because a configuration that does not fit produces no profile at all. Once it runs, the profile decides what comes next; in this scenario exposed input waits made the data pipeline the target ahead of any kernel tuning, because a faster kernel cannot shorten a step spent waiting for its input. After each intervention, re-profiling determines whether input delivery, memory bandwidth, arithmetic throughput, or another execution cost now limits progress.
This walkthrough demonstrates why training optimization is a sequential diagnostic discipline rather than an arbitrary collection of techniques. Each intervention addresses a constraint established by the memory calculation or the profile. Mixed precision halves activation storage, FlashAttention removes the quadratic attention term, and accumulation brings the batch within capacity without extra arithmetic, a 9× modeled memory reduction in all. Prefetching then addresses exposed input waits once execution begins. The result is a run of about 35 days on one accelerator.
Checkpoint 8.3: From a feasible configuration to a validated run
The walkthrough combines memory calculations with a modeled execution profile. Use the distinction to decide what an actual run must verify.
Single-accelerator optimizations address complementary constraints: mixed precision enables higher-throughput arithmetic, FlashAttention avoids materializing full attention matrices in HBM, accumulation and checkpointing bound activation memory, and asynchronous prefetching hides host input latency. Even fully optimized, however, a run of GPT-2 XL’s size occupies one accelerator for about 35 days, and larger runs are bounded by the arithmetic throughput of an individual chip.
Scaling beyond single-device compute or memory capacity requires distributing computation across multiple accelerators. This architectural transition introduces inter-device communication overhead, collective synchronization barriers, and fault-tolerance constraints that become the primary determinants of scaling efficiency.
Self-Check: Question
For each batch, a training step has three dependent stages in a serial baseline: data preprocessing (\(T_{\text{prep}} = 30\text{ ms}\)), host-to-device transfer (\(T_{\text{xfer}} = 10\text{ ms}\)), and GPU compute (\(T_{\text{comp}} = 50\text{ ms}\)). Different batches can occupy independent resources and overlap with correct handoff. If the team implements steady-state overlapping with prefetching and double buffering, what iteration interval is theoretically possible after fill and before drain?
- \(40\text{ ms}\), because preprocessing and transfer replace compute once overlap is enabled.
- \(50\text{ ms}\), because in ideal steady state the interval is bounded by the slowest overlapped stage rather than the serial sum.
- \(10\text{ ms}\), because all stages run concurrently and the fastest one sets the pace.
- \(90\text{ ms}\), because DMA transfers cannot overlap useful GPU computation.
Explain how FlashAttention computes exact self-attention with substantially lower memory footprint than standard attention, and describe what its backward pass does instead of reading a full stored score matrix from HBM.
Why does the chapter’s conventional FP16 mixed-precision recipe keep FP32 master weights and perform selected reductions in FP32 instead of forcing every part of training into 16-bit precision?
- Tensor Cores cannot execute backpropagation unless gradients are stored in FP64.
- FP16 allocations can lock the accelerator memory bus unless the master weights are moved to host RAM.
- Automatic differentiation requires symbolic derivatives to be represented only in FP32.
- Very small parameter updates can be rounded away when applied directly to FP16 weights, and selected reductions benefit from the wider range or precision of FP32 accumulation.
Gradient accumulation increases the memory footprint on the accelerator linearly with the accumulation factor \(K\) because all \(K\) micro-batches’ intermediate activations must remain in GPU memory simultaneously until the optimizer step.
In FP16 mixed-precision training, the loss is multiplied before backpropagation so the resulting gradients are shifted into a safer numeric range, then divided back down before the optimizer update. This technique is known as loss ____.
A team enables mixed precision on a transformer model and observes compute time drop by 45 percent, but total step time decreases by only 10 percent because the GPU now shows large idle gaps. Explain what likely happened in the system pipeline and what the team should do next.
8.7 Scaling Training Systems
The GPT-2 walkthrough fits the batch-32 step on one H100 and finishes the run in about 35 days. One accelerator cannot finish sooner, and some models cannot fit at all. Spread across the 8 accelerators of one server with perfect scaling, the same run would take about 4.4 days. A 70-billion-parameter model needs about 140 GB for its FP16 weights alone and far more for full training state, which no single accelerator holds, motivating sharding, offload, or multiple devices.
Two micro-batches of 16 fit one H100; batch 32 without checkpointing and a 70B model do not.
When a chosen workload still exceeds one device’s memory or schedule, spreading it across devices provides aggregate memory and compute. Other responses include reducing the model, batch, sequence length, or training scope; offloading state; and parameter-efficient adaptation, which trains only a small set of added parameters on top of a frozen model. Scaling beyond one device begins with multi-GPU configurations inside one machine and may extend across nodes. The major parallelism strategies make different communication trade-offs; a full treatment of distributed-training implementation lies beyond this chapter.
Not all workloads benefit equally from adding GPUs. Adding accelerators helps only until communication and synchronization consume the time saved. Figure 14 charts this scaling decay on a log-log speedup plot up to 256 GPUs, contrasting ideal linear scaling against compute-bound (ResNet), balanced (a large language model (LLM) over NVLink), and communication-bound regimes. The widening divergence between the ideal linear dashed reference and the plateauing modeled curves illustrates the communication overhead that accumulates as synchronization compounds. In this fixed-fraction model, even unlimited parallel compute leaves the non-scaling fraction of the original runtime, so the limiting speedup is its reciprocal, the Amdahl bound of equation 11.1.

The red curve’s widening gap from the dashed ideal is that communication overhead made visible, and shrinking that gap is what the distributed strategies in section 8.7.1 exist to do. Those strategies are older than deep learning: training platforms inherit dense matrix multiplication kernels and tightly synchronized parallel execution from high-performance computing (HPC), and from warehouse-scale computing they inherit cluster orchestration and automated fault recovery for multi-day jobs, the lineage that matters once a run spans many machines.
The same inheritance appears inside one training system as pressure at three scales. At data scale, large corpora require high-throughput input pipelines to avoid accelerator starvation. At model scale, billion-parameter architectures force a choice between replicating weights across devices and partitioning the model. At infrastructure scale, coordinating multiple accelerators introduces synchronization overhead that can dominate training time. The stage interfaces formalized in Stage interface contracts govern what each scale may assume of the others.
8.7.1 Single-node multi-GPU training
Multi-GPU training within a single node introduces the core parallelism strategies. AlexNet16 (Krizhevsky et al. 2012) split its convolutional layers across two GTX 580 GPUs because the 3 GB device memory limit prevented single-chip execution, making cross-GPU connectivity an immediate architectural constraint. Confining multi-accelerator topologies to single-node interconnects (such as PCIe or NVLink) isolates these strategies before cross-rack network fabrics enter.
16 AlexNet (2012): The paper reports 60M parameters and a 3 GB single-GPU ceiling, but does not attribute the limit to one memory component. Its model-parallel design placed roughly half the kernels on each GPU and allowed communication only in selected layers, explicitly trading memory capacity against communication.
Krizhevsky, Alex, Ilya Sutskever, and Geoffrey E. Hinton. 2012. “ImageNet Classification with Deep Convolutional Neural Networks.” Advances in Neural Information Processing Systems (NeurIPS) 25.
The two foundational strategies partition different things. Data parallelism replicates the model and partitions the data, while model parallelism partitions model state or computation. This distinction determines memory requirements, communication patterns, and scaling behavior.
Data parallelism
Data parallelism replicates the entire model on each GPU, with each processing different batches. After computing gradients locally, GPUs synchronize via gradient averaging. Input batches split across parallel GPU workers for independent forward and backward passes, then converge into an AllReduce collective, which sums the gradients from every worker and returns the result to each of them, so every replica applies the identical parameter update (figure 15).
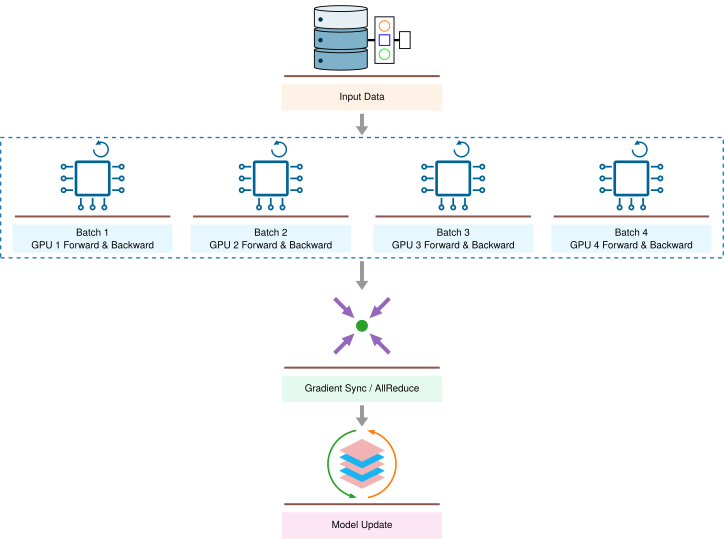
When a model and its optimizer state fit comfortably within single-device memory, data parallelism serves as the primary scaling baseline because local forward and backward kernels run at native memory bandwidth without inter-device synchronization. Gradient aggregation is the principal recurring communication cost; some implementations also synchronize buffers or other state. Historically, frameworks supported multi-GPU execution within a single node using multithreaded wrappers like PyTorch’s DataParallel (DP). However, this single-process design suffers from two severe architectural bottlenecks: the Python runtime remains throttled by the Global Interpreter Lock (GIL), and a primary coordinator (GPU 0) must sequentially scatter mini-batches and gather outputs over PCIe, saturating host-device interconnect bandwidth and creating severe compute and memory imbalances. Modern systems commonly use PyTorch’s DistributedDataParallel (DDP); TensorFlow’s MirroredStrategy also provides replicated training but has a different execution model. With an independent Python process per accelerator, DDP avoids cross-replica contention for one Python GIL; each process maintains its own model replica and local optimizer, relying on decentralized collective AllReduce operations that bucket gradients into contiguous buffers and overlap synchronization directly with backward-pass computation.
Synchronizing gradients is the step that data parallelism adds, and for GPT-2 XL inside one server its cost can be derived directly. Each replica holds FP16 gradients of 3 GB, and every replica must end the step with their sum. Ring AllReduce (Patarasuk and Yuan 2009) arranges the \(\AcceleratorCount\) accelerators in a logical ring and splits the gradient into \(\AcceleratorCount\) chunks. In a reduce-scatter phase, each accelerator passes a chunk to its neighbor \(\AcceleratorCount - 1\) times, adding the chunk it receives to its own, until each holds one fully summed chunk; in an all-gather phase, the summed chunks circulate \(\AcceleratorCount - 1\) more times until every accelerator holds all of them. Each accelerator therefore sends \(2(\AcceleratorCount-1)/\AcceleratorCount\) of the gradient bytes \(\DataVolume\), nearly twice the gradient however large the ring, and over a link of bandwidth \(\Bandwidth\) the bandwidth term of the synchronization time is
Patarasuk, Pitch, and Xin Yuan. 2009. “Bandwidth Optimal All-Reduce Algorithms for Clusters of Workstations.” Journal of Parallel and Distributed Computing 69 (2): 117–24. https://doi.org/10.1016/j.jpdc.2008.09.002.
\[ \CommunicationTime \approx \frac{2(\AcceleratorCount-1)}{\AcceleratorCount} \cdot \frac{\DataVolume}{\Bandwidth} \tag{12}\]
For 8 H100s the factor is 1.75, so each accelerator sends 5.25 GB per step, which takes about 12 ms at 450 GB/s per direction over NVLink. Against a 596 ms step when each replica processes the full batch of 32 sequences, synchronization is about 2 percent of the step even without overlap. Splitting a fixed batch of 32 eight ways shrinks each replica’s compute to 75 ms while the gradient bytes stay the same, raising the unhidden share to about 14 percent. Data parallelism inside one server is cheap for GPT-2 XL as long as each replica keeps enough work to amortize a synchronization whose size depends only on the parameter count; frameworks hide most of what remains by launching bucketed AllReduce calls while the backward pass is still computing earlier layers’ gradients.
Unsharded data parallelism has a hard constraint. Every accelerator holds a complete model replica and its full training state, 16 bytes per parameter in the mixed-precision Adam recipe, or 24 GB for GPT-2 XL on each of the 8 accelerators. The Zero Redundancy Optimizer (ZeRO) (Rajbhandari et al. 2020) removes that redundancy by sharding training state across the data-parallel replicas in three stages. ZeRO-1 shards the 12 bytes of FP32 master weights and Adam moments, leaving 8.2 GB per accelerator for GPT-2 XL; ZeRO-2 also shards the gradients, leaving 5.6 GB; and ZeRO-3, which fully sharded data parallelism (FSDP) (Zhao et al. 2023) implements, also shards the FP16 parameters, leaving 3 GB. The same arithmetic brings the Llama 3 8B full fine-tune that overflowed one accelerator in section 8.3.3.3 down to about 16 GB of static state per accelerator. The memory comes back as communication. ZeRO-1 and ZeRO-2 keep the data-parallel volume, because a reduce-scatter of gradients followed by an all-gather of updated parameters moves the same bytes as one AllReduce, while ZeRO-3 must also gather each layer’s parameters before its forward and backward computation, about 1.5 times the data-parallel volume (Rajbhandari et al. 2020). A model that still exceeds local memory after sharding requires pipeline or tensor partitioning.
Rajbhandari, Samyam, Jeff Rasley, Olatunji Ruwase, and Yuxiong He. 2020. “ZeRO: Memory Optimizations Toward Training Trillion Parameter Models.” SC20: International Conference for High Performance Computing, Networking, Storage and Analysis, 1–16. https://doi.org/10.1109/sc41405.2020.00024.
Zhao, Yanli, Andrew Gu, Rohan Varma, Liang Luo, Chien-Chin Huang, Min Xu, Less Wright, et al. 2023. “PyTorch FSDP: Experiences on Scaling Fully Sharded Data Parallel.” Proceedings of the VLDB Endowment 16 (12): 3848–60. https://doi.org/10.14778/3611540.3611569.
Model parallelism
Model parallelism partitions the model itself across GPUs, which becomes necessary when the model exceeds single-GPU memory. AlexNet adopted an early form of this strategy: selected convolutional layers split their kernels and channels across two GPUs, with communication at selected connections. Figure 16 illustrates a different, layerwise partition of the same broader model-parallel idea: Device 1 through Device 3 sequentially process layers 1–16, 17–32, and 33–48, streaming boundary activations forward during the forward pass and propagating loss gradients in reverse during backpropagation.
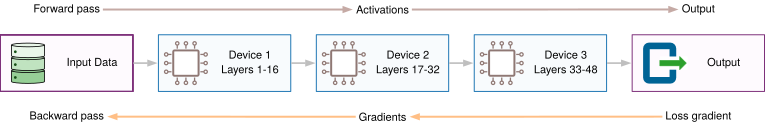
Systems Perspective 8.4: Data vs. model parallelism
When a selected workload is partitioned across \(\AcceleratorCount\) devices, the split may divide examples, model state, layers, or tensor operations. For a model with parameters \(\Parameters\) and batch size \(\BatchSize\), data and model parallelism provide two starting points.
Data parallelism (split the batch): For a fixed global batch, each of \(\AcceleratorCount\) workers processes about \(1/\AcceleratorCount\) of the examples, but every worker holds a model replica and ordinarily its associated training state. Dense gradient communication is proportional to \(\Parameters\) per update. Scaling departs from the ideal as local batches shrink or synchronization and input costs grow.
Model parallelism (split model computation): Each accelerator stores and computes a portion of the model. An even partition may approach \(\Parameters/\AcceleratorCount\) parameters per worker, but embeddings, buffers, imbalance, and replicated state alter that estimate. Communication depends on the partition: layerwise pipeline parallelism exchanges activations at stage boundaries, while tensor parallelism performs collectives within partitioned layers.
Systems insight: Data parallelism is the simplest candidate when the complete training state fits per worker and more throughput is needed. Model-state, pipeline, or tensor partitioning becomes necessary when it does not, often in combination with data parallelism.
When a model exceeds the memory capacity of a single accelerator, its depth can be partitioned across sequential devices. Figure 17 stages this pipeline allocation across a four-accelerator execution chain, grouping 24 transformer blocks into contiguous six-block partitions (Blocks 1–6 through 19–24) that exchange boundary activations over the interconnect.
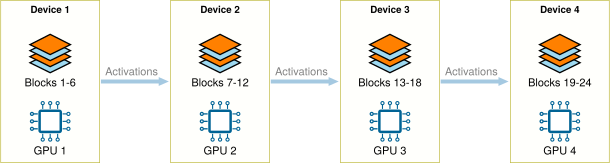
The main bottleneck in naive layer-wise partitioning is device serialization. Because layer evaluation is strictly sequential, Device 1 computes layers 1–6 while Devices 2–4 sit idle waiting for forward activations. During the backward pass, the dependency reverses: Device 4 computes first while upstream devices wait for returning gradients. This idle duration constitutes the pipeline bubble, which caps theoretical hardware utilization at \(1/\AcceleratorCount\) under naive sequential execution. It differs from the accelerator bubbles of the staged training pipeline, which arise when one device’s data-loading, transfer, and compute stages run at mismatched rates; a pipeline bubble arises even with perfectly fed devices, because each device must wait for another device’s layers. Mitigating this idle time requires either pipelining micro-batches across stages or partitioning tensor dimensions within layers so that all devices compute simultaneously.
Both remedies fit inside one node. Pipeline parallelism splits each batch into micro-batches and streams them through the stages, so Device 2 works on the first micro-batch while Device 1 starts the second, and the bubble shrinks to the time spent filling and draining the pipeline at the start and end of each batch (Huang et al. 2019; Narayanan et al. 2019). Tensor parallelism instead splits the matrix operations of each layer across devices, so every device works on every layer at once (Shoeybi et al. 2019). The price is communication inside every layer, because the partial results must be combined before the next layer can begin. That frequency is why tensor parallelism is normally kept within one node, on its fastest links.
Huang, Y., Y. Cheng, A. Bapna, O. Firat, D. Chen, M. X. Chen, H. Lee, et al. 2019. “GPipe: Efficient Training of Giant Neural Networks Using Pipeline Parallelism.” Advances in Neural Information Processing Systems (NeurIPS) 32: 103–12.
Narayanan, Deepak, Aaron Harlap, Amar Phanishayee, Vivek Seshadri, Nikhil R. Devanur, Gregory R. Ganger, Phillip B. Gibbons, and Matei Zaharia. 2019. “PipeDream: Generalized Pipeline Parallelism for DNN Training.” Proceedings of the 27th ACM Symposium on Operating Systems Principles, 1–15. https://doi.org/10.1145/3341301.3359646.
Shoeybi, Mohammad, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper, and Bryan Catanzaro. 2019. “Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism.” arXiv Preprint arXiv:1909.08053.
Within a node, GPUs may communicate through high-bandwidth links such as NVLink (up to 900 GB/s aggregate bidirectional bandwidth for the represented H100 configuration). Effective collective bandwidth depends on topology and contention and is lower than a raw aggregate link specification. Data parallelism communicates gradients via collective AllReduce operations, while layerwise model parallelism communicates activations point-to-point at partition boundaries. Data parallelism suits models that fit on one accelerator, whereas larger models require sharded training state or a split model.
8.7.2 Scaling beyond a single node
One machine is this book’s scope, but its boundary is worth knowing. When a model’s parameter footprint, optimizer state, or training duration exceeds the capacity of an 8-accelerator node, distributed training extends across machines. The strategies of this section still apply, but three things change once training leaves the node. First, bandwidth drops sharply because machines are joined by a network such as Ethernet or InfiniBand rather than NVLink, reducing link throughput by one to two orders of magnitude so that gradient synchronization that overlapped with the backward pass inside a node can come to dominate each step. Second, placement must match each strategy to a tier of the network: the frequent intra-layer communication of tensor parallelism stays inside the node, whereas the once-per-step gradient exchange of data parallelism can cross slower inter-node links. Third, hardware failure becomes a routine operational event across thousands of accelerators during a multi-day run, making automated checkpointing and restart an essential part of the training design. Each of these is a subject of its own in large-scale distributed training; within one machine the same principles appear in their simplest form, which is why the single-node case comes first.
↪ Empirical protocols for quantifying multi-accelerator scaling efficiency and communication loss are developed in Scalability and parallelism.
8.7.3 When to scale: The physical ceiling
Even a perfectly tuned single accelerator hits hard physical walls: a 70-billion-parameter model overflows 80 GB of HBM on weights alone, and a \(10^{24}\)-FLOP pretraining run at \(10^{15}\) sustained FLOP/s would take 32 years on one chip. Until a run meets one of those walls, however, distributing state across devices adds communication traffic, synchronization barriers, and new failure modes that can slow a job that would have fit locally. Single-device optimizations therefore come first to separate solvable local bottlenecks from genuine capacity or schedule limits: lower-precision execution (section 8.6.3) when numerical stability permits, gradient accumulation (section 8.6.5) to build target batch sizes without activation blowup, activation checkpointing (section 8.6.5.1) to trade redundant forward compute for memory headroom, and overlapped data prefetching (section 8.6.2) when host ingestion limits the critical path.
Table 16 structures this progression as a resource lookup keyed to measured hardware bottlenecks rather than arbitrary parameter thresholds.
| Observed constraint | Candidate approach | Rationale |
|---|---|---|
| Training state fits one device and time is acceptable | Single GPU | Minimizes communication and operational complexity |
| State or throughput exceeds one device but fits one node | Single multi-GPU node | Uses fast local interconnects before crossing the network |
| Required state or schedule exceeds one node | Multi-node cluster | Adds aggregate memory or compute at a communication cost |
| Input service rate is below accelerator demand | Parallel or distributed input pipeline | Adds input throughput where profiling shows it is needed |
A measured single-device baseline guides scaling decisions, while a decisive capacity or compute-time lower bound can establish the need for additional resources before every local optimization is attempted. Once local tuning is exhausted or ruled out by lower bounds, resource expansion must match the specific physical limit that has been reached. Memory exhaustion occurs when model weights, gradients, optimizer states, and activations exceed the VRAM of a single GPU: a 70-billion-parameter model requires about 140 GB in FP16 for weights alone, exceeding the reference H100’s capacity and leaving little or no headroom on higher-capacity variants once training state is included. Training wall-clock time binds when the estimated duration on one device exceeds the project’s deadline, as in a \(10^{24}\)-FLOP workload that would take roughly 32 years at \(10^{15}\) FLOP/s sustained. Input throughput binds when the host pipeline cannot sustain the aggregate accelerator consumption rate, which calls for more input-service capacity rather than more training accelerators; dataset size alone does not determine this limit because reuse, compression, locality, transformation cost, and storage bandwidth govern delivery rate.
Data parallelism also meets a statistical ceiling. Each added replica enlarges the global batch, and beyond the critical batch size met in the discussion of batch size and parameter updates (section 8.4.4.1), larger batches stop reducing the number of updates needed to reach a target loss (McCandlish et al. 2018). Past that point, more replicas raise throughput in samples per second without shortening the time to target quality, so a scaling decision needs both the hardware ceiling and the batch at which the recipe’s convergence flattens.
McCandlish, Sam, Jared Kaplan, Dario Amodei, and OpenAI Dota Team. 2018. “An Empirical Model of Large-Batch Training.” arXiv Preprint arXiv:1812.06162, ahead of print. https://doi.org/10.48550/arXiv.1812.06162.
These three limits are technical, but scaling carries a cost beyond complexity and capacity. Adding devices amplifies the energy consumption and environmental impact of training, so efficiency optimization becomes an environmental concern as much as a performance one.
Napkin Math 8.11: The carbon footprint of training
Context: Training large models requires substantial energy and compute. The physical ceiling appears once training time is converted to energy, cluster power multiplied by training time (\(\TotalEnergy = \ClusterPower\cdot \TrainingTime\)), quantifying environmental scale:
- Workload: Training a 7 billion-parameter model for 1 trillion tokens.
- Compute: \(\Operations\approx\) \(4.2 \times 10^{22}\).
- Efficiency: 494 TFLOP/s sustained on the H100 (700 W thermal design power).
- Execution time: \(\TrainingTime\approx\) 0.96 days on 1,024 GPUs.
- Energy footprint: \(\TotalEnergy = \ClusterPower\cdot \TrainingTime= (\AcceleratorCount \cdot \DevicePower + \ClusterNodeCount \cdot \HostPower) \cdot \TrainingTime\) evaluates to (1,024 GPUs \(\times\) 700 W + 128 hosts \(\times\) 200 W) \(\times\) 23 hours \(\approx\) 17,104.8 kWh.
Impact: Under the assumed constant GPU and host-CPU power, this modeled subtotal equals 19.0 months of average household electricity use. GPU thermal design power is a scenario input rather than measured draw; memory, storage, network equipment, and facility overhead are not separately included, so the subtotal is not total facility energy.
Systems lesson: Doubling hardware utilization \(\EfficiencyHw\) at constant cluster power \(\ClusterPower\) halves execution time \(\TrainingTime\) and total energy \(\TotalEnergy\). Under average grid carbon intensity, doubling efficiency saves ~8,552.4 kWh of electricity and avoids 3.7 t of emissions. Environmental audits must measure \(\TotalEnergy = \int \ClusterPower(\TimeInstant)\,d\TimeInstant\) rather than relying on GPU utilization metrics alone.
Scaling changes the binding constraint rather than removing it. Data parallelism adds throughput, sharded and model parallelism add memory capacity, pipeline parallelism recovers utilization lost to idle stages, and tensor parallelism makes layers larger than one device feasible, but each adds communication and coordination cost. The implementation details of multi-node distributed training, including collective communication primitives, fault tolerance mechanisms, and elastic scheduling, build directly on the single-machine principles covered throughout this chapter and are treated in depth in advanced distributed systems texts.
Checkpoint 8.4: Scaling decisions
Scaling trades compute bottlenecks for communication bottlenecks.
Self-Check: Question
A team trains a 1.5-billion-parameter model that already fits on one 80 GB GPU with batch size 16 and its Adam training state, but one epoch still takes 12 days. The team has an 8-GPU node available. Which strategy is the best first baseline, and why?
- Tensor parallelism, because splitting every weight matrix across the 8 GPUs is always the fastest way to improve training throughput.
- Pipeline parallelism, because dividing layers across devices is the default first step whenever a model is a transformer.
- Data parallelism such as DDP, because the model already fits per device and replication avoids unnecessary pipeline bubbles or intra-layer communication as the initial throughput baseline.
- Full parameter sharding first, because any multi-GPU run should avoid keeping complete replicas even when memory is sufficient.
In distributed data parallel training with \(N\) GPUs and a model with \(P\) parameters whose gradients use \(B_{\text{bytes}}\) bytes each, what is the number of bytes sent by each GPU during a Ring AllReduce?
- \(2 \times \frac{N-1}{N} \times P \times B_{\text{bytes}}\), which approaches \(2 P B_{\text{bytes}}\) as \(N\) grows.
- \(N \times P \times B_{\text{bytes}}\), because each GPU must broadcast the full gradient to every other GPU.
- \(\frac{P \times B_{\text{bytes}}}{N^2}\), because the ring divides both the model and the communication quadratically.
- Zero, because GPU replicas synchronize through shared CPU memory rather than explicit data movement.
Explain what communication overhead is in distributed training, and analyze why adding more GPUs can lead to diminishing throughput returns.
In pipeline model parallelism, partitioning a network linearly across \(K\) stages without micro-batching (naive pipeline parallelism) achieves 100 percent GPU utilization because downstream devices can compute backward gradients while upstream devices run forward passes.
Arrange the following engineering steps in the chapter’s preferred order for deciding whether to scale beyond one device, assuming the initial bounds do not already prove that single-device training is infeasible: (1) Re-evaluate whether memory or time limits still justify scaling. (2) Add distributed parallelism or sharding if the remaining limit still requires it. (3) Establish a single-device baseline and quantify the current bottleneck. (4) Apply relevant local optimizations such as mixed precision, prefetching, checkpointing, or accumulation.
8.8 Fallacies and Pitfalls
The approach developed throughout this chapter quantifies costs through the iron law, diagnoses bottlenecks through profiling, applies targeted optimizations, and scales only when necessary. The following fallacies and pitfalls are the errors that most often waste training compute.
Fallacy: Larger models always yield better performance.
Teams sometimes treat scale as a monotonic lever: if a 7B-parameter model works well, a 20B-parameter model must work better. A 20B model requires approximately 320 GB of nonactivation training state in the stated mixed-precision Adam recipe (40 GB FP16 parameters + 40 GB FP16 gradients + 80 GB FP32 master weights + 160 GB Adam states). Whether it outperforms a 7B model depends on data quantity and quality, training compute, optimization, and evaluation, not on parameter count alone.
Pitfall: Assuming distributed training automatically accelerates development.
More accelerators do not guarantee faster training because communication, smaller local batches, input limits, and imbalance can consume the gain. The chapter’s own derivation shows the mechanism: splitting GPT-2 XL’s batch of 32 across eight H100s shrinks each replica’s compute while the gradient bytes stay fixed, so unoverlapped synchronization grows to about 14 percent of the step. In a hypothetical 8 GPUs scenario, the same effect lets synchronization occupy 30–50 percent of step time, so speedup reaches only 4–6× rather than the ideal 8×. The decision requires measured end-to-end time and scaling efficiency.
Fallacy: Hyperparameters transfer directly from small-scale experiments to large-scale training.
A learning rate that works at batch size 512 may not transfer to batch size 4,096. The linear scaling rule (Goyal et al. 2017) would increase the rate from 0.1 to 0.8 for this eightfold change, often with warmup, but it is an empirical recipe rather than a requirement or convergence guarantee. Large-scale runs must validate the learning rate, schedule, optimizer state, and effective batch together.
Goyal, Priya, Piotr Dollár, Ross Girshick, Pieter Noordhuis, Lukasz Wesolowski, Aapo Kyrola, Andrew Tulloch, Yangqing Jia, and Kaiming He. 2017. “Accurate, Large Minibatch SGD: Training ImageNet in 1 Hour.” arXiv Preprint arXiv:1706.02677 abs/1706.02677.
Pitfall: Treating mixed precision training as a simple toggle without validation.
The H100’s peak ratios bound the gain at 2× over the TF32 Tensor Core path and 15× over FP32 scalar units, but elementwise kernels, optimizer updates, and input waits do not speed up with the matrix units, so the measured gain is smaller. FP16 commonly requires loss scaling (Micikevicius et al. 2018), while BF16 usually does not (Wang and Kanwar 2019; Kalamkar et al. 2019) (section 8.6.3 compares the two formats). Either recipe can change numerical behavior, so throughput and convergence must be validated on the target workload.
Kalamkar, Dhiraj, Dheevatsa Mudigere, Naveen Mellempudi, Dipankar Das, Kunal Banerjee, Sasikanth Avancha, Dharma Teja Vooturi, et al. 2019. A Study of BFLOAT16 for Deep Learning Training.
Fallacy: Memory and computation can be optimized independently.
Memory and compute are coupled: in this illustrative profile, accelerator utilization drops from 90 percent at batch 256 to 60–70 percent at batch 16. Gradient accumulation (effective batch 512, physical batch 64) shows a 5-percentage-point utilization gap for 8× activation-memory reduction. Tuning these parameters independently can therefore extend training time materially, because the utilization lost at the smaller physical batch applies to every step of the run (section 8.6.5 develops this trade-off).
Pitfall: Budgeting training memory as if it only contains model weights.
Sizing training memory from weights alone omits gradients, optimizer state, master weights when used, activations, temporary workspaces, and allocator overhead. In the chapter’s mixed-precision Adam recipe, the static state alone is 16 bytes per parameter before activations. Other optimizers and sharding strategies change this budget. Activation memory then depends on batch size, sequence length, architecture, kernels, and checkpointing; no universal multiple of the weight footprint applies.
Fallacy: The accelerator is always the training bottleneck.
Data loading often creates idle time, yet teams optimize computation first. On the reference H100, ResNet-50’s demand outruns the host cores available to it and leaves the accelerator busy only about 52 percent of the time, and GPT-2 XL with single-core tokenization is busy only about 48 percent; a faster accelerator fixes neither, while parallel preparation and overlap (section 8.6.2) address both. Profile before assuming the GPU is the bottleneck.
Pitfall: Optimizing kernels before profiling the input pipeline.
Kernel-level tuning is attractive because accelerator utilization is easy to inspect, but a starved accelerator can look like an inefficient one. Before changing precision, rewriting kernels, or adding accelerators, measure dataloader throughput, host preprocessing time, and storage wait. If the accelerator is waiting for batches, feeding it reliably beats faster kernels.
Self-Check: Question
A team scales a dense model from 7 billion to 20 billion parameters while keeping the same training-token budget, precision recipe, and optimizer structure. Under the chapter’s fallacies discussion, what is the most defensible conclusion?
- Validation accuracy must improve in proportion to parameter count because the larger model can represent more functions.
- The run will necessarily move to CPU execution because 20B parameters cannot be trained on accelerators.
- The larger model guarantees worse accuracy because fixed-token training always causes catastrophic interference at higher parameter counts.
- The training-state and compute budgets rise substantially under the same dense-model accounting, but model quality is not guaranteed to improve because it still depends on data, optimization, and evaluation.
Explain why directly transferring hyperparameters such as learning rate and weight decay from a batch-size 512 baseline to a batch-size 4,096 distributed run can cause training to underperform, even when raw GPU busy time stays above 90 percent.
Which engineering mistake exemplifies “pipeline neglect” as described in the chapter’s pitfalls?
- Using BF16 mixed precision instead of FP16 on NVIDIA Ampere GPUs.
- Spending weeks hand-tuning custom CUDA attention kernels to achieve 95% peak arithmetic throughput, only to discover in production that the GPU sits idle 50% of the time waiting for single-threaded Python CPU tokenization.
- Setting
pin_memory=Trueandnum_workers=8in a PyTorch DataLoader. - Checkpointing activations every \(\sqrt{N_L}\) layers to reduce peak memory.
A team proposes moving a single-GPU training job to a 16-GPU cluster to achieve a \(16\times\) reduction in development cycle time. Explain two reasons why distributed training rarely delivers a linear \(16\times\) improvement in developer velocity.
8.9 Summary
Training cost is governed by three quantities that this chapter first kept separate and then joined. The training-time law, \(\TrainingTime= \Operations/(\PeakRate \times \EfficiencyHw)\), sets the time a run takes, and device power multiplied by that time sets its energy. The four-term memory budget decides what fits, and in a standard mixed-precision Adam recipe the static state alone reaches 8× the FP16 weights before a single activation is stored. The min-of-three pipeline model decides whether the accelerator is fed at all. GPT-2 XL tied the three together. Its \(6\Parameters\DatasetSize\) operation count set a run of about 35 days on one H100, its weights, optimizer state, and activations overflowed that accelerator at batch 32 before any arithmetic began, and its single-threaded data loader could starve the device once the step fit.
Every intervention in the chapter relieves one term and burdens another, which is the conservation of complexity at work. Mixed precision raises \(\PeakRate\) and shrinks activation memory and traffic, but it leaves the static state unchanged and requires loss scaling or a wider-exponent format. Checkpointing trades extra forward arithmetic for activation memory, accumulation trades update frequency for batch size, prefetching hides input time at the cost of host memory, and FlashAttention removes quadratic HBM traffic by recomputing tiles. Scaling to more devices adds aggregate memory and compute but turns gradient synchronization into a new term on the critical path. The profile, not the menu of techniques, decides which trade is worth making.
The same pressures shaped the hardware. Dense matrix patterns drove Tensor Cores, frameworks exposed them through mixed-precision APIs, and reduced-precision training pushed later accelerators toward BF16 and FP8. The bitter lesson explains why this matters. If capability grows with the computation a general method can absorb, every point of utilization lost to stalls is capability forgone at a fixed budget.
The counting rules developed across the chapter fit on one page (table 17). Together they estimate, before any profiler runs, how long a run takes, what it costs in energy, whether its step fits in memory, and which stage of its pipeline binds.
| Quantity | Formula | Where derived |
|---|---|---|
| Training time | \(\TrainingTime= \frac{\Operations}{\PeakRate \times \EfficiencyHw}\) | equation 1 |
| Training work | \(\Operations \approx 6\Parameters\DatasetSize\) FLOPs (2 forward, 4 backward per parameter per token) | section 8.1.1 |
| Training energy | \(\TotalEnergy = \DevicePower \times \TrainingTime\) at constant power | section 8.2 |
| Training memory | \(\TotalMemoryFootprint = \WeightMemory + \GradientMemory + \OptimizerStateMemory + \ActivationMemory\); 16 bytes per parameter of static state in mixed-precision Adam | equation 4 |
| Activation memory | \(\ActivationMemory = \BatchSize \times \sum_{\LayerIndex=1}^{\LayerCount} \left(\LayerIntermediateStateMemory + \ActivationMemory^{(\LayerIndex)}\right)\) | equation 3 |
| Pipeline throughput | \(\TrainingThroughput=\min\left(\PreprocessingThroughput, \frac{\HostTransferBandwidth}{\BatchDataVolume}, \frac{\SustainedComputeRate}{\BatchOperations}\right)\) | equation 6 |
| Model FLOPs utilization | \(\ModelFlopsUtilization = \ModelStepOperations/ (\PeakRate \cdot \TrainingStepTime)\) | section 8.5 |
| Checkpointed activations | \(\ActivationCheckpointCount\times \ActivationMemory^{(\ell)} + (\LayerCount/\ActivationCheckpointCount)\times \ActivationMemory^{(\ell)}\), minimized at \(\ActivationCheckpointCount= \sqrt{\LayerCount}\) | table 13 |
| Effective batch | \(\BatchSize= \AccumulationStepCount\times \MicrobatchSize\) per device | equation 10 |
| Ring AllReduce time | \(\CommunicationTime \approx \frac{2(\AcceleratorCount-1)}{\AcceleratorCount} \cdot \frac{\DataVolume}{\Bandwidth}\) | equation 12 |
Compute and memory deserve equal weight in that estimate, because the step that fits is not always the step that is cheapest to compute (table 18).
| Workload (step) | FLOPs per step | Static state | Activations | Fits one H100 |
|---|---|---|---|---|
| GPT-2 XL, 32 sequences of 1,024 tokens | 295 TFLOP | 24 GB | 287 GB stored; 85.6 GB with FlashAttention | With FlashAttention and two micro-batches of 16 |
| ResNet-50, 32 images | 787 GFLOP | 0.4 GB | About 12 GB (FP32 scenario) | Yes; the binding term is the input feed |
| Llama 3 8B fine-tuning, 4 sequences of 2,048 tokens | 395 TFLOP | 128 GB (full) | 36.5 GB | Only with adapters (53 GB) |
Key Takeaways: Why training costs millions
- Training cost is an iron-law budget: \(\TrainingTime= \frac{\Operations}{\PeakRate \times \EfficiencyHw}\) makes every optimization accountable: reduce work, raise effective throughput, or improve utilization. A change that misses the dominant term only moves cost around the training loop.
- Memory determines whether a step fits: Standard mixed-precision Adam holds 16 bytes per parameter, 8× the FP16 inference weights, before activations. Optimizer state and batch-dependent activations, not weights alone, determine whether training fits.
- Profiles choose the remedy: Profile, diagnose, fix, and re-profile. Compute-bound jobs need better arithmetic or algorithms; memory-bound jobs need less state or traffic; data- and communication-bound jobs need pipeline or parallelism changes.
- Precision and IO-aware kernels shift bottlenecks: FP16 with FP32 accumulation can improve throughput and shrink activation memory (the static state is unchanged), while FlashAttention avoids materializing the full \(\SequenceLength{\times}\SequenceLength\) matrix in HBM; realized gains depend on workload and hardware.
- Checkpointing trades recomputation for memory: The segment schedule counts retained boundaries and one live reconstructed segment, reducing GPT-2 XL’s batch-32 activations from 85.6 GB to 11.5 GB for about one-third more arithmetic. Use it when memory, not compute, binds.
- Composed optimizations can postpone scale-out: Mixed precision, FlashAttention, and gradient accumulation turn GPT-2 XL’s 598 GB batch-32 step into a modeled 66.8 GB that fits one H100, for a run of about 35 days. Use relevant local levers before accepting distributed communication and operational overhead.
Training is where the iron law becomes a daily instrument. A profile read against the law names the dominant term, and the engineering task is to apply the least costly intervention that changes it before reaching for more hardware. The analysis took the model and training corpus as given, while changing how the system executed their work, including the extra arithmetic needed for recomputation. A further lever is which examples enter that workload in the first place.
What’s Next: From training to data selection
Training produces learned parameters by spending compute on every example. Once the training loop is efficient, the next question is whether every example earns that cost. Repeated or low-information samples consume the same forward pass, backward pass, optimizer update, and communication as examples that add coverage or correct a weakness.
Data Selection therefore turns upstream from execution to workload composition, and in doing so opens the book’s optimization sequence, which asks whether work is necessary before asking how to simplify or accelerate it. It starts from a supply imbalance. Accelerator fleets can grow usable compute faster than the stock of high-quality data, so extracting more learning from each example begins to matter more than collecting more examples. Its measure is the information-compute ratio, the learning an example returns per unit of training compute, and redundancy, representativeness, uncertainty, and class coverage all enter through it. A useful subset must reduce work without erasing rare cases or shifting the effective training distribution. When that balance holds, a carefully selected subset can approach full-dataset accuracy while lowering the cost of every epoch and making additional experiments affordable. The optimization target is no longer only how efficiently the system processes an example, but which examples the system should process at all.
8.10 Self-Check Answers
Self-Check: Answer
A 7-billion-parameter model uses 14 GB of FP16 weights for inference and fits comfortably on a single 40 GB accelerator. Switching the same model to standard mixed-precision Adam training causes immediate out-of-memory failures even before activations are accounted for. Using the mixed-precision Adam accounting that the section previews, which factor is most directly responsible?
- Adam internally re-runs the forward and backward passes, so the same weights must be stored several extra times during each step.
- Adam adds 14 GB of FP16 gradients, 28 GB of FP32 master weights, and 56 GB of FP32 first- and second-moment state, pushing the static training state to about 112 GB before activations.
- Adam requires the full training corpus to be cached in accelerator memory so batches can be reused across optimizer steps.
- Adam forces all model tensors into FP64 during backpropagation, which multiplies the weight footprint beyond device capacity.
Answer: The correct answer is B. In the section’s standard mixed-precision Adam recipe, training state includes 14 GB of FP16 weights, 14 GB of FP16 gradients, 28 GB of FP32 master weights, and 56 GB of FP32 moment state, for about 112 GB before activations. The idea that Adam re-runs model passes confuses optimizer state with the forward/backward computation, and dataset caching is part of the input pipeline rather than resident model-training state on the accelerator.
Learning Objective: Calculate the static mixed-precision Adam training-state footprint from weights, gradients, master weights, and optimizer state.
True or False: Sudden NaN loss spikes during mixed-precision training are usually the same failure mode as an out-of-memory error, because both come from the GPU running out of memory during backpropagation.
Answer: False. An out-of-memory failure is a capacity problem that triggers an allocation error, while NaNs indicate numerical instability somewhere in the training computation. Mixed precision can contribute to numerical issues, but a NaN spike is not the same diagnosis as memory exhaustion.
Learning Objective: Distinguish memory-capacity failures from numerical-instability failures in mixed-precision training.
In machine learning frameworks, the technique of discarding selected intermediate forward activations and recomputing them on demand during the backward pass to reduce peak memory is known as activation ____ (or gradient checkpointing).
Answer: The correct answer is rematerialization (or recomputation). Rematerialization allows training systems to trade additional computation for a substantially reduced activation memory footprint.
Learning Objective: Identify the systems term for trading backward recomputation against forward activation storage.
Self-Check: Answer
A training run has confirmed that input delivery and communication are off the critical path. The model FLOP count and the peak-throughput convention are being held fixed, yet profiling still reports only 38 percent effective end-to-end utilization relative to the stated peak. Under the training-time law \(T_{\text{train}} = \frac{O}{R_{\text{peak}} \times \eta_{\text{hw}}}\), which lever is the most direct target for the next round of profiling?
- Hardware utilization \(\eta_{\text{hw}}\), because with \(O\) and the relevant \(R_{\text{peak}}\) convention fixed, the remaining gap points to how efficiently kernels are being executed end to end.
- Peak throughput \(R_{\text{peak}}\), because low effective end-to-end utilization relative to the stated peak automatically means the hardware peak specification is too small for the workload.
- Total operations \(O\), because once data and communication are hidden, utilization is no longer relevant to training time.
- Dataset size, because shrinking the number of tokens directly raises effective end-to-end utilization relative to the stated peak even when execution efficiency is unchanged.
Answer: The correct answer is A. In the current equation, \(O\) and the chosen \(R_{\text{peak}}\) convention are fixed, so 38 percent effective end-to-end utilization relative to the stated peak points to the effective utilization term \(\eta_{\text{hw}}\). That does not prove one unique cause, but it does justify profiling device execution for stalls, inefficient kernels, launch overhead, or other losses inside the end-to-end throughput term. Reducing \(O\) may shorten total training time, but it answers a different question than why this execution reaches only 38 percent of the chosen peak.
Learning Objective: Apply the training-time law to identify utilization as the immediate profiling target when workload size and peak-throughput convention are fixed.
When a team transitions a model from FP32 training to mixed-precision (FP16/BF16) on Tensor Core accelerators without changing the model architecture, batch size, or dataset, which term of the training-time law (\(T_{\text{train}} = \frac{O}{R_{\text{peak}} \times \eta_{\text{hw}}}\)) is most directly improved?
- Total operations \(O\), because lower numerical precision halves the number of multiplications required in each matrix multiplication.
- Hardware utilization \(\eta_{\text{hw}}\), because mixed precision automatically eliminates all GPU pipeline bubbles and CPU data stalls.
- Peak throughput \(R_{\text{peak}}\), because Tensor Cores provide a substantially higher theoretical FLOP/s ceiling for reduced-precision matrix operations compared to standard FP32 execution units.
- Data volume \(D_{\text{tokens}}\), because lower precision requires fewer training tokens for the loss to converge.
Answer: The correct answer is C. The chapter’s optimization matching table assigns mixed precision (FP16/BF16) to peak throughput (\(R_{\text{peak}}\)). Tensor Cores execute reduced-precision matrix multiplications at several times the theoretical FLOP/s ceiling of FP32 ALUs. The claim regarding total operations \(O\) is incorrect because the algorithmic graph and number of multiply-accumulate operations remain identical. The utilization claim is incorrect because \(\eta_{\text{hw}}\) measures efficiency relative to the available peak, and precision changes do not inherently eliminate data loader bubbles. The data volume claim is false because precision does not reduce sample requirements.
Learning Objective: Classify mixed-precision training by its direct target term (\(R_{\text{peak}}\)) in the training-time law.
Explain the scope conditions under which the simplified training-time law \(T_{\text{train}} = \frac{O}{R_{\text{peak}} \times \eta_{\text{hw}}}\) is useful, and identify why the formula alone cannot diagnose a slow small-batch debugging run.
Answer: The equation is useful as an accounting identity: it relates total work, a chosen peak-throughput reference, and effective achieved throughput into one training-time estimate. But because the end-to-end utilization term can already include stalls from launches, transfers, synchronization, and underfilled kernels, the formula alone does not reveal which mechanism caused a slow run. In a small-batch debug session, the problem is not that the law becomes invalid; it is that a low measured utilization could come from many overheads, so diagnosis still requires profiling rather than reading the formula by itself.
Learning Objective: Explain what the simplified training-time law captures and why it does not by itself localize the cause of low-throughput execution.
True or False: All large deep learning models are primarily compute-bound, so training speed is always governed mainly by Tensor Core TFLOP/s.
Answer: False. Dense transformer training often spends much of its work in matrix multiplications, but other workloads can be limited by memory capacity or bandwidth instead. The section’s DLRM example is dominated by large embedding tables, where fitting and moving the state can matter more than raw dense-math throughput.
Learning Objective: Distinguish compute-bound dense training from regimes where memory capacity or bandwidth is the binding constraint.
Place the following milestones in chronological order, reflecting how training-system constraints evolved: (1) Transformers shift sequence modeling toward high-throughput dense matrix multiplication and large activation footprints. (2) Backpropagation is popularized for multilayer neural networks. (3) Large-scale foundation models such as GPT-3 make utilization and multi-accelerator scaling central engineering concerns. (4) AlexNet demonstrates that deep neural network training maps effectively to GPUs. (5) IO-aware FlashAttention appears as a response to attention memory-bandwidth limits.
Answer: The correct order is: (2) Backpropagation is popularized for multilayer neural networks, (4) AlexNet demonstrates that deep neural network training maps effectively to GPUs, (1) Transformers shift sequence modeling toward high-throughput dense matrix multiplication and large activation footprints, (3) Large-scale foundation models such as GPT-3 make utilization and multi-accelerator scaling central engineering concerns, (5) IO-aware FlashAttention appears as a response to attention memory-bandwidth limits. This sequence matters because each later systems response addresses a constraint exposed by the earlier stage: GPU acceleration follows practical deep learning, transformers amplify activation and attention costs, frontier-scale models make utilization and scaling decisive, and FlashAttention targets the resulting IO bottleneck in attention.
Learning Objective: Trace the historical sequence linking major training-system milestones to the constraints they exposed.
Self-Check: Answer
Why do batched matrix-matrix multiplications (GEMM, BLAS Level 3) usually achieve much higher accelerator utilization in neural network training than matrix-vector operations (GEMV, BLAS Level 2)?
- Matrix-matrix operations avoid gradient computation during backpropagation, so they save both memory traffic and arithmetic work.
- Under the ideal traffic model in the section, GEMM reuses loaded operands across many outputs, so arithmetic intensity can grow with matrix size, whereas GEMV offers much less reuse and tends to stay near constant arithmetic intensity.
- Matrix-vector operations cannot run efficiently on GPUs because every layer result must be synchronized back to the CPU before the next layer starts.
- Batched matrix-matrix operations reduce the model’s parameter count, which is why they keep more of the network in HBM.
Answer: The correct answer is B. Under the section’s idealized traffic analysis, GEMM performs many more FLOPs per byte moved because tiles of weights and activations are reused across multiple outputs, so its arithmetic intensity can scale upward with problem size. GEMV offers far less reuse, so moving bytes can dominate execution. The claim that GEMM avoids gradients is wrong because training uses matrix multiplies heavily in backward as well as forward, and the CPU-synchronization explanation confuses low arithmetic intensity with an unsupported execution model.
Learning Objective: Compare GEMM and GEMV using arithmetic intensity and operand reuse in the accelerator memory hierarchy.
A team trains a 7-billion-parameter model on accelerators with 80 GB of HBM each. Weights, gradients, activations, and common workspaces already occupy 64 GB per accelerator, and this total already includes any FP32 master weights if the recipe uses them. The model is unsharded per device. Using the section’s optimizer-memory accounting, explain the systems trade-off between choosing plain SGD and Adam for this run.
Answer: Adam adds two FP32 moment tensors, or 8 bytes per parameter, so a 7B-parameter model needs about 56 GB more optimizer state. That pushes the per-device total from 64 GB to about 120 GB, which exceeds an 80 GB accelerator before any sharding decision is considered, whereas plain SGD adds no auxiliary optimizer state and still fits at 64 GB. The practical consequence is that this choice is first a capacity question; once a feasible optimizer is chosen, the team should then measure time to target quality rather than assume one optimizer will always converge faster.
Learning Objective: Calculate whether SGD or Adam fits within a fixed HBM budget when common training state is already accounted for.
The point on a roofline model curve where the memory-bandwidth-bound diagonal ceiling intersects the flat peak-compute ceiling, defined mathematically as \(\text{Peak FLOP/s} / \text{Memory Bandwidth}\), is known as the ____ point.
Answer: The correct answer is ridge (or roofline ridge). The ridge point represents the minimum arithmetic intensity required for an operation to reach the accelerator’s maximum computational throughput.
Learning Objective: Identify the definition and significance of the ridge point in roofline model analysis.
**Order the following events in a standard backpropagation training step to reflect their strict causal and data dependencies:
- Compute scalar objective loss by evaluating predictions against ground-truth labels.
- Update model parameters using gradient-based optimization rules (such as Adam or SGD).
- Execute forward propagation through successive layers while caching intermediate activations.
- Evaluate the chain rule backward from the loss through layers to compute parameter and activation gradients.
- Fetch and preprocess the training mini-batch on the host and transfer it to device memory.**
Answer: The correct answer is 5, 3, 1, 4, 2: (5) Fetch and preprocess the training mini-batch on the host and transfer it to device memory. (3) Execute forward propagation through successive layers while caching intermediate activations. (1) Compute scalar objective loss by evaluating predictions against ground-truth labels. (4) Evaluate the chain rule backward from the loss through layers to compute parameter and activation gradients. (2) Update model parameters using gradient-based optimization rules.
Learning Objective: Order the operations of a training iteration based on their mathematical and data dependencies.
For a transformer with hidden dimension \(d_{\text{model}} = 768\) and 12 heads (\(d_{\text{head}} = 64\)), the section’s restricted accounting gives the materialized attention-score computation an arithmetic intensity of about \(d_{\text{head}}/2 = 32\text{ FLOP/byte}\). If the target accelerator is the reference H100, whose ridge point is about \(295\text{ FLOP/byte}\), what does that imply and what optimization direction best matches the section?
- The kernel is compute-bound, so increasing peak TFLOP/s is the main expected lever under this model.
- The kernel is latency-bound, so shrinking the batch is the main way to move it onto the compute roof.
- The kernel is network-bound, so the right first response is a faster inter-node AllReduce fabric.
- The kernel falls on the memory-bandwidth side of the roofline under this accounting, so reducing materialized score traffic through IO-aware tiling is the appropriate optimization direction.
Answer: The correct answer is D. With an estimated intensity of \(32\text{ FLOP/byte}\) against the H100’s ridge point of about \(295\text{ FLOP/byte}\), the roofline classifies this implementation as memory-bandwidth-limited under the stated traffic model. That does not prove a measured kernel already saturates bandwidth or that hardware upgrades can never help, but it does indicate that reducing score-matrix traffic is the matching optimization direction. The network answer is irrelevant because this is a local attention-kernel analysis, and shrinking batch size does not address the materialized-attention IO term the section highlights.
Learning Objective: Use ridge-point comparison to classify an attention implementation and select the matching traffic-reduction optimization direction.
Self-Check: Answer
Which set of subsystems defines the chapter’s high-level training system architecture, and what systems engineering advantage does this decomposition provide?
- Storage controller, compiler intermediate representation, and runtime execution engine; this separates hardware target code generation from storage layout.
- Data pipeline, training loop, and evaluation pipeline; this separates distinct resource profiles (CPU/storage I/O, accelerator compute/memory, and periodic validation) so bottlenecks can be isolated at subsystem interfaces.
- Tokenizer, hyperparameter optimizer, and model registry; this organizes the model deployment lifecycle around developer interfaces.
- Gradient aggregator, parameter server, and checkpoint restorer; this decomposes cloud service microservices.
Answer: The correct answer is B. The training architecture decomposes the system into three interconnected subsystems: the data pipeline (ingestion, transformation, batching), the training loop (forward pass, loss, backward pass, optimizer update), and the evaluation pipeline (validation metrics on held-out data). This separation enables engineers to diagnose bottlenecks by subsystem resource demands (host CPU/disk for data, accelerator compute/HBM for training loop, and periodic synchronization pauses for evaluation). The storage controller and compiler option describes compiler infrastructure rather than runtime training systems. The tokenizer and registry option describes MLOps lifecycle tools. The gradient aggregator option lists distributed implementation components rather than end-to-end training subsystems.
Learning Objective: Identify the three major subsystems of a training pipeline architecture and explain the systems rationale for this decomposition.
In a profiled training pipeline, CPU data preprocessing sustains \(4\text{ GB/s}\) on the same logical batch representation that host-to-device transfer and GPU consumption are being compared against. Host-to-device PCIe transfer sustains \(32\text{ GB/s}\), and GPU compute consumes data at an equivalent rate of \(12\text{ GB/s}\). Under the section’s ideal-overlap pipeline model, what determines end-to-end throughput, and what is the best first engineering action?
- The average of the three rates, so the effective throughput is \(16\text{ GB/s}\) and all stages should be tuned evenly.
- The PCIe transfer rate, because every batch must cross the bus before any compute can happen.
- The minimum rate, \(4\text{ GB/s}\) from preprocessing, so the first action is to reduce the input-side bottleneck before tuning faster stages.
- The GPU compute rate, because training pipelines are ultimately limited by accelerator execution speed rather than host stages.
Answer: The correct answer is C. In the section’s pipeline model, comparable stage rates are combined through a minimum: the slowest stage caps throughput even if transfer and compute are faster. Here preprocessing at \(4\text{ GB/s}\) is the binding constraint, so the first goal is to raise input-side service rate and remove that bottleneck. An answer based on averaging ignores how pipelines work, and upgrading a non-binding PCIe or compute stage does not change a system still waiting on preprocessing.
Learning Objective: Apply the pipeline bottleneck model to identify the slowest comparable stage as the limit on end-to-end throughput.
Explain why CPU-side tokenization and data augmentation can severely bottleneck GPU training even when the resulting tensor transfer across PCIe takes less than one millisecond.
Answer: A fast PCIe copy only shows that the transfer stage is short once a batch already exists; it says nothing about how long the CPU needed to create that batch. If CPU preprocessing takes 65 ms and GPU compute takes 80 ms, then with proper overlap the next batch can still be ready in time, but without overlap or with an unstable host service interval the GPU can see bubbles despite the sub-millisecond transfer. The practical consequence is that busy-time fractions alone are not peak arithmetic efficiency and do not prove a specific worker count; what matters is whether preprocessing can consistently supply the next batch before compute needs it.
Learning Objective: Analyze why preprocessing latency can dominate input delivery even when the PCIe transfer itself is short.
True or False: Scaling the training batch size by \(8\times\) while keeping the learning rate and schedule unchanged guarantees the same model quality in less wall-clock time.
Answer: False. A larger batch changes both the number of updates per epoch and the gradient statistics seen by the optimizer, so the old learning-rate schedule may no longer be appropriate. The section says validation is needed after a large batch-size change, and retuning may be needed rather than guaranteed.
Learning Objective: Evaluate why changing batch size can alter optimization behavior even when hardware throughput improves.
To enable fast, asynchronous Direct Memory Access (DMA) transfers from host RAM to GPU memory without intermediate CPU staging copies, host memory buffers must be allocated as page-locked or ____ memory.
Answer: The correct answer is pinned (or page-locked). Pinned memory prevents the operating system from paging memory to disk, enabling the GPU DMA controller to read tensors asynchronously concurrently with compute.
Learning Objective: Identify the systems mechanism (pinned memory) used for asynchronous host-to-device transfers.
In the chapter’s staged system pipeline framework, what constitutes an “accelerator bubble” and what is the primary diagnostic step to resolve it?
- An intentional synchronization barrier inserted by automatic differentiation to ensure memory coherence across gradient passes; resolved by disabling graph checks.
- An on-chip SRAM cache eviction event caused by large transformer sequence lengths; resolved by switching to smaller embedding tables.
- A loss of arithmetic intensity when batch sizes fall below the hardware ridge point; resolved by forcing FP64 accumulation.
- Silicon idleness where accelerator ALUs wait for data loading, host-to-device PCIe transfer, or parameter synchronization; resolved by profiling the four pipeline stages to identify and overlap the slowest stage.
Answer: The correct answer is D. An accelerator bubble is defined as idle or underutilized accelerator time resulting from a throughput mismatch across the four pipeline stages (Data Loading & Preprocessing, Host-to-Device Transfer, Forward/Backward Compute, and Parameter Synchronization). Resolving bubbles requires profiling each stage to locate the binding constraint and applying overlapping techniques such as asynchronous prefetching. The assertion of intentional synchronization misinterprets a performance inefficiency as a design feature. The SRAM cache eviction option confuses low-level cache misses with macro pipeline stalls. The ridge-point loss option misapplies roofline terminology to pipeline-level time allocation.
Learning Objective: Explain the systems definition of accelerator bubbles across the four pipeline stages and identify the diagnostic procedure to eliminate them.
Self-Check: Answer
Why is Model FLOPs Utilization (MFU) a more reliable metric than raw GPU busy percentage (reported by tools like
nvidia-smi) when evaluating training systems efficiency?- MFU is measured directly from host CPU clock cycles, eliminating GPU driver instrumentation overhead.
- MFU is mathematically fixed to 100% on any healthy accelerator cluster regardless of software overhead.
- MFU counts only the theoretical forward and backward FLOPs required by the model architecture divided by the product of peak hardware throughput and measured step time, whereas raw GPU busy percentage also counts time spent on recomputation, padding, and memory stalls outside that model-FLOP numerator.
- MFU measures training loss convergence speed per dollar rather than floating-point operations.
Answer: The correct answer is C. Raw GPU utilization measures the percentage of time GPU execution units or kernels are active. A GPU can show 95% utilization while spending half its time stalling on memory bandwidth or recomputing activations during gradient checkpointing. In contrast, MFU (\(\text{MFU} = \frac{O_{\text{model}}}{R_{\text{peak}} \times T_{\text{step}}}\)) includes only the useful forward and backward model FLOPs in the numerator, explicitly penalizing recomputation, padding FLOPs, memory stalls, and pipeline bubbles. MFU is an accelerator metric, not a CPU metric. MFU is not fixed to 100%; reported values depend on workload, hardware, precision, and the FLOP-counting convention. MFU measures hardware efficiency, not loss convergence per dollar.
Learning Objective: Differentiate Model FLOPs Utilization (MFU) from raw GPU busy utilization and explain which overheads MFU exposes.
An engineer profiles two training workloads. Workload A shows 92 percent GPU busy time, near-saturated HBM bandwidth, low CPU activity, and continuous kernel timelines. Workload B shows 20 percent GPU busy time with regular 50 ms idle gaps, low HBM bandwidth, and 100 percent CPU utilization. Apply the D·A·M taxonomy to classify each workload’s likely bottleneck and state the next optimization category for each.
Answer: Workload A supports a bandwidth-bound hypothesis on the Machine side: kernels are running continuously and HBM is heavily used, so the next step is to confirm that critical kernels are limited by memory traffic and then target traffic reduction or fusion. Workload B is consistent with a Data-side bottleneck only if the GPU gaps correlate with batch preparation rather than host dispatch or synchronization, so the next step is stage correlation and then input-pipeline optimization if starvation is confirmed. The practical consequence is that D·A·M categories are diagnostic guides, not exclusive labels you can assign from one metric alone.
Learning Objective: Apply D·A·M reasoning to profile signatures while distinguishing likely bottlenecks from confirmed diagnoses.
**Order the steps of the systematic training optimization workflow recommended in the chapter:
- Classify the primary performance constraint (Data-, Memory-, or Compute-bound) using the D·A·M taxonomy.
- Run a representative training run with framework and system profilers enabled to capture CPU, PCIe, and GPU timeline traces.
- Re-profile the system to evaluate MFU improvement and identify whether the bottleneck has shifted to a new pipeline stage.
- Apply a targeted optimization technique specifically addressing the identified binding constraint.**
Answer: The correct answer is 2, 1, 4, 3: (2) Run a representative training run with framework and system profilers enabled to capture CPU, PCIe, and GPU timeline traces. (1) Classify the primary performance constraint (Data-, Memory-, or Compute-bound) using the D·A·M taxonomy. (4) Apply a targeted optimization technique specifically addressing the identified binding constraint. (3) Re-profile the system to evaluate MFU improvement and identify whether the bottleneck has shifted to a new pipeline stage.
Learning Objective: Order the systematic profile-diagnose-fix-reprofile optimization cycle.
An engineering team suspects that an individual custom LayerNorm kernel has poor arithmetic intensity and low register occupancy, while another team suspects their DataLoader is causing host-to-device PCIe transfer stalls. Which combination of profiling tool classes from the chapter is best suited to investigate each respective issue?
- A kernel-level GPU profiler with per-kernel counters for the arithmetic intensity and occupancy analysis; a framework-level or system-level timeline profiler for the DataLoader and PCIe transfers.
nvidia-smifor kernel-level arithmetic intensity; TensorBoard loss curves for DataLoader PCIe transfer stalls.- NVIDIA Nsight Compute for cluster-wide inter-node network bandwidth; PyTorch Profiler for register allocation analysis.
- Linux
topcommand for GPU kernel instruction analysis; NVIDIA Nsight Systems for CPU register spill tracking.
Answer: The correct answer is A. The chapter distinguishes two classes of profilers. Kernel-level GPU profilers record per-kernel counters such as achieved memory throughput and arithmetic-unit occupancy, making them right for the custom LayerNorm kernel. Framework-level and system-level timeline profilers (for example PyTorch Profiler or NVIDIA Nsight Systems) record timeline traces capturing CPU thread execution, CUDA API dispatches, PCIe memory copies, and GPU stream synchronization, making them ideal for diagnosing DataLoader and PCIe stalls.
nvidia-smiprovides coarse device-wide polling rather than kernel-level roofline analysis. Linuxtopmonitors host OS processes, not GPU internal instruction pipelines.Learning Objective: Select the appropriate class of profiler (kernel-level counters versus timeline traces) based on the granularity of the performance investigation.
A team’s profiler shows the GPU at 18 percent utilization with periodic drops to zero, while one CPU core is pinned near 100 percent and the PCIe link is mostly idle. Using the section’s staged-pipeline framework, explain how to diagnose the bubble’s source and what fix should be targeted.
Answer: This pattern suggests the input side of the staged pipeline may be starving the accelerator, because the GPU has bubbles while host work is active and PCIe is not the limiting stage. To confirm the source, correlate the GPU idle gaps with batch-preparation time versus host dispatch or synchronization delays; if the gaps line up with preprocessing, then the right fix is input-pipeline work such as additional workers or prefetching. The practical implication is that high CPU usage alone is not enough to blame tokenization or the GIL with certainty—the stage correlation must come first.
Learning Objective: Analyze staged-pipeline signals to distinguish likely input starvation from other host-side causes of accelerator bubbles.
Self-Check: Answer
For each batch, a training step has three dependent stages in a serial baseline: data preprocessing (\(T_{\text{prep}} = 30\text{ ms}\)), host-to-device transfer (\(T_{\text{xfer}} = 10\text{ ms}\)), and GPU compute (\(T_{\text{comp}} = 50\text{ ms}\)). Different batches can occupy independent resources and overlap with correct handoff. If the team implements steady-state overlapping with prefetching and double buffering, what iteration interval is theoretically possible after fill and before drain?
- \(40\text{ ms}\), because preprocessing and transfer replace compute once overlap is enabled.
- \(50\text{ ms}\), because in ideal steady state the interval is bounded by the slowest overlapped stage rather than the serial sum.
- \(10\text{ ms}\), because all stages run concurrently and the fastest one sets the pace.
- \(90\text{ ms}\), because DMA transfers cannot overlap useful GPU computation.
Answer: The correct answer is B. The serial baseline takes \(30 + 10 + 50 = 90\text{ ms}\) per batch, but ideal steady-state overlap changes the limiting interval to \(\max(30, 10, 50) = 50\text{ ms}\). That is a throughput improvement to \(90/50 = 1.8\times\), not a promise that the latency of one isolated batch falls to 50 ms from startup. The \(10\text{ ms}\) answer uses the fastest stage instead of the slowest, and the no-overlap answer ignores the purpose of prefetching and copy/compute concurrency.
Learning Objective: Calculate the steady-state throughput interval of an overlapped training pipeline from its stage times.
Explain how FlashAttention computes exact self-attention with substantially lower memory footprint than standard attention, and describe what its backward pass does instead of reading a full stored score matrix from HBM.
Answer: FlashAttention keeps the same attention mathematics, with possible floating-point rounding differences, but changes where intermediate work lives: it processes query, key, and value tiles in on-chip SRAM and maintains the softmax statistics online instead of materializing the full \(S \times S\) score matrix in HBM. That cuts saved activation storage and reduces off-chip traffic tied to those score blocks rather than implying a linear law for all HBM IO. In backward, it recomputes the needed tiled score and probability blocks from saved inputs and normalization statistics rather than loading a full stored score matrix, so the systems gain comes from less HBM traffic, not from changing the attention mathematics.
Learning Objective: Explain how IO-aware tiling and backward recomputation reduce attention memory traffic without changing attention mathematics.
Why does the chapter’s conventional FP16 mixed-precision recipe keep FP32 master weights and perform selected reductions in FP32 instead of forcing every part of training into 16-bit precision?
- Tensor Cores cannot execute backpropagation unless gradients are stored in FP64.
- FP16 allocations can lock the accelerator memory bus unless the master weights are moved to host RAM.
- Automatic differentiation requires symbolic derivatives to be represented only in FP32.
- Very small parameter updates can be rounded away when applied directly to FP16 weights, and selected reductions benefit from the wider range or precision of FP32 accumulation.
Answer: The correct answer is D. The section’s FP16 recipe keeps FP32 master weights because an update can be too small to change a stored FP16 weight after rounding even when the update itself is representable; preserving the update in FP32 avoids losing it across many steps. The same section also notes that selected reductions are often kept in FP32 because wider accumulation improves numerical behavior, though it does not guarantee stability everywhere. The FP64 and host-RAM claims invent hardware requirements the chapter does not make, and autodiff does not require a purely FP32 graph representation.
Learning Objective: Justify FP32 master weights and selected FP32 reductions in the conventional FP16 mixed-precision training recipe.
Gradient accumulation increases the memory footprint on the accelerator linearly with the accumulation factor \(K\) because all \(K\) micro-batches’ intermediate activations must remain in GPU memory simultaneously until the optimizer step.
Answer: False. Gradient accumulation executes forward and backward passes sequentially across \(K\) micro-batches, accumulating (summing) only the parameter gradients in a single fixed-size gradient buffer. Saved backward tensors for each micro-batch can be released after its backward pass when the graph is not retained; other references or cached tensors may extend storage lifetime. Consequently, activation memory is bounded by the size of a single micro-batch (\(B_{\text{micro}}\)), allowing systems to emulate an effective batch size of \(K \times B_{\text{micro}}\) without increasing activation memory.
Learning Objective: Analyze the memory behavior of gradient accumulation across multiple micro-batches.
In FP16 mixed-precision training, the loss is multiplied before backpropagation so the resulting gradients are shifted into a safer numeric range, then divided back down before the optimizer update. This technique is known as loss ____.
Answer: scaling. Loss scaling multiplies the loss before backward so the resulting gradients are less likely to underflow in FP16, then unscales them before the optimizer step.
Learning Objective: Identify loss scaling as the technique used to reduce FP16 gradient underflow risk.
A team enables mixed precision on a transformer model and observes compute time drop by 45 percent, but total step time decreases by only 10 percent because the GPU now shows large idle gaps. Explain what likely happened in the system pipeline and what the team should do next.
Answer: The compute optimization removed part of the old critical path, but the new timeline shows that another stage is now exposed because the GPU is spending meaningful time idle. Those gaps are not proof of a data-loader problem by themselves: they could come from input waits, dispatch overhead, synchronization, or another serial stage. The right next step is to re-profile and correlate the gaps with pipeline stages so the next optimization targets the newly binding bottleneck rather than assuming mixed precision failed.
Learning Objective: Explain why speeding up compute can expose a different bottleneck and why re-profiling is required before choosing the next optimization.
Self-Check: Answer
A team trains a 1.5-billion-parameter model that already fits on one 80 GB GPU with batch size 16 and its Adam training state, but one epoch still takes 12 days. The team has an 8-GPU node available. Which strategy is the best first baseline, and why?
- Tensor parallelism, because splitting every weight matrix across the 8 GPUs is always the fastest way to improve training throughput.
- Pipeline parallelism, because dividing layers across devices is the default first step whenever a model is a transformer.
- Data parallelism such as DDP, because the model already fits per device and replication avoids unnecessary pipeline bubbles or intra-layer communication as the initial throughput baseline.
- Full parameter sharding first, because any multi-GPU run should avoid keeping complete replicas even when memory is sufficient.
Answer: The correct answer is C. When the full model and training state already fit on one device, data parallelism is the natural first baseline because each GPU can run the local forward and backward pass without introducing the extra sequential dependencies of pipeline parallelism or the frequent collectives of tensor partitioning. An answer based on splitting layers or tensors solves a memory problem the scenario does not currently have. Sharding may still become useful later, but it is not the first throughput baseline when replication already fits.
Learning Objective: Select data parallelism as the first multi-GPU baseline when memory already fits on each device and the main goal is throughput.
In distributed data parallel training with \(N\) GPUs and a model with \(P\) parameters whose gradients use \(B_{\text{bytes}}\) bytes each, what is the number of bytes sent by each GPU during a Ring AllReduce?
- \(2 \times \frac{N-1}{N} \times P \times B_{\text{bytes}}\), which approaches \(2 P B_{\text{bytes}}\) as \(N\) grows.
- \(N \times P \times B_{\text{bytes}}\), because each GPU must broadcast the full gradient to every other GPU.
- \(\frac{P \times B_{\text{bytes}}}{N^2}\), because the ring divides both the model and the communication quadratically.
- Zero, because GPU replicas synchronize through shared CPU memory rather than explicit data movement.
Answer: The correct answer is A. In a ring AllReduce, each GPU participates in a scatter-reduce phase and an all-gather phase, and the bytes sent per GPU total \(2 \times \frac{N-1}{N} \times P \times B_{\text{bytes}}\). That expression tends toward \(2 P B_{\text{bytes}}\) as \(N\) becomes large, so the per-GPU sent volume stays bounded rather than growing linearly with the cluster size. The broadcast-style answer describes a different and less efficient mental model of synchronization.
Learning Objective: Calculate the per-GPU bytes sent in Ring AllReduce and interpret its scaling with device count.
Explain what communication overhead is in distributed training, and analyze why adding more GPUs can lead to diminishing throughput returns.
Answer: Communication overhead is the time spent synchronizing gradients or exchanging partitioned activations and tensors instead of doing local model computation. As more GPUs are added, ideal compute work per device can fall, but communication latency, transfer volume, and incomplete overlap do not disappear, so synchronization becomes a larger fraction of each step. The practical consequence is that scaling efficiency drops once communication and coordination consume enough of the step that extra devices save less compute time than they add in communication cost.
Learning Objective: Analyze how communication overhead limits scaling efficiency as distributed training spans more accelerators.
In pipeline model parallelism, partitioning a network linearly across \(K\) stages without micro-batching (naive pipeline parallelism) achieves 100 percent GPU utilization because downstream devices can compute backward gradients while upstream devices run forward passes.
Answer: False. In naive pipeline parallelism without micro-batching, downstream devices must wait idle until upstream devices complete their forward passes, and upstream devices must wait idle until downstream devices compute backward loss gradients. This introduces massive idle pipeline bubbles where device utilization collapses to \(\approx 1/K\). Practical pipeline parallelism systems (like GPipe and 1F1B in PipeDream) mitigate this by splitting batches into multiple small micro-batches and interleaving forward and backward passes to fill the pipeline.
Learning Objective: Identify the pipeline bubble pathology of naive pipeline parallelism and explain how micro-batch schedules mitigate it.
Arrange the following engineering steps in the chapter’s preferred order for deciding whether to scale beyond one device, assuming the initial bounds do not already prove that single-device training is infeasible: (1) Re-evaluate whether memory or time limits still justify scaling. (2) Add distributed parallelism or sharding if the remaining limit still requires it. (3) Establish a single-device baseline and quantify the current bottleneck. (4) Apply relevant local optimizations such as mixed precision, prefetching, checkpointing, or accumulation.
Answer: The correct order is: (3) Establish a single-device baseline and quantify the current bottleneck, (4) Apply relevant local optimizations such as mixed precision, prefetching, checkpointing, or accumulation, (1) Re-evaluate whether memory or time limits still justify scaling, (2) Add distributed parallelism or sharding if the remaining limit still requires it. This order matters because the chapter’s scaling discipline uses baseline measurement first, then local fixes targeted to the observed constraint, then a new decision about whether a hard limit remains. Jumping straight to distributed scaling can add communication and operational complexity before the single-device bottleneck is even understood.
Learning Objective: Sequence the chapter’s single-machine-first process for deciding when distributed scaling is actually justified.
Self-Check: Answer
A team scales a dense model from 7 billion to 20 billion parameters while keeping the same training-token budget, precision recipe, and optimizer structure. Under the chapter’s fallacies discussion, what is the most defensible conclusion?
- Validation accuracy must improve in proportion to parameter count because the larger model can represent more functions.
- The run will necessarily move to CPU execution because 20B parameters cannot be trained on accelerators.
- The larger model guarantees worse accuracy because fixed-token training always causes catastrophic interference at higher parameter counts.
- The training-state and compute budgets rise substantially under the same dense-model accounting, but model quality is not guaranteed to improve because it still depends on data, optimization, and evaluation.
Answer: The correct answer is D. Under the chapter’s dense-model accounting with fixed precision and optimizer assumptions, a larger parameter count clearly raises memory and leading FLOP requirements, so systems cost goes up in a predictable direction. But the scientific outcome is not guaranteed: keeping the same token budget does not prove either improvement or collapse in validation quality. The “must improve” answer mistakes model size for a universal quality guarantee, while the CPU answer invents a hardware consequence the chapter does not state.
Learning Objective: Distinguish the predictable systems costs of scaling parameter count from the uncertain effect on final model quality.
Explain why directly transferring hyperparameters such as learning rate and weight decay from a batch-size 512 baseline to a batch-size 4,096 distributed run can cause training to underperform, even when raw GPU busy time stays above 90 percent.
Answer: An eightfold batch increase means eight times fewer parameter updates per fixed epoch, and it also changes the gradient statistics seen by the optimizer, so the old hyperparameters no longer operate in the same regime. High GPU busy time only shows that hardware is active; it does not prove that the optimizer is making equally effective progress per unit data. The practical response is to validate the learning-rate schedule, warmup, and target quality metric on the larger-batch run instead of assuming the small-batch recipe transfers unchanged.
Learning Objective: Explain why batch-size scaling can invalidate a previously successful optimization recipe even when hardware utilization looks strong.
Which engineering mistake exemplifies “pipeline neglect” as described in the chapter’s pitfalls?
- Using BF16 mixed precision instead of FP16 on NVIDIA Ampere GPUs.
- Spending weeks hand-tuning custom CUDA attention kernels to achieve 95% peak arithmetic throughput, only to discover in production that the GPU sits idle 50% of the time waiting for single-threaded Python CPU tokenization.
- Setting
pin_memory=Trueandnum_workers=8in a PyTorch DataLoader. - Checkpointing activations every \(\sqrt{N_L}\) layers to reduce peak memory.
Answer: The correct answer is B. Pipeline neglect occurs when engineers focus exclusively on accelerator-side compute optimizations (such as custom CUDA kernels, mixed precision, or Tensor Core utilization) while neglecting end-to-end profiling. If the upstream data pipeline (CPU tokenization, disk I/O, or augmentation) is bottlenecked, the GPU will starve, rendering kernel-level speedups useless at the system level. BF16, DataLoader worker and pinned-memory settings, and checkpointing are candidate interventions whose value depends on the diagnosed constraint and validation results.
Learning Objective: Distinguish pipeline neglect and the data-side blind spot as a major operational pitfall in training optimization.
A team proposes moving a single-GPU training job to a 16-GPU cluster to achieve a \(16\times\) reduction in development cycle time. Explain two reasons why distributed training rarely delivers a linear \(16\times\) improvement in developer velocity.
Answer: First, distributed execution adds communication and synchronization overhead, so throughput rarely scales linearly with GPU count even when the code is correct. Second, developer velocity depends on more than throughput: distributed jobs bring extra debugging, launch, checkpointing, and failure-handling overhead that can delay iteration even if step time improves. The practical consequence is that cluster scaling should be justified by measured end-to-end iteration gains, not by hardware count alone.
Learning Objective: Evaluate why communication overhead and operational complexity both limit the developer-velocity gains of distributed training.