$$ \newcommand{\AbsoluteConicImageEntry}{B} \newcommand{\AbsoluteConicImageMatrix}{\mathbf{B}} \newcommand{\AbsoluteConicVector}{\mathbf{b}} \newcommand{\AcceleratedEpisodeTime}{T'} \newcommand{\AcceleratedFractionSpeedup}{G} \newcommand{\AccelerationNoiseDensityMatrix}{\mathbf{Q}_c} \newcommand{\AccelerationNoiseSpectralDensity}{q_c} \newcommand{\AccelerationWhiteNoise}{w} \newcommand{\AcceleratorBatchTime}{T_{\text{GPU}}} \newcommand{\AcceleratorConsumptionRate}{R_{\text{accel}}} \newcommand{\AcceleratorCount}{N_{\text{GPU}}} \newcommand{\AcceleratorDataConsumptionRate}{R_{\text{consumption}}} \newcommand{\AcceleratorGain}{G_{\text{accel}}} \newcommand{\AcceleratorHourlyPrice}{R_{\text{GPU/hr}}} \newcommand{\AcceleratorMemoryBandwidth}{\text{BW}_{\text{accelerator}}} \newcommand{\AcceleratorRailVoltage}{V_{\text{rail}}} \newcommand{\AcceleratorSecondsPerQuery}{S_{\text{GPU/query}}} \newcommand{\AcceleratorSupplyCurrent}{i} \newcommand{\AcceleratorTargetQueryRate}{R_{\text{GPU,target}}} \newcommand{\AcceleratorsPerNode}{G_{\text{node}}} \newcommand{\AccelerometerBias}{b_a} \newcommand{\AcceptanceFraction}{\alpha} \newcommand{\AcceptanceIntervalLowerLimit}{L} \newcommand{\AcceptanceIntervalUpperLimit}{U} \newcommand{\AcceptanceProbability}{p_{\text{acc}}} \newcommand{\AcceptedInfluences}{\text{Inf}} \newcommand{\AcceptedInputSet}{\mathcal{A}_{\tau}} \newcommand{\AcceptedLabelCount}{d} \newcommand{\AcceptedOutcomePayoff}{V} \newcommand{\AcceptedSampleCount}{X} \newcommand{\AcceptedTaskMeanCost}{C_{\text{succ}}} \newcommand{\AcceptedTasks}{N_{\text{acc}}} \newcommand{\AcceptingStateSet}{F} \newcommand{\AccessAttemptTime}{t} \newcommand{\AccountQueryDistribution}{p_{\text{user}}} \newcommand{\AccumulatedProcessNoiseCovariance}{\mathbf{Q}_d} \newcommand{\AccumulatedSyncTime}{T_{\text{sync}}} \newcommand{\AccumulatedUpdateTime}{T_{\text{effective}}} \newcommand{\AccumulationStepCount}{k} \newcommand{\AccuracyAfterDeployment}{\text{Accuracy}} \newcommand{\AccuracyDecayRate}{\gamma} \newcommand{\AccuracyPayoffPerQuery}{V} \newcommand{\AchievedBrakingDeceleration}{a} \newcommand{\AchievedKernelBandwidth}{\text{BW}_{\text{effective}}} \newcommand{\AcquisitionEpoch}{t_{\text{acq}}} \newcommand{\ActVariationalObjective}{\mathcal{L}_{\text{ACT}}} \newcommand{\ActionBinCount}{B} \newcommand{\ActionChunk}{\mathbf{A}} \newcommand{\ActionChunkHorizon}{H} \newcommand{\ActionChunkIndex}{k} \newcommand{\ActionDimension}{d_a} \newcommand{\ActionExecutionRate}{f_{\text{exec}}} \newcommand{\ActionFilterCutoffFrequency}{f_{\text{cutoff}}} \newcommand{\ActionLowerBound}{\mathbf{a}_{\min}} \newcommand{\ActionMagnitudeBound}{a_{\max}} \newcommand{\ActionRangeMaximum}{a_{\max}} \newcommand{\ActionRangeMinimum}{a_{\min}} \newcommand{\ActionRecoverableFraction}{\rho_{a}} \newcommand{\ActionResidualVector}{\mathbf{r}} \newcommand{\ActionSpace}{\mathcal{A}} \newcommand{\ActionTokenPrefix}{a_{<j}} \newcommand{\ActionUpperBound}{\mathbf{a}_{\max}} \newcommand{\ActivationCheckpointCount}{n_{\text{ckpt}}} \newcommand{\ActivationFunction}{f} \newcommand{\ActivationInput}{x} \newcommand{\ActivationLipschitzBound}{L_{\phi}} \newcommand{\ActivationMatrix}{\mathbf{A}} \newcommand{\ActivationMemory}{M_{\text{activations}}} \newcommand{\ActivationPayloadSize}{M_{\text{act}}} \newcommand{\ActivationStagingTime}{t_{\text{activate}}} \newcommand{\ActivationVector}{\mathbf{a}} \newcommand{\ActiveContactIndex}{k} \newcommand{\ActiveControlTorque}{\mathbf{u}_{\text{active}}} \newcommand{\ActiveInferencePower}{P_{\text{active}}} \newcommand{\ActiveLeaseCount}{N_{\text{active}}} \newcommand{\ActiveMotionDuration}{T_{\text{motion}}} \newcommand{\ActiveParameterCount}{P_{\text{model}}} \newcommand{\ActivePrefillRequestSet}{\mathcal{P}_{\text{active}}} \newcommand{\ActiveSchemaSet}{\mathcal{S}} \newcommand{\ActiveTargetTokenCount}{N_{\text{active}}} \newcommand{\ActorAccelerationBound}{a_{k,\max}} \newcommand{\ActorBodyRadius}{r} \newcommand{\ActorUpdateDelayCount}{d} \newcommand{\ActuatedJointAccelerations}{\ddot{\mathbf{q}}_j} \newcommand{\ActuatedJointBiasForces}{\mathbf{h}_j} \newcommand{\ActuatedJointCoordinates}{\mathbf{q}_j} \newcommand{\ActuationSelectionBaseBlock}{\mathbf{S}_b} \newcommand{\ActuationSelectionMatrix}{\mathbf{S}} \newcommand{\ActuatorAxisCount}{N_{\text{axes}}} \newcommand{\ActuatorBiasEffort}{u_{\text{bias}}} \newcommand{\ActuatorCyclePeriod}{t_{\text{cycle}}} \newcommand{\ActuatorDutyCycle}{D_{\text{cycle}}} \newcommand{\ActuatorEffort}{u} \newcommand{\ActuatorOffTime}{t_{\text{off}}} \newcommand{\ActuatorOnTime}{t_{\text{on}}} \newcommand{\ActuatorResponseTime}{T_{\text{act}}} \newcommand{\ActuatorTorqueLowerBound}{\mathbf{u}_{\min}} \newcommand{\ActuatorTorqueUpperBound}{\mathbf{u}_{\max}} \newcommand{\AdamFirstMoment}{m} \newcommand{\AdamMomentDecayRate}{\beta} \newcommand{\AdamSecondMoment}{v} \newcommand{\AdaptationEnergyAllowance}{E_{\text{slack}}} \newcommand{\AdaptationInvestmentCost}{C_{\text{invest}}} \newcommand{\AdaptationLatencyIncrease}{\Delta L_{\text{lat,fg}}^{\text{wc}}} \newcommand{\AdaptationModule}{g_{\psi}} \newcommand{\AdaptationPeakMemory}{M_{\text{peak}}} \newcommand{\AdaptationPowerIncrement}{P_{\text{update}}} \newcommand{\AdaptationWindowEnergy}{E_{\text{update}}} \newcommand{\AdaptedHiddenActivation}{\mathbf{h}'} \newcommand{\AdaptedTaskCost}{C_{\text{task, adapt}}} \newcommand{\AdaptedWeightMatrix}{\mathbf{W}_{\text{adapted}}} \newcommand{\AdapterActivationFunction}{\sigma} \newcommand{\AdapterAssignmentVector}{\mathbf{m}} \newcommand{\AdapterDownProjectionMatrix}{\mathbf{A}} \newcommand{\AdapterIndex}{k} \newcommand{\AdapterInitializationStandardDeviation}{\sigma} \newcommand{\AdapterRank}{r} \newcommand{\AdapterScalingFactor}{\gamma} \newcommand{\AdapterUpProjectionMatrix}{\mathbf{B}} \newcommand{\AdjacentNeighboringDataset}{X'} \newcommand{\AdjacentQueryResult}{v'} \newcommand{\AdminLeaseTime}{T_{\text{admin}}} \newcommand{\AdmissibleBacklogCount}{n} \newcommand{\AdmissibleControlSet}{\mathcal{U}_{\text{adm}}} \newcommand{\AdmissibleDisturbanceSet}{\mathcal{W}} \newcommand{\AdmissionCheckCount}{n_{\text{chk}}} \newcommand{\AdmissionCheckIndex}{i} \newcommand{\AdmissionDecisionEvent}{e_{\text{auth}}} \newcommand{\AdmissionInclusivePrebrakeDelay}{T_{\text{true}}} \newcommand{\AdmissionRouteYield}{Y} \newcommand{\AdmittedAttemptCap}{N} \newcommand{\AdmittedCommand}{u} \newcommand{\AdmittedContactForce}{F^*} \newcommand{\AdmittedControlCommand}{\mathbf{u}} \newcommand{\AdmittedSpeedCommand}{v^*} \newcommand{\AdmittedTargetPosition}{\hat{\mathbf{p}}_{\text{target}}} \newcommand{\AdmittedWorkUnitCount}{m} \newcommand{\AdvantageStabilizer}{\epsilon_{\text{stab}}} \newcommand{\AdversarialDisturbance}{\mathbf{d}} \newcommand{\AdversarialExample}{x_{\text{adv}}} \newcommand{\AdversarialInputLength}{n} \newcommand{\AdversarialPenaltyWeight}{\lambda_{\text{adv}}} \newcommand{\AdversarialPerturbation}{\boldsymbol{\delta}_{\text{adv}}} \newcommand{\AdversarialPerturbationBudget}{\epsilon_{\text{adv}}} \newcommand{\AdversaryLoss}{\mathcal{L}_{\text{adv}}} \newcommand{\AffordanceFrame}{\mathcal{F}_{\text{affordance}}} \newcommand{\AffordanceSuccessEstimate}{V_{\text{policy}}} \newcommand{\AgeBlindTravel}{\Delta x_{\text{blind}}} \newcommand{\AgeCheckInstant}{t_{\text{curr}}} \newcommand{\AggregateServerPower}{P_{\text{servers}}} \newcommand{\AggregateSlotWork}{W} \newcommand{\AggregatedRecoveryDataset}{\mathcal{D}} \newcommand{\AggregatedSurrogateLoss}{\epsilon_N} \newcommand{\AggregationLearnedPolicy}{\hat{\pi}} \newcommand{\AggregationLearnerStateDistribution}{d_{\hat{\pi}_i}} \newcommand{\AggregationRoundCount}{N} \newcommand{\AggregationRoundIndex}{i} \newcommand{\AggregationRoundTrajectorySet}{\mathcal{T}} \newcommand{\AiStandaloneSensitivity}{S_{\text{AI}}} \newcommand{\AisleTravelSpeed}{v_{\text{aisle}}} \newcommand{\AisleWidth}{w} \newcommand{\AlertCheckCount}{N_{\text{tests}}} \newcommand{\AlertFalsePositiveRate}{\alpha_{\text{fp}}} \newcommand{\AlgorithmTaxonomyAxis}{\mathsf{Algorithm}} \newcommand{\AliasedVibrationFrequency}{f_{\text{alias}}} \newcommand{\AliasingHarmonicIndex}{k} \newcommand{\AllGatherCompletionTime}{T_{\text{allgather}}} \newcommand{\AllOnesVector}{\mathbf{1}} \newcommand{\AllReduceCompletionTime}{T_{\text{allreduce}}} \newcommand{\AllReduceMinimumBandwidthTime}{T_{\text{bandwidth}}^{\text{min}}} \newcommand{\AllRunsPassEstimate}{\widehat{r}} \newcommand{\AllToAllCompletionTime}{T_{\text{alltoall}}} \newcommand{\AllToAllExchangeTime}{T} \newcommand{\AllocatedBlockCount}{N_{\text{blocks}}} \newcommand{\AllocatedHazardRate}{\lambda_{\text{alloc}}} \newcommand{\AllocatedWallTime}{T_{\text{wall}}} \newcommand{\AllowableCollisionEnergy}{E_{k, \text{allow}}} \newcommand{\AllowableRailDroop}{\Delta V_{\text{droop, max}}} \newcommand{\AllowableRailExcursion}{\Delta V_{\max}} \newcommand{\AllowableWindingTemperatureRise}{\Delta T_{\max}} \newcommand{\AllowedTokenSet}{\mathcal{V}_{\text{allow}}} \newcommand{\AllowedViolationFraction}{V^{\text{allow}}} \newcommand{\AlphabetByte}{b} \newcommand{\AlternateModelInput}{x'} \newcommand{\AmbientDimension}{D} \newcommand{\AmbientTemperature}{T_{\text{amb}}} \newcommand{\AmortizedTurnCost}{\bar{C}_{\text{turn}}} \newcommand{\AngularAcceleration}{\boldsymbol{\alpha}} \newcommand{\AngularClearance}{\theta_{\text{clear}}} \newcommand{\AngularClearanceRate}{\dot{\theta}_{\text{clear}}} \newcommand{\AngularFrequency}{\omega} \newcommand{\AngularSpeed}{\omega} \newcommand{\AngularVelocity}{\boldsymbol{\omega}} \newcommand{\AngularVelocityDerivative}{\dot{\boldsymbol{\omega}}} \newcommand{\AnnualQueryVolume}{Q_{\text{annual}}} \newcommand{\AnonymitySetSize}{k_{\text{anon}}} \newcommand{\AntiWindupTrackingTimeConstant}{T_t} \newcommand{\AntialiasingFilterVariance}{s} \newcommand{\ApiAccount}{u} \newcommand{\ApparentContrast}{C} \newcommand{\AppearanceRealityGap}{\Delta_{\text{vis}}} \newcommand{\AppliedForce}{F} \newcommand{\AppliedLoadCycleCount}{n} \newcommand{\ApproachChannelCount}{K_a} \newcommand{\ApproachDirection}{\hat{\mathbf{a}}_{\text{approach}}} \newcommand{\ApproachPosition}{x} \newcommand{\ApproachPredicate}{P_{\text{approach}}} \newcommand{\ApproachSpeed}{v_{\text{app}}} \newcommand{\ApprovalCatchFraction}{q} \newcommand{\ApprovalHeldTrajectories}{N_{\text{held}}} \newcommand{\ApproximatingDistribution}{q} \newcommand{\ArbitrationFieldBitCount}{B_{\text{arb},i}} \newcommand{\ArcObstacleDistance}{d_{\text{arc}}} \newcommand{\ArchitectureResourceCost}{C} \newcommand{\ArchitectureSearchSpace}{\mathcal{A}} \newcommand{\ArcsineEffectSize}{h} \newcommand{\ArgumentLegConfidence}{r} \newcommand{\ArgumentLegCount}{m} \newcommand{\ArithmeticIntensity}{I} \newcommand{\ArmStoppingDeceleration}{a_{\text{arm}}} \newcommand{\ArmSuccessProbability}{p} \newcommand{\ArmingSettleDuration}{t_{\text{settle}}} \newcommand{\ArrivalOffsetTravel}{\Delta x} \newcommand{\ArrivalRate}{\lambda_{\text{arr}}} \newcommand{\ArrivalStampOffset}{\Delta t_{\text{recv}}} \newcommand{\ArrivalTimestamp}{t_{\text{recv}}} \newcommand{\ArtifactVersion}{v} \newcommand{\AssessedContactForceLimit}{F_{\text{limit}}} \newcommand{\AssignedJobGpu}{g} \newcommand{\AssociationCostEntry}{c} \newcommand{\AssuranceClaim}{C} \newcommand{\AsymptoticTightBound}{\Theta} \newcommand{\AtmosphericExtinctionCoefficient}{\beta_{\text{atm}}} \newcommand{\AttackStepsPgd}{K_{\text{PGD}}} \newcommand{\AttackedTrialCount}{n} \newcommand{\AttainableComputeRate}{R_{\text{attain}}} \newcommand{\AttemptCleanupCost}{C_{\text{cleanup}}} \newcommand{\AttemptCost}{C_{\text{attempt}}} \newcommand{\AttemptCycleDuration}{t_{\text{cyc}}} \newcommand{\AttemptDuration}{t_{\text{att}}} \newcommand{\AttemptGenerationTime}{T_{\text{gen}}} \newcommand{\AttemptPassProbability}{p} \newcommand{\AttemptRuntimeOverheadCost}{C_{\text{runtime}}} \newcommand{\AttemptVerificationCost}{C_{\text{verify}}} \newcommand{\AttentionHeadCount}{N_{\text{heads}}} \newcommand{\AttentionHeadDimension}{d_{\text{head}}} \newcommand{\AttentionHeadIndex}{i} \newcommand{\AttentionHeadOutput}{\mathbf{O}} \newcommand{\AttentionKeyMatrix}{\mathbf{K}} \newcommand{\AttentionOutputMatrix}{\mathbf{O}} \newcommand{\AttentionOutputProjectionMatrix}{\mathbf{W}_{O}} \newcommand{\AttentionQueryMatrix}{\mathbf{Q}} \newcommand{\AttentionScoreEntry}{S_{ij}} \newcommand{\AttentionScoreMatrix}{\mathbf{S}} \newcommand{\AttentionScoreRow}{\mathbf{S}_{i, \cdot}} \newcommand{\AttentionScoreSummand}{S_{ik}} \newcommand{\AttentionScoreTile}{\mathbf{S}_{ij}} \newcommand{\AttentionValuesMatrix}{\mathbf{V}} \newcommand{\AttentionValuesProjectionMatrix}{\mathbf{W}_{V}} \newcommand{\AttentionValuesSourceMatrix}{\mathbf{X}_{V}} \newcommand{\AttentionValuesVector}{\mathbf{v}} \newcommand{\AttentionWeightEntry}{A_{ij}} \newcommand{\AttentionWeightMatrix}{\mathbf{A}} \newcommand{\AttentionWeightVector}{\mathbf{a}} \newcommand{\AttitudeError}{\theta_{\text{att}}} \newcommand{\AttributionFeatureCount}{n_{\text{feat}}} \newcommand{\AuditGroupRecordCount}{n_{\text{records}}} \newcommand{\AuthorityExposureLevel}{A} \newcommand{\AutocorrelationLagIndex}{k} \newcommand{\AutoencoderReconstructionError}{\mathcal{L}_{\text{rec}}} \newcommand{\AutomatedResetTime}{t_{\text{reset,auto}}} \newcommand{\AutomatonStateSet}{Q} \newcommand{\AutomatonTransitionFunction}{\delta} \newcommand{\AutonomousExecutionComputeCost}{C_{\text{compute}}} \newcommand{\AutoscalingDecisionTime}{T_{\text{decide}}} \newcommand{\AutoscalingDetectionTime}{T_{\text{detect}}} \newcommand{\AutoscalingResponseTime}{T_{\text{response}}} \newcommand{\AvailabilityObjective}{S_{\text{availability}}} \newcommand{\AvailableBrakingDistance}{D_{\text{avail}}} \newcommand{\AvailableDeceleration}{a} \newcommand{\AvailableObservations}{\mathcal{O}_{\text{avail}}} \newcommand{\AverageCopperLossPower}{\bar{P}_{\text{loss}}} \newcommand{\AverageOnlineRegret}{\gamma_N} \newcommand{\AveragePower}{P_{\text{avg}}} \newcommand{\AverageStateVisitationDistribution}{\bar{d}} \newcommand{\AxiBurstLength}{A_{\text{len}}} \newcommand{\AxisGridPointCount}{N} \newcommand{\AzimuthAngle}{\theta_{\text{az}}} \newcommand{\BackEmfVoltage}{e_{\text{bemf}}} \newcommand{\BacklashAngle}{\theta_{\text{backlash}}} \newcommand{\BackwardEulerEigenvalue}{\lambda_{\text{BE}}} \newcommand{\BackwardEulerTransitionMatrix}{\mathbf{A}_{\text{BE}}} \newcommand{\BackwardPassTime}{T_{\text{backward}}} \newcommand{\BackwardReachableTube}{\mathcal{R}} \newcommand{\BalanceDivergenceTime}{\tau_{\text{fall}}} \newcommand{\BallRadius}{r} \newcommand{\BallVolume}{V_D} \newcommand{\Bandwidth}{\text{BW}} \newcommand{\BankConflictPenalty}{\Delta t_{\text{conflict}}} \newcommand{\BarrierConstraintBound}{b_{\text{cbf}}} \newcommand{\BarrierConstraintCount}{K_b} \newcommand{\BarrierConstraintNormal}{\mathbf{a}_{\text{cbf}}} \newcommand{\BarrierFunction}{h} \newcommand{\BarrierFunctionRate}{\dot{h}} \newcommand{\BarrierHalfSpaceControlSet}{\mathcal{U}_{\text{safe}}} \newcommand{\BarrierMargin}{\delta} \newcommand{\BarrierNormalizationScale}{h_{\text{scale}}} \newcommand{\BarrierProjectionLagrangian}{L_{\text{Lag}}} \newcommand{\BarrierProjectionMultiplier}{\lambda} \newcommand{\BarrierRelativeDegree}{r} \newcommand{\BaseAbscissaVelocity}{\dot{x}} \newcommand{\BaseAccelerationCommand}{a} \newcommand{\BaseBatchSize}{B_{\text{base}}} \newcommand{\BaseCameraRotation}{\mathbf{R}_{\text{base}}^{\text{cam}}} \newcommand{\BaseCameraTransform}{\mathbf{T}_{\text{base}}^{\text{cam}}} \newcommand{\BaseCameraTranslation}{\mathbf{t}_{\text{base}}^{\text{cam}}} \newcommand{\BaseFlangeTransform}{\mathbf{T}_{\text{base}}^{\text{flange}}} \newcommand{\BaseForwardSpeed}{v} \newcommand{\BaseFramePoint}{\mathbf{p}_{\text{base}}} \newcommand{\BaseHeadingRate}{\dot{\theta}_{\text{head}}} \newcommand{\BaseJointInertiaCoupling}{\mathbf{M}_{bj}} \newcommand{\BaseLateralPosition}{y_{\text{base}}} \newcommand{\BaseLateralVelocity}{\dot{y}} \newcommand{\BaseLayerCount}{N_{L,0}} \newcommand{\BaseLearningRate}{\eta_{\text{base}}} \newcommand{\BaseLongitudinalPosition}{x_{\text{base}}} \newcommand{\BaseLongitudinalVelocity}{\dot{x}} \newcommand{\BaseOdometrySpeed}{v} \newcommand{\BaseOrdinateVelocity}{\dot{y}} \newcommand{\BasePosition}{\mathbf{p}_{\text{base}}} \newcommand{\BasePromptLength}{S_{\text{base}}} \newcommand{\BaseStoppingDistance}{d_{\text{base}}} \newcommand{\BaseToCameraTransform}{\mathbf{T}_{\text{cam} \leftarrow \text{base}}} \newcommand{\BaseTrainingComputeCost}{C_{\text{compute}}} \newcommand{\BaseTrajectoryTokenCount}{N_{\text{base}}} \newcommand{\BaseTravelDistance}{d} \newcommand{\BaseTravelSpeed}{v_{\text{base}}} \newcommand{\BaseWidthMultiplier}{w_{\text{mult},0}} \newcommand{\BaseWorkerCount}{N_{\text{base}}} \newcommand{\BaseWristTransform}{\mathbf{T}_{\text{base} \leftarrow \text{wrist}}} \newcommand{\BaseYawRateBias}{\omega_{\text{bias}}} \newcommand{\BaselineAcceptanceEstimate}{\hat{p}_{\text{base}}} \newcommand{\BaselineAnnualOperationsCost}{C_{\text{current}}} \newcommand{\BaselineControllerAction}{\mathbf{a}_t^{\text{base}}} \newcommand{\BaselineConversionRate}{p_0} \newcommand{\BaselineFeatureMean}{\mu_{\text{base}}} \newcommand{\BaselineFeatureStandardDeviation}{\sigma_{\text{base}}} \newcommand{\BaselineIntervalLowerLimit}{l_{\text{base}}} \newcommand{\BaselineIntervalUpperLimit}{u_{\text{base}}} \newcommand{\BaselineLowerLimitDistance}{\delta^-_{\text{base}}} \newcommand{\BaselineOnlyAcceptedTaskCount}{b} \newcommand{\BaselineOnlyCorrectCount}{n_{\text{base}}} \newcommand{\BaselinePolicyAcceptanceProbability}{p_{X}} \newcommand{\BaselinePolicyCost}{C_{X}} \newcommand{\BaselineStateDistribution}{d^{\pi_{\text{base}}}} \newcommand{\BaselineTaskCost}{C_{\text{task, base}}} \newcommand{\BaselineToolCallDistribution}{p_{b}} \newcommand{\BaselineTrackingError}{e_{\text{track}}} \newcommand{\BaselineTrainingDuration}{T_{\text{hours}}} \newcommand{\BaselineTrajectoryGoodput}{\mathcal{G}_{b}} \newcommand{\BaselineUpperLimitDistance}{\delta^+_{\text{base}}} \newcommand{\BatchArrivalRate}{\lambda_{\text{batch}}} \newcommand{\BatchAxisLabel}{b} \newcommand{\BatchBufferMemory}{M_{\text{batch}}} \newcommand{\BatchCostPerAcceptedTask}{C_{\text{eff,batch}}} \newcommand{\BatchDataVolume}{D_{\text{vol}}^{(\text{batch})}} \newcommand{\BatchExampleIndex}{n} \newcommand{\BatchFetchTime}{T_{\text{fetch}}} \newcommand{\BatchFillArrivalCount}{k} \newcommand{\BatchFixedOverheadTime}{T_{\text{fixed}}} \newcommand{\BatchFlushStartTime}{t_{\text{start}}} \newcommand{\BatchFormationDelay}{L_{\text{lat,form}}} \newcommand{\BatchIndex}{k} \newcommand{\BatchLabelComponent}{y_{ij}} \newcommand{\BatchLatencyEnvelope}{L_{\text{lat,envelope}}} \newcommand{\BatchLoss}{\mathcal{L}_{\text{batch}}} \newcommand{\BatchMaxOutputLength}{S_{\text{max}}} \newcommand{\BatchMaximumDeviationMultiple}{k} \newcommand{\BatchMeanOutputLength}{\bar{S}} \newcommand{\BatchNormMean}{\mu_{\mathcal{B}}} \newcommand{\BatchNormOutput}{y} \newcommand{\BatchNormRunningMean}{\boldsymbol{\mu}_{\mathcal{B}}} \newcommand{\BatchNormRunningStandardDeviation}{\boldsymbol{\sigma}_{\mathcal{B}}} \newcommand{\BatchNormStandardDeviation}{\sigma_{\mathcal{B}}} \newcommand{\BatchOperations}{O_{\text{batch}}} \newcommand{\BatchPredictedProbability}{\hat{y}_{ij}} \newcommand{\BatchProcessingTime}{T_{\text{process}}} \newcommand{\BatchRolloutCount}{N_{\text{batch}}} \newcommand{\BatchScalingFactor}{k} \newcommand{\BatchServiceTime}{T_{\text{svc}}} \newcommand{\BatchSize}{B} \newcommand{\BatchTransferTime}{T_{\text{transfer}}} \newcommand{\BatchedDecodeStepTime}{t_{\text{step}}} \newcommand{\BatchedEventIndex}{i} \newcommand{\BatchedRequestLatency}{L_{\text{lat,batch}}} \newcommand{\BatchingLatencyBudget}{L_{\text{lat,budget}}} \newcommand{\BatchingQueueWait}{L_{\text{lat,wait}}} \newcommand{\BatchingWindow}{T_{\text{window}}} \newcommand{\BatteryCellResistance}{R_{\text{cell}}} \newcommand{\BeamDivergenceAngle}{\delta\theta_{\text{div}}} \newcommand{\BeamWidth}{W} \newcommand{\BearingRay}{\mathbf{r}} \newcommand{\BeatFrequency}{f_b} \newcommand{\BehaviorCloningHorizon}{S} \newcommand{\BehaviorCloningLoss}{\mathcal{L}_{\text{BC}}} \newcommand{\BehaviorDistribution}{b} \newcommand{\BehaviorPolicyVersion}{\text{ver}_b} \newcommand{\BeliefErrorBound}{E} \newcommand{\BeliefInvalidationHorizon}{T_{\text{inv}}} \newcommand{\BeliefState}{b} \newcommand{\BellmanBackupTarget}{y} \newcommand{\BellmanErrorLoss}{\mathcal{L}_{\text{Bellman}}} \newcommand{\BelowThresholdIndicator}{\mathbf{1}_{\{|(\mathbf{W}_{\text{sparse}})_{ij}| \leq \delta_{\text{prune}}\}}} \newcommand{\BestEffortWireBitCount}{B_{\text{BE,wire}}} \newcommand{\BetterArmSuccessProbability}{p_{\text{high}}} \newcommand{\BetweenTaskStandardDeviation}{\sigma_{\text{task}}} \newcommand{\BevPillarFeature}{\mathbf{V}_{\text{BEV}}} \newcommand{\BevPillarXIndex}{X} \newcommand{\BevPillarYIndex}{Y} \newcommand{\BiasFeedbackFactor}{\alpha_{\text{fb}}} \newcommand{\BiasVector}{\mathbf{b}} \newcommand{\BilledAllocationTime}{T_{\text{total}}} \newcommand{\BinaryActivationVector}{\mathbf{a}} \newcommand{\BinaryClassifier}{h} \newcommand{\BinaryWeightVector}{\mathbf{w}} \newcommand{\BinomialSuccessCount}{X} \newcommand{\BipedTiltAcceleration}{\ddot{\theta}_{\text{tilt}}} \newcommand{\BisectionBandwidth}{\text{BW}_{\text{bisect}}} \newcommand{\BitFlippedFloatNumber}{x_{\text{corrupt}}} \newcommand{\BitTime}{T_{\text{bit}}} \newcommand{\BlackoutClockConversionError}{\Delta t_{\text{one-sigma scenario}}} \newcommand{\BlendDeadline}{t_{\text{blend}}} \newcommand{\BlendedCommandJerk}{j_{\text{cmd}}} \newcommand{\BlendedControlCommand}{\mathbf{u}_{\text{blend}}} \newcommand{\BlendedInputTokenPrice}{c_{\text{in}}} \newcommand{\BlendingTransitionWindow}{\tau_{\text{blend}}} \newcommand{\BlindTravelDistance}{d_{\text{blind}}} \newcommand{\BlockCheckTime}{T_{\text{ver}}} \newcommand{\BlockCoordinateX}{b_x} \newcommand{\BlockCoordinateY}{b_y} \newcommand{\BlockCoordinateZ}{b_z} \newcommand{\BlockEdgeVoxelCount}{n_{\text{blk}}} \newcommand{\BlockMaximum}{M} \newcommand{\BlockMaximumLevel}{z} \newcommand{\BlockMaximumLimitDistribution}{G} \newcommand{\BlockMaximumNormalizingScale}{a} \newcommand{\BlockMaximumNormalizingShift}{b} \newcommand{\BlockMetadataSize}{s_{\text{meta}}} \newcommand{\BlockQuantizationScale}{s_b} \newcommand{\BlockRangeMaximum}{x_{\max,i}} \newcommand{\BlockRangeMinimum}{x_{\min,i}} \newcommand{\BlockSampleCount}{n} \newcommand{\BlockedWorkerCount}{N_{\text{blocked}}} \newcommand{\BlockingCallTimeout}{T_{\text{out}}} \newcommand{\BlockingTaskIndex}{k} \newcommand{\BodyAcceleration}{\dot{v}} \newcommand{\BodyDisplacement}{x} \newcommand{\BodyEndEffectorTransform}{\mathbf{T}_{BE}} \newcommand{\BodyFramePoint}{\mathbf{p}_{\text{body}}} \newcommand{\BodyFramePointCovariance}{\boldsymbol{\Sigma}_{\text{body}}} \newcommand{\BodyLidarTransform}{\mathbf{T}_{bl}} \newcommand{\BodyReferenceFrame}{\mathcal{F}_B} \newcommand{\BodyRegionMass}{m_H} \newcommand{\BodySpeed}{v} \newcommand{\BoltzmannConstant}{k_B} \newcommand{\BoltzmannStateEnergy}{E} \newcommand{\BoltzmannTemperature}{T} \newcommand{\BootstrapQuantileFunction}{Q} \newcommand{\BootstrapReplicateCount}{B_{\text{boot}}} \newcommand{\BootstrapReplicateIndex}{r} \newcommand{\BottomedOutContactStiffness}{k_{\infty}} \newcommand{\BouligandContingentCone}{T_{\mathcal{C}}} \newcommand{\BoundaryConditionVector}{\mathbf{b}} \newcommand{\BoundaryLayerTime}{t_{\text{fast}}} \newcommand{\BoundedRegimeTimestamp}{t_{\text{bounded}}} \newcommand{\BoxMaximumHorizontalCoordinate}{x_{\text{max}}} \newcommand{\BoxMaximumVerticalCoordinate}{y_{\text{max}}} \newcommand{\BoxMinimumHorizontalCoordinate}{x_{\text{min}}} \newcommand{\BoxMinimumVerticalCoordinate}{y_{\text{min}}} \newcommand{\BrakeChopperResistance}{R_{\text{brake}}} \newcommand{\BrakeCommandForce}{F_{\text{cmd}}} \newcommand{\BrakeResistorPulseEnergy}{E_{\text{pulse}}} \newcommand{\BrakingDistance}{d_{\text{brake}}} \newcommand{\BrakingForce}{F_{\text{brake}}} \newcommand{\BrakingOnsetContactForce}{F_{\text{cmd}}} \newcommand{\BrakingWork}{W_{\text{brake}}} \newcommand{\BreadthCriticalPathLatency}{T^{\text{breadth}}} \newcommand{\BreadthPeakKvCacheMemory}{M_{\text{KV}}^{\text{breadth}}} \newcommand{\BreakEvenAcceptanceProbability}{p'} \newcommand{\BreakEvenBrakingDeceleration}{a} \newcommand{\BreakEvenParseFailureRate}{p_{\text{break}}} \newcommand{\BreakEvenTaskCount}{N^*} \newcommand{\BreakEvenUtilization}{u^*} \newcommand{\BreakerCooldownInterval}{T_{\text{cool}}} \newcommand{\BreakerFailureFraction}{r} \newcommand{\BreakerMinimumSampleCount}{n_{\min}} \newcommand{\BreakerOutcomeIndex}{i} \newcommand{\BreakerOutcomeWindow}{W} \newcommand{\BreakerTripThreshold}{r_{\text{trip}}} \newcommand{\BridgeTraceResistance}{R_{\text{trace}}} \newcommand{\BroadcastColumnElement}{A} \newcommand{\BroadcastColumnTensor}{\mathbf{A}} \newcommand{\BroadcastCompletionTime}{T_{\text{broadcast}}} \newcommand{\BroadcastRowElement}{b} \newcommand{\BroadcastRowTensor}{\mathbf{B}} \newcommand{\BroadcastTableSize}{s_{\text{table}}} \newcommand{\BspLearningRate}{\eta_{\text{BSP}}} \newcommand{\BsplineBasisFunction}{B} \newcommand{\BudgetEvaluationTime}{\tau} \newcommand{\BudgetFreeBalance}{F} \newcommand{\BudgetNodeIndex}{k} \newcommand{\BudgetReservedFunds}{R} \newcommand{\BudgetSettledCharges}{E} \newcommand{\BudgetedAcceptanceProbability}{q_{\pi}} \newcommand{\BufferDependencyEdgeSet}{E} \newcommand{\BufferDependencyGraph}{G} \newcommand{\BufferDependencyVertexSet}{V} \newcommand{\BufferIndex}{i} \newcommand{\BulkDecouplingCapacitance}{C_{\text{bulk}}} \newcommand{\BumplessTransferBlend}{\alpha} \newcommand{\BumplessTransferBlendAcceleration}{\ddot{\alpha}} \newcommand{\BumplessTransferBlendRate}{\dot{\alpha}} \newcommand{\BumplessTransferBlendSlope}{\alpha'} \newcommand{\BumplessTransferProgress}{\hat{t}} \newcommand{\BumplessTransferStartInstant}{t_{\text{start}}} \newcommand{\BurstArrivalCount}{N_{\text{burst}}} \newcommand{\BurstSurvivalTime}{t_{\text{limit}}} \newcommand{\BusBitRate}{R_{\text{bit}}} \newcommand{\BusCapacitorEnergy}{E_C} \newcommand{\BusCapacitorVoltage}{V_C} \newcommand{\BusSerializationTime}{t_{\text{bus}}} \newcommand{\ButterflyAllReduceTime}{T_{\text{butterfly}}} \newcommand{\ByteAlphabet}{\Sigma} \newcommand{\ByteString}{u} \newcommand{\ByzantineClientCount}{f} \newcommand{\ByzantineFaultCount}{f} \newcommand{\CableFlexCycleCount}{n_{\text{cable}}} \newcommand{\CableRatedFatigueLife}{L_{\text{cable}}} \newcommand{\CacheMissStallFraction}{f} \newcommand{\CachedInputTokenCount}{n_{\text{cache}}} \newcommand{\CachedInputTokenPrice}{c_{\text{cache}}} \newcommand{\CalibratedAcceptanceEstimate}{\hat{p}} \newcommand{\CalibrationBinCount}{N_{\text{bins}}} \newcommand{\CalibrationBinExampleSet}{B_m} \newcommand{\CalibrationBinIndex}{m} \newcommand{\CalibrationConstraintMatrix}{\mathbf{V}} \newcommand{\CalibrationDataDistribution}{p_{\text{cal}}} \newcommand{\CalibrationDataset}{\mathcal{C}_{\text{cal}}} \newcommand{\CalibrationExampleCount}{n_{\text{cal}}} \newcommand{\CalibrationModelPoint}{\mathbf{M}} \newcommand{\CalibrationPoseIndex}{k} \newcommand{\CalibrationRotationAxisCount}{N} \newcommand{\CalibrationSceneIndex}{j} \newcommand{\CalibrationTemperature}{T_{\text{cal}}} \newcommand{\CalibrationViewCount}{N} \newcommand{\CallLatency}{T_{\text{call}}} \newcommand{\CallPostprocessingTime}{T_{\text{post}}} \newcommand{\CallPreparationTime}{T_{\text{prep}}} \newcommand{\CallTailProbability}{p_{\text{tail}}} \newcommand{\CallUsefulWorkTime}{W} \newcommand{\CameraCenterArcPosition}{x_{\text{rot}}} \newcommand{\CameraExtrinsicRotation}{\mathbf{R}_{bc}} \newcommand{\CameraExtrinsicTransform}{\mathbf{T}_{bc}} \newcommand{\CameraExtrinsicTranslation}{\mathbf{p}_{bc}} \newcommand{\CameraFrameDepth}{Z_c} \newcommand{\CameraFrameHorizontalCoordinate}{X_c} \newcommand{\CameraFramePeriod}{T_{\text{sample}}} \newcommand{\CameraFramePoint}{\mathbf{p}_c} \newcommand{\CameraFramePointCovariance}{\boldsymbol{\Sigma}_c} \newcommand{\CameraFrameVerticalCoordinate}{Y_c} \newcommand{\CameraIdentifierEmbedding}{\mathbf{e}_{\text{cam}}} \newcommand{\CameraImage}{\mathbf{I}} \newcommand{\CameraImuTimeOffset}{\Delta t_{\text{imu}}} \newcommand{\CameraIntrinsicCalibrationMatrix}{\mathbf{K}} \newcommand{\CameraIntrinsicInverseTranspose}{\mathbf{K}^{-\top}} \newcommand{\CameraLateralStandardDeviation}{\sigma_{x_c}} \newcommand{\CameraMountTiltAngle}{\theta_{\text{ext}}} \newcommand{\CameraObjectTransform}{\mathbf{T}_{\text{camera}}^{\text{object}}} \newcommand{\CameraOpticalCenter}{\mathbf{o}} \newcommand{\CameraReferenceFrame}{\mathcal{F}_{\text{cam}}} \newcommand{\CameraRotationColumn}{\mathbf{r}} \newcommand{\CameraSampleTimestamp}{t_{\text{cam}}} \newcommand{\CameraSkewCoefficient}{\gamma} \newcommand{\CameraTargetTransform}{\mathbf{T}_{\text{cam}}^{\text{target}}} \newcommand{\CameraToWorldRotation}{\mathbf{R}_{WC}} \newcommand{\CameraToWorldTransform}{\mathbf{T}_{WC}} \newcommand{\CameraToWorldTranslation}{\mathbf{t}_{WC}} \newcommand{\CampaignActiveTime}{T_{\text{active}}} \newcommand{\CanHighLineVoltage}{V_{\text{CANH}}} \newcommand{\CanLowLineVoltage}{V_{\text{CANL}}} \newcommand{\CanaryAllocationFraction}{\rho} \newcommand{\CanaryInterventionRate}{\lambda_{\text{canary}}} \newcommand{\CanaryLabelDelay}{t_{\text{label}}} \newcommand{\CanarySpeedBound}{v_{\text{canary}}} \newcommand{\CanaryStageDuration}{T_{\text{stage}}} \newcommand{\CanaryTrafficFraction}{p_{\text{stage}}} \newcommand{\CandidateAcceptanceEstimate}{\hat{p}_{\text{cand}}} \newcommand{\CandidateActionVector}{\hat{\mathbf{a}}} \newcommand{\CandidateArchitecture}{a} \newcommand{\CandidateAvailabilityEstimate}{\widehat{q}} \newcommand{\CandidateAvailabilityProbability}{q} \newcommand{\CandidateCheckingCost}{v} \newcommand{\CandidateClientCount}{K_{\text{candidates}}} \newcommand{\CandidateControlCommand}{\mathbf{u}^{\text{cand}}} \newcommand{\CandidateControlCommandDerivative}{\dot{\mathbf{u}}^{\text{cand}}} \newcommand{\CandidateDefectRate}{\epsilon} \newcommand{\CandidateGenerationCost}{g} \newcommand{\CandidateIndex}{i} \newcommand{\CandidateIntervalLowerLimit}{l_{\text{cand}}} \newcommand{\CandidateIntervalUpperLimit}{u_{\text{cand}}} \newcommand{\CandidateLowerLimitDistance}{\delta^-_{\text{cand}}} \newcommand{\CandidateOnlyAcceptedTaskCount}{c} \newcommand{\CandidatePolicyAcceptanceProbability}{p_{Y}} \newcommand{\CandidatePolicyAction}{\mathbf{a}_t^{\text{cand}}} \newcommand{\CandidatePolicyCost}{C_{Y}} \newcommand{\CandidatePoolSize}{N} \newcommand{\CandidateProposal}{p} \newcommand{\CandidateRoutingPolicy}{Y} \newcommand{\CandidateScoreVector}{\mathbf{c}} \newcommand{\CandidateScoringCost}{c_{\text{infer}}} \newcommand{\CandidateScoringError}{\epsilon} \newcommand{\CandidateSkill}{a} \newcommand{\CandidateSpeedCommand}{v_{\text{cand}}} \newcommand{\CandidateTailCompletionTime}{\widehat{T}_{c,0.99}} \newcommand{\CandidateToolCallDistribution}{p_{c}} \newcommand{\CandidateTrackingErrorStandardDeviation}{\sigma_{\text{track}}} \newcommand{\CandidateTrajectoryGoodput}{\mathcal{G}_{c}} \newcommand{\CandidateUpperLimitDistance}{\delta^+_{\text{cand}}} \newcommand{\CandidateUtility}{U} \newcommand{\CandidateUtilityMean}{\mu} \newcommand{\CandidateUtilityStandardDeviation}{\sigma_{U}} \newcommand{\CandidateViolationCount}{V_{c}} \newcommand{\CandidateWinCount}{j} \newcommand{\CapabilityGrant}{\Gamma} \newcommand{\CaptureAgeEmbedding}{\mathbf{e}_{\Delta t}} \newcommand{\CaptureSampleIndex}{t_0} \newcommand{\CaptureSampleKalmanGain}{\mathbf{G}_{t_0}} \newcommand{\CaptureSampleMeasurementMatrix}{\mathbf{H}_{t_0}} \newcommand{\CaptureSamplePredictedCovariance}{\mathbf{P}_{t_0|t_0-1}} \newcommand{\CaptureSamplePredictedEstimate}{\hat{\mathbf{x}}_{t_0|t_0-1}} \newcommand{\CaptureSampleUpdatedCovariance}{\mathbf{P}_{t_0|t_0}} \newcommand{\CaptureSampleUpdatedEstimate}{\hat{\mathbf{x}}_{t_0|t_0}} \newcommand{\CaptureTimestamp}{t_{\text{capture}}} \newcommand{\CapturedSensorObservation}{\mathbf{z}_{t_0}} \newcommand{\CartesianAcceleration}{\ddot{\mathbf{p}}} \newcommand{\CartesianPosition}{\mathbf{p}} \newcommand{\CartesianXCoordinate}{x} \newcommand{\CartesianYCoordinate}{y} \newcommand{\CartesianZCoordinate}{z} \newcommand{\CascadeEscalationProbability}{p_{\text{escalate}}} \newcommand{\CascadeGateCost}{g} \newcommand{\CascadeGateDuration}{v} \newcommand{\CascadeInferenceEnergy}{E_{\text{cascade}}} \newcommand{\CascadeTaskCost}{C_{\text{cascade}}} \newcommand{\CascadeTaskDuration}{T_{\text{cascade}}} \newcommand{\CascadeTierCost}{c^{\text{tier}}} \newcommand{\CascadeTierDuration}{t} \newcommand{\CascadeTierIndex}{j} \newcommand{\CascadedBarrierCertificate}{\psi} \newcommand{\CascadedBarrierClassKFunction}{\alpha} \newcommand{\CascadedBarrierDerivative}{\dot{\psi}} \newcommand{\CaseAmbientThermalResistance}{R_{\text{th,case-amb}}} \newcommand{\CaseTemperature}{T_{\text{case}}} \newcommand{\CaseThermalCapacitance}{C_{\text{case}}} \newcommand{\CaseThermalTimeConstant}{\tau_{\text{th,case}}} \newcommand{\CatalogDefinitionTokens}{S_{\text{catalog}}} \newcommand{\CatalogStagingCallCount}{N} \newcommand{\CategoryRecordCount}{n} \newcommand{\CausalInterventionMask}{\mathcal{M}} \newcommand{\CausalMediator}{M} \newcommand{\CausalTokenPosition}{s} \newcommand{\CbsRuntimeBudget}{Q} \newcommand{\CellOccupancyProbability}{p} \newcommand{\CenterCount}{k} \newcommand{\CentralizedTrainingEnergy}{E_{\text{centralized}}} \newcommand{\CentroidalAngularMomentum}{\mathbf{h}_{\text{ang}}} \newcommand{\CentroidalAngularMomentumDerivative}{\dot{\mathbf{h}}_{\text{ang}}} \newcommand{\CentroidalLinearMomentum}{\mathbf{h}_{\text{lin}}} \newcommand{\CentroidalLinearMomentumDerivative}{\dot{\mathbf{h}}_{\text{lin}}} \newcommand{\CentroidalMomentum}{\mathbf{h}_G} \newcommand{\CentroidalMomentumMatrix}{\mathbf{A}_G} \newcommand{\CentroidalMomentumMatrixDerivative}{\dot{\mathbf{A}}_G} \newcommand{\CentroidalMomentumRate}{\dot{\mathbf{h}}_G} \newcommand{\CertifiedCommandWindow}{\mathbf{u}^*_{t:t+H-1}} \newcommand{\CertifiedControlAction}{\mathbf{u}^*} \newcommand{\CertifiedJointTorque}{u^*} \newcommand{\CertifiedRadius}{R} \newcommand{\ChainRuleInput}{x} \newcommand{\ChainRuleIntermediate}{u} \newcommand{\ChainRuleOutput}{v} \newcommand{\ChainedOperationCount}{n_{\text{ops}}} \newcommand{\ChanceAnnotatorAgreement}{p_e} \newcommand{\ChannelAuthorityState}{S} \newcommand{\ChannelCommand}{u} \newcommand{\ChannelStoredEnergy}{E_{\text{channel}}} \newcommand{\CharacteristicPolynomial}{p} \newcommand{\CharacteristicPolynomialCoefficient}{c} \newcommand{\ChassisThermalResistance}{R_{\text{th,chassis}}} \newcommand{\CheapConfigurationAttemptCost}{c_{\text{small}}} \newcommand{\CheapConfigurationPassProbability}{p_{\text{small}}} \newcommand{\CheckIntervalStepCount}{m} \newcommand{\CheckPassProbability}{p^{\text{chk}}} \newcommand{\CheckSlotTime}{T} \newcommand{\CheckWindowTurnCount}{w} \newcommand{\CheckedSignal}{x} \newcommand{\CheckedSignalLimit}{L_{\text{limit}}} \newcommand{\CheckpointAttemptDuration}{T_{\text{att}}} \newcommand{\CheckpointExtraPauseTime}{T_{\text{pause}}} \newcommand{\CheckpointInterval}{T_{\text{ckpt}}} \newcommand{\CheckpointLoadTime}{T_{\text{load}}} \newcommand{\CheckpointLogPosition}{j_{\text{ckpt}}} \newcommand{\CheckpointOrdinalIndex}{m} \newcommand{\CheckpointOverheadFraction}{f_{\text{ckpt}}} \newcommand{\CheckpointOverheadRatio}{w} \newcommand{\CheckpointRecoveryOverheadTime}{T_{\text{overhead}}} \newcommand{\CheckpointRestoreTime}{T_{\text{restore}}} \newcommand{\CheckpointStride}{k} \newcommand{\CheckpointSuffixReadTime}{T_{\text{read}}} \newcommand{\CheckpointWasteFraction}{W} \newcommand{\CheckpointWriteTime}{T_{\text{write}}} \newcommand{\ChildBatchSize}{n_{\text{batch}}} \newcommand{\ChildBudgetAllocation}{C_{\max,C}} \newcommand{\ChildCapabilityGrant}{\Gamma_{\text{child}}} \newcommand{\ChildFreeBalance}{F_{C}} \newcommand{\ChildPruningProbability}{p_{\text{prune}}} \newcommand{\ChildReservedFunds}{R_{C}} \newcommand{\ChildSettledCharges}{E_{C}} \newcommand{\ChinchillaIrreducibleLoss}{E} \newcommand{\ChirpDuration}{T_c} \newcommand{\ChirpSlope}{S} \newcommand{\ChopperClampVoltage}{V_{\text{clamp}}} \newcommand{\ChopperTurnOffVoltage}{V_{\text{clamp,off}}} \newcommand{\ChopperTurnOnVoltage}{V_{\text{clamp,on}}} \newcommand{\ChunkActionDimension}{d_{\text{chunk}}} \newcommand{\ChunkEnsemblingWeight}{w} \newcommand{\ChunkExecutionHorizon}{H_{\text{exec}}} \newcommand{\ChunkImitationLoss}{\mathcal{L}_{\text{chunk}}} \newcommand{\ChunkLease}{T_{\text{lease}}} \newcommand{\ChunkLeaseTime}{T_{\text{lease}}} \newcommand{\ChunkReactionLatency}{T_{\text{reaction}}} \newcommand{\ChunkRenewalPeriod}{T_{\text{chunk}}} \newcommand{\ChunkRenewalRate}{f_{\text{replan}}} \newcommand{\ChunkStepIndex}{i} \newcommand{\ClampedControlCommand}{\mathbf{u}_{\text{clip}}} \newcommand{\ClassCount}{K} \newcommand{\ClassIndex}{j} \newcommand{\ClassKFunction}{\kappa} \newcommand{\ClassKFunctionSet}{\mathcal{K}} \newcommand{\ClassProbabilityVector}{\mathbf{p}} \newcommand{\ClassificationThreshold}{\gamma_{\text{cls}}} \newcommand{\CleanLabelSampleCount}{D_{\text{clean}}} \newcommand{\CleanTrainingDataset}{\mathcal{S}} \newcommand{\CleanupGraphEdgeSet}{E} \newcommand{\CleanupGraphVertexSet}{V} \newcommand{\ClearDistance}{D_{\text{clear}}} \newcommand{\ClearanceAcceleration}{\ddot{D}_{\text{clear}}} \newcommand{\ClearanceAllowance}{C} \newcommand{\ClearanceExhaustionTime}{t_{\text{impact}}} \newcommand{\ClearanceInset}{C_{\text{inset}}} \newcommand{\ClearanceQueryTime}{t_{\text{query}}} \newcommand{\ClearanceRate}{\dot{D}_{\text{clear}}} \newcommand{\ClearanceSpeedClamp}{v_{\text{clamp}}} \newcommand{\ClearanceTimeBudget}{T_{\text{total}}} \newcommand{\ClfClassKFunction}{\alpha_V} \newcommand{\ClfDescentControlSet}{\mathcal{U}_{\text{CLF}}} \newcommand{\ClientGradientVector}{\mathbf{g}} \newcommand{\ClientIndex}{k} \newcommand{\ClientLocalDataset}{\mathcal{D}} \newcommand{\ClientLocalTrainingEnergy}{E_{\text{client}}} \newcommand{\ClientMaskVector}{\mathbf{r}} \newcommand{\ClientObjectiveWeight}{w} \newcommand{\ClientSampleCount}{n} \newcommand{\ClientUpdateUploadEnergy}{E_{\text{upload}}} \newcommand{\ClippedSurrogateObjective}{\mathcal{M}} \newcommand{\ClippingRangeLowerBound}{\alpha} \newcommand{\ClippingRangeUpperBound}{\beta} \newcommand{\ClockConversionBound}{\epsilon_{\text{sync}}} \newcommand{\ClockConversionIntercept}{b_{\text{clk}}} \newcommand{\ClockConversionSlope}{a} \newcommand{\ClockFrequency}{f} \newcommand{\ClockOffset}{\theta_{\text{offset}}} \newcommand{\ClockPeriod}{T_{\text{clk}}} \newcommand{\ClockSynchronizationSkew}{\delta_{\text{skew}}} \newcommand{\ClosedLoopTrajectoryDensity}{p_{\text{cl}}} \newcommand{\ClosingSpeedBound}{v_{\text{close}}} \newcommand{\CloudInferenceEnergy}{E_{\text{cloud}}} \newcommand{\CloudOffloadEnergy}{E_{\text{transmit}}} \newcommand{\CloudTrainingRunEnergy}{E_{\text{cloud,train}}} \newcommand{\ClusterAvailability}{A_{\text{cluster}}} \newcommand{\ClusterCount}{k} \newcommand{\ClusterHeadroom}{N} \newcommand{\ClusterNodeCount}{N_{\text{nodes}}} \newcommand{\ClusterPower}{P_{\text{cluster}}} \newcommand{\CoarseCellCount}{C} \newcommand{\CodecDecodeTime}{T_{\text{decode}}} \newcommand{\CodecEncodeTime}{T_{\text{encode}}} \newcommand{\CodecOverheadTime}{T_{\text{overhead}}} \newcommand{\CognitivePolicyAction}{\mathbf{a}} \newcommand{\CoherencyCoefficient}{\kappa_{\text{coh}}} \newcommand{\ColdCopperLossPower}{P_0} \newcommand{\ColdResetCycleTime}{T_{\text{cycle,cold}}} \newcommand{\CollaborativeContactForce}{F_{\text{contact}}} \newcommand{\CollectedPhotocharge}{Q} \newcommand{\CollectionCohortCost}{C_{\text{cohort}}} \newcommand{\CollectionStateVisitationDistribution}{p^{\pi_{\text{col}}}} \newcommand{\CollectiveCallStartupLatency}{\alpha_{\text{eff}}} \newcommand{\CollectiveInputTensor}{\mathbf{X}} \newcommand{\CollectivePayloadSize}{M} \newcommand{\CollectiveTensorSize}{M_{\text{coll}}} \newcommand{\CollisionHullCount}{N_{\text{hulls}}} \newcommand{\CollocationDefect}{\Delta} \newcommand{\ColumnAccessLatency}{t_{\text{CL}}} \newcommand{\ColumnModeComponentVector}{\mathbf{b}_s} \newcommand{\ColumnModeFactorMatrix}{\mathbf{B}} \newcommand{\ColumnModeFactorSlice}{\mathbf{b}} \newcommand{\ColumnParallelWeightMatrix}{\mathbf{A}} \newcommand{\CombinedBatch}{B_{\text{total}}} \newcommand{\CombinedPlanValidationAllowance}{t_{\text{validate}}} \newcommand{\CommandComponentCount}{N_c} \newcommand{\CommandRateCeiling}{r} \newcommand{\CommandTransportTime}{T_{\text{bus}}} \newcommand{\CommandedActuatorEffort}{u_{\text{cmd}}} \newcommand{\CommandedApproachAcceleration}{a_{\text{cmd}}} \newcommand{\CommandedJointConfiguration}{\mathbf{q}_{\text{cmd}}} \newcommand{\CommandedJointCount}{N_j} \newcommand{\CommandedJointTorque}{\tau} \newcommand{\CommandedJointTorqueSlew}{\dot{\tau}} \newcommand{\CommandedTrackedPosition}{r_{\text{cmd}}} \newcommand{\CommandedTractiveForce}{F_{\text{cmd}}} \newcommand{\CommitBatchRecordCount}{N_{\text{batch}}} \newcommand{\CommitmentInstant}{t_{\text{commit}}} \newcommand{\CommitmentPathPosition}{q_{c}} \newcommand{\CommonPositionShift}{\Delta} \newcommand{\CommunicationComputeRatio}{\rho} \newcommand{\CommunicationIntensity}{\text{CI}} \newcommand{\CommunicationSlowdownFactor}{r} \newcommand{\CommunicationTime}{T_{\text{comm}}} \newcommand{\CommunicationTimeFraction}{f} \newcommand{\CompactedContextLength}{S_{\text{comp}}} \newcommand{\CompactionBoundaryCount}{k} \newcommand{\CompactionBoundaryIndex}{i} \newcommand{\CompactionCycleTurnCount}{n_{\text{cycle}}} \newcommand{\CompactionCycleTurnIndex}{i} \newcommand{\CompactionLossProbability}{\rho} \newcommand{\CompactionPassCost}{C_{\text{comp}}} \newcommand{\CompactionPathCost}{C_{\text{compact}}} \newcommand{\CompactionPaybackCallCount}{N_{\min}} \newcommand{\CompactionPerCallSaving}{s} \newcommand{\CompactionTargetLength}{S_{\text{low}}} \newcommand{\CompactionTriggerLength}{S_{\text{high}}} \newcommand{\CompactionUpfrontCost}{U} \newcommand{\ComparedPeriodAccuracy}{a} \newcommand{\ComparisonArmTrialCount}{n_{\text{arm}}} \newcommand{\ComparisonContext}{c} \newcommand{\ComparisonSampleEmpiricalCdf}{G_{m}} \newcommand{\ComparisonSampleSize}{m} \newcommand{\ComparisonTrajectory}{z} \newcommand{\ComparisonTrajectoryDerivative}{\dot{z}} \newcommand{\CompensatedEnvironmentState}{\sigma_0'} \newcommand{\CompensationPostcondition}{\phi} \newcommand{\CompensationPostconditionSet}{\Phi} \newcommand{\CompetingKeyCount}{n} \newcommand{\CompetingKeyLogit}{z} \newcommand{\CompilationBreakevenCount}{N_{\text{breakeven}}} \newcommand{\CompilationTime}{T_{\text{compile}}} \newcommand{\CompiledExecutionTime}{T_{\text{compiled}}} \newcommand{\CompilerBackendCount}{N_{\text{backend}}} \newcommand{\CompilerFrontendCount}{M} \newcommand{\ComplementarityNormalForce}{\lambda_n} \newcommand{\CompletedRequestCount}{N} \newcommand{\CompletedRoundIndex}{r} \newcommand{\CompletionCriteria}{\mathcal{K}_{\text{comp}}} \newcommand{\CompletionDeadline}{T_{\text{deadline}}} \newcommand{\CompletionOffset}{c} \newcommand{\CompliantElementPreload}{F_{\text{preload}}} \newcommand{\CompliantElementStiffness}{k_{\text{spring}}} \newcommand{\ComponentAvailability}{A_{\text{component}}} \newcommand{\ComponentFailureRate}{\lambda} \newcommand{\ComponentHazardRate}{h} \newcommand{\ComponentMttf}{\text{MTTF}_{\text{component}}} \newcommand{\ComponentReliability}{R_{\text{single}}} \newcommand{\ComposedChainTransform}{\mathbf{T}_{AC}} \newcommand{\ComposedFunctionInput}{x} \newcommand{\ComposedFunctionOutput}{y} \newcommand{\ComposedMechanismCount}{k} \newcommand{\CompoundScalingCoefficient}{\phi} \newcommand{\CompressedCommunicationTime}{T_{\text{compressed}}} \newcommand{\CompressedGradientUpdate}{\mathbf{v}} \newcommand{\CompressedGradientUpdateElement}{v} \newcommand{\CompressedOnlyCorrectCount}{n_{\text{comp}}} \newcommand{\CompressionRatio}{r_{\text{comp}}} \newcommand{\ComputationalDimensionCount}{N_{\text{comp}}} \newcommand{\ComputationalGraph}{G} \newcommand{\ComputeBudgetConstraint}{g} \newcommand{\ComputeChipPower}{P_{\text{chip}}} \newcommand{\ComputeConstrainedLagrangian}{\mathcal{L}_{\text{Lagrange}}} \newcommand{\ComputeConstraintMultiplier}{\lambda} \newcommand{\ComputeDemandVolume}{Q} \newcommand{\ComputeLimitedSampleRate}{R_{\text{compute}}} \newcommand{\ComputeOptimalTokenCount}{D_{\text{opt}}} \newcommand{\ComputeUnitCost}{P} \newcommand{\ConcordantTaskCount}{n} \newcommand{\ConcurrentTrajectories}{N_{\text{traj}}} \newcommand{\ConditionalDamageProbability}{p} \newcommand{\ConditionalDistribution}{p(y \mid x)} \newcommand{\ConditionalFlowMap}{\psi} \newcommand{\ConditionalVelocityField}{v} \newcommand{\ConditioningTokenPrefix}{x} \newcommand{\ConductorCurrent}{I} \newcommand{\ConeLimitStepSize}{\tau} \newcommand{\ConfidenceCalibrationDataset}{\mathcal{D}_{\text{cal}}} \newcommand{\ConfidenceCriticalQuantile}{z_{\alpha/2}} \newcommand{\ConfidenceLevel}{C} \newcommand{\ConfidentialityLabel}{\kappa} \newcommand{\ConfigurationSpace}{\mathcal{C}} \newcommand{\ConfirmationHitCount}{M} \newcommand{\ConfirmationWindowCount}{N_{\text{conf}}} \newcommand{\ConfluentVandermondeMatrix}{\mathbf{M}} \newcommand{\ConformalMiscoverageRate}{\epsilon} \newcommand{\ConformalPredictionSet}{\mathcal{C}} \newcommand{\ConformalQuantileRank}{k_{\epsilon}} \newcommand{\ConformalScoreQuantile}{\widehat{q}_{1-\epsilon}} \newcommand{\ConservativePenaltyWeight}{\alpha_{\text{CQL}}} \newcommand{\ConservativeSamplingDistribution}{\mu} \newcommand{\ConsoleCommunicationTime}{T_{\text{comm}}} \newcommand{\ConsolidationOverheadTime}{T_{\text{overhead}}} \newcommand{\ConsolidationStride}{c} \newcommand{\ConstantDivisorGrpoObjective}{\widehat{\mathcal{J}}_{\text{const}}} \newcommand{\ConstantHazardRate}{\lambda} \newcommand{\ConstrainedCallLatency}{T_{\text{constrained}}} \newcommand{\ConstrainedDecodingAutomaton}{\mathcal{D}} \newcommand{\ConstrainedParameterVector}{\mathbf{w}} \newcommand{\ConstrainedTestEnvelope}{\mathcal{S}} \newcommand{\ConstraintLagrangeMultiplier}{\lambda} \newcommand{\ConstraintRetentionFraction}{\eta_{\mathcal{C}}} \newcommand{\ContactApproachSpeed}{v_{\text{approach}}} \newcommand{\ContactCount}{N_c} \newcommand{\ContactDeformationDuration}{\Delta t_{\text{def}}} \newcommand{\ContactDirectionSpeed}{v_c} \newcommand{\ContactDirectionVelocity}{\dot{x}} \newcommand{\ContactDriftAcceleration}{a_{\text{drift}}} \newcommand{\ContactForce}{F_{\text{contact}}} \newcommand{\ContactForceBarrierFunction}{h_{\text{force}}} \newcommand{\ContactForceCap}{F_{\text{cap}}} \newcommand{\ContactForceCeiling}{F_{\max}} \newcommand{\ContactForceLimit}{F_{\text{limit}}} \newcommand{\ContactForceMagnitude}{F} \newcommand{\ContactForceRegularizationWeight}{w_f} \newcommand{\ContactForceRiseTime}{t_{\text{rise}}} \newcommand{\ContactGapAcceleration}{\ddot{\phi}} \newcommand{\ContactGapFunction}{\phi} \newcommand{\ContactGapVelocity}{\dot{\phi}} \newcommand{\ContactImpulse}{I} \newcommand{\ContactJacobianBaseBlock}{\mathbf{J}_{k,b}} \newcommand{\ContactJacobianJointBlock}{\mathbf{J}_{k,j}} \newcommand{\ContactLoopResponseTime}{T_c} \newcommand{\ContactNaturalTimescale}{T_{\text{contact}}} \newcommand{\ContactNormal}{\hat{\mathbf{n}}} \newcommand{\ContactNormalDeflection}{x} \newcommand{\ContactNormalJacobian}{\mathbf{J}_n} \newcommand{\ContactNormalJacobianDerivative}{\dot{\mathbf{J}}_n} \newcommand{\ContactNormalPosition}{x} \newcommand{\ContactNormalVelocity}{v_n} \newcommand{\ContactPatchRegion}{\mathcal{A}} \newcommand{\ContactPointForce}{\mathbf{f}} \newcommand{\ContactPointIndex}{i} \newcommand{\ContactPointJacobian}{\mathbf{J}_{\text{c}}} \newcommand{\ContactPointJacobianDerivative}{\dot{\mathbf{J}}_{\text{c}}} \newcommand{\ContactPointOffset}{\mathbf{r}} \newcommand{\ContactPointPosition}{x} \newcommand{\ContactPointTorque}{\boldsymbol{\tau}} \newcommand{\ContactReactionForce}{F} \newcommand{\ContactResponseLatency}{t_{\text{resp}}} \newcommand{\ContactStiffness}{k_{\text{contact}}} \newcommand{\ContactTorqueCeiling}{\tau_{\max}} \newcommand{\ContactTripwireForce}{F_{\text{trip}}} \newcommand{\ContactWrench}{\mathbf{w}} \newcommand{\ContactWrenchCeiling}{\mathbf{w}_{\max}} \newcommand{\ContactWrenchEnvelope}{\mathbf{w}_{\text{contact}}} \newcommand{\ContactWrenchTransform}{\mathbf{X}_k^*} \newcommand{\ContactYieldDeadline}{t_{\text{yield}}} \newcommand{\ContainerInnerRadius}{R} \newcommand{\ContainmentForceCeiling}{F_{\max}} \newcommand{\ContendingApplicationCount}{N} \newcommand{\ContentionCoefficient}{\sigma_{\text{cont}}} \newcommand{\ContextChunkTokenCount}{n} \newcommand{\ContextHiddenRepresentation}{\mathbf{h}_{\text{context}}} \newcommand{\ContextParallelDegree}{c} \newcommand{\ContextParallelRankIndex}{i} \newcommand{\ContextSaveTime}{t_{\text{context\_save}}} \newcommand{\ContextWindow}{S_{\max}} \newcommand{\ContinuationCount}{K} \newcommand{\ContinuationIndex}{i} \newcommand{\ContinuationReturnStandardDeviation}{\sigma} \newcommand{\ContinuityCorrectedCrossProduct}{A} \newcommand{\ContinuousActionComponent}{a} \newcommand{\ContinuousActionSpace}{\mathcal{A}} \newcommand{\ContinuousActionVector}{\mathbf{a}} \newcommand{\ContinuousCurrent}{I_{\text{cont}}} \newcommand{\ContinuousFactorialFunction}{\Gamma} \newcommand{\ContinuousMeasurementNoiseIntensity}{\mathbf{R}_{\text{cont}}} \newcommand{\ContinuousMotionModel}{\mathbf{f}} \newcommand{\ContinuousOutcome}{\mathbf{x}} \newcommand{\ContinuousRandomVariable}{\mathbf{X}} \newcommand{\ContinuousStateTransitionMatrix}{\boldsymbol{\Phi}} \newcommand{\ContinuousTorque}{\tau_{\text{cont}}} \newcommand{\ContractedBarrierFunction}{h_{\text{contracted}}} \newcommand{\ControlAffineDriftField}{\mathbf{f}} \newcommand{\ControlAffineInputField}{\mathbf{g}} \newcommand{\ControlCommand}{\mathbf{u}} \newcommand{\ControlCommandDerivative}{\dot{\mathbf{u}}} \newcommand{\ControlCommandSpace}{\mathcal{U}} \newcommand{\ControlConversionRate}{\hat{p}_A} \newcommand{\ControlCycleIndex}{i} \newcommand{\ControlInput}{\mathbf{u}} \newcommand{\ControlInputDimension}{m} \newcommand{\ControlInputLowerLimit}{\mathbf{u}_{\min}} \newcommand{\ControlInputSet}{\mathcal{U}} \newcommand{\ControlInputUpperLimit}{\mathbf{u}_{\max}} \newcommand{\ControlInputWindow}{\mathbf{u}_{[t, t+\Delta t]}} \newcommand{\ControlSampleIndex}{k} \newcommand{\ControlSampleSize}{m_A} \newcommand{\ControlSetpointJerk}{\mathbf{j}} \newcommand{\ControlSetpointPeriod}{\Delta t_{\text{ctrl}}} \newcommand{\ControlStepIndex}{t} \newcommand{\ControlTaskIndex}{i} \newcommand{\ControllabilityMatrix}{\mathbf{C}_{\text{ctrb}}} \newcommand{\ControlledStopCommand}{\mathbf{u}_{\text{stop}}} \newcommand{\ControllerReactionDelay}{T_{\text{react}}} \newcommand{\ConversationTurnIndex}{i} \newcommand{\ConverterLockoutVoltage}{V_{\text{uvlo}}} \newcommand{\ConveyorSpeed}{v_{\text{conv}}} \newcommand{\ConveyorSpeedBound}{v_{\text{conv}}} \newcommand{\ConvolutionActivation}{H} \newcommand{\ConvolutionTimeInstant}{t'} \newcommand{\CookedTokenKeyVector}{\mathbf{k}_{\text{cooked}}} \newcommand{\CookedTokenQueryVector}{\mathbf{q}_{\text{cooked}}} \newcommand{\CoolantHeatLoad}{P_{\text{thermal}}} \newcommand{\CoolantMassFlowRate}{\dot{m}} \newcommand{\CoolantTemperature}{T} \newcommand{\CoolingEnergy}{E_{\text{cooling}}} \newcommand{\CoordinateFrameEmbedding}{\mathbf{e}_{\text{frame}}} \newcommand{\CoordinationLatency}{L_{\text{lat,coordination}}} \newcommand{\CoordinationOverhead}{h} \newcommand{\CopperIronThermalResistance}{R_{\text{th,cu-iron}}} \newcommand{\CopperReferenceTemperature}{T_0} \newcommand{\CopperTemperatureCoefficient}{\alpha_{\text{Cu}}} \newcommand{\CopperThermalCapacitance}{C_{\text{cu}}} \newcommand{\CopperThermalTimeConstant}{\tau_{\text{th,cu}}} \newcommand{\CoreAmbientThermalResistance}{R_{\text{th,ca}}} \newcommand{\CoreRailVoltageDroop}{\Delta V_{\text{droop}}} \newcommand{\CoreThermalCapacitance}{C_{\text{core}}} \newcommand{\CoresetBudget}{K} \newcommand{\CoriolisCentrifugalMatrix}{\mathbf{C}} \newcommand{\CorrectCandidateTrialPassProbability}{p_{g}} \newcommand{\CorrectClassIndex}{c} \newcommand{\CorrectClassLogit}{z_{c}} \newcommand{\CorrectClassProbability}{\hat{y}_{c}} \newcommand{\CorrectnessReward}{R_{\text{corr}}} \newcommand{\CorrelationCoefficient}{\rho} \newcommand{\CorruptedAttentionScoreMatrix}{\mathbf{S}_{\text{corrupt}}} \newcommand{\CorruptedModelWeight}{w'} \newcommand{\CostAnomalyScore}{Z} \newcommand{\CostBudgetUsedFraction}{\rho_C} \newcommand{\CostCeiling}{C_{\max}} \newcommand{\CostPerAcceptedTask}{C_{\text{eff}}} \newcommand{\CostPerEmittedArtifact}{C_{\text{emit}}} \newcommand{\CostToGo}{C} \newcommand{\CoulombFrictionCoefficient}{\mu} \newcommand{\CoulombFrictionForce}{F_{\text{friction}}} \newcommand{\CountedFailureIndicator}{e} \newcommand{\CovariateDriftBound}{\mathcal{O}(S^2 \epsilon)} \newcommand{\CoverageFactor}{k} \newcommand{\CpuEnergy}{E_{\text{CPU}}} \newcommand{\CredibleBrakingDeceleration}{a_{\text{brake}}} \newcommand{\CreditWindowCapacity}{N_{\text{win}}} \newcommand{\CriticActionReturnEstimate}{Q_{\phi}} \newcommand{\CriticApproximationError}{\epsilon} \newcommand{\CriticModel}{M_{\text{value}}} \newcommand{\CriticParameters}{\phi} \newcommand{\CriticReturnEstimate}{V_{\phi}} \newcommand{\CriticalBatchSize}{B^{*}} \newcommand{\CriticalConstraint}{c} \newcommand{\CriticalPathDuration}{T_{\text{crit}}} \newcommand{\CriticalSectionIndex}{s} \newcommand{\CriticalSectionWcet}{C^{\text{cs}}} \newcommand{\CriticalTrackingErrorBound}{\epsilon_{\text{crit}}} \newcommand{\CriticalTransitDistance}{d_{\text{crit}}} \newcommand{\CrossEntropyLevelThreshold}{\gamma} \newcommand{\CrossEntropyLoss}{\mathcal{L}_{\text{CE}}} \newcommand{\CrossoverFrequency}{\omega_c} \newcommand{\CruiseSpeed}{v_{c}} \newcommand{\CumulativeArrivals}{A} \newcommand{\CumulativeCompletions}{C} \newcommand{\CumulativeIncidentCount}{N} \newcommand{\CumulativeLogLikelihoodRatio}{\Lambda} \newcommand{\CumulativeScheduleStepIndex}{s} \newcommand{\CumulativeTransmittance}{T} \newcommand{\CumulativeWorkCost}{C} \newcommand{\CurrentBinProportion}{A} \newcommand{\CurrentDistribution}{P_t} \newcommand{\CurrentFeatureMean}{\mu_{\text{curr}}} \newcommand{\CurrentFeatureStandardDeviation}{\sigma_{\text{curr}}} \newcommand{\CurrentLayerWidth}{n_{\ell}} \newcommand{\CurrentModelParameters}{\theta_{\text{old}}} \newcommand{\CurrentMonotonicTime}{t_{\text{now,mono}}} \newcommand{\CurrentNodeIndex}{j} \newcommand{\CurrentPeriodCost}{C_{\text{current}}} \newcommand{\CurrentStateDigest}{h_{\text{state},t}} \newcommand{\CurrentStateEstimate}{\hat{\mathbf{x}}_{t_{\text{current}}}} \newcommand{\CurrentTime}{t_{\text{now}}} \newcommand{\CurrentWallClockTime}{t_{\text{current}}} \newcommand{\CutCrossingDataVolume}{V_{\text{cut}}} \newcommand{\CvaeEncoderParameters}{\phi} \newcommand{\CvaeRecognitionEncoder}{q_\phi} \newcommand{\CycleAveragePowerCeiling}{\bar{P}_{\max}} \newcommand{\CycleGuardTime}{t_{\text{guard}}} \newcommand{\CylinderForce}{F_{\text{cyl}}} \newcommand{\DailyAccountQueryCount}{q_{\text{daily}}} \newcommand{\DailyQueryVolume}{Q_{\text{day}}} \newcommand{\DamageEventCount}{N_{\text{damage}}} \newcommand{\DamageProbabilityTolerance}{\epsilon} \newcommand{\DamageProbabilityUpperBound}{p_U} \newcommand{\DamagingOutcomeIndicator}{Y} \newcommand{\DampedLeastSquaresPseudoinverse}{\mathbf{J}_{\lambda}^\dagger} \newcommand{\DampedStepConfiguration}{\mathbf{q}_\lambda} \newcommand{\DampingRatio}{\zeta} \newcommand{\DataAcquisitionCost}{C_{\text{acquire}}} \newcommand{\DataDebtGrowthRate}{r} \newcommand{\DataEgressCost}{C_{\text{egress}}} \newcommand{\DataFieldBitCount}{B_{\text{data},i}} \newcommand{\DataInformationContent}{\mathcal{I}} \newcommand{\DataLabelingCost}{C_{\text{label}}} \newcommand{\DataLoaderWorkerCount}{W} \newcommand{\DataMovementEnergyFraction}{q} \newcommand{\DataParallelDegree}{N_{\text{DP}}} \newcommand{\DataPhaseBitRate}{R_{\text{data}}} \newcommand{\DataPipelineProcessingCost}{C_{\text{process}}} \newcommand{\DataProcessingCost}{C_{\text{process}}} \newcommand{\DataScaleCoefficient}{B} \newcommand{\DataScalingExponent}{\beta} \newcommand{\DataScalingLossFactor}{D^{-\beta}} \newcommand{\DataStallFraction}{f_{\text{stall}}} \newcommand{\DataStorageCost}{C_{\text{store}}} \newcommand{\DataSupplyRate}{R_{\text{data}}} \newcommand{\DataTaxonomyAxis}{\mathsf{Data}} \newcommand{\DataVolume}{D_{\text{vol}}} \newcommand{\DatasetQuery}{f} \newcommand{\DatasetQueryResult}{v} \newcommand{\DatasetShardCount}{K_{\text{shards}}} \newcommand{\DatasetSize}{D} \newcommand{\DatasetTransferTime}{T} \newcommand{\DcBusBulkCapacitance}{C_{\text{bus}}} \newcommand{\DcBusOvervoltageThreshold}{V_{\text{max\_safe}}} \newcommand{\DcBusVoltage}{V_{\text{bus}}} \newcommand{\DcRailVoltage}{V_{\text{rail}}} \newcommand{\DeadTimeCycleCount}{N_{\text{dtg}}} \newcommand{\DeadTimeDqVoltageError}{\Delta V_{d,q}} \newcommand{\DeadTimeSafetyMargin}{t_{\text{margin}}} \newcommand{\DeadTimeTickPeriod}{T_{\text{dtg}}} \newcommand{\DeadTimeVoltageError}{\Delta V_{\text{phase}}} \newcommand{\DeadlineInstant}{t_{\text{deadline}}} \newcommand{\DebiasingTotalLoss}{\mathcal{L}_{\text{total}}} \newcommand{\DebounceFrameCount}{N} \newcommand{\DecisionProcessState}{s} \newcommand{\DecisionScore}{s_{\text{dec}}} \newcommand{\DecisionStepIndex}{k} \newcommand{\DecodeArithmeticIntensity}{I_{\text{decode}}} \newcommand{\DecodeBatchSize}{B_{\text{dec}}} \newcommand{\DecodeInterval}{T_{\text{decode}}} \newcommand{\DecodeRequestSet}{\mathcal{D}} \newcommand{\DecodeTokenTimeFloor}{T_{\text{token}}} \newcommand{\DecoderEvaluationCount}{N_{\text{eval}}} \newcommand{\DecoderPassTime}{t_{\text{pass}}} \newcommand{\DecodingConstraintState}{q} \newcommand{\DecomposedTensor}{\mathcal{Y}} \newcommand{\DecomposedTensorEntry}{y_{ijt}} \newcommand{\DecouplingCapacitance}{C} \newcommand{\DecouplingDriftVector}{\mathbf{b}} \newcommand{\DecouplingMatrix}{\mathbf{E}} \newcommand{\DecouplingMatrixElement}{E} \newcommand{\DedicatedHourlyFixedCost}{C_{\text{fixed}}} \newcommand{\DedicatedVariableTokenCost}{c_{\text{ded}}} \newcommand{\DefectiveActionProbability}{p_{\text{bad}}} \newcommand{\DefinitionSerializedSize}{S} \newcommand{\DeflectionComplianceAllowance}{\delta_{\text{deflect}}} \newcommand{\DegradedFrictionCoefficient}{\mu_{\text{fault}}} \newcommand{\DegradedStepTime}{T_{\text{slow}}} \newcommand{\DelassusOperator}{\mathbf{A}_{\text{Delassus}}} \newcommand{\DelayPhaseLag}{\Delta \phi} \newcommand{\DelayTravelDistance}{d_{\text{delay}}} \newcommand{\DelayWindowIntegrationTime}{\sigma} \newcommand{\DelayedObservation}{\mathbf{y}_{t_0}} \newcommand{\DelegatedAllocationAmount}{b} \newcommand{\DelegationTokenMultiple}{r} \newcommand{\DeliveredActuatorTorque}{\tau_{\text{act}}} \newcommand{\DeliveredCapacityFraction}{u} \newcommand{\DemandCap}{x_{\max}} \newcommand{\DemandPriceElasticity}{\epsilon_{\text{elast}}} \newcommand{\DemandThreshold}{x} \newcommand{\DemonstratedTargetA}{\mathbf{y}_A} \newcommand{\DemonstratedTargetB}{\mathbf{y}_B} \newcommand{\DemonstrationActionDistribution}{p} \newcommand{\DemonstrationActionLabel}{\mathbf{a}} \newcommand{\DemonstrationArchiveActionDistribution}{p_{\text{demo}}} \newcommand{\DemonstrationChunkDistribution}{p_{\text{data}}} \newcommand{\DemonstrationDataset}{\mathcal{D}_{\text{demo}}} \newcommand{\DemonstrationRetentionRate}{R} \newcommand{\DemonstratorAction}{\mathbf{a}^{*}} \newcommand{\DemonstratorActionComponent}{a} \newcommand{\DenseEvaluationEnergy}{E_{\text{eval}}} \newcommand{\DenseEvaluationRate}{f_{\text{eval}}} \newcommand{\DenseVoxelGridMemory}{M_{\text{dense}}} \newcommand{\DepartmentQuotaLimit}{Q_{\text{department}}} \newcommand{\DependencyGraphEdgeSet}{E} \newcommand{\DependencyGraphVertex}{v} \newcommand{\DependencyGraphVertexSet}{V} \newcommand{\DepletedBusVoltage}{V_{\text{low}}} \newcommand{\DeploymentAge}{t} \newcommand{\DeploymentDistribution}{p_{\text{deploy}}} \newcommand{\DeploymentDuration}{T_{\text{deployment}}} \newcommand{\DepthBinCount}{D} \newcommand{\DepthBinDistribution}{\boldsymbol{\alpha}_{u, v}} \newcommand{\DepthBinIndex}{k} \newcommand{\DepthBinLogits}{\mathbf{d}_{u, v}} \newcommand{\DepthBinProbability}{\alpha_{u, v}} \newcommand{\DepthCalibrationScale}{s} \newcommand{\DepthCalibrationShift}{t} \newcommand{\DepthCriticalPathLatency}{T^{\text{depth}}} \newcommand{\DepthFrameRate}{f_{\text{cam}}} \newcommand{\DepthHypothesis}{d} \newcommand{\DepthModeComponentVector}{\mathbf{c}_s} \newcommand{\DepthModeFactorMatrix}{\mathbf{C}} \newcommand{\DepthModeFactorSlice}{\mathbf{c}} \newcommand{\DepthRayCount}{N_{\text{rays}}} \newcommand{\DepthScalingRatio}{\alpha} \newcommand{\DepthStandardDeviation}{\sigma_z} \newcommand{\DerivativeControlEffort}{\mathbf{u}_{d}} \newcommand{\DerivativeFilterTimeConstant}{T_{f}} \newcommand{\DerivativeGainMatrix}{\mathbf{K}_{d}} \newcommand{\DerivativeOperator}{d} \newcommand{\DerivativeSplineControlPoint}{\mathbf{v}} \newcommand{\DerivedMemoryEntry}{c} \newcommand{\DerivedRecord}{y} \newcommand{\DesignLatencyQuantile}{Q_{1-\epsilon}} \newcommand{\DesiredContactPosition}{x_{\text{des}}} \newcommand{\DesiredContactVelocity}{\dot{x}_{\text{des}}} \newcommand{\DesiredTaskAcceleration}{\ddot{\mathbf{x}}_d} \newcommand{\DesiredTaskPosition}{\mathbf{x}_d} \newcommand{\DesiredTaskSpaceAcceleration}{\ddot{\mathbf{x}}^{\text{des}}} \newcommand{\DesiredTaskVelocity}{\dot{\mathbf{x}}_d} \newcommand{\DestinationRankIndex}{j} \newcommand{\DetectionCount}{n_{\text{det}}} \newcommand{\DetectionInterval}{t_{\text{detect}}} \newcommand{\DetectionMeasurementNoiseCovariance}{\boldsymbol{\Sigma}_{\text{meas},j}} \newcommand{\DetectionRangeShortfall}{\Delta d_{\text{detect}}} \newcommand{\DetectionTimestamp}{t_{\text{det}}} \newcommand{\DetectorMissProbability}{p_{\text{miss}}} \newcommand{\DeterministicPolicy}{\mu_{\theta}} \newcommand{\DevelopmentIterationCount}{N_{\text{dev}}} \newcommand{\DeviationDisadvantage}{u} \newcommand{\DeviceCount}{N} \newcommand{\DeviceEnergy}{E_{\text{device}}} \newcommand{\DeviceHardwareTime}{T_{\text{hw}}} \newcommand{\DeviceMemoryCapacity}{M_{\text{device}}} \newcommand{\DevicePower}{P_{\text{device}}} \newcommand{\DeviceRequestCapacity}{Q_{\text{req,max}}} \newcommand{\DeviceSilentCorruptionProbability}{p} \newcommand{\DiagnosticCoverage}{C_{\text{diag}}} \newcommand{\DictionaryCoefficientMatrix}{\mathbf{C}} \newcommand{\DifferentiabilityClass}{C} \newcommand{\DifferentialEntropy}{h} \newcommand{\DiffusionCumulativeSchedule}{\bar{\alpha}} \newcommand{\DiffusionGaussianNoise}{\boldsymbol{\epsilon}} \newcommand{\DiffusionMatchingLoss}{\mathcal{L}_{\text{diff}}} \newcommand{\DiffusionNoiseVariance}{\beta} \newcommand{\DiffusionStepCount}{N} \newcommand{\DiffusionStepIndex}{k} \newcommand{\DiffusionStepRetention}{\alpha} \newcommand{\DiffusionTimeCoordinate}{t_{\text{diff}}} \newcommand{\DirectAxisCurrent}{i_d} \newcommand{\DirectAxisInductance}{L_d} \newcommand{\DirectAxisVoltage}{v_d} \newcommand{\DirectionalCosineMatrix}{\mathbf{R}} \newcommand{\DirectionalDerivativeStep}{\epsilon} \newcommand{\DisadvantagedGroupClassificationThreshold}{\gamma_{\text{cls},g=\text{B}}} \newcommand{\DiscordantPairCount}{n_{\text{disc}}} \newcommand{\DiscordantPairFraction}{\psi} \newcommand{\DiscountFactor}{\gamma} \newcommand{\DiscountedReturn}{G} \newcommand{\DiscountedReturnStepOffset}{j} \newcommand{\DiscountedStateVisitationDistribution}{d} \newcommand{\DiscreteLqrFeedbackGain}{\mathbf{K}_{\text{lqr},d}} \newcommand{\DiscreteLqrQuadraticObjective}{J_d} \newcommand{\DiscreteOutcome}{x} \newcommand{\DiscretePlantDynamics}{f} \newcommand{\DiscreteRandomVariable}{X} \newcommand{\DiscreteSampleIndex}{k} \newcommand{\DiscreteStateSpaceInputMatrix}{\mathbf{B}_{d}} \newcommand{\DiscreteStateSpaceSystemMatrix}{\mathbf{A}_{d}} \newcommand{\DiscretizationBinCount}{n_{\text{bin}}} \newcommand{\DisengagedTakeoverResponseTime}{T_{\Sigma,2}} \newcommand{\DiskBandwidth}{\text{BW}_{\text{disk}}} \newcommand{\DisparityStandardDeviation}{\sigma_d} \newcommand{\DispatchAdmissionCeiling}{\Delta_{\text{da,max}}} \newcommand{\DispatchAdmissionInterval}{\Delta_{\text{da}}} \newcommand{\DispatchObservationAge}{t_{\text{age}}} \newcommand{\DispatchedOperationCount}{N_{\text{ops}}} \newcommand{\DisplayPipelineLatency}{t_{\text{disp}}} \newcommand{\DispreferredReferenceRelativeScore}{\Delta_l} \newcommand{\DispreferredTrajectory}{\tau_l} \newcommand{\DistanceEstimateStandardDeviation}{\sigma} \newcommand{\DistanceMeasurement}{z} \newcommand{\DistanceNormOrder}{p} \newcommand{\DistanceQueryPoint}{\mathbf{y}} \newcommand{\DistillationClassProbability}{p^{(T_{\text{distill}})}} \newcommand{\DistillationLoss}{\mathcal{L}_{\text{distill}}} \newcommand{\DistillationLossWeight}{\gamma_{\text{KD}}} \newcommand{\DistillationTemperature}{T_{\text{distill}}} \newcommand{\DistortedImageAbscissa}{x_d} \newcommand{\DistortedImageOrdinate}{y_d} \newcommand{\DistributedStepTime}{T_{\text{step}}} \newcommand{\DisturbanceAccelerationBound}{a_{\text{dist}}} \newcommand{\DisturbanceBasisCoefficient}{\psi} \newcommand{\DisturbanceBasisCount}{K} \newcommand{\DisturbanceBasisFunction}{B} \newcommand{\DisturbanceBudget}{\Delta_{w}} \newcommand{\DisturbanceDimension}{p} \newcommand{\DisturbanceForceBound}{d_{\max}} \newcommand{\DisturbanceParameterSet}{\Psi} \newcommand{\DisturbanceParameterVector}{\boldsymbol{\psi}} \newcommand{\DisturbanceTrajectory}{w_{\text{dist}}} \newcommand{\DivergenceInstant}{t_{\text{div}}} \newcommand{\DivergenceMeasure}{\mathcal{D}} \newcommand{\DivergenceTolerance}{\delta_{\text{tol}}} \newcommand{\DmaBurstPeriod}{T_{\text{dma}}} \newcommand{\DmaBurstStallTime}{C_{\text{dma}}} \newcommand{\DmaQueueTime}{t_{\text{DMA}}} \newcommand{\DocumentPayloadFraction}{q} \newcommand{\DomainRandomizationDistribution}{\mathcal{D}_{\text{DR}}} \newcommand{\DomainRandomizationObjective}{J_{\text{DR}}} \newcommand{\DominantComponentEnergy}{E_{\text{dominant}}} \newcommand{\DominantShare}{d} \newcommand{\DoorOpenReward}{r_{\text{open}}} \newcommand{\DoubleIntegratorPosition}{p} \newcommand{\DoubleIntegratorPositionDerivative}{\dot{p}} \newcommand{\DoubleIntegratorVelocity}{v} \newcommand{\DoubleIntegratorVelocityDerivative}{\dot{v}} \newcommand{\DoubleTreeAllReduceTime}{T_{\text{double-tree}}} \newcommand{\DownstreamStageLatency}{Y} \newcommand{\DpoLoss}{\mathcal{L}_{\text{DPO}}} \newcommand{\DraftAcceptanceRate}{\alpha} \newcommand{\DraftCandidateToken}{\tilde{x}} \newcommand{\DraftModelDistribution}{q_{\phi}} \newcommand{\DraftPositionAcceptanceProbability}{\alpha_{\text{spec}, j}} \newcommand{\DraftPositionIndex}{i} \newcommand{\DraftSamplingDistribution}{q} \newcommand{\DraftTokenAcceptanceProbability}{\alpha_{\text{acc}}} \newcommand{\DraftTokenCostRatio}{\beta} \newcommand{\DraftTokenCount}{\gamma} \newcommand{\DraftedToken}{T} \newcommand{\DragonflyGlobalChannelCount}{h} \newcommand{\DragonflyGroupRouterCount}{a} \newcommand{\DragonflyTerminalPortCount}{p} \newcommand{\DrainSourceVoltage}{V_{\text{ds}}} \newcommand{\DriftElapsedTime}{t_{\text{drift}}} \newcommand{\DriftImpactTime}{t_{\text{impact}}} \newcommand{\DriftLieDerivativeOperator}{L_{\mathbf{f}}} \newcommand{\DriftSpeedBound}{v_{\text{drift}}} \newcommand{\DriftTestSampleSize}{n} \newcommand{\DriftVelocityBound}{v_{\text{drift}}} \newcommand{\DriveBrakingForceCeiling}{F} \newcommand{\DriveBrakingTorqueCeiling}{\tau} \newcommand{\DrivenWheelLoadFraction}{\phi_{\text{drive}}} \newcommand{\DriverInterruptLatency}{t_{\text{driver\_irq}}} \newcommand{\DrivetrainAntiresonanceFrequency}{f_{\text{anti}}} \newcommand{\DrivetrainResonanceFrequency}{f_{\text{res}}} \newcommand{\DroopedSupplyVoltage}{V_{\text{droop}}} \newcommand{\DropletDiameter}{d_{\text{droplet}}} \newcommand{\DropoutProbability}{p_{\text{drop}}} \newcommand{\DualNumberInfinitesimal}{\epsilon} \newcommand{\DuplicateEffectProbability}{p_{\text{dup}}} \newcommand{\DurableAcknowledgmentTime}{t_{\text{ack}}} \newcommand{\DurableStoreWriteBandwidth}{\text{BW}_{\text{store}}} \newcommand{\DutyCyclePeriod}{T_{\text{period}}} \newcommand{\DynamicPower}{P_{\text{dynamic}}} \newcommand{\DynamicReachableSet}{\mathcal{R}} \newcommand{\DynamicsRealityGap}{\Delta_{\text{dyn}}} \newcommand{\EagerExecutionTime}{T_{\text{eager}}} \newcommand{\EarlierBaseFlangeTransform}{\mathbf{T}_{\text{base}, k}^{\text{flange}}} \newcommand{\EarlierCameraTargetTransform}{\mathbf{T}_{\text{cam}, k}^{\text{target}}} \newcommand{\EarlierControlStepIndex}{t'} \newcommand{\EarlierWorkerCount}{k} \newcommand{\EarliestConflictTime}{t_{\text{conflict}}} \newcommand{\EarthReferenceFrame}{\mathcal{F}_{\text{earth}}} \newcommand{\EchoFactor}{e} \newcommand{\EchoRoundTripTime}{t_{\text{rt}}} \newcommand{\EditGrantRights}{\mathcal{R}_{\Gamma_{\text{edit}}}} \newcommand{\EditPhaseCapabilityGrant}{\Gamma_{\text{edit}}} \newcommand{\EffectiveAdmissionCeiling}{Q_{\text{effective}}} \newcommand{\EffectiveApiOutputTokenPrice}{c_{\text{API}}} \newcommand{\EffectiveBrakingDelay}{T_{\text{eff}}} \newcommand{\EffectiveBranchingFactor}{b_{\text{eff}}} \newcommand{\EffectiveConfidentialityLabel}{\kappa_{\text{eff}}} \newcommand{\EffectiveFleetThroughput}{R_{\text{eff}}} \newcommand{\EffectiveImpactMass}{m_{\text{eff}}} \newcommand{\EffectiveIntegrityProvenance}{\iota_{\text{eff}}} \newcommand{\EffectiveJointInertia}{J_{\text{eff}}} \newcommand{\EffectiveLossResistance}{R_{\text{eff}}} \newcommand{\EffectiveSampleSize}{N_{\text{eff}}} \newcommand{\EffectiveSeriesStiffness}{k_{\text{eff}}} \newcommand{\EffectiveServiceRate}{\mu_{\text{eff}}} \newcommand{\EffectiveSpotTrainingCost}{C_{\text{effective}}} \newcommand{\EffectiveStorageThroughput}{R_{\text{storage,eff}}} \newcommand{\EffectiveWasteFraction}{W_{\text{effective}}} \newcommand{\EfficiencyHw}{\eta_{\text{hw}}} \newcommand{\EgressArrivalRate}{\lambda_{\text{arr}}} \newcommand{\EgressBufferCapacity}{Q_{\text{max}}} \newcommand{\EgressPortUtilization}{\rho_{\text{egress}}} \newcommand{\EgressPrice}{R_{\text{egress/GB}}} \newcommand{\EgressQueueOccupancy}{Q} \newcommand{\EgressServiceRate}{\mu} \newcommand{\ElapsedPlanningPeriods}{n} \newcommand{\ElasticJointTorque}{\mathbf{z}} \newcommand{\ElasticMaximumWorkerCount}{N_{\text{max}}} \newcommand{\ElasticMinimumWorkerCount}{N_{\text{min}}} \newcommand{\ElasticModalFrequencyMatrix}{\boldsymbol{\Omega}} \newcommand{\ElasticPotentialEnergy}{E} \newcommand{\ElasticStrainEnergy}{U_{\text{elastic}}} \newcommand{\ElasticTorqueSecondDerivative}{\ddot{\mathbf{z}}} \newcommand{\ElbowSwivelAngle}{\psi} \newcommand{\ElectricalAngularSpeed}{\omega_e} \newcommand{\ElectricalResistance}{R} \newcommand{\ElectricalRotorAngle}{\theta_e} \newcommand{\ElectricalTimeConstant}{\tau_e} \newcommand{\ElectricityPrice}{R_{\$/\text{kWh}}} \newcommand{\ElementStorageSize}{s_{\text{elem}}} \newcommand{\ElementaryCharge}{q} \newcommand{\ElementaryOperationCount}{W} \newcommand{\ElevationAngle}{\phi} \newcommand{\EligibleCachedPrefixLength}{S_{\text{hit}}} \newcommand{\EligibleTargetPositionSet}{\mathcal{P}_{\text{elig}}} \newcommand{\EligibleVectorCount}{N} \newcommand{\EliteSampleFraction}{\beta} \newcommand{\EmbeddingDimension}{d} \newcommand{\EmbeddingShardCount}{N_{\text{shards}}} \newcommand{\EmergencyStopContact}{S} \newcommand{\EmergencyStopCount}{n_{\text{estop}}} \newcommand{\EmittedArtifactCount}{N_{\text{emit}}} \newcommand{\EmittedTokenCount}{S_{\text{out}}} \newcommand{\EmpiricalBellmanOperator}{\mathcal{B}} \newcommand{\EmpiricalExceedanceFraction}{\hat{\zeta}_{u}} \newcommand{\EmpiricalTimestepAverage}{\hat{\mathbb{E}}} \newcommand{\EmpiricalTransferDiscrepancy}{\hat{\epsilon}_{\text{gap}}} \newcommand{\EmptyByteString}{\epsilon} \newcommand{\EncodedLatentState}{\hat{\mathbf{z}}} \newcommand{\EncoderAngle}{\theta_{\text{enc}}} \newcommand{\EncoderBitCount}{n} \newcommand{\EncoderLatentRepresentation}{\mathbf{z}} \newcommand{\EncoderVelocityEstimate}{\dot{\theta}_{\text{enc}}} \newcommand{\EncoderVelocityNoise}{\sigma_{\dot{\theta}_{\text{enc}}}} \newcommand{\EndEffectorCameraTransform}{\mathbf{T}_{EC}} \newcommand{\EndEffectorFirstAxisPosition}{x} \newcommand{\EndEffectorPitchAngle}{\phi_{\text{pitch}}} \newcommand{\EndEffectorPose}{\mathbf{T}_{WE}} \newcommand{\EndEffectorRollAngle}{\phi_{\text{roll}}} \newcommand{\EndEffectorSecondAxisPosition}{y} \newcommand{\EndEffectorTaskAcceleration}{\ddot{\mathbf{x}}} \newcommand{\EndEffectorTaskPosition}{\mathbf{x}} \newcommand{\EndEffectorTaskVelocity}{\dot{\mathbf{x}}} \newcommand{\EndEffectorThirdAxisPosition}{z} \newcommand{\EndEffectorTwist}{\mathbf{V}_E} \newcommand{\EndEffectorVelocity}{\mathbf{v}_e} \newcommand{\EndEffectorYawAngle}{\phi_{\text{yaw}}} \newcommand{\EndToEndRequestLatency}{L_{\text{lat,total}}} \newcommand{\EnergyCrossoverIntensity}{I_{\text{crossover}}} \newcommand{\EnergyLimitedContactForce}{F_E} \newcommand{\EnergyPerByteMoved}{E_{\text{move}}} \newcommand{\EnergyPerOperation}{E_{\text{compute}}} \newcommand{\EnergyTankBarrierFunction}{h_{\text{energy}}} \newcommand{\EnergyTankLevel}{E_{\text{tank}}} \newcommand{\EnergyTankPower}{\dot{E}_{\text{tank}}} \newcommand{\EnergyTankReserve}{E_{\text{min}}} \newcommand{\EnforcedCommandLabel}{\mathbf{a}_{\text{enf}, t}} \newcommand{\EnforcedCommandTap}{a_{\text{enf}}} \newcommand{\EnforcerComputeTime}{T_{\text{comp}}} \newcommand{\EnforcerDeadline}{T_{\text{deadline,enf}}} \newcommand{\EngineerHourlyCost}{C_{\text{engineer}}} \newcommand{\EngineeringTeamSize}{n} \newcommand{\EngineeringTemperatureCeiling}{T_{\text{ceil}}} \newcommand{\EnsembleSpreadThreshold}{\sigma_{\text{thresh}}} \newcommand{\EnsemblingDecayRate}{m} \newcommand{\EnsemblingWindowLength}{K} \newcommand{\EntityCount}{N_{\text{entities}}} \newcommand{\EntityEmbedding}{\mathbf{e}} \newcommand{\EntityIndex}{j} \newcommand{\EntropyTemperature}{\alpha} \newcommand{\EnvelopeCallCount}{N} \newcommand{\EnvelopeSetupTime}{T_{\text{setup}}} \newcommand{\EnvironmentCycleTime}{T_{\text{cycle}}} \newcommand{\EnvironmentFixture}{f} \newcommand{\EnvironmentLatentDimension}{d_z} \newcommand{\EnvironmentLatentVector}{\mathbf{z}} \newcommand{\EnvironmentParameters}{e} \newcommand{\EnvironmentResetTime}{T_{r}} \newcommand{\EnvironmentResponseFunction}{g} \newcommand{\EnvironmentRolloutStepCount}{h} \newcommand{\EnvironmentTransitionDistribution}{p} \newcommand{\EpipolarLine}{\mathbf{l}} \newcommand{\EpochCount}{N_{\text{epochs}}} \newcommand{\EpochIndex}{n_{\text{epoch}}} \newcommand{\EquilibriumWindingTemperature}{T_\infty} \newcommand{\EquivalentSeriesStiffness}{k_{\text{eq}}} \newcommand{\ErasureDataFragmentCount}{d} \newcommand{\ErasureParityFragmentCount}{m} \newcommand{\ErroneousPredictionCost}{C_{\text{error}}} \newcommand{\ErrorBudgetConsumption}{B} \newcommand{\ErrorCovarianceDerivative}{\dot{\mathbf{P}}} \newcommand{\ErrorFeedbackResidual}{\mathbf{e}} \newcommand{\ErrorFeedbackResidualElement}{e} \newcommand{\ErrorGrowthRate}{r} \newcommand{\ErrorRecoveryCost}{C_{\text{recovery}}} \newcommand{\EscalationDecision}{d} \newcommand{\EscalationLossMatrix}{\mathbf{L}} \newcommand{\EscalationThresholdProbability}{p_{\text{threshold}}} \newcommand{\EssentialMatrix}{\mathbf{E}} \newcommand{\EstimateEpoch}{t_{\text{est}}} \newcommand{\EstimatedAcceptanceProbability}{\hat{p}} \newcommand{\EstimatedAccuracy}{\hat{p}} \newcommand{\EstimatedCandidateUtility}{\hat{U}} \newcommand{\EstimatedCleanActionChunk}{\hat{\mathbf{A}}} \newcommand{\EstimatedCoriolisMatrix}{\hat{\mathbf{C}}} \newcommand{\EstimatedDamageProbability}{\hat{p}} \newcommand{\EstimatedDivergenceInstant}{\hat{t}_{\text{div}}} \newcommand{\EstimatedForceSensorBias}{\hat{b}} \newcommand{\EstimatedGravitationalTorque}{\hat{\mathbf{g}}} \newcommand{\EstimatedGripContactForce}{\hat{x}} \newcommand{\EstimatedHistoryAdvantage}{\hat{A}} \newcommand{\EstimatedInertiaMatrix}{\hat{\mathbf{M}}} \newcommand{\EstimatedPairedAcceptanceDifference}{\hat{\Delta}} \newcommand{\EstimatedPlantState}{\hat{\mathbf{x}}} \newcommand{\EstimatedPosition}{\hat{\mathbf{p}}} \newcommand{\EstimatedRemainingReturn}{\hat{V}} \newcommand{\EstimatedUtilityStandardDeviation}{s} \newcommand{\EstimatedVelocity}{\hat{\mathbf{v}}} \newcommand{\EstimatedWindingTemperature}{\hat{T}_{\text{wind}}} \newcommand{\EstimationErrorCovariance}{\mathbf{P}} \newcommand{\EstimatorDrawCount}{N} \newcommand{\EstimatorDrawStandardDeviation}{\sigma} \newcommand{\EstimatorState}{\mathbf{x}} \newcommand{\EstimatorStateVector}{\mathbf{x}} \newcommand{\EstimatorStepIndex}{k} \newcommand{\EulerIntegralFirstShape}{a} \newcommand{\EulerIntegralSecondShape}{b} \newcommand{\EulerIntegralVariable}{t} \newcommand{\EvaluatedExceedance}{y} \newcommand{\EvaluationPredicate}{\phi} \newcommand{\EvaluationSampleCount}{N} \newcommand{\EvaluationTrialCount}{N} \newcommand{\EvaluationTrialIndex}{i} \newcommand{\EventContrastThreshold}{C_{\text{th}}} \newcommand{\EventDetectionPower}{P_{\text{detect}}} \newcommand{\EventIndicator}{\mathbf{1}} \newcommand{\EventPacket}{e} \newcommand{\EventPolarity}{p} \newcommand{\EventProcessingEnergy}{E_{\text{event}}} \newcommand{\EvidenceCaptureInstant}{t_{\text{capture}}} \newcommand{\EvidenceEpoch}{t_0} \newcommand{\EvidenceHorizon}{\tau_{\text{ev}}} \newcommand{\EvidenceLowerBound}{\mathcal{L}_{\text{ELBO}}} \newcommand{\EvidenceRecordEvent}{e_{\text{obs}}} \newcommand{\ExactFailureLowerLimit}{p_{L}} \newcommand{\ExactFailureUpperLimit}{p_{U}} \newcommand{\ExampleAveragedBatchLoss}{\mathcal{L}_{\text{example}}} \newcommand{\ExampleIndex}{i} \newcommand{\ExampleLabel}{y} \newcommand{\ExceedanceReturnLevel}{z_\epsilon} \newcommand{\ExceedanceSampleSet}{\mathcal{Y}_u} \newcommand{\ExceedanceThreshold}{u} \newcommand{\ExcessDistributionFunction}{F_{u}} \newcommand{\ExcessForcePenaltyWeight}{\lambda_f} \newcommand{\ExcessSupportUpperEndpoint}{y_{\max}} \newcommand{\ExecutedActionStepCount}{T_a} \newcommand{\ExecutedToolCall}{a} \newcommand{\ExecutedTrialCount}{N_{\text{trial}}} \newcommand{\ExecutionHorizon}{H_{\text{exec}}} \newcommand{\ExecutionNondeterminism}{\xi} \newcommand{\ExecutionSwitchTime}{T_{\text{switch}}} \newcommand{\ExogenousDataDistribution}{\mathcal{D}} \newcommand{\ExpectedCategoryFrequency}{n_i^{\text{exp}}} \newcommand{\ExpectedCheckingTime}{T_{\text{check}}} \newcommand{\ExpectedCostLimit}{\delta} \newcommand{\ExpectedDecisionRisk}{\mathcal{R}} \newcommand{\ExpectedHistoryActionReturn}{Q} \newcommand{\ExpectedIrreversibleLoss}{L_A} \newcommand{\ExpectedNormalMaximum}{m_{N}} \newcommand{\ExpectedQueryDistribution}{p_{\text{expected}}} \newcommand{\ExpectedRemainingReturn}{V} \newcommand{\ExpectedReturnObjective}{J} \newcommand{\ExpectedRunCompletionTime}{T} \newcommand{\ExpectedTaskCostSum}{J} \newcommand{\ExperienceReplayBuffer}{\mathcal{D}} \newcommand{\ExperimentCount}{N_{\text{exp}}} \newcommand{\ExperimentUserIndex}{i} \newcommand{\ExpertCapacityFactor}{C_{\text{cap}}} \newcommand{\ExpertCount}{N_{\text{experts}}} \newcommand{\ExpertDiscountedStateVisitationDistribution}{d^{\pi^*}} \newcommand{\ExpertIndex}{e} \newcommand{\ExpertSelectionProbability}{p_e} \newcommand{\ExpertStateVisitationDistribution}{p^{\pi^*}} \newcommand{\ExpertTokenCount}{B_e} \newcommand{\ExploitCandidateFraction}{p_{\text{exp}}} \newcommand{\ExploitTrajectory}{\tau_{\text{hack}}} \newcommand{\ExploratoryStateVisitationDistribution}{p^{\pi_{\text{expl}}}} \newcommand{\ExponentBitIndex}{k} \newcommand{\ExponentialSeriesArgument}{u} \newcommand{\ExponentialStabilityConstant}{k} \newcommand{\ExposedCommunicationTime}{T_{\text{comm,exposed}}} \newcommand{\ExposedUnitCount}{E_{\text{exposure}}} \newcommand{\ExposureDuration}{t_{\text{exp}}} \newcommand{\ExposureMidpointTime}{t_{\text{mid}}} \newcommand{\ExposureMotionDisplacement}{\Delta x_{\text{motion}}} \newcommand{\ExposureStartTime}{t_{\text{start}}} \newcommand{\ExposureTravelDistance}{\Delta x} \newcommand{\ExtendedClassKInfinityFamily}{\mathcal{K}_\infty} \newcommand{\ExtendedDepthLength}{K_{\text{ext}}} \newcommand{\ExternalContactTorque}{\boldsymbol{\tau}_{\text{ext}}} \newcommand{\ExternalDispatchAction}{a_{\text{ext}}} \newcommand{\ExternalDisturbanceForce}{d} \newcommand{\ExternalDisturbanceLoad}{\mathbf{d}_{\text{ext}}} \newcommand{\ExternalJointTorque}{\tau_{\text{ext}}} \newcommand{\ExternalObjectWrench}{\mathbf{w}_{\text{ext}}} \newcommand{\ExternalWait}{T_{\text{wait}}} \newcommand{\ExternalWrench}{\mathbf{F}_{\text{ext}}} \newcommand{\ExtractionAnomalyClassifier}{f_{\theta}} \newcommand{\ExtractionQueryCount}{n_{\text{queries}}} \newcommand{\ExtrinsicCalibrationCovariance}{\boldsymbol{\Sigma}_{\text{ext}}} \newcommand{\ExtrinsicCovarianceJacobian}{\mathbf{J}_{\text{ext}}} \newcommand{\ExtrinsicLateralError}{\Delta y} \newcommand{\ExtrinsicMisalignmentAngle}{\theta_{\text{ext}}} \newcommand{\EyeInHandCameraMotion}{\mathbf{B}} \newcommand{\EyeInHandFlangeMotion}{\mathbf{A}} \newcommand{\EyeInHandUnknownTransform}{\mathbf{X}} \newcommand{\EyeToHandCameraPose}{\mathbf{B}'} \newcommand{\EyeToHandFlangePose}{\mathbf{A}'} \newcommand{\EyeToHandTargetTransform}{\mathbf{Z}} \newcommand{\EyeToHandUnknownTransform}{\mathbf{X}'} \newcommand{\FacilityEnergy}{E_{\text{facility}}} \newcommand{\FacilityHeatRemovalCapacity}{\dot{Q}_{\text{remove,max}}} \newcommand{\FacilityPower}{P_{\text{facility}}} \newcommand{\FacilityWaterConsumption}{W_{\text{water}}} \newcommand{\FactoredIntermediateActivation}{\mathbf{z}} \newcommand{\FactorizationRank}{k} \newcommand{\FailureDetectionTime}{T_{\text{detect}}} \newcommand{\FailureEventCost}{C_{\text{per-failure}}} \newcommand{\FailureFlagLatency}{\delta_{\text{flag}}} \newcommand{\FailureMarginFunction}{l} \newcommand{\FailureModeOccurrenceCount}{n_{f}} \newcommand{\FailureObservationInterval}{T} \newcommand{\FailureOverheadFraction}{F_{\text{fail}}} \newcommand{\FailureRecoveryTime}{T_{\text{recovery}}} \newcommand{\FailureRegion}{F} \newcommand{\FailureSet}{\mathcal{F}_{\text{fail}}} \newcommand{\FailureUpperConfidenceLimit}{p_{\text{fail, upper}}} \newcommand{\FairShareStabilizingConstant}{\epsilon_{\text{stab}}} \newcommand{\FairnessGapTolerance}{\epsilon_{\text{fair}}} \newcommand{\FakeQuantizedOutput}{x_{\text{fake}}} \newcommand{\FallbackCost}{C_{\text{fallback}}} \newcommand{\FallbackDeadline}{T_{\text{deadline,fallback}}} \newcommand{\FallbackHold}{T_{\text{hold}}} \newcommand{\FalseAcceptHarmCost}{C_{\text{harm}}} \newcommand{\FalseApprovalCount}{N_{\text{fa}}} \newcommand{\FalseApprovalOutcomeCount}{k} \newcommand{\FalseApprovalPropensity}{Q} \newcommand{\FalseApprovalPropensityLevel}{q} \newcommand{\FalseDiscoveryRateTarget}{q} \newcommand{\FalsificationInitialStateSet}{\mathcal{X}_0} \newcommand{\FanoutBackendCount}{m} \newcommand{\FarthestCandidateDistance}{D_{\max}} \newcommand{\FatTreeHostCount}{N_{\text{hosts}}} \newcommand{\FatigueLifeCycleCount}{N} \newcommand{\FaultContainmentLatency}{\Delta t_{\text{bounded}}} \newcommand{\FaultDetectionLatency}{\Delta t_{\text{det}}} \newcommand{\FaultDomainIsolation}{\mathcal{F}} \newcommand{\FaultInjectionDuration}{\Delta t_{\text{duration}}} \newcommand{\FaultStartTimestamp}{t_{\text{fault\_start}}} \newcommand{\FaultTakeoverLatency}{\Delta t_{\text{takeover}}} \newcommand{\FaultTakeoverTimestamp}{t_{\text{takeover}}} \newcommand{\FaultToleranceCost}{C_{\text{ft}}} \newcommand{\FaultToleranceInvestment}{x} \newcommand{\FeasibleOutputTokenRate}{\mu_{\text{out}}} \newcommand{\FeasibleTrajectoryProjection}{\Pi_{\mathcal{K}}} \newcommand{\FeasibleTrajectorySet}{\mathcal{K}} \newcommand{\FeatureCategoryCount}{k} \newcommand{\FeatureCategoryIndex}{i} \newcommand{\FeatureCellVector}{\mathbf{f}_{u, v}} \newcommand{\FeatureChannelCount}{C} \newcommand{\FeatureCount}{N_{\text{features}}} \newcommand{\FeatureFreshnessLatency}{T_{\text{freshness}}} \newcommand{\FeatureMapColumnCoordinate}{x} \newcommand{\FeatureMapGrowthRate}{g} \newcommand{\FeatureMapHeight}{H_{\text{img}}} \newcommand{\FeatureMapRowCoordinate}{y} \newcommand{\FeatureMapWidth}{W_{\text{img}}} \newcommand{\FeatureRecordTime}{t} \newcommand{\FeatureRetentionWindow}{T_{\text{retention}}} \newcommand{\FeatureUpdateInterval}{T_{\text{update}}} \newcommand{\FeatureUpdateLag}{T_{\text{staleness}}} \newcommand{\FeatureUpdateTimestamp}{t_{\text{feat}}} \newcommand{\FeatureViewingDistance}{r} \newcommand{\FederatedRoundCount}{R} \newcommand{\FederatedRoundIndex}{t} \newcommand{\FederatedTrainingEnergy}{E_{\text{federated}}} \newcommand{\FeedForwardOperations}{O_{\text{FFN}}} \newcommand{\FeedForwardWidth}{d_{\text{ff}}} \newcommand{\FeedbackCheckDuration}{t_{\text{check}}} \newcommand{\FeedbackCriticalPathLatency}{T^{\text{feedback}}} \newcommand{\FeedbackIntervalCount}{k} \newcommand{\FeedbackStepIndex}{t} \newcommand{\FeedforwardJointTorque}{\boldsymbol{\tau}_{\text{ff}}} \newcommand{\FeedthroughMatrix}{\mathbf{D}} \newcommand{\FewShotStepCount}{n_{\text{steps}}} \newcommand{\FewShotSupportSet}{\mathcal{D}_{\text{shot}}} \newcommand{\FiberPropagationSpeed}{c_{\text{fiber}}} \newcommand{\FieldbusCycleTime}{T_{\text{cycle}}} \newcommand{\FilmEncounterRate}{\lambda_{\text{film}}} \newcommand{\FilterSolveBudget}{T_{\text{budget}}} \newcommand{\FilterSolveTime}{T_{\text{solve}}} \newcommand{\FilterTapCount}{N} \newcommand{\FilterWeight}{w} \newcommand{\FilteredScreenSpaceCovariance}{\boldsymbol{\Sigma}_{2D}'} \newcommand{\FinalBusVoltage}{V_{\text{final}}} \newcommand{\FinalGeneratorLatentVector}{\mathbf{z}_{m}} \newcommand{\FinalLayerFunction}{f_{N_L}} \newcommand{\FinalLayerWidth}{n_{N_L}} \newcommand{\FinalMiniBatchActivation}{a_{B}} \newcommand{\FinalRecurrentHiddenState}{\mathbf{h}_{S}} \newcommand{\FinalWatchdogToken}{T_{\text{final}}} \newcommand{\FingerNormalForce}{f_n} \newcommand{\FingerTangentialForce}{\mathbf{f}_t} \newcommand{\FinishedWorkerCount}{j} \newcommand{\FiniteChange}{\Delta} \newcommand{\FiniteSampleGeneralizationBound}{\delta_N} \newcommand{\FiniteTimeHorizon}{T} \newcommand{\FirstAdjacentCheckIndex}{a} \newcommand{\FirstAdjacentCheckPassProbability}{p_{a}} \newcommand{\FirstAdjacentCheckSlotTime}{T_{a}} \newcommand{\FirstAtomicGradientUpdate}{A} \newcommand{\FirstCatalogDefinitionCount}{n_{\text{def},A}} \newcommand{\FirstCatalogDefinitionSize}{S_{A}} \newcommand{\FirstClassCoverageFloor}{a} \newcommand{\FirstClientMaskedUpdate}{\mathbf{y}_A} \newcommand{\FirstClientModelParameters}{\theta_A} \newcommand{\FirstComparedGroupLabel}{a} \newcommand{\FirstComparedItem}{i} \newcommand{\FirstDiscardedSingularNumber}{\sigma_{r+1}} \newcommand{\FirstErrorStepIndex}{k} \newcommand{\FirstFloatingPointAddend}{a} \newcommand{\FirstGroupClassificationThreshold}{\tau_{\text{thr},a}} \newcommand{\FirstGroupQualifiedFraction}{q_a} \newcommand{\FirstGroupSampleApprovalRate}{\hat{p}_a} \newcommand{\FirstGroupSampleSize}{n_a} \newcommand{\FirstGroupThresholdClassifier}{h_a} \newcommand{\FirstIncidentTime}{t_1} \newcommand{\FirstInputNodePrimal}{v_{1-N}} \newcommand{\FirstJaccardSet}{\mathcal{A}} \newcommand{\FirstMistakeEvent}{\mathcal{E}} \newcommand{\FirstRankComputeTime}{T_{\text{rank}_0}} \newcommand{\FirstRaterCategoryFraction}{p_{y,1}} \newcommand{\FirstRingTraceElement}{a} \newcommand{\FirstSummandStandardDeviation}{\sigma_a} \newcommand{\FirstTwinCriticReturnEstimate}{Q_{\phi_1}} \newcommand{\FittedSensitivity}{\lambda} \newcommand{\FixedClearanceAllowance}{\delta} \newcommand{\FlangeCameraTransform}{\mathbf{T}_{\text{flange}}^{\text{cam}}} \newcommand{\FlangePose}{\mathbf{T}_{\text{flange}}} \newcommand{\FlangeReferenceFrame}{\mathcal{F}_{\text{flange}}} \newcommand{\FlangeTargetTransform}{\mathbf{T}_{\text{flange}}^{\text{target}}} \newcommand{\FlattenedFilterWeights}{\mathbf{w}_{\text{col}}} \newcommand{\FleetAcceleratorCount}{N_{\text{fleet}}} \newcommand{\FleetCommunicationTaxonomyAxis}{C_2} \newcommand{\FleetComputeTaxonomyAxis}{C_1} \newcommand{\FleetCoordinationTaxonomyAxis}{C_3} \newcommand{\FleetEnergyProductivity}{\rho_{\text{energy}}} \newcommand{\FleetManufacturingDistribution}{\mathcal{M}} \newcommand{\FleetResourceCapacity}{C_{r}} \newcommand{\FleetRobotCount}{N_{\text{fleet}}} \newcommand{\FlippedFloatExponentField}{e'} \newcommand{\FloatEncodedNumber}{x} \newcommand{\FloatExponentField}{e} \newcommand{\FloatMantissaField}{m} \newcommand{\FloatSignBit}{s} \newcommand{\FloatingBaseAccelerations}{\ddot{\mathbf{q}}_b} \newcommand{\FloatingBaseBiasForces}{\mathbf{h}_b} \newcommand{\FloatingBaseInertiaBlock}{\mathbf{M}_{bb}} \newcommand{\FloatingBasePose}{\mathbf{q}_b} \newcommand{\FlopPrice}{c_{\text{FLOP}}} \newcommand{\FlowMatchingLoss}{\mathcal{L}_{\text{FM}}} \newcommand{\FlowProbabilityPath}{\rho} \newcommand{\FlowSampleVector}{\mathbf{y}} \newcommand{\FlowTimeCoordinate}{t} \newcommand{\FocalLength}{f} \newcommand{\FollowerForwardWave}{\mathbf{u}_s} \newcommand{\FollowerJointPositions}{\mathbf{q}_{\text{follower}}} \newcommand{\FollowerMechanicalLatency}{t_{\text{mech}}} \newcommand{\FollowerReturnWave}{\mathbf{w}_s} \newcommand{\ForceGuidedRelay}{K} \newcommand{\ForceReadingInnovation}{\nu} \newcommand{\ForceSensorBias}{b} \newcommand{\ForceSensorReading}{y} \newcommand{\ForegroundLatency}{L_{\text{lat,fg}}} \newcommand{\ForgetDataset}{D_{\text{forget}}} \newcommand{\ForkBoundarySet}{\mathcal{B}_{\text{fork}}} \newcommand{\ForkedTrajectoryTokenCount}{N_{\text{total}}} \newcommand{\FormatComplianceScore}{\Phi} \newcommand{\FormatEfficiency}{\eta_{\text{format}}} \newcommand{\FormatRewardWeight}{\lambda_{\text{fmt}}} \newcommand{\ForwardDiffusionDistribution}{q} \newcommand{\ForwardEulerEigenvalue}{\lambda_{\text{FE}}} \newcommand{\ForwardEulerTransitionMatrix}{\mathbf{A}_{\text{FE}}} \newcommand{\ForwardInvariantSafeSet}{\mathcal{C}} \newcommand{\ForwardKinematicsMap}{\mathbf{FK}} \newcommand{\ForwardOccupancySet}{\mathcal{R}} \newcommand{\ForwardPassTokenCount}{n} \newcommand{\ForwardPosteriorMean}{\tilde{\boldsymbol{\mu}}} \newcommand{\ForwardPosteriorVariance}{\tilde{\beta}} \newcommand{\FourthRingTraceElement}{d} \newcommand{\FrameBitCount}{B_{\text{frame}}} \newcommand{\FrameBlockingTime}{B} \newcommand{\FrameExposureStartTime}{t_{\text{start}}} \newcommand{\FrameIndex}{i} \newcommand{\FramePayloadSize}{B_{\text{payload}}} \newcommand{\FramePeriod}{T} \newcommand{\FrameReadoutTime}{t_{\text{readout}}} \newcommand{\FrameReleaseJitter}{J} \newcommand{\FrameResponseTime}{R} \newcommand{\FrameSerializationTime}{t_{\text{frame},i}} \newcommand{\FrameTransmissionTime}{C} \newcommand{\FrameWireBitCount}{B_{\text{wire},i}} \newcommand{\FreeConfigurationSpace}{\mathcal{C}_{\text{free}}} \newcommand{\FreeCreditCount}{N_{\text{free}}} \newcommand{\FreeSpaceDepth}{d_{\text{free}}} \newcommand{\FreeSpaceLogOddsIncrement}{L_{\text{free}}} \newcommand{\FreeSurfaceTiltAngle}{\theta_{\text{tilt}}} \newcommand{\FreeboardHeight}{h_{f}} \newcommand{\FreshEvidenceTime}{t_{\text{fresh}}} \newcommand{\FreshInputTokenCount}{S_{\text{fresh}}} \newcommand{\FreshnessObjective}{S_{\text{freshness}}} \newcommand{\FrictionCoefficientFloor}{\mu_{\min}} \newcommand{\FrictionPyramidMatrix}{\mathbf{F}} \newcommand{\FrobeniusNorm}{F} \newcommand{\FrozenBackboneFunction}{f} \newcommand{\FrozenFeatureEncoder}{f} \newcommand{\FrozenWeightMatrix}{\mathbf{W}_{\text{frozen}}} \newcommand{\FrustumFeature}{\mathbf{c}_{u, v, k}} \newcommand{\FullBatchLoss}{\mathcal{L}_B} \newcommand{\FullDatasetSize}{D_{\text{total}}} \newcommand{\FullPrecisionWeight}{w} \newcommand{\FullSnapshotWriteVolume}{D_{\text{vol,full}}} \newcommand{\FullSpeedTravelTime}{b} \newcommand{\FunctionInputAdjoint}{\bar{x}} \newcommand{\FunctionInputDimension}{N} \newcommand{\FunctionInputElement}{x} \newcommand{\FunctionInputTangent}{\dot{x}} \newcommand{\FunctionInputVariable}{x} \newcommand{\FunctionInputVector}{\mathbf{x}} \newcommand{\FunctionJacobian}{\mathbf{J}} \newcommand{\FunctionOutputDimension}{M} \newcommand{\FunctionOutputElement}{y} \newcommand{\FunctionOutputVariable}{z} \newcommand{\FunctionOutputVector}{\mathbf{y}} \newcommand{\FunctionSecondInputVariable}{y} \newcommand{\FundamentalMatrix}{\mathbf{F}} \newcommand{\FusedConvolutionBias}{\mathbf{b}_{\text{fused}}} \newcommand{\FusedConvolutionWeight}{\mathbf{W}_{\text{fused}}} \newcommand{\FusedTokenCount}{N_{\text{total}}} \newcommand{\FusionCandidate}{x_{\text{cand}}} \newcommand{\FusionInputList}{\mathcal{L}} \newcommand{\FusionInputRank}{r} \newcommand{\FusionInputTensor}{\mathbf{X}} \newcommand{\FusionIntermediateTensor}{\mathbf{Z}} \newcommand{\FusionOutputTensor}{\mathbf{Y}} \newcommand{\FutureControlTrajectory}{\mathbf{u}_{[t, \infty)}} \newcommand{\FutureTimeInstant}{t'} \newcommand{\GaeAdvantageEstimate}{\widehat{A}^{\text{GAE}}} \newcommand{\GateCurrent}{I_g} \newcommand{\GateDriverSkew}{t_{\text{prop, skew}}} \newcommand{\GatePropagationDelay}{t_{\text{prop}}} \newcommand{\GateSourceCapacitance}{C_{\text{gs}}} \newcommand{\GateSourceCharge}{Q_{\text{gs}}} \newcommand{\GateSourceVoltage}{V_{\text{gs}}} \newcommand{\GaussianCovarianceMatrix}{\boldsymbol{\Sigma}} \newcommand{\GaussianDistribution}{\mathcal{N}} \newcommand{\GaussianFirstAxisScale}{s_{x}} \newcommand{\GaussianMeanVector}{\boldsymbol{\mu}} \newcommand{\GaussianMechanismNoiseVector}{\mathbf{z}} \newcommand{\GaussianMechanismStandardDeviation}{\sigma_{\text{mech}}} \newcommand{\GaussianOpacityLogit}{o} \newcommand{\GaussianPrimitiveCovariance}{\boldsymbol{\Sigma}} \newcommand{\GaussianPrimitiveDensity}{G} \newcommand{\GaussianPrimitiveIndex}{i} \newcommand{\GaussianPrimitiveMean}{\boldsymbol{\mu}} \newcommand{\GaussianPrimitiveOpacity}{\alpha} \newcommand{\GaussianPrimitiveScaleMatrix}{\mathbf{S}} \newcommand{\GaussianSecondAxisScale}{s_{y}} \newcommand{\GaussianStandardDeviation}{\sigma} \newcommand{\GaussianThirdAxisScale}{s_{z}} \newcommand{\GaussianViewDependentColor}{c} \newcommand{\GearFaceWidth}{b} \newcommand{\GearModule}{m} \newcommand{\GearRatedFatigueLife}{L_{\text{gear}}} \newcommand{\GearReductionRatio}{N_{\text{gear}}} \newcommand{\GearTangentialLoad}{W_t} \newcommand{\GearToothBendingStress}{\sigma_b} \newcommand{\GearTorqueReversalCount}{n_{\text{gear}}} \newcommand{\GearboxTransmissionEfficiency}{\eta_{\text{gear}}} \newcommand{\GemmAccumulatorScale}{\beta} \newcommand{\GemmColumnDimension}{N} \newcommand{\GemmInnerDimension}{K} \newcommand{\GemmLeftOperand}{\mathbf{A}} \newcommand{\GemmLeftOperandElement}{A} \newcommand{\GemmLeftOperandEntry}{A_{ik}} \newcommand{\GemmOutputElement}{C} \newcommand{\GemmOutputEntry}{C_{ij}} \newcommand{\GemmOutputMatrix}{\mathbf{C}} \newcommand{\GemmProductScale}{\alpha} \newcommand{\GemmReductionIndex}{k} \newcommand{\GemmRightOperand}{\mathbf{B}} \newcommand{\GemmRightOperandElement}{B} \newcommand{\GemmRightOperandEntry}{B_{kj}} \newcommand{\GemmRowDimension}{M} \newcommand{\GemmTileColumnDimension}{N_{\text{tile}}} \newcommand{\GemmTileInnerDimension}{K_{\text{tile}}} \newcommand{\GemmTileRowDimension}{M_{\text{tile}}} \newcommand{\GemvArithmeticIntensity}{I_{\text{GEMV}}} \newcommand{\GeneralPurposeEnergyProductivity}{\rho_{\text{energy,general}}} \newcommand{\GeneralizedAccelerationLowerBound}{\ddot{\mathbf{q}}_{\min}} \newcommand{\GeneralizedAccelerationUpperBound}{\ddot{\mathbf{q}}_{\max}} \newcommand{\GeneralizedAccelerations}{\ddot{\mathbf{q}}} \newcommand{\GeneralizedBiasForces}{\mathbf{h}} \newcommand{\GeneralizedCoordinateCount}{n} \newcommand{\GeneralizedCoordinates}{\mathbf{q}} \newcommand{\GeneralizedInertiaMatrix}{\mathbf{M}} \newcommand{\GeneralizedParetoDistribution}{H} \newcommand{\GeneralizedParetoLikelihood}{L} \newcommand{\GeneralizedVelocities}{\dot{\mathbf{q}}} \newcommand{\GeneratedResponse}{y} \newcommand{\GeneratedSampleCount}{n} \newcommand{\GeneratedTokenCap}{N_{\text{cap}}} \newcommand{\GenerationStepErrorRate}{\lambda_{\text{error}}} \newcommand{\GenerativeActionModelDistribution}{p_\theta} \newcommand{\GeneratorLatentVector}{\mathbf{z}} \newcommand{\GenericRandomVariable}{X} \newcommand{\GeometricStateRepresentation}{\mathbf{Z}_{\text{geom}}} \newcommand{\GevLocationParameter}{\mu} \newcommand{\GevScaleParameter}{\sigma} \newcommand{\GlobalBatchGradient}{\mathbf{g}_{\text{global}}} \newcommand{\GlobalBatchSize}{B_{\text{global}}} \newcommand{\GlobalDeviationPenalty}{\mathcal{R}} \newcommand{\GlobalModelParameters}{\theta_{\text{global}}} \newcommand{\GoalConfiguration}{\mathbf{q}_{\text{goal}}} \newcommand{\GoalSet}{\mathcal{G}_{\text{goal}}} \newcommand{\GoodputRelativeTolerance}{\epsilon_{\mathcal{G}}} \newcommand{\GpdCumulativeDistribution}{F_{\text{GPD}}} \newcommand{\GpdScaleParameter}{\tilde{\sigma}} \newcommand{\GpuAvailability}{A_{\text{GPU}}} \newcommand{\GpuEnergy}{E_{\text{GPU}}} \newcommand{\GpuFailureRate}{\lambda_{\text{GPU}}} \newcommand{\GpuMttf}{\text{MTTF}_{\text{GPU}}} \newcommand{\GpuTopologicalDistance}{d} \newcommand{\GradientClippingNorm}{C} \newcommand{\GradientCovarianceMatrix}{\Sigma} \newcommand{\GradientElementCount}{d_{\text{grad}}} \newcommand{\GradientMemory}{M_{\text{gradients}}} \newcommand{\GradientPayload}{M_{\text{grad}}} \newcommand{\GradientStaleness}{\tau_{\text{stale}}} \newcommand{\GrantAllowedAccesses}{\mathcal{A}} \newcommand{\GrantCondition}{\phi_{\Gamma}} \newcommand{\GrantExpiryTime}{t_{\text{exp}}} \newcommand{\GrantIssueTime}{T} \newcommand{\GrantRights}{\mathcal{R}_{\Gamma}} \newcommand{\GraphEdgeSet}{E} \newcommand{\GraphNodeIndex}{i} \newcommand{\GraphNodeSet}{V} \newcommand{\GraspContactDisplacement}{\mathbf{d}} \newcommand{\GraspForceCeiling}{f_{\max}} \newcommand{\GraspForceFloor}{f_{\min}} \newcommand{\GraspMap}{\mathbf{G}} \newcommand{\GraspOrientation}{\mathbf{R}_{\text{grasp}}} \newcommand{\GraspPose}{\mathbf{T}_{\text{grasp}}} \newcommand{\GraspPosition}{\mathbf{p}_{\text{grasp}}} \newcommand{\GraspVerticalAcceleration}{a_z} \newcommand{\GravitationalTorqueVector}{\mathbf{g}} \newcommand{\Gravity}{g} \newcommand{\GravityCenterHeight}{h_{\text{cg}}} \newcommand{\GravityVector}{\mathbf{g}_0} \newcommand{\GridFeedCapacity}{P_{\text{grid}}} \newcommand{\GridSideCellCount}{N} \newcommand{\GripContactForce}{x} \newcommand{\GripperContactAngle}{\theta_{\text{contact}}} \newcommand{\GripperOpeningCommand}{a_{\text{gripper}}} \newcommand{\GroundPlaneAbscissa}{x} \newcommand{\GroundPlaneOrdinate}{y} \newcommand{\GroupCommitWaitTime}{L_{\text{lat}, i}} \newcommand{\GroupContrastProbability}{p_{\text{contrast}}} \newcommand{\GroupDisparity}{\Delta_g} \newcommand{\GroupMeanReward}{\mu_{R}} \newcommand{\GroupRelativeAdvantage}{\hat{A}} \newcommand{\GroupRewardStandardDeviation}{\sigma_{R}} \newcommand{\GroupRolloutIndex}{i} \newcommand{\GroupSize}{G} \newcommand{\GrpoSampledObjective}{\widehat{\mathcal{J}}_{\text{GRPO}}} \newcommand{\GuardBandDuration}{t_{\text{guard}}} \newcommand{\GuardedContactPredicate}{P_{\text{contact}}} \newcommand{\GuestImageMemory}{M_{\text{guest}}} \newcommand{\GuestKernelBootTime}{T_{\text{kernel}}} \newcommand{\HadamardRotationMatrix}{\mathbf{H}} \newcommand{\HalfPrecisionGemvIntensity}{I_{\text{GEMV, 16-bit}}} \newcommand{\HammingDataBitCount}{n} \newcommand{\HandForceCriterion}{F_h} \newcommand{\HandleAffordanceFrame}{\mathcal{F}_{\text{handle}}} \newcommand{\HandoffExceedanceProbability}{\epsilon} \newcommand{\HandoverTimeout}{T_{\text{timeout}}} \newcommand{\HandoverTimeoutCeiling}{T_{\text{config}}} \newcommand{\HandshakeProtocolLatency}{T_{\text{handshake}}} \newcommand{\HardwareCommonCauseRate}{\lambda_{\text{other}}} \newcommand{\HardwareParameterVector}{\boldsymbol{\xi}_{\text{real}}} \newcommand{\HardwareServiceLife}{T_{\text{lifetime}}} \newcommand{\HarmInclusiveTaskCost}{C_{\text{with\ harm}}} \newcommand{\HarmInstant}{t_{\text{harm}}} \newcommand{\HarmLeadTime}{t_{\text{harm}}} \newcommand{\HarmonicDriveTorsionalStiffness}{k_c} \newcommand{\HarmonicPeriodMultiple}{m} \newcommand{\HarnessConnectorResistance}{R_{\text{harness}}} \newcommand{\HashBucketCount}{N_{\text{buckets}}} \newcommand{\HashEntrySize}{s_{\text{entry}}} \newcommand{\HashRingServer}{s} \newcommand{\HashRingServerCount}{N} \newcommand{\HashRingServerSet}{\mathcal{S}_{\text{srv}}} \newcommand{\HashedGridMemory}{M_{\text{hashed}}} \newcommand{\HazardClassIndex}{h} \newcommand{\HazardOnset}{t_{\text{onset}}} \newcommand{\HazardOnsetBound}{t_{\text{bound}}} \newcommand{\HazardousProposalRate}{\lambda_{\text{proposal}, h}} \newcommand{\HazardousWorldState}{s_B} \newcommand{\HeadAxisLabel}{h} \newcommand{\HeadByteAllocation}{M_{\text{head}}} \newcommand{\HeadComponentIndex}{m} \newcommand{\HeadDimensionAxisLabel}{d} \newcommand{\HeadKeyProjectionMatrix}{\mathbf{W}_{K,i}} \newcommand{\HeadQueryProjectionMatrix}{\mathbf{W}_{Q,i}} \newcommand{\HeadSamplingProbability}{\theta} \newcommand{\HeadValuesProjectionMatrix}{\mathbf{W}_{V,i}} \newcommand{\HeadingAngle}{\theta_{\text{head}}} \newcommand{\HeadingCurvature}{\kappa} \newcommand{\HealthyStepTime}{T_{\text{healthy}}} \newcommand{\HeartbeatAge}{\Delta t_{\text{heartbeat}}} \newcommand{\HeartbeatInterval}{H} \newcommand{\HeartbeatReceiptTime}{t_{\text{local}}} \newcommand{\HeartbeatSequenceCounter}{k} \newcommand{\HeartbeatTimestamp}{t^{\text{hb}}} \newcommand{\HeatDissipationPower}{P_{\text{heat}}} \newcommand{\HermiteBasisFunction}{h} \newcommand{\HermiteInterpolationFraction}{\lambda} \newcommand{\HermiteSegmentProgress}{s} \newcommand{\HertzianContactCoefficient}{k_{c}} \newcommand{\HertzianContactStiffness}{k_H} \newcommand{\HiddenActivation}{\mathbf{h}} \newcommand{\HiddenActivationMatrix}{\mathbf{H}} \newcommand{\HiddenDimension}{d} \newcommand{\HiddenUnitOutput}{h} \newcommand{\HighOccupancyBinCount}{m} \newcommand{\HigherPriorityFrames}{hp} \newcommand{\HigherPriorityTasks}{hp} \newcommand{\HighestSignalFrequency}{f_{\max}} \newcommand{\HnswLayerIndex}{L} \newcommand{\HnswLevelDraw}{U} \newcommand{\HnswLevelNormalization}{m_\ell} \newcommand{\HnswMaximumConnectionCount}{M} \newcommand{\HnswSearchBeamWidth}{ef_{\text{search}}} \newcommand{\HoldingTorque}{\tau_{\text{hold}}} \newcommand{\HomogeneousCameraFramePoint}{\tilde{\mathbf{p}}_C} \newcommand{\HomogeneousPixelCoordinates}{\tilde{\mathbf{m}}} \newcommand{\HomogeneousPointCoordinates}{\tilde{\mathbf{p}}} \newcommand{\HomogeneousTransform}{\mathbf{T}_{AB}} \newcommand{\HomogeneousWorldFramePoint}{\tilde{\mathbf{p}}_W} \newcommand{\HomographyColumn}{\mathbf{h}} \newcommand{\HomographyColumnEntry}{h} \newcommand{\HomographyConstraintVector}{\mathbf{v}} \newcommand{\HomographyScaleFactor}{\lambda} \newcommand{\HomomorphicCiphertext}{c} \newcommand{\HomomorphicFunction}{f} \newcommand{\HomomorphicPublicKey}{pk} \newcommand{\HomomorphicSecretKey}{sk} \newcommand{\HorizonStepIndex}{k} \newcommand{\HorizontalFocalLength}{f_x} \newcommand{\HostArrivalTimestamp}{t_{\text{host}}} \newcommand{\HostHeartbeatRate}{f_{\text{heartbeat}}} \newcommand{\HostLinkBandwidth}{\text{BW}_{\text{link}}} \newcommand{\HostPower}{P_{\text{host}}} \newcommand{\HostPreparationTime}{T_{\text{prep}}} \newcommand{\HostRuntimeCount}{N_{\text{host}}} \newcommand{\HostSoftwareTime}{T_{\text{sw}}} \newcommand{\HostTransferBandwidth}{\text{BW}_{\text{host}}} \newcommand{\HotTierHitProbability}{h} \newcommand{\HotTierServiceTime}{T_{\text{hot}}} \newcommand{\HourlyAccountQueryCount}{q_{\text{hourly}}} \newcommand{\HourlyComponentFailureRate}{\lambda_{\text{hour}}} \newcommand{\HuberLossThreshold}{\delta} \newcommand{\HullQueryTime}{t_{\text{query}}} \newcommand{\HullSphereRadius}{r_{\text{hull}}} \newcommand{\HumanCommandRate}{\dot{\mathbf{u}}_{\text{human}}} \newcommand{\HumanControlCommand}{\mathbf{u}_{\text{human}}} \newcommand{\HumanFallbackCost}{C_{h}} \newcommand{\HumanReactionTime}{T_{\text{human}}} \newcommand{\HumanResolutionProbability}{h} \newcommand{\HumanReviewCost}{C_{\text{human}}} \newcommand{\HumanStandaloneSensitivity}{S_{\text{human}}} \newcommand{\HumanWalkingSpeedBound}{v_h} \newcommand{\HybridIterationTime}{T_{\text{step}}} \newcommand{\HydraulicSupplyPressure}{p} \newcommand{\HypothesisIndex}{h} \newcommand{\HypothesisTestFalseNegativeRate}{\beta_{\text{stat}}} \newcommand{\HypothesisTestSignificanceLevel}{\alpha_{\text{sig}}} \newcommand{\HypothesizedAcceptanceProbability}{p} \newcommand{\HypothesizedTrialFailureProbability}{p} \newcommand{\IdealAcceleratorTime}{T_{\text{ideal}}} \newcommand{\IdealMemoryQueueDelay}{t_{\text{queue,ideal}}} \newcommand{\IdempotentAlgebraElement}{x} \newcommand{\IdentityMatrix}{\mathbf{I}} \newcommand{\IllustrativeFunction}{f} \newcommand{\ImageChannelCount}{C} \newcommand{\ImageChannelIndex}{c} \newcommand{\ImageColumnIndex}{w} \newcommand{\ImageEpipole}{\mathbf{e}} \newcommand{\ImageHeight}{H} \newcommand{\ImagePlanePixelCoordinates}{\mathbf{u}_{\text{px}}} \newcommand{\ImageRowIndex}{h} \newcommand{\ImageTensorElement}{X} \newcommand{\ImageWidth}{W} \newcommand{\ImaginaryUnit}{j} \newcommand{\ImitationLearnedPolicy}{\hat{\pi}} \newcommand{\ImitationTargetCommand}{\mathbf{u}_{\text{target}}} \newcommand{\ImmediateTaskCostScore}{C} \newcommand{\ImpactInstant}{T} \newcommand{\ImpactRiseTime}{t_{\text{rise}}} \newcommand{\ImpactSpeed}{v_{\text{impact}}} \newcommand{\ImpedanceControlledPosition}{x} \newcommand{\ImpedanceControlledVelocity}{\dot{x}} \newcommand{\ImpedanceEquilibriumPosition}{x_{\text{des}}} \newcommand{\ImpedanceEquilibriumVelocity}{\dot{x}_{\text{des}}} \newcommand{\ImpedanceRestoringForce}{F} \newcommand{\ImplicitPolicyEnergyFunction}{E_\theta} \newcommand{\ImportanceProposalDistribution}{q} \newcommand{\ImportanceSampledFailureProbability}{\hat{p}_F} \newcommand{\ImuSampleTime}{t_{\text{IMU}}} \newcommand{\InContactViableSet}{\mathcal{C}_{\text{contact}}} \newcommand{\IncidenceAngle}{\theta_{\text{inc}}} \newcommand{\IncidentOpticalPower}{P_{\text{opt}}} \newcommand{\IncomingChannelCommand}{u_{\text{new}}} \newcommand{\IncomingCommandDerivative}{\dot{u}_{\text{new}}} \newcommand{\IncorrectCandidateTrialPassProbability}{p_{b}} \newcommand{\IncrementalSnapshotWriteVolume}{D_{\text{vol,delta}}} \newcommand{\IncumbentControlCommand}{\mathbf{u}^{\text{incumbent}}} \newcommand{\IncumbentInterventionRate}{\lambda_{\text{incumbent}}} \newcommand{\IncumbentTrackingErrorStandardDeviation}{\sigma_{\text{incumbent}}} \newcommand{\IndependentAttemptCount}{k} \newcommand{\IndependentEventProbability}{p} \newcommand{\IndependentSampleRate}{f} \newcommand{\IndexGraphNodeSet}{V} \newcommand{\IndexedDocumentCount}{N} \newcommand{\IndicatorFunction}{\mathbb{I}} \newcommand{\InducedGateVoltage}{V_{\text{gs,induced}}} \newcommand{\InductiveVoltage}{v} \newcommand{\InequalityConstraintFunction}{g} \newcommand{\InertiaMatchingRatio}{N^*} \newcommand{\InertiaMatrixDerivative}{\dot{\mathbf{M}}} \newcommand{\InertialIntegrationTime}{T} \newcommand{\InferenceActiveTime}{t_{\text{inference}}} \newcommand{\InferenceCost}{C_{\text{infer}}} \newcommand{\InferenceDutyCycle}{\alpha_{\text{duty}}} \newcommand{\InferenceEnergy}{E_{\text{inf}}} \newcommand{\InferenceLatency}{L_{\text{lat,infer}}} \newcommand{\InferenceLoadSocPower}{P_{\text{load}}} \newcommand{\InflatedHullRadius}{r_{\text{inflated}}} \newcommand{\InflightRolloutReservation}{M_{\text{inflight}}} \newcommand{\InfluenceFunction}{I} \newcommand{\InformationTechnologyEnergy}{E_{\text{IT}}} \newcommand{\InformationTechnologyHeatLoad}{\dot{Q}_{\text{IT}}} \newcommand{\InformationTechnologyPower}{P_{\text{IT}}} \newcommand{\InformativeTaskFraction}{p_{\text{inform}}} \newcommand{\IngestionPricePerSample}{C_{\text{ingest/sample}}} \newcommand{\InitialAccuracy}{\text{Accuracy}_0} \newcommand{\InitialBusVoltage}{V_{\text{initial}}} \newcommand{\InitialPositionStandardDeviation}{\sigma_{p,0}} \newcommand{\InitialPositionVelocityCovariance}{\sigma_{pv,0}} \newcommand{\InitialProposalDistribution}{q_{\boldsymbol{\psi}_0}} \newcommand{\InitialStateDistribution}{\rho_0} \newcommand{\InitialTrackingError}{e_0} \newcommand{\InitialVelocityStandardDeviation}{\sigma_{v,0}} \newcommand{\InitiatedTasks}{N} \newcommand{\InjectionBandwidth}{\text{BW}_{\text{inject}}} \newcommand{\InjectionTriggerEpoch}{t_{\text{inject}}} \newcommand{\InnerChainTransform}{\mathbf{T}_{BC}} \newcommand{\InnerLayerFunction}{g} \newcommand{\InnerProductLeftComponent}{a} \newcommand{\InnerProductLeftVector}{\mathbf{a}} \newcommand{\InnerProductRightComponent}{v} \newcommand{\InnerProductRightVector}{\mathbf{b}} \newcommand{\InnovationBias}{b} \newcommand{\InnovationCovariance}{\mathbf{S}} \newcommand{\InnovationVariance}{S} \newcommand{\InputCaptureTime}{T_{\text{capture}}} \newcommand{\InputChannelCount}{C_{\text{in}}} \newcommand{\InputChannelIndex}{c} \newcommand{\InputColumnLieDerivativeOperator}{L_{\mathbf{g}_j}} \newcommand{\InputConsumerAcceleratorCount}{N_{\text{GPU}}} \newcommand{\InputCoordinateCount}{d} \newcommand{\InputDistribution}{p(x)} \newcommand{\InputEventRate}{r_{\text{event}}} \newcommand{\InputFeatureIndex}{i} \newcommand{\InputFeatureVector}{\mathbf{x}} \newcommand{\InputLieDerivativeOperator}{L_{\mathbf{g}}} \newcommand{\InputNodePrimal}{v_{i-N}} \newcommand{\InputPipelineRate}{R_{\text{pipeline}}} \newcommand{\InputPipelineRatio}{r_{\text{pipe}}} \newcommand{\InputPipelineServiceRate}{r_{\text{pipeline}}} \newcommand{\InputPipelineStageIndex}{j} \newcommand{\InputQuantizationScale}{s_X} \newcommand{\InputResolution}{r} \newcommand{\InputStageServiceRate}{r} \newcommand{\InputTokenPrice}{c_{\text{in}}} \newcommand{\InputTokenSequence}{x_{1:S}} \newcommand{\InputVariableIndex}{m} \newcommand{\InsetAvailableBrakingDistance}{D_{\text{avail}}} \newcommand{\InstanceReplenishTime}{T_{\text{init}}} \newcommand{\InstantaneousPhaseCurrent}{i_{\text{phase}}} \newcommand{\InstantaneousRequestOccupancy}{Q} \newcommand{\IntegerWeightCode}{q} \newcommand{\IntegralControlEffort}{\mathbf{u}_{\text{int}}} \newcommand{\IntegralGainMatrix}{\mathbf{K}_{i}} \newcommand{\IntegratedPixelResponse}{I_{\text{pixel}}} \newcommand{\IntegrationCandidateCommitHash}{h_{\text{candidate}}} \newcommand{\IntegrationDummyTime}{t'} \newcommand{\IntegrationHeadCommitHash}{h_{\text{head}}} \newcommand{\IntegrationPoint}{\mathbf{y}} \newcommand{\IntegrationPointCoordinate}{y} \newcommand{\IntegrationTimeInstant}{s} \newcommand{\IntegratorState}{\mathbf{z}} \newcommand{\IntegratorStateRate}{\dot{\mathbf{z}}} \newcommand{\IntegratorUnwindDelay}{T_{\text{unwind}}} \newcommand{\IntegrityProvenance}{\iota} \newcommand{\IntegrityTrustLabel}{\iota} \newcommand{\IntentAcknowledgmentEvent}{e_{\text{flush}}} \newcommand{\IntentAdministrativeLease}{T_{\text{admin}}} \newcommand{\IntentDemonstrationDataset}{\mathcal{D}_{\text{intent}}} \newcommand{\IntentLease}{\mathcal{I}_{\text{intent}}} \newcommand{\IntentLeaseExpiry}{t_{\text{intent\_exp}}} \newcommand{\IntentProposalPeriod}{T_{\text{period}}} \newcommand{\InterAnnotatorAgreement}{\kappa} \newcommand{\InterFeedInterval}{T_{\text{feed}}} \newcommand{\InterGroupColumnDelay}{t_{\text{CCD\_S}}} \newcommand{\InterKernelGapTime}{T_{\text{gap}}} \newcommand{\InterNodeContextParallelDegree}{c_{\text{inter}}} \newcommand{\InterQueryIntervalDeviation}{\sigma_{\text{inter-query}}} \newcommand{\InterSensorClockSkew}{\Delta t_{\text{skew}}} \newcommand{\InteractionHistory}{h} \newcommand{\InteractionPortForce}{F} \newcommand{\InteractionPortVelocity}{v} \newcommand{\InterarrivalVariationCoefficient}{c_{a}} \newcommand{\InterfaceMaterialThermalResistance}{R_{\text{th,TIM}}} \newcommand{\InterferenceSlowdownFactor}{r_{\text{slow}}} \newcommand{\InterframeSpacingTime}{t_{\text{interframe},i}} \newcommand{\InterleavedPipelineBubbleFraction}{b_{\text{interleaved}}} \newcommand{\IntermediateTensorSize}{M_{\text{tensor}}} \newcommand{\InternalDissipationPower}{g} \newcommand{\IntervalCompletionTime}{T_{\text{total}}} \newcommand{\IntervalMean}{\bar{T}} \newcommand{\IntervalMeanOccupancy}{\bar{Q}} \newcommand{\IntervalNormalQuantile}{z} \newcommand{\IntervalStandardDeviation}{\sigma} \newcommand{\IntervalTransitionMatrix}{\boldsymbol{\Phi}} \newcommand{\IntervalVariationCoefficient}{c} \newcommand{\InterventionDensity}{D_{\text{int}}} \newcommand{\InterventionRate}{\lambda_{\text{int}}} \newcommand{\InterventionWindowDuration}{W} \newcommand{\IntraClusterCorrelation}{\rho_{\text{ICC}}} \newcommand{\IntraGroupColumnDelay}{t_{\text{CCD\_L}}} \newcommand{\IntraNodeContextParallelDegree}{c_{\text{intra}}} \newcommand{\IntrusionDistance}{C} \newcommand{\IntrusionDistanceAllowance}{C} \newcommand{\InvalidatedArtifactNode}{v} \newcommand{\InverseDepth}{\rho} \newcommand{\InverseDepthLandmarkParameters}{\mathbf{y}} \newcommand{\InverseKinematicsDamping}{\lambda} \newcommand{\InverseSensorLogOdds}{L_{\text{sensor}}} \newcommand{\InverterCurrentLimit}{I_{\max}} \newcommand{\InverterDeadTime}{t_{\text{dead}}} \newcommand{\IoTransferTime}{T_{\text{IO}}} \newcommand{\IronCaseThermalResistance}{R_{\text{th,iron-case}}} \newcommand{\IronLawComputeTime}{T_{\text{compute}}} \newcommand{\IronLawMemoryTime}{T_{\text{memory}}} \newcommand{\IronLossPower}{P_{\text{iron}}} \newcommand{\IronThermalCapacitance}{C_{\text{iron}}} \newcommand{\IrreducibleLoss}{C_{\mathcal{L}}} \newcommand{\IsolatedEnforcerExecutionTime}{t_{\text{iso}}} \newcommand{\IsolatedJobRunTime}{T} \newcommand{\IspProcessingTime}{t_{\text{ISP}}} \newcommand{\IsrExecutionTime}{t_{\text{ISR}}} \newcommand{\IterationCost}{C_{\text{iter}}} \newcommand{\IterationTokenBudget}{N_{\text{budget}}} \newcommand{\JaccardSimilarity}{J} \newcommand{\JacobianLeftSingularMatrix}{\mathbf{U}} \newcommand{\JacobianLeftSingularVector}{\mathbf{u}} \newcommand{\JacobianPseudoinverse}{\mathbf{J}^\dagger} \newcommand{\JacobianRightSingularMatrix}{\mathbf{V}} \newcommand{\JacobianRightSingularVector}{\mathbf{v}} \newcommand{\JacobianSingularNumber}{\sigma} \newcommand{\JacobianSingularNumberMatrix}{\boldsymbol{\Sigma}} \newcommand{\JawAperture}{w_{\text{aperture}}} \newcommand{\JensenShannonDivergence}{\mathcal{D}_{\text{JS}}} \newcommand{\JensenShannonMixtureDistribution}{\bar{P}} \newcommand{\JerkLimit}{j_{\max}} \newcommand{\JerkWeightMatrix}{\mathbf{W}_j} \newcommand{\JitterBufferPlayoutDelay}{T_{\text{buf}}} \newcommand{\JobAbsoluteDeadline}{d} \newcommand{\JobAvailability}{A_{\text{all}}} \newcommand{\JobDuration}{T_{\text{job}}} \newcommand{\JobIndex}{j} \newcommand{\JobQueueWaitTime}{W} \newcommand{\JobReleaseTime}{r} \newcommand{\JobRestartTime}{T_{\text{restart}}} \newcommand{\JobSlowdown}{S} \newcommand{\JobStartupTime}{T_{\text{startup}}} \newcommand{\JointAcceleration}{\ddot{q}} \newcommand{\JointAngle}{\theta_{\text{joint}}} \newcommand{\JointAngleLowerLimit}{q_{\min}} \newcommand{\JointAngleUpperLimit}{q_{\max}} \newcommand{\JointAngularAcceleration}{\dot{\omega}} \newcommand{\JointAngularRate}{\omega} \newcommand{\JointAngularSpeed}{\omega} \newcommand{\JointBaseInertiaCoupling}{\mathbf{M}_{jb}} \newcommand{\JointBiasTorque}{\tau_{\text{bias}}} \newcommand{\JointCoordinate}{q} \newcommand{\JointCount}{n} \newcommand{\JointFrictionTorque}{\tau_{\text{fric}}} \newcommand{\JointIndex}{i} \newcommand{\JointJerk}{j_{\text{joint}}} \newcommand{\JointLoadTorque}{\tau_{\text{load}}} \newcommand{\JointOutputImpedance}{Z_{\text{out}}} \newcommand{\JointOutputTorque}{\tau_{\text{out}}} \newcommand{\JointPathCurvature}{\mathbf{q}''} \newcommand{\JointPathTangent}{\mathbf{q}'} \newcommand{\JointPosition}{q} \newcommand{\JointPositionLowerLimit}{\mathbf{q}_{\min}} \newcommand{\JointPositionSetpoint}{\mathbf{q}^*} \newcommand{\JointPositionTarget}{q_{\text{des}}} \newcommand{\JointPositionUpperLimit}{\mathbf{q}_{\max}} \newcommand{\JointReflectedRotorInertia}{J_{m}} \newcommand{\JointSampleTimestamp}{t_{\text{joint}}} \newcommand{\JointTorque}{\boldsymbol{\tau}} \newcommand{\JointTorqueConstant}{K_t} \newcommand{\JointTorqueLimit}{\tau_{\max}} \newcommand{\JointTorqueLimits}{\boldsymbol{\tau}_{\max}} \newcommand{\JointTorqueLowerLimit}{\boldsymbol{\tau}_{\min}} \newcommand{\JointTorqueSlew}{\dot{\boldsymbol{\tau}}} \newcommand{\JointTorqueSlewLimit}{\dot{\boldsymbol{\tau}}_{\max}} \newcommand{\JointTorqueTarget}{\tau_{\text{des}}} \newcommand{\JointTorqueUpperLimit}{\boldsymbol{\tau}_{\max}} \newcommand{\JointTorsionalStiffnessMatrix}{\mathbf{K}} \newcommand{\JointTrackingError}{\mathbf{e}} \newcommand{\JointVelocity}{\dot{q}} \newcommand{\JointVelocityCeiling}{\dot{q}_{\max}} \newcommand{\JointVelocityLimit}{\dot{\mathbf{q}}_{\max}} \newcommand{\JointVelocitySetpoint}{\dot{\mathbf{q}}^*} \newcommand{\JointVelocityTarget}{\dot{q}_{\text{des}}} \newcommand{\JouleanTemperatureRise}{\Delta T} \newcommand{\JunctionAmbientThermalResistance}{R_{\text{th,JA}}} \newcommand{\JunctionCaseThermalResistance}{R_{\text{th,JC}}} \newcommand{\JunctionTemperature}{T_{\text{j}}} \newcommand{\KalmanBucyObserverGain}{\mathbf{L}} \newcommand{\KalmanGain}{\mathbf{G}} \newcommand{\KeepContextPathCost}{C_{\text{keep}}} \newcommand{\KendallMarkovianCode}{M} \newcommand{\KernelActiveTime}{T_{\text{compute}}} \newcommand{\KernelColumnOffset}{n} \newcommand{\KernelExecutionTime}{T_{\text{kernel}}} \newcommand{\KernelHeight}{K_h} \newcommand{\KernelHorizontalLoopOffset}{k_{x}} \newcommand{\KernelRowOffset}{m} \newcommand{\KernelSize}{K} \newcommand{\KernelVerticalLoopOffset}{k_{y}} \newcommand{\KernelWeight}{W} \newcommand{\KernelWidth}{K_w} \newcommand{\KeyAxisLabel}{j} \newcommand{\KeyBufferPosition}{j} \newcommand{\KeyComponent}{k_{jm}} \newcommand{\KeyLeftSingularMatrix}{\mathbf{U}} \newcommand{\KeyLeftSingularVector}{\mathbf{u}} \newcommand{\KeyProjectionMatrix}{\mathbf{W}_{K}} \newcommand{\KeyRightSingularMatrix}{\mathbf{V}} \newcommand{\KeyRightSingularVector}{\mathbf{v}} \newcommand{\KeySingularNumber}{\sigma} \newcommand{\KeySingularSpectrumMatrix}{\mathbf{\Sigma}} \newcommand{\KeySourceMatrix}{\mathbf{X}_{K}} \newcommand{\KeySpectrumLength}{q} \newcommand{\KeyVector}{\mathbf{k}} \newcommand{\KineticEnergy}{E_k} \newcommand{\KineticEnergyCeiling}{E_{\max}} \newcommand{\KineticInsetBarrierFunction}{h_{\text{kinetic}}} \newcommand{\KineticInsetBarrierRate}{\dot{h}_{\text{kinetic}}} \newcommand{\KlDivergence}{\mathcal{D}_{\text{KL}}} \newcommand{\KlPenaltyCoefficient}{\beta_{\text{KL}}} \newcommand{\KlSampleStatistic}{d} \newcommand{\KnownComponentStopDistance}{d_{\text{budget}}} \newcommand{\KolmogorovSmirnovCriticalThreshold}{c_{\text{crit}}} \newcommand{\KolmogorovSmirnovStatistic}{\mathcal{D}_{\text{KS}}} \newcommand{\KroneckerIndicator}{\delta} \newcommand{\KrumClientCount}{n} \newcommand{\KrylovSubspace}{\mathcal{K}} \newcommand{\KsCriticalCoefficient}{c} \newcommand{\KvBlockSize}{S_{\text{blk}}} \newcommand{\KvBlockTailWaste}{\Delta_{\text{tail}}} \newcommand{\KvCacheBytesPerToken}{m_{\text{token}}} \newcommand{\KvCacheHandoffTime}{T_{\text{handoff}}} \newcommand{\KvCacheMemory}{M_{\text{KV}}} \newcommand{\KvElementStorageSize}{s_{\text{elem,KV}}} \newcommand{\KvHeadCount}{H_{\text{KV}}} \newcommand{\KvPoolHeadroomFraction}{f_{\text{head}}} \newcommand{\KvPoolMemory}{M_{\text{pool}}} \newcommand{\KvRecomputeTime}{T_{\text{recompute}}} \newcommand{\KvReloadTime}{T_{\text{reload}}} \newcommand{\KvTileCount}{T_c} \newcommand{\KvTileIndex}{j} \newcommand{\KvTileSize}{B_c} \newcommand{\LaSalleInvariantSet}{\Omega} \newcommand{\LabelCategoryIndex}{i} \newcommand{\LabelVector}{\mathbf{y}} \newcommand{\LabeledRecord}{x} \newcommand{\LabeledSampleCount}{D_{\text{labeled}}} \newcommand{\LabelingRoundIndex}{k} \newcommand{\LaggedModelInput}{x_{t-\Delta}} \newcommand{\LaggedStateDigest}{h_{\text{state},t-k}} \newcommand{\LandmarkDepth}{d} \newcommand{\LanguageInstruction}{c_{\text{instr}}} \newcommand{\LanguageSkillPrior}{p_{\text{LLM}}} \newcommand{\LaplaceLikelihoodScale}{b} \newcommand{\LaplaceNoiseSample}{x} \newcommand{\LaplaceNoiseScale}{b} \newcommand{\LaplaceVariable}{s} \newcommand{\LargestDrivenWheelLoadShare}{\varphi} \newcommand{\LargestEigenvalue}{\lambda_{\max}} \newcommand{\LargestInvariantSet}{\mathcal{M}} \newcommand{\LargestSingularNumber}{\sigma_{\max}} \newcommand{\LarsGlobalLearningRate}{\eta_{\text{global}}} \newcommand{\LastCandidateEmbeddingVector}{\mathbf{x}_N} \newcommand{\LastFunctionInputComponent}{x_N} \newcommand{\LastMeasurementTime}{t_{\text{last}}} \newcommand{\LastRankComputeTime}{T_{\text{rank}_{N-1}}} \newcommand{\LatchApproachSpeed}{v_{\text{latch}}} \newcommand{\LatchClearance}{c} \newcommand{\LatchContactForce}{f} \newcommand{\LatchForceLimit}{F_{\text{lim}}} \newcommand{\LatchPlateStiffness}{k_{\text{latch}}} \newcommand{\LatchStallForce}{F} \newcommand{\LatchStrengthFloor}{F_{\text{floor}}} \newcommand{\LateHandoffProbability}{p} \newcommand{\Latency}{L_{\text{lat}}} \newcommand{\LatencyBandwidthCrossoverSize}{n^*} \newcommand{\LatencyBoundedBatchSize}{B_{\text{SLO}}} \newcommand{\LatencyObjective}{S_{\text{latency}}} \newcommand{\LatencyQuantileFunction}{Q_p} \newcommand{\LatencyRewardExponent}{\beta_{\text{lat}}} \newcommand{\LatencySlo}{L_{\text{lat,SLO}}} \newcommand{\LatentActionComponent}{u} \newcommand{\LatentComponentMean}{\mu_{\phi, j}} \newcommand{\LatentComponentStandardDeviation}{\sigma_{\phi, j}} \newcommand{\LatentDimension}{d_z} \newcommand{\LatentGaussianPolicyDensity}{\mu} \newcommand{\LatentKlWeight}{\beta} \newcommand{\LatentPosteriorDistribution}{q} \newcommand{\LatentPosteriorMean}{\boldsymbol{\mu}_\phi} \newcommand{\LatentPosteriorStandardDeviation}{\boldsymbol{\sigma}_\phi} \newcommand{\LatentStateEncoder}{q_\phi} \newcommand{\LatentStyleVariable}{\mathbf{z}} \newcommand{\LatentVariableSpace}{\mathcal{Z}} \newcommand{\LaterBaseFlangeTransform}{\mathbf{T}_{\text{base}, k+1}^{\text{flange}}} \newcommand{\LaterCameraTargetTransform}{\mathbf{T}_{\text{cam}, k+1}^{\text{target}}} \newcommand{\LaterRolloutTurnIndex}{j} \newcommand{\LaterStepIndex}{j} \newcommand{\LateralClearance}{W_{\text{clear}}} \newcommand{\LatestSequentialObservation}{X_m} \newcommand{\LayerAllReduceTime}{T_{\text{layer comm}}} \newcommand{\LayerBackwardTime}{T_{\text{layer backward}}} \newcommand{\LayerCount}{N_L} \newcommand{\LayerExposedCommunicationTime}{T_{\text{exposed}}} \newcommand{\LayerFunction}{f} \newcommand{\LayerIndex}{\ell} \newcommand{\LayerInputComponent}{x} \newcommand{\LayerInputMatrix}{\mathbf{X}} \newcommand{\LayerInputVector}{\mathbf{x}} \newcommand{\LayerInputWidth}{d_{\text{in}}} \newcommand{\LayerIntermediateStateMemory}{s_{\ell}} \newcommand{\LayerNonlinearity}{\phi} \newcommand{\LayerNormMean}{\mu_{\text{LN}}} \newcommand{\LayerNormStandardDeviation}{\sigma_{\text{LN}}} \newcommand{\LayerOutputMatrix}{\mathbf{Y}} \newcommand{\LayerOutputVector}{\mathbf{y}} \newcommand{\LayerOutputWidth}{d_{\text{out}}} \newcommand{\LayerParameterPayload}{M_{\text{layer}}} \newcommand{\LayerSavedTensorCount}{n_{\text{saved}}} \newcommand{\LayerSelectionIndex}{i} \newcommand{\LayerWeightEntry}{W} \newcommand{\LayerWeights}{\mathbf{w}} \newcommand{\LayerWidth}{n} \newcommand{\LcResonantFrequency}{f_0} \newcommand{\LeaderForwardWave}{\mathbf{u}_m} \newcommand{\LeaderJointPositions}{\mathbf{q}_{\text{leader}}} \newcommand{\LeaderPortEffort}{\mathbf{F}_m} \newcommand{\LeaderPortFlow}{\dot{\mathbf{x}}_m} \newcommand{\LeaderPortPower}{P_m} \newcommand{\LeaderReturnWave}{\mathbf{w}_m} \newcommand{\LeaderWristRollAngle}{\theta_{\text{roll}}} \newcommand{\LeadingSupportDistance}{d_{\text{lead}}} \newcommand{\LeakageCurrent}{I_{\text{leak}}} \newcommand{\LeakagePower}{P_{\text{leakage}}} \newcommand{\LearnedActionProposal}{\hat{\mathbf{a}}_{\text{learned}}} \newcommand{\LearnedNominalTrajectory}{\hat{\mathbf{q}}_{\text{learned}}} \newcommand{\LearnedRemainingReturnEstimate}{\widehat{V}} \newcommand{\LearnedVelocityField}{v_\theta} \newcommand{\LearnerStateDisagreementRate}{\epsilon_\pi} \newcommand{\LearnerStateVisitationDistribution}{p^{\pi}} \newcommand{\LearningCurveSampleCount}{n} \newcommand{\LearningRate}{\eta} \newcommand{\LeaseAdmissionInstant}{t_{\text{adm}}} \newcommand{\LeaseDirtyMemory}{M_{\text{dirty}}} \newcommand{\LeaseExpiryDelaySubtotal}{\tau_{\text{delay,sub}}} \newcommand{\LeaseHoldTime}{T_{\text{hold}}} \newcommand{\LeasePathTravel}{d_{\text{lease}}} \newcommand{\LeaseRefreshInstant}{t_{\text{refresh}}} \newcommand{\LeftEvasionAction}{\mathbf{a}_{\text{left}}} \newcommand{\LeftSingularVectorMatrix}{\mathbf{P}} \newcommand{\LengthPenaltyWeight}{\lambda_{\text{len}}} \newcommand{\LeverArmLength}{r_{\text{arm}}} \newcommand{\LeverArmSweepError}{e_{\text{rot}}} \newcommand{\LewisFormFactor}{Y} \newcommand{\LexicalDocument}{x} \newcommand{\LexicalFrequencySaturation}{k_1} \newcommand{\LexicalLengthNormalization}{b} \newcommand{\LexicalQuery}{Q} \newcommand{\LidarAzimuthAngle}{\theta_{\text{az}}} \newcommand{\LidarBeamDirection}{\mathbf{d}} \newcommand{\LidarElevationAngle}{\phi} \newcommand{\LidarFramePoint}{\mathbf{p}_{\text{lidar}}} \newcommand{\LidarReferenceFrame}{\mathcal{F}_{\text{lidar}}} \newcommand{\LidarScanRate}{f_{\text{scan}}} \newcommand{\LidarSweepPeriod}{T_{\text{sweep}}} \newcommand{\LidarSweepStartTime}{t_{\text{sweep}}} \newcommand{\LieDerivativeAlongControl}{L_{\mathbf{g}} h} \newcommand{\LieDerivativeAlongDrift}{L_{\mathbf{f}} h} \newcommand{\LieDerivativeOrder}{k} \newcommand{\LikelihoodRatioWeight}{w} \newcommand{\LimitMarginFunction}{M} \newcommand{\LinearAcceleration}{\mathbf{a}} \newcommand{\LinearBarrierDecayRate}{\gamma_{\text{cbf}}} \newcommand{\LinearMomentum}{p} \newcommand{\LinearizedVirtualInput}{\mathbf{v}} \newcommand{\LinkAngularAcceleration}{\ddot{\theta}_{\text{link}}} \newcommand{\LinkBandwidth}{\beta} \newcommand{\LinkBitRate}{R_{\text{link}}} \newcommand{\LinkLength}{l} \newcommand{\LinkOutputPosition}{q_{\text{out}}} \newcommand{\LintFalseAcceptFraction}{\phi} \newcommand{\LipschitzConstant}{K} \newcommand{\LiveAutomatonStateSet}{Q_{\text{live}}} \newcommand{\LoadCurrent}{I_{\text{load}}} \newcommand{\LoadInertia}{J_{\text{load}}} \newcommand{\LoadStepCurrentDeficit}{\Delta I_{\text{step}}} \newcommand{\LoadStepDeficitDuration}{\Delta t_{\text{step}}} \newcommand{\LoadedEnforcerExecutionTime}{t_{\text{enf}}} \newcommand{\LoadedJunctionTemperature}{T_{\text{load}}} \newcommand{\LocalBatchSize}{B_{\text{local}}} \newcommand{\LocalEpochCount}{E} \newcommand{\LocalGradient}{\mathbf{g}} \newcommand{\LocalInferenceEnergy}{E_{\text{local}}} \newcommand{\LocalPathTime}{T_{\text{local}}} \newcommand{\LocalRankIndex}{i} \newcommand{\LocalTokenCount}{B_{\text{tok}}} \newcommand{\LocalUpdateCount}{H_{\text{local}}} \newcommand{\LocalityPenaltyFunction}{w} \newcommand{\LocalizationBound}{\delta_{\text{loc}}} \newcommand{\LogFailureRatio}{s_{\text{fail}}} \newcommand{\LogOddsLowerClamp}{L_{\min}} \newcommand{\LogOddsUpperClamp}{L_{\max}} \newcommand{\LogPositionIndex}{j} \newcommand{\LoggedEvent}{e} \newcommand{\LoggedEventPrefix}{\mathbf{e}_{1:j}} \newcommand{\LoggpLongMessageTime}{T_{\text{long}}} \newcommand{\LogisticProbability}{p_{\text{sig}}} \newcommand{\LogitMask}{\mathbf{M}} \newcommand{\LogitMaskEntry}{M} \newcommand{\LogitStorageSize}{s_{\text{logit}}} \newcommand{\LogitVector}{\mathbf{z}} \newcommand{\LogpNetworkLatency}{L_{\text{LogGP}}} \newcommand{\LonePassAdvantage}{\hat{A}_{\text{pass}}} \newcommand{\LongMessageGapPerByte}{G} \newcommand{\LongestInterruptMaskTime}{t_{\text{irq\_disabled,max}}} \newcommand{\LongitudinalFrictionCoefficient}{\mu_x} \newcommand{\LongitudinalSlipRatio}{\lambda} \newcommand{\LongitudinalTractionStiffness}{C_x} \newcommand{\LongitudinalVehicleSpeed}{v_x} \newcommand{\LookaheadStepIndex}{l} \newcommand{\LoopAcceptanceProbability}{p_{\text{loop}}} \newcommand{\LoopGainScalingFactor}{\kappa} \newcommand{\LoopNestDepth}{n_{\text{loops}}} \newcommand{\LoopOrderCount}{N_{\text{order}}} \newcommand{\LoopParallelizationChoiceCount}{\mathcal{P}_{\text{parallel}}} \newcommand{\LoopTurnCost}{C} \newcommand{\Loss}{L} \newcommand{\LossAdjointSeed}{\bar{\mathcal{L}}} \newcommand{\LossFunction}{\mathcal{L}} \newcommand{\LossGradient}{g} \newcommand{\LossGradientVector}{\mathbf{g}} \newcommand{\LossHessian}{\mathbf{H}} \newcommand{\LossLowerBound}{\mathcal{L}_{\inf}} \newcommand{\LossScaleFactor}{s_{\text{loss}}} \newcommand{\LossTimeDerivative}{\dot{\mathcal{L}}} \newcommand{\LostMotionDeflection}{\delta_{\text{lost}}} \newcommand{\LostSuffixTurnCount}{H_{\text{suffix},i}} \newcommand{\LostWorkReplayTime}{T_{\text{replay}}} \newcommand{\LotSamplingProbability}{q} \newcommand{\LowRankLeftFactor}{\mathbf{U}} \newcommand{\LowRankRightFactor}{\mathbf{V}} \newcommand{\LowerPriorityFrames}{lp} \newcommand{\LowerPriorityTasks}{lp} \newcommand{\LowerRatioClippingWidth}{\epsilon_{\text{low}}} \newcommand{\LqrControlWeightMatrix}{\mathbf{R}_u} \newcommand{\LqrCostToGoMatrix}{\mathbf{P}} \newcommand{\LqrFeedbackGain}{\mathbf{K}_{\text{lqr}}} \newcommand{\LqrQuadraticObjective}{J} \newcommand{\LqrStateWeightMatrix}{\mathbf{Q}_x} \newcommand{\LshBandCount}{L} \newcommand{\LshCandidateProbability}{p_{\text{candidate}}} \newcommand{\LshRowsPerBand}{r} \newcommand{\LyapunovAnalysisDomain}{\mathcal{D}} \newcommand{\LyapunovFunction}{V} \newcommand{\LyapunovFunctionDerivative}{\dot{V}} \newcommand{\LyapunovPositivityMargin}{\epsilon_{\text{pos}}} \newcommand{\LyapunovSublevelSet}{\Omega_c} \newcommand{\MacAccumulator}{\text{acc}} \newcommand{\MachineTaxonomyAxis}{\mathsf{Machine}} \newcommand{\MahalanobisDistance}{d_M} \newcommand{\ManifestTrackIndex}{k} \newcommand{\ManipulatorBaseFrame}{\mathcal{F}_{\text{base}}} \newcommand{\ManipulatorJacobian}{\mathbf{J}} \newcommand{\ManualLease}{T_{\text{lease,man}}} \newcommand{\ManualResetTime}{t_{\text{reset,manual}}} \newcommand{\ManualReviewCost}{C_{\text{manual}}} \newcommand{\ManualReviewFraction}{r_{\text{manual}}} \newcommand{\MapCovarianceJacobian}{\mathbf{J}_{\text{map}}} \newcommand{\MapOdometryTransform}{\mathbf{T}_{\text{map}}^{\text{odom}}} \newcommand{\MapParameterEstimate}{\theta_{\text{MAP}}} \newcommand{\MapPoseCovariance}{\boldsymbol{\Sigma}_{\text{map}}} \newcommand{\MapReferenceFrame}{\mathcal{F}_{\text{map}}} \newcommand{\MappedCommandTap}{a_{\text{cmd}}} \newcommand{\MappingSearchSpaceSize}{\mathcal{S}_{\text{mapping}}} \newcommand{\MarginalFalseApprovalProbability}{p} \newcommand{\MarginalRequestServiceTime}{t_{\text{req}}} \newcommand{\MarginalStoppingThreshold}{\epsilon_{\text{stop}}} \newcommand{\MarginalVelocityField}{u} \newcommand{\MarginalizedModelParameters}{\theta'} \newcommand{\MarkovDecisionProcess}{\mathcal{M}} \newcommand{\MaskTokenIndex}{i} \newcommand{\MaskedClientUpdate}{\mathbf{y}} \newcommand{\MaskedFinetuningLoss}{\mathcal{L}_{\text{SFT}}} \newcommand{\MaskedImitationDataset}{\mathcal{D}_{\text{train}}} \newcommand{\MaskedImitationLoss}{\mathcal{L}_{\text{imitation}}} \newcommand{\MaskedLogitVector}{\mathbf{z}'} \newcommand{\MaskedTokenLogit}{z'} \newcommand{\Mass}{m} \newcommand{\MassCenterAcceleration}{\ddot{\mathbf{c}}} \newcommand{\MassCenterHeight}{z_c} \newcommand{\MassCenterPosition}{\mathbf{c}} \newcommand{\MasterProcessingTime}{t_{\text{master}}} \newcommand{\MatchingRowCount}{K} \newcommand{\MatrixColumnIndex}{j} \newcommand{\MatrixEigenvalue}{\lambda} \newcommand{\MatrixMultiplyDestination}{\mathbf{D}} \newcommand{\MatrixRowIndex}{i} \newcommand{\MaxBatchSize}{B_{\text{max}}} \newcommand{\MaxBatchingWindow}{T_{\text{max}}} \newcommand{\MaxReceivedTokenCount}{B_{\text{max}}} \newcommand{\MaxResidentContextCount}{B_{\max}} \newcommand{\MaximumActuatorEffort}{u_{\max}} \newcommand{\MaximumBreakerCooldownInterval}{T_{\text{cool}}^{\max}} \newcommand{\MaximumCompletionOffset}{c_{\max}} \newcommand{\MaximumDepthHypothesis}{d_{\max}} \newcommand{\MaximumEntropyObjective}{J} \newcommand{\MaximumLoadCurrentStep}{\Delta I_{\max}} \newcommand{\MaximumLogit}{z_{\max}} \newcommand{\MaximumObservationAge}{t_{\text{age},\max}} \newcommand{\MaximumPlateIndentation}{x_{\max}} \newcommand{\MaximumRetryBackoffInterval}{b_{\max}} \newcommand{\MaximumTurnOffDelay}{t_{\text{off, max}}} \newcommand{\McnemarTestStatistic}{\chi^2} \newcommand{\McuCaptureTime}{t_{\text{MCU,capture}}} \newcommand{\McuDispatchTime}{t_{\text{MCU,dispatch}}} \newcommand{\MealTokenKeyVector}{\mathbf{k}_{\text{meal}}} \newcommand{\MealTokenQueryVector}{\mathbf{q}_{\text{meal}}} \newcommand{\MeanAcceptedDraftLength}{\bar{m}} \newcommand{\MeanAttemptCost}{c} \newcommand{\MeanClusterSize}{m} \newcommand{\MeanContextLength}{\bar{S}} \newcommand{\MeanDeliveryPayloadLength}{L} \newcommand{\MeanDocumentLength}{\overline{|x|}} \newcommand{\MeanHoldTime}{\bar{T}_{\text{hold}}} \newcommand{\MeanLatchContactForce}{\bar{F}} \newcommand{\MeanMessageQueueDelay}{\bar{T}_q} \newcommand{\MeanNeesStatistic}{\bar{\epsilon}} \newcommand{\MeanQueryDistance}{\mu_D} \newcommand{\MeanRolloutLength}{\bar{N}} \newcommand{\MeanSlotOccupancy}{\bar{N}_{\text{slot}}} \newcommand{\MeanSquaredErrorCloningLoss}{\mathcal{L}_{\text{MSE}}} \newcommand{\MeanStoredTokensPerRecord}{\bar{S}} \newcommand{\MeanTargetTokensPerRecord}{\bar{w}} \newcommand{\MeanTimeBetweenFailures}{\text{MTBF}} \newcommand{\MeanTimeToFailure}{\text{MTTF}} \newcommand{\MeanTimeToRepair}{\text{MTTR}} \newcommand{\MeanVerifierServiceTime}{\bar{T}_{\text{svc}}} \newcommand{\MeasuredAxisPosition}{x_{\text{meas}}} \newcommand{\MeasuredContactForce}{\mathbf{F}_{\text{contact}}} \newcommand{\MeasuredJointVelocities}{\dot{\mathbf{q}}_{\text{meas}}} \newcommand{\MeasuredPixelDepth}{Z_{\text{meas}}} \newcommand{\MeasuredResponseTap}{a_{\text{meas}}} \newcommand{\MeasuredSeamAccelerations}{\ddot{\mathbf{q}}_{\text{meas}}} \newcommand{\MeasuredSeamConfiguration}{\mathbf{q}_{\text{meas}}} \newcommand{\MeasuredSeamVelocities}{\dot{\mathbf{q}}_{\text{meas}}} \newcommand{\MeasuredTrackedPosition}{\mathbf{p}_{\text{meas}}} \newcommand{\MeasurementCovariance}{\boldsymbol{\Sigma}_z} \newcommand{\MeasurementDimension}{m} \newcommand{\MeasurementErrorStandardDeviation}{\sigma} \newcommand{\MeasurementFunction}{h} \newcommand{\MeasurementHistory}{\mathbf{y}_{1:k}} \newcommand{\MeasurementInnovation}{\boldsymbol{\nu}} \newcommand{\MeasurementMatrix}{\mathbf{H}} \newcommand{\MeasurementNoiseCovariance}{\boldsymbol{\Sigma}_{\text{meas}}} \newcommand{\MeasurementNoiseVector}{\mathbf{v}_{\text{meas}}} \newcommand{\MeasurementVector}{\mathbf{y}} \newcommand{\MeasurementVectorDerivative}{\dot{\mathbf{y}}} \newcommand{\MeasurementWindowEnd}{t_{\text{end}}} \newcommand{\MechanicalEnergy}{E} \newcommand{\MechanicalEnergyDerivative}{\dot{E}} \newcommand{\MechanicalImpedanceMap}{Z} \newcommand{\MechanicalPlantState}{\mathbf{x}} \newcommand{\MechanicalWork}{W} \newcommand{\MechanismAcceptanceProbability}{p'_{\text{acc}}} \newcommand{\MechanismAttemptCost}{C'_{\text{attempt}}} \newcommand{\MechanismLogMoment}{\alpha_{\mathcal{M}}} \newcommand{\MechanismOutcome}{o} \newcommand{\MechanismOutputSet}{\mathcal{S}} \newcommand{\MechanismOutputVector}{\mathbf{y}} \newcommand{\MechanismRenyiPrivacyBudget}{\epsilon_{\text{R},i}} \newcommand{\MemoryBusQueueDelay}{t_{\text{queue}}} \newcommand{\MemoryEntryBirthGeneration}{g_{\text{birth}}} \newcommand{\MemoryEntryDeathGeneration}{g_{\text{death}}} \newcommand{\MemoryHierarchyLevelCount}{N_{\text{mem}}} \newcommand{\MemoryHoldDuringWait}{O_{\text{mem}}} \newcommand{\MemoryPlacementCount}{\mathcal{M}_{\text{placement}}} \newcommand{\MemorySubsystemEnergy}{E_{\text{memory}}} \newcommand{\MergedAttentionOutput}{\mathbf{O}^{\text{new}}} \newcommand{\MergedSoftmaxMaximum}{m^{\text{new}}} \newcommand{\MergedSoftmaxNormalizer}{z^{\text{new}}} \newcommand{\MergedWeightMatrix}{\mathbf{W}_{\text{final}}} \newcommand{\MessageInjectionGap}{g} \newcommand{\MessageQueueDelay}{T_q} \newcommand{\MessageStartupLatency}{\alpha} \newcommand{\MessageTimestamp}{t_{\text{msg}}} \newcommand{\MetricDepth}{z_{\text{metric}}} \newcommand{\MicroUnitPrefix}{\text{µ}} \newcommand{\MicrobatchCount}{m} \newcommand{\MicrobatchGradient}{\mathbf{g}} \newcommand{\MicrobatchIndex}{j} \newcommand{\MicrobatchPassTime}{T_{\text{micro},j}} \newcommand{\MicrobatchSize}{B_{\text{micro}}} \newcommand{\MicrocontrollerClockTime}{t_{\text{MCU}}} \newcommand{\MillerCapacitance}{C_{\text{gd}}} \newcommand{\MillerCharge}{Q_{\text{gd}}} \newcommand{\MillerDisplacementCurrent}{I_{\text{miller}}} \newcommand{\MillerPlateauDuration}{t_{\text{plateau}}} \newcommand{\MillerPlateauVoltage}{V_{\text{plateau}}} \newcommand{\MinHashPermutation}{\sigma} \newcommand{\MinHashPermutationCount}{n_{\sigma}} \newcommand{\MinHashSketchSize}{s} \newcommand{\MiniBatchActivation}{a} \newcommand{\MiniBatchSet}{\mathcal{B}} \newcommand{\MinibatchGradient}{\mathbf{g}} \newcommand{\MinimumActuatorEffort}{u_{\min}} \newcommand{\MinimumCellSupportCount}{N_{\min}} \newcommand{\MinimumChunkSetpointCount}{h_{\min}} \newcommand{\MinimumCompletionOffset}{c_{\min}} \newcommand{\MinimumDepthHypothesis}{d_{\min}} \newcommand{\MinimumDetectableEffect}{\delta_{\text{MDE}}} \newcommand{\MinimumPrefetchBufferCount}{Q_{\text{prefetch,min}}} \newcommand{\MinimumRailVoltage}{V_{\text{rail,min}}} \newcommand{\MinimumRoundTripLatency}{L_{\text{lat,min}}} \newcommand{\MinimumStableBatchSize}{B_{\text{min}}} \newcommand{\MinimumTransitTime}{t_{\min}} \newcommand{\MinimumTurnOnDelay}{t_{\text{on, min}}} \newcommand{\MisclassifiedFraction}{r_{\text{error}}} \newcommand{\MisroutedQueryFraction}{m} \newcommand{\MissAcceptanceProbability}{\alpha} \newcommand{\MissPathServiceTime}{T_{\text{cold}}} \newcommand{\MissionDuration}{T_{\text{mission}}} \newcommand{\MissionEnergy}{E_{\text{mission}}} \newcommand{\MissionExceedanceBudget}{\epsilon_{\text{mission}}} \newcommand{\MissionHandoffCount}{K} \newcommand{\MixtureComponentCount}{M} \newcommand{\MixtureComponentCovariance}{\boldsymbol{\Sigma}_m} \newcommand{\MixtureComponentIndex}{m} \newcommand{\MixtureComponentMean}{\boldsymbol{\mu}_m} \newcommand{\MixtureComponentWeight}{w_m} \newcommand{\MixupSample}{\tilde{x}} \newcommand{\MixupWeight}{\lambda_{\text{mix}}} \newcommand{\MlProductivityGoodput}{\text{MPG}} \newcommand{\MlpWeightArithmeticIntensity}{I_{\text{MLP}}} \newcommand{\MobileBaseBarrierFunction}{h_{\text{base}}} \newcommand{\MobilenetWidthMultiplier}{\alpha_{\text{width}}} \newcommand{\ModelBandwidthUtilization}{\text{MBU}} \newcommand{\ModelCallIndex}{i} \newcommand{\ModelCallRequest}{\mathcal{R}} \newcommand{\ModelDownloadEnergy}{E_{\text{download}}} \newcommand{\ModelFlopsUtilization}{\text{MFU}} \newcommand{\ModelGenerationIndex}{n} \newcommand{\ModelInput}{x} \newcommand{\ModelLifetimeCost}{C_{\text{total}}} \newcommand{\ModelParameters}{\theta} \newcommand{\ModelPointAbscissa}{X} \newcommand{\ModelPointHeight}{Z} \newcommand{\ModelPointOrdinate}{Y} \newcommand{\ModelPrediction}{\hat{y}} \newcommand{\ModelPredictor}{f} \newcommand{\ModelScore}{s} \newcommand{\ModelStepOperations}{O_{\text{model}}} \newcommand{\ModelTime}{T_{\text{model}}} \newcommand{\ModelTimeFraction}{f} \newcommand{\ModelWeight}{w} \newcommand{\MomentOrder}{\lambda_{\text{mom}}} \newcommand{\MonitorStartupTime}{T_{\text{vmm}}} \newcommand{\MonitoredFairnessMetricCount}{m} \newcommand{\MonitoredFeatureLevel}{x_{\text{feat}}} \newcommand{\MonitoredGroupCount}{k} \newcommand{\MonitoredMetric}{X} \newcommand{\MonitoredMetricMean}{\mu} \newcommand{\MonitoredMetricStandardDeviation}{\sigma} \newcommand{\MonitoringAlertCost}{C_{\text{alert}}} \newcommand{\MonitoringComputeCost}{C_{\text{compute}}} \newcommand{\MonitoringCostComponent}{C_*} \newcommand{\MonitoringIngestionCost}{C_{\text{ingest}}} \newcommand{\MonitoringStorageCost}{C_{\text{storage}}} \newcommand{\MonotonicClockInstant}{t} \newcommand{\MonthlyOptimizationSavings}{C_{\text{save,monthly}}} \newcommand{\MotionBlurLength}{L} \newcommand{\MotionCyclePeriod}{T_{\text{cycle}}} \newcommand{\MotionModelInput}{\mathbf{u}} \newcommand{\MotorBackEmfConstant}{K_e} \newcommand{\MotorConstant}{K_m} \newcommand{\MotorPhaseRmsCurrent}{I_{\text{phase}}} \newcommand{\MotorRotorAccelerations}{\ddot{\boldsymbol{\theta}}_{\text{motor}}} \newcommand{\MotorRotorCoordinates}{\boldsymbol{\theta}_{\text{motor}}} \newcommand{\MotorRotorVelocities}{\dot{\boldsymbol{\theta}}_{\text{motor}}} \newcommand{\MotorShaftDamping}{D_{\text{motor}}} \newcommand{\MotorShaftPosition}{q_{\text{motor}}} \newcommand{\MotorTorque}{\tau_{\text{motor}}} \newcommand{\MotorTorqueConstant}{K_t} \newcommand{\MotorViscousDamping}{B_{m}} \newcommand{\MotorViscousDampingMatrix}{\mathbf{B}_m} \newcommand{\MpcControlSequence}{\mathbf{u}_{0:N_{\text{mpc}}-1}} \newcommand{\MpcControlSequenceTail}{\mathbf{u}_{1:N_{\text{mpc}}-1}} \newcommand{\MpcHorizonObjective}{J} \newcommand{\MpcPredictionHorizon}{N_{\text{mpc}}} \newcommand{\MpcTerminalCost}{\ell_f} \newcommand{\MpcTerminalCostMatrix}{\mathbf{P}_{N_{\text{mpc}}}} \newcommand{\MultiAgentAcceptanceProbability}{p_{\text{multi}}} \newcommand{\MultiDeviceRunTime}{T_N} \newcommand{\MultimodalFusedTokenStream}{\mathbf{Z}} \newcommand{\MultimodalObservation}{\mathbf{o}} \newcommand{\MutatingToolAction}{a} \newcommand{\MutualInformation}{I} \newcommand{\NaturalLogarithmBase}{e} \newcommand{\NearestCandidateDistance}{D_{\min}} \newcommand{\NeesStatistic}{\epsilon} \newcommand{\NegativeGateSupplyVoltage}{V_{\text{ee}}} \newcommand{\NeighborCount}{k} \newcommand{\NeighborUserIndex}{j} \newcommand{\NeighboringDataset}{X} \newcommand{\NetAngularBrakingDeceleration}{\alpha_{\text{net}}} \newcommand{\NetBrakingDeceleration}{a_{\text{net}}} \newcommand{\NetworkBandwidth}{\text{BW}_{\text{network}}} \newcommand{\NetworkDelayStandardDeviation}{\sigma_d} \newcommand{\NetworkEnergy}{E_{\text{network}}} \newcommand{\NetworkEquipmentPower}{P_{\text{network}}} \newcommand{\NetworkFunction}{f_{\text{net}}} \newcommand{\NetworkLatency}{L_{\text{lat,network}}} \newcommand{\NetworkOutput}{y} \newcommand{\NetworkTrafficVolume}{M} \newcommand{\NeuralLyapunovFactor}{\mathbf{L}_{\phi}} \newcommand{\NeuronActivation}{a} \newcommand{\NeuronBias}{b} \newcommand{\NeuronConnectionWeight}{w_{ij}} \newcommand{\NeuronIndex}{j} \newcommand{\NeuronPreactivation}{z} \newcommand{\NewSoftmaxRunningMaximum}{m_{\text{new}}} \newcommand{\NextDecisionProcessState}{s'} \newcommand{\NextFailureTime}{F} \newcommand{\NextLayerActivationMemory}{M_{\text{activations}}^{(\ell+1)}} \newcommand{\NextProprioceptiveObservation}{\mathbf{o}_{\text{proprio}, t+1}} \newcommand{\NextRobotAction}{\mathbf{a}'} \newcommand{\NextTokenDistribution}{p} \newcommand{\NextTokenEntropy}{\mathcal{H}} \newcommand{\NextTokenLogitFunction}{\mathbf{f}_\theta} \newcommand{\NgramLength}{n} \newcommand{\NicMttf}{\text{MTTF}_{\text{nic}}} \newcommand{\NicsPerNode}{n_{\text{nic}}} \newcommand{\NodeAcceleratorCount}{n_{\text{acc}}} \newcommand{\NodeHbmCapacity}{M_{\text{HBM}}} \newcommand{\NodeMtbf}{\text{MTBF}_{\text{node}}} \newcommand{\NodeStragglerProbability}{p_{\text{straggle}}} \newcommand{\NoisePredictionNetwork}{\boldsymbol{\epsilon}_\theta} \newcommand{\NoisedActionChunk}{\mathbf{A}^k} \newcommand{\NoisyClassProbability}{\tilde{p}} \newcommand{\NoisyClassProbabilityVector}{\tilde{\mathbf{p}}} \newcommand{\NoisyLabelSampleCount}{D_{\text{noisy}}} \newcommand{\NominalBitRate}{R_{\text{nom}}} \newcommand{\NominalBitTime}{T_{\text{bit,nom}}} \newcommand{\NominalBrakingDeceleration}{a_{\text{nominal}}} \newcommand{\NominalClearance}{C_{\text{nominal}}} \newcommand{\NominalClockFrequency}{f_{\text{nom}}} \newcommand{\NominalCommandWindow}{\mathbf{u}_{\text{nom}, t:t+H-1}} \newcommand{\NominalContactForces}{\mathbf{f}_{\text{nom}}} \newcommand{\NominalControlCommand}{\mathbf{u}_{\text{nom}}} \newcommand{\NominalFrameInterval}{T_{\text{nominal}}} \newcommand{\NominalFrictionCoefficient}{\mu_{\text{nom}}} \newcommand{\NominalOscillatorFrequency}{f_{\text{nom}}} \newcommand{\NominalPlanExpiry}{t_{\text{plan\_exp}}} \newcommand{\NominalRatedSpeed}{v_{\text{nominal}}} \newcommand{\NominalReferenceClearance}{c} \newcommand{\NominalSupplyVoltage}{V_{\text{nom}}} \newcommand{\NominalTickPeriod}{T_{\text{period}}} \newcommand{\NominalTrackingTolerance}{\epsilon_{\text{nom}}} \newcommand{\NonconformityScore}{s} \newcommand{\NoninferiorityRatioMargin}{\delta} \newcommand{\NoninferiorityTolerance}{\delta_{\text{tol}}} \newcommand{\NonlinearBiasTorque}{\mathbf{h}} \newcommand{\NonlinearObservationSpace}{\mathbf{O}_{\text{NL}}} \newcommand{\NonlinearOutputFunction}{\mathbf{h}} \newcommand{\NonzeroCount}{n_{\text{nz}}} \newcommand{\NonzeroParameterBudget}{k_{\text{nz}}} \newcommand{\NormWeightMatrix}{\mathbf{W}} \newcommand{\NormalContactForce}{f_{k, \perp}} \newcommand{\NormalContactImpulse}{P_n} \newcommand{\NormalizationScale}{\gamma} \newcommand{\NormalizationScaleVector}{\boldsymbol{\gamma}} \newcommand{\NormalizationShift}{\beta} \newcommand{\NormalizationShiftVector}{\boldsymbol{\beta}} \newcommand{\NormalizedActionCommand}{\tilde{a}} \newcommand{\NormalizedActionResidual}{e} \newcommand{\NormalizedActivation}{\hat{a}} \newcommand{\NormalizedCandidateScore}{c} \newcommand{\NormalizedElapsedTimeRatio}{D} \newcommand{\NormalizedGearRatio}{\tilde{N}} \newcommand{\NormalizedImageAbscissa}{x_n} \newcommand{\NormalizedImageOrdinate}{y_n} \newcommand{\NormalizedMetricBaseline}{v} \newcommand{\NormalizedPredicateMargin}{\bar{f}} \newcommand{\NormalizedRadialDistance}{r} \newcommand{\NormalizedStatusEnvelope}{\mathcal{N}} \newcommand{\NormalizerTokenIndex}{w} \newcommand{\NormalizingClassIndex}{k} \newcommand{\NormalizingKeyIndex}{m} \newcommand{\NormalizingNextState}{\tilde{s}} \newcommand{\NoticeByteAllocation}{M_{\text{notice}}} \newcommand{\NucleusProbabilityMass}{p} \newcommand{\NullSpaceProjector}{\mathbf{N}} \newcommand{\NullSpaceVelocityBias}{\dot{\mathbf{q}}_0} \newcommand{\NumericBitWidth}{b} \newcommand{\NumericalStabilityConstant}{\epsilon} \newcommand{\ObjectHandle}{h} \newcommand{\ObjectWrench}{\mathbf{w}_{\text{obj}}} \newcommand{\ObservabilityMatrix}{\mathbf{O}_{\text{obs}}} \newcommand{\ObservableModelOutput}{O} \newcommand{\ObservationAge}{t_{\text{age}}} \newcommand{\ObservationAgeBudget}{t_{\text{age},\max}} \newcommand{\ObservationAgeDisplacement}{\Delta \mathbf{p}} \newcommand{\ObservationBinding}{\lambda} \newcommand{\ObservationByteBudget}{M_{\text{obs},\max}} \newcommand{\ObservationCount}{N} \newcommand{\ObservationDataset}{\mathcal{D}} \newcommand{\ObservationEncodingTime}{t_{\text{enc}}} \newcommand{\ObservationFunction}{h} \newcommand{\ObservationHistory}{\mathbf{O}} \newcommand{\ObservationHistoryLength}{H_{\text{hist}}} \newcommand{\ObservationHistorySequence}{\mathbf{o}_{0:t}} \newcommand{\ObservationHistoryWindow}{\mathbf{o}_{t-H_{\text{hist}}:t}} \newcommand{\ObservationIntervalEnd}{t_{b}} \newcommand{\ObservationIntervalLength}{T_{\text{obs}}} \newcommand{\ObservationIntervalStart}{t_{a}} \newcommand{\ObservationPairingLag}{\Delta t_{\text{lag}}} \newcommand{\ObservationPayload}{\mathbf{T}_{\text{payload}}} \newcommand{\ObservationResponseLatency}{T_{\text{total}}} \newcommand{\ObservationTimestamp}{t_{\text{obs}}} \newcommand{\ObservationTokenCount}{S_{\text{obs}}} \newcommand{\ObservationTokenSequence}{\mathbf{z}_{\text{token}}} \newcommand{\ObservedAnnotatorAgreement}{p_o} \newcommand{\ObservedCategoryCount}{n_i^{\text{obs}}} \newcommand{\ObservedCycleCount}{N} \newcommand{\ObservedDataPoint}{\mathbf{x}} \newcommand{\ObservedFailureCount}{k} \newcommand{\ObservedFailureFraction}{\hat{p}} \newcommand{\ObservedFreeSpace}{\mathcal{M}_{\text{free}}} \newcommand{\ObservedLabelCount}{n} \newcommand{\ObservedOccupiedSpace}{\mathcal{M}_{\text{occ}}} \newcommand{\ObservedPixelCoordinates}{\tilde{\mathbf{m}}_{\text{observed}}} \newcommand{\ObservedPlantState}{\mathbf{x}_{\text{obs}}} \newcommand{\ObservedPointRange}{r} \newcommand{\ObservedRelativeSpeed}{v_{\text{rel}}} \newcommand{\ObservedSignificanceLevel}{p_{\text{val}}} \newcommand{\ObservedSuccessFraction}{\hat{p}} \newcommand{\ObservedTrialFailureCount}{k} \newcommand{\ObservedViolationFraction}{V} \newcommand{\ObservedVolume}{V_{\text{obs}}} \newcommand{\ObstacleConfigurationSet}{\mathcal{C}_{\text{obs}}} \newcommand{\ObstacleCostWeight}{\lambda_{\text{obs}}} \newcommand{\ObstaclePoint}{\mathbf{o}} \newcommand{\ObstaclePosition}{x_{\text{obstacle}}} \newcommand{\ObstacleProximityCost}{c_{\text{obs}}} \newcommand{\ObstacleRiskRadius}{r_{\text{risk}}} \newcommand{\ObstacleSeparationDistance}{d} \newcommand{\ObstacleStateSet}{\mathcal{X}_{\text{obs}}} \newcommand{\ObstacleSurfaceArea}{A_{\text{surface}}} \newcommand{\OccupancyCoverageMultiplier}{k_\sigma} \newcommand{\OccupancyLogOdds}{L} \newcommand{\OccupancyThreshold}{k} \newcommand{\OccupiedLogOddsIncrement}{L_{\text{occ}}} \newcommand{\OccupiedScenarioCellCount}{N_{\text{supported}}} \newcommand{\OdometryBaseTransform}{\mathbf{T}_{\text{odom}}^{\text{base}}} \newcommand{\OdometryCovarianceJacobian}{\mathbf{J}_{\text{odom}}} \newcommand{\OdometryNoiseStandardDeviation}{\sigma_{w}} \newcommand{\OdometryPoseCovariance}{\boldsymbol{\Sigma}_{\text{odom}}} \newcommand{\OdometryReferenceFrame}{\mathcal{F}_{\text{odom}}} \newcommand{\OfflineTransitionDataset}{\mathcal{D}_{\text{offline}}} \newcommand{\OffloadTailNetworkTime}{t_{\text{net}}^{\text{tail}}} \newcommand{\OffloadTailProcessingTime}{t_{\text{proc}}^{\text{tail}}} \newcommand{\OffloadTransactionWindow}{W} \newcommand{\OhmUnit}{\Omega} \newcommand{\OilBulkModulus}{\beta} \newcommand{\OldSoftmaxRunningMaximum}{m_{\text{old}}} \newcommand{\OnDieDecouplingCapacitance}{C_{\text{die}}} \newcommand{\OnlineSoftmaxKeyTile}{\mathbf{K}_{\text{tile}}} \newcommand{\OnlineSoftmaxQueryBlock}{\mathbf{Q}_{\text{block}}} \newcommand{\OnlineSoftmaxScoreBlock}{\mathbf{A}_{\text{block}}} \newcommand{\OpenLoopTransferFunction}{L} \newcommand{\OpenLoopTransferMatrix}{\mathbf{L}} \newcommand{\OperationChargeBound}{\bar{c}} \newcommand{\OperationDispatchOverhead}{t_{\text{dispatch}}} \newcommand{\OperationRecipient}{r} \newcommand{\OperationReconciliationTime}{T_{\text{rec}}} \newcommand{\OperationalFailureProbability}{p_F} \newcommand{\OperationalOverheadFraction}{f_{\text{overhead}}} \newcommand{\OperationalScenarioDistribution}{p} \newcommand{\OperationalTaxonomyDimension}{C} \newcommand{\OperationalTestDistribution}{\mathcal{D}} \newcommand{\Operations}{O} \newcommand{\OperationsPerSample}{O_{\text{sample}}} \newcommand{\OperatorCognitiveTime}{T_{\text{cognitive}}} \newcommand{\OperatorMotorTime}{T_{\text{motor}}} \newcommand{\OperatorResponseLatency}{t_{\text{hum}}} \newcommand{\OperatorSensoryTime}{T_{\text{sensory}}} \newcommand{\OperatorStabilizationInstant}{t_{\text{stabilize}}} \newcommand{\OperatorWindowTime}{t'} \newcommand{\OperatorWorkspaceMemory}{M_{\text{workspace}}} \newcommand{\OpticalFrequency}{\nu} \newcommand{\OpticalWavelength}{\lambda_{\text{wl}}} \newcommand{\OptimalCheckpointInterval}{T^\ast_{\text{ckpt}}} \newcommand{\OptimalCostToGoDerivative}{\dot{V}} \newcommand{\OptimalCostToGoFunction}{V} \newcommand{\OptimalModelParameters}{\theta^*} \newcommand{\OptimalStateReturn}{V_{\text{RL}}} \newcommand{\OptimizationBreakevenTime}{T_{\text{breakeven}}} \newcommand{\OptimizationImplementationCost}{C_{\text{optimization}}} \newcommand{\OptimizationIterate}{x} \newcommand{\OptimizerStateMemory}{M_{\text{optimizer}}} \newcommand{\OptimizerStepIndex}{t} \newcommand{\OptimizerStepTime}{T_{\text{update}}} \newcommand{\OptimizerUpdateCount}{T} \newcommand{\OptimumMissFactor}{x} \newcommand{\OrderedTestRank}{r} \newcommand{\OrientationTolerance}{\theta_{\text{tol}}} \newcommand{\OrphanSweepInterval}{T} \newcommand{\OscillationPriorStateDigest}{h_{\text{state},t-2}} \newcommand{\OscillatorAcceleration}{\ddot{q}} \newcommand{\OscillatorNaturalFrequency}{\omega} \newcommand{\OscillatorPosition}{q} \newcommand{\OscillatorStepVelocity}{v} \newcommand{\OscillatorVelocity}{\dot{q}} \newcommand{\OutcomeAlphabet}{\mathcal{X}} \newcommand{\OutcomeCheckPassProbability}{p_{\text{out}}} \newcommand{\OutcomeCheckSlotTime}{T_{\text{out}}} \newcommand{\OutcomePairPrivacyLoss}{\mathcal{L}_{\text{priv},(X,X')}^{(o)}} \newcommand{\OutcomeStandardDeviation}{\sigma} \newcommand{\OutgoingChannelCommand}{u_{\text{prior}}} \newcommand{\OutgoingCommandDerivative}{\dot{u}_{\text{prior}}} \newcommand{\OutputBearingDamping}{D_{\text{joint}}} \newcommand{\OutputChannel}{y} \newcommand{\OutputChannelCount}{C_{\text{out}}} \newcommand{\OutputChannelIndex}{k} \newcommand{\OutputComponentFunction}{h} \newcommand{\OutputDimension}{p} \newcommand{\OutputFeatureMapHeight}{H_{\text{out}}} \newcommand{\OutputFeatureMapWidth}{W_{\text{out}}} \newcommand{\OutputIndex}{\ell} \newcommand{\OutputLayerBiasVector}{\mathbf{b}_{\text{out}}} \newcommand{\OutputLayerWeightMatrix}{\mathbf{W}_{\text{out}}} \newcommand{\OutputLength}{K} \newcommand{\OutputLengthStandardDeviation}{\sigma} \newcommand{\OutputLimit}{K_{\max}} \newcommand{\OutputLogit}{z} \newcommand{\OutputNodeAdjoint}{\bar{v}_W} \newcommand{\OutputNodePrimal}{v_W} \newcommand{\OutputProjectionOperations}{O_{\text{out}}} \newcommand{\OutputQuantizationScale}{s_Y} \newcommand{\OutputRelativeDegree}{r} \newcommand{\OutputToken}{y} \newcommand{\OutputTokenPrefix}{y_{<t}} \newcommand{\OutputTokenPrice}{c_{\text{out}}} \newcommand{\OutputTokenSequence}{y_{1:K}} \newcommand{\OutputTorqueCeiling}{\tau_{\text{out,max}}} \newcommand{\OutstandingItemCount}{N_{\text{out}}} \newcommand{\OverheadCameraEmbedding}{\mathbf{e}_{\text{overhead}}} \newcommand{\OverlappedBackwardCommunicationTime}{T_{\text{pipelined}}} \newcommand{\OverlappedTime}{T_{\text{overlap}}} \newcommand{\OverlappingGaussianSet}{\mathcal{N}} \newcommand{\OversubscriptionRatio}{R} \newcommand{\OwnershipAcquisitionTime}{T_{\text{own}}} \newcommand{\PackageDecouplingCapacitance}{C_{\text{pkg}}} \newcommand{\PackageInductance}{L_{\text{pkg}}} \newcommand{\PackageResistance}{R_{\text{pkg}}} \newcommand{\PackageThermalCapacitance}{C_{\text{th}}} \newcommand{\PackageThermalTimeConstant}{\tau_{\text{th}}} \newcommand{\PackedExampleIndex}{k} \newcommand{\PackedExampleLength}{s} \newcommand{\PackedExampleOffset}{b} \newcommand{\PacketBuffer}{b} \newcommand{\PaddingWasteFraction}{W} \newcommand{\PageRankDampingFactor}{d} \newcommand{\PageRankScoreVector}{\mathbf{r}} \newcommand{\PairedAcceptanceDifference}{\Delta} \newcommand{\PairedDifferenceLowerLimit}{L_{\Delta}} \newcommand{\PairedDifferenceUpperLimit}{U_{\Delta}} \newcommand{\PairedOutcomeCellCount}{n} \newcommand{\PairedRandomVariable}{Y} \newcommand{\PairedTaskIndex}{j} \newcommand{\PairedTimeInstant}{s} \newcommand{\PairedVerdictCorrelation}{\hat{\phi}} \newcommand{\PairingLagCeiling}{\Delta t_{\text{lag,max}}} \newcommand{\PairwiseCoordinationCoefficient}{\beta_{\text{pair}}} \newcommand{\PairwiseMaskSecret}{\mathbf{s}} \newcommand{\ParallelEnvironmentCount}{n_{\text{env}}} \newcommand{\ParallelFraction}{f_{\text{parallel}}} \newcommand{\ParallelLoopCount}{k_{\text{parallel}}} \newcommand{\ParallelRigCount}{N_{\text{rig}}} \newcommand{\ParameterPayload}{M_{\text{param}}} \newcommand{\ParameterRandomizationRanges}{\mathcal{P}} \newcommand{\ParameterScaleCoefficient}{A} \newcommand{\ParameterScalingExponent}{\alpha} \newcommand{\ParameterServerCount}{K_{\text{srv}}} \newcommand{\ParameterSpace}{\Theta} \newcommand{\ParameterSpaceDirection}{u} \newcommand{\ParameterStreamingTime}{t_{\text{stream}}} \newcommand{\ParameterVelocity}{\dot{\theta}} \newcommand{\ParameterizedPredictor}{f_{\theta}} \newcommand{\Parameters}{P} \newcommand{\ParametricProposalDistribution}{q_{\boldsymbol{\psi}}} \newcommand{\ParasiticLoopInductance}{L_{\text{parasitic}}} \newcommand{\ParentCapabilityGrant}{\Gamma_{\text{parent}}} \newcommand{\ParentFreeBalance}{F_{P}} \newcommand{\ParentNodeIndex}{k} \newcommand{\ParentReservedFunds}{R_{P}} \newcommand{\ParentSettledCharges}{E_{P}} \newcommand{\ParetoMinimumDemand}{x_{\min}} \newcommand{\ParetoTailExponent}{\alpha_{\text{tail}}} \newcommand{\ParetoTaskDemand}{X} \newcommand{\ParticipatingClientCount}{N_{\text{clients}}} \newcommand{\PartnerBitIndex}{k} \newcommand{\PassAtKEstimate}{\widehat{\operatorname{pass@}k}} \newcommand{\PassedTrialCount}{N_{\text{pass}}} \newcommand{\PassingRunCount}{s} \newcommand{\PassingSampleCount}{c} \newcommand{\PassiveModelPrediction}{\hat{Y}} \newcommand{\PastSynchronizationStepIndex}{j} \newcommand{\PatchColumnIndex}{w} \newcommand{\PatchRowIndex}{h} \newcommand{\PatchTokenCount}{N} \newcommand{\PathAcceleration}{\ddot{s}} \newcommand{\PathAccelerationInput}{u} \newcommand{\PathAccelerationLowerBound}{\ddot{s}_{\min}} \newcommand{\PathAccelerationTorqueCoefficient}{\mathbf{a}_{\tau}} \newcommand{\PathAccelerationUpperBound}{\ddot{s}_{\max}} \newcommand{\PathCoordinate}{s} \newcommand{\PathDelayAsymmetry}{\Delta t_{\text{asym}}} \newcommand{\PathGridPointCount}{N_{\text{grid}}} \newcommand{\PathVelocity}{\dot{s}} \newcommand{\PathVelocityField}{v} \newcommand{\PathVelocitySquaredTorqueCoefficient}{\mathbf{b}_{\tau}} \newcommand{\PayloadGravityTorque}{\tau_{g}} \newcommand{\PayloadLeverArm}{r} \newcommand{\PcieLinkFailureRate}{\lambda_{\text{PCIe}}} \newcommand{\PdnBranchCurrent}{I_{\text{branch}}} \newcommand{\PdnBranchResistance}{R_{\text{PDN}}} \newcommand{\PdnTargetImpedance}{Z_{\text{target}}} \newcommand{\PeakBridgeJerk}{j_{\text{peak}}} \newcommand{\PeakContactForce}{F_{\text{peak}}} \newcommand{\PeakCopperLossPower}{P_{\text{peak}}} \newcommand{\PeakCurrent}{I_{\text{peak}}} \newcommand{\PeakMemoryBandwidth}{\text{BW}_{\text{peak}}} \newcommand{\PeakPenetrationDepth}{\delta_{\max}} \newcommand{\PeakRate}{R_{\text{peak}}} \newcommand{\PeakRegenerativePower}{P_{\text{regen, peak}}} \newcommand{\PeakRotorAngularSpeed}{\omega_{\max}} \newcommand{\PeakSlipRatio}{\lambda_{\text{peak}}} \newcommand{\PeakStopDeceleration}{a_{\text{peak}}} \newcommand{\PeakTorque}{\tau_{\text{peak}}} \newcommand{\PeakTractionCoefficient}{\mu_{\text{peak}}} \newcommand{\PearsonFitStatistic}{\chi^2} \newcommand{\PeerReviewerIndex}{i} \newcommand{\PeerToolCallIndex}{j} \newcommand{\PenaltyContactDamping}{c} \newcommand{\PenaltyContactStiffness}{k_{\text{pen}}} \newcommand{\PenaltyPenetrationDepth}{\delta_{\text{pen}}} \newcommand{\PenaltyRestitutionDuration}{\Delta t_{\text{res}}} \newcommand{\PendulumNaturalFrequency}{\omega_0} \newcommand{\PenetrationDepth}{\delta} \newcommand{\PenetrationRate}{\dot{\delta}} \newcommand{\PenultimateLayerWidth}{n_{N_L-1}} \newcommand{\PerDeviceComputeTime}{T_{\text{compute,local}}} \newcommand{\PerDeviceWeightReadTime}{T_{\text{read}}} \newcommand{\PerExperimentComputeCost}{C_{\text{compute,per-exp}}} \newcommand{\PerExperimentEngineeringCost}{C_{\text{engineer,per-exp}}} \newcommand{\PerFrameDetectionProbability}{p_{\text{frame}}} \newcommand{\PerGpuNetworkFailureRate}{\lambda_{\text{network/GPU}}} \newcommand{\PerGpuPowerFailureRate}{\lambda_{\text{power/GPU}}} \newcommand{\PerGpuTotalFailureRate}{\lambda_{\text{total/GPU}}} \newcommand{\PerStepCostBound}{C_{\max}} \newcommand{\PerStepErrorRate}{\epsilon} \newcommand{\PerStreamTokenRate}{R} \newcommand{\PerTaskRunCount}{R} \newcommand{\PerTestSignificanceLevel}{\alpha_{\text{sig}}'} \newcommand{\PerTokenDecodeTime}{t_{\text{decode}}} \newcommand{\PerTokenKlEstimate}{\hat{\mathcal{D}}} \newcommand{\PerTokenMaskingTime}{t_{\text{mask}}} \newcommand{\PerTokenPrefillTime}{t_{\text{prefill}}} \newcommand{\PerWorkerBatchSize}{B_{\text{per-worker}}} \newcommand{\PerceptionDepthCovariance}{\boldsymbol{\Sigma}_{\text{depth}}} \newcommand{\PerceptionDispatchTime}{t_{\text{IPC}}} \newcommand{\PerceptionErrorScale}{\epsilon_{\text{scale}}} \newcommand{\PeriodicPeakWindingTemperature}{T_{\text{peak}}} \newcommand{\PeriodicTaskCount}{n} \newcommand{\PermanentMagnetFluxLinkage}{\lambda_{\text{pm}}} \newcommand{\PermissionLoopPeriod}{T_{\text{tick}}} \newcommand{\PermissionPathKernel}{G_\kappa} \newcommand{\PermissionPathParameters}{\kappa} \newcommand{\PermissionTickWaitTime}{t_{\text{wait}}} \newcommand{\PermissionTickWcet}{T_{\text{wcet}}} \newcommand{\PermittedActions}{\mathcal{A}_{\text{perm}}} \newcommand{\PermittedUsePassProbability}{p_{\text{use}}} \newcommand{\PersonApproachTravel}{S_h} \newcommand{\PersonPositionUncertainty}{Z_d} \newcommand{\PersonalizationPenaltyWeight}{\lambda_{\text{reg}}} \newcommand{\PersonalizationVector}{\mathbf{p}} \newcommand{\PerturbationNoiseStandardDeviation}{\sigma} \newcommand{\PerturbationNormOrder}{p} \newcommand{\PerturbedPose}{\mathbf{T}'} \newcommand{\PerturbedSignalDimension}{D} \newcommand{\PerturbedSignalVector}{\mathbf{x}} \newcommand{\PfcWatchdogTimeout}{T_{\text{watchdog}}} \newcommand{\PhaseInductance}{L_{\text{phase}}} \newcommand{\PhaseJoulePower}{P_{\text{phase}}} \newcommand{\PhaseMargin}{\Phi_m} \newcommand{\PhaseResistance}{R_{\text{phase}}} \newcommand{\PhotodiodeQuantumEfficiency}{\eta_{\text{QE}}} \newcommand{\PhysicalPlantDynamics}{f_{\text{real}}} \newcommand{\PhysicalRestoreTime}{t_{\text{physical\_restore}}} \newcommand{\PhysicalReturnLevel}{z_{T, \text{real}}} \newcommand{\PhysicalStateTrajectory}{s_{\text{real}}} \newcommand{\PhysicalStlRobustness}{\rho_{\text{real}}} \newcommand{\PhysicalTrajectorySet}{\mathcal{S}_{\text{real}}} \newcommand{\PhysicalWorldState}{s} \newcommand{\PidDerivativeGain}{K_d} \newcommand{\PidIntegralGain}{K_i} \newcommand{\PidProportionalGain}{K_p} \newcommand{\PidProportionalGainMatrix}{\mathbf{K}_p} \newcommand{\PipelineBubbleFraction}{b_{\text{pipe}}} \newcommand{\PipelineBufferMemory}{M_{\text{required}}} \newcommand{\PipelineClockSkew}{t_{\text{skew}}} \newcommand{\PipelineFlushDelay}{t_{\text{hw\_pipe}}} \newcommand{\PipelineIterationTime}{T_{\text{iteration}}} \newcommand{\PipelineParallelDegree}{N_{\text{PP}}} \newcommand{\PipelineTimeSlot}{t} \newcommand{\PipelinedExecutionTime}{T_{\text{pipelined}}} \newcommand{\PistonArea}{A} \newcommand{\PixelColumnCoordinate}{u} \newcommand{\PixelLastEventTime}{t_{\text{last}}} \newcommand{\PixelOpacityContribution}{\alpha'} \newcommand{\PixelRowCoordinate}{v} \newcommand{\PixelRowStandardDeviation}{\sigma_v} \newcommand{\PixelStandardDeviation}{\sigma_u} \newcommand{\PlacementChoiceCount}{n} \newcommand{\PlaintextInput}{m} \newcommand{\PlanAction}{a} \newcommand{\PlanarHomographyMatrix}{\mathbf{H}} \newcommand{\PlanarPositionEmbedding}{\mathbf{E}_{\text{pos}}^{2D}} \newcommand{\PlanarSpecialEuclideanGroup}{SE(2)} \newcommand{\PlanckConstant}{h} \newcommand{\PlanningOperator}{o} \newcommand{\PlanningStageLatency}{T_{\text{plan}}} \newcommand{\PlanningStartInstant}{t_{\text{plan}}} \newcommand{\PlantDynamicsFunction}{\mathbf{f}} \newcommand{\PlantDynamicsParameters}{\theta_{\text{plant}}} \newcommand{\PlantOutcomeFunction}{g} \newcommand{\PlantParameters}{m} \newcommand{\PlantStateAcceleration}{\ddot{\mathbf{x}}} \newcommand{\PlantStateComponentCount}{N_s} \newcommand{\PlantStateDimension}{n} \newcommand{\PlantStateRate}{\dot{\mathbf{x}}} \newcommand{\PlantStateSpace}{\mathcal{X}} \newcommand{\PlantTransitionDensity}{p_m} \newcommand{\PlantTransitionKernel}{\mathcal{T}} \newcommand{\PlatformAnnualOperationsCost}{C_{\text{after}}} \newcommand{\PlatformResourceCapacity}{\text{Cap}} \newcommand{\PlatformResourceIndex}{i} \newcommand{\PlatformTotalCost}{C_{\text{platform}}} \newcommand{\PlatformUtilization}{U_{\text{platform}}} \newcommand{\PointClearanceMargin}{d_{\text{margin}}} \newcommand{\PointToPointMessageSize}{n} \newcommand{\PointToPointTransferTime}{T} \newcommand{\PoisonedModel}{f_{\mathcal{S} \cup \mathcal{S}_{\text{poison}}}} \newcommand{\PoisoningDataset}{\mathcal{S}_{\text{poison}}} \newcommand{\PoisoningTargetDataset}{\mathcal{S}_{\text{test}}} \newcommand{\PoissonSubintervalCount}{n} \newcommand{\Policy}{\pi_\theta} \newcommand{\PolicyAction}{a} \newcommand{\PolicyActionStandardDeviation}{\sigma^{\pi}} \newcommand{\PolicyActionWindow}{\mathbf{A}_{t:t+H-1}} \newcommand{\PolicyCheckpoint}{v} \newcommand{\PolicyEnsembleCovariance}{\boldsymbol{\Sigma}_{\pi}} \newcommand{\PolicyEntropy}{\mathcal{H}} \newcommand{\PolicyGaussianMean}{\boldsymbol{\mu}_{\theta}} \newcommand{\PolicyGaussianMeanComponent}{\mu^{\pi}} \newcommand{\PolicyGaussianStandardDeviation}{\boldsymbol{\sigma}_{\theta}} \newcommand{\PolicyGradientBaseline}{b} \newcommand{\PolicyGradientEstimate}{\widehat{g}} \newcommand{\PolicyHistoryActionReturn}{Q^{\pi}} \newcommand{\PolicyHistoryAdvantage}{A^{\pi}} \newcommand{\PolicyImitationLoss}{\mathcal{L}_{\text{policy}}} \newcommand{\PolicyLipschitzBound}{L_{\text{lip}}} \newcommand{\PolicyObservedState}{s} \newcommand{\PolicyPassRate}{f} \newcommand{\PolicyProbabilityRatio}{\rho} \newcommand{\PolicyRemainingReturn}{V^{\pi}} \newcommand{\PolicyRequestLength}{S_{\pi}} \newcommand{\PolicyStateActionDistribution}{\rho_{\pi_\theta}} \newcommand{\PolicyTrajectoryDistribution}{p_\theta} \newcommand{\PolicyTti}{T_{\text{TTI}}} \newcommand{\PolicyUpdateStepTime}{T_{\text{step}}} \newcommand{\PolyakAveragingCoefficient}{\tau} \newcommand{\PolynomialCoefficientVector}{\mathbf{a}} \newcommand{\PolynomialTrajectoryCoefficient}{a} \newcommand{\PomdpActionSet}{\mathsf{A}} \newcommand{\PomdpObservationFunction}{\mathsf{O}} \newcommand{\PomdpObservationSet}{\Omega} \newcommand{\PomdpRewardFunction}{\mathsf{R}} \newcommand{\PomdpStateSpace}{\mathsf{S}} \newcommand{\PomdpTransitionFunction}{\mathsf{T}} \newcommand{\PoolResidentMemory}{M_{\text{pool}}} \newcommand{\PooledAcceptanceProbability}{\bar{p}} \newcommand{\PooledConversionRate}{\hat{p}} \newcommand{\PooledSampleApprovalRate}{\hat{p}} \newcommand{\PopulationStabilityBinCount}{n_{\text{bins}}} \newcommand{\PopulationStabilitySmoothingConstant}{\epsilon_{\text{smooth}}} \newcommand{\PortCycleNetEnergy}{\Delta E} \newcommand{\PortEffort}{\mathbf{F}} \newcommand{\PortFlow}{\dot{\mathbf{x}}} \newcommand{\PortInput}{\mathbf{u}} \newcommand{\PortOutput}{\mathbf{y}} \newcommand{\PortStoredEnergy}{E} \newcommand{\PortVelocity}{v} \newcommand{\Pose}{\mathbf{T}} \newcommand{\PoseTwistPerturbation}{\boldsymbol{\epsilon}} \newcommand{\PoseTwistPerturbationMatrix}{\hat{\boldsymbol{\epsilon}}} \newcommand{\PositionComponent}{p} \newcommand{\PositionConfidenceEllipsoidRadius}{\chi_{3,0.95}} \newcommand{\PositionErrorBound}{E} \newcommand{\PositionErrorCeiling}{e_{\max}} \newcommand{\PositionErrorCovariance}{\mathbf{P}_{pp}} \newcommand{\PositionErrorEnvelope}{e} \newcommand{\PositionLossMask}{m} \newcommand{\PositionUncertaintyRadius}{r} \newcommand{\PositionalTaskTolerance}{r_{\text{tol}}} \newcommand{\PositiveClassInput}{x_{+}} \newcommand{\PositiveIntegerExponent}{n} \newcommand{\PostContactDrivenStroke}{\Delta x_{\text{driven}}} \newcommand{\PostImpactNormalVelocity}{v_n^+} \newcommand{\PostRevocationDelay}{\tau_{\text{rev}}} \newcommand{\PosteriorCovarianceMatrix}{\boldsymbol{\Sigma}_{\text{post}}} \newcommand{\PosteriorDifferentialEntropy}{h_{\text{post}}} \newcommand{\PostprocessingLatency}{L_{\text{lat,post}}} \newcommand{\PotentialOutcome}{Y^{\text{pot}}} \newcommand{\PowerCriticalQuantile}{z_{\beta}} \newcommand{\PowerLimitBase}{a} \newcommand{\PowerRailInductance}{L_{\text{bus}}} \newcommand{\PowerRailResistance}{R_{\text{bus}}} \newcommand{\PoweredHoldCommand}{\mathbf{u}_{\text{hold}}} \newcommand{\PoweredHoldState}{\mathbf{x}_{\text{hold}}} \newcommand{\PoweredServerCount}{N} \newcommand{\PpoClippedSurrogateObjective}{\mathcal{L}^{\text{CLIP}}} \newcommand{\PqApproximateDistance}{\tilde{d}} \newcommand{\PqCentroidCode}{c^{\text{pq}}} \newcommand{\PqSubspaceIndex}{j} \newcommand{\PqSubvectorCount}{m} \newcommand{\PreForwardEnvironmentState}{\sigma_0} \newcommand{\PreImpactNormalVelocity}{v_n^-} \newcommand{\PreImpactSeparationDistance}{d_{\text{sep}}} \newcommand{\PrePivotCatchRate}{v} \newcommand{\PreTriggerWindowDuration}{T_{\text{pre}}} \newcommand{\PreactivationMatrix}{\mathbf{Z}} \newcommand{\PreactivationVector}{\mathbf{z}} \newcommand{\PrebrakeDelay}{\tau_{\text{delay}}} \newcommand{\PrebrakeDelayCeiling}{\tau_{\text{delay},\max}} \newcommand{\PredecessorGraphVertex}{u} \newcommand{\PredicateLipschitzConstant}{L_{\phi}} \newcommand{\PredicateNormalizationScale}{c} \newcommand{\PredictedActionComponent}{\hat{a}} \newcommand{\PredictedClassProbability}{p} \newcommand{\PredictedConfidence}{\hat{p}} \newcommand{\PredictedDecision}{\hat{Y}} \newcommand{\PredictedEnvironmentLatent}{\hat{\mathbf{z}}} \newcommand{\PredictedErrorCovariance}{\mathbf{P}_{k|k-1}} \newcommand{\PredictedForceReading}{\hat{y}} \newcommand{\PredictedOutput}{\hat{\mathbf{y}}} \newcommand{\PredictedOutputComponent}{\hat{y}} \newcommand{\PredictedPolicyAction}{\hat{\mathbf{a}}} \newcommand{\PredictedProtectedAttribute}{\hat{a}} \newcommand{\PredictedRelativeDepth}{z_{\text{pred}}} \newcommand{\PredictedStateEmbedding}{\mathbf{e}_{\text{state}}} \newcommand{\PredictedStateEstimate}{\hat{\mathbf{x}}_{k|k-1}} \newcommand{\PredictionHeadFunction}{g} \newcommand{\PredictionStepIndex}{i} \newcommand{\PredictiveEntropy}{H_{\text{pred}}} \newcommand{\PreemptionFanoutCount}{k} \newcommand{\PreemptionRate}{\lambda_{\text{preempt}}} \newcommand{\PreemptionTaxTime}{T_{\text{preempt}}} \newcommand{\PreferenceMargin}{z} \newcommand{\PreferencePairDataset}{\mathcal{D}} \newcommand{\PreferenceScale}{\beta} \newcommand{\PreferenceScoredPositionSet}{\mathcal{A}} \newcommand{\PreferredReferenceRelativeScore}{\Delta_w} \newcommand{\PreferredTrajectory}{\tau_w} \newcommand{\PrefetchBufferCount}{N_{\text{prefetch}}} \newcommand{\PrefillAllocatedTokenCount}{C} \newcommand{\PrefillArithmeticIntensity}{I_{\text{prefill}}} \newcommand{\PrefillChunkSize}{C_{\text{chunk}}} \newcommand{\PrefillOperations}{O_{\text{prefill}}} \newcommand{\PrefillRequestIndex}{i} \newcommand{\PrefillTime}{T_{\text{prefill}}} \newcommand{\PrefixHitRate}{\rho_{\text{prefix}}} \newcommand{\PregraspPosition}{\mathbf{p}_{\text{pre}}} \newcommand{\PreprocessingLatency}{L_{\text{lat,pre}}} \newcommand{\PreprocessingServiceTime}{T_{\text{preprocessing}}} \newcommand{\PreprocessingThroughput}{R_{\text{preprocessing}}} \newcommand{\PresaturationTorqueCommand}{\boldsymbol{\tau}_{\text{cmd}}} \newcommand{\PreviousLayerWidth}{n_{\ell-1}} \newcommand{\PreviousPeriodCost}{C_{\text{previous}}} \newcommand{\PreviousRangeObservationHistory}{z_{1:t-1}} \newcommand{\PreviousUpdatedErrorCovariance}{\mathbf{P}_{k-1|k-1}} \newcommand{\PreviousUpdatedStateEstimate}{\hat{\mathbf{x}}_{k-1|k-1}} \newcommand{\PrimitiveOperation}{\phi} \newcommand{\PrincipalPointColumn}{c_x} \newcommand{\PrincipalPointRow}{c_y} \newcommand{\PriorCovarianceMatrix}{\boldsymbol{\Sigma}_{\text{prior}}} \newcommand{\PriorDifferentialEntropy}{h_{\text{prior}}} \newcommand{\PriorStandardDeviation}{\sigma_0} \newcommand{\PriorTurnCount}{j} \newcommand{\PrivacyAdditiveSlack}{\delta} \newcommand{\PrivacyBudget}{\epsilon} \newcommand{\PrivacyLossVariable}{\mathcal{L}_{\text{priv}}} \newcommand{\PrivacyNoiseMultiplier}{\sigma} \newcommand{\PrivatizedQuery}{\tilde{f}} \newcommand{\PrivilegeTrapTime}{T_{\text{trap}}} \newcommand{\PrivilegedSimulatorState}{s_{\text{priv}}} \newcommand{\PrivilegedStateDimension}{d_{\text{priv}}} \newcommand{\PrivilegedStateEncoder}{E} \newcommand{\ProbabilityFunction}{p} \newcommand{\ProbabilitySimplex}{\Delta} \newcommand{\ProbedCellCount}{n_{\text{probe}}} \newcommand{\ProcessConditionCheckTime}{T_{\text{proc}}} \newcommand{\ProcessConditionPassProbability}{p_{\text{proc}}} \newcommand{\ProcessNoiseCovariance}{\mathbf{Q}} \newcommand{\ProcessNoiseIntensity}{\mathbf{Q}} \newcommand{\ProcessNoiseVector}{\mathbf{w}} \newcommand{\ProcessedDataVolume}{D_{\text{vol,processed}}} \newcommand{\ProcessedKeyTileIndex}{t} \newcommand{\ProcessedSampleCount}{N_{\text{samples}}} \newcommand{\ProcessingBufferCount}{N_{\text{processing}}} \newcommand{\ProcessingPrice}{R_{\text{process/GB}}} \newcommand{\ProductFactorIndex}{j} \newcommand{\ProductionExecutionCount}{N_{\text{prod}}} \newcommand{\ProductionModelCount}{N_{\text{models}}} \newcommand{\ProductionOnlyFailureCount}{n_{\text{prod}}} \newcommand{\ProfileAccelerationBound}{a_{\max}} \newcommand{\ProfileJerk}{\dot{a}} \newcommand{\ProgramGoodput}{\eta_{\text{program}}} \newcommand{\ProgramInvariantPredicate}{P} \newcommand{\ProgramState}{s} \newcommand{\ProgramStateSpace}{\Sigma} \newcommand{\ProjectedSeamState}{\hat{\mathbf{x}}_{\text{seam}}} \newcommand{\ProjectedTrajectoryRecord}{R} \newcommand{\ProjectedTurnGradientContribution}{Z} \newcommand{\ProjectionBallRadius}{\epsilon} \newcommand{\ProjectionConstraintSet}{\mathcal{C}} \newcommand{\ProjectiveDistanceSample}{s} \newcommand{\ProjectiveRayScale}{\lambda} \newcommand{\ProjectiveScaleFactor}{s} \newcommand{\PromotedFusionInputRank}{r'} \newcommand{\PromptLength}{S_{\text{prompt}}} \newcommand{\PromptToken}{x} \newcommand{\PromptTokensSent}{S_{\text{sent}}} \newcommand{\PropagatedPositionStandardDeviation}{\sigma_p} \newcommand{\PropensityPriorApprovalShape}{a} \newcommand{\PropensityPriorRejectionShape}{b} \newcommand{\ProportionTestStatistic}{z} \newcommand{\ProportionalGainMatrix}{\mathbf{K}_{p}} \newcommand{\ProportionalPotentialEnergy}{\mathcal{L}_{\text{pos}}} \newcommand{\ProposalDeserializationTime}{t_{\text{deser}}} \newcommand{\ProposalExpiryInstant}{t_{\text{valid}}} \newcommand{\ProposalFirstWaypoint}{\mathbf{a}_0} \newcommand{\ProposalLinkTransportTime}{t_{\text{link}}} \newcommand{\ProposalParameterVector}{\boldsymbol{\psi}} \newcommand{\ProposalPayload}{\mathcal{P}} \newcommand{\ProposedAccess}{r} \newcommand{\ProposedContactForce}{F_{\text{nom}}} \newcommand{\ProposedEndEffectorPoseSequence}{\mathbf{X}_{1:H}} \newcommand{\ProposedGripperCommandSequence}{\mathbf{g}_{1:H}} \newcommand{\ProposedJointPositionSequence}{\mathbf{Q}_{1:H}} \newcommand{\ProposedJointVelocitySequence}{\dot{\mathbf{Q}}_{1:H}} \newcommand{\ProposedOperation}{o} \newcommand{\ProposerConfidenceScore}{\hat{p}} \newcommand{\ProposerEvaluationRate}{f} \newcommand{\ProposerInferenceTime}{t_{\text{infer}}} \newcommand{\ProprioceptiveInputSpace}{\mathcal{X}} \newcommand{\ProprioceptiveInputVector}{\mathbf{x}} \newcommand{\ProprioceptiveTokenEmbeddings}{\mathbf{z}_{\text{proprio}}} \newcommand{\ProtectedAttribute}{a} \newcommand{\ProtectedGroupMembership}{G} \newcommand{\ProtectedTrainingRecord}{R} \newcommand{\ProtectionSwitchResistance}{R_{\text{switch}}} \newcommand{\ProtectiveClearanceMargin}{\delta_{\text{margin}}} \newcommand{\ProtectiveSeparationDistance}{S_p} \newcommand{\ProtectiveSpringStiffness}{k_{\text{spring}}} \newcommand{\ProtectiveSpringTravel}{\delta} \newcommand{\ProxyTrajectoryReward}{\hat{R}} \newcommand{\PrunedWeightMatrix}{\hat{\mathbf{W}}} \newcommand{\PruningMask}{\mathbf{M}} \newcommand{\PruningMaskEntry}{M_{i,j}} \newcommand{\PruningThreshold}{\delta_{\text{prune}}} \newcommand{\PsuMttf}{\text{MTTF}_{\text{psu}}} \newcommand{\PtpExchangeTimestamp}{t} \newcommand{\PtpForwardPathDelay}{T_{\text{prop}, M \to S}} \newcommand{\PtpHardwareTimestamp}{t_{\text{PTP}}} \newcommand{\PtpPropagationDelay}{T_{\text{prop}}} \newcommand{\PtpReversePathDelay}{T_{\text{prop}, S \to M}} \newcommand{\PublicationEpoch}{t_{\text{pub}}} \newcommand{\PufChallenge}{C} \newcommand{\PufResponse}{R} \newcommand{\PufResponseBit}{r} \newcommand{\PulseRoundTripTime}{\Delta t} \newcommand{\PureNoiseActionChunk}{\mathbf{A}^N} \newcommand{\PureTransportDelay}{T_d} \newcommand{\PwmPeriod}{T_{\text{pwm}}} \newcommand{\QuadratureAxisInductance}{L_q} \newcommand{\QuadratureAxisVoltage}{v_q} \newcommand{\QualifiedAdmissionRate}{r} \newcommand{\QualityObjective}{S_{\text{quality}}} \newcommand{\QuantileLevel}{u} \newcommand{\QuantileProbabilityLevel}{q} \newcommand{\QuantileThresholdCandidate}{x} \newcommand{\QuantizationBitWidth}{b} \newcommand{\QuantizationBlockSize}{b_{\text{block}}} \newcommand{\QuantizationScale}{s} \newcommand{\QuantizationStep}{\delta} \newcommand{\QuantizationZeroPoint}{z} \newcommand{\QuantizedGradient}{\mathbf{g}_{\text{int8}}} \newcommand{\QuantizedIntegerCode}{x_q} \newcommand{\QuantizedWeightEntry}{W_{ik}} \newcommand{\QuantizerInput}{x} \newcommand{\QuarterCycleCompressionTime}{t_{\text{peak}}} \newcommand{\QueryAxisLabel}{i} \newcommand{\QueryBlockCount}{T_r} \newcommand{\QueryBlockIndex}{i} \newcommand{\QueryBlockSize}{B_r} \newcommand{\QueryBoundaryCount}{S_{\text{eff}}} \newcommand{\QueryBufferPosition}{i} \newcommand{\QueryComponent}{q_{im}} \newcommand{\QueryPrice}{p_{\text{query}}} \newcommand{\QueryProjectionMatrix}{\mathbf{W}_{Q}} \newcommand{\QuerySensitivity}{\Delta} \newcommand{\QuerySourceMatrix}{\mathbf{X}_{Q}} \newcommand{\QueryVector}{\mathbf{q}} \newcommand{\QueryWord}{q} \newcommand{\QueryWordDocumentFrequency}{n} \newcommand{\QueryWordFrequency}{f} \newcommand{\QueryWorkspaceGeneration}{g_q} \newcommand{\QueueArrivalTime}{t_{\text{arr}, i}} \newcommand{\QueueServerCount}{c} \newcommand{\QueueServiceVariationCoefficient}{c_{s}} \newcommand{\QueueSystemCapacity}{K} \newcommand{\QueueWaitTime}{W_{q}} \newcommand{\QueuedJobCount}{N_{\text{queue}}} \newcommand{\QueuedTransactionBytes}{D_{\text{vol}}} \newcommand{\QueuedTransactionCount}{K} \newcommand{\QueuedTransactionSet}{\mathcal{Q}} \newcommand{\QueueingLatency}{L_{\text{lat,queue}}} \newcommand{\QuiescentJunctionTemperature}{T_{\text{j},\text{target}}} \newcommand{\QuiescentSocPower}{P_{\text{base}}} \newcommand{\QuinticBlendCoefficient}{\mathbf{a}} \newcommand{\QuotaReductionSensitivity}{\gamma_{\text{rate}}} \newcommand{\RadarRangeResolution}{\Delta R} \newcommand{\RadialBasisKernelCoefficient}{\gamma} \newcommand{\RadialDistortionCoefficient}{k} \newcommand{\RadialRange}{R} \newcommand{\RadialRangeStandardDeviation}{\sigma_R} \newcommand{\RadiationWavelength}{\lambda} \newcommand{\RailVoltageTolerance}{\delta_{\text{tol}}} \newcommand{\RandomEnvironmentState}{S} \newcommand{\RandomRetainedElementCount}{K_{\text{rand}}} \newcommand{\RandomSampleCollectionSize}{D_{\text{eval,total}}} \newcommand{\RandomVectorDimension}{d} \newcommand{\RandomizationClusterCount}{K} \newcommand{\RandomizedMechanism}{\mathcal{M}} \newcommand{\RandomizedSmoothingNoise}{\boldsymbol{\delta}} \newcommand{\RangeObservation}{z} \newcommand{\RangeObservationHistory}{z_{1:t}} \newcommand{\RankComponentIndex}{s} \newcommand{\RankConstrainedMatrix}{\mathbf{A}} \newcommand{\RankContribution}{x} \newcommand{\RankCountBinaryExponent}{m} \newcommand{\RankFusionSmoothingConstant}{k_{\text{rrf}}} \newcommand{\RankIndex}{i} \newcommand{\RankReductionResult}{y} \newcommand{\RankingFunction}{V} \newcommand{\RatedActuatorTorque}{\tau_{\text{rated}}} \newcommand{\RatedCurrentEquilibriumTemperature}{T_{\text{eq}}} \newcommand{\RatedFatigueLife}{L_{10}} \newcommand{\RatedJointTorque}{\boldsymbol{\tau}_{\text{rated}}} \newcommand{\RatingCategory}{y} \newcommand{\RatioClippingWidth}{\epsilon_{\text{clip}}} \newcommand{\RationaleTokens}{z} \newcommand{\RawClearanceBarrierFunction}{h_{\text{raw}}} \newcommand{\RawDataUploadEnergy}{E_{\text{raw}}} \newcommand{\RawHardwareFaultRate}{\lambda_{\text{raw}}} \newcommand{\RawPipelineInput}{x} \newcommand{\RawRecordCount}{N} \newcommand{\RawSensoryData}{\mathbf{S}} \newcommand{\RayReturnRange}{r_{\text{hit}}} \newcommand{\RayStepCount}{N_{\text{steps}}} \newcommand{\RayTraversalLength}{d_{\text{ray}}} \newcommand{\RayVoxelRange}{r_{\text{voxel}}} \newcommand{\RayleighDissipationFunction}{\mathcal{D}} \newcommand{\ReachabilityCostate}{\mathbf{p}} \newcommand{\ReachabilityHamiltonian}{\mathcal{H}} \newcommand{\ReachabilityHorizonInstant}{t'} \newcommand{\ReachabilityLevelFunction}{V} \newcommand{\ReachabilityTerminalTime}{T} \newcommand{\ReachableArtifactNode}{u} \newcommand{\ReachableDistance}{d_{\text{reach}}} \newcommand{\ReachableWorkspace}{\mathcal{W}} \newcommand{\ReadEndSequenceCount}{c_{\text{end}}} \newcommand{\ReadStartSequenceCount}{c_{\text{start}}} \newcommand{\ReadTimeCeiling}{R} \newcommand{\RealDataset}{\mathcal{S}_{\text{real}}} \newcommand{\RealTimeTaskIndex}{i} \newcommand{\RealityGapVector}{\boldsymbol{\Delta}_{\text{sim2real}}} \newcommand{\RealizedActuatorEffort}{u_{\text{act}}} \newcommand{\RealizedArrivalCount}{n} \newcommand{\RealizedDamageOutcome}{y} \newcommand{\RealizedDampingPower}{P_d} \newcommand{\RealizedDeviceComputeRate}{R} \newcommand{\RealizedFalseAlarmProbability}{\alpha_{*}} \newcommand{\RealizedMissedDegradationProbability}{\beta_{*}} \newcommand{\RealizedServiceTime}{s} \newcommand{\ReceiptSampleIndex}{t_{\text{recv}}} \newcommand{\ReceiveBandwidth}{\text{BW}_{\text{rx}}} \newcommand{\ReceiverOverhead}{o_{\text{recv}}} \newcommand{\ReceiverTimingJitter}{\sigma_{\Delta t}} \newcommand{\RecentUsageShare}{F_{\text{actual}}} \newcommand{\RecommenderItemCount}{N_{\text{items}}} \newcommand{\RecommenderUserCount}{N_{\text{users}}} \newcommand{\ReconcilableToolInterface}{\mathbb{T}_{a}} \newcommand{\ReconstructedGradient}{\hat{\mathbf{g}}} \newcommand{\ReconstructedWeight}{\hat{w}} \newcommand{\RecordAdequacyPassProbability}{p_{\text{record}}} \newcommand{\RecordSizeCeiling}{s_{\max}} \newcommand{\RecordedAuthorityState}{S_{\text{auth}}} \newcommand{\RecoveryCompletionInstant}{t_{\text{rec}}} \newcommand{\RecoveryPoseTolerance}{\epsilon_{\text{sync}}} \newcommand{\RecoveryTargetLogPosition}{j_{\text{target}}} \newcommand{\RecoveryWarmupTime}{T_{\text{warmup}}} \newcommand{\RecurrentHiddenBias}{\mathbf{b}_{\text{h}}} \newcommand{\RecurrentHiddenState}{\mathbf{h}} \newcommand{\RecurrentInputWeights}{\mathbf{W}_{\text{hx}}} \newcommand{\RecurrentOutputWeights}{\mathbf{W}_{\text{yh}}} \newcommand{\RecurrentStateWeights}{\mathbf{W}_{\text{hh}}} \newcommand{\ReduceScatterCompletionTime}{T_{\text{reducescatter}}} \newcommand{\ReducedBoundaryConditionVector}{\mathbf{b}_{\text{red}}} \newcommand{\ReducedImpactMass}{m_{\text{red}}} \newcommand{\ReducibleLoss}{\hat{\mathcal{L}}} \newcommand{\ReductionInputCount}{n} \newcommand{\RedundantComponentCount}{N_{\text{red}}} \newcommand{\RedundantReplicaCount}{k} \newcommand{\RedundantServiceAvailability}{A_{\text{system}}} \newcommand{\ReferenceActionDisadvantage}{A_t^{\pi^*}} \newcommand{\ReferenceAssessedFailure}{F} \newcommand{\ReferenceBinIndex}{b} \newcommand{\ReferenceBinProportion}{E} \newcommand{\ReferenceCostToGo}{Q_t^{\pi^*}} \newcommand{\ReferenceDisagreementProbability}{\mathcal{L}} \newcommand{\ReferenceDistribution}{p} \newcommand{\ReferenceJointAccelerations}{\ddot{\mathbf{q}}^{\text{ref}}} \newcommand{\ReferenceJointPosition}{q_{\text{reference}}} \newcommand{\ReferenceJointPositions}{\mathbf{q}^{\text{ref}}} \newcommand{\ReferenceJointVelocities}{\dot{\mathbf{q}}^{\text{ref}}} \newcommand{\ReferenceLogProbabilitySum}{\Delta_{\text{ref}}} \newcommand{\ReferenceMixingProbability}{\lambda} \newcommand{\ReferenceNextTokenDistribution}{q} \newcommand{\ReferencePosition}{\mathbf{r}} \newcommand{\ReferenceProbabilityRatio}{z} \newcommand{\ReferenceRelativeScore}{\Delta_\theta} \newcommand{\ReferenceRequestLength}{S_{\text{ref}}} \newcommand{\ReferenceSampleEmpiricalCdf}{F} \newcommand{\ReferenceStateDisagreementRate}{\epsilon_E} \newcommand{\ReferenceStateDistribution}{d_{\pi^*}} \newcommand{\ReferenceStepDisagreementRate}{\epsilon} \newcommand{\ReferenceWindingResistance}{R_0} \newcommand{\ReflectedContactForce}{F_{\text{contact}}} \newcommand{\ReflectedRotorInertia}{J_{\text{ref}}} \newcommand{\ReflectedRotorInertiaMatrix}{\mathbf{J}_m} \newcommand{\ReflectedTransmissionInputInertia}{J_{\text{ref,in}}} \newcommand{\ReflectionAngle}{\theta_{\text{refl}}} \newcommand{\ReflexCollisionBudget}{T_{\text{reflex\_budget}}} \newcommand{\RegeneratedBrakingEnergy}{E_{\text{regen}}} \newcommand{\RegenerativeBrakingTorque}{\tau_{\text{brake}}} \newcommand{\RegenerativeRecoveryEfficiency}{\eta_{\text{regen}}} \newcommand{\RegisterSetupTime}{t_{\text{setup}}} \newcommand{\RegisteredDescriptorCount}{n_{\text{reg}}} \newcommand{\RegularizedEulerIntegral}{I} \newcommand{\RejectionDecodeStep}{t_{\text{cut}}} \newcommand{\RelationalSelection}{\sigma} \newcommand{\RelativeContrastTolerance}{\epsilon_{\text{contrast}}} \newcommand{\RelativeDeviationBound}{\delta} \newcommand{\RelativeImprovementFraction}{\delta} \newcommand{\RelativeStandardError}{r} \newcommand{\RelevantRecordSet}{\mathcal{D}^*} \newcommand{\ReliabilityTargetIndex}{i} \newcommand{\ReliableDetectionFrameCount}{N_{\text{frames}}} \newcommand{\RemainingCallCount}{N_{\text{rem}}} \newcommand{\RemainingDistanceEstimate}{\hat{s}} \newcommand{\RemainingExecutionLease}{T_{\text{lease,rem}}} \newcommand{\RemainingHarmDistance}{d_{\text{rem}}} \newcommand{\RemainingIntentTime}{T_{\text{rem}}} \newcommand{\RemainingReturn}{R_{\geq k}} \newcommand{\RemainingUprightDistance}{s} \newcommand{\RemoteHardwareEfficiency}{\eta_{\text{hw,remote}}} \newcommand{\RemotePathTime}{T_{\text{remote}}} \newcommand{\RemotePeakRate}{R_{\text{peak,remote}}} \newcommand{\RenderedPixelColor}{C} \newcommand{\RenewalJitterAllowance}{T_{\text{jitter}}} \newcommand{\RenyiDivergence}{\mathcal{D}_{\alpha_{\text{R}}}} \newcommand{\RenyiOrder}{\alpha_{\text{R}}} \newcommand{\RenyiPrivacyBudget}{\epsilon_{\text{R}}} \newcommand{\RepairAttemptCost}{C_{\text{repair}}} \newcommand{\RepairCap}{K_{\text{repair}}} \newcommand{\RepairCapabilityGrant}{\Gamma_{\text{repair}}} \newcommand{\RepairFirstCost}{C_{\text{repair\ first}}} \newcommand{\RepairPatchArtifact}{P} \newcommand{\RepairSuccessProbability}{p} \newcommand{\RepairTurnLatency}{T_{\text{repair}}} \newcommand{\ReparameterizationNoise}{\boldsymbol{\epsilon}} \newcommand{\RepeatedRunCount}{k} \newcommand{\RepeatedRunMean}{\mu_{\text{run}}} \newcommand{\RepeatedRunStandardDeviation}{\sigma_{\text{run}}} \newcommand{\ReplacementLatency}{L} \newcommand{\ReplacementTimingReserve}{T_{\text{reserve}}} \newcommand{\ReplanRequestOffset}{T_{\text{request}}} \newcommand{\ReplayBuffer}{\mathcal{M}} \newcommand{\ReplayBufferTransitionCount}{n_{\text{replay}}} \newcommand{\ReplayedErrorCovariance}{\mathbf{P}_{t_{\text{recv}}}} \newcommand{\ReplayedStateEstimate}{\hat{\mathbf{x}}_{t_{\text{recv}}}} \newcommand{\ReplicaAvailability}{A_{\text{single}}} \newcommand{\ReplicaColdStartTime}{T_{\text{cold-start}}} \newcommand{\ReplicaCount}{R} \newcommand{\ReplicaModelLoadTime}{T_{\text{load}}} \newcommand{\ReplicaProvisioningTime}{T_{\text{provision}}} \newcommand{\ReplicaWarmupTime}{T_{\text{warmup}}} \newcommand{\ReplyLossProbability}{q_{\text{rep}}} \newcommand{\RepositoryEdgeSourceIndex}{i} \newcommand{\RepositoryEdgeTargetIndex}{j} \newcommand{\RepositoryEdgeWeight}{A} \newcommand{\RepositoryEdgeWeightMatrix}{\mathbf{A}} \newcommand{\RepositoryFileCount}{n} \newcommand{\RepositoryGraphEdgeSet}{E} \newcommand{\RepositoryGraphVertexSet}{V} \newcommand{\RepositoryTransitionMatrix}{\mathbf{P}_{\text{graph}}} \newcommand{\ReprojectionResidual}{\epsilon_{\text{reproj}}} \newcommand{\RepublicationIndex}{k} \newcommand{\RepublicationPeriod}{T_{\text{rep}}} \newcommand{\RequantizationScale}{s_{\text{eff}}} \newcommand{\RequestCompressionRatio}{\gamma_{\text{req}}} \newcommand{\RequestConcurrency}{Q_{\text{req}}} \newcommand{\RequestLossProbability}{q_{\text{req}}} \newcommand{\RequestOutputLength}{S} \newcommand{\RequestPromptTokens}{\mathbf{x}} \newcommand{\RequestQueueTime}{T_{\text{queue}}} \newcommand{\RequestResidenceTime}{W} \newcommand{\RequestResponseTime}{t} \newcommand{\RequestSeenBatchSize}{B_{\text{req}}} \newcommand{\RequestServiceTime}{T_{\text{svc}}} \newcommand{\RequestTimeInSystem}{T_{\text{lat}}} \newcommand{\RequestedActionTap}{a_{\text{req}}} \newcommand{\RequiredClearance}{C_{\text{safe}}} \newcommand{\RequiredComponentCount}{N} \newcommand{\RequiredDetectionRange}{d_{\text{detect}}} \newcommand{\RequiredInputBandwidth}{\text{BW}_{\text{required}}} \newcommand{\RequiredMemoryBandwidth}{\text{BW}_{\text{req}}} \newcommand{\RequiredPremiseClaim}{P} \newcommand{\RequiredPremiseConfidence}{p} \newcommand{\RequiredPremiseCount}{n} \newcommand{\RequiredResultCount}{k} \newcommand{\RequiredScenarioCellCount}{N_{\text{req}}} \newcommand{\RequiredScenarioSet}{\mathcal{S}_{\text{req}}} \newcommand{\RequiredServiceRate}{\mu_{\text{required}}} \newcommand{\RequiredTaskPairCount}{N'} \newcommand{\RequiredUsersPerVariant}{n} \newcommand{\ResampledReplacementToken}{T_4'} \newcommand{\ReservedDeviceMemory}{M_{\text{reserve}}} \newcommand{\ResetCalibrationTime}{t_{\text{calibration}}} \newcommand{\ResetDuration}{t_{\text{rst}}} \newcommand{\ResetLatency}{T_{\text{reset}}} \newcommand{\ResidentStopDistance}{d_{\text{suffix}}} \newcommand{\ResidentWeightMemory}{M_{\text{weights,resident}}} \newcommand{\ResidualAdapterFunction}{A} \newcommand{\ResidualBlockOutput}{\mathbf{y}} \newcommand{\ResidualCorrectionCeiling}{\Delta_{\max}} \newcommand{\ResidualDynamicsPerturbation}{\Delta \mathbf{f}} \newcommand{\ResidualFrequencyError}{\Delta f_{\text{res}}} \newcommand{\ResidualFunction}{\mathcal{F}} \newcommand{\ResidualGate}{g} \newcommand{\ResidualPolicyTorque}{\boldsymbol{\tau}_{\text{res},\theta}} \newcommand{\ResidualSamplingDistribution}{p_{\text{res}}} \newcommand{\ResizedWorkerCount}{N_{\text{new}}} \newcommand{\ResolutionScalingRatio}{\gamma} \newcommand{\ResourceChangeRate}{r_{\text{chg}}} \newcommand{\ResourceCostBudget}{C_{\text{max}}} \newcommand{\ResourceTypeIndex}{r} \newcommand{\ResourceUtilization}{U} \newcommand{\ResponseActionTokens}{a} \newcommand{\ResponseMetadata}{\mathbf{m}} \newcommand{\ResponsePayload}{\mathbf{y}} \newcommand{\ResponseReward}{r} \newcommand{\ResponseThreshold}{\tau} \newcommand{\ResponseTimeDistributionFunction}{F} \newcommand{\ResponseTimeIterationIndex}{\ell} \newcommand{\ResponseTimeStandardDeviation}{\sigma_t} \newcommand{\RestConfiguration}{\mathbf{q}_{\text{rest}}} \newcommand{\RestitutionCoefficient}{e} \newcommand{\RestoreWorkerCount}{w} \newcommand{\RestrictedAccelerationBound}{a_{\text{restricted}}} \newcommand{\RestrictedSpeedBound}{v_{\text{restricted}}} \newcommand{\ResultActionTime}{T_{\text{action}}} \newcommand{\ResumeTime}{T_{\text{resume}}} \newcommand{\RetainedDigestCount}{m} \newcommand{\RetainedGradientElementCount}{K_{\text{top}}} \newcommand{\RetainedProductiveTime}{T_{\text{productive}}} \newcommand{\RetainedSpectralEnergyFraction}{\eta_r} \newcommand{\RetainingCallCount}{H_{\text{rem}}} \newcommand{\RetiringChunkJointVelocity}{\dot{q}_A} \newcommand{\RetiringChunkReferenceState}{\mathbf{x}_A} \newcommand{\RetrainingComputeCost}{C_{\text{compute}}} \newcommand{\RetrainingDeploymentCost}{C_{\text{deployment}}} \newcommand{\RetrainingInterval}{T} \newcommand{\RetrainingRiskCost}{C_{\text{risk}}} \newcommand{\RetrainingRunCost}{C} \newcommand{\RetrainingValidationCost}{C_{\text{validation}}} \newcommand{\RetrievalCollectionSize}{N} \newcommand{\RetrievalCutoffCount}{k} \newcommand{\RetrievalMethodIndex}{i} \newcommand{\RetrievedRecordSet}{\mathcal{R}} \newcommand{\RetryAttemptIndex}{j} \newcommand{\RetryBackoffInterval}{b} \newcommand{\RetryJitterDelay}{d} \newcommand{\ReturnLevel}{z} \newcommand{\ReturnPeriodTrialCount}{T} \newcommand{\ReturnStepOffset}{k} \newcommand{\ReturnedClassLabel}{c} \newcommand{\ReusedPrefixLength}{S_{\text{match}}} \newcommand{\ReverseModeWorkConstant}{C} \newcommand{\ReverseTransitionCovariance}{\boldsymbol{\Sigma}} \newcommand{\ReverseTransitionMean}{\boldsymbol{\mu}_\theta} \newcommand{\RevertFidelity}{\rho_{\text{revert}}} \newcommand{\ReviewerFalseApprovalIndicator}{X} \newcommand{\ReviewerIndex}{j} \newcommand{\RevisionPassProbability}{p_{\text{rev}}} \newcommand{\Reward}{r} \newcommand{\RewardFunction}{r} \newcommand{\RewardModel}{r} \newcommand{\RightEvasionAction}{\mathbf{a}_{\text{right}}} \newcommand{\RightSingularVectorMatrix}{\mathbf{Q}} \newcommand{\RigidGangJob}{J} \newcommand{\RigidImpactInstant}{t_{\text{impact}}} \newcommand{\RigidTransformTranslation}{\mathbf{t}} \newcommand{\RingAllReduceBandwidthTime}{T_{\text{bandwidth}}} \newcommand{\RingAllReduceCompletionTime}{T_{\text{ring}}} \newcommand{\RingAllReduceStartupTime}{T_{\text{latency}}} \newcommand{\RingBufferHorizon}{T_{\text{buffer}}} \newcommand{\RingBufferSlotCount}{N_{\text{buffer}}} \newcommand{\RingStepIndex}{s} \newcommand{\RingTreeCrossoverPayload}{M_{\text{crossover}}} \newcommand{\RmsMotorTorque}{\tau_{\text{rms}}} \newcommand{\RmspropSquaredGradientAverage}{s} \newcommand{\RobotAction}{\mathbf{a}} \newcommand{\RobotApproachSpeed}{v_r} \newcommand{\RobotApproachVelocity}{v_{\text{robot}}} \newcommand{\RobotObservation}{\mathbf{o}} \newcommand{\RobotPosition}{x_{\text{robot}}} \newcommand{\RobotPositionUncertainty}{Z_r} \newcommand{\RobotReactionTime}{T_r} \newcommand{\RobotReactionTravel}{S_r} \newcommand{\RobotStoppingTravel}{S_s} \newcommand{\RobotStructuralStiffness}{k_{\text{robot}}} \newcommand{\RobotTransitVolume}{\mathcal{T}_{\text{robot}}} \newcommand{\RollingShutterDistortion}{\Delta \mathbf{x}} \newcommand{\RollingShutterFrameSkew}{\Delta t_{\text{skew}}} \newcommand{\RollingShutterRowReadout}{t_{\text{row}}} \newcommand{\RolloutAction}{a} \newcommand{\RolloutActionSequence}{\mathbf{a}_{0:T}} \newcommand{\RolloutAdmissionAge}{\Delta T_{\text{rollout}}} \newcommand{\RolloutAssessmentTime}{T_{v}} \newcommand{\RolloutDuration}{T_{\text{rollout}}} \newcommand{\RolloutEnvironmentState}{s} \newcommand{\RolloutHorizon}{T} \newcommand{\RolloutLoss}{\mathcal{L}} \newcommand{\RolloutPolicyParameters}{\theta_{\text{old}}} \newcommand{\RolloutPolicyTokenCount}{N} \newcommand{\RolloutStateSequence}{s_{0:T}} \newcommand{\RolloutStepCount}{N} \newcommand{\RolloutStepIndex}{k} \newcommand{\RolloutSurrogateObjective}{\mathcal{L}} \newcommand{\RolloutTurnIndex}{k} \newcommand{\RooflineRidgePoint}{I_{\text{ridge}}} \newcommand{\RotaryRotationMatrix}{\mathbf{R}} \newcommand{\RotatedActivationMatrix}{\mathbf{X}'} \newcommand{\RotatedWeightMatrix}{\mathbf{W}'} \newcommand{\RotatingBodyAngularSpeed}{\omega} \newcommand{\RotatingBodyInertia}{J} \newcommand{\RotationOriginAcceleration}{\mathbf{a}_O} \newcommand{\RotationOriginVelocity}{\mathbf{v}_O} \newcommand{\RotationalKineticEnergy}{E_{k,\text{rot}}} \newcommand{\RotationalSpringStiffness}{K} \newcommand{\RotorAngularSpeed}{\omega_m} \newcommand{\RotorInertia}{J_{\text{rotor}}} \newcommand{\RotorPolePairCount}{N_{\text{poles}}} \newcommand{\RoundCommunicationVolume}{M_r} \newcommand{\RoundDownloadVolume}{M_{\text{download},r}} \newcommand{\RoundDuration}{t_r} \newcommand{\RoundEmittedTokenCount}{N_{\text{emit}}} \newcommand{\RoundProtocolVolume}{M_{\text{protocol},r}} \newcommand{\RoundRetryVolume}{M_{\text{retry},r}} \newcommand{\RoundSampleCount}{n_{\text{round}}} \newcommand{\RoundUploadVolume}{M_{\text{upload},r}} \newcommand{\RoundedClassProbability}{p^{\text{rnd}}} \newcommand{\RoundingDecimalCount}{d_{\text{dec}}} \newcommand{\RoutedExpertCount}{k_{\text{experts}}} \newcommand{\RouterGateProbability}{p_{\text{gate}}} \newcommand{\RowActivationDelay}{t_{\text{RCD}}} \newcommand{\RowActiveTime}{t_{\text{RAS}}} \newcommand{\RowAttitudeIncrement}{\Delta \boldsymbol{\theta}_{\text{att}}} \newcommand{\RowConflictCount}{N_{\text{conflict}}} \newcommand{\RowCycleTime}{t_{\text{RC}}} \newcommand{\RowExposureStartTime}{t_{\text{scan}}} \newcommand{\RowModeComponentVector}{\mathbf{a}_s} \newcommand{\RowModeFactorMatrix}{\mathbf{A}} \newcommand{\RowModeFactorSlice}{\mathbf{a}} \newcommand{\RowParallelOutputMatrix}{\mathbf{Z}} \newcommand{\RowParallelWeightMatrix}{\mathbf{B}} \newcommand{\RowPrechargeTime}{t_{\text{RP}}} \newcommand{\RunIndexSubset}{J} \newcommand{\RuntimeGoodput}{\eta_{\text{runtime}}} \newcommand{\RuntimeReserveMemory}{M_{\text{runtime}}} \newcommand{\SCurveAccelerationPhaseTime}{T_{\text{acc}}} \newcommand{\SafeApproachSpeedEnvelope}{v_{\text{safe}}} \newcommand{\SafeControlSet}{\mathcal{U}_{\text{safe}}} \newcommand{\SafeOverrideCommand}{\mathbf{u}_{\text{safe}}} \newcommand{\SafeSeparationDistance}{d_{\text{safe}}} \newcommand{\SafeSetProjection}{\mathcal{P}_{\mathcal{C}}} \newcommand{\SafeStateConstraintSet}{\mathcal{X}_{\text{safe}}} \newcommand{\SafeStateSet}{\mathcal{X}_{\text{safe}}} \newcommand{\SafeWorldState}{s_A} \newcommand{\SafeguardSeparationDistance}{S} \newcommand{\SafeguardStoppingTime}{T} \newcommand{\SafetyBoundaryManifold}{\partial \mathcal{C}} \newcommand{\SagaCompensatingStep}{C} \newcommand{\SagaFailedForwardStep}{F_k^{\text{fail}}} \newcommand{\SagaForwardStep}{F} \newcommand{\SagaStepIndex}{k} \newcommand{\SampleAcquisitionPrice}{c_{\text{sample}}} \newcommand{\SampleGradientStandardDeviation}{\sigma} \newcommand{\SampleLabelingPrice}{c_{\text{label}}} \newcommand{\SampleStatistic}{\widehat{\theta}} \newcommand{\SampleStorageSize}{s_{\text{sample}}} \newcommand{\SampledPolicyToken}{w} \newcommand{\SampledSimulationParameterVector}{\tilde{\boldsymbol{\xi}}} \newcommand{\SampledUnit}{y} \newcommand{\SampledUnitCount}{m} \newcommand{\SamplingParameters}{\mathbf{\Theta}_{\text{sample}}} \newcommand{\SamplingPeriod}{T_s} \newcommand{\SamplingRate}{f_s} \newcommand{\SamplingTemperature}{\tau_{\text{temp}}} \newcommand{\SandboxColdBootTime}{T_{\text{cold}}} \newcommand{\SaturatedJointTorque}{\boldsymbol{\tau}_{\text{act}}} \newcommand{\SavedEngineeringTime}{T_{\text{saved}}} \newcommand{\ScalarFieldSize}{k} \newcommand{\ScalarGraphFunction}{f} \newcommand{\ScalarKalmanGain}{g} \newcommand{\ScalarTrackingError}{e} \newcommand{\ScalarTrackingErrorAcceleration}{\ddot{e}} \newcommand{\ScalarTrackingErrorRate}{\dot{e}} \newcommand{\ScaleCoefficient}{A_{\mathcal{L}}} \newcommand{\ScaledBatchSize}{B_{\text{new}}} \newcommand{\ScaledJointStiffnessMatrix}{\tilde{\mathbf{K}}} \newcommand{\ScaledLearningRate}{\eta_{\text{new}}} \newcommand{\ScaledResource}{X} \newcommand{\ScaledSerialFraction}{s} \newcommand{\ScalingCurveWorkerCount}{k} \newcommand{\ScalingEfficiency}{\eta_{\text{scaling}}} \newcommand{\ScalingExponent}{\alpha_{\text{scale}}} \newcommand{\ScalingLawLoss}{\mathcal{L}} \newcommand{\ScanCapabilityGrant}{\Gamma_{\text{scan}}} \newcommand{\ScatteringCrossSection}{\sigma_s} \newcommand{\ScenarioCellRecordCount}{N_{\text{cell}}} \newcommand{\SceneRadiance}{I} \newcommand{\ScheduleFinishTime}{T_{\text{finish}}} \newcommand{\ScheduledSessionDuration}{T_{\text{sched}}} \newcommand{\SchedulingClassWeight}{w} \newcommand{\SchedulingGoodput}{\eta_{\text{scheduling}}} \newcommand{\SchedulingIntervalLength}{t} \newcommand{\ScoreNoiseStandardDeviation}{\sigma} \newcommand{\ScoreNoiseVector}{\mathbf{z}} \newcommand{\ScoreRefreshInterval}{k_{\text{refresh}}} \newcommand{\ScoredPrefixLength}{S_{\text{step}}} \newcommand{\ScoredStepCount}{J} \newcommand{\ScoredStepIndex}{j} \newcommand{\ScoredToolCall}{a} \newcommand{\ScoredToolCallCount}{N} \newcommand{\ScoringErrorStandardDeviation}{\sigma} \newcommand{\ScreenSpaceCovariance}{\boldsymbol{\Sigma}_{2D}} \newcommand{\ScreenedFeature}{x} \newcommand{\ScreenedFeatureSet}{X} \newcommand{\ScreeningMissRate}{m} \newcommand{\SeamActualAccelerations}{\ddot{\mathbf{q}}_{\text{actual}}} \newcommand{\SeamActualConfiguration}{\mathbf{q}_{\text{actual}}} \newcommand{\SeamActualVelocities}{\dot{\mathbf{q}}_{\text{actual}}} \newcommand{\SeamBlendReference}{\mathbf{s}} \newcommand{\SeamBridgeDuration}{T_{\text{blend}}} \newcommand{\SeamBridgePosition}{q_{\text{blend}}} \newcommand{\SeamInstant}{t_{\text{seam}}} \newcommand{\SeamStepTorque}{\tau_{\text{request}}} \newcommand{\SearchBranchingFactor}{b} \newcommand{\SearchDepth}{d_{\max}} \newcommand{\SearchDepthIndex}{d} \newcommand{\SearchQueryEmbedding}{\mathbf{q}} \newcommand{\SecondAdjacentCheckIndex}{b} \newcommand{\SecondAdjacentCheckPassProbability}{p_{b}} \newcommand{\SecondAdjacentCheckSlotTime}{T_{b}} \newcommand{\SecondAtomicGradientUpdate}{B} \newcommand{\SecondCatalogDefinitionCount}{n_{\text{def},B}} \newcommand{\SecondCatalogDefinitionSize}{S_{B}} \newcommand{\SecondClassCoverageFloor}{b} \newcommand{\SecondClientMaskedUpdate}{\mathbf{y}_B} \newcommand{\SecondClientModelParameters}{\theta_B} \newcommand{\SecondComparedGroupLabel}{b} \newcommand{\SecondComparedItem}{j} \newcommand{\SecondFloatingPointAddend}{b} \newcommand{\SecondGroupClassificationThreshold}{\tau_{\text{thr},b}} \newcommand{\SecondGroupQualifiedFraction}{q_b} \newcommand{\SecondGroupSampleApprovalRate}{\hat{p}_b} \newcommand{\SecondGroupSampleSize}{n_b} \newcommand{\SecondJaccardSet}{\mathcal{B}} \newcommand{\SecondRankComputeTime}{T_{\text{rank}_1}} \newcommand{\SecondRaterCategoryFraction}{p_{y,2}} \newcommand{\SecondRingTraceElement}{b} \newcommand{\SecondSummandStandardDeviation}{\sigma_b} \newcommand{\SecondTwinCriticReturnEstimate}{Q_{\phi_2}} \newcommand{\SecurityLabelLattice}{\mathbb{L}} \newcommand{\SecurityLabelSet}{\mathcal{S}_{\text{lab}}} \newcommand{\SelectedActuationCommand}{\mathbf{u}_{\text{act}}} \newcommand{\SelectedDescriptorCount}{n_{\text{sel}}} \newcommand{\SelectedLayerSet}{\mathcal{S}} \newcommand{\SelectionOverheadSize}{S_{\text{sel}}} \newcommand{\SelectionScoreFunction}{f} \newcommand{\SelectionTime}{T_{\text{selection}}} \newcommand{\SelectiveAcceptanceScore}{\kappa} \newcommand{\SelfConsistencySampleCount}{k} \newcommand{\SelfWatchdogTimeout}{T_{\text{self}}} \newcommand{\SenderOverhead}{o_{\text{send}}} \newcommand{\SensingRealityGap}{\Delta_{\text{sens}}} \newcommand{\SensingStageLatency}{T_{\text{sense}}} \newcommand{\SensorErrorBound}{\epsilon} \newcommand{\SensorFeatureTokens}{\mathbf{z}_{\text{sensor}}} \newcommand{\SensorLeverArm}{\mathbf{r}_{P/O}} \newcommand{\SensorLeverArmLength}{r} \newcommand{\SensorLinkTransportTime}{t_{\text{transport}}} \newcommand{\SensorNoiseBound}{\epsilon} \newcommand{\SensorNoiseDensity}{N_{\text{IMU}}} \newcommand{\SensorNoiseStandardDeviation}{\sigma} \newcommand{\SensorObservationFunction}{g} \newcommand{\SensorPatternDictionary}{\mathbf{\Phi}_{\text{dict}}} \newcommand{\SensorPitchAngle}{\theta_{\text{pitch}}} \newcommand{\SensorPointAcceleration}{\mathbf{a}_P} \newcommand{\SensorPointVelocity}{\mathbf{v}_P} \newcommand{\SensorReadoutTime}{t_{\text{readout}}} \newcommand{\SensorReferenceFrame}{\mathcal{F}_{\text{sensor}}} \newcommand{\SensorRowIndex}{y} \newcommand{\SensorTraceMatrix}{\mathbf{X}} \newcommand{\SequenceCounterReading}{S} \newcommand{\SequenceIterationOperations}{c_{\text{decode}}} \newcommand{\SequenceLength}{S} \newcommand{\SequenceToken}{x} \newcommand{\SequentialAttemptIndex}{j} \newcommand{\SequentialBackwardCommunicationTime}{T_{\text{sequential}}} \newcommand{\SequentialCandidateCount}{M} \newcommand{\SequentialCostPerAcceptedTask}{C_{\text{eff,seq}}} \newcommand{\SequentialExecutionTime}{T_{\text{sequential}}} \newcommand{\SequentialLikelihoodRatio}{\Lambda_m} \newcommand{\SequentialLogLikelihoodRatio}{\Lambda_m} \newcommand{\SequentialTestObservation}{X} \newcommand{\SequentialTrialCount}{m} \newcommand{\SerialAutocorrelation}{\rho} \newcommand{\SerialCallCount}{n} \newcommand{\SerialFraction}{r} \newcommand{\SerialLinkClockFrequency}{f_{\text{link}}} \newcommand{\SerialReferenceTime}{T_{\text{serial}}} \newcommand{\SerializationLatency}{L_{\text{lat,serialization}}} \newcommand{\SerializedChunkVolume}{D_{\text{vol,chunk}}} \newcommand{\SerializedTrainingExample}{X} \newcommand{\SeriesComponentCount}{N_{\text{series}}} \newcommand{\SeriesElasticStiffness}{k} \newcommand{\SeriesPsuCount}{n_{\text{psu}}} \newcommand{\ServerAggregationEnergy}{E_{\text{aggregation}}} \newcommand{\ServerIndex}{i} \newcommand{\ServerPower}{P_{\text{server}}} \newcommand{\ServerRoutingWeight}{w} \newcommand{\ServiceRate}{\mu} \newcommand{\ServiceTimeStandardDeviation}{\sigma} \newcommand{\ServiceTimeVariationCoefficient}{c_{s}} \newcommand{\ServingCostPerQuery}{C_{\text{serving}}} \newcommand{\ServingEmpiricalCdf}{F_{P_t}} \newcommand{\ServingPathPredictor}{f_{\text{serve}}} \newcommand{\ServingTransformFunction}{f_{\text{serve}}} \newcommand{\ServingUtilization}{\rho_{\text{serv}}} \newcommand{\ServoFrequencyCorrection}{\Delta f} \newcommand{\SessionAttemptCount}{N_{\text{att}}} \newcommand{\SessionRequestCount}{N_{\text{session}}} \newcommand{\SetMemberPoint}{\mathbf{z}} \newcommand{\SetpointSampleIndex}{k} \newcommand{\SetpointStepInterval}{\Delta t_{\text{step}}} \newcommand{\SettledOperationCharge}{c} \newcommand{\SettledTrajectoryCost}{C} \newcommand{\SetupShareCap}{\phi} \newcommand{\ShadowOnlyFailureCount}{n_{\text{shadow}}} \newcommand{\ShannonEntropy}{H} \newcommand{\ShapedObservationSize}{S_{\text{shaped}}} \newcommand{\ShapedTotalReward}{r_{\text{total}}} \newcommand{\ShapingPotential}{\Phi} \newcommand{\ShardIndex}{s} \newcommand{\ShardReaderCount}{n_{\text{workers}}} \newcommand{\SharedBusBandwidth}{\text{BW}_{\text{bus}}} \newcommand{\SharedHardwareInterferenceDelay}{T_{\text{interf,shared}}} \newcommand{\SharedPoolWorkerCount}{N_{\text{pool}}} \newcommand{\SharedPrefixFraction}{f} \newcommand{\SharedPrefixLength}{S_{\text{prefix}}} \newcommand{\SharedPrefixRequestCount}{n_{\text{req}}} \newcommand{\ShellRelativeThickness}{\epsilon} \newcommand{\ShieldInterceptionCoverage}{c_h} \newcommand{\ShiftedMpcControlSequence}{\tilde{\mathbf{u}}_{0:N_{\text{mpc}}-1}} \newcommand{\ShiftedTestDistribution}{\mathcal{D}'} \newcommand{\ShingleLength}{w} \newcommand{\ShipDecision}{\mathbf{1}_{\text{ship}}} \newcommand{\ShootThroughCurrent}{I_{\text{shoot-through}}} \newcommand{\SiblingPolicyAction}{a'} \newcommand{\SiblingTeamAllocation}{U_{\text{allocated}}} \newcommand{\SightlineRange}{d} \newcommand{\SigmoidFunction}{\sigma} \newcommand{\SignalDimension}{n} \newcommand{\SignalHandoff}{\mathcal{H}} \newcommand{\SignalPropagationDelay}{t_{\text{prop}}} \newcommand{\SignalTrajectory}{s} \newcommand{\SignatureBandCount}{b} \newcommand{\SignificanceCriticalQuantile}{z_{1-\alpha_{\text{sig}}/2}} \newcommand{\SignificanceLevel}{\alpha} \newcommand{\SiliconThermalTimeConstant}{\tau_{\text{th,silicon}}} \newcommand{\SimplexProjection}{\Pi_{\Delta^{K-1}}} \newcommand{\SimulatedPlantDynamics}{f_{\text{sim}}} \newcommand{\SimulatedReturnLevel}{z_{T, \text{sim}}} \newcommand{\SimulatedStateTrajectory}{s_{\text{sim}}} \newcommand{\SimulatedStlRobustness}{\rho_{\text{sim}}} \newcommand{\SimulatedTrajectorySet}{\mathcal{S}_{\text{sim}}} \newcommand{\SimulatedTransportDelay}{T_{d,\text{sim}}} \newcommand{\SimulatedUnbrakedImpactForce}{F_{\text{unbraked,sim}}} \newcommand{\SimulationParameterSet}{\Xi} \newcommand{\SimulationParameterVector}{\boldsymbol{\xi}} \newcommand{\SimulatorStepFunction}{\mathbf{F}} \newcommand{\SingleAgentAcceptanceProbability}{p_{\text{single}}} \newcommand{\SingleDeviceContextLength}{S_{\text{single}}} \newcommand{\SingleDeviceRunTime}{T_1} \newcommand{\SingleJointAccelerationLimit}{\ddot{q}_{i,\max}} \newcommand{\SingleJointInertia}{M} \newcommand{\SingleJointVelocityLimit}{\dot{q}_{i,\max}} \newcommand{\SingleLinkBandwidth}{\text{BW}_{\text{link}}} \newcommand{\SinglePrecisionGemvIntensity}{I_{\text{GEMV, 32-bit}}} \newcommand{\SingleStepImitationError}{\epsilon} \newcommand{\SingularSpectrumMatrix}{\mathbf{\Sigma}} \newcommand{\SisaShardCount}{K} \newcommand{\SisaTrainingShard}{S} \newcommand{\SixthHarmonicTorqueRipple}{\tau_{\text{ripple}}} \newcommand{\SkewDisplacementEnvelope}{d_{\text{skew}}} \newcommand{\SkillSelectionDistribution}{p} \newcommand{\SlaveDriveCount}{S} \newcommand{\SlaveDriveIndex}{s} \newcommand{\SlaveForwardingDelay}{t_{\text{slave},s}} \newcommand{\SlipAccelerationBound}{a_{\text{slip}}} \newcommand{\SlipRegularizationSpeed}{\epsilon_{\text{reg}}} \newcommand{\SloVector}{\mathbf{S}} \newcommand{\SlowdownPersistenceUpdateCount}{K} \newcommand{\SmallChange}{\delta} \newcommand{\SmallPerturbation}{\delta} \newcommand{\SmallestJacobianSingularNumber}{\sigma_{\min}} \newcommand{\SmallestKeySingularNumber}{\sigma_{\min(S, d_{\text{head}})}} \newcommand{\SmoothedClassifier}{g} \newcommand{\SmoothedRunnerUpProbability}{p_{B}} \newcommand{\SmoothedTargetAction}{\tilde{\mathbf{a}}'} \newcommand{\SmoothedTopClassProbability}{p_{A}} \newcommand{\SmoothingNoiseClipBound}{c} \newcommand{\SmoothingNoiseStandardDeviation}{\sigma} \newcommand{\SmoothnessConstant}{L_s} \newcommand{\SnapshotReadTime}{t_{\text{own}}} \newcommand{\SnapshotResetCycleTime}{T_{\text{cycle,snap}}} \newcommand{\SnapshotStepIndex}{s} \newcommand{\SoftExpectedActionReturn}{Q} \newcommand{\SoftExpectedRemainingReturn}{V} \newcommand{\SoftenedStudentProbabilityVector}{\mathbf{p}_{\text{student}}^{(T_{\text{distill}})}} \newcommand{\SoftenedTeacherProbabilityVector}{\mathbf{p}_{\text{teacher}}^{(T_{\text{distill}})}} \newcommand{\SoftmaxFunction}{\sigma} \newcommand{\SoftmaxInputScore}{x} \newcommand{\SoftmaxInputVector}{\mathbf{x}} \newcommand{\SoftmaxNormalizer}{z} \newcommand{\SoftmaxOutputProbability}{p} \newcommand{\SoftmaxRowMaximum}{m} \newcommand{\SoftmaxRowScore}{s} \newcommand{\SoftmaxRunningMaximum}{m} \newcommand{\SoftmaxVectorLength}{n} \newcommand{\SontagStabilizingControl}{\mathbf{u}_{\text{Sontag}}} \newcommand{\SourceCurrent}{I_{\text{source}}} \newcommand{\SourceEventTime}{T_{\text{event}}} \newcommand{\SourceFramePoint}{\mathbf{p}_B} \newcommand{\SourceSinkPathSet}{\Pi} \newcommand{\SourceVoltage}{V_{\text{source}}} \newcommand{\SourceWriteShardGrant}{\Gamma_{c}} \newcommand{\SpareStoppingClearance}{d_{\text{spare}}} \newcommand{\SparseMatrixEntryCount}{n_{\text{elem}}} \newcommand{\SparseMatrixRowCount}{n_{\text{rows}}} \newcommand{\SparseProductInputComponent}{v} \newcommand{\SparseWeightMatrix}{\mathbf{W}_{\text{sparse}}} \newcommand{\SparsityPenaltyWeight}{\lambda_{\text{L1}}} \newcommand{\SparsityRatio}{\rho_{\text{sparse}}} \newcommand{\SpatialClearancePredicate}{P_{\text{clear}}} \newcommand{\SpatialColumnIndex}{j} \newcommand{\SpatialCovarianceEmbedding}{\mathbf{e}_{\Sigma}} \newcommand{\SpatialErrorVector}{\boldsymbol{\epsilon}_{\text{spatial}}} \newcommand{\SpatialHashFunction}{h} \newcommand{\SpatialMemoryMap}{\mathcal{M}} \newcommand{\SpatialPositionCount}{N_{\text{pix}}} \newcommand{\SpatialRowIndex}{i} \newcommand{\SpatialTransformation}{\mathcal{T}} \newcommand{\SpecialEuclideanAlgebra}{\mathfrak{se}(3)} \newcommand{\SpecialEuclideanGroup}{SE(3)} \newcommand{\SpecialOrthogonalGroup}{SO(3)} \newcommand{\SpecializedEnergyProductivity}{\rho_{\text{energy,specific}}} \newcommand{\SpecificHeatCapacity}{c_p} \newcommand{\SpectrallyNormalizedWeightMatrix}{\overline{\mathbf{W}}} \newcommand{\SpeculativeDecodingSpeedup}{S_{\text{spec}}} \newcommand{\SpeculativeDraftLength}{K} \newcommand{\SpeculativeDraftTokenCount}{k} \newcommand{\SpeedAtDetection}{v} \newcommand{\SpeedBound}{v_{\max}} \newcommand{\SpendingWindowDuration}{T_{\text{win}}} \newcommand{\SphereSurfaceArea}{S_{D-1}} \newcommand{\SplineControlPoint}{\mathbf{p}} \newcommand{\SplineDegree}{p} \newcommand{\SplineFinalControlIndex}{L} \newcommand{\SplineKnotTime}{\xi} \newcommand{\SplitAssignmentMap}{s} \newcommand{\SplitMessageCount}{N_{\text{msg}}} \newcommand{\SpotHourlyPrice}{C_{\text{spot}}} \newcommand{\SpringBrakeEngagementTime}{t_{\text{engage}}} \newcommand{\SpringCompressionForce}{F} \newcommand{\SprtExpectedLogIncrement}{m} \newcommand{\SprtLowerBoundary}{\Lambda_{\text{lo}}} \newcommand{\SprtLowerLogBoundary}{b_{\text{low}}} \newcommand{\SprtStoppingSampleCount}{N_{\text{stop}}} \newcommand{\SprtUpperBoundary}{\Lambda_{\text{up}}} \newcommand{\SprtUpperLogBoundary}{u} \newcommand{\SquareGemmDimension}{N} \newcommand{\SquaredGaussianSumQuantile}{\chi} \newcommand{\SquaredPathVelocity}{x} \newcommand{\SquaredRadiusSubstitution}{u} \newcommand{\SquashedActionComponent}{a} \newcommand{\SramCapacity}{M_{\text{SRAM}}} \newcommand{\StabilizationErrorThreshold}{\epsilon_{\text{stable}}} \newcommand{\StabilizationSlewCeiling}{j_{\text{stable}}} \newcommand{\StackedContactForces}{\mathbf{f}_{\text{c}}} \newcommand{\StageConditionalAcceptanceProbability}{q} \newcommand{\StageEpisodeCount}{N_{\text{episodes}}} \newcommand{\StageReachProbability}{r} \newcommand{\StagedDefinitionCount}{n_{\text{def}}} \newcommand{\StagingExhaustionTime}{T_{\text{exhaust}}} \newcommand{\StagingStoreCapacity}{M_{\text{stage}}} \newcommand{\StaleSupportRate}{\epsilon_{\text{stale}}} \newcommand{\StalenessAdjustedLearningRate}{\eta'} \newcommand{\StalenessBound}{s} \newcommand{\StallCounterTorque}{\tau_{\text{stall}}} \newcommand{\StallTravelBound}{d_{\text{F1}}} \newcommand{\StandardDeviationMultiple}{k} \newcommand{\StandardNormalCumulativeDistribution}{\Phi} \newcommand{\StandardNormalQuantile}{z_q} \newcommand{\StandbyInstanceMemory}{M_{\text{standby}}} \newcommand{\StandbyPower}{P_{\text{idle}}} \newcommand{\StandbyReserveCount}{N_{\text{reserve}}} \newcommand{\StandstillSpeedThreshold}{\epsilon_{\text{vel}}} \newcommand{\StateConstraintMatrix}{\mathbf{H}_x} \newcommand{\StateConstraintVector}{\mathbf{b}_x} \newcommand{\StateCotangentSpace}{T_{\mathbf{x}}^*} \newcommand{\StateDimension}{n} \newcommand{\StateDistribution}{d_\pi} \newcommand{\StateEstimate}{\hat{\mathbf{x}}} \newcommand{\StateEstimateDerivative}{\dot{\hat{\mathbf{x}}}} \newcommand{\StateEstimationError}{\mathbf{e}} \newcommand{\StateExposureLevel}{S} \newcommand{\StateNormWeighting}{W} \newcommand{\StateOperation}{f} \newcommand{\StateParameterSensitivity}{\mathbf{S}} \newcommand{\StateRecurrencePeriod}{\ell} \newcommand{\StateScalarFunction}{\phi} \newcommand{\StateSpaceDimension}{d_s} \newcommand{\StateSpaceInputMatrix}{\mathbf{B}} \newcommand{\StateSpaceSystemMatrix}{\mathbf{A}_{\text{sys}}} \newcommand{\StateTokenCount}{K_s} \newcommand{\StateTrackingWeightMatrix}{\mathbf{W}_q} \newcommand{\StateTransitionMatrix}{\mathbf{F}} \newcommand{\StatelessCursorPayload}{d} \newcommand{\StaticBatchingOperations}{O_{\text{traditional}}} \newcommand{\StaticChassisPower}{P_{\text{chassis\_static}}} \newcommand{\StaticDataDistribution}{p_{\text{data}}} \newcommand{\StationaryConditionPolynomial}{P} \newcommand{\StatisticalDivergence}{\mathcal{D}(P_t \| P_0)} \newcommand{\StatisticalFalseNegativeRate}{\beta} \newcommand{\StatisticalHypothesis}{H} \newcommand{\StatisticalPowerQuantile}{z_{1-\beta}} \newcommand{\StatisticalSignificanceLevel}{\alpha_{\text{sig}}} \newcommand{\StatorCoreTemperature}{T_{\text{core}}} \newcommand{\StatorIronTemperature}{T_{\text{iron}}} \newcommand{\StatorThermalCapacitance}{C_{\text{th}}} \newcommand{\StatusPollCount}{N_{\text{poll}}} \newcommand{\SteadyDeceleration}{a} \newcommand{\SteadyStateAvailability}{A} \newcommand{\SteadyStateCurrent}{I_{\text{final}}} \newcommand{\SteadyStateErrorCovariance}{\mathbf{P}_{\text{est}}} \newcommand{\SteadyStateIntegratorState}{\mathbf{z}_{\text{ss}}} \newcommand{\SteadyStateTemperatureRise}{\Delta T_{\max}} \newcommand{\SteadyStateTrackingError}{\mathbf{e}_{\text{ss}}} \newcommand{\SteeringTransferTime}{T} \newcommand{\StepFailureHazard}{a} \newcommand{\StepGenerationCost}{C_{\text{gen}}} \newcommand{\StepGenerationTime}{T_{\text{step}}} \newcommand{\StepIoTime}{T_{\text{IO}}} \newcommand{\StepResponsePhaseLag}{\Delta \phi} \newcommand{\StepSettlingTime}{t_{\text{settle}}} \newcommand{\StepSuccessProbability}{p} \newcommand{\StepTestVoltage}{V_{\text{step}}} \newcommand{\StepTimePenalty}{c_{\text{time}}} \newcommand{\StepTokenLogit}{z_{t,v}} \newcommand{\StereoBaseline}{b} \newcommand{\StereoDisparity}{d} \newcommand{\StlEventuallyDeadline}{\tau} \newcommand{\StlFormula}{\phi} \newcommand{\StlIntervalEnd}{b} \newcommand{\StlIntervalStart}{a} \newcommand{\StlPredicateFunction}{f} \newcommand{\StlRobustness}{\rho} \newcommand{\StlUntilOperator}{\mathcal{U}_{[a, b]}} \newcommand{\StockoutNormalQuantile}{z_{1-\epsilon}} \newcommand{\StockoutProbabilityTarget}{\epsilon} \newcommand{\StopAxisAcceleration}{\ddot{q}_{\text{stop}}} \newcommand{\StopAxisPosition}{q_{\text{stop}}} \newcommand{\StopCompletionInstant}{t_{\text{stop\_end}}} \newcommand{\StopDecisionComputeBound}{T_{\text{compute}}} \newcommand{\StopProgress}{u} \newcommand{\StopSequenceSet}{\mathcal{S}_{\text{stop}}} \newcommand{\StoppingBoundaryClearance}{z} \newcommand{\StoppingCrossoverSpeed}{v^{*}} \newcommand{\StoppingDeadline}{t_{\text{deadline,stop}}} \newcommand{\StoppingDistance}{d_{\text{stop}}} \newcommand{\StoppingDistanceBudget}{d_{\text{budget}}} \newcommand{\StoppingDuration}{T_{\text{stop}}} \newcommand{\StorageAccessFactor}{F_{\text{access}}} \newcommand{\StorageBandwidth}{\text{BW}_{\text{storage}}} \newcommand{\StorageCapacityPrice}{C_{\text{storage/byte-time}}} \newcommand{\StorageEquipmentPower}{P_{\text{storage}}} \newcommand{\StorageFunction}{V} \newcommand{\StorageFunctionDerivative}{\dot{V}} \newcommand{\StorageIngestBandwidth}{\text{BW}_{\text{ingest}}} \newcommand{\StoragePrice}{c_{\text{storage}}} \newcommand{\StorageReadTime}{T_{\text{read}}} \newcommand{\StorageRetentionTime}{T_{\text{months}}} \newcommand{\StorageThroughput}{R_{\text{storage}}} \newcommand{\StoredDataVolume}{D_{\text{vol,store}}} \newcommand{\StoredEmbedding}{\mathbf{z}} \newcommand{\StoredIndexVector}{\mathbf{x}} \newcommand{\StoredSystemState}{s} \newcommand{\StoredTokenVolume}{V} \newcommand{\StragglerStepTime}{T_{\text{step,straggler}}} \newcommand{\StreamAcceptanceProbability}{p} \newcommand{\StreamingEndToEndLatency}{T_{\text{streaming}}} \newcommand{\StrideCheckpointCount}{N} \newcommand{\StrongConfigurationAttemptCost}{c_{\text{big}}} \newcommand{\StrongConfigurationPassProbability}{p_{\text{big}}} \newcommand{\StruckObjectMass}{m_{\text{obj}}} \newcommand{\StructuredSparsityGroupSize}{m_{\text{group}}} \newcommand{\StructuredSparsityNonzeroCount}{n_{\text{keep}}} \newcommand{\StudentProbabilityVector}{\mathbf{p}_{\text{student}}} \newcommand{\StuffBitTime}{t_{\text{stuff},i}} \newcommand{\SubgroupIndex}{g} \newcommand{\SubgroupSampleSize}{n} \newcommand{\SubintervalFailureProbability}{p} \newcommand{\SublevelSetThreshold}{c} \newcommand{\SubsequentArrivalTime}{\tau} \newcommand{\SubsetAllPassIndicator}{I_J^{\text{all}}} \newcommand{\SubsetAnyPassIndicator}{I_J} \newcommand{\SubsetDatasetSize}{D_{\text{subset}}} \newcommand{\SuccessCountIndex}{j} \newcommand{\SuccessLowerConfidenceLimit}{p_{\text{lower}}} \newcommand{\SuccessfulTrialCount}{k} \newcommand{\SuccessorActionVector}{\mathbf{a}'} \newcommand{\SuccessorPlanningState}{s'} \newcommand{\SuffixFoldTime}{T_{\text{fold}}} \newcommand{\SummaryOutputLength}{K_{\text{sum}}} \newcommand{\SummaryTokenEmbedding}{\mathbf{x}_{\text{class}}} \newcommand{\SupervisoryMtbi}{T_{\text{MTBI}}} \newcommand{\SupervisoryTakeoverLatency}{T_{\Sigma}} \newcommand{\SupplyVoltage}{V} \newcommand{\SupportPolygon}{\mathcal{P}_{\text{support}}} \newcommand{\SupportSetSize}{n_{\text{shot}}} \newcommand{\SustainableAttemptRate}{R_{\text{attempt}}} \newcommand{\SustainableCopperLossPower}{P_{\text{loss,ss}}} \newcommand{\SustainableHoldingTorque}{\tau_{\text{hold,max}}} \newcommand{\SustainedComputeRate}{R_{\text{sustained}}} \newcommand{\SustainedDropoutFrameCount}{N_{\text{drop}}} \newcommand{\SustainedMemoryBandwidth}{\text{BW}_{\text{mem}}} \newcommand{\SweepCandidateCostFraction}{f} \newcommand{\SweepCandidateCount}{k} \newcommand{\SwitchBreakdownVoltage}{V_{\text{breakdown}}} \newcommand{\SwitchInputCapacitance}{C_{\text{iss}}} \newcommand{\SwitchOnResistance}{R_{\text{ds(on)}}} \newcommand{\SwitchRadix}{k} \newcommand{\SwitchedCapacitance}{C} \newcommand{\SwitchingActivityFactor}{\alpha} \newcommand{\SwitchingEnergy}{E} \newcommand{\SwitchingTransitionTime}{t_{\text{sw}}} \newcommand{\SymbolicPlanningState}{s} \newcommand{\SymmetricClippingThreshold}{\alpha_{\text{sym}}} \newcommand{\SymmetricMessageOverhead}{o} \newcommand{\SymplecticEulerTransitionMatrix}{\mathbf{A}_{\text{symp}}} \newcommand{\SyncMessageInterval}{\Delta t_{\text{interval}}} \newcommand{\SyncPairingDisplacement}{\Delta \mathbf{x}_{\text{sync}}} \newcommand{\SynchronizationBlackout}{T_{\text{blackout}}} \newcommand{\SynchronizationClearanceMargin}{d_{\text{sync}}} \newcommand{\SynchronizationErrorBound}{\epsilon_{\text{sync}}} \newcommand{\SynchronizationStepIndex}{k} \newcommand{\SynchronizationTime}{T_{\text{sync}}} \newcommand{\SyntheticDataGenerator}{G_{\theta}} \newcommand{\SyntheticDataset}{\mathcal{S}_{\text{synthetic}}} \newcommand{\SystemCallFilterTime}{T_{\text{filter}}} \newcommand{\SystemCallOverheadTime}{T_{\text{syscall}}} \newcommand{\SystemFailureRate}{\lambda_{\text{system}}} \newcommand{\SystemHazardRate}{\lambda_{\text{system}, h}} \newcommand{\SystemInstructionTokenCount}{S_{\text{system}}} \newcommand{\SystemMatrixPowerIndex}{k} \newcommand{\SystemMemoryBandwidth}{\text{BW}_{\text{system}}} \newcommand{\SystemMtbf}{\text{MTBF}_{\text{system}}} \newcommand{\SystemReliability}{R_{\text{system}}} \newcommand{\TableRowCount}{N} \newcommand{\TailByteAllocation}{M_{\text{tail}}} \newcommand{\TailMomentOrder}{k} \newcommand{\TailPerformanceMetric}{X} \newcommand{\TailRequestLatency}{T_{\text{lat},\text{p99}}} \newcommand{\TailRequestSeenBatchSize}{B_{\text{req,p99}}} \newcommand{\TailRiskDistributionFunction}{F} \newcommand{\TailRiskObservation}{X} \newcommand{\TailRiskObservationLevel}{x} \newcommand{\TailShapeParameter}{\xi} \newcommand{\TailStepIoTime}{T_{\text{IO,p99}}} \newcommand{\TailSupportUpperEndpoint}{x_F} \newcommand{\TakeoverInstant}{t_{\text{takeover}}} \newcommand{\TakeoverResponseTime}{T_{\Sigma, 1}} \newcommand{\TakeoverStateVisitationDistribution}{p^{\text{takeover}}} \newcommand{\TakeoverTrackingError}{\mathbf{e}_{\text{track}}} \newcommand{\TangentDirection}{\mathbf{v}} \newcommand{\TangentSeedVector}{\dot{\mathbf{x}}} \newcommand{\TangentialContactShear}{\mathbf{f}_{k, \parallel}} \newcommand{\TangentialSpeed}{v_{\text{tangential}}} \newcommand{\TapeIntermediateResult}{y_{\text{tape}}} \newcommand{\TargetAcceptanceDifference}{\Delta} \newcommand{\TargetActionReturnEstimate}{\hat{Q}} \newcommand{\TargetActorParameters}{\theta'} \newcommand{\TargetBatchSize}{B_{\text{target}}} \newcommand{\TargetCompletionQuantile}{q} \newcommand{\TargetComputeRate}{R_{\text{ops}}} \newcommand{\TargetComputeTimeFraction}{\eta_{\text{target}}} \newcommand{\TargetCriticParameters}{\phi'} \newcommand{\TargetCriticReturnEstimate}{Q_{\phi'}} \newcommand{\TargetDeterministicPolicy}{\mu_{\theta'}} \newcommand{\TargetError}{\epsilon} \newcommand{\TargetExceedanceProbability}{\epsilon} \newcommand{\TargetFairShare}{F_{\text{target}}} \newcommand{\TargetFramePoint}{\mathbf{p}_A} \newcommand{\TargetHazardRate}{\lambda_{\text{target}}} \newcommand{\TargetImpedanceDampingMatrix}{\mathbf{D}_d} \newcommand{\TargetImpedanceInertiaMatrix}{\mathbf{M}_d} \newcommand{\TargetImpedanceStiffnessMatrix}{\mathbf{K}_d} \newcommand{\TargetInferenceLatency}{L_{\text{lat,target}}} \newcommand{\TargetKeyAttentionWeight}{\alpha_{\text{target}}} \newcommand{\TargetKeyLogit}{z_{\text{target}}} \newcommand{\TargetModelDistribution}{p_{\theta}} \newcommand{\TargetOrientation}{\mathbf{R}_{\text{target}}} \newcommand{\TargetPlantState}{\mathbf{x}_{f}} \newcommand{\TargetPolicyEntropy}{\overline{\mathcal{H}}} \newcommand{\TargetPose}{\mathbf{T}_{\text{target}}} \newcommand{\TargetPosition}{\mathbf{p}_{\text{target}}} \newcommand{\TargetPositionComponent}{p_{\text{target},i}} \newcommand{\TargetRange}{z} \newcommand{\TargetRepeatedRunConsistency}{p_{\text{target}}} \newcommand{\TargetSamplingDistribution}{p} \newcommand{\TargetServingUtilization}{\rho_{\text{target}}} \newcommand{\TargetSmoothingNoise}{\boldsymbol{\epsilon}} \newcommand{\TargetSmoothingNoiseStandardDeviation}{\sigma} \newcommand{\TargetTokenVolume}{W} \newcommand{\TargetTravelDistance}{d} \newcommand{\TargetTrialFailureProbability}{p_{*}} \newcommand{\TargetTrialSuccessProbability}{p_{\text{target}}} \newcommand{\TargetTwinCriticReturnEstimate}{Q_{\phi'_i}} \newcommand{\TargetUnitQuaternion}{\mathbf{q}_{\text{quat,target}}} \newcommand{\TargetUpdateCount}{K_{\text{target}}} \newcommand{\TargetUtilizationBatchSize}{B_{\text{util}}} \newcommand{\TargetXPosition}{x} \newcommand{\TargetYPosition}{p_y} \newcommand{\TargetZPosition}{z} \newcommand{\TaskAcceptanceLabel}{x} \newcommand{\TaskBlockingTime}{B} \newcommand{\TaskContract}{\mathcal{C}} \newcommand{\TaskContractGoal}{G} \newcommand{\TaskCost}{C_{\text{task}}} \newcommand{\TaskCount}{K} \newcommand{\TaskCoverageProbability}{Q} \newcommand{\TaskCriticalSections}{cs} \newcommand{\TaskDerivativeGain}{\mathbf{K}_{d,i}} \newcommand{\TaskDistance}{d_{\text{task}}} \newcommand{\TaskEnvironment}{\mathcal{E}_{\text{env}}} \newcommand{\TaskErrorTolerance}{\tau_{\text{tol}}} \newcommand{\TaskGroupMap}{g} \newcommand{\TaskIndex}{i} \newcommand{\TaskInterferenceTime}{I} \newcommand{\TaskJacobian}{\mathbf{J}} \newcommand{\TaskJacobianDerivative}{\dot{\mathbf{J}}} \newcommand{\TaskJacobianPseudoinverse}{\mathbf{J}^\dagger} \newcommand{\TaskKinematicMap}{f} \newcommand{\TaskLoss}{\mathcal{L}_{\text{task}}} \newcommand{\TaskLossGradient}{\nabla \mathcal{L}} \newcommand{\TaskPeriod}{T} \newcommand{\TaskProportionalGain}{\mathbf{K}_{p,i}} \newcommand{\TaskReadCount}{n_{\text{read}}} \newcommand{\TaskRelativeDeadline}{D} \newcommand{\TaskRelevantOutcome}{\mathbf{Y}_{\text{task}}} \newcommand{\TaskReward}{r_{\text{task}}} \newcommand{\TaskSetUtilization}{U} \newcommand{\TaskSpaceAcceleration}{\ddot{\mathbf{x}}} \newcommand{\TaskSpaceCoordinates}{\mathbf{x}} \newcommand{\TaskSpaceDimension}{m} \newcommand{\TaskSpaceReference}{\mathbf{x}_i^{\text{ref}}} \newcommand{\TaskSpaceReferenceAcceleration}{\ddot{\mathbf{x}}^{\text{ref}}} \newcommand{\TaskSpaceReferenceVelocity}{\dot{\mathbf{x}}^{\text{ref}}} \newcommand{\TaskSpaceVelocity}{\dot{\mathbf{x}}} \newcommand{\TaskSpecificLoss}{\mathcal{L}} \newcommand{\TaskStateTokenCount}{S_{\text{state}}} \newcommand{\TaskToleranceSemiAxes}{\mathbf{r}} \newcommand{\TaskToleranceSemiAxis}{r} \newcommand{\TaskTurnCost}{C_{\text{call}}} \newcommand{\TaskWeight}{w} \newcommand{\TasksPerComparisonArm}{N_{\text{arm}}} \newcommand{\TeacherProbabilityVector}{\mathbf{p}_{\text{teacher}}} \newcommand{\TeamQuotaCap}{Q_{\text{team}}} \newcommand{\TelemetryFlushTime}{t_{\text{telemetry\_flush}}} \newcommand{\TelemetryFreshnessBound}{\Delta t_{\text{fresh}}} \newcommand{\TelemetryRetentionDuration}{T_{\text{retention}}} \newcommand{\TelemetrySamplingFrequency}{f_{\text{sample}}} \newcommand{\TelemetrySeriesCount}{N_{\text{series}}} \newcommand{\TelemetryTickInterval}{\Delta t_s} \newcommand{\TeleoperationCommandLatency}{t_{\text{cmd}}} \newcommand{\TeleoperationDownlinkTime}{T_{\text{downlink}}} \newcommand{\TeleoperationRoundTripLatency}{t_{\text{loop}}} \newcommand{\TeleoperationRoundTripTime}{T_{\text{RTT}}} \newcommand{\TeleoperationStateVisitationDistribution}{p^{\pi_{\text{teleop}}}} \newcommand{\TeleoperationUplinkTime}{T_{\text{uplink}}} \newcommand{\TeleoperationVideoLatency}{T_{\text{video}}} \newcommand{\TemperatureDualObjective}{\mathcal{L}} \newcommand{\TemperatureStepSize}{\lambda_{\alpha}} \newcommand{\TemplateSharedMemory}{M_{\text{template}}} \newcommand{\TemporalDifferenceResidual}{\delta} \newcommand{\TemporalEnsemblingWeight}{w_i} \newcommand{\TenantIndex}{i} \newcommand{\TenantResourceAllocation}{a_{i,r}} \newcommand{\TensorAxisCount}{n} \newcommand{\TensorColumnModeSize}{J} \newcommand{\TensorCoreAccumulatorMatrix}{\mathbf{C}_{\text{acc}}} \newcommand{\TensorCoreLeftInput}{\mathbf{A}_{\text{tc}}} \newcommand{\TensorCoreOutputMatrix}{\mathbf{D}_{\text{tc}}} \newcommand{\TensorCoreRightInput}{\mathbf{B}_{\text{tc}}} \newcommand{\TensorDepthModeSize}{T} \newcommand{\TensorElementCount}{N} \newcommand{\TensorModeIndex}{n_{\text{mode}}} \newcommand{\TensorParallelDegree}{N_{\text{TP}}} \newcommand{\TensorParallelLayerTime}{T_{\text{inference}}} \newcommand{\TensorRowModeSize}{I} \newcommand{\TerminalFeedbackGain}{\mathbf{K}_f} \newcommand{\TerminalInvariantSet}{\mathcal{X}_{f}} \newcommand{\TerminalPlantState}{\mathbf{x}_N} \newcommand{\TerminalTransitTime}{t_{\text{transit}}} \newcommand{\TerminalVoltageLimit}{V_{\max}} \newcommand{\TerminationProtocol}{\kappa} \newcommand{\TestExample}{z_{\text{test}}} \newcommand{\TestFamilySize}{k} \newcommand{\TestPhaseCapabilityGrant}{\Gamma_{\text{test}}} \newcommand{\TestsDirectoryShardGrant}{\Gamma_{a}} \newcommand{\TextTokenCount}{S_{\text{text}}} \newcommand{\TextTokenEmbeddings}{\mathbf{z}_{\text{text}}} \newcommand{\ThermalExpansionCoefficient}{\alpha} \newcommand{\ThermalPenaltyWeight}{\lambda_T} \newcommand{\ThermalPowerLimit}{P_{\text{thermal}}} \newcommand{\ThermalResistance}{R_{\text{th}}} \newcommand{\ThermalTimeConstant}{\tau_{\text{th}}} \newcommand{\ThirdAtomicGradientUpdate}{C} \newcommand{\ThirdFloatingPointAddend}{c} \newcommand{\ThirdRingTraceElement}{c} \newcommand{\ThresholdExceedanceCount}{N_u} \newcommand{\ThresholdExceedanceRate}{\zeta_u} \newcommand{\ThresholdExcess}{y} \newcommand{\ThresholdExcessVariable}{Y} \newcommand{\ThresholdedSparsityRatio}{\rho_{\text{sparse},\delta}} \newcommand{\ThrottleClearTemperature}{T_{\text{clear}}} \newcommand{\ThrottleOnsetJunctionTemperature}{T_{\text{j},\text{start}}} \newcommand{\ThrottleRecoveryTime}{t_{\text{recov}}} \newcommand{\ThrottleTripTemperature}{T_{\text{trip}}} \newcommand{\ThrottledClockFrequency}{f_{\text{throt}}} \newcommand{\TickCycleCount}{N} \newcommand{\TickIndex}{n} \newcommand{\TickPeriodJitterBound}{J_{\text{phase}}} \newcommand{\TieredRequestServiceTime}{T} \newcommand{\TightenedDiscreteSafeSet}{\mathcal{C}_{\text{discrete}}} \newcommand{\TileRowIndex}{m} \newcommand{\TiltAngle}{\theta_{\text{tilt}}} \newcommand{\Time}{T} \newcommand{\TimeBudgetUsedFraction}{\rho_T} \newcommand{\TimeInstant}{t} \newcommand{\TimeScaleSeparationRatio}{\epsilon} \newcommand{\TimeStepIndex}{t} \newcommand{\TimeToResult}{T_{\text{result}}} \newcommand{\TimeToTarget}{T_{\text{target}}} \newcommand{\TimeoutSafetyMultiplier}{k} \newcommand{\TimeoutTrialCount}{n_{\text{timeout}}} \newcommand{\TimerClockPeriod}{T_{\text{timer\_clk}}} \newcommand{\TimestampJitterDelay}{\delta_{\text{jitter}}} \newcommand{\TimestampQuantizationBound}{T_{\text{quant}}} \newcommand{\TimestampSkew}{t_{\text{skew}}} \newcommand{\TimingJitter}{\sigma_{\text{jitter}}} \newcommand{\TimingRealityGap}{\Delta_{\text{lat}}} \newcommand{\TokenAuthenticationCode}{\sigma} \newcommand{\TokenAveragedBatchLoss}{\mathcal{L}_{\text{token}}} \newcommand{\TokenBucketDepth}{b} \newcommand{\TokenBucketRefillRate}{r} \newcommand{\TokenBudgetUsedFraction}{\rho_N} \newcommand{\TokenByteDecoding}{s} \newcommand{\TokenCaveat}{c} \newcommand{\TokenDispatchTime}{T_{\text{dispatch}}} \newcommand{\TokenIdentifierSize}{s_{\text{id}}} \newcommand{\TokenIndex}{t} \newcommand{\TokenPrefix}{x_{<t}} \newcommand{\TokenVocabulary}{\mathcal{V}} \newcommand{\TokenizationTime}{T_{\text{tokenize}}} \newcommand{\ToleranceEllipsoidMatrix}{\mathbf{E}} \newcommand{\ToleratedFailureProbability}{\epsilon} \newcommand{\ToleratedPositionError}{\epsilon_{\text{pos}}} \newcommand{\TombstonedNodeSet}{V_{\text{tomb}}} \newcommand{\TombstonedRecordFraction}{\rho_{\text{dead}}} \newcommand{\ToolArgumentKey}{p} \newcommand{\ToolCallCategory}{y} \newcommand{\ToolCallCost}{c_{\text{tool}}} \newcommand{\ToolCallIndex}{i} \newcommand{\ToolCallReadSet}{R} \newcommand{\ToolCallWriteSet}{W} \newcommand{\ToolCartesianPose}{\mathbf{x}} \newcommand{\ToolCartesianVelocity}{\dot{\mathbf{x}}} \newcommand{\ToolCenterPointAxis}{\hat{\mathbf{z}}_{\text{TCP}}} \newcommand{\ToolCenterPointFrame}{\mathcal{F}_{\text{TCP}}} \newcommand{\ToolCenterPointPose}{\mathbf{T}_{\text{TCP}}} \newcommand{\ToolCenterPointPosition}{\mathbf{p}_{\text{TCP}}} \newcommand{\ToolClearanceDistance}{d_{\text{tool}}} \newcommand{\ToolDeclarationTokenCount}{S_{\text{tools}}} \newcommand{\ToolDescriptorSize}{S_{\text{desc}}} \newcommand{\ToolPlanarAbscissa}{x} \newcommand{\ToolPlanarOrdinate}{y} \newcommand{\ToolPositionError}{e_{\text{tool}}} \newcommand{\ToolServiceCount}{N_{\text{tool}}} \newcommand{\ToolSpeedLimit}{v_{\text{TCP}}} \newcommand{\ToolTargetState}{s} \newcommand{\ToolTime}{T_{\text{tool}}} \newcommand{\ToolTipPose}{\mathbf{T}_{\text{tool}}} \newcommand{\TopClassCount}{k} \newcommand{\TopMagnitudeIndicator}{\mathbf{1}_{|\mathbf{g}| \geq |\mathbf{g}|_{(K_{\text{top}})}}} \newcommand{\TopTokenSampleCount}{k} \newcommand{\TopologicalPlaceNode}{p^{\text{place}}} \newcommand{\TopologyEndpointCount}{N} \newcommand{\TorqueCutoffCommand}{\mathbf{u}_{\text{cutoff}}} \newcommand{\TorqueEffortPenaltyWeight}{\lambda_{\tau}} \newcommand{\TorqueProducingCurrent}{i_q} \newcommand{\TorqueRateLimit}{\dot{\tau}_{\max}} \newcommand{\TorqueRegularizationWeight}{w_\tau} \newcommand{\TorqueSlewPenaltyWeight}{\lambda_{\dot{\tau}}} \newcommand{\TorusFirstAxisChipCount}{X} \newcommand{\TorusSecondAxisChipCount}{Y} \newcommand{\TorusThirdAxisChipCount}{Z} \newcommand{\TotalChipPower}{P_{\text{total}}} \newcommand{\TotalCollisionQueryTime}{T_{\text{query\_total}}} \newcommand{\TotalDataCost}{C_{\text{total}}} \newcommand{\TotalDelayPhaseShift}{\phi_{\text{total}}} \newcommand{\TotalEnergy}{E_{\text{total}}} \newcommand{\TotalExecutedTrialCount}{N_{\text{total}}} \newcommand{\TotalFailureRecoveryTime}{T_{\text{recovery}}} \newcommand{\TotalGateCharge}{Q_g} \newcommand{\TotalInterventionCount}{N_{\text{int}}} \newcommand{\TotalKineticEnergy}{E_{k,\text{total}}} \newcommand{\TotalMemoryFootprint}{M_{\text{total}}} \newcommand{\TotalPipelineLatency}{L_{\text{lat,total}}} \newcommand{\TotalTrainingRunCost}{C_{\text{total}}} \newcommand{\TraceCrashCount}{N_{\text{crash}}} \newcommand{\TraceCrashIndex}{i} \newcommand{\TraceDecay}{\lambda} \newcommand{\TraceIntermediateAdjoint}{\bar{v}} \newcommand{\TraceIntermediateTangent}{\dot{v}} \newcommand{\TraceIntermediateVariable}{v} \newcommand{\TrackIndex}{i} \newcommand{\TrackLastUpdateTime}{t_{\text{last}}} \newcommand{\TrackLossTimeout}{T_{\text{lost}}} \newcommand{\TrackPositionDeviation}{\sigma_{\text{track}}} \newcommand{\TrackPredictedErrorCovariance}{\mathbf{P}_{t|t-1}} \newcommand{\TrackPredictedStateEstimate}{\hat{\mathbf{x}}_{t|t-1}} \newcommand{\TrackedEvidenceHorizon}{\tau_{\text{ev,tracked}}} \newcommand{\TrackerFrameIndex}{t} \newcommand{\TrackingErrorAcceleration}{\ddot{\mathbf{e}}} \newcommand{\TrackingErrorAllowance}{\epsilon_{\text{pos}}} \newcommand{\TrackingErrorBound}{\epsilon_{\text{track}}} \newcommand{\TrackingErrorDistance}{e} \newcommand{\TrackingErrorRate}{\dot{\mathbf{e}}} \newcommand{\TrackingErrorVector}{\mathbf{e}} \newcommand{\TrackingRelaxationSlack}{\delta} \newcommand{\TrackingSlackPenaltyWeight}{p} \newcommand{\TrackingStartInstant}{t_{\text{start}}} \newcommand{\TractionLimitedDeceleration}{a} \newcommand{\TractiveForce}{F_x} \newcommand{\TrainableStateMemory}{M_{\text{train}}} \newcommand{\TrainerUpdateTime}{T_{\text{train}}} \newcommand{\TrainingCompute}{O_{\text{train}}} \newcommand{\TrainingCost}{C_{\text{train}}} \newcommand{\TrainingDataset}{D} \newcommand{\TrainingDistribution}{P_0} \newcommand{\TrainingEmpiricalCdf}{F_{P_0}} \newcommand{\TrainingExample}{z} \newcommand{\TrainingFailureCount}{N_{\text{failures}}} \newcommand{\TrainingFeatureMean}{\mu} \newcommand{\TrainingFeatureStandardDeviation}{\sigma} \newcommand{\TrainingLabelMask}{\mathcal{M}_{\text{train}}} \newcommand{\TrainingLoss}{\mathcal{L}_{\text{train}}} \newcommand{\TrainingPathPredictor}{f_{\text{train}}} \newcommand{\TrainingPipelineFunction}{f} \newcommand{\TrainingRunCount}{N_{\text{runs}}} \newcommand{\TrainingSampleThroughput}{R_{\text{train}}} \newcommand{\TrainingSchemaKeySet}{\mathcal{K}_{\text{train}}} \newcommand{\TrainingServingSkew}{S_{\text{skew}}} \newcommand{\TrainingSplitFraction}{f_{\text{train}}} \newcommand{\TrainingStepCount}{K} \newcommand{\TrainingStepEnergy}{E_{\text{step}}} \newcommand{\TrainingStepOperations}{O_{\text{step}}} \newcommand{\TrainingStepTime}{T_{\text{step}}} \newcommand{\TrainingThroughput}{R_{\text{training}}} \newcommand{\TrainingTime}{T_{\text{train}}} \newcommand{\TrainingTransformFunction}{f_{\text{train}}} \newcommand{\Trajectory}{\tau} \newcommand{\TrajectoryAction}{a} \newcommand{\TrajectoryAdmissionRate}{\lambda_{\text{traj}}} \newcommand{\TrajectoryBudget}{\mathbf{B}} \newcommand{\TrajectoryCallCount}{N_{\text{call}}} \newcommand{\TrajectoryCategoryIndex}{j} \newcommand{\TrajectoryCheckpointCount}{N_{\text{ckpt}}} \newcommand{\TrajectoryDivergenceResidual}{e_{\text{div}}} \newcommand{\TrajectoryDuration}{T_{\text{traj}}} \newcommand{\TrajectoryGoodput}{\mathcal{G}} \newcommand{\TrajectoryObservation}{o} \newcommand{\TrajectoryOptimizationObjective}{\mathcal{U}} \newcommand{\TrajectoryRecordDuration}{T_{\text{record}}} \newcommand{\TrajectoryRecordFrame}{\mathcal{F}} \newcommand{\TrajectoryReturn}{R} \newcommand{\TrajectoryReward}{R} \newcommand{\TrajectorySampleCount}{N} \newcommand{\TrajectoryState}{s} \newcommand{\TrajectoryStateSpace}{\mathcal{S}} \newcommand{\TrajectoryTimeLimit}{T_{\max}} \newcommand{\TrajectoryTokenCost}{C_{\text{session}}} \newcommand{\TrajectoryTokenLimit}{N_{\max}} \newcommand{\TrajectoryTurnLimit}{H_{\max}} \newcommand{\TransceiverDelay}{t_{\text{transceiver}}} \newcommand{\TransductionInstant}{t_{\text{transduction}}} \newcommand{\TransferBufferCount}{N_{\text{transfer}}} \newcommand{\TransferDiscrepancyBound}{\epsilon_{\text{gap}}} \newcommand{\TransferTimeForPayload}{T_{\text{transfer}}} \newcommand{\TransferredDataVolume}{D_{\text{vol,transfer}}} \newcommand{\TransformGraph}{\mathcal{G}} \newcommand{\TransformGraphEdgeSet}{\mathcal{E}} \newcommand{\TransformGraphFrame}{\mathcal{F}} \newcommand{\TransformGraphVertexSet}{\mathcal{V}} \newcommand{\TransformRotationBlock}{\mathbf{R}_{AB}} \newcommand{\TransformTranslationBlock}{\mathbf{t}_{AB}} \newcommand{\TransformationInputCount}{k} \newcommand{\TransformedCartesianPosition}{\mathbf{p}'} \newcommand{\TransformedHomogeneousPointCoordinates}{\tilde{\mathbf{p}}'} \newcommand{\TransistorThresholdVoltage}{V_{\text{th}}} \newcommand{\TransitionStorageSize}{b_{\text{tr}}} \newcommand{\TranslationComponent}{v} \newcommand{\TranslationVector}{\mathbf{v}} \newcommand{\TranslationalDriftError}{e_{\text{trans}}} \newcommand{\TranslationalJerk}{j} \newcommand{\TranslationalKineticEnergy}{E_{k,\text{trans}}} \newcommand{\TransmissionEnergyPerByte}{E_{\text{tx}}} \newcommand{\TransmissionInputInertia}{J_{\text{in}}} \newcommand{\TransmissionTorsionalStiffness}{K_{\text{joint}}} \newcommand{\TransverseStandardDeviation}{\sigma_\perp} \newcommand{\TravelPosition}{x} \newcommand{\TraverseDistance}{d} \newcommand{\TreatedNeighborFraction}{e} \newcommand{\TreatmentAssignment}{w} \newcommand{\TreatmentConversionRate}{\hat{p}_B} \newcommand{\TreatmentSampleSize}{m_B} \newcommand{\TreeAllReduceCompletionTime}{T_{\text{tree}}} \newcommand{\TreeLikeAllReduceTime}{T_{\text{tree-like}}} \newcommand{\TreeSearchExplorationWeight}{c_{\text{explore}}} \newcommand{\TreeSearchLeafScore}{V} \newcommand{\TreeSearchMeanReturn}{Q} \newcommand{\TreeSearchPriorDistribution}{p_{\text{prior}}} \newcommand{\TreeSearchVisitCount}{N_{\text{visit}}} \newcommand{\TrialCampaignWallTime}{T_{\text{wall}}} \newcommand{\TrialCompletionIndicator}{Y} \newcommand{\TrialCondition}{c} \newcommand{\TrialControlStepCount}{N_{\text{steps}, i}} \newcommand{\TrialCount}{N} \newcommand{\TrialFailureIndicator}{x} \newcommand{\TrialFailureProbability}{p_{\text{fail}}} \newcommand{\TrialIndex}{n} \newcommand{\TrialInterventionCount}{n_{\text{int}}} \newcommand{\TrialLoadReversalCount}{n_{\text{rev}}} \newcommand{\TrialPassProbability}{p_{\text{trial}}} \newcommand{\TrialPathDistance}{d} \newcommand{\TrialResetLatency}{T_{\text{reset}}} \newcommand{\TrialResetTime}{t_{\text{reset}}} \newcommand{\TrialRolloutTime}{t_{\text{rollout}}} \newcommand{\TrialRunTime}{t_{\text{run}}} \newcommand{\TrialSuccessProbability}{p} \newcommand{\TriggeredWindowArrivalCount}{Q_{\text{arr}}} \newcommand{\TrueClearance}{C_{\text{true}}} \newcommand{\TrueLabelComponent}{y} \newcommand{\TrueOutcome}{Y} \newcommand{\TrueOutcomeLevel}{v} \newcommand{\TrueReferentScore}{c_{y_j}} \newcommand{\TruncatedDistanceSample}{d_{\mu}} \newcommand{\TruncatedKeyApproximation}{\hat{\mathbf{K}}_r} \newcommand{\TruncatedKeyLeftSingularMatrix}{\mathbf{U}_r} \newcommand{\TruncatedKeyRightSingularMatrix}{\mathbf{V}_r} \newcommand{\TruncatedKeySpectrumMatrix}{\mathbf{\Sigma}_r} \newcommand{\TruncationBandVolume}{V_{\text{band}}} \newcommand{\TruncationRank}{r} \newcommand{\TruthInstrumentSet}{\mathcal{I}_{\text{truth}}} \newcommand{\TsdfAccumulatedDistance}{D} \newcommand{\TsdfAccumulatedWeight}{W} \newcommand{\TsdfObservationWeight}{w} \newcommand{\TsdfTruncationBand}{\mu_{\text{tsdf}}} \newcommand{\TsdfWeightCap}{W_{\max}} \newcommand{\TuckerCoreTensor}{\mathcal{G}} \newcommand{\TurnAppendLength}{\Delta S_{\text{turn}}} \newcommand{\TurnBoundaryDelay}{t_{\text{boundary}}} \newcommand{\TurnBudgetUsedFraction}{\rho_H} \newcommand{\TurnContext}{c} \newcommand{\TurnContributionDeviationBound}{\sigma} \newcommand{\TurnCovarianceBoundScale}{C} \newcommand{\TurnCovarianceDecayRatio}{\alpha_{\text{corr}}} \newcommand{\TurnFailureRate}{\lambda_{\text{fail}}} \newcommand{\TurnGeneratedTokenCount}{n_{\text{gen}}} \newcommand{\TurnHorizon}{H} \newcommand{\TurnIndex}{t} \newcommand{\TurnInputTokenCost}{C_{\text{in}}} \newcommand{\TurnOffGateCurrent}{I_{g,\text{off}}} \newcommand{\TurnOffGateResistance}{R_{g,\text{off}}} \newcommand{\TurnOnGateResistance}{R_{g,\text{on}}} \newcommand{\TurnOutputTokenCost}{C_{\text{out}}} \newcommand{\TurnPayloadProbability}{q_{\text{turn}}} \newcommand{\TurnReadCount}{r} \newcommand{\TurnReconstructionTime}{T_{\text{recon}}} \newcommand{\TurnReexecutionTime}{T_{\text{exec}}} \newcommand{\TurnReward}{r} \newcommand{\TurnSandboxCost}{C_{\text{sandbox}}} \newcommand{\TurnStateGrowth}{s_{\text{turn}}} \newcommand{\TurnToolFeeCost}{C_{\text{tools}}} \newcommand{\TustinEigenvalue}{\lambda_{\text{Tustin}}} \newcommand{\TustinTransitionMatrix}{\mathbf{A}_{\text{Tustin}}} \newcommand{\TwinCriticReturnEstimate}{Q_{\phi_i}} \newcommand{\TwistCoordinates}{\boldsymbol{\xi}} \newcommand{\TwistCovarianceMatrix}{\boldsymbol{\Sigma}_{\boldsymbol{\xi}}} \newcommand{\TwistMatrix}{\hat{\boldsymbol{\xi}}} \newcommand{\TwistRotationAngle}{\theta_{\text{rot}}} \newcommand{\TwistRotationCoordinates}{\boldsymbol{\omega}} \newcommand{\TwistTranslationMatrix}{\mathbf{V}} \newcommand{\TwistWedgeOperator}{\wedge} \newcommand{\UnacceptedTaskMeanCost}{C_{\text{fail}}} \newcommand{\UnassistedCompletionCount}{N_{\text{unassisted}}} \newcommand{\UnassistedSuccessIndicator}{A} \newcommand{\UnbiasedAngularBrakingDeceleration}{\alpha_{\text{nom}}} \newcommand{\UnbrakedImpactForce}{F_{\text{unbraked}}} \newcommand{\UncachedInputTokenCount}{n_{\text{in}}} \newcommand{\UncachedPromptLength}{S_{\text{new}}} \newcommand{\UncertainScenarioParameters}{x} \newcommand{\UnconstrainedCallLatency}{T_{\text{free}}} \newcommand{\UnconstrainedParseFailureRate}{p_{\text{err}}} \newcommand{\UndampedNaturalFrequency}{\omega_n} \newcommand{\UnfoldedConvolutionOutput}{\mathbf{Y}_{\text{col}}} \newcommand{\UnfoldedPatchMatrix}{\mathbf{X}_{\text{col}}} \newcommand{\UniformDistribution}{\mathcal{U}} \newcommand{\UniformLoopTurnCost}{C_{\text{turn}}} \newcommand{\UnitAliasMultiplier}{k} \newcommand{\UnitImpulseFunction}{\delta} \newcommand{\UnitQuaternion}{\mathbf{q}_{\text{quat}}} \newcommand{\UnitQuaternionScalarComponent}{q_w} \newcommand{\UnitQuaternionSphere}{S^3} \newcommand{\UnitQuaternionXComponent}{q_x} \newcommand{\UnitQuaternionYComponent}{q_y} \newcommand{\UnitQuaternionZComponent}{q_z} \newcommand{\UnitTemperatureProbabilityVector}{\mathbf{p}_{\tau_{\text{temp}}=1}} \newcommand{\UnlabeledPool}{U} \newcommand{\UnloadedTickExecutionTime}{t_{\text{unloaded}}} \newcommand{\UnmitigatedHardwareFaultRate}{\lambda_{\text{unmitigated}}} \newcommand{\UnmodeledCommandPathDelay}{\Delta t_{\text{bus}}} \newcommand{\UnobservableForceOffset}{\Delta} \newcommand{\UnobservedUnknownSpace}{\mathcal{M}_{\text{unknown}}} \newcommand{\UnprojectionJacobian}{\mathbf{J}_{\text{unproj}}} \newcommand{\UnrecoverableDamageCost}{C_{\text{blast}}} \newcommand{\UnreservedStopDelay}{\delta} \newcommand{\UnscaledAttentionScoreMatrix}{\mathbf{A}} \newcommand{\UnshardedLocalExecutionTime}{T_{\text{compute}}} \newcommand{\UnsquashedLatentAction}{\mathbf{u}} \newcommand{\UntilPrefixTime}{t''} \newcommand{\UntrackedEvidenceHorizon}{\tau_{\text{ev,untracked}}} \newcommand{\UpdatedErrorCovariance}{\mathbf{P}_{k|k}} \newcommand{\UpdatedModelParameters}{\theta_{\text{new}}} \newcommand{\UpdatedParameterSubset}{\theta_{\text{updated}}} \newcommand{\UpdatedSoftmaxRunningMaximum}{m'} \newcommand{\UpdatedStateEstimate}{\hat{\mathbf{x}}_{k|k}} \newcommand{\UpperRatioClippingWidth}{\epsilon_{\text{high}}} \newcommand{\UprightPosition}{\mathbf{p}_{\text{upright}}} \newcommand{\UprightRange}{r} \newcommand{\UpstreamGradientElement}{\bar{y}} \newcommand{\UpstreamGradientVector}{\mathbf{v}} \newcommand{\UpstreamStageLatency}{X} \newcommand{\UsableDemonstrationYield}{Y_{\text{usable}}} \newcommand{\UsefulAcceleratorHourCost}{C_{\text{useful}}} \newcommand{\UsefulComputeFraction}{f_{\text{compute}}} \newcommand{\UsefulModelFlops}{O_{\text{useful}}} \newcommand{\UsefulStepCount}{N} \newcommand{\UsefulTrainingTime}{T_{\text{useful}}} \newcommand{\UserConnectionSet}{\mathcal{N}} \newcommand{\UserSpaceSetupTime}{T_{\text{user}}} \newcommand{\UvloThresholdVoltage}{V_{\text{UVLO}}} \newcommand{\VacuumLightSpeed}{c} \newcommand{\ValidCandidateRate}{p_{\text{valid}}} \newcommand{\ValidTokenSet}{\mathcal{V}_{\text{valid}}} \newcommand{\ValidatedMotionDuration}{T_{\text{yield}}} \newcommand{\ValidatedProposalEvent}{e_{\text{prop}}} \newcommand{\ValidationDataset}{\mathcal{D}_{\text{val}}} \newcommand{\ValidationGateThreshold}{\gamma_{\text{gate}}} \newcommand{\ValidationLoss}{\mathcal{L}_{\text{val}}} \newcommand{\VanishingTimeOffset}{\epsilon} \newcommand{\VariationalDistribution}{q_\phi} \newcommand{\VariationalParameters}{\phi} \newcommand{\VectorAngle}{\phi} \newcommand{\VectorElementCount}{N_{\text{vec}}} \newcommand{\Velocity}{\mathbf{v}} \newcommand{\VelocitySaturationExponent}{\alpha} \newcommand{\VerificationCheckCost}{C_{\text{ver}}} \newcommand{\VerificationCheckCount}{K} \newcommand{\VerificationPoolCapacity}{\mu_{\text{verify}}} \newcommand{\VerificationScheduleCost}{C} \newcommand{\VerificationTrialCount}{n_{\text{trial}}} \newcommand{\VerificationTrialIndex}{j} \newcommand{\VerificationTrialTime}{T_{\text{trial}}} \newcommand{\VerifiedDemonstrationDataset}{\mathcal{D}_{\text{verified}}} \newcommand{\VerifierFalseAcceptanceRate}{\epsilon_{\text{FA}}} \newcommand{\VerifierFalseRejectionRate}{\epsilon_{\text{FR}}} \newcommand{\VerifierPassProbability}{q} \newcommand{\VerifierPrecision}{\Pi_{V}} \newcommand{\VerifierTimeout}{T_{\text{out}}} \newcommand{\VerifierTrueAcceptanceRate}{u} \newcommand{\VerifierVerdict}{V} \newcommand{\VersionSkewBound}{k_{\text{skew}}} \newcommand{\VertexSlotTime}{d} \newcommand{\VerticalFocalLength}{f_y} \newcommand{\VibrationFrequency}{f_{\text{vib}}} \newcommand{\VirtualAccelerationCommand}{\ddot{\mathbf{q}}^*} \newcommand{\VirtualDampingMatrix}{\mathbf{D}_{\text{virt}}} \newcommand{\VirtualPipelineStagesPerDevice}{V} \newcommand{\ViscousDampingMatrix}{\mathbf{D}} \newcommand{\VisionBackboneTime}{t_{\text{backbone}}} \newcommand{\VisionTokenEmbeddings}{\mathbf{z}_{\text{vision}}} \newcommand{\VisualConditioningEmbedding}{\mathbf{E}} \newcommand{\VisualEncodingTime}{t_{\text{vis}}} \newcommand{\VitImagePatch}{\mathbf{x}_p} \newcommand{\VitPatchProjectionWeights}{\mathbf{W}_{\text{patch}}} \newcommand{\VitPatchSize}{p_{\text{patch}}} \newcommand{\VitPatchTokenEmbedding}{\mathbf{z}} \newcommand{\VocabularyToken}{v} \newcommand{\VocabularyTokenLogit}{o} \newcommand{\VolumetricFlowRate}{\dot{V}} \newcommand{\VoxelBlockCoordinate}{\mathbf{b}} \newcommand{\VoxelBlockEdgeLength}{L_{\text{blk}}} \newcommand{\VoxelCenterPosition}{\mathbf{p}_{\text{vox}}} \newcommand{\VoxelIndex}{i} \newcommand{\VoxelOccupancyState}{m} \newcommand{\VoxelPitch}{r} \newcommand{\VoxelStorageSize}{s_{\text{voxel}}} \newcommand{\VoxelUpdateTraffic}{s_{\text{rw}}} \newcommand{\WarmupEpochCount}{N_{\text{warmup}}} \newcommand{\WarmupStepCount}{W} \newcommand{\WatchdogClockFrequency}{f_{\text{wdg}}} \newcommand{\WatchdogCounterReading}{W} \newcommand{\WatchdogEarliestServiceTime}{T_{\text{lower}}} \newcommand{\WatchdogLatestServiceTime}{T_{\text{upper}}} \newcommand{\WatchdogLowerWindowCount}{W_{\text{lower}}} \newcommand{\WatchdogReloadCount}{W_{\text{init}}} \newcommand{\WatchdogServiceTime}{t_{\text{service}}} \newcommand{\WatchdogToken}{T} \newcommand{\WatchdogUpperWindowCount}{W_{\text{upper}}} \newcommand{\WaveImpedance}{b} \newcommand{\WeightElementStorageSize}{s_{\text{elem,W}}} \newcommand{\WeightMatrix}{\mathbf{W}} \newcommand{\WeightMatrixColumnCount}{n} \newcommand{\WeightMatrixEntry}{W_{ij}} \newcommand{\WeightMatrixRowCount}{m} \newcommand{\WeightMemory}{M_{\text{weights}}} \newcommand{\WeightOnlyStepTime}{t} \newcommand{\WeightPenaltyStrength}{\lambda_{\text{reg}}} \newcommand{\WeightQuantizationScale}{s_W} \newcommand{\WeightRangeBound}{W_{\text{max}}} \newcommand{\WeightStreamingDecodeTime}{T_{\text{decode}}} \newcommand{\WeightVector}{\mathbf{w}} \newcommand{\WeightedNormArgument}{\mathbf{z}} \newcommand{\WheelAngularSpeed}{\omega} \newcommand{\WheelDiameter}{D_{\text{wheel}}} \newcommand{\WheelInertia}{J_{\text{wheel}}} \newcommand{\WheelNormalLoad}{F_z} \newcommand{\WheelRadius}{r} \newcommand{\WheelRevolutionCount}{N_{\text{rev}}} \newcommand{\WheelTrackWidth}{b} \newcommand{\WhiteNoiseProcess}{\mathcal{WN}} \newcommand{\WholeBodyDecisionVariables}{\mathbf{z}} \newcommand{\WholeRepositoryShardGrant}{\Gamma_{b}} \newcommand{\WidthMultiplier}{w_{\text{mult}}} \newcommand{\WidthScalingRatio}{\beta} \newcommand{\WilsonIntervalCenter}{\tilde{p}} \newcommand{\WindingCoreThermalResistance}{R_{\text{th,wc}}} \newcommand{\WindingCurrent}{I} \newcommand{\WindingJouleHeat}{E_{\text{thermal}}} \newcommand{\WindingLossPower}{P_{\text{loss}}} \newcommand{\WindingTemperature}{T_{\text{winding}}} \newcommand{\WindingTemperatureLimit}{T_{\text{limit}}} \newcommand{\WindingTerminalVoltage}{V_{\text{terminal}}} \newcommand{\WindingThermalCapacitance}{C_{\text{wind}}} \newcommand{\WindowArrivalCount}{k} \newcommand{\WindowArrivalOffset}{t} \newcommand{\WindowSpendingLimit}{C_{\text{win}}} \newcommand{\WithinTaskRunStandardDeviation}{\sigma_{\text{run}}} \newcommand{\WorkedTraceProduct}{c} \newcommand{\WorkedTraceProductAdjoint}{\bar{c}} \newcommand{\WorkedTraceSine}{b} \newcommand{\WorkedTraceSineAdjoint}{\bar{b}} \newcommand{\WorkedTraceSquare}{a} \newcommand{\WorkedTraceSquareAdjoint}{\bar{a}} \newcommand{\WorkerBaseCommitHash}{h_{\text{base}}} \newcommand{\WorkerCandidateCommitHash}{h_{\text{worker}}} \newcommand{\WorkerCompletionDistribution}{F} \newcommand{\WorkerCompletionTime}{T} \newcommand{\WorkerCount}{N_{\text{workers}}} \newcommand{\WorkerDelayProbability}{p} \newcommand{\WorkerIndex}{k} \newcommand{\WorkerMinibatch}{B} \newcommand{\WorkerOverheadSlope}{\gamma} \newcommand{\WorkerTransformTime}{T_{\text{transform}}} \newcommand{\WorkerWrittenFileCount}{w} \newcommand{\WorkloadMeanOutputLength}{\mu} \newcommand{\WorkloadRequestIndex}{i} \newcommand{\WorkspaceExtentX}{L_x} \newcommand{\WorkspaceExtentY}{L_y} \newcommand{\WorkspaceExtentZ}{L_z} \newcommand{\WorkspaceRestoreTime}{T_{\text{ws}}} \newcommand{\WorkspaceVolume}{V_{\text{ws}}} \newcommand{\WorldBaseTransform}{\mathbf{T}_{WB}} \newcommand{\WorldBodyTransform}{\mathbf{T}_{wb}} \newcommand{\WorldFramePoint}{\mathbf{p}_{\text{world}}} \newcommand{\WorldLidarTransform}{\mathbf{T}_{wl}} \newcommand{\WorldMapTransform}{\mathbf{T}_{\text{world}}^{\text{map}}} \newcommand{\WorldPointCovariance}{\boldsymbol{\Sigma}_{\text{world}}} \newcommand{\WorldReferenceFrame}{\mathcal{F}_W} \newcommand{\WorldStateSpace}{\mathcal{S}} \newcommand{\WorldToCameraRotation}{\mathbf{R}_{CW}} \newcommand{\WorldToCameraTransform}{\mathbf{T}_{CW}} \newcommand{\WorldToCameraTranslation}{\mathbf{t}_{CW}} \newcommand{\WornPlantTransitionDistribution}{p_{n \gg 1}} \newcommand{\WorseArmSuccessProbability}{p_{\text{low}}} \newcommand{\WorstCaseExecutionTime}{C} \newcommand{\WorstCaseInterruptLatency}{t_{\text{irq,lat}}} \newcommand{\WorstCasePermissionCycleTime}{T_{\text{exec}}} \newcommand{\WorstCaseResponseTime}{R} \newcommand{\WristAngularVelocity}{\boldsymbol{\omega}_{\text{wrist}}} \newcommand{\WristCameraEmbedding}{\mathbf{e}_{\text{wrist}}} \newcommand{\WristLinearVelocity}{\mathbf{v}_{\text{wrist}}} \newcommand{\WristObjectTransform}{\mathbf{T}_{\text{wrist} \leftarrow \text{object}}} \newcommand{\WristSkewDisplacement}{\Delta \mathbf{p}_{\text{skew}}} \newcommand{\XAxisAngularRate}{\omega_x} \newcommand{\XAxisRotationCoordinate}{\omega_x} \newcommand{\XForceCeiling}{F_x} \newcommand{\XPositionErrorEnvelope}{e_x} \newcommand{\XTaskToleranceSemiAxis}{r_x} \newcommand{\XTorqueCeiling}{\tau_x} \newcommand{\YAxisAngularRate}{\omega_y} \newcommand{\YAxisRotationCoordinate}{\omega_y} \newcommand{\YForceCeiling}{F_y} \newcommand{\YPositionErrorEnvelope}{e_y} \newcommand{\YTaskToleranceSemiAxis}{r_y} \newcommand{\YTorqueCeiling}{\tau_y} \newcommand{\YawRate}{\omega_z} \newcommand{\YoshikawaManipulability}{w} \newcommand{\ZAxisRotationCoordinate}{\omega_z} \newcommand{\ZForceCeiling}{F_z} \newcommand{\ZPositionErrorEnvelope}{e_z} \newcommand{\ZTaskToleranceSemiAxis}{r_z} \newcommand{\ZTorqueCeiling}{\tau_z} \newcommand{\ZTransformVariable}{z} \newcommand{\ZeroEntryIndicator}{\mathbf{1}_{\{(\mathbf{W}_{\text{sparse}})_{ij} = 0\}}} \newcommand{\ZeroFailureTrialCount}{n} \newcommand{\ZeroFailureUpperConfidenceLimit}{p_{\text{fail, upper}}^{95\%}} \newcommand{\ZeroMatrix}{\mathbf{0}} \newcommand{\ZeroMomentPoint}{\mathbf{p}_{\text{ZMP}}} \newcommand{\ZeroVector}{\mathbf{0}} \newcommand{\ZohHoldTravel}{d_{\text{ZOH}}} \newcommand{\ZohPhaseShift}{\phi_{\text{ZOH}}} \newcommand{\ZohTransportDelay}{\tau_{\text{ZOH}}} \newcommand{\AuthorityLevels}{\AuthorityExposureLevel} \newcommand{\BreakEvenTaskVolume}{\BreakEvenTaskCount} \newcommand{\PertokenPricesCache}{\CachedInputTokenPrice} \newcommand{\ContentionAndCoherencyCoefficientsTwo}{\CoherencyCoefficient} \newcommand{\CoherencyContentionCoefficient}{\CoherencyCoefficient} \newcommand{\TaskDeadline}{\CompletionDeadline} \newcommand{\Deadline}{\CompletionDeadline} \newcommand{\Confidentiality}{\ConfidentialityLabel} \newcommand{\ContentionAndCoherencyCoefficients}{\ContentionCoefficient} \newcommand{\CostPerAcceptedTaskEff}{\CostPerAcceptedTask} \newcommand{\DuplicateeffectProbability}{\DuplicateEffectProbability} \newcommand{\EstimatedAdvantageK}{\EstimatedHistoryAdvantage} \newcommand{\EstimatedValueK}{\EstimatedRemainingReturn} \newcommand{\ExpectedIrreversibleLossA}{\ExpectedIrreversibleLoss} \newcommand{\PertokenPricesIn}{\InputTokenPrice} \newcommand{\CohensKappa}{\InterAnnotatorAgreement} \newcommand{\KvBlockSizeBlk}{\KvBlockSize} \newcommand{\MaskedFinetuningLossSft}{\MaskedFinetuningLoss} \newcommand{\ValidityIntervalOfAMemoryEntryBirth}{\MemoryEntryBirthGeneration} \newcommand{\ValidityIntervalOfAMemoryEntryDeath}{\MemoryEntryDeathGeneration} \newcommand{\MemoryHeldDuringAWait}{\MemoryHoldDuringWait} \newcommand{\OptimalCheckpointIntervalCkpt}{\OptimalCheckpointInterval} \newcommand{\PertokenPricesOut}{\OutputTokenPrice} \newcommand{\PertokenDecodeTime}{\PerTokenDecodeTime} \newcommand{\TokenLossMask}{\PositionLossMask} \newcommand{\LossMaskT}{\PositionLossMask} \newcommand{\ValidityIntervalOfAMemoryEntryQ}{\QueryWorkspaceGeneration} \newcommand{\RequestAndReplylossProbabilitiesTwo}{\ReplyLossProbability} \newcommand{\RequestAndReplylossProbabilities}{\RequestLossProbability} \newcommand{\EnvironmentStateK}{\RolloutEnvironmentState} \newcommand{\StalesupportRate}{\StaleSupportRate} \newcommand{\StateLevels}{\StateExposureLevel} \newcommand{\GoalContract}{\TaskContractGoal} \newcommand{\Environment}{\TaskEnvironment} \newcommand{\Vocabulary}{\TokenVocabulary} \newcommand{\ActionProposal}{\TrajectoryAction} \newcommand{\ConcurrentTrajectoriesTwo}{\TrajectoryAdmissionRate} \newcommand{\ActionObservation}{\TrajectoryObservation} \newcommand{\Observation}{\TrajectoryObservation} \newcommand{\StateAtTurn}{\TrajectoryState} \newcommand{\PerturnAppend}{\TurnAppendLength} \newcommand{\Context}{\TurnContext} \newcommand{\Horizon}{\TurnHorizon} \newcommand{\VerifierFalseacceptance}{\VerifierFalseAcceptanceRate} \newcommand{\VerifierFalseacceptanceFr}{\VerifierFalseRejectionRate} \newcommand{\WorkerCountWorkers}{\WorkerCount} \newcommand{\AllocationHoldTime}{\AllocatedWallTime} \newcommand{\CheckpointIntervalCkpt}{\CheckpointInterval} \newcommand{\AcceleratorsPerNodeNodes}{\ClusterNodeCount} \newcommand{\CommunicationcomputationRatio}{\CommunicationComputeRatio} \newcommand{\PercomponentFailureRate}{\ComponentFailureRate} \newcommand{\Correlation}{\CorrelationCoefficient} \newcommand{\DataparallelDegreeDp}{\DataParallelDegree} \newcommand{\NumberOfDevices}{\DeviceCount} \newcommand{\TypeIAndTypeIiErrorRatesStat}{\HypothesisTestFalseNegativeRate} \newcommand{\TypeIAndTypeIiErrorRatesSig}{\HypothesisTestSignificanceLevel} \newcommand{\DollarCostInfer}{\InferenceCost} \newcommand{\KvcacheBytesPerToken}{\KvCacheBytesPerToken} \newcommand{\KvcacheMemory}{\KvCacheMemory} \newcommand{\CrossoverPoint}{\LatencyBandwidthCrossoverSize} \newcommand{\LoggpLongmessageTime}{\LoggpLongMessageTime} \newcommand{\LogploggpNetworkLatency}{\LogpNetworkLatency} \newcommand{\LongmessageGapPerByte}{\LongMessageGapPerByte} \newcommand{\MeanTimeBetweenFailuresThree}{\MeanTimeBetweenFailures} \newcommand{\PermessageLatency}{\MessageStartupLatency} \newcommand{\NdeviceTime}{\MultiDeviceRunTime} \newcommand{\PipelineparallelDegreePp}{\PipelineParallelDegree} \newcommand{\MlProductivityGoodputFactorsProgram}{\ProgramGoodput} \newcommand{\ReceiverOverheadRecv}{\ReceiverOverhead} \newcommand{\CollectiveCompletionTimeRing}{\RingAllReduceCompletionTime} \newcommand{\RingtreeCrossoverPayload}{\RingTreeCrossoverPayload} \newcommand{\MlProductivityGoodputFactorsRuntime}{\RuntimeGoodput} \newcommand{\GoodputRatio}{\RuntimeGoodput} \newcommand{\ScalingExponentScale}{\ScalingExponent} \newcommand{\MlProductivityGoodputFactorsScheduling}{\SchedulingGoodput} \newcommand{\SingledeviceTimeOne}{\SingleDeviceRunTime} \newcommand{\ReliabilityFunctionSystem}{\SystemReliability} \newcommand{\TensorparallelDegreeTp}{\TensorParallelDegree} \newcommand{\SmallConstant}{\ToleratedFailureProbability} \newcommand{\DollarCostTrain}{\TrainingCost} \newcommand{\CollectiveCompletionTimeTree}{\TreeAllReduceCompletionTime} \newcommand{\UsefulComputetimeFraction}{\UsefulComputeFraction} \newcommand{\AccuracyAtTime}{\AccuracyAfterDeployment} \newcommand{\NumberOfAttentionHeads}{\AttentionHeadCount} \newcommand{\Distribution}{\InputDistribution} \newcommand{\NumberOfKeyValueHeads}{\KvHeadCount} \newcommand{\NumberOfKeyvalueHeadsKv}{\KvHeadCount} \newcommand{\NumberOfLayers}{\LayerCount} \newcommand{\LayerInputAndOutputWidths}{\LayerInputWidth} \newcommand{\LayerInputAndOutputWidthsTwo}{\LayerOutputWidth} \newcommand{\Gradient}{\LossGradient} \newcommand{\TrainingDistributionZero}{\TrainingDistribution} \newcommand{\AcceleratorCountGpu}{\AcceleratorCount} \newcommand{\ActivationMemoryActivations}{\ActivationMemory} \newcommand{\BatchServiceTimeSvc}{\BatchServiceTime} \newcommand{\EnergyPerOperationCompute}{\EnergyPerOperation} \newcommand{\GradientMemoryGradients}{\GradientMemory} \newcommand{\IronlawTermTimesCompute}{\IronLawComputeTime} \newcommand{\SingleDeviceComputeTime}{\IronLawComputeTime} \newcommand{\IronlawTermTimesMemory}{\IronLawMemoryTime} \newcommand{\LossscaleFactor}{\LossScaleFactor} \newcommand{\OptimizerstateMemory}{\OptimizerStateMemory} \newcommand{\RequestTimeInSystemLat}{\RequestTimeInSystem} \newcommand{\StoragePricePerByteTime}{\StorageCapacityPrice} \newcommand{\WeightMemoryWeights}{\WeightMemory} \newcommand{\WindingAndAmbientTemperatureTwo}{\AmbientTemperature} \newcommand{\BackemfVoltageBemf}{\BackEmfVoltage} \newcommand{\CoordinateReferenceFramesB}{\BodyReferenceFrame} \newcommand{\CameraframeThreedCoordinate}{\CameraFramePoint} \newcommand{\CartesianThreedPosition}{\CartesianPosition} \newcommand{\CommandTransportTimeBus}{\CommandTransportTime} \newcommand{\ContactForceVectorK}{\ContactPointForce} \newcommand{\ContactPointJacobianK}{\ContactPointJacobian} \newcommand{\ContinuousPeakCurrent}{\ContinuousCurrent} \newcommand{\CredibleDecelerationBrake}{\CredibleBrakingDeceleration} \newcommand{\OpenloopCrossoverFrequency}{\CrossoverFrequency} \newcommand{\PhaseLagDegradation}{\DelayPhaseLag} \newcommand{\DiffusionScheduleParameterK}{\DiffusionCumulativeSchedule} \newcommand{\DispatchtoadmissionIntervalDa}{\DispatchAdmissionInterval} \newcommand{\EmittedTokenCountOut}{\EmittedTokenCount} \newcommand{\FundamentalAndEssentialMatricesTwo}{\EssentialMatrix} \newcommand{\ForwardinvariantSafeSet}{\ForwardInvariantSafeSet} \newcommand{\FreespaceDepth}{\FreeSpaceDepth} \newcommand{\FundamentalAndEssentialMatrices}{\FundamentalMatrix} \newcommand{\TransmissionEfficiencyGear}{\GearboxTransmissionEfficiency} \newcommand{\HardwareAndCommoncauseRateOther}{\HardwareCommonCauseRate} \newcommand{\ContinuousPeakTorqueHold}{\HoldingTorque} \newcommand{\OptimalInertiamatchingRatio}{\InertiaMatchingRatio} \newcommand{\IntentleaseExpiryIntentexp}{\IntentLeaseExpiry} \newcommand{\LatentStyleStateEmbedding}{\LatentStyleVariable} \newcommand{\LinearBarrierDecayRateCbf}{\LinearBarrierDecayRate} \newcommand{\Momentum}{\LinearMomentum} \newcommand{\RotorAndLoadInertiaTwo}{\LoadInertia} \newcommand{\LqrGainAndWeights}{\LqrFeedbackGain} \newcommand{\CenterOfMass}{\MassCenterPosition} \newcommand{\TorqueAndBackemfConstants}{\MotorTorqueConstant} \newcommand{\NoisePredictionNetworkTwo}{\NoisedActionChunk} \newcommand{\ObservabilityMatricesNl}{\NonlinearObservationSpace} \newcommand{\ObservabilityMatrices}{\ObservabilityMatrix} \newcommand{\ContinuousPeakCurrentTwo}{\PeakCurrent} \newcommand{\ContinuousPeakTorque}{\PeakTorque} \newcommand{\PermissionloopPeriodTick}{\PermissionLoopPeriod} \newcommand{\PhaseInductanceAndResistance}{\PhaseInductance} \newcommand{\PhaseInductanceAndResistanceTwo}{\PhaseResistance} \newcommand{\InitialAndCeilingError}{\PositionErrorCeiling} \newcommand{\RenewaljitterAllowance}{\RenewalJitterAllowance} \newcommand{\ResidentStopDistanceSuffix}{\ResidentStopDistance} \newcommand{\CoefficientOfRestitution}{\RestitutionCoefficient} \newcommand{\RigidtransformTranslation}{\RigidTransformTranslation} \newcommand{\RotorAndLoadInertia}{\RotorInertia} \newcommand{\SamplingPeriodAndRate}{\SamplingPeriod} \newcommand{\SensorLeverarmVector}{\SensorLeverArm} \newcommand{\SequentialLoglikelihoodRatioM}{\SequentialLogLikelihoodRatio} \newcommand{\SinglestepImitationError}{\SingleStepImitationError} \newcommand{\SprtBoundariesLo}{\SprtLowerBoundary} \newcommand{\SprtBoundariesUp}{\SprtUpperBoundary} \newcommand{\LinearStatespaceMatrices}{\StateSpaceInputMatrix} \newcommand{\LinearStatespaceMatricesSys}{\StateSpaceSystemMatrix} \newcommand{\PertrialProbabilitiesTarget}{\TargetTrialSuccessProbability} \newcommand{\TorqueproducingCurrent}{\TorqueProducingCurrent} \newcommand{\TrackingerrorBound}{\TrackingErrorBound} \newcommand{\PertrialProbabilitiesFail}{\TrialFailureProbability} \newcommand{\TsdfAccumulatedVolumeVox}{\TsdfAccumulatedWeight} \newcommand{\VirtualDampingAndStiffness}{\VirtualDampingMatrix} \newcommand{\Radius}{\WheelRadius} \newcommand{\WindingAndAmbientTemperature}{\WindingTemperature} \newcommand{\CoordinateReferenceFramesW}{\WorldReferenceFrame} \newcommand{\ZerofailureTrialCount}{\ZeroFailureTrialCount} \newcommand{\ZeroMomentPointZmp}{\ZeroMomentPoint} \newcommand{\Glyph}[1]{#1} $$

3 ML Lifecycle

Isometric blueprint of an ML workflow loop connecting definition, data, training, deployment, monitoring, and feedback around a central model workbench.

Purpose

Machine Learning Systems Architecture Stack

Architecture stack focus for this chapter.

Why is seeing the whole map necessary before walking any single path?

Engineering organizations often split an ML system into three specialties, with one team curating datasets, another tuning model architectures, and a third provisioning serving hardware. The components those teams own remain coupled. The volume and quality of collected data bound which algorithms are viable, the computational structure of the chosen algorithm dictates what hardware can execute it efficiently, and the memory and bandwidth of the target hardware reshape what preprocessing can run at inference. Optimizing each in isolation tends to produce accurate models that cannot be deployed and efficient data pipelines that serve the wrong distributions, and the cost of such a mismatch compounds with how late it surfaces. A memory limit discovered during initial design changes one line of a hardware specification; the same limit discovered on the eve of deployment discards months of training runs, annotation budgets, and integration work. Before analyzing any single component, an engineer needs the full map of how an ML system is specified, trained, validated, deployed, and sustained as one operational loop. In D·A·M terms, the ML lifecycle is where data, algorithm, and machine are co-designed over time, each stage passing constraints to the others until their combined capability meets real-world requirements.

Learning Objectives
  • Explain the six ML lifecycle stages as coordinated data-algorithm-machine decisions with feedback
  • Compare ML workflows with traditional software using drift, nondeterminism, and operational feedback
  • Construct a problem definition that states a request as a measurable improvement over an existing baseline
  • Analyze how problem-definition constraints propagate through data, modeling, validation, and deployment
  • Estimate rework from a late-discovered constraint by tracing dependent data, model, validation, and deployment artifacts
  • Evaluate accuracy, efficiency, reproducibility, and deployment readiness trade-offs across lifecycle stages
  • Design feedback loops that connect monitoring signals to retraining, maintenance, and revised requirements

3.1 The Lifecycle as a Loop

Building an ML system takes far more than training a model. A team must decide what the system has to do and within which limits, gather and prepare the data it learns from, train and test the model, install it where it will run, and keep checking that it still works as the world around it changes. System Paradigms examined one of those limits in depth, showing that the deployment target can change the engineering of the same model by orders of magnitude between a phone and a data center. The rest of this book takes the remaining work apart piece by piece along the data, algorithm, and machine axes, from data pipelines and model architectures through training, optimization, and serving. Those pieces are not independent. Each hands its results to the next, and a mistake made in one tends to surface in another, so understanding any single piece first requires understanding how they connect: the sequence of stages every ML system moves through, what each stage hands to the next, and how a constraint discovered in one place reaches the others.

That sequence is the machine learning lifecycle, a structured, iterative process1 that guides the development, evaluation, and improvement of ML systems (Amershi et al. 2019). Numbered in the order a project first meets them, its six stages form a chain in which each stage produces the artifact the next one needs: problem definition (1) turns a request into measurable targets and deployment constraints, which guide data collection and preparation (2) as it turns raw observations into a versioned, validated dataset. Model development and training (3) then fits trained weights to that dataset, and evaluation and validation (4) tests those weights against the original targets and records the release evidence in a release manifest. Once the manifest clears the gate, deployment and integration (5) installs the approved model where it must run, while monitoring and maintenance (6) watches the live system and sends what it learns back to earlier stages, closing the loop drawn in figure 1.

1 CRISP-DM (cross-industry standard process for data mining): CRISP-DM codified data-intensive system development as six interconnected, iterative phases rather than a linear waterfall (Chapman et al. 2000); its core design principle (moving back and forth between phases as results require) directly informs the modern ML lifecycle’s structure.
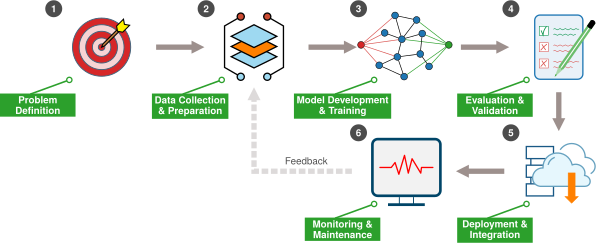
Chapman, Pete, Julian Clinton, Randy Kerber, Thomas Khabaza, Thomas Reinartz, Colin Shearer, and Rudiger Wirth. 2000. “CRISP-DM 1.0: Step-by-Step Data Mining Guide.” SPSS Inc 1: 78.
Amershi, Saleema, Andrew Begel, Christian Bird, Robert DeLine, Harald Gall, Ece Kamar, Nachiappan Nagappan, Besmira Nushi, and Thomas Zimmermann. 2019. “Software Engineering for Machine Learning: A Case Study.” 2019 IEEE/ACM 41st International Conference on Software Engineering: Software Engineering in Practice (ICSE-SEIP), 291–300. https://doi.org/10.1109/icse-seip.2019.00042.
Figure 1: Simplified Lifecycle with Feedback: The six core stages of ML engineering form a closed loop rather than a linear handoff. A primary feedback path from monitoring back to data collection supports investigation and adaptation as production distributions shift, model accuracy degrades, and operational constraints evolve.

The return arrow from monitoring is what makes the lifecycle a loop rather than a checklist. Evidence flows back from later stages to earlier ones, and constraints should flow back with it. A memory limit set by the deployment device belongs in problem definition, where it can shape the dataset, the model, and the evaluation, not in deployment, where it can only reject them.

Definition 3.1: Machine learning lifecycle

Machine learning lifecycle is the iterative engineering process of building, deploying, monitoring, and updating ML systems, where evidence from later stages can feed back to earlier stages because model performance may change after deployment.

  1. Significance: The lifecycle is a closed loop, not a linear pipeline. Each stage hands the next an artifact it depends on (targets, a dataset, trained weights, release evidence, a running service, monitoring evidence), so a decision at one stage constrains every stage after it, and evidence from a later stage can force an earlier one to be revisited. How often the loop must turn is itself a recurring budget, set by how quickly the deployment environment changes and how long verified labels take to arrive.
  2. Distinction: Unlike traditional software, whose behavior changes when code, configuration, dependencies, or environment changes, ML behavior can also change as the world changes. A deployed model’s accuracy may change through distribution shift even when the code, infrastructure, and configuration remain untouched.
  3. Common pitfall: Treating deployment as the end of the lifecycle. Retraining decisions depend on outcome evidence that exists only after deployment.

Carrying constraints around that loop is the job of the ML workflow, the engineering framework that makes constraints explicit at each stage and traces how deployment constraints propagate across Data, Algorithm, and Machine. The two terms divide the job. The lifecycle is what gets traversed, the stages themselves; the workflow is how the traversal is managed, the engineering discipline of orchestrating them. The workflow marks the shift from model researcher to systems engineer. A researcher optimizes individual elements: a better architecture, a cleaner dataset, a faster accelerator. A systems engineer orchestrates those elements into production systems that reliably deliver value.

↩︎ The deployment paradigms whose memory, latency, and power constraints the workflow propagates are established in Four Deployment Regimes Across Nine Orders of Magnitude.

In practice, the stages between problem definition and deployment run as two pipelines on different clocks. Figure 2 zooms into that work as ten finer-grained blocks. The upper data pipeline, the substance of stage 2, continuously transforms raw operational streams through ingestion, curation, annotation, and validation into versioned, ML-ready datasets. The lower model pipeline executes the inner development loop of stages 3 and 4: training architectures, computing evaluation metrics, validating system constraints, and packaging approved artifacts for deployment, with stage 4’s release manifest drawn as an ML certificate. Outer-loop feedback arrows carry production telemetry and validation discoveries back to upstream data stages, the return path that stage 6 operates.
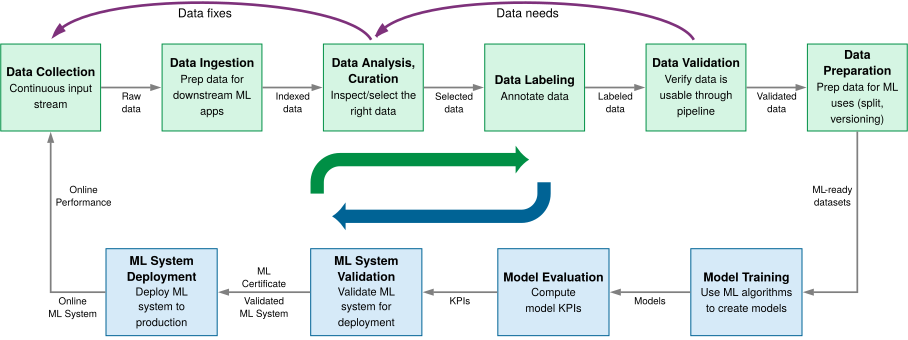
Figure 2: Dual-Pipeline ML Development: Machine learning engineering decouples into parallel data and model pipelines operating on different timescales. While the model pipeline executes rapid inner-loop training and evaluation, outer-loop feedback from production deployment and data validation continuously reshapes upstream collection and curation.

↪ The operational tooling and infrastructure that automate these lifecycle stages at scale are developed in ML Operations.

3.1.1 ML vs. traditional software

The loop and its two pipelines exist because of one difference between ML systems and traditional software. Both iterate.2 The difference that forces new workflow controls is where behavior comes from. Rule-based software changes behavior when someone changes the code, configuration, or dependencies. An ML system learns its behavior from data, so that behavior can also change when the data changes while the code stays fixed, and only fresh labeled outcomes can show whether today’s model still meets today’s requirement. Every workflow addition this chapter introduces (versioned datasets,3 statistical evaluation gates, drift monitoring) exists to manage that second path.

2 Waterfall model: A plan-driven lifecycle is often depicted as a sequence of requirements, implementation, and testing, but Royce (1970) warned that a purely sequential implementation was risky and described iteration between successive phases. ML systems add data and model feedback that must be managed explicitly.

Royce, Winston W. 1970. “Managing the Development of Large Software Systems.” Proceedings of IEEE WESCON 26: 328–88.

3 Data versioning: Unlike code, which changes through discrete, auditable commits, data can drift gradually (distribution shift), suddenly (schema migration), or subtly (label quality degradation). Plain Git is impractical for many multi-terabyte datasets, so teams commonly version external-data manifests or pointers using tools such as DVC and Git LFS. Without data versioning, teams cannot reliably reproduce a prior training run or determine whether an accuracy regression stems from a code change or a data change.

↩︎ Data-defined behavior, and the silent degradation it makes possible, are established in When ML Systems Fail Silently.

That difference alters how lifecycle stages interact. While conventional software engineering relies on production feedback to refine code and requirements, ML systems introduce feedback loops where operational data reshapes training distributions, detected drift prompts investigation, and runtime errors expose dataset blind spots. Table 1 contrasts traditional software and ML engineering across six core lifecycle dimensions, highlighting how data evolution redefines testing, deployment, and ongoing maintenance.

Table 1: Traditional Software vs. ML Development Lifecycles: Six dimensions where ML development diverges from traditional software engineering. Both use production feedback, while ML systems add loops in which deployment insights reshape data collection, monitoring drives model updates, and production experience informs model design.
Aspect Traditional Software Lifecycles Machine Learning Lifecycles
Problem Definition Functional requirements specify behavior; tests check the code against them. Objectives are statistical targets whose feasibility is known only after experiments on data.
Development Process Engineers write and revise the logic directly in code and configuration. Engineers shape behavior indirectly through data, features, architecture, and training runs.
Testing and Validation Many functional tests have exact expected results; performance and reliability remain quantitative. Metrics over held-out data, reported with uncertainty and across subgroups.
Deployment Logic stays fixed until code, configuration, or dependencies change. Accuracy can degrade when input distributions shift, with code unchanged.
Maintenance Maintenance involves modifying code to address bugs or add features. Continuous monitoring, updating data pipelines, retraining models, and adapting to new data distributions.
Feedback Loops Production feedback changes code, configuration, and requirements. Production data can become future training data, so feedback also reshapes data collection and the model.
Checkpoint 3.1: ML vs. traditional software

ML systems are not traditional software with a model attached. Check the differences that force a separate workflow:

Each difference in the comparison traces back to behavior learned from data, which ties every stage to the stages around it. A diagram shows where the stages sit but not how tightly they bind. Seeing that requires a concrete system, and this chapter carries one through every stage.

3.1.2 The running case: Diabetic retinopathy screening

Diabetic retinopathy (DR) is a major cause of preventable vision loss.4 While early detection prevents severe vision loss, limited access to specialist ophthalmologists in rural regions motivates automated screening programs. Google built one of the best documented of these programs, a deep-learning model that performed at the level of ophthalmologists on curated retinal images (Gulshan et al. 2016) and that Google Health then deployed in clinics in Thailand (Beede et al. 2020). Detecting the pathology, however, requires identifying subtle microvascular features under variable capture conditions. Figure 3 contrasts a normal retina (Panel A) with one showing diabetic retinopathy (Panel B).

4 Diabetic retinopathy (DR): DR is a common complication of diabetes; early detection can prevent vision loss, but specialist access varies substantially across countries. This gap motivates scalable screening programs. In clinics with limited hardware or unreliable connectivity, model size, offline capability, latency, and workflow integration can become binding deployment constraints.
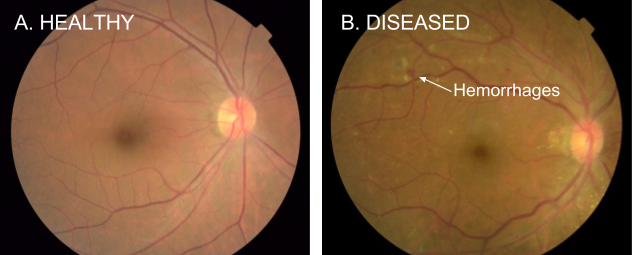
Figure 3: Retinal Hemorrhages in DR Screening: Side-by-side fundus images illustrate the subtle visual features an ML screening system must detect. Identifying localized microvascular lesions (such as the indicated hemorrhage) requires preserving fine spatial resolution through the vision pipeline and establishing strict input-quality validation to handle lighting and camera variations in clinical field deployments. Source: (Peng and Gulshan 2016).
Peng, Lily, and Varun Gulshan. 2016. Deep Learning for Detection of Diabetic Eye Disease.

This chapter follows diabetic retinopathy screening because it is a real production system whose documentation covers the full lifecycle, and because a task that looks straightforward on the surface met substantial operational friction in practice. Google’s program spans both sides of the lab-to-field divide. Its controlled validation documented expert-level accuracy, while its deployment in Thai clinics exposed problems the validation never saw: images rejected as ungradable, retakes that added work for nurses, and screening delayed when slow clinic internet connections held up uploads to the remote grading service.5

5 Healthcare AI deployment gap: In the Thai DR deployment studied by Beede et al. (2020), 393 of 1,838 submitted images (21 percent) failed the system’s image-quality requirements, often because clinic lighting, camera maintenance, or dilation practices did not match its assumptions. The case shows why laboratory metrics alone do not establish deployment readiness.

Beede, Emma, Elizabeth Baylor, Fred Hersch, Anna Iurchenko, Lauren Wilcox, Paisan Ruamviboonsuk, and Laura M. Vardoulakis. 2020. “A Human-Centered Evaluation of a Deep Learning System Deployed in Clinics for the Detection of Diabetic Retinopathy.” Proceedings of the CHI Conference on Human Factors in Computing Systems (CHI), 1–12. https://doi.org/10.1145/3313831.3376718.

The scenario this chapter uses to put numbers on each stage is a composite based on that real case study. Because the remote grading path depended on each clinic’s internet connection, the scenario moves inference into the clinic: a network of rural clinics, each executing local inference on an Orin Nano-class edge device with 4 to 8 GB of shared memory and an intermittent wide-area uplink of roughly 2 Mbps. The clinical mandate requires more than 90 percent sensitivity and a result the nurse can act on before the patient leaves, which means within seconds of capture and even when the uplink is down. Sensitivity measures the fraction of true disease cases correctly flagged; its denominator includes only patients with the condition, meaning high aggregate accuracy on an imbalanced, mostly healthy population provides no assurance that sick patients will be detected. Specificity measures the fraction of healthy patients correctly left unflagged, bounding unnecessary referrals that would overwhelm regional specialists.

A team that runs these stages as a line rather than a loop fails in a predictable way. Day one: “Build a diabetic retinopathy screening model for rural clinics.” Day 90: 92 percent sensitivity on the validation set used to guide development. Day 120: 94 percent sensitivity after a month of architecture tuning. Day 150: the model is handed to deployment engineers. Day 151: deployment engineers report that the model needs 4 GB of memory to run. Day 152: someone checks the deployment target, a low-power edge device in each clinic whose 4–8 GB of memory is shared with the operating system, the camera pipeline, and the clinic software; the clinic’s IT plan reserves about 500 MB of it for the model. Day 153: five months of work is discarded.

The model’s accuracy was excellent. The team’s machine learning skills were excellent. The failure was a workflow failure. A deployment constraint that should have shaped every decision from day one was discovered only after the work was done. That 500 MB budget should have propagated backward to the first architecture meeting, constraining which models were even worth considering. Instead, the team optimized each component in isolation (data collection, architecture selection, training), and the integration failure appeared only when the pieces were assembled. The day-153 failure is one instance of a general principle about how constraints travel through the lifecycle.

Self-Check: Question
  1. Team A ships a diabetic retinopathy (DR) screening model and freezes all development once the model clears validation in the lab, treating subsequent tasks as standard server operations. Team B treats the launch as the beginning of an ongoing feedback loop, monitoring operational telemetry and data distributions to guide investigation and evidence-based model updates. Which team’s posture aligns with the ML lifecycle as defined in this chapter, and why?

    1. A. Team B, because the ML lifecycle is a closed loop where operational feedback, distribution drift, and real-world performance continuously reshape upstream data and model decisions.
    2. B. Team A, because once a model meets its offline validation thresholds, its statistical properties remain fixed and require only standard infrastructure maintenance.
    3. C. Team A, because changing a validated model in production introduces regulatory risk that outweighs the benefits of adapting to data drift.
    4. D. Team B, because the ML lifecycle mandates automatic daily retraining of production models regardless of whether input distributions have drifted.
  2. In the running case’s day-153 failure scenario, a team spends five months developing a diagnostic model that reaches 94 percent sensitivity, only to have the entire project discarded on day 153. Explain the root cause of this failure from a workflow perspective and state the systems engineering rule that would have prevented it.

  3. True or False: Traditional software workflows and ML lifecycles differ fundamentally because ML system behavior can degrade through data distribution drift over time even when application source code, execution environment, and hardware configuration remain completely untouched.

See Answers →

3.2 How Decisions Cascade: The Constraint Propagation Principle

In the DR scenario, the in-visit requirement already ruled out cloud inference and so required edge deployment. The edge target’s memory and power budgets then constrain model architecture, favoring compact MobileNet-class models over large ensembles (several models whose predictions are combined) and requiring automated image-quality checks at capture time. Each downstream constraint narrows the design space for upstream stages, coupling hardware limits directly to data collection and model design.

Definition 3.2: Constraint propagation principle

The constraint propagation principle states that a constraint discovered late in the ML lifecycle can force rework across affected upstream stages. Datasets, trained weights, validation evidence, and deployment packages record decisions that later work depends on. Correcting a missing constraint requires tracing those dependencies to determine which artifacts must change and which remain valid. Estimating actual rework requires the effort to revise each affected artifact, repeat its dependent work, and validate the resulting system.

  1. Significance: A latency target discovered at deployment (stage 5), such as 100 ms in a web service, may propagate backward to constrain model size (stage 3: operation count \(\Operations\)), dataset requirements (stage 2: dataset size \(\DatasetSize\), the number of training examples), and problem definition (stage 1: what accuracy is achievable). Rework depends on which earlier decisions relied on the missing constraint. Within the iron law, a latency budget bounds total time \(\Time\), and therefore every term that sums to it, so it redefines the feasible region for \(\Operations\), for the bytes moved \(\DataVolume\) (distinct from the example count \(\DatasetSize\)), and for the hardware efficiency \(\EfficiencyHw\) the model must achieve.
  2. Distinction: Unlike modular decomposition (which encourages independent optimization of each component), this principle mandates end-to-end reasoning, because an accuracy optimum reached in isolation can be an infeasible system.
  3. Common pitfall: Treating deployment as “the last step” and so deferring its latency, memory, and power limits until they can only reject finished work.

Propagation runs in both directions, so the stages form a network of constraints rather than a chain. Backward propagation carries a deployment limit upstream. When rural clinic deployment reveals tight bandwidth, the team can compress images before sending them over the uplink, but lossy compression degrades input quality, so the training dataset must then include matching compression artifacts or the model will see different inputs in service than in training (training-serving skew). Shifting inference entirely to the edge and transmitting only the diagnostic result relieves the uplink instead, but tightens the edge device’s memory capacity and power budget. Forward propagation carries an early data decision downstream. Capturing fundus images at the resolution needed to see small hemorrhages fixes the model’s input size, and with it the operation count every inference must pay on the clinic device. Upstream data choices and downstream machine boundaries remain physically coupled.

Decisions made without accounting for downstream execution boundaries accumulate technical debt.6 The stage interface specification (table 2) puts this principle to work by making constraints explicit at each stage boundary, so the team catches violations before handing an artifact downstream. When propagation occurs specifically through data quality failures, the resulting pattern is known as a data cascade, a chain of downstream failures triggered by bad data (Sambasivan et al. 2021) that Data cascades examines. Propagation explains why a late constraint is expensive; how much time each loop costs, and where that time goes, is the next question.

6 ML technical debt: Sculley et al. (2015) identify ML-specific debt mechanisms such as entanglement (changing one feature affects all others because the model learned joint distributions), hidden feedback loops (predictions influence future training data), and undeclared consumers (downstream systems depending on outputs without contracts). Since ML code is often only a small part of a production system, the surrounding configuration, pipelines, and infrastructure can allow this debt to accumulate silently.

Sculley, D., Gary Holt, Daniel Golovin, Eugene Davydov, Todd Phillips, Dietmar Ebner, Vinay Chaudhary, Michael Young, Jean-François Crespo, and Dan Dennison. 2015. “Hidden Technical Debt in Machine Learning Systems.” Advances in Neural Information Processing Systems (NeurIPS) 28: 2503–11.
Sambasivan, Nithya, Shivani Kapania, Hannah Highfill, Diana Akrong, Praveen Paritosh, and Lora M Aroyo. 2021. “‘Everyone Wants to Do the Model Work, Not the Data Work’: Data Cascades in High-Stakes AI.” Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems, 1–15. https://doi.org/10.1145/3411764.3445518.

↪ Shared contracts and deployment paths that reject incompatible changes before they reach production are enforced in Development Infrastructure.

Self-Check: Question
  1. Which interpretation of the Constraint Propagation Principle is consistent with the chapter’s treatment of discovering constraints late in the ML lifecycle?

    1. A. It holds that a late-discovered constraint can force rework across upstream stages, with the actual rework depending on which datasets, weights, validation evidence, and deployment packages relied on the missing constraint.
    2. B. It establishes a universal linear rule: each later lifecycle stage adds the same fixed amount of rework regardless of what artifacts were affected.
    3. C. It claims late-discovered constraints always force a complete rebuild of every downstream artifact, so the exact dependency structure does not matter.
    4. D. It implies correction cost generally falls in later stages because downstream telemetry makes fixes easier than catching the issue early.
  2. True or False: Constraints in the ML lifecycle propagate only backward, from deployment limits discovered late toward earlier stages.

  3. When a data quality failure introduced during data collection propagates downstream to cause compounding failures in model training, validation, and deployment, the resulting pattern is known as a(n) ____.

See Answers →

3.3 Where the Hours Go: Quantifying the ML Lifecycle

The DR team lost five months to one late constraint, counting both the hours already spent and the experiments those hours could have run. Conceptual models of the ML lifecycle describe which stages exist, but planning a workflow requires knowing where its hours go, and that time rarely concentrates where research literature spends its pages.

Practitioner surveys show a gap between where research attention centers and where practitioners report spending their time, with about 79 percent of data scientists in CrowdFlower’s 2016 survey naming data collection or cleaning as the activity that consumed most of their time (CrowdFlower 2016). In the full distribution (figure 4), algorithm refinement and training-set construction together draw fewer responses than data collection alone.
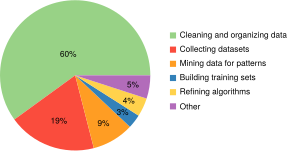
Figure 4: Data Scientist Most-Time Responses: In CrowdFlower’s 2016 survey, 60 percent of respondents selected cleaning and organizing data as the activity where they spent the most time, with 19 percent selecting data collection. Model-focused responses such as pattern mining, training set construction, and algorithm refinement together represent roughly 16 percent of responses. Adapted from CrowdFlower (2016).
CrowdFlower. 2016. Data Science Report 2016.

The survey responses identify data work as a major time sink for these practitioners, without measuring how all engineering hours were divided. In the DR project, where each image must be graded by multiple ophthalmologists before it can train anything, collection and labeling can delay useful experiments more than training does; improving that pipeline can then reduce iteration time before model or training optimizations become the binding concern. The workflow must identify its actual bottleneck rather than assign investment priorities from response shares alone. Even so, the imbalance explains why data engineering, developed in Data Engineering, deserves explicit planning rather than treatment as setup work.

Iteration velocity governs project progress. The feedback arrows in figure 2 (the Data fixes loop from curation back to collection, the Data needs loop from validation back to curation, and the Online Performance path from production deployment back to collection) are not rare exceptions; they are paths teams traverse repeatedly. Drifting clinic images or wrong labels send the DR team back to collection, and a candidate that exceeds the clinic device’s memory sends it back to model design. Each loop consumes calendar time and compute budget, so the length of one cycle bounds how much a team can learn. Consider two candidate DR models developed over the same six months: a large ensemble trained in the cloud, which takes a week per training run, and a lightweight edge model that trains in hours.

Two horizontal gray bars: 100 experiments for an hourly cycle and 26 for a weekly cycle, joined by a bracket labeled approximately 3.8 times.

Over the same six months, the hourly cycle tests nearly four times as many ideas.

Napkin Math 3.1: The iteration tax
Problem: Compare what six months of development buys for a rural diabetic retinopathy screening system: a large ensemble developed on cloud hardware as a laboratory baseline, which would itself need compression before it could fit the clinic’s memory budget (training time: 1 week, initial accuracy: 95 percent), or a lightweight edge model (training time: 1 hour, initial accuracy: 90 percent). How do the two compare in final accuracy and in the number of hypotheses the team can test?

Math: In six months (~26 weeks), the possible experiment count is:

  1. Large model: 26 weeks of calendar time at 1 week per experiment. Each experiment improves accuracy by an assumed constant ~0.15 percentage points.
  2. Small model: 26 weeks of calendar time at 168 h/week gives 4,368 possible experiments at 1 hour each. Machine time is not the binding constraint at that cycle length, so this scenario counts only 100 of them as effective experiments, a few per working week, the pace at which a team can design, run, and learn from experiments. Because the slow-cycle team runs one experiment per week, this cap on hypotheses, not the hardware, sets the breadth ratio below; a team that could formulate useful hypotheses faster would raise the ratio in proportion.

Result: If each iteration improves accuracy by 0.1 percentage points on average, the small model starts at 90 percent and reaches 100 percent after 100 effective iterations, before applying the 99 percent ceiling. With the 99 percent ceiling applied, the small model achieves 99 percent. The large model starts at 95 percent and reaches 98.9 percent after 26 slower iterations. Both approaches end near the ceiling, and the accuracy gap between them is an artifact of the assumed gains, not a finding. The difference that survives is breadth. Under the stated cap, the fast-cycle team tested 3.8× as many ideas, so it also learned which augmentations and preprocessing choices matter, knowledge the slow-cycle team never acquired.

Systems insight: Iteration velocity is a feature. Its value lies in search breadth rather than in a guaranteed accuracy lead. When candidate systems have comparable attainable quality, shorter cycles expand how much of the design space a team can test. Speed alone cannot guarantee that a smaller model will outperform a larger one. In the DR screening scenario, the lightweight model’s rapid iteration cycle enables the team to experiment with label-preserving input transformations, preprocessing pipelines, and architecture variations far more quickly.

This cumulative delay defines the iteration tax: time spent waiting on slow training runs or cumbersome validation pipelines reduces how many candidate models a team can test. Late discoveries amplify this penalty,7 as the constraint propagation principle (section 3.2) established. Violations caught only after deployment invalidate artifacts produced by earlier stages, forcing expensive retraining, pipeline adjustments, and renewed validation. Intercepting defects before they cascade into systemic rework requires explicit stage interface contracts that validate outputs at every stage boundary (section 3.4.1).

7 Late correction costs: Boehm (1981) discussed in Software Engineering Economics how defects found late can cost more to fix than those caught during requirements. In ML systems, late-discovered constraints may require retraining, data-pipeline changes, and renewed validation.

Boehm, Barry W. 1981. Software Engineering Economics. Prentice-Hall.
Self-Check: Question
  1. In the 2016 CrowdFlower data scientist survey cited in the text, respondents indicated that data-related tasks dominated their time, with 60 percent selecting ____ and organizing data as their largest time sink, compared to only 4 percent for refining algorithms.

  2. A DR team’s validation pipeline takes a full week per candidate model. Using the chapter’s iteration tax, explain what this slow loop costs the team beyond calendar time, and name the workflow mechanism the chapter proposes to keep late discoveries from multiplying that cost.

See Answers →

3.4 Stage Ownership and Hand-offs

The rural-clinic failure showed what happens when no stage owns a constraint. The deployment limit surfaced only after data curation, model training, and evaluation decisions had hardened around an unfeasible target, and preventing such misalignments requires clear ownership across the system stack. The six stages of figure 1 divide project responsibilities along the D·A·M axes. Problem definition sets the governing requirements for all three. Data collection and preparation owns the Data axis, model development and training governs the Algorithm axis, and deployment and integration commits both to a physical Machine. Evaluation and monitoring own no single axis of their own; their role is verification, testing whether the three axes work together before release and continuously in production.

A single model choice in the DR project touches every stage. Problem definition fixed the clinic device’s 500 MB model budget, so model development starts from architectures designed for budgets of that kind. MobileNetV2, the book’s mobile lighthouse workload (Lighthouse models put the iron law into practice), is a natural candidate backbone, at about 14 MB of FP32 weights and about 600 MFLOP per inference. It reaches that operation count by replacing standard image-processing layers with a cheaper variant8 rather than by pruning a larger model. Choosing it immediately constrains the other stages. Data preparation must produce images at the capture resolution that keeps small hemorrhages visible, since that resolution rather than the backbone’s default sets the input size, evaluation must measure latency on the clinic device as well as sensitivity, and deployment must confirm that weights, activations, and runtime together fit the budget. If on-device evaluation then misses the latency target, the fix loops back to architecture or input resolution, so the stage sequence in the diagram is traversed as a cycle rather than once.

8 Depthwise separable convolutions: The layer type MobileNetV2 uses in place of standard convolutions. It splits one expensive operation into two cheaper ones and cuts computation by roughly 8–9\(\times\) for typical kernel sizes (Sandler et al. 2018), which is what makes the roughly 600 MFLOP inference budget plausible on mobile-class hardware.

Sandler, Mark, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, and Liang-Chieh Chen. 2018. “MobileNetV2: Inverted Residuals and Linear Bottlenecks.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 4510–20. https://doi.org/10.1109/cvpr.2018.00474.
Checkpoint 3.2: The workflow cycle

Verify that each stage enforces contracts that bind upstream choices to physical deployment constraints.

Each of those stage decisions also lands on a term of the iron law. In the retinal screening pipeline, the capture resolution chosen during data preparation sets the bytes moved per image (\(\DataVolume\)), the MobileNetV2 backbone selected during model development fixes the operations per frame (\(\text{FLOPs/Sample}\)), and the clinic hardware together with its serving runtime determines the realized execution speed (\(\text{Seconds/FLOP}\)) and dispatch overhead (\(\Latency\)). Tracing how the six stages map onto the equation shows where each team’s local choices enter the end-to-end time budget.

↩︎ The iron law of ML systems and its governing terms are established in Iron Law of ML Systems.

Systems Perspective 3.1: Lifecycle stages and the iron law
The six lifecycle stages alter distinct factors in the iron law of ML systems, both across its multiplicative D·A·M form (equation 1.2) and across its unpacked physical terms (\(\Time = \frac{\DataVolume}{\Bandwidth} + \frac{\Operations}{\PeakRate \cdot \EfficiencyHw} + \Latency\)). Rather than rigid one-to-one assignments, the mappings serve as diagnostic starting points:

  • Problem definition: Sets target constraints for accuracy, latency, cost, privacy, and deployment paradigm (screened across privacy, latency, compute, and cost gates using the decision framework in Deployment Decision Screening). These targets determine which terms of the equation are permitted to grow and which must be bounded from the outset.
  • Data collection and preparation: Shapes dataset composition, the sample budget (\(\text{Samples/Task}\)), and the byte volume (\(\DataVolume\)) presented to downstream pipelines. Curation can also change the training work required to reach a quality target.
  • Model development and training: Dictates per-sample algorithmic work (\(\text{FLOPs/Sample}\)) and total operations (\(\Operations\)), along with data reuse patterns, parameter movement, and achievable hardware efficiency (\(\EfficiencyHw\)).
  • Evaluation and validation: Tests whether model quality and end-to-end execution meet deployment requirements on the target system.
  • Deployment and integration: Determines the serving path and realized machine speed (\(\text{Seconds/FLOP}\)), including runtime data movement, execution efficiency, and fixed overhead (\(\Latency\)).
  • Monitoring and maintenance: Observes distribution drift, latency, throughput, and operational cost after launch, feeding violations back into earlier stages for re-optimization.

Viewing the lifecycle through the iron law grounds latency and cost in hardware physics. Production workflows must simultaneously satisfy accuracy, safety, privacy, and organizational constraints that sit outside the equation.

3.4.1 Stage interface contracts

If the data team hands over \(512 \times 512\) retinal crops while the training script expects \(1024 \times 1024\) images, or if problem definition hands off to data collection without recording the clinic device’s 500 MB memory limit, the defect travels silently until a downstream stage crashes or rejects the finished model. Catching those mismatches at the hand-off requires treating each lifecycle stage as an engineering boundary with defined inputs, outputs, and quality invariants. In production, pipeline orchestrators encode these dependencies as directed acyclic graphs (DAGs), where nodes represent discrete execution tasks and directed edges represent validated artifacts. While the overarching ML lifecycle forms a recurring feedback loop over weeks and months, each individual pipeline run executes as an acyclic sequence of dependent steps. This structure enables the orchestrator to parallelize independent branches, cache validated intermediate outputs, and halt execution the moment a contract is violated. Just as microservice architectures rely on interface specifications to enforce API boundaries, ML pipelines require strict schema, distribution, and performance contracts to prevent defective data or degraded weights from corrupting downstream artifacts. Each stage therefore has defined inputs, deliverables, and quality invariants (table 2).

Table 2: Stage Interface Specification: Each lifecycle stage has explicit input requirements, output deliverables, and quality invariants that must hold for the stage to be considered complete. Violations of these contracts create technical debt that compounds through subsequent stages. The deployment paradigm selection in Problem Definition (Cloud, Edge, Mobile, or TinyML) constrains all downstream stages, as a TinyML target imposes different data, model, and monitoring requirements than a Cloud target.
Stage Input Contract Output Contract Quality Invariant
Problem Definition Business requirements; operational context Measurable objectives; deployment paradigm selection; resource constraints All success criteria are quantifiable; target deployment paradigm is explicit
Data Collection & Preparation Objectives; deployment target; quality requirements Versioned dataset with schema; preprocessing pipeline; data validation rules Distribution approximates anticipated production environment; labeling meets accuracy requirements
Model Development & Training Dataset; accuracy targets; resource constraints Trained model weights; training configuration; experiment logs Meets accuracy thresholds within computational budget; architecture compatible with deployment target
Evaluation & Validation Trained model; held-out test data; evaluation criteria Performance metrics across subgroups; failure mode analysis; release manifest No critical subgroup falls below minimum thresholds; predicted confidence matches observed accuracy as closely as the domain requires
Deployment & Integration Validated model; infrastructure requirements; service-level agreement (SLA) targets Serving endpoint; monitoring instrumentation; rollback procedures Latency and throughput meet paradigm requirements; integration tests pass
Monitoring & Maintenance Live system; performance baselines; alert threshold Drift detection alerts; update-review criteria; incident reports Alert coverage and detection windows are defined; detected degradation triggers review

Enforcing explicit contracts turns the conceptual feedback loop in figure 1 into an operational audit trail. When validation or monitoring surfaces a defect, the contract boundary identifies which upstream stage owns the fix. For example, a mismatch between training features and production inputs may demand targeted data collection, whereas an error in feature transformation points directly to a bug in the serving pipeline. Catching these violations at stage boundaries stops bad assumptions before they harden into late-stage rework.

Example 3.1: Auditing stage transitions
Scenario: An engineering team claims to have completed Problem Definition for the DR screening classifier, attempting to transition to Data Collection without establishing deployment target constraints.

Diagnosis: The output contract lacks deployment paradigm selection and resource constraints (latency and memory targets). If the violation surfaces only at deployment as a trained model larger than the edge device’s 500 MB model budget, the audit must trace what relied on the missing limit. A smaller candidate may require revised input-resolution or preprocessing choices, new weights, repeated sensitivity and on-device memory tests, and a replacement deployment package. Existing raw images may remain usable; changing the candidate does not imply recollecting every image.

Repair schedule: Suppose the repair plan preserves the raw images and labels but changes input preparation and the candidate architecture. Assume 1 day to revise preparation, 2 days to train new weights, 2 days to repeat validation, and 1 day to package the approved result. If each task waits for the preceding artifact and the required staff and compute are available, the repair takes 6 days. This is a supplied schedule for this dependency chain, not a multiplier determined by the discovery stage. Queueing, failed validation, or parallel independent tests would change the elapsed time.

Systems lesson: Stage transitions act as quality gates in the ML lifecycle. Enforcing strict output contract validation before proceeding downstream prevents expensive upstream rework and ensures data collection aligns with target deployment hardware.

Without explicit contract gates, unstated assumptions propagate downstream. The earliest opportunity to bound them is Problem Definition, which records the operational constraints that subsequent stages must satisfy.

Self-Check: Question
  1. Order the following lifecycle phases in the canonical sequence established in the chapter for a new ML system project: (1) Deployment and Integration, (2) Problem Definition, (3) Monitoring and Maintenance, (4) Data Collection and Preparation, (5) Model Development and Training, (6) Evaluation and Validation.

  2. An engineering team completes Problem Definition with clinical sensitivity targets but marks the target deployment paradigm as ‘TBD — to be determined after model training.’ According to the Stage Interface Specification, what should the transition audit verdict be, and why?

    1. A. Approved, because decoupling model development from hardware targets allows researchers to maximize accuracy before applying post-hoc pruning.
    2. B. Approved with warning, provided the team commits to using cloud inference if the model exceeds edge memory budgets.
    3. C. Blocked, because Problem Definition’s output contract explicitly requires deployment paradigm and resource constraints to be established before data collection and modeling begin.
    4. D. Blocked only if the model architecture requires distributed multi-GPU training, since single-device models can adapt to any deployment target.
  3. The chapter considers MobileNetV2 (about 14 MB of FP32 weights and ~600 MFLOPs per inference) as a candidate backbone for the DR clinic device, whose model budget was fixed at Problem Definition. Explain how choosing a model to fit that budget propagates across Data Collection, Model Development, and Evaluation.

  4. Which mapping between lifecycle stages and the terms in the Iron Law of ML Systems (\(T = \frac{D_{\text{vol}}}{\text{BW}} + \frac{O}{R_{\text{peak}} \cdot \eta_{\text{hw}}} + L_{\text{lat}}\)) is conceptually consistent with the chapter?

    1. A. Problem Definition exclusively determines \(R_{\text{peak}}\), and later lifecycle stages cannot materially affect hardware throughput or efficiency once the use case is chosen.
    2. B. Model Development and Training exclusively determines \(O\), while Data Collection and Preparation cannot affect bytes moved and Deployment and Integration cannot affect latency overhead.
    3. C. Deployment and Integration exclusively determines \(L_{\text{lat}}\), while earlier stages cannot materially affect operation count, data volume, or serving-path overhead once deployment begins.
    4. D. Data Collection and Preparation is diagnostically associated with bytes moved such as \(D_{\text{vol}}\); Model Development and Training is associated with computational work \(O\) and opportunities for reuse; Deployment and Integration is associated with serving-path overhead such as \(L_{\text{lat}}\), even though these influences are not exclusive.
  5. To prevent defect propagation across lifecycle boundaries, the chapter formalizes each stage boundary using a(n) ____ contract, which defines required inputs, output deliverables, and non-negotiable quality invariants.

See Answers →

3.5 Stage 1: Problem Definition

Problem definition in ML begins with sentences that look deceptively simple. A product manager writes: “Build a model that detects diabetic retinopathy.” That single sentence conceals a dozen engineering decisions: sensitivity thresholds for patient safety, hardware capabilities in rural clinics, latency budgets that keep clinicians engaged, and regulatory frameworks governing approval. Software requirements still govern control flow, interfaces, and data storage. ML adds an empirical obligation. Defining what the system should do is inseparable from defining how it will learn from data and what physical constraints its execution must survive.

The request for a model must first become a requirement for a useful improvement. In the clinic case, the baseline is the existing screening and referral workflow, evaluated on the outcomes and resource limits the proposed system must improve. A simpler rule or an existing model can provide an additional comparison where appropriate. The comparison must include the complexity tax established in Four screening gates for choosing a tier, so a learned system earns its place only when the value of the errors it avoids exceeds the infrastructure and maintenance it adds. If available data cannot support the required evaluation, or the expected benefit does not justify the added errors, cost, and maintenance, the team should revise the problem or retain the baseline rather than proceed automatically to training.

Balancing these demands requires reasoning across the full system stack. An engineering team cannot optimize accuracy in isolation, because pursuing marginal sensitivity gains by scaling model depth or adopting a larger model family inflates parameter count and computational demands (FLOPs per inference), directly challenging the memory capacity and thermal limits of low-cost clinic hardware. Conversely, pruning a model (removing the weights that contribute least) to fit an embedded accelerator’s DRAM budget risks dropping sensitivity below clinical safety thresholds. Every technical decision operates within a multi-constraint optimization problem where statistical goals, physical execution budgets, and operational mandates continually bound each other’s feasible design space.

3.5.1 Constraint layers

A screening model that reaches 95 percent sensitivity in a cloud notebook is unusable if it needs 4 GB of RAM on a clinic device with 500 MB to spare, or if clinic staff cannot audit why it flagged a patient. Every ML problem definition therefore decomposes into three interacting constraint layers: statistical, physical, and operational. Rather than isolated requirements, these layers form a coupled stack where a constraint in one tier immediately restricts the degrees of freedom in the others. At the top, the statistical layer specifies target behavior over data distributions, such as achieving \(>90\) percent sensitivity and \(>80\) percent specificity across diverse patient demographics and camera models rather than an unweighted aggregate accuracy that conceals failure modes on minority subpopulations. Meeting that target in the field depends on the physical layer, which bounds execution within hardware limits: for rural clinics, that means running inference on local edge accelerators under tight thermal budgets and bounded memory capacity (such as 4 to 8 GB of shared DRAM) and returning a result during the visit without depending on intermittent network uplinks. Surrounding both is the operational layer, which governs clinical auditability, regulatory clearance, and the maintenance rules that keep the deployed system safe over time.

The operational layer carries physical consequences that traditional software engineering rarely encounters. In a traditional database, deleting a patient’s record is a DELETE statement. In an ML system, model weights may encode statistical patterns learned from that record. Where law or a regulator requires removing that influence, compliance may require machine unlearning (Cao and Yang 2015; Bourtoule et al. 2021) (an active research area with incomplete guarantees) or retraining on the remaining data. The obligation and remedy depend on the governing rule and system; at DR-system scale, either can make privacy compliance a recurring compute-budget item and training provenance an architectural constraint.

Cao, Yinzhi, and Junfeng Yang. 2015. “Towards Making Systems Forget with Machine Unlearning.” 2015 IEEE Symposium on Security and Privacy, 463–80. https://doi.org/10.1109/sp.2015.35.
Bourtoule, Lucas, Varun Chandrasekaran, Christopher A. Choquette-Choo, Hengrui Jia, Adelin Travers, Baiwu Zhang, David Lie, and Nicolas Papernot. 2021. “Machine Unlearning.” 2021 IEEE Symposium on Security and Privacy (SP), 141–59. https://doi.org/10.1109/sp40001.2021.00019.

↪ Why removing a record’s influence from trained weights remains a compliance obligation is developed in Responsible Engineering.

The constraint propagation principle (section 3.2) explains why all three layers must be bound before development begins. A constraint that exists in the physical or operational environment but remains unstated in the problem definition does not vanish. It re-emerges later as an architectural violation after dependent decisions have hardened. For example, if an engineering team defines the objective solely as aggregate classification accuracy on retinal images, standard optimization will minimize the average training loss, which the majority class dominates. In an imbalanced screening population where 90 percent of patients are healthy, a model predicting “no disease” achieves 90 percent aggregate accuracy while failing every patient who needs urgent care. Preventing this requires translating a domain invariant (a missed diagnosis costs far more than a false referral) into an explicit statistical contract: class-weighted loss, a sensitivity floor, and subgroup targets.

War Story 3.1: When the label was the bias (2018)
Context: In 2014, Amazon assembled an engineering team at its Edinburgh hub to build an internal machine-learning system for ranking technical job applicants, training it on ten years of resumes submitted to Amazon (Dastin 2018).

Mechanism: Because prior hiring was male-dominated, the model learned that male-coded language correlated with hiring success, systematically penalizing terms like “women’s” and downgrading graduates of two all-women’s colleges.

Impact: The model reproduced historical hiring bias, rendering automated resume screening unsuitable for production recruitment.

Fix: Amazon abandoned the experimental tool after attempts to remove explicit gender signals could not guarantee that it would not learn other discriminatory proxies.

Systems lesson: Problem definition must specify fairness, auditability, and rejection criteria before data collection and training. A workflow trained on biased labels does not learn the operational goal; it learns to reproduce the labels.

Dastin, Jeffrey. 2018. “Amazon Scraps Secret AI Recruiting Tool That Showed Bias Against Women.” Reuters.

3.5.2 Problem definitions evolve

When a DR screening program expands from one pilot clinic with a calibrated fundus camera to dozens of regional health centers with different camera brands and patient populations,9 its initial assumptions break. Sensor noise profiles diverge, optical resolutions shift, and demographic changes alter subgroup error rates. A problem definition is therefore not a static specification frozen at the start of a project; it must evolve as deployment expands, adding subgroup accuracy targets and broader hardware compatibility checks. How such subgroup and governance requirements are specified, tested, and maintained is developed in Responsible Engineering.

9 Demographic drift: Population changes can expose performance gaps that aggregate evaluation obscures. Facial-analysis benchmarks found large demographic error-rate disparities (Buolamwini and Gebru 2018), while a healthcare risk-scoring study found racially biased allocation from a proxy label despite similar need (Obermeyer et al. 2019). These examples come from other domains; they illustrate why a growing DR program should evaluate subgroup performance.

Buolamwini, Joy, and Timnit Gebru. 2018. “Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification.” Conference on Fairness, Accountability and Transparency, 77–91.
Obermeyer, Ziad, Brian Powers, Christine Vogeli, and Sendhil Mullainathan. 2019. “Dissecting Racial Bias in an Algorithm Used to Manage the Health of Populations.” Science 366 (6464): 447–53. https://doi.org/10.1126/science.aax2342.

This evolution follows directly from how ML systems learn. Scaling exposes rare inputs absent from pilot evaluations, while production environments shift the input distribution in ways no static offline dataset fully captures. A sound problem definition anticipates this drift by setting governance rules upfront: defining which monitoring signals trigger formal re-evaluation and bounding how threshold updates propagate through later pipeline stages. Once these operational constraints and performance boundaries are defined on paper, the workflow must ground them in physical artifacts, beginning with the data collection pipelines that gather the training distribution.

Self-Check: Question
  1. Why does the statement ‘Build a computer vision model that detects diabetic retinopathy’ fail as a complete problem definition for an ML system?

    1. A. It specifies only a high-level task while omitting the statistical constraint layers (sensitivity/specificity floors across subgroups), physical constraints (edge device memory/latency budgets), and operational constraints (regulatory compliance, clinical workflow integration).
    2. B. It fails to specify which exact deep neural network backbone and learning rate schedule must be used during training.
    3. C. It defines an image classification problem when medical AI systems must always be framed as unsupervised anomaly detection tasks.
    4. D. It defines quantifiable objectives before data collection has occurred, which violates standard ML agile practices.
  2. Explain why ophthalmologists and clinic administrators must participate directly in Problem Definition for a DR screening system, rather than being consulted only during clinical evaluation.

  3. In the 2018 Amazon automated recruiting war story cited in the chapter, an ML model trained on ten years of resumes was abandoned because it systematically penalized female applicants. What fundamental systems lesson does this case illustrate regarding Problem Definition?

    1. A. Resume screening models require recurrent neural networks rather than transformer architectures to avoid learning gendered proxies.
    2. B. Offline evaluation metrics are inherently incapable of measuring demographic disparities in supervised learning models.
    3. C. A model trained on historical data learns to reproduce historical label biases rather than the intended operational goal; fairness criteria and auditability must be explicitly defined at Problem Definition.
    4. D. Multi-class classification algorithms should not be applied to human evaluation tasks where ground truth is subjective.
  4. True or False: When a diabetic retinopathy screening deployment scales from a 3-clinic pilot to 200 clinics across diverse regions, the high-level clinical intent (detect referable retinopathy early) remains stable, but the specific engineering targets (subgroup sensitivity thresholds, device latency budgets, and camera-specific preprocessing rules) must evolve.

See Answers →

3.6 Stage 2: Data Collection and Preparation

On paper, the problem definition asks for 90 percent sensitivity across rural clinics; in the field, that target immediately meets smudged camera lenses, missing patient records, and a 2 Mbps clinic internet link. Moving from problem definition to data collection is where abstract accuracy targets meet those physical realities. This stage determines dataset size \((\DatasetSize)\), the number of examples, and through it the iron law’s byte volume \((\DataVolume)\), the bytes that storage systems, networks, and memory buses must move; the two grow together but are not the same quantity, since image resolution and encoding set how many bytes each example costs. The deployment constraints established during problem definition become technical data requirements. If the model must run on edge devices, the collection pipeline must produce inputs compatible with edge preprocessing; if it must achieve 90 percent sensitivity across diverse populations, the dataset must sample those subpopulations sufficiently to support model training.

Data collection and preparation is an ongoing engineering discipline rather than a one-time task. For diabetic retinopathy screening, these criteria demand a collection strategy far more stringent than standard computer vision benchmarks. The pipeline must assemble roughly \(10^5\) retinal fundus photographs across diverse patient cohorts and imaging hardware, with each image graded by multiple ophthalmologists and disagreements resolved to establish consensus ground-truth labels capable of withstanding clinical and regulatory scrutiny. The annotation protocol must capture fine pathological features (microaneurysms, hemorrhages, and hard exudates) across the entire disease severity continuum. Curation also governs computational efficiency, because not all captured data contributes equally to training, and deliberate selection (The case for smaller datasets) can eliminate redundant samples while preserving the statistical coverage required for generalizable performance.

Each retinal photograph spans several megabytes, and clinical protocols capture multiple views per patient, immediately creating a physical infrastructure bottleneck. A busy rural facility generates gigabytes of raw imaging data each day, a volume that would overwhelm an intermittent 2 Mbps uplink during operating hours. Rather than saturating limited wide-area bandwidth with raw uploads, the system can execute inference locally on the edge accelerator and transmit only a compact edge summary: a structured record containing the diagnostic classification and clinical metadata. Local inference reduces uplink traffic from tens of megabytes to kilobytes per patient.

Two violet bars on a log scale: a long bar for raw images at 2 GB/day and a short bar for edge summaries at 1 MB/day, with a dimension arrow between their ends labeled 2,000×.

Edge summaries shrink the clinic’s daily uplink about 2,000-fold.

Napkin Math 3.2: Bandwidth vs. compute
Problem: Quantify the uplink window occupancy for raw image uploads from a busy rural clinic capturing retinal images for diabetic retinopathy screening, and evaluate architectural alternatives to relieve link contention.

Math:

  1. Daily data: At 100 patients/day, 4 photos/patient, and 5 MB/photo, the clinic produces 2 GB/day.
  2. Upload time: The uplink is 2 Mb/s, or 0.25 MB/s. Dividing 2,000 MB by that rate gives 8,000 s, approximately 2.2 h.
  3. Constraint: If the clinic requires same-shift upload during its 8 h operating window, this transfer alone occupies the link for 27.8 percent of that window and may contend with other traffic.

Systems insight: On a good day the raw upload fits the shift, but it ties up a large share of the link, and on a day the link drops it does not happen at all. A screening result that must reach the nurse during the visit therefore cannot depend on the uplink, which is the case for local inference. Uploading detection summaries (10 KB/patient) instead of images also cuts uplink traffic by 2,000×. Overnight batching of images for training remains possible and is not compared here.

Running inference at the clinic (notebook 3.2) is the data locality invariant (definition 2.3) applied to a clinic uplink. Edge accelerators such as the NVIDIA Jetson family10 make it practical, though they introduce a hardware trade-off between using a smaller model that fits a low-power edge budget and provisioning more capable on-premise devices at higher cost. The bandwidth constraint makes this infrastructure choice a data-collection decision rather than a late implementation detail: the scenario architecture combines edge devices for local inference and preprocessing, clinic aggregation servers for data management and buffering, and cloud training infrastructure for periodic model updates, targeting a result within seconds of capture and operation that does not depend on connectivity.

10 NVIDIA Jetson: NVIDIA’s Jetson family spans a wide product range, from Jetson Orin Nano (7–15 W) through Jetson Orin NX (10–25 W) to Jetson AGX Orin (15–60 W). This scenario uses an Orin Nano-class device (4–8 GB shared LPDDR5, 7–15 W power envelope) as a concrete edge target. Its memory and power budgets constrain model complexity, while selecting a larger device changes both the feasible model and the per-clinic cost.

Privacy constraints impose a similar architectural decision. Patient privacy regulations may motivate local retention or distributed training, but they generally specify protections and permitted uses rather than one required training topology. Workflows that keep raw clinic data local while sharing only approved updates or summaries add complexity to both data collection and model training infrastructure.

3.6.1 Lab-to-field data gap

Laboratory data and production data inhabit different worlds. This lab-to-field gap appeared when Google’s DR screening reached clinics in Thailand (Beede et al. 2020): images arrive from diverse camera equipment operated by staff with varying expertise, often under suboptimal lighting with inconsistent patient positioning. A model trained on high-quality research images from standardized fundus cameras may fail on blurry, poorly lit images from older equipment, not because the algorithm is wrong but because the data distribution has shifted beyond the training envelope. Closing that gap across many clinics is an infrastructure problem as much as a modeling one.

3.6.2 Distributed data infrastructure

If a deployment grows from a handful of clinics to hundreds, the data infrastructure becomes a distributed system whose design follows from the constraints set during problem definition. Connectivity decides transmission. Facilities with reliable broadband can stream diagnostic summaries in near real time, whereas clinics with intermittent satellite links require store-and-forward architectures that buffer data locally and synchronize opportunistically during connectivity windows. That choice propagates through the physical stack, because store-and-forward clinics need larger local storage buffers, edge inference that runs without the network, and a way to reconcile local preliminary classifications with later central review. Storage placement matters at the central end as well, since the training set is read in full every epoch, validation sets occasionally, and the regulatory archive almost never, so each belongs on a different storage tier.

↪ The cost and throughput of each storage tier, and why ML systems combine them, are measured in Storage tiers and cost.

11 Distributed clinic data: Training across clinic sites without simply pooling all raw data addresses privacy and governance constraints, but it shifts cost into coordination. Each site may use different cameras, serve different patient populations, and follow different operating routines, so the system must track where data came from and how each site differs. The workflow cost is therefore not just storage capacity; it is the engineering work needed to compare, validate, and update models across sites whose data does not behave identically.

Data heterogeneity grows alongside byte volume. Divergent camera optics, uneven clinic illumination, and variable operator training give each clinic a distinct input distribution, so each clinic operates as a distinct data source.11 The dataset this stage hands forward must therefore carry provenance metadata that records camera model, capture settings, and operator ID for every image. That provenance trail is what isolates a site-specific accuracy regression and satisfies a regulatory audit. Heterogeneity also argues for validation at the point of capture, because a miscalibrated camera discovered weeks later during a central training run has already wasted storage, compute, and patient follow-up opportunities.

3.6.3 Quality assurance and validation

A blurry retinal image that slips past quality checks does not merely waste storage. If such images enter training with unreliable labels or appear frequently in production, they distort the statistical evidence available to the model and degrade clinical safety. Quality assurance ensures that incoming data satisfies the invariants downstream stages depend upon. In the diabetic retinopathy scenario, automated quality-scoring models deployed at the fundus camera immediately flag out-of-focus or improperly framed captures, prompting clinical staff to retake the photograph while the patient is still present rather than discovering the defect weeks later during model training.

↪ Data cascades, in which uncaught collection defects compound into downstream training and evaluation failures, are developed in Data cascades.

Validation extends beyond image quality to verify proper labeling, patient association, and privacy compliance. Local validation catches capture problems on the spot, whereas centralized validation detects distributional anomalies across the full clinic network, for instance by flagging when a particular site’s images skew toward a narrow demographic range that would bias the training set. Together with the bandwidth and privacy limits set earlier in the stage, these quality checks settle what data the training set contains and what clinic-to-clinic variations the model must handle. Even a curated, validated dataset can still starve the next stage, however, if the order in which training reads it fights the storage system that holds it.

3.6.4 Sample order and delivery rate

The DR training procedure reads the training set, on the order of \(10^5\) fundus photographs, in full on every epoch, in a fresh random order each time. Whether the accelerator stays busy depends on one comparison, the rate at which the data loader (the software that reads and batches examples for training) delivers images against the rate at which training consumes them. If delivery is slower, the accelerator idles however fast it is, and random order makes that outcome more likely because it scatters reads across storage and defeats the caching and prefetching that sequential reads enjoy. The data hand-off is therefore complete only when the workflow has measured the loader’s delivery rate against the consumption rate. Closing a gap is the work of data engineering, which treats it as the feeding problem (The feeding problem), and of training systems; the workflow’s responsibility is to run the test and route a failure to the right fix.

↪ How prefetching overlaps data delivery with computation so that the loader keeps the accelerator busy is developed in Data prefetching and overlapping.

Data collection therefore does not end when training begins. Feedback from evaluation and production keeps revising what is collected, and the delivery test keeps checking whether the loader can feed what the model consumes. Building the collection and delivery pipelines is the subject of Data Engineering, and deciding which collected examples deserve training compute is the subject of Data Selection. What this stage hands forward is a versioned dataset, its preprocessing pipeline, and a measured delivery rate, which together become the raw material that model development turns into trained models.

Self-Check: Question
  1. A rural clinic screens 100 patients per day for DR, capturing 4 retinal photos per patient (two fields per eye) at 5 MB per photo. The clinic operates on an 8-hour daily shift with an intermittent 2 Mbps uplink. According to the chapter’s Bandwidth vs. Compute analysis, why does the screening result still require edge inference?

    1. A. Raw upload takes about 2.2 hours, so it fits the shift and cloud inference is sufficient whenever the link is up.
    2. B. Raw upload of 2 GB takes about 2.2 hours, roughly a quarter of the shift, but a result that must reach the nurse during the visit cannot depend on a link that drops, so inference runs locally and only 10 KB summaries go upstream, cutting traffic by about 2,000\(\times\).
    3. C. Daily raw image upload generates 75 GB of data, which exceeds daily satellite uplink capacity by a factor of 100\(\times\) regardless of compression.
    4. D. Raw uploads complete in 45 minutes, but cloud GPU queuing delay adds 12 hours of fixed inference latency.
  2. Explain why a DR screening model achieving an AUC of 0.99 on a curated laboratory research dataset can see its sensitivity fall well below the 90 percent screening target when deployed to rural clinics.

  3. As a DR screening deployment expands from a pilot site to hundreds of clinics, the data pipeline records the camera model, capture settings, and operator ID for every image. Why does the chapter treat this provenance metadata as essential rather than optional bookkeeping?

    1. A. It lets the training cluster skip quality validation for images from clinics with trusted operators.
    2. B. Data heterogeneity grows with the number of clinics, so the provenance trail is what isolates site-specific accuracy regressions and satisfies regulatory audit requirements.
    3. C. It compresses each image enough to fit within the clinic’s 2 Mbps uplink during operating hours.
    4. D. It replaces the need for consensus grading by multiple ophthalmologists.
  4. True or False: In large-scale medical data collection, if collected images pass basic file format and schema validation, image-quality defects (such as blur, low contrast, or partial occlusion) can be safely ignored because deep neural networks naturally learn to filter out bad samples when trained on sufficiently large datasets.

  5. In rural clinics with intermittent connectivity, an architecture that buffers captured images locally and reconciles inference results asynchronously with the central cloud during available network windows is known as a(n) ____ architecture.

  6. A training pipeline randomly shuffles a multi-terabyte dataset across samples on every epoch, pulling records from storage backed by NVMe and spinning disks. Even though the hardware accelerator has ample peak compute capacity, training throughput stalls. Which explanation correctly identifies the systems-level bottleneck according to the chapter?

    1. A. Random shuffling makes the training workload strictly compute-bound, so the accelerator cores become overloaded by stochastic gradient calculations.
    2. B. Random sample access scatters reads across storage, defeating the caching and prefetching that sequential reads enjoy, so the data loader cannot deliver samples as fast as the accelerator consumes them.
    3. C. Shuffling multi-terabyte datasets bypasses the operating system page cache entirely, forcing floating-point arithmetic units to stall on instruction decoding.
    4. D. The memory hierarchy becomes saturated because the accelerator requires deterministic sample ordering to maintain kernel pipeline parallelism.

See Answers →

3.7 Stage 3: Model Development and Training

The DR team has on the order of \(10^5\) labeled retinal images, the scale of the 128,000-image dataset in Google’s study, along with a validated preprocessing pipeline and a target: more than 90 percent sensitivity on edge hardware, returned within seconds of capture. The question is no longer what data to collect but what model to build, and that question has no answer independent of the deployment constraints already established. In iron law terms, this stage defines the operations \((\Operations)\) term, because architectural choices set the computational floor that hardware must sustain. Training is where that cost is first paid. The model learns by making repeated passes over the labeled images, adjusting its parameters slightly after each group of examples, and a single training run can occupy an accelerator for hours or weeks. Every idea the team wants to test costs at least one such run, so training systems must coordinate data ingestion, accelerator execution, and the search over training settings12 without stalling execution pipelines. In high-stakes domains like healthcare, every design decision affects clinical outcomes, so technical performance and operational constraints must be integrated from the start.

12 Hyperparameter: Architectural and optimizer choices (for example, learning rate and network depth) affect the computational work of training. A naive Cartesian grid that trains every combination independently incurs a multiplicative search cost: 5 hyperparameters with 4 values each produces 1,024 (\(4^{5}\)) configurations. Search strategies that stop unpromising runs early or choose the next configuration from earlier results avoid completing every run, which is why the grid represents a baseline rather than an unavoidable cost.

13 Transfer learning: For the same architecture, transfer learning changes how parameters are initialized and optimized, not the operations required at inference.

Russakovsky, Olga, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, et al. 2015. “ImageNet Large Scale Visual Recognition Challenge.” International Journal of Computer Vision 115 (3): 211–52. https://doi.org/10.1007/s11263-015-0816-y.
Yosinski, Jason, Jeff Clune, Yoshua Bengio, and Hod Lipson. 2014. “How Transferable Are Features in Deep Neural Networks?” Advances in Neural Information Processing Systems 27.

The DR system faces a sharp training challenge: achieve expert-level diagnostic accuracy with finite labeled-data and optimization budgets. Transfer learning13 addresses this constraint by adapting a model pretrained on a source task to a target task. The ImageNet Large Scale Visual Recognition Challenge (ILSVRC) 2012 training subset contains 1.3 million labeled images (Russakovsky et al. 2015). Reusing learned representations can improve target-task optimization and generalization relative to random initialization, with the benefit depending on source-target similarity, which layers are transferred, and transfer-related optimization effects (Yosinski et al. 2014).

In Google’s controlled validation study (Gulshan et al. 2016), transfer learning and a labeled dataset of 128,000 images produced an AUC14 of 0.99, with sensitivity of 97.5 percent and specificity of 93.4 percent at one operating point. The result demonstrates the potential of pretraining on general images followed by further training on retinal images under the study conditions; it does not by itself establish deployment performance. Reaching a result of this kind takes repeated training runs over the full labeled dataset, and the arithmetic cost of each run on the available hardware sets how many runs a team can afford, which is the iteration tax again in another form.

Gulshan, Varun, Lily Peng, Marc Coram, Martin C. Stumpe, Derek Wu, Arunachalam Narayanaswamy, Subhashini Venugopalan, et al. 2016. “Development and Validation of a Deep Learning Algorithm for Detection of Diabetic Retinopathy in Retinal Fundus Photographs.” JAMA 316 (22): 2402. https://doi.org/10.1001/jama.2016.17216.

14 AUC (area under the ROC curve): Measures the area under the receiver operating characteristic (ROC) curve plotting true positive rate vs. false positive rate across all classification thresholds, ranging from 0 to 1; 0.5 represents random discrimination, and values below 0.5 are possible. Unlike accuracy, AUC is threshold-independent and insensitive to class prevalence, making it a common metric for medical screening systems. The systems consequence: a model with 0.99 AUC can still produce unacceptable sensitivity at the specific operating threshold chosen for deployment, so AUC alone cannot validate deployment readiness.

Johnston, Casey. 2012. “Netflix Never Used Its $1 Million Algorithm Due to Engineering Costs.” Ars Technica, April.

Achieving high statistical accuracy on benchmark data is only the first hurdle, because edge deployment requires models to fit within strict memory allocations, execute within tight latency envelopes, and stay within thermal limits. Ensemble learning illustrates this tension between maximizing accuracy and fitting the deployment target. Combining predictions from multiple models routinely delivers top benchmark accuracy, yet inference compute, parameter storage, and memory traffic scale directly with ensemble size. Serial execution increases latency, while parallel execution demands additional hardware concurrency, so no fixed latency multiplier follows from ensemble size alone. The historic Netflix Prize demonstrated how ensemble complexity can block deployment: the winning solution delivered the highest predictive accuracy, yet Netflix never deployed it because the operational costs of maintaining and serving the ensemble exceeded the marginal business value (Johnston 2012). Even an ensemble of lightweight models multiplies orchestration complexity, working memory, and operational monitoring, so every architectural decision creates downstream systems ripples that accumulate at the physical deployment boundary.

3.7.1 Accuracy vs. efficiency

In diabetic retinopathy screening, missing an active case risks permanent vision loss, whereas misclassifying a healthy eye generates an unnecessary hospital referral. Because those two errors carry very different clinical costs, medical diagnostics require specialized statistical objectives15 rather than the generic average error that standard training minimizes. The system must maintain high sensitivity (\(>90\) percent) to catch pathology while preserving high specificity (\(>80\) percent) to avoid overwhelming regional healthcare infrastructure. These targets must also hold across diverse patient demographics, varying illumination, and distinct fundus camera models.

15 Medical AI performance metrics: This DR scenario sets a >90 percent sensitivity target because missed referable disease can delay care and contribute to avoidable vision loss; actual acceptance criteria are product- and regulator-specific. The subtler systems trap is positive predictive value (PPV): even a high-accuracy model can have low PPV in a low-prevalence population. This prevalence dependence can require different operating thresholds across deployment sites, a constraint invisible in standard ML evaluation.

↪ The probability outputs and cross-entropy losses that standard classifiers optimize are developed in Cross-entropy and classification loss functions.

16 Model compression pipeline: Bridging the gap between research accuracy and edge deployment requires an iterative “compress-validate-adjust” loop. Each compression step can reduce model size or execution cost, but it can also silently degrade sensitivity below the clinical threshold. Finding a model that fits in device memory while preserving clinical sensitivity typically requires multiple iterations because only the full validation suite reveals whether the smaller model still satisfies the problem definition.

Optimizing for clinical metrics alone remains insufficient if the resulting architecture cannot execute within the physical deployment envelope. In this scenario, running the model must remain strictly within the 500 MB memory reservation on the clinic’s shared 4–8 GB edge device. That budget must accommodate the static weight parameters alongside input buffers, dynamic activation tensors, and runtime execution overhead. Simultaneously, the accelerator must operate within the Orin Nano-class power envelope of 7–15 W and return each prediction within seconds. Balancing these competing pressures requires navigating the trade-offs of the iron law: shrinking parameter volume \((\DataVolume)\) and arithmetic operations \((\Operations)\), for example by storing each weight in fewer bits or removing parts of the model that contribute little, while continuously revalidating that the smaller model preserves clinical sensitivity.16 The accuracy in the cited study came from a larger Inception-family network, so whether a mobile backbone such as MobileNetV2 keeps that sensitivity is exactly what compression and validation must show. The capture resolution needed to see small hemorrhages also raises the backbone’s operation count above its figure at the default input size, so the 500 MB budget and the latency target must be checked at that resolution.

↪ Renegotiating accuracy against memory and latency envelopes through systematic pruning, quantization, and distillation is developed in Fitting the Deployment Budget.

The model that training produces is therefore a candidate, not yet the model that ships. Making it fit the clinic device is engineering work in its own right, and it acts on all three parts of the system. On the data side, training compute goes to the examples that teach the model the most (Data Selection). On the algorithm side, the trained model is made smaller and cheaper to run (Model Compression). On the machine side, its operations are mapped onto the accelerator so that the hardware’s peak rate is approached in practice (Hardware Acceleration). Each change is then measured against the budgets that problem definition fixed (Benchmarking). None of these steps can be skipped by training a more accurate model, because accuracy and fit are separate properties that the workflow must establish separately.

3.7.2 Constraint-driven development

An ML engineer who downsamples retinal images to standard \(224 \times 224\) ImageNet resolution to save compute will erase tiny microaneurysms before the network ever sees them. Avoiding that kind of blind spot requires domain experts (ophthalmologists in the DR case) at the table from initial exploration through final optimization to identify which lesions and image-quality details matter clinically. Without that domain knowledge, a model architect can easily choose an input resolution or receptive field, the input region each internal feature can see, that discards the diagnostic signal before training even begins. Working together keeps model architectures focused on clinically relevant evidence while respecting the compute limits identified during data collection.

Computational constraints shape how experiments are run. Each model variant, training setting, and preprocessing approach adds training runs, so exhaustive experimentation quickly becomes expensive. This economic reality drives investments in scheduling runs so accelerators do not sit idle, reusing intermediate results instead of recomputing them, and stopping runs that are clearly not improving. Searching training settings systematically, with disciplined experiment design, reduces computation relative to exhaustive search.

The inherent uncertainty of ML outcomes demands scientific methodology: controlled variables through fixed random seeds and environment versions, systematic ablation studies17 to isolate component contributions, confounding factor analysis to separate architecture effects from optimization effects, and statistical significance testing across multiple training runs using paired offline tests rather than the A/B testing18 reserved for comparing models on live production traffic. Without this rigor, teams cannot distinguish genuine performance improvements from statistical noise, a distinction that becomes critical when a model sits near the clinical sensitivity threshold. The test set must then contain enough confirmed positive cases that the lower bound of the confidence interval, not the point estimate, clears the floor.

17 Ablation studies: Named for surgical tissue removal, ablation studies systematically disable individual components to isolate their contribution to performance. The rigor matters because a 0.5 percentage-point sensitivity difference can determine whether the DR model meets its clinical sensitivity threshold. Without ablation, a team cannot distinguish a genuine architectural improvement from noise introduced by a different random seed, wasting iteration cycles on gains that are not real.

18 A/B testing in ML: Compares a new model (B) against the production baseline (A) on randomly assigned live traffic to estimate the model’s causal effect. Required sample size depends on the baseline event rate, effect size, variance, allocation, significance level, and statistical power (Kohavi et al. 2020); no universal interaction count or duration follows from a 0.5 percentage-point change alone.

Kohavi, Ron, Diane Tang, and Ya Xu. 2020. Trustworthy Online Controlled Experiments: A Practical Guide to A/B Testing. Cambridge University Press. https://doi.org/10.1017/9781108653985.

At every development milestone, teams validate models against the deployment constraints identified in earlier lifecycle stages. Each architectural innovation must be evaluated for accuracy improvements and compatibility with edge device limitations and clinical workflow requirements. This dual validation approach ensures that development efforts align with deployment goals rather than optimizing for laboratory conditions that do not translate to real-world performance.

3.7.3 Prototype to production

A small team of data scientists can often coordinate exploratory experiments using ad hoc scripts, spreadsheets, and shared notebooks. As projects evolve from prototype to production, however, complexity expands across multiple dimensions simultaneously: datasets grow, models require distributed training across accelerator clusters, and multiple engineers launch concurrent runs. Under these conditions, informal coordination rapidly becomes a development bottleneck. Without shared infrastructure, team members inadvertently train on conflicting data splits, duplicate expensive preprocessing passes across separate machines, overwrite shared model checkpoints, and struggle to reconcile divergent notebook versions. The time required to untangle conflicting artifacts and unrecorded configurations begins to dominate development.

Shared workflow platforms resolve this coordination friction by standardizing stage interfaces and centralizing resource management. Rather than relying on manual handoffs and uncoordinated scripts, a shared platform provides standardized data partitioning, cached preprocessing pipelines that compute intermediate representations once for the entire team, and automated job schedulers that allocate cluster accelerators efficiently. Shared platforms also track experiment metadata systematically, linking code revisions to exact training configurations, hyperparameters, and resulting evaluation metrics. Operating at scale therefore requires teams to systematically preserve each experiment’s inputs, software dependencies, and execution configuration, establishing the baseline needed to verify genuine improvements.

3.7.4 Reproducibility and system artifacts

Shared infrastructure accelerates experimentation only if its results can be trusted. If a candidate model beats the validation baseline by a full percentage point on Tuesday, but rerunning the same training script on Thursday falls short, the team cannot tell whether the gain was real or a fluke of thread scheduling and unrecorded library versions. Reproducibility, the ability to rebuild a result and bound how much it varies from run to run, is what lets a team distinguish a genuine improvement from noise. Its absence is an economic cost as well as a scientific one, because a team that cannot reproduce a result reruns experiments that may not converge to the same outcome, and each unreproducible result adds to the system’s technical debt.19

19 ML artifact interdependence: ML artifacts are deeply interdependent. A model’s measured accuracy is tied to the data version, preprocessing pipeline, and hyperparameter configuration used to produce it. Without lineage tracking, the team may not be able to determine whether a regression stems from code, data, or run-to-run variation, forcing expensive reruns of experiments whose provenance is lost.

↪ The technical debt that accumulates when experiments and artifacts go untracked, and the practices that contain it, are developed in Technical Debt.

Reproducing ML results requires tracking data versions, random seeds, hardware configurations, and library versions alongside program logic, because the hardware itself introduces run-to-run variation. When parallel accelerator threads add up partial results during training, the order in which partial sums arrive can differ from run to run, and floating-point addition is non-associative (\((\FirstFloatingPointAddend+ \SecondFloatingPointAddend) + \ThirdFloatingPointAddend\neq \FirstFloatingPointAddend+ (\SecondFloatingPointAddend+ \ThirdFloatingPointAddend)\)), so identical code can produce slightly different weights. Optimized math libraries may also benchmark several compute kernels (the routines that execute an operation such as a matrix multiplication on the accelerator) at runtime and select different ones across runs or machines unless deterministic execution is explicitly requested. Recording a random seed alone therefore does not establish reproducibility; the execution configuration and the measured variation across repeated runs matter as well, a requirement that Reproducibility extends to benchmark reports. Systematic experiment tracking records unique run identifiers and links data versions, code commits, hyperparameters, and resulting models, so a team can reconstruct what changed between two runs.

Experiment tracking needs a well-defined unit to version, and that unit is the stage’s actual deliverable. A common failure mode is treating the trained model weights as the sole output of model development. In a mature ML workflow, the deliverable is a reproducible system artifact whose inference package has four components:

  • Model weights: The learned parameters.
  • Inference code: The exact code used to run the model, including preprocessing logic.
  • Environment specification: The complete dependency graph (for example, a container image, requirements.txt, and accelerator drivers) required to execute the code.
  • Configuration: Hyperparameters and runtime settings.

Reproducing inference and rebuilding a trained candidate require different evidence. Alongside the inference package, the artifact must link to the dataset version, training-code version, preprocessing recipe, training configuration, and execution environment that produced the weights. Under the data-as-code invariant (principle 1), a changed training set changes learned behavior as surely as changed inference code does. This provenance makes the training procedure repeatable; the nondeterminism described earlier still requires checking variation across runs rather than promising identical weights.

The environment belongs in the bundle because dependency mismatches do not always fail loudly. An unsupported driver or a missing library stops the serving process at once, whereas a different linear algebra library or image-resizing routine (OpenCV rather than PIL, for example) can alter floating-point results or pixel interpolation without any crash, shifting model outputs and accuracy. A model that meets its sensitivity target in development must therefore be reevaluated if its production environment changes, even when inference completes without an exception. Packaging a reproducible artifact still establishes only that the candidate runs consistently as built; the next stage tests whether it holds up under the clinical conditions it will actually encounter.

Self-Check: Question
  1. According to the chapter, which bundle of deliverables constitutes the inference package of a reproducible system artifact from the Model Development and Training stage, and why are model weights alone insufficient?

    1. A. Model weights, inference/preprocessing code, environment specification (e.g., container or locked dependency graph), and runtime configuration; weights alone fail because library version mismatches or preprocessing differences alter outputs without crashing.
    2. B. Model weights and a serialized training log; the execution environment can always be inferred from the framework version tag.
    3. C. Model weights, a test-set evaluation scorecard, and an architecture diagram; deployment engineers reconstruct dependencies during serving containerization.
    4. D. Source code repository commits and hyperparameters; weights can be deterministically reproduced from random seeds on any hardware.
  2. Explain why a competition-winning 50-model ensemble that achieves state-of-the-art accuracy on a benchmark may be discarded for production edge deployment, citing the Netflix Prize as an empirical reference.

  3. In the chapter’s Iteration Tax scenario, a team compares Model L (large ensemble, starts at 95% accuracy, 1-week training cycle, +0.15% gain/iter) with Model S (lightweight model, starts at 90% accuracy, 1-hour training cycle, +0.1% gain/iter, 100 effective iters) over a 26-week window with a 99% ceiling. What is the modeled outcome after 26 weeks, and what systems lesson does it demonstrate?

    1. A. Model L reaches 99.0% while Model S reaches 92.6%, proving that starting accuracy dominates iteration speed over six months.
    2. B. Model S reaches the 99.0% ceiling while Model L reaches 98.9%, so both end near the ceiling; the lasting difference is that the fast-cycle team tests about four times as many ideas.
    3. C. Both models reach exactly 95.0% accuracy because human hypothesis generation saturates at 26 experiments regardless of training speed.
    4. D. Model L fails to converge due to training instability, while Model S converges to 90.0% without improvement.
  4. A team observes that model validation accuracy drops 2 percent between run 47 and run 48. Explain how an automated experiment tracking lineage record helps investigate this regression compared to an ad hoc notebook workflow.

  5. Arrange the following model development milestones in a plausible order for a constraint-driven ML workflow, where each milestone uses the outputs of the one before it: (1) Baseline transfer-learning fine-tuning from pretrained weights, (2) Physical constraint profiling (target latency, memory ceiling, power envelope), (3) Systematic ablation studies to isolate component contributions, (4) Model compression (pruning/quantization) and hardware-in-the-loop latency validation, (5) Packaging weights, preprocessing code, dependencies, and configuration into a reproducible system artifact.

See Answers →

3.8 Stage 4: Evaluation and Validation

Suppose the DR team’s candidate matches the study’s AUC of 0.99 on curated research data. The team then tests it on images from a rural clinic where a nurse with two weeks of training operates a five-year-old fundus camera, and sensitivity falls well below the 90 percent target. The software executes without throwing an exception or returning an error code; the model’s learned features simply encounter pixel distributions distorted by optical blur, low illumination, and variable pupil dilation that never appeared in the training distribution. High accuracy on curated test partitions does not guarantee operational reliability in production. Before deployment, trained models must pass through systematic evaluation and validation gates to verify that they satisfy accuracy, latency, and robustness requirements across realistic deployment conditions. This stage transforms raw checkpoint files into production-ready software systems by measuring behavior against predefined operational thresholds.

Definition 3.3: Model validation

Model validation is an evidence gate for deciding whether a trained model is suitable to deploy for a specified use. It tests the model against deployment constraints such as latency targets, subgroup performance targets, cost budgets, and robustness under distribution shift, but cannot certify safety under every possible condition.

  1. Significance: Validation adds dimensions that test-set accuracy ignores. A model achieving 95 percent accuracy on a static test set may miss a latency target, such as 100 ms in a web service, on its slowest requests, underperform a required subgroup threshold such as a maximum five percentage-point performance gap across demographic groups, or lose more than ten percentage points of accuracy under common image-quality problems such as blur and glare. Each unchecked dimension is a deployment risk that compounds silently in production.
  2. Distinction: Evaluation measures model behavior using chosen datasets, metrics, and experiments, which may include out-of-distribution and subgroup tests. Validation assembles the broader evidence needed for a specified deployment decision, including system latency, throughput, robustness, operational readiness, and cost.
  3. Common pitfall: Treating validation as “one more test.” A model can pass the accuracy test and still fail the gate on latency, subgroup reliability, or cost.

Evaluation supplies measurements; validation uses them to decide whether the integrated software and hardware pipeline meets its intended deployment requirements. This deployment decision is broader than evaluation on a validation set, the data partition used to guide model selection. A separate test set supplies evidence after those choices are fixed; repeatedly using it to choose a model weakens its independence. Accuracy on held-out examples supplies only part of the release evidence, alongside tests of execution, robustness, and operational readiness. Metric thresholds, controlled production exposure, environmental stress tests, and any required regulatory qualification address complementary risks, with the evidence and sequence determined by the intended use. The measurement methodology behind these gates is developed in Benchmarking.

3.8.1 Evaluation metrics and thresholds

In a screening clinic where 90 percent of patients have healthy eyes, a model that labels every image “normal” scores 90 percent accuracy while missing every case of disease. Evaluation metrics must therefore reflect the actual clinical consequences of each kind of error. In diabetic retinopathy screening, the evaluation reports sensitivity and specificity separately, with sensitivity above 90 percent limiting missed disease and specificity above 80 percent limiting false-positive referrals. Neither requirement alone establishes adequate clinical performance or referral capacity; that judgment also depends on disease prevalence, screening volume, and available care. The ROC curve summarizes how detection and false-positive rates change as the classification threshold varies. Evaluation must determine whether any threshold satisfies both requirements under the intended operating conditions.
Plot with specificity on the horizontal axis and sensitivity on the vertical axis. A red dashed horizontal line marks sensitivity above 90% and a red dashed vertical line marks specificity above 80%; the upper-right corner beyond both lines is shaded gray and labeled Pass. An illustrative dark curve falls from high sensitivity at low specificity to low sensitivity at high specificity, and briefly passes through the Pass corner.

Sweeping the threshold traces one illustrative curve; it must reach the corner where both floors hold.

Even separated into sensitivity and specificity, overall numbers can hide local failures. Stratified evaluation splits the test set across patient age brackets, chronic conditions, and clinic camera models to check whether accuracy holds across every subgroup. A DR model with 94 percent overall sensitivity may fall below 80 percent on images captured from patients with cataracts or under low clinic lighting. Those local drops stay hidden in overall averages and surface only as missed diagnoses after launch unless automated evaluation checks each subgroup slice before promoting a candidate checkpoint.

Beyond label accuracy, evaluation must measure probability calibration:20 whether a model’s predicted confidence score matches how often it is actually right. Modern deep neural networks often produce uncalibrated probabilities, reporting high confidence (\(>90\) percent) even on wrong or out-of-distribution predictions (Guo et al. 2017). When automated triage routes borderline cases to human specialists based on confidence cutoffs, overconfident errors send the wrong cases through without review and erode clinician trust.

20 Calibration: A calibrated model’s predicted probabilities match observed frequencies: 80 percent confidence should correspond to 80 percent correctness. Calibration is distinct from accuracy, and the systems consequence for the DR system is severe: clinicians use confidence scores for triage decisions, so a miscalibrated model that assigns 90 percent confidence to uncertain cases can misdirect clinical workflows more dangerously than a less accurate but well-calibrated alternative. Recalibration after training can improve it, but its effect must be evaluated on representative data.

Guo, Chuan, Geoff Pleiss, Yu Sun, and Kilian Q. Weinberger. 2017. “On Calibration of Modern Neural Networks.” International Conference on Machine Learning (ICML) 70: 1321–30.

↪ How calibration is measured, and the recalibration methods that improve it, are developed in Confidence calibration.

3.8.2 Offline and online evaluation

The validation gate begins offline on static datasets and progresses incrementally toward live production traffic. Accuracy-only evaluation on held-out test partitions establishes predictive behavior but does not exercise bursty concurrency, network serialization, or telemetry overhead. Offline load tests and replay can expose such systems bottlenecks when they reproduce the relevant conditions; live traffic supplies additional evidence about the deployed environment. For a centralized service, online evaluation extends the gate to live traffic through staged rollout:21 shadow mode mirrors live requests to the candidate and logs its predictions without returning them, a canary returns the candidate’s predictions to a small fraction of traffic, and an A/B test splits traffic between candidate and baseline to measure whether the improvement reaches clinical or business outcomes. In a regulated medical device, splitting patients between models is a clinical study that requires ethical approval, and changing a cleared model requires regulatory change control. This staged rollout workflow manages deployment validation risk, which is distinct from the cross-tier model compression pattern termed progressive deployment in Splitting work across tiers: Three integration patterns, and each validation stage adds a different kind of operational evidence (table 3).

21 Staged rollout: Coverage depends on traffic, observability, duration, and the failure modes exercised, so staged rollout reduces risk without guaranteeing that it catches a fixed share of production issues.

↪ Shadow and canary releases, the production form of this staged rollout, are developed alongside blue-green switching in Model deployment.

Table 3: Staged Validation Coverage: The stages provide complementary, overlapping evidence rather than partitioning failures into exclusive classes.
Validation stage Typical evidence it adds
Offline evaluation Algorithmic behavior
Shadow mode Integration behavior
Canary deployment Limited-traffic behavior
A/B testing Comparative outcomes

The gates must also run where the model runs. In the DR scenario, intermittent connectivity and local execution move these evidence gates to clinic devices and pilot sites. Teams can compare a candidate against recorded clinic inputs, run it alongside the active model where device resources permit, and introduce an approved update at a small group of clinics before expanding the rollout. The workflow must preserve the evidence and exposure limits of each gate while adapting its implementation to the deployment target.

3.8.3 Production-condition validation

A model evaluated on one clinic’s images still needs evidence for the other cameras, capture conditions, and patient populations specified during problem definition. Production-condition validation tests these requirements across site heterogeneity, input-level perturbations, and temporal drift. These dimensions apply within the offline and controlled-production gates in section 3.8.2; they are not stages that begin after live A/B testing. Held-out samples from the training distribution alone cannot supply all of this evidence.

External and multisite validation test whether the model has learned generalizable disease features or merely memorized the quirks of the development hospital’s cameras. In retinal screening, sensor sensitivity, lens coatings, and flash color differ across camera vendors. A DR model trained exclusively on images from high-end fundus cameras in research hospitals can fail when deployed to community clinics using older hardware. Multisite validation therefore benchmarks candidate models on data collected across independent clinic sites with different cameras, lighting conditions, and operator experience levels.

Robustness testing shifts focus to individual inference requests, checking how the model handles realistic image flaws and edge cases. For computer vision pipelines, these flaws include sensor noise, optical blur, uneven contrast, and partial pupil occlusions. As in the Thai clinics of the running case, dim room lighting and undilated pupils produce images the system rejects as ungradable. Testing models against both synthetic and real-world degraded images reveals whether the serving pipeline needs an upstream image-quality check to reject unusable frames before spending accelerator cycles on inference.

Temporal validation tests whether the model keeps its accuracy as the clinic environment changes over weeks and months. Test sets drawn from a single historical window miss later shifts in patient demographics, disease prevalence, or clinic referral habits. When the input distribution changes while the relationship between inputs and labels stays the same, the system faces covariate shift (Quiñonero-Candela et al. 2009); when the relationship between input features and clinical diagnoses itself changes, it faces concept drift (Gama et al. 2014). Both can cause silent model degradation and motivate the continuous telemetry and drift detection pipelines described in section 3.10.

Quiñonero-Candela, Joaquin, Masashi Sugiyama, Anton Schwaighofer, and Neil D. Lawrence, eds. 2009. Dataset Shift in Machine Learning. Neural Information Processing Series. The MIT Press.
Gama, João, Indrė Žliobaitė, Albert Bifet, Mykola Pechenizkiy, and Abdelhamid Bouchachia. 2014. “A Survey on Concept Drift Adaptation.” ACM Computing Surveys 46 (4): 1–37. https://doi.org/10.1145/2523813.

↪ Statistical tests that detect covariate shift and concept drift in production are developed in Data drift detection and response.

3.8.4 Regulatory validation

Healthcare AI systems face device- and pathway-specific validation requirements. When U.S. Food and Drug Administration (FDA) premarket review is required, the safety and performance evidence must be appropriate to the device and its regulatory pathway; clinical data are required for some submissions, though not all.22 In practice, domain-specific validation goes beyond paperwork compliance to test clinical usefulness and safe failure behavior. For diabetic retinopathy screening, clinical validation studies run the automated system alongside licensed ophthalmologists, comparing model classifications against ground truth established by specialist consensus panels. These studies must demonstrate both specialist-level diagnostic accuracy and safe failure modes: systems that fail safely, by routing ambiguous or low-confidence images to human specialists, fit into clinical care, whereas systems that fail silently produce missed diagnoses that no one catches until patients lose vision.

22 FDA AI/ML regulation: FDA marketing authorization requires evidence appropriate to the device, intended use, risk, and regulatory pathway. The FDA’s 2021 action plan for AI/ML-based software as a medical device (SaMD) identified lifecycle management, real-world performance monitoring, and predetermined change control planning as central issues for adaptive medical-device software (U.S. Food and Drug Administration 2021). These concerns make model versions, training provenance, monitoring, and change documentation important workflow artifacts without imposing one identical audit artifact at every lifecycle stage.

Human factors validation tests how the model fits into the clinic staff’s daily decisions. Even an accurate model will be turned off or bypassed if its interface confuses nurses, its inference latency slows down patient intake, or frequent false alarms cause alert fatigue. Validation studies must therefore measure how staff and system work together (tracking how often clinicians override the model, how long an exam takes from capture to referral, and how closely referrals match specialist diagnoses) alongside raw statistical accuracy.

3.8.5 Deployment readiness

Passing the validation gate produces an immutable release manifest recording the evidence and approval for a particular model version, intended use, and operating conditions. This manifest records the exact model checkpoint hash, preprocessing container configuration, calibration parameters, benchmark scores across designated demographic and equipment slices, and any required regulatory authorization. The manifest binds the release to that evidence; it does not itself confer external authorization or establish performance outside the evaluated conditions. If a model fails to clear an established threshold, such as p99 serving latency (the latency that 99 percent of requests stay under) exceeding the service level agreement (SLA) budget or sensitivity on low-light fundus images falling below the safety floor, the release gate halts deployment. Diagnostics then route backward to the responsible lifecycle stage: data curation for targeted data collection, model training for loss function re-weighting, or runtime optimization to reduce execution cost.

Clearing the validation gate establishes the evidence and approval for a particular system configuration. Deployment must install and sustain that configuration at each clinic, including its preprocessing routines, compiled model, telemetry collectors, and rollback triggers. Rollout checks confirm that the installed serving path matches the evaluated conditions and that local integration has not invalidated the release evidence.

Self-Check: Question
  1. What is the primary conceptual distinction between Model Evaluation and Model Validation as defined in this chapter?

    1. A. Evaluation is conducted by internal software engineers, whereas validation is conducted exclusively by government regulatory agencies.
    2. B. Evaluation tests software execution speed on accelerators, whereas validation tests algorithm mathematical convergence on CPUs.
    3. C. Evaluation measures model behavior on chosen datasets and metrics; validation is a multi-dimensional evidence gate confirming the model satisfies all operational, latency, subgroup fairness, robustness, and cost constraints under production-representative conditions.
    4. D. Evaluation is performed on live production traffic, whereas validation is performed exclusively on synthetic offline data.
  2. A diabetic retinopathy screening model achieves 94 percent aggregate accuracy on held-out validation data. However, stratified evaluation reveals that sensitivity drops to 76 percent for patients with cataracts and falls below the 90 percent sensitivity floor for one demographic subpopulation. How should the engineering team respond?

    1. A. Proceed to full deployment immediately, because aggregate accuracy above 90 percent statistically compensates for minor subpopulation variations.
    2. B. Apply post-hoc temperature scaling to increase overall prediction confidence, which automatically resolves subgroup sensitivity deficits.
    3. C. Deploy the model in shadow mode permanently, since shadow mode bypasses clinical subgroup safety requirements.
    4. D. Block deployment, because the model violates non-negotiable clinical sensitivity safety thresholds for vulnerable subgroups; stratified validation exists precisely to prevent aggregate metrics from masking localized clinical harm.
  3. Explain why a medical diagnostic model with an outstanding Area Under the ROC Curve (AUC) of 0.99 on a research dataset may still fail deployment validation for clinical screening.

  4. Order the stages of progressive online validation from lowest initial user risk to broadest comparative evaluation: (1) Canary deployment exposing 1–5% of live traffic, (2) Offline evaluation on held-out and stratified test sets, (3) A/B testing comparing outcomes against the production baseline, (4) Shadow mode running in parallel on live requests without serving predictions to users.

  5. True or False: Model calibration—ensuring that a predicted confidence score of 0.80 corresponds to an empirical 80 percent probability of correctness—is critical for medical AI systems because clinical triage workflows rely directly on confidence scores to route ambiguous cases to human specialists.

See Answers →

3.9 Stage 5: Deployment and Integration

A model that passes validation in development faces different failure modes once deployed to production. In the DR scenario, the model must run on Orin Nano-class edge devices in rural clinics with intermittent connectivity, integrate with hospital information systems with distinct schema requirements, and deliver predictions clinicians can interpret directly. The in-visit requirement already ruled out round-trip cloud inference. Deployment is where abstract operational constraints become physical systems requirements. In iron-law terms, the serving path couples data movement, execution efficiency, and fixed overhead together; on the clinic device, the 500 MB memory reservation is the precondition every candidate must meet, and per-image latency then sits comfortably inside the seconds-scale budget. Dedicated serving infrastructure manages these trade-offs under live traffic, and Model Serving develops it in depth.

3.9.1 Deployment requirements

Deployment turns an abstract computation graph into hard physical budgets: peak memory footprint, execution latency, heat limits, and network bandwidth. In the clinical screening scenario, feasibility settles the choice between centralized cloud serving and local edge execution before cost is weighed, because the in-visit latency target and offline operation fixed during problem definition already rule out a cloud round trip. Cost serves only as a check. Napkin math 3.3 applies the comparison of capital expense against recurring operating expense from Cloud ML trade-offs and constraints at network scale to confirm that the feasible option also pays back.

Napkin Math 3.3: Cloud vs. edge deployment economics
Problem: The cloud option fails the clinic’s stated latency and connectivity requirements, so treat it as a cost benchmark only. Compare the total cost of ownership and operational trade-offs between a cloud inference endpoint and clinic edge devices for processing 760,000 billable screening images monthly across 500 clinics. Where the bandwidth calculation in napkin math 3.2 sized one busy clinic uploading every photograph, this network-wide estimate assumes an average clinic at 50 patients/day and bills one graded image per patient rather than every capture, so its image volume is lower by design.

Option A: Cloud inference.

  • Model runs on centralized GPU servers
  • Inference cost: ~$0.01/image (cloud GPU time + API overhead)
  • Annual inference cost across 500 clinics, 50 patients/day, 1 billable image per patient, 365 days/year, and $0.01/image is $91,250/year
  • Plus: An assumed connectivity and network-operations allocation for uploading 5 MB per billable image = ~$45,000/year
  • Total: ~$136,250/year operational cost
  • Risk: uploading one 5 MB image over the clinic’s 2 Mb/s uplink alone takes about 20 s, before 200 ms+ of remote processing, far beyond the scenario latency target; connectivity outages halt screening

Option B: Edge deployment on a clinic device.

  • One-time hardware: one $500/device per clinic across 500 clinics requires $250,000 capital expense
  • Inference cost: ~$0.001/image (assumed all-in variable operating allocation)
  • Annual cost: approximately $25,000/year maintenance plus approximately $9,125/year variable inference cost, for about $34,125/year
  • Total: $250,000 upfront + ~$34,125/year
  • Benefit: latency below 50 ms; works offline; much lower per-inference cost

Math:

  • Annual savings: $136,250/year (cloud) − $34,125/year (edge) = $102,125/year
  • Payback: $250,000 (hardware) ÷ $102,125/year = ~2.4 years

Systems insight: Under these scenario assumptions, edge deployment pays back in ~2.4 years and allows inference during connectivity outages, yet it requires tighter model optimization (must fit in edge memory) and more complex update pipelines. The deployment paradigm selected during Problem Definition determines whether the edge option is even viable.
Two straight lines of cumulative cost over time, in dark and medium gray: edge starts high with a shallow slope, cloud starts at zero with a steep slope, and they cross at a dot marked approximately 2.4 years.

Edge costs more up front, but cloud’s running cost passes it in about 2.4 years.

In this scenario, bandwidth limits, latency targets, and offline operational requirements favor edge deployment, which dictates strict memory, latency, and thermal envelopes that model compression must satisfy and serving runtimes must execute within production bounds. Host integration extends these physical constraints to the software interfaces of existing clinical infrastructure, where the inference runtime exchanges data with hospital information systems (HIS) to ingest patient records and record diagnostic output. Because prediction scores do not automatically provide reliable uncertainty estimates, their interpretation must be evaluated on representative data before an interface contract uses them to route decisions. This contract specifies which classifications trigger automated referrals and which demand physician review, including how rejected or low-quality inputs are handled, so a confidence threshold cannot be evaluated in isolation from the downstream workflow it triggers.

Regulatory frameworks place further structural constraints on this data lifecycle. Legal mandates such as data protection law (the Health Insurance Portability and Accountability Act, HIPAA, in the United States) govern data transmission and restrict whether production inference payloads can be persisted, linked to patient identifiers, or ingested into retraining pipelines. When compliance prohibits retaining raw inputs, continuous improvement cannot rely on passive telemetry logging, so privacy rules constrain ongoing model maintenance strategies rather than serving merely as a transport-layer security checklist (ML Operations).

3.9.2 Pilot to full deployment

Shipping a new screening model to 500 clinics at once would turn any undiscovered camera mismatch or schema bug into a network-wide outage. Production rollout therefore proceeds in stages to contain failures as the environment widens. Offline replay and synthetic test harnesses first verify schema contracts and concurrency limits without risking patient safety. Pilot deployments in a handful of clinics then expose the serving stack to real-world conditions absent from laboratory benchmarks: optical distortion across camera models, sensor noise under uneven clinic lighting, and differences in how staff position patients. Full-scale rollout broadens exposure to rare anatomical variations and uncommon pathologies. Catching those shifts requires continuous runtime monitoring rather than assuming validation distributions hold forever.

Scaling across hundreds of remote clinics brings hardware diversity and tight network limits across the fleet. Differences in local camera optics shift pixel distributions before inference even begins, requiring on-device input checks that reject out-of-spec captures on the spot. At the same time, narrow wide-area bandwidth rules out continuous weight updates or streaming high-resolution telemetry back to a central cluster. Clinic edge devices must instead run on their own, logging metrics locally and syncing state during scheduled maintenance windows.

Keeping the screener clinically safe requires calibrated uncertainty estimates rather than high average accuracy alone. When the model encounters a borderline retina, returning an uncalibrated score risks a missed diagnosis. Instead, the serving path uses human-in-the-loop routing, applying calibrated confidence cutoffs to send borderline cases to specialist ophthalmologists. This routing does two jobs at once: it protects patients in real time, and it creates a steady stream of high-value training examples. Specialist-graded borderline cases provide verified labels that feed back into later training runs, targeting the model’s hardest cases.

Keeping hundreds of clinic devices consistent requires versioned, immutable model packages and atomic updates. Client runtimes verify cryptographic checksums of compiled model binaries before loading new weights into memory, so a dropped connection during download cannot leave a clinic running a corrupted model. Deployment marks the shift from static offline evaluation to continuous operations, where telemetry checks whether real-world latency and predictions stay within their approved bounds.

Self-Check: Question
  1. A deployment model processes ~760,000 screening images per month across 500 rural clinics. Cloud inference costs $0.01/image plus $45,000/year for connectivity/network operations ($136,200/year total). Edge deployment requires a $500 device per clinic ($250,000 CapEx), $25,000/year maintenance, and $0.001/image ($34,120/year total OpEx). Treat cloud as a counterfactual cost benchmark because it fails the stated connectivity and latency requirements. Using these rounded annual-cost givens, what is the annual operating savings of edge deployment and its payback period?

    1. A. Approximately $102,080 annual savings with a payback period of approximately 2.4 to 2.5 years, while enabling offline operation during connectivity outages.
    2. B. The same annual savings with a payback period of ten years, making cloud deployment far more economical.
    3. C. The same annual savings with an immediate three-month payback period.
    4. D. Zero annual savings, because edge hardware maintenance costs exactly equal cloud inference fees at 500 clinics.
  2. Explain what integration requirements an ML screening score adds to a Hospital Information System (HIS) interface beyond recording a measurement with units, and why neither a sensor reading nor a model score establishes its own reliability.

  3. An edge-deployed vision device has a 100 ms total latency budget. Profiling reveals the following execution breakdown: on-device model inference = 15 ms, remote cloud lookup for patient metadata = 60 ms, and local serialization/HIS formatting = 40 ms (total = 115 ms). Assume a local cache contains valid, sufficiently fresh patient metadata and a lookup takes less than 1 ms without changing the other costs. Which engineering modification directly reduces the Iron Law fixed overhead (\(L_{\text{lat}}\)) term to meet the 100 ms budget?

    1. A. Prune the neural network weights to reduce on-device model inference time from 15 ms to 5 ms.
    2. B. Cache patient metadata locally on the device to eliminate the 60 ms remote network round-trip.
    3. C. Quantize the model from FP32 to INT8 to increase arithmetic intensity (operations per byte).
    4. D. Increase the GPU clock frequency on the edge device to accelerate tensor core processing.
  4. True or False: Phased deployment progressing from simulation to pilot clinics to full production rollout is recommended because each phase is designed to expose a distinct, non-overlapping class of system failures: simulation catches software integration and schema bugs; pilots catch real-world camera and workflow heterogeneity; and full production catches distributed concurrency contention and rare clinical tail cases.

  5. A deployment policy that automatically routes low-confidence or high-uncertainty model predictions to an expert specialist for manual review, while allowing high-confidence predictions to proceed automatically, is known as ____ routing.

See Answers →

3.10 Stage 6: Monitoring and Maintenance

Consider an illustrative case six months after a DR screening system launches. A clinic upgrades its fundus cameras, and the new equipment produces images with different color profiles. In this assumed outcome, the model’s sensitivity drops at that site because the pixel distributions it learned during training no longer match the images it receives; the monitoring team cannot establish that drop from the camera change alone. No code changed. The data drifted beyond the training envelope, and the model degraded silently. Where paired drift and outcome data support a local fit, the degradation equation (equation 1.1) describes the mechanism. The new color profile raises the statistical divergence \(\StatisticalDivergence\) between production and training images, and accuracy falls by roughly the fitted coefficient \(\FittedSensitivity\) times that divergence, with nothing in the serving logs to show it. ML systems can degrade through data drift even when their artifacts remain untouched. Deployment is therefore not the end of the lifecycle; it starts an ongoing operational phase. Monitoring provides the statistical telemetry to detect degradation, while continuous maintenance pipelines update models when evidence warrants it. The infrastructure that runs this phase in production is developed in ML Operations.

In this illustrative scenario, monitoring tracks performance across clinics to detect whether changing patient demographics, camera technology, or equipment degradation affects accuracy. Adding a new imaging modality such as optical coherence tomography would be a product change requiring new data, validation, workflow integration, and any applicable regulatory review rather than routine maintenance. Three feedback pathways guide update decisions: performance evidence can motivate targeted data collection, data-quality findings can prompt preparation changes, and confirmed model degradation can justify retraining or another intervention. Because clinics upload only diagnostic summaries in normal operation, those pathways need a data path of their own: a sampled set of images, sent during off-hours and labeled centrally, supplies the outcome evidence and the retraining data that summaries cannot. Drift thresholds initiate review; they do not select the remedy automatically.

↪ Divergence metrics and threshold conventions for measuring distribution drift are collected for reference in Measuring drift.

3.10.1 Production monitoring

Monitoring serves two audiences, technical teams tracking system health and clinical staff who need actionable findings. Because no validation set captures every production condition (the lab-to-field gap of section 3.6.1), initial deployment can reveal blind spots that laboratory validation missed.23 Clinics with older equipment may show accuracy decreases, and specific patient subgroups, such as those with proliferative retinopathy or cataracts complicating the fundus image, may see higher error rates. Monitoring infrastructure is therefore a deployment prerequisite rather than a post-launch addition, and its findings drive targeted data collection and model revisions.

23 Lab-to-clinic performance gap: Medical AI systems can experience substantial performance changes when camera models, image quality, patient populations, or operator workflows differ from development data; the gap arises because training data cannot capture the full diversity of production conditions. FDA has emphasized total product lifecycle oversight and real-world performance monitoring for AI/ML-enabled medical devices (U.S. Food and Drug Administration 2021), and device submissions may need evidence appropriate to the product’s intended use and risk.

U.S. Food and Drug Administration. 2021. Artificial Intelligence/Machine Learning (AI/ML)-Based Software as a Medical Device (SaMD) Action Plan. U.S. Department of Health; Human Services.

24 Population stability index (PSI) and Kolmogorov-Smirnov (KS) test: Two lightweight statistical methods for detecting distribution drift, developed in Quality through validation and monitoring (KS) and Data drift detection and response (PSI). The KS test measures maximum distance between empirical cumulative distributions. Both are cheap enough for frequent monitoring, but a detected input shift does not by itself prove an accuracy change; labels or other outcome evidence are needed.

A DR screening system, where missed referable disease can delay care and contribute to avoidable vision loss, demands continuous operational monitoring plus periodic performance evaluation when labels arrive. Teams establish quantitative thresholds for latency, accuracy, and data distribution stability. Lightweight statistical tests for comparing production distributions against baseline data (such as the population stability index and Kolmogorov-Smirnov test)24 trigger responses ranging from automated alerts to retraining reviews.

↪ Drift detection pipelines that run these tests against training baselines in production are developed in Feature distribution monitoring.

A production DR system can track four metric categories at different timescales. The following thresholds illustrate one scenario policy; clinical and operational teams must validate them for the intended product, population, and deployment environment.

  • Model performance metrics (requiring ground truth, available with delay): sensitivity (target above 90 percent, alert if the rolling average, pooled across sites until enough confirmed cases accumulate to resolve a drop of that size, falls below 88 percent), specificity (target above 80 percent, alert if it drops below 78 percent), and subgroup performance (alert if any demographic drops more than 5 percentage points below baseline).
  • Proxy metrics (available immediately, without ground truth): prediction confidence distribution (alert if mean confidence drops more than 10 percent relative to baseline), referral rate (alert if rate changes more than 15 percent from baseline), and image quality rejection rate (alert if more than 20 percent of images fail quality checks).
  • Operational metrics: Inference latency (p95 below 50 ms, alert if above 100 ms), throughput (alert if queue depth exceeds 50 images), and error rate (alert if more than 0.1 percent of requests fail).
  • Data stability metrics: Feature and prediction distributions compared with a baseline, with alerts when recent traffic moves outside the expected range.

The displayed alerts are urgent escalation thresholds, distinct from the acceptance targets. A measured target violation already opens a review of the affected site and system version. Neither threshold alone chooses retraining. The hierarchy matters because operational metrics surface immediate problems, proxy metrics flag possible model issues without ground truth, and labeled performance evidence arrives later.

For the camera upgrade, an immediate color-distribution alert supplies a signal and a site identifier, but until representative labels arrive the team holds evidence of changed inputs, not a measured sensitivity loss, and applies the previously approved exposure limits or alternative screening workflow. Reviewed referrals alone cannot supply those labels, because the routing policy selects which cases are reviewed. Whether the remedy turns out to be restoring a validated camera configuration or returning to data collection and model development, the fix re-enters the lifecycle at the stage that owns the defect and leaves through the same release gate, with a revised release manifest, before a controlled rollout.

That return path is the lifecycle loop, in which every production finding has an owning stage and a gate to pass again. Running the loop in production is a separate discipline, the operations loop that detects, diagnoses, decides, releases, and recovers. Its incident workflow, from severity classification to postmortem, is developed in Incident response for ML systems, and Retraining decision framework weighs a retraining against its compute and validation cost.

3.10.2 Maintenance at scale

Model updates return through the same release gate as the original model. For a regulated device such as the DR screener, staged rollouts must follow the approved change-control plan, and rollback mechanisms25 limit the damage when an update misbehaves. As the deployment scales from pilot sites to hundreds of clinics, monitoring must track global metrics and site-specific behavior together and maintain data lineage, the metadata trail linking production logs to data, code, and model versions. Lineage lets a team correlate a site-specific accuracy drop with the training experiment and data version behind it instead of reconstructing that link by manual forensic analysis, and regulators may require it.

25 ML rollback complexity: An ML model’s validity is coupled to the data distribution on which it was trained, not just its code. Because the data environment keeps changing, rolling back to an older model binary cannot restore the past data distribution, so the older model may also misbehave on today’s live inputs. Even a fast rollback is therefore a temporary containment step rather than a full restore.

Correlating production evidence with its causes sends work back upstream. Figure 5 maps those return paths across stages 2 through 6, drawing data collection and data preparation as separate boxes and omitting problem definition, which sits upstream of every path shown. In the diabetic retinopathy deployment, when model evaluation uncovers accuracy drops on older fundus cameras, the Data gaps path triggers targeted image collection from those specific clinics. Similarly, when validation across patient cohorts reveals lower sensitivity for patients with cataracts, the Validation Issues path motivates retraining with synthetic lens-opacity augmentations. In production, runtime telemetry routes along the Data Quality Issues and Performance Insights paths back into data preparation and collection whenever clinic hardware upgrades change how images look.
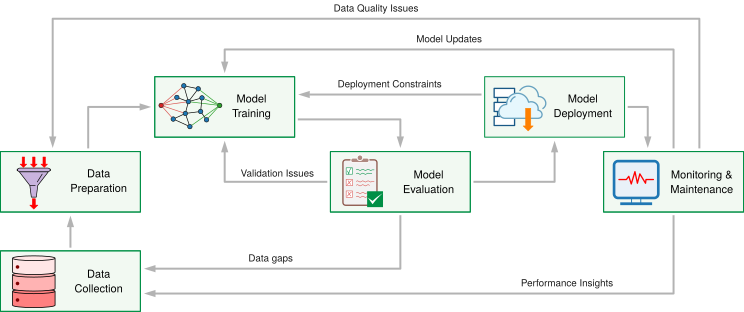
Figure 5: Feedback Paths Across Lifecycle Stages: Multi-stage feedback pathways show how downstream discoveries can require upstream corrections. Data-quality and distribution gaps detected during evaluation may prompt targeted collection or augmentation, while operational constraints and performance drift can motivate model, data, or pipeline changes after investigation.

Proactive maintenance closes the lifecycle loop. Operational signals identify potential problems, review determines whether newly validated data or another change is needed, and production evidence feeds back to refine problem definitions, data-quality standards, and architectural decisions. When retraining is selected, scheduled or evidence-triggered pipelines can incorporate approved data and return the candidate through validation. With the loop closed, the coupling among stages stops being a design-time concern and becomes a property of the running system, one whose consequences no single stage’s metrics reveal.

Self-Check: Question
  1. Why does production ML monitoring structure its telemetry into a four-tier hierarchy of operational, proxy, performance, and data stability metrics rather than relying on a single metric class?

    1. A. Because cloud monitoring vendors charge lower fees when metrics are divided into multiple dashboard tabs.
    2. B. Because operational metrics like latency and CPU load are sufficient to detect model accuracy degradation in real time.
    3. C. Because different failure modes emerge across different timescales: operational metrics catch service crashes in seconds, proxy metrics (confidence, referral rate) detect distribution shifts in hours without labels, and performance metrics (sensitivity, specificity) confirm diagnostic accuracy weeks later when ground truth arrives.
    4. D. Because ground-truth diagnostic labels are instantly available in real time for every inference request in production.
  2. Explain why reverting an ML system to an older model checkpoint during a production degradation incident is only a mitigation tactic rather than a true system state restoration.

  3. Six months after launch, a clinic network upgrades its fundus cameras to a newer model with a distinct color profile. System latency and server error rates remain perfectly stable at 0.0%, but clinical sensitivity drops from 92% to 77%. What systems phenomenon does this scenario illustrate?

    1. A. A deterministic crash in the GPU serving container caused by CUDA driver incompatibility.
    2. B. An adversarial perturbation attack executed against the clinic edge devices.
    3. C. Concept drift caused by a sudden biological mutation in the underlying disease pathology.
    4. D. Silent degradation caused by covariate/data drift; input pixel distributions shifted beyond the training envelope while traditional infrastructure monitoring showed healthy green dashboards.
  4. True or False: In production ML monitoring, lightweight statistical tests such as the Population Stability Index (PSI) and Kolmogorov-Smirnov (KS) test can detect shifts in input feature distributions, but an alert from these tests does not by itself prove that model classification accuracy has degraded until ground-truth outcome evidence is evaluated.

  5. Describe what metadata elements must be linked in an automated data lineage audit trail for medical ML systems, and explain how lineage reduces the engineering cost of investigating a site-specific accuracy regression.

See Answers →

3.11 Systems Thinking Across the Lifecycle

The camera-upgrade case that opened the monitoring stage touched every stage at once. A change in capture hardware at one clinic shifted the input distribution, degraded a model that had passed validation, and required routing evidence back through the lifecycle to identify and validate a remedy. The whole DR walk showed the same coupling: bandwidth, latency, and connectivity constraints favored edge deployment, edge deployment constrained model size, and model size reshaped preprocessing. Explaining coupled behavior of this kind requires systems thinking, which analyzes how a system’s parts interrelate rather than treating them in isolation. Three structural mechanisms account for most of it. The first, backward constraint propagation (section 3.2), has recurred at every stage handoff since it was defined. Multi-scale feedback organizes the different response times within that loop, while emergent behavior explains failures that no single stage or site can see. Managing all three distinguishes proactive, constraint-driven system design from reactive post-deployment debugging.

Checkpoint 3.3: Closing the feedback loop

Apply the monitoring response to a different source of uncertainty.

During monitoring, a clinic reports a changed referral rate for patients over seventy. Latency and image-quality rejection rates remain stable. Labels are available only for referred patients, and the release manifest contains no separate sensitivity evaluation for this age group. The intended-use requirements include these patients, but the evaluation plan omitted the subgroup.

3.11.1 Multi-scale feedback

ML systems succeed by orchestrating feedback loops across multiple timescales, each serving a different purpose. One illustrative operating plan for the DR scenario uses minute-level checks to catch a misconfigured camera before it produces a shift’s worth of unusable images; daily reviews for proxy shifts such as referral-rate, confidence, rejection-rate, or site-specific camera changes; weekly aggregation of labeled accuracy statistics and drift tests when ground truth is available; monthly analysis of population coverage; and quarterly review of whether the architecture still meets clinical needs. Actual cadences depend on label delay, product risk, traffic, and the cost of acting on each signal.
Vertical ladder of five gray bars on a log scale, longest at top: quarter, month, week, day, minute, spanning about five orders of magnitude in duration.

Monitoring loops span minutes to quarters, five orders of magnitude.

Each cadence matches how long its signal takes to become trustworthy. A misconfigured camera is visible within minutes, even if correcting it takes a site visit, whereas a demographic shift that calls for expanded training data takes months of monitoring to establish reliably. Reacting to short-term variance causes pipeline thrashing, such as retraining on transient shifts, while reacting too slowly lets silent accuracy decay persist.

3.11.2 Emergent behavior

In a multisite DR deployment, each individual clinic can report steady overall accuracy while network-wide analysis uncovers a sharp drop in sensitivity for a specific age group that no single clinic sees often enough to spot on its own. Complex systems produce emergent behaviors of this kind, which stay invisible when components or sites are inspected in isolation. Network timeouts and out-of-memory crashes expose some failures directly, but neither conventional nor ML systems can rely on exceptions to reveal every harmful outcome. ML monitoring must also investigate data drift, concept drift, and bias amplification, since predictive quality can decline without generating stack traces or runtime exceptions even while the model continues serving within its latency SLA. Together, constraint propagation across stage boundaries, multi-scale feedback timing, and emergent behavior show that ML systems cannot be engineered through modular decomposition alone, and teams that apply conventional software assumptions to these coupled dynamics fail in predictable ways.

Self-Check: Question
  1. A referral-rate change appears for patients over seventy, who are included in the intended use, but labels are available only for referred patients and the release manifest contains no separate sensitivity evaluation for this age group. What can the monitoring team conclude, what evidence must it obtain, and which artifacts should it review before selecting a remedy?

  2. In a multi-site distributed ML deployment spanning hundreds of clinics, why can system-wide emergent behaviors produce failures that are completely invisible when examining individual clinics in isolation?

    1. A. Because distributed communication protocols inject pseudo-random noise into inference predictions.
    2. B. Because local monitoring averages away subpopulation variance; an underserved demographic group that represents only 1–2% of patients at each clinic appears as statistical noise locally, but forms a significant, systematically failing population in aggregate.
    3. C. Because modern ML models are strictly non-deterministic on edge devices and deterministic in the cloud.
    4. D. Because individual clinics never experience data drift, which occurs only across wide-area networks.
  3. Arrange the following feedback loop cadences in order from shortest operating timescale (most rapid) to longest operating timescale (slowest): (1) Weekly aggregation of labeled accuracy metrics and statistical drift tests, (2) Minute-level operational health and image-capture focus checks, (3) Quarterly architectural review of model families and regulatory compliance, (4) Daily monitoring of proxy metrics such as referral rates and confidence distributions.

See Answers →

3.12 Fallacies and Pitfalls

Treating ML as ordinary software produces predictable failures, each of which traces back to a section of this chapter. The misconceptions below recur when teams manage statistical models with assumptions inherited from deterministic application code.

Fallacy: ML development can follow traditional software workflows without modification.

Software practices such as version control, unit testing, and iterative delivery remain necessary. Machine learning systems also derive behavior from data, so those practices must cover datasets, learned artifacts, and statistical performance evidence (table 1). In an ML workflow, problem definitions evolve as exploratory training reveals distribution gaps, class imbalances, or infeasible accuracy-latency trade-offs, and practitioners name data preparation as their largest time sink (section 3.3).

Pitfall: Treating data preparation as a one-time preprocessing step.

Teams often treat data cleaning and feature engineering as a static milestone to clear before training begins. In production, incoming data distributions evolve continuously as user behavior shifts, sensors degrade, and upstream schemas change. The two-tier lifecycle of figure 2 reflects this operational reality, with an upper data pipeline and a lower model pipeline that execute concurrently and feed back into each other. Early data preparation decisions cascade directly through training and deployment (section 3.6). When data preparation is static, silent distribution shifts and training-serving feature skew bypass code-level tests, degrading inference accuracy long before raising an operational alert. Continuous data validation pipelines with automated schema checking and distribution monitoring are necessary to catch data drift at ingestion rather than after silent model failure in production.

Fallacy: Passing model evaluation means the system is ready for deployment.

Model-only offline evaluation measures statistical loss on curated validation sets and leaves operational serving dynamics untested. Across the dual pipelines mapped in figure 2, an accuracy-only evaluation tests the candidate model without establishing serving integration, real-time input delivery, or operational monitoring. The diabetic retinopathy case (section 3.1.2) shows the disconnect, since a model with specialist-level accuracy on curated images rejected 21 percent of clinic images as ungradable and struggled with variable camera lighting, technician workflow interruptions, and intermittent network connectivity. Production readiness demands system-level verification, including tail-latency budgets under concurrency, feature pipeline consistency, and graceful degradation under hardware faults.

Pitfall: Scaling data collection before checking marginal model value.

Expanding dataset size is often assumed to be a universally profitable investment for boosting accuracy. Additional examples incur storage, ingestion, and labeling costs, but their learning value depends on which gaps they fill. Once a region of the input distribution is well covered, returns there diminish, and more examples of already well-covered cases may contribute little, while targeted collection can expose a failure that aggregate accuracy conceals. The upstream feedback loops in figure 2 route data fixes from curation back to collection before samples enter training, allowing observed errors and coverage gaps to guide acquisition. Because data quality decisions cascade through all downstream pipeline stages (section 3.6), teams must measure the marginal gain in the required task and subgroup metrics against the cost of collecting and processing additional data.

Fallacy: Skipping validation stages accelerates delivery.

Compressing or bypassing justified validation stages transfers unresolved risk to production traffic. Multi-stage validation (section 3.8) supplies complementary evidence across increasingly realistic execution environments, and no stage substitutes for another or for independent offline evaluation. A release plan should state the evidence required, the exposure permitted, and the conditions for stopping or reversing a rollout. A gate may be removed only when its evidence obligation is met another way.

Pitfall: Deferring deployment paradigm selection until after model development.

Teams often assume deployment targets can be selected after optimizing model accuracy. In practice, the deployment paradigm (Cloud, Edge, Mobile, or TinyML) is a primary constraint that shapes every preceding lifecycle stage (table 2). The day-153 failure is the canonical case, in which a model needing 4 GB reached deployment (stage 5) before anyone checked that the clinic device reserves about 500 MB for it. Deployment hardware dictates which models are physically realizable, not merely where they execute.

Self-Check: Question
  1. Why does the chapter characterize ‘scaling dataset size is always the best way to improve model accuracy’ as a major engineering pitfall?

    1. A. Because deep learning models degrade in accuracy when trained on more than \(10^5\) samples due to parameter saturation.
    2. B. Because collecting additional data increases the Operations (\(O\)) term during inference execution.
    3. C. Because additional examples can have poor marginal value in already well-covered regions, so collection and curation choices must be compared using observed gains in required task and subgroup metrics against their labeling, storage, and compute costs.
    4. D. Because data privacy regulations strictly limit training set sizes to under 100,000 images in healthcare applications.
  2. True or False: Deferring deployment paradigm selection (Cloud, Edge, Mobile, or TinyML) until after model architecture design and training are complete is an effective engineering strategy because modern model compression techniques can universally fit any trained model onto any target hardware without compromising accuracy.

  3. A team skips shadow-mode validation and canary deployment, relying entirely on strong test-set accuracy, although its release plan requires evidence of integration behavior, live-input latency, and limited-exposure operation. Why does skipping these unmet evidence obligations increase deployment risk and possible rework?

    1. A. Because skipping canary deployment causes compilers to emit unoptimized serving binaries.
    2. B. Because offline test sets are mathematically incapable of computing classification accuracy.
    3. C. Because modern cloud orchestrators refuse to route traffic to containers that have not completed shadow mode.
    4. D. Because strong test-set accuracy does not meet those integration and exposure obligations; unresolved failures may reach production and require investigation, containment, artifact repair, and renewed validation.

See Answers →

3.13 Summary

The day-153 failure in the running case was a workflow failure, and the six stages traced since show why it was predictable. Those six project responsibilities coordinate the finer-grained data and model pipelines. Within them, the data pipeline transforms raw inputs through collection, ingestion, analysis, labeling, validation, and preparation into ML-ready datasets, and the model development pipeline takes these datasets through training, evaluation, validation, and deployment to create production systems. The closed-loop return paths in figure 2, which link deployment telemetry back to collection and validation findings back to curation, show that production observations continuously reshape upstream pipelines rather than terminating at a deployment milestone.

Machine learning systems need additions to established software-engineering practice because ML workflows add probabilistic optimization, learned statistical behavior, and data-dependent feedback loops. The iron law supplies one quantitative lens: decisions across the lifecycle jointly change data movement, operation count, hardware efficiency, and fixed latency in \((\Time = \frac{\DataVolume}{\Bandwidth} + \frac{\Operations}{\PeakRate \cdot \EfficiencyHw} + \Latency)\), while production evidence feeds constraint violations back into review. Success depends on how data quality affects model performance, how deployment constraints shape training strategies, and how production insights inform each subsequent iteration.

Two patterns define the engineering discipline of the ML lifecycle. Many practitioners report data collection, cleaning, labeling, validation, or preparation as major time sinks, while model development is only one part of the lifecycle. Production-ready systems also require repeated iteration cycles across data, model, and infrastructure stages, so investment in data engineering can have high leverage when data quality is a major source of rework. Early constraint discovery does not require freezing the workflow. It establishes an operating envelope through latency, memory, power, safety, and validation obligations while data and model choices continue to iterate within those bounds.

Key Takeaways: See the whole map first
  • The lifecycle is a loop, not a checklist: Because an ML system’s behavior is learned from data, it can degrade while the code stays fixed, so production feedback is what makes the data and model pipelines a system. Monitoring, validation, and retraining send lessons from deployment back into collection, labeling, architecture, and infrastructure decisions.
  • Late constraints can increase rework: A deployment limit discovered late may invalidate preprocessing, weights, validation evidence, and integration work. Trace those dependencies and estimate the required tasks to bound the correction effort and delay.
  • Accuracy is not deployment readiness: A model can clear its offline accuracy target and still fail on latency, memory, subgroup sensitivity, calibration, or an unreproducible environment. Validation is a multi-dimensional gate whose release manifest records evidence for one specific configuration.
  • Iteration velocity expands search opportunity: Under the worked assumptions, a lightweight model starting 5 percentage points behind ends near the same ceiling as the large model while testing about four times as many ideas. Workflow speed buys search breadth rather than guaranteed model quality.
  • Interfaces make feedback actionable: Stage contracts define inputs, outputs, and quality invariants so that data, model, and deployment teams can detect violations before integration. Without explicit contracts, each stage can optimize locally while the system fails globally.
  • Production speaks on different clocks: Real-time inference monitoring, batch update reviews, and quarterly architectural reviews answer different failure modes. Treating all feedback as one loop either reacts too slowly to drift or churns expensive workflows without signal.
  • Workflow carries constraints through time: Problem definition records targets, data collection shapes evidence and byte volume, model development changes operations and reuse, deployment realizes the complete serving path, and monitoring sends violations back into review. The lifecycle is data-algorithm-machine coupling unfolding over time.

Seen as a checklist, the lifecycle is a sequence of stages to clear in order. Seen correctly, it is a loop. A constraint discovered at deployment does not stay there; it may force rework in dependent model and data decisions. A workflow is therefore a coupled system rather than a pipeline, the same coupling the D·A·M taxonomy describes in space, now unfolding in time. Optimizing one stage in isolation moves the failure instead of removing it. Workflow management reduces risk, and the discipline is to see the whole map before touching any single part of it.

What’s Next: From blueprint to data
The lifecycle is the blueprint for every chapter that follows, and its first material is data. In the DR project that means on the order of \(10^5\) graded fundus images, capture-quality checks at the camera, site provenance, and ingestion that survives a fragile uplink, needs particular to one deployment. Data Engineering takes up the stage in full on two workloads chosen to stress each of the bounds data places on a system. Data bounds a system twice, once through the coverage and labels that decide what the model can learn and once through the delivery rate that decides how fast the machine can learn it, and that chapter builds a pipeline that meets both bounds. Each later chapter assumes familiarity with where its techniques fit within this lifecycle.

3.14 Self-Check Answers

Self-Check: Answer
  1. Team A ships a diabetic retinopathy (DR) screening model and freezes all development once the model clears validation in the lab, treating subsequent tasks as standard server operations. Team B treats the launch as the beginning of an ongoing feedback loop, monitoring operational telemetry and data distributions to guide investigation and evidence-based model updates. Which team’s posture aligns with the ML lifecycle as defined in this chapter, and why?

    1. A. Team B, because the ML lifecycle is a closed loop where operational feedback, distribution drift, and real-world performance continuously reshape upstream data and model decisions.
    2. B. Team A, because once a model meets its offline validation thresholds, its statistical properties remain fixed and require only standard infrastructure maintenance.
    3. C. Team A, because changing a validated model in production introduces regulatory risk that outweighs the benefits of adapting to data drift.
    4. D. Team B, because the ML lifecycle mandates automatic daily retraining of production models regardless of whether input distributions have drifted.

    Answer: The correct answer is A. The chapter defines the ML lifecycle as an iterative, closed-loop engineering process where deployment is the start of the feedback loop rather than its conclusion. Production inputs, patient demographics, and equipment can shift even when code remains untouched, requiring continuous monitoring and evidence-based updates. The view that offline validation permanently freezes statistical behavior ignores real-world distribution drift. The claim that updates should be avoided due to regulatory risk misinterprets compliance frameworks, which mandate lifecycle management and change control. Furthermore, the lifecycle prescribes evidence-driven investigation and retraining when justified, not unconditional automatic daily retraining.

    Learning Objective: Classify post-deployment engineering practices against the chapter’s closed-loop lifecycle definition.

  2. In the running case’s day-153 failure scenario, a team spends five months developing a diagnostic model that reaches 94 percent sensitivity, only to have the entire project discarded on day 153. Explain the root cause of this failure from a workflow perspective and state the systems engineering rule that would have prevented it.

    Answer: The failure was a workflow breakdown caused by optimizing model accuracy in isolation while ignoring downstream physical constraints. The team discovered only after development that the clinic edge device, whose memory is shared with the operating system and camera pipeline, left the model a budget of about 500 MB, whereas the model required 4 GB. The systems engineering rule that prevents this is backward constraint propagation: physical deployment limits (memory, latency, power budgets) must be established at Problem Definition on day one and propagate backward to constrain feasible model architectures before development begins.

    Learning Objective: Explain how late discovery of deployment constraints invalidates isolated model development and forces backward propagation of physical limits.

  3. True or False: Traditional software workflows and ML lifecycles differ fundamentally because ML system behavior can degrade through data distribution drift over time even when application source code, execution environment, and hardware configuration remain completely untouched.

    Answer: True. Keeping code, environment, and hardware fixed does not guarantee correctness in either kind of system: conventional software can still fail because of bad inputs, external state, or changing dependencies outside that narrow boundary. The ML-specific risk is different: a deployed model learns a statistical relationship from training data, so shifts in real-world inputs can degrade accuracy even when those artifacts remain unchanged.

    Learning Objective: Compare how ML systems and traditional software differ in their sensitivity to changes in deployment data over time.

← Back to Questions

Self-Check: Answer
  1. Which interpretation of the Constraint Propagation Principle is consistent with the chapter’s treatment of discovering constraints late in the ML lifecycle?

    1. A. It holds that a late-discovered constraint can force rework across upstream stages, with the actual rework depending on which datasets, weights, validation evidence, and deployment packages relied on the missing constraint.
    2. B. It establishes a universal linear rule: each later lifecycle stage adds the same fixed amount of rework regardless of what artifacts were affected.
    3. C. It claims late-discovered constraints always force a complete rebuild of every downstream artifact, so the exact dependency structure does not matter.
    4. D. It implies correction cost generally falls in later stages because downstream telemetry makes fixes easier than catching the issue early.

    Answer: The correct answer is A. The chapter’s constraint propagation principle holds that a constraint discovered late can force rework across affected upstream stages, and that estimating the actual rework requires tracing which datasets, trained weights, validation evidence, and deployment packages depended on the missing constraint. The linear, always-rebuild-everything, and cost-decreases-over-time alternatives are false universal claims that contradict the chapter’s emphasis on dependency-sensitive rework.

    Learning Objective: Analyze dependent artifact rework and distinguish an assigned timing-sensitivity scenario from a project cost estimate.

  2. True or False: Constraints in the ML lifecycle propagate only backward, from deployment limits discovered late toward earlier stages.

    Answer: False. The chapter shows propagation in both directions. Backward propagation carries a deployment limit upstream, as when tight clinic bandwidth forces compressed inputs that the training data must then match. Forward propagation carries an early decision downstream: capturing fundus images at the resolution needed to see small hemorrhages fixes the model’s input size, and with it the operation count every inference must pay on the clinic device. The stages therefore form a network of constraints rather than a one-way chain.

    Learning Objective: Analyze how problem-definition constraints propagate through data, modeling, validation, and deployment.

  3. When a data quality failure introduced during data collection propagates downstream to cause compounding failures in model training, validation, and deployment, the resulting pattern is known as a(n) ____.

    Answer: data cascade. The chapter defines a data cascade as a chain of downstream failures triggered by bad data, the case of constraint propagation that travels specifically through data quality failures.

    Learning Objective: Explain data cascades as compounding downstream failure chains caused by upstream data quality defects.

← Back to Questions

Self-Check: Answer
  1. In the 2016 CrowdFlower data scientist survey cited in the text, respondents indicated that data-related tasks dominated their time, with 60 percent selecting ____ and organizing data as their largest time sink, compared to only 4 percent for refining algorithms.

    Answer: cleaning. Cleaning and organizing data accounted for 60 percent of most-time responses, and collecting datasets accounted for 19 percent. Most respondents therefore named one of these data activities as their largest time sink. These response shares do not measure the fraction of total engineering hours spent on each activity.

    Learning Objective: Analyze the primary empirical time sinks reported by ML practitioners in the chapter’s survey analysis.

  2. A DR team’s validation pipeline takes a full week per candidate model. Using the chapter’s iteration tax, explain what this slow loop costs the team beyond calendar time, and name the workflow mechanism the chapter proposes to keep late discoveries from multiplying that cost.

    Answer: A week-long loop limits how many candidate models the team can test in a fixed period, so the team explores a much narrower part of the design space and learns less about which data, preprocessing, and architecture choices matter. That lost search breadth is the iteration tax. Late discoveries amplify it, because a violation caught after deployment invalidates artifacts produced by earlier stages and forces retraining and renewed validation. The chapter’s remedy is explicit stage interface contracts that validate each stage’s outputs at its boundary, so violations surface where they are cheapest to fix.

    Learning Objective: Trace late-discovery rework through dependent data, model, validation, and deployment artifacts.

← Back to Questions

Self-Check: Answer
  1. Order the following lifecycle phases in the canonical sequence established in the chapter for a new ML system project: (1) Deployment and Integration, (2) Problem Definition, (3) Monitoring and Maintenance, (4) Data Collection and Preparation, (5) Model Development and Training, (6) Evaluation and Validation.

    Answer: The correct order is: (2) Problem Definition, (4) Data Collection and Preparation, (5) Model Development and Training, (6) Evaluation and Validation, (1) Deployment and Integration, (3) Monitoring and Maintenance. Each stage consumes artifacts and contracts produced by preceding stages: Problem Definition sets measurable objectives and physical constraints; Data Collection acquires and curates versioned datasets satisfying those constraints; Model Development trains candidate models within the computational budget; Evaluation and Validation gates models against stratified safety thresholds; Deployment and Integration delivers serving infrastructure meeting latency SLAs; and Monitoring and Maintenance tracks live operational telemetry and feeds drift evidence back into upstream stages.

    Learning Objective: Classify and sequence the six core ML lifecycle stages and justify the prerequisite artifact dependencies across stage boundaries.

  2. An engineering team completes Problem Definition with clinical sensitivity targets but marks the target deployment paradigm as ‘TBD — to be determined after model training.’ According to the Stage Interface Specification, what should the transition audit verdict be, and why?

    1. A. Approved, because decoupling model development from hardware targets allows researchers to maximize accuracy before applying post-hoc pruning.
    2. B. Approved with warning, provided the team commits to using cloud inference if the model exceeds edge memory budgets.
    3. C. Blocked, because Problem Definition’s output contract explicitly requires deployment paradigm and resource constraints to be established before data collection and modeling begin.
    4. D. Blocked only if the model architecture requires distributed multi-GPU training, since single-device models can adapt to any deployment target.

    Answer: The correct answer is C. The Stage Interface Specification says Problem Definition must produce measurable objectives, deployment paradigm selection, and resource constraints before downstream work proceeds. Leaving the target as TBD violates that gate because deployment constraints shape what data collection, preprocessing, and model choices are feasible. The chapter’s constraint-propagation discussion shows that late discovery can force rework across dependent artifacts, with the amount depending on which earlier outputs must be revisited. An answer based on unconstrained accuracy-first optimization ignores those early dependencies, and the cloud-fallback idea ignores that latency or connectivity requirements may already rule cloud out.

    Learning Objective: Apply stage interface contracts to audit lifecycle transitions and enforce early constraint binding.

  3. The chapter considers MobileNetV2 (about 14 MB of FP32 weights and ~600 MFLOPs per inference) as a candidate backbone for the DR clinic device, whose model budget was fixed at Problem Definition. Explain how choosing a model to fit that budget propagates across Data Collection, Model Development, and Evaluation.

    Answer: The memory budget fixed at Problem Definition reshapes all downstream stages. In Data Collection, images must be prepared at the input resolution the chosen backbone expects. In Model Development, it favors architectures built from cheap operators (such as depthwise separable convolutions) over dense convolutions or large ensembles; MobileNetV2’s ~600 MFLOPs per inference is what such a design costs, not the requirement itself. In Evaluation, on-device latency and memory footprint must be validated alongside sensitivity, and a missed latency target loops back to architecture or input resolution.

    Learning Objective: Explain how mobile hardware constraints propagate backward through Problem Definition, Data Collection, Model Development, and Evaluation.

  4. Which mapping between lifecycle stages and the terms in the Iron Law of ML Systems (\(T = \frac{D_{\text{vol}}}{\text{BW}} + \frac{O}{R_{\text{peak}} \cdot \eta_{\text{hw}}} + L_{\text{lat}}\)) is conceptually consistent with the chapter?

    1. A. Problem Definition exclusively determines \(R_{\text{peak}}\), and later lifecycle stages cannot materially affect hardware throughput or efficiency once the use case is chosen.
    2. B. Model Development and Training exclusively determines \(O\), while Data Collection and Preparation cannot affect bytes moved and Deployment and Integration cannot affect latency overhead.
    3. C. Deployment and Integration exclusively determines \(L_{\text{lat}}\), while earlier stages cannot materially affect operation count, data volume, or serving-path overhead once deployment begins.
    4. D. Data Collection and Preparation is diagnostically associated with bytes moved such as \(D_{\text{vol}}\); Model Development and Training is associated with computational work \(O\) and opportunities for reuse; Deployment and Integration is associated with serving-path overhead such as \(L_{\text{lat}}\), even though these influences are not exclusive.

    Answer: The correct answer is D. The chapter treats these stage-to-term links as nonexclusive diagnostic associations, not one-to-one ownership. Data Collection and Preparation strongly influences how much data must be stored and moved, Model Development and Training strongly influences computational work and reuse structure, and Deployment and Integration strongly influences serving overhead such as latency. The exclusive-assignment alternatives are wrong because the chapter explicitly teaches overlapping influences: data work can affect compute efficiency, model choices can affect bytes moved and latency, and deployment choices do not erase upstream effects on the other terms.

    Learning Objective: Apply the Iron Law of ML Systems as a diagnostic lens for how lifecycle stages most directly influence different system terms.

  5. To prevent defect propagation across lifecycle boundaries, the chapter formalizes each stage boundary using a(n) ____ contract, which defines required inputs, output deliverables, and non-negotiable quality invariants.

    Answer: stage interface. Stage interface contracts establish formal quality gates at each transition boundary in the ML lifecycle, ensuring that prerequisites (such as deployment paradigm selection or schema validation) are met before downstream engineering begins.

    Learning Objective: Explain the role of stage interface contracts as control-plane quality gates in ML workflows.

← Back to Questions

Self-Check: Answer
  1. Why does the statement ‘Build a computer vision model that detects diabetic retinopathy’ fail as a complete problem definition for an ML system?

    1. A. It specifies only a high-level task while omitting the statistical constraint layers (sensitivity/specificity floors across subgroups), physical constraints (edge device memory/latency budgets), and operational constraints (regulatory compliance, clinical workflow integration).
    2. B. It fails to specify which exact deep neural network backbone and learning rate schedule must be used during training.
    3. C. It defines an image classification problem when medical AI systems must always be framed as unsupervised anomaly detection tasks.
    4. D. It defines quantifiable objectives before data collection has occurred, which violates standard ML agile practices.

    Answer: The correct answer is A. An ML problem definition is not a one-sentence task label; it is a multi-constraint optimization problem spanning statistical layers (>90% sensitivity and >80% specificity across diverse populations), physical layers (inference on edge hardware within seconds of capture and under a 500 MB memory budget), and operational layers (FDA regulatory compliance, HIS workflow integration, patient privacy). Omitting these layers leaves downstream teams without the constraints needed to bound the design space. Specifying model backbones upfront inverts the workflow order, unsupervised anomaly detection is not mandatory for medical classification, and establishing quantifiable targets upfront is an essential requirement of the Problem Definition output contract.

    Learning Objective: Explain why complete ML problem definitions require layered statistical, physical, and operational constraints.

  2. Explain why ophthalmologists and clinic administrators must participate directly in Problem Definition for a DR screening system, rather than being consulted only during clinical evaluation.

    Answer: Engineers optimizing models in isolation tend to maximize aggregate accuracy, but clinical safety depends on domain-specific trade-offs that only medical experts understand. Ophthalmologists define the clinical penalty of false negatives (missed cases leading to blindness) versus false positives (overwhelming specialist clinics), translating medical needs into non-negotiable sensitivity (>90%) and specificity (>80%) floors. Clinic administrators identify physical and workflow constraints (such as returning a result before the patient leaves, older fundus cameras, and intermittent connectivity), ensuring engineering targets reflect real clinical operations from day one.

    Learning Objective: Justify the necessity of cross-disciplinary domain collaboration during Problem Definition to establish valid engineering constraints.

  3. In the 2018 Amazon automated recruiting war story cited in the chapter, an ML model trained on ten years of resumes was abandoned because it systematically penalized female applicants. What fundamental systems lesson does this case illustrate regarding Problem Definition?

    1. A. Resume screening models require recurrent neural networks rather than transformer architectures to avoid learning gendered proxies.
    2. B. Offline evaluation metrics are inherently incapable of measuring demographic disparities in supervised learning models.
    3. C. A model trained on historical data learns to reproduce historical label biases rather than the intended operational goal; fairness criteria and auditability must be explicitly defined at Problem Definition.
    4. D. Multi-class classification algorithms should not be applied to human evaluation tasks where ground truth is subjective.

    Answer: The correct answer is C. The Amazon recruiting case demonstrated that when historical hiring was male-dominated, the model learned that male-coded terms correlated with past hiring decisions and penalized female-coded terms. Simply removing explicit gender words failed because the model identified correlated proxy features. The systems lesson is that Problem Definition must specify fairness, auditability, and validation criteria before data collection and training; an ML workflow trained on biased historical labels optimizes to reproduce the bias of those labels rather than the true organizational goal. The failure was not an architecture choice, offline metrics can measure disparities if stratified evaluation is performed, and binary/multi-class framing was not the root cause.

    Learning Objective: Analyze how historical label bias corrupts ML workflows and justify why fairness criteria must be specified at Problem Definition.

  4. True or False: When a diabetic retinopathy screening deployment scales from a 3-clinic pilot to 200 clinics across diverse regions, the high-level clinical intent (detect referable retinopathy early) remains stable, but the specific engineering targets (subgroup sensitivity thresholds, device latency budgets, and camera-specific preprocessing rules) must evolve.

    Answer: True. Scaling exposes heterogeneity in patient demographics, camera manufacturers, lighting conditions, and operator training that was invisible at pilot scale. While the overarching clinical mission remains unchanged, the engineering problem definition is a living document that must be revised to include stratified subgroup thresholds, support for older hardware, and updated operational constraints.

    Learning Objective: Compare stable clinical intent with evolving engineering targets during deployment scaling.

← Back to Questions

Self-Check: Answer
  1. A rural clinic screens 100 patients per day for DR, capturing 4 retinal photos per patient (two fields per eye) at 5 MB per photo. The clinic operates on an 8-hour daily shift with an intermittent 2 Mbps uplink. According to the chapter’s Bandwidth vs. Compute analysis, why does the screening result still require edge inference?

    1. A. Raw upload takes about 2.2 hours, so it fits the shift and cloud inference is sufficient whenever the link is up.
    2. B. Raw upload of 2 GB takes about 2.2 hours, roughly a quarter of the shift, but a result that must reach the nurse during the visit cannot depend on a link that drops, so inference runs locally and only 10 KB summaries go upstream, cutting traffic by about 2,000\(\times\).
    3. C. Daily raw image upload generates 75 GB of data, which exceeds daily satellite uplink capacity by a factor of 100\(\times\) regardless of compression.
    4. D. Raw uploads complete in 45 minutes, but cloud GPU queuing delay adds 12 hours of fixed inference latency.

    Answer: The correct answer is B. Daily volume is \(100 \times 4 \times 5 \text{ MB} = 2,000 \text{ MB}\), and a 2 Mbps link moves 0.25 MB/s, so the upload takes \(2,000 / 0.25 = 8,000 \text{ s} \approx 2.2 \text{ hours}\), about 28 percent of the shift. Bandwidth alone does not force edge deployment; the requirement that a result reach the nurse during the visit, even when the intermittent link is down, does. Local inference with 10 KB summaries (\(100 \times 10 \text{ KB} = 1 \text{ MB}\)) also cuts uplink traffic about \(2,000\times\). The claim that cloud inference suffices whenever the link is up ignores outages, and the remaining choices miscompute the volume or invent latencies.

    Learning Objective: Calculate network transmission times for clinical data collection and evaluate edge preprocessing as a bandwidth mitigation strategy.

  2. Explain why a DR screening model achieving an AUC of 0.99 on a curated laboratory research dataset can see its sensitivity fall well below the 90 percent screening target when deployed to rural clinics.

    Answer: This drop illustrates the lab-to-field distribution gap. Curated research datasets are captured using standardized, high-end fundus cameras under controlled lighting with dilated pupils and experienced operators. In rural field clinics, images are captured on older, lower-resolution cameras by technicians with minimal training, leading to motion blur, poor illumination, glare, and improper framing. The model degrades not because the learning algorithm is broken, but because production inputs fall outside the training data distribution envelope.

    Learning Objective: Analyze how distribution mismatches between curated research datasets and real-world field environments cause deployment performance gaps.

  3. As a DR screening deployment expands from a pilot site to hundreds of clinics, the data pipeline records the camera model, capture settings, and operator ID for every image. Why does the chapter treat this provenance metadata as essential rather than optional bookkeeping?

    1. A. It lets the training cluster skip quality validation for images from clinics with trusted operators.
    2. B. Data heterogeneity grows with the number of clinics, so the provenance trail is what isolates site-specific accuracy regressions and satisfies regulatory audit requirements.
    3. C. It compresses each image enough to fit within the clinic’s 2 Mbps uplink during operating hours.
    4. D. It replaces the need for consensus grading by multiple ophthalmologists.

    Answer: The correct answer is B. Divergent camera optics, clinic illumination, and operator training give each clinic a distinct input distribution, so heterogeneity scales alongside byte volume. Recording camera model, capture settings, and operator ID for every image makes it possible to trace an accuracy regression to a specific site or device and to satisfy regulatory audits. Provenance does not replace quality validation, does not reduce upload size, and does not substitute for consensus labels.

    Learning Objective: Explain why distributed data collection requires per-image provenance metadata.

  4. True or False: In large-scale medical data collection, if collected images pass basic file format and schema validation, image-quality defects (such as blur, low contrast, or partial occlusion) can be safely ignored because deep neural networks naturally learn to filter out bad samples when trained on sufficiently large datasets.

    Answer: False. File format and schema checks do not guarantee that an image contains usable clinical evidence. Blur, low contrast, or occlusion can hide the very features the model must learn, creating misleading training examples or unusable production inputs. Catching these problems at capture time can trigger immediate recapture and prevent downstream rework; letting them pass pushes the problem into later validation, retraining, or deployment debugging.

    Learning Objective: Evaluate why early point-of-capture data quality validation is essential despite large training set sizes.

  5. In rural clinics with intermittent connectivity, an architecture that buffers captured images locally and reconciles inference results asynchronously with the central cloud during available network windows is known as a(n) ____ architecture.

    Answer: store-and-forward. Store-and-forward architectures buffer data locally during network outages and transmit batched data when connectivity is restored, decoupling local clinical operations from central cloud availability.

    Learning Objective: Classify store-and-forward architectures as the primary mechanism for managing intermittent network connectivity in distributed data pipelines.

  6. A training pipeline randomly shuffles a multi-terabyte dataset across samples on every epoch, pulling records from storage backed by NVMe and spinning disks. Even though the hardware accelerator has ample peak compute capacity, training throughput stalls. Which explanation correctly identifies the systems-level bottleneck according to the chapter?

    1. A. Random shuffling makes the training workload strictly compute-bound, so the accelerator cores become overloaded by stochastic gradient calculations.
    2. B. Random sample access scatters reads across storage, defeating the caching and prefetching that sequential reads enjoy, so the data loader cannot deliver samples as fast as the accelerator consumes them.
    3. C. Shuffling multi-terabyte datasets bypasses the operating system page cache entirely, forcing floating-point arithmetic units to stall on instruction decoding.
    4. D. The memory hierarchy becomes saturated because the accelerator requires deterministic sample ordering to maintain kernel pipeline parallelism.

    Answer: The correct answer is B. Random sample order scatters reads across storage, so the caching and prefetching that make sequential reads fast stop helping. The data loader then delivers samples more slowly than training consumes them, and the accelerator idles however much peak compute it has. The chapter’s delivery test (compare the loader’s delivery rate with the rate training consumes samples) exposes this stall; the fixes belong to data layout and prefetching, not to more compute. The other options misplace the bottleneck in arithmetic, instruction decoding, or ordering requirements that the workload does not have.

    Learning Objective: Analyze how randomized data access patterns in ML training defeat OS locality mechanisms and cause data-delivery bottlenecks.

← Back to Questions

Self-Check: Answer
  1. According to the chapter, which bundle of deliverables constitutes the inference package of a reproducible system artifact from the Model Development and Training stage, and why are model weights alone insufficient?

    1. A. Model weights, inference/preprocessing code, environment specification (e.g., container or locked dependency graph), and runtime configuration; weights alone fail because library version mismatches or preprocessing differences alter outputs without crashing.
    2. B. Model weights and a serialized training log; the execution environment can always be inferred from the framework version tag.
    3. C. Model weights, a test-set evaluation scorecard, and an architecture diagram; deployment engineers reconstruct dependencies during serving containerization.
    4. D. Source code repository commits and hyperparameters; weights can be deterministically reproduced from random seeds on any hardware.

    Answer: The correct answer is A. A mature ML workflow defines the inference package of a reproducible system artifact as four co-dependent components: model weights, inference preprocessing code, environment specification (Docker image, CUDA driver, dependency graph), and runtime configuration. Packaging weights alone creates ‘works on my machine’ failures: subtle differences in linear algebra kernels, CUDA versions, or image-resizing libraries (e.g., OpenCV vs. PIL) alter floating-point outputs or pixel interpolation without throwing exceptions, silently degrading accuracy. The complete artifact also links dataset and training-code versions, preprocessing and training recipes, and the training environment. Training logs or scorecards do not enable execution, and hardware differences make pure seed-based bitwise weight reconstruction unreliable across different accelerator architectures.

    Learning Objective: Classify the four inference-package components of a reproducible system artifact and explain why weights alone fail to guarantee consistent inference.

  2. Explain why a competition-winning 50-model ensemble that achieves state-of-the-art accuracy on a benchmark may be discarded for production edge deployment, citing the Netflix Prize as an empirical reference.

    Answer: An ensemble generally adds inference work and model storage across its constituents. Serial execution adds their runtimes, whereas parallel execution requires enough hardware and coordination; model count alone establishes no fixed latency multiplier. The chapter cites the Netflix Prize as a case where benchmark gains did not justify operational complexity. On a clinic device with a 500 MB model budget, a 50-model ensemble may exceed memory, latency, or power limits, but that verdict requires constituent sizes and measured execution on the target. The team must compare the integrated ensemble’s quality and resource demands with simpler or compressed alternatives rather than infer infeasibility from model count alone.

    Learning Objective: Analyze the competition-versus-production trade-off in ensemble methods and justify why benchmark-winning models may be unviable for edge serving.

  3. In the chapter’s Iteration Tax scenario, a team compares Model L (large ensemble, starts at 95% accuracy, 1-week training cycle, +0.15% gain/iter) with Model S (lightweight model, starts at 90% accuracy, 1-hour training cycle, +0.1% gain/iter, 100 effective iters) over a 26-week window with a 99% ceiling. What is the modeled outcome after 26 weeks, and what systems lesson does it demonstrate?

    1. A. Model L reaches 99.0% while Model S reaches 92.6%, proving that starting accuracy dominates iteration speed over six months.
    2. B. Model S reaches the 99.0% ceiling while Model L reaches 98.9%, so both end near the ceiling; the lasting difference is that the fast-cycle team tests about four times as many ideas.
    3. C. Both models reach exactly 95.0% accuracy because human hypothesis generation saturates at 26 experiments regardless of training speed.
    4. D. Model L fails to converge due to training instability, while Model S converges to 90.0% without improvement.

    Answer: The correct answer is B. As modeled in the Iteration Tax notebook: over 26 weeks, Model L runs 26 iterations at 1 week each, reaching \(95.0\% + (26 \times 0.15\%) = 98.9\%\). Model S runs 100 effective iterations (capped by hypothesis generation), reaching an uncapped \(90.0\% + (100 \times 0.1\%) = 100.0\%\), which hits the \(99.0\%\) ceiling. The 0.1-point gap between them is an artifact of the assumed gains, not a finding. The systems lesson is that iteration velocity is a feature because it buys search breadth: 100 effective iterations against 26 means the fast-cycle team tests about four times as many architectures, data augmentations, and preprocessing choices. The claim that starting accuracy dominates contradicts the worked math, and the saturation/non-convergence claims contradict the chapter’s scenario parameters.

    Learning Objective: Calculate the cumulative accuracy trajectory under the Iteration Tax model and explain how experimentation velocity acts as a systems optimization lever.

  4. A team observes that model validation accuracy drops 2 percent between run 47 and run 48. Explain how an automated experiment tracking lineage record helps investigate this regression compared to an ad hoc notebook workflow.

    Answer: Automated lineage narrows the search space by showing exactly which artifacts changed between the two runs: dataset version, code commit, hyperparameters, environment, and seed. In an ad hoc notebook workflow, those differences may be incomplete or missing, so the team spends much more time reconstructing what changed before it can even form a hypothesis. A metadata diff does not prove the cause by itself, but it identifies the most plausible candidates and supports repeated or controlled comparisons to test which change actually produced the regression.

    Learning Objective: Explain how automated artifact lineage narrows regression investigation by identifying changed artifacts and guiding controlled comparisons.

  5. Arrange the following model development milestones in a plausible order for a constraint-driven ML workflow, where each milestone uses the outputs of the one before it: (1) Baseline transfer-learning fine-tuning from pretrained weights, (2) Physical constraint profiling (target latency, memory ceiling, power envelope), (3) Systematic ablation studies to isolate component contributions, (4) Model compression (pruning/quantization) and hardware-in-the-loop latency validation, (5) Packaging weights, preprocessing code, dependencies, and configuration into a reproducible system artifact.

    Answer: The correct order is: (2) Physical constraint profiling (target latency, memory ceiling, power envelope), (1) Baseline transfer-learning fine-tuning from pretrained weights, (3) Systematic ablation studies to isolate component contributions, (4) Model compression (pruning/quantization) and hardware-in-the-loop latency validation, (5) Packaging weights, preprocessing code, dependencies, and configuration into a reproducible system artifact. The chapter does not prescribe a fixed sequence, but each step depends on the previous one. Development begins by establishing physical constraint boundaries; next, transfer learning establishes a functional baseline; ablation studies systematically isolate architectural improvements; model compression adapts the architecture to target device constraints; and finally, all code, weights, environment specs, and configs are packaged into a reproducible artifact.

    Learning Objective: Design the sequence of stages in a constraint-driven model development and optimization pipeline.

← Back to Questions

Self-Check: Answer
  1. What is the primary conceptual distinction between Model Evaluation and Model Validation as defined in this chapter?

    1. A. Evaluation is conducted by internal software engineers, whereas validation is conducted exclusively by government regulatory agencies.
    2. B. Evaluation tests software execution speed on accelerators, whereas validation tests algorithm mathematical convergence on CPUs.
    3. C. Evaluation measures model behavior on chosen datasets and metrics; validation is a multi-dimensional evidence gate confirming the model satisfies all operational, latency, subgroup fairness, robustness, and cost constraints under production-representative conditions.
    4. D. Evaluation is performed on live production traffic, whereas validation is performed exclusively on synthetic offline data.

    Answer: The correct answer is C. The chapter defines Model Evaluation as characterizing algorithmic performance using selected datasets, loss metrics, and test benchmarks. Model Validation is an evidence-based decision gate for deployment readiness, verifying that the integrated model and system satisfy all physical constraints (latency, memory, power), subgroup safety floors (demographic fairness, comorbidity performance), robustness under distribution shift (blur, lighting, camera variation), and cost budgets. Confining validation to external regulators misses its internal engineering function, splitting evaluation/validation by hardware architecture is incorrect, and online vs. offline execution is handled within staged validation rather than defining the conceptual boundary.

    Learning Objective: Compare Model Evaluation and Model Validation to classify their distinct roles in deployment readiness gating.

  2. A diabetic retinopathy screening model achieves 94 percent aggregate accuracy on held-out validation data. However, stratified evaluation reveals that sensitivity drops to 76 percent for patients with cataracts and falls below the 90 percent sensitivity floor for one demographic subpopulation. How should the engineering team respond?

    1. A. Proceed to full deployment immediately, because aggregate accuracy above 90 percent statistically compensates for minor subpopulation variations.
    2. B. Apply post-hoc temperature scaling to increase overall prediction confidence, which automatically resolves subgroup sensitivity deficits.
    3. C. Deploy the model in shadow mode permanently, since shadow mode bypasses clinical subgroup safety requirements.
    4. D. Block deployment, because the model violates non-negotiable clinical sensitivity safety thresholds for vulnerable subgroups; stratified validation exists precisely to prevent aggregate metrics from masking localized clinical harm.

    Answer: The correct answer is D. In medical AI systems, aggregate accuracy is deceptive: high overall accuracy can obscure catastrophic error rates in specific sub-populations. A sensitivity drop to 76 percent in cataract patients or below the 90 percent safety floor means referable eye disease will be missed, leading to preventable blindness. Problem Definition establishes that subgroup sensitivity floors are hard quality invariants; failing them must block deployment regardless of aggregate accuracy. Relying on aggregate metrics to override subgroup failure violates medical safety principles, temperature scaling modifies confidence scores without altering underlying class sensitivity, and shadow mode is an evaluation stage rather than a permanent production workaround.

    Learning Objective: Evaluate stratified subgroup validation results and justify blocking deployment when subgroup safety thresholds are violated.

  3. Explain why a medical diagnostic model with an outstanding Area Under the ROC Curve (AUC) of 0.99 on a research dataset may still fail deployment validation for clinical screening.

    Answer: AUC is a threshold-independent metric that evaluates ranking quality across all possible classification cutoffs from 0 to 1. In production clinical screening, however, the model operates at a single, fixed decision threshold. At that specific operating point, the model must simultaneously satisfy strict clinical floors: sensitivity >90 percent (to prevent missed diagnoses) and specificity >80 percent (to prevent overwhelming referral clinics) on production-representative data with diverse camera models and lighting. A high AUC does not guarantee that any single operating threshold meets both clinical floors under real-world distribution shift.

    Learning Objective: Explain why threshold-free AUC metrics do not establish clinical deployment readiness at fixed operating thresholds.

  4. Order the stages of progressive online validation from lowest initial user risk to broadest comparative evaluation: (1) Canary deployment exposing 1–5% of live traffic, (2) Offline evaluation on held-out and stratified test sets, (3) A/B testing comparing outcomes against the production baseline, (4) Shadow mode running in parallel on live requests without serving predictions to users.

    Answer: The correct order is: (2) Offline evaluation on held-out and stratified test sets, (4) Shadow mode running in parallel on live requests without serving predictions to users, (1) Canary deployment exposing 1–5% of live traffic, (3) A/B testing comparing outcomes against the production baseline. Progressive validation begins offline with static benchmark testing; next, shadow mode tests end-to-end serving integration and performance under live production load with zero user exposure; canary deployment routes a small, controlled fraction of traffic to verify stability under real user interactions; and finally, A/B testing establishes statistically significant comparative efficacy against the incumbent baseline.

    Learning Objective: Design the sequence of progressive online validation stages from zero-exposure integration testing to live comparative evaluation.

  5. True or False: Model calibration—ensuring that a predicted confidence score of 0.80 corresponds to an empirical 80 percent probability of correctness—is critical for medical AI systems because clinical triage workflows rely directly on confidence scores to route ambiguous cases to human specialists.

    Answer: True. Calibration is distinct from classification accuracy. In clinical triage, physicians use model confidence scores to determine whether automated decisions can be trusted or require specialist review. An uncalibrated model that outputs 95% confidence on borderline, uncertain cases can dangerously mislead clinicians into skipping necessary specialist referrals, creating severe safety risks even if aggregate accuracy appears acceptable.

    Learning Objective: Evaluate the role of model calibration in supporting safe clinical triage and human-in-the-loop routing.

← Back to Questions

Self-Check: Answer
  1. A deployment model processes ~760,000 screening images per month across 500 rural clinics. Cloud inference costs $0.01/image plus $45,000/year for connectivity/network operations ($136,200/year total). Edge deployment requires a $500 device per clinic ($250,000 CapEx), $25,000/year maintenance, and $0.001/image ($34,120/year total OpEx). Treat cloud as a counterfactual cost benchmark because it fails the stated connectivity and latency requirements. Using these rounded annual-cost givens, what is the annual operating savings of edge deployment and its payback period?

    1. A. Approximately $102,080 annual savings with a payback period of approximately 2.4 to 2.5 years, while enabling offline operation during connectivity outages.
    2. B. The same annual savings with a payback period of ten years, making cloud deployment far more economical.
    3. C. The same annual savings with an immediate three-month payback period.
    4. D. Zero annual savings, because edge hardware maintenance costs exactly equal cloud inference fees at 500 clinics.

    Answer: The correct answer is A. Using the question’s rounded annual-cost givens: Total Cloud Annual OpEx = $136,200. Total Edge Annual OpEx = $25,000 (maintenance) + $9,120 (variable inference) = $34,120. Annual Savings = $136,200 - $34,120 = $102,080. Edge Hardware CapEx = 500 clinics \(\times\) $500/device = $250,000. Payback Period = $250,000 / $102,080 \(\approx\) 2.45 years (~2.5 years). Beyond cost recovery, edge deployment provides the critical operational advantage of functioning without internet connectivity during network outages. The alternative payback periods contradict the stated capital expense divided by annual savings.

    Learning Objective: Calculate total cost of ownership, annual operating savings, and payback period for cloud versus edge ML deployment.

  2. Explain what integration requirements an ML screening score adds to a Hospital Information System (HIS) interface beyond recording a measurement with units, and why neither a sensor reading nor a model score establishes its own reliability.

    Answer: A measurement interface records a value, units, and relevant device and capture context; sensor readings still require evidence about calibration, error, and operating conditions. An ML screening score also requires evaluation of what its values mean on the intended population. A raw score does not automatically provide a reliable uncertainty estimate. Before the HIS uses a score to route a case, the workflow must validate its interpretation, decision thresholds, handling of rejected inputs, and downstream clinical response. The chapter also explains that privacy rules constrain retention, audit links, and reuse for model updates. Both interfaces require validated contracts, while the learned score adds population-dependent performance and routing evidence.

    Learning Objective: Explain the additional score-interpretation and routing evidence required for ML integration into clinical software.

  3. An edge-deployed vision device has a 100 ms total latency budget. Profiling reveals the following execution breakdown: on-device model inference = 15 ms, remote cloud lookup for patient metadata = 60 ms, and local serialization/HIS formatting = 40 ms (total = 115 ms). Assume a local cache contains valid, sufficiently fresh patient metadata and a lookup takes less than 1 ms without changing the other costs. Which engineering modification directly reduces the Iron Law fixed overhead (\(L_{\text{lat}}\)) term to meet the 100 ms budget?

    1. A. Prune the neural network weights to reduce on-device model inference time from 15 ms to 5 ms.
    2. B. Cache patient metadata locally on the device to eliminate the 60 ms remote network round-trip.
    3. C. Quantize the model from FP32 to INT8 to increase arithmetic intensity (operations per byte).
    4. D. Increase the GPU clock frequency on the edge device to accelerate tensor core processing.

    Answer: The correct answer is B. The remote lookup and serialization account for 100 ms before any model inference. Keeping those costs unchanged leaves total latency above the 100 ms budget whenever inference takes positive time; reducing the stated 15 ms inference to 5 ms still gives 105 ms. Under the question’s valid-cache and local-read assumptions, caching replaces the 60 ms remote lookup with less than 1 ms, leaving total latency below 56 ms with the existing 15 ms inference and 40 ms serialization. The cache’s validity and freshness are necessary premises for this latency repair to preserve the integration contract.

    Learning Objective: Apply the Iron Law fixed overhead term (\(L_{\text{lat}}\)) to analyze latency bottlenecks and evaluate caching strategies.

  4. True or False: Phased deployment progressing from simulation to pilot clinics to full production rollout is recommended because each phase is designed to expose a distinct, non-overlapping class of system failures: simulation catches software integration and schema bugs; pilots catch real-world camera and workflow heterogeneity; and full production catches distributed concurrency contention and rare clinical tail cases.

    Answer: False. The phases are useful because they provide complementary, overlapping evidence under increasingly realistic conditions, not because each one owns a perfectly separate failure class. Simulation often surfaces integration and schema issues, pilots add evidence about site heterogeneity and workflow fit, and full production reveals broader operating behavior, but a given failure can appear in more than one phase. There is no guarantee that simulation cannot expose a problem later seen in pilot, or that pilot cannot reveal latency or concurrency issues as well.

    Learning Objective: Assess why phased deployment provides complementary overlapping evidence rather than perfectly separate failure coverage.

  5. A deployment policy that automatically routes low-confidence or high-uncertainty model predictions to an expert specialist for manual review, while allowing high-confidence predictions to proceed automatically, is known as ____ routing.

    Answer: human-in-the-loop. Human-in-the-loop routing uses calibrated model uncertainty to triage decisions, ensuring that ambiguous or borderline cases receive expert human oversight while automating routine, high-confidence cases.

    Learning Objective: Explain human-in-the-loop routing as an operational mechanism for managing model uncertainty in high-stakes deployments.

← Back to Questions

Self-Check: Answer
  1. Why does production ML monitoring structure its telemetry into a four-tier hierarchy of operational, proxy, performance, and data stability metrics rather than relying on a single metric class?

    1. A. Because cloud monitoring vendors charge lower fees when metrics are divided into multiple dashboard tabs.
    2. B. Because operational metrics like latency and CPU load are sufficient to detect model accuracy degradation in real time.
    3. C. Because different failure modes emerge across different timescales: operational metrics catch service crashes in seconds, proxy metrics (confidence, referral rate) detect distribution shifts in hours without labels, and performance metrics (sensitivity, specificity) confirm diagnostic accuracy weeks later when ground truth arrives.
    4. D. Because ground-truth diagnostic labels are instantly available in real time for every inference request in production.

    Answer: The correct answer is C. Different system failures surface on distinct timescales. Operational metrics (latency, error rate, queue depth) detect infrastructure crashes within seconds but reveal nothing about statistical prediction quality. Proxy metrics (confidence distributions, referral rates, image quality rejection rates) provide real-time indicators of data drift within hours without waiting for labels. Performance metrics (sensitivity, specificity) measure true accuracy but require adjudicated ground-truth labels that arrive with weeks of delay. Relying on any single tier creates blind spots: operational metrics miss silent drift, while performance metrics respond too slowly to active incidents.

    Learning Objective: Analyze the multi-timescale hierarchy of operational, proxy, and performance metrics in production ML monitoring.

  2. Explain why reverting an ML system to an older model checkpoint during a production degradation incident is only a mitigation tactic rather than a true system state restoration.

    Answer: Rolling back restores an earlier model artifact, but it does not restore the rest of the live environment to its old state. Conventional software rollbacks also may not recreate prior external state, and ML adds another problem: the current input distribution may have shifted away from what the older model was trained on. For example, if clinics changed camera hardware, the old weights may no longer match current images, so rollback buys time while the team evaluates current outcomes rather than guaranteeing a full return to the earlier system behavior.

    Learning Objective: Explain why model rollback is a temporary mitigation rather than a complete system restore when live conditions have changed.

  3. Six months after launch, a clinic network upgrades its fundus cameras to a newer model with a distinct color profile. System latency and server error rates remain perfectly stable at 0.0%, but clinical sensitivity drops from 92% to 77%. What systems phenomenon does this scenario illustrate?

    1. A. A deterministic crash in the GPU serving container caused by CUDA driver incompatibility.
    2. B. An adversarial perturbation attack executed against the clinic edge devices.
    3. C. Concept drift caused by a sudden biological mutation in the underlying disease pathology.
    4. D. Silent degradation caused by covariate/data drift; input pixel distributions shifted beyond the training envelope while traditional infrastructure monitoring showed healthy green dashboards.

    Answer: The correct answer is D. This scenario illustrates silent degradation through covariate/data drift. The upgraded cameras alter the input image distribution (color spectrum, contrast, sensor noise), moving incoming data outside the envelope learned during training. Because the model executes without code errors, traditional software monitoring (uptime, latency, error codes) reports healthy green dashboards while clinical diagnostic performance degrades severely. It is not an infrastructure crash, not an adversarial attack, and not concept drift (the biological relationship between retina lesions and diabetes did not change; the imaging sensor distribution shifted).

    Learning Objective: Analyze silent model degradation caused by data drift and explain why traditional infrastructure monitoring fails to detect it.

  4. True or False: In production ML monitoring, lightweight statistical tests such as the Population Stability Index (PSI) and Kolmogorov-Smirnov (KS) test can detect shifts in input feature distributions, but an alert from these tests does not by itself prove that model classification accuracy has degraded until ground-truth outcome evidence is evaluated.

    Answer: True. PSI and KS tests detect distribution divergence \(\mathcal{D}(P_t \parallel P_0)\) between current inference traffic and baseline training data. An input shift indicates that incoming data has drifted, which raises the probability of accuracy loss and triggers investigation; however, it does not prove that accuracy has degraded (the model might be robust to the specific feature shift). Confirming accuracy degradation requires evaluating labeled outcomes or verified clinical feedback.

    Learning Objective: Evaluate the diagnostic scope of statistical drift tests (PSI, KS) and distinguish input distribution shifts from confirmed accuracy loss.

  5. Describe what metadata elements must be linked in an automated data lineage audit trail for medical ML systems, and explain how lineage reduces the engineering cost of investigating a site-specific accuracy regression.

    Answer: A lineage trail should connect production behavior to the relevant artifacts: model version, dataset version or training snapshot, preprocessing and inference code versions, environment details, and site-specific context such as clinic or hardware identifiers. That record does not instantly prove a single cause from one query or one example. Instead, it lets engineers trace which versions and site changes coincided with the regression, narrow the hypothesis set, and then run targeted comparisons or tests to determine whether the problem came from a camera change, a preprocessing update, or a model update.

    Learning Objective: Analyze the metadata links required in a data lineage audit trail and justify how lineage supports efficient, hypothesis-driven regression investigation.

← Back to Questions

Self-Check: Answer
  1. A referral-rate change appears for patients over seventy, who are included in the intended use, but labels are available only for referred patients and the release manifest contains no separate sensitivity evaluation for this age group. What can the monitoring team conclude, what evidence must it obtain, and which artifacts should it review before selecting a remedy?

    Answer: The referral-rate change warrants investigation but does not establish a sensitivity failure. Labels from referred patients omit cases the model did not refer, so the evaluation owner needs representative labeled evidence for the affected screening population. The monitoring owner records the signal and artifact versions and applies the approved exposure policy while evidence is collected. Requirements already include these patients, but the evaluation plan and coverage records need review. Preprocessing changes or retraining require evidence that those interventions address the cause. A revised candidate must pass subgroup and regression evaluation and on-device latency and memory checks, with the evidence and approval recorded in a revised release manifest before controlled rollout.

    Learning Objective: Design an evidence-gated monitoring response and trace the artifact revisions needed for re-release.

  2. In a multi-site distributed ML deployment spanning hundreds of clinics, why can system-wide emergent behaviors produce failures that are completely invisible when examining individual clinics in isolation?

    1. A. Because distributed communication protocols inject pseudo-random noise into inference predictions.
    2. B. Because local monitoring averages away subpopulation variance; an underserved demographic group that represents only 1–2% of patients at each clinic appears as statistical noise locally, but forms a significant, systematically failing population in aggregate.
    3. C. Because modern ML models are strictly non-deterministic on edge devices and deterministic in the cloud.
    4. D. Because individual clinics never experience data drift, which occurs only across wide-area networks.

    Answer: The correct answer is B. Emergent complexity means system-level behaviors cannot be understood by observing individual components in isolation. At any single clinic, an underrepresented patient subpopulation (e.g., elderly patients with rare comorbidities) may comprise only a handful of cases, making local accuracy metrics appear stable and healthy. When aggregated across hundreds of clinics, however, the model may systematically fail for thousands of patients in that demographic. Global cross-site telemetry is essential to surface systemic disparities that local averages conceal. Network noise, deterministic execution claims, and local drift immunity are technically incorrect.

    Learning Objective: Analyze how emergent complexity creates systemic demographic disparities that local component monitoring obscures.

  3. Arrange the following feedback loop cadences in order from shortest operating timescale (most rapid) to longest operating timescale (slowest): (1) Weekly aggregation of labeled accuracy metrics and statistical drift tests, (2) Minute-level operational health and image-capture focus checks, (3) Quarterly architectural review of model families and regulatory compliance, (4) Daily monitoring of proxy metrics such as referral rates and confidence distributions.

    Answer: The correct order is: (2) Minute-level operational health and image-capture focus checks, (4) Daily monitoring of proxy metrics such as referral rates and confidence distributions, (1) Weekly aggregation of labeled accuracy metrics and statistical drift tests, (3) Quarterly architectural review of model families and regulatory compliance. Multi-scale feedback operates across five orders of magnitude: minute-level checks catch immediate operational and hardware misconfigurations; daily proxy tracking detects distribution shifts without waiting for labels; weekly performance reviews incorporate adjudicated ground-truth outcomes; and quarterly strategic reviews evaluate model architectures, lifecycle costs, and regulatory compliance.

    Learning Objective: Compare multi-scale feedback loops across operational, proxy, performance, and strategic timescales.

← Back to Questions

Self-Check: Answer
  1. Why does the chapter characterize ‘scaling dataset size is always the best way to improve model accuracy’ as a major engineering pitfall?

    1. A. Because deep learning models degrade in accuracy when trained on more than \(10^5\) samples due to parameter saturation.
    2. B. Because collecting additional data increases the Operations (\(O\)) term during inference execution.
    3. C. Because additional examples can have poor marginal value in already well-covered regions, so collection and curation choices must be compared using observed gains in required task and subgroup metrics against their labeling, storage, and compute costs.
    4. D. Because data privacy regulations strictly limit training set sizes to under 100,000 images in healthcare applications.

    Answer: The correct answer is C. More examples incur acquisition and processing costs, but their learning value depends on which coverage gaps they fill. Repeated examples from well-covered regions can have poor marginal returns, whereas targeted collection or label repair may address observed failure modes. Neither curation nor added volume universally delivers higher gains at lower cost; the team must compare measured task and subgroup improvements with the cost of each option. Sample count alone establishes no parameter-saturation failure or universal legal cap, and adding training examples does not by itself increase the deployed model’s inference operation count.

    Learning Objective: Evaluate marginal task and subgroup gains against the costs of data collection and curation.

  2. True or False: Deferring deployment paradigm selection (Cloud, Edge, Mobile, or TinyML) until after model architecture design and training are complete is an effective engineering strategy because modern model compression techniques can universally fit any trained model onto any target hardware without compromising accuracy.

    Answer: False. Deployment paradigm is a day-one constraint that bounds feasible model and preprocessing choices. Compression cannot universally make an arbitrary trained model fit a target while preserving required quality. Late discovery requires tracing which artifacts depend on the missed limit: preprocessing choices, weights, evaluation evidence, and the deployment package may need revision, while some collected data may remain usable. Correction effort and delay follow the affected tasks and their dependencies; the discovery stage alone does not determine them or require every stage to restart.

    Learning Objective: Evaluate how a deferred deployment decision creates dependency-sensitive rework.

  3. A team skips shadow-mode validation and canary deployment, relying entirely on strong test-set accuracy, although its release plan requires evidence of integration behavior, live-input latency, and limited-exposure operation. Why does skipping these unmet evidence obligations increase deployment risk and possible rework?

    1. A. Because skipping canary deployment causes compilers to emit unoptimized serving binaries.
    2. B. Because offline test sets are mathematically incapable of computing classification accuracy.
    3. C. Because modern cloud orchestrators refuse to route traffic to containers that have not completed shadow mode.
    4. D. Because strong test-set accuracy does not meet those integration and exposure obligations; unresolved failures may reach production and require investigation, containment, artifact repair, and renewed validation.

    Answer: The correct answer is D. The omitted gates supply complementary evidence about serving integration and controlled live exposure that model accuracy alone does not establish. Skipping them without meeting those obligations another way leaves unresolved risk in the release decision. If a failure then appears in production, the team may need containment, rollback, diagnosis, and revalidation under operating constraints. The chapter does not establish a universal increase in calendar time from omitting any named gate; removal can be justified when its evidence obligation is met another way. Canary deployment does not determine compiler optimization, offline tests can measure accuracy, and orchestrators do not universally enforce shadow evaluation.

    Learning Objective: Analyze the deployment risk and possible rework from skipping unmet validation evidence obligations.

← Back to Questions

Back to top