ML Workflow
Purpose
Why is seeing the whole map necessary before walking any single path?
The D·A·M taxonomy names the components of every ML system, and deployment location determines the physical constraints each component must satisfy. Teams often treat these as separate concerns, with one team collecting data, another designing the model, and a third provisioning hardware. Yet the taxonomy’s deepest lesson is that these components interact. The collected data constrains which algorithms are feasible. The chosen algorithm dictates what hardware can run it. The target hardware reshapes what data can be processed. Pull on any single thread and the entire system shifts. These interactions play out across components and across time. A model that performs well at launch may degrade as the data distribution shifts, prompting investigation and, when evidence warrants it, model or data updates. Optimizing each piece in isolation is how teams build accurate models that cannot be deployed and efficient pipelines that feed the wrong data. A data engineer who sees how preprocessing choices constrain downstream architectures builds different pipelines than one who treats data preparation as an isolated task; a model developer who knows the deployment target’s memory budget from day one makes different architecture decisions than one chasing accuracy in a vacuum. Before the details of any one component can be understood, the full map must show how an ML system is built, evaluated, and sustained as a coherent whole. The ML workflow sets that map in motion through iterative D·A·M co-design across data, algorithm, and machine until their emergent capability meets the requirements of the real world.
Learning Objectives
- Explain the six ML lifecycle stages as coordinated data-algorithm-machine decisions with feedback
- Compare ML workflows with traditional software using drift, nondeterminism, and operational feedback
- Analyze how problem-definition constraints propagate through data, modeling, validation, and deployment
- Calculate late-discovery integration costs using the workflow’s constraint propagation principle
- Evaluate accuracy, efficiency, reproducibility, and deployment readiness trade-offs across lifecycle stages
- Design feedback loops that connect monitoring signals to retraining, maintenance, and revised requirements
ML Lifecycle
A typical deployment failure illustrates the danger of uncoordinated engineering. Day one: “Build a diagnostic model for rural clinics.” Day 90: 95 percent accuracy on the test set. Day 120: 96 percent accuracy after a month of architecture tuning. Day 150: the model is handed to deployment engineers. Day 151: deployment engineers report that the model requires 4 GB of memory. Day 152: someone checks the deployment target—tablets in mobile clinics with 512 MB available. Day 153: five months of work is discarded.
The model’s accuracy was excellent. The team’s machine learning skills were excellent. The failure was a workflow failure. A deployment constraint that should have shaped every decision from day one was discovered only after the work was done. The tablet’s memory limit should have propagated backward to the first architecture meeting, constraining which models were even worth considering. Instead, the team optimized each component in isolation (data collection, architecture selection, training), and the integration failure appeared only when the pieces were assembled. A documented diabetic retinopathy (DR) deployment exposed analogous workflow and infrastructure gaps.1
1 Lab-to-deployment gap: Beede et al. (2020) documented this empirically for a deep-learning diabetic retinopathy screening system deployed in Thai clinics. Although the system had specialist-level accuracy in earlier validation, 393 of 1,838 submitted images (21 percent) failed its image-quality requirements, often because clinic lighting, camera maintenance, or dilation practices did not match the system’s assumptions. Those rejections added work for nurses, forced retakes or referrals, and exposed workflow and infrastructure barriers rather than simply a model-accuracy problem.
ML systems combine Data, Algorithm, and Machine under physical constraints that partition deployment into Cloud, Edge, Mobile, and TinyML, each imposing hard physical limits on compute throughput, memory capacity, and thermal dissipation. Connecting these components into a functioning system requires orchestrating how constraints propagate across Data, Algorithm, and Machine.
The ML workflow is an engineering framework designed to prevent integration failures by making constraints explicit at each development stage and tracing how they propagate across Data, Algorithm, and Machine. It marks the shift from model researcher to systems engineer. A researcher optimizes individual elements: a better architecture, a cleaner dataset, a faster accelerator. A systems engineer orchestrates those elements into production systems that reliably deliver value. The day-153 failure did not stem from an isolated modeling, data, or hardware defect; it arose from the unmanaged interaction among all three. The workflow supplies the mental map that keeps technical decisions attached to the larger system.
The machine learning lifecycle is the orchestration framework for this work: a structured, iterative process2 that guides the development, evaluation, and improvement of ML systems (Amershi et al. 2019). The formal definition emphasizes continuous management rather than a one-time release.
2 CRISP-DM (cross-industry standard process for data mining): CRISP-DM codified data-intensive system development as six interconnected, iterative phases rather than a linear waterfall (Chapman et al. 2000); its core design principle (feedback loops between all phases) directly informs the modern ML lifecycle’s structure. Boehm’s software-engineering economics work discussed the higher cost of late fixes (Boehm 1981). The workflow model later uses \(2^{N_{\text{stage}}-1}\), where \(N_{\text{stage}}\) is the lifecycle stage index, as an illustrative sensitivity scenario rather than an empirical cost law.
Chapman, Pete, Julian Clinton, Randy Kerber, Thomas Khabaza, Thomas Reinartz, Colin Shearer, and Rudiger Wirth. 2000. “CRISP-DM 1.0: Step-by-Step Data Mining Guide.” SPSS Inc 1: 78.
Amershi, Saleema, Andrew Begel, Christian Bird, Robert DeLine, Harald Gall, Ece Kamar, Nachiappan Nagappan, Besmira Nushi, and Thomas Zimmermann. 2019. “Software Engineering for Machine Learning: A Case Study.” 2019 IEEE/ACM 41st International Conference on Software Engineering: Software Engineering in Practice (ICSE-SEIP), 291–300. https://doi.org/10.1109/icse-seip.2019.00042.
Definition 1.1: Machine learning lifecycle
Machine learning lifecycle is the iterative engineering process of building, deploying, monitoring, and updating ML systems, where evidence from later stages can feed back to earlier stages because model performance may change after deployment.
- Significance: The lifecycle is a closed loop, not a linear pipeline. Distribution divergence \(\mathcal{D}(P_t \lVert P_0)\) between current and training traffic is an alert signal that raises the probability of accuracy loss; the exact relationship depends on the model, labels, loss, and deployment distribution. A full retraining run incurs the \(O/(R_{\text{peak}} \cdot \eta_{\text{hw}})\) compute cost, while partial or incremental updates may cost less. Drift velocity and validation delay therefore turn lifecycle maintenance into a budgeting problem, not just an engineering process.
- Distinction: Unlike traditional software, whose behavior changes when code, configuration, dependencies, or environment changes, ML behavior can also change as the world changes. A deployed model’s accuracy may change through distribution shift even when the code, infrastructure, and configuration remain untouched.
- Common pitfall: A frequent misconception is that the lifecycle ends at deployment. In reality, deployment is the beginning of the feedback loop: production monitoring surfaces drift, drift triggers investigation, and outcome evidence determines whether a retrained model should re-enter the deployment stage.
Here, lifecycle describes the stages themselves and workflow describes the engineering discipline of orchestrating them; the lifecycle is what gets traversed, the workflow is how the traversal is managed. This distinction requires systems thinking: analyzing how a system’s parts interrelate rather than treating them in isolation. The patterns formalized in section 1.9 and illustrated through the detailed case study explain why ML systems require integrated engineering approaches rather than sequential component optimization.
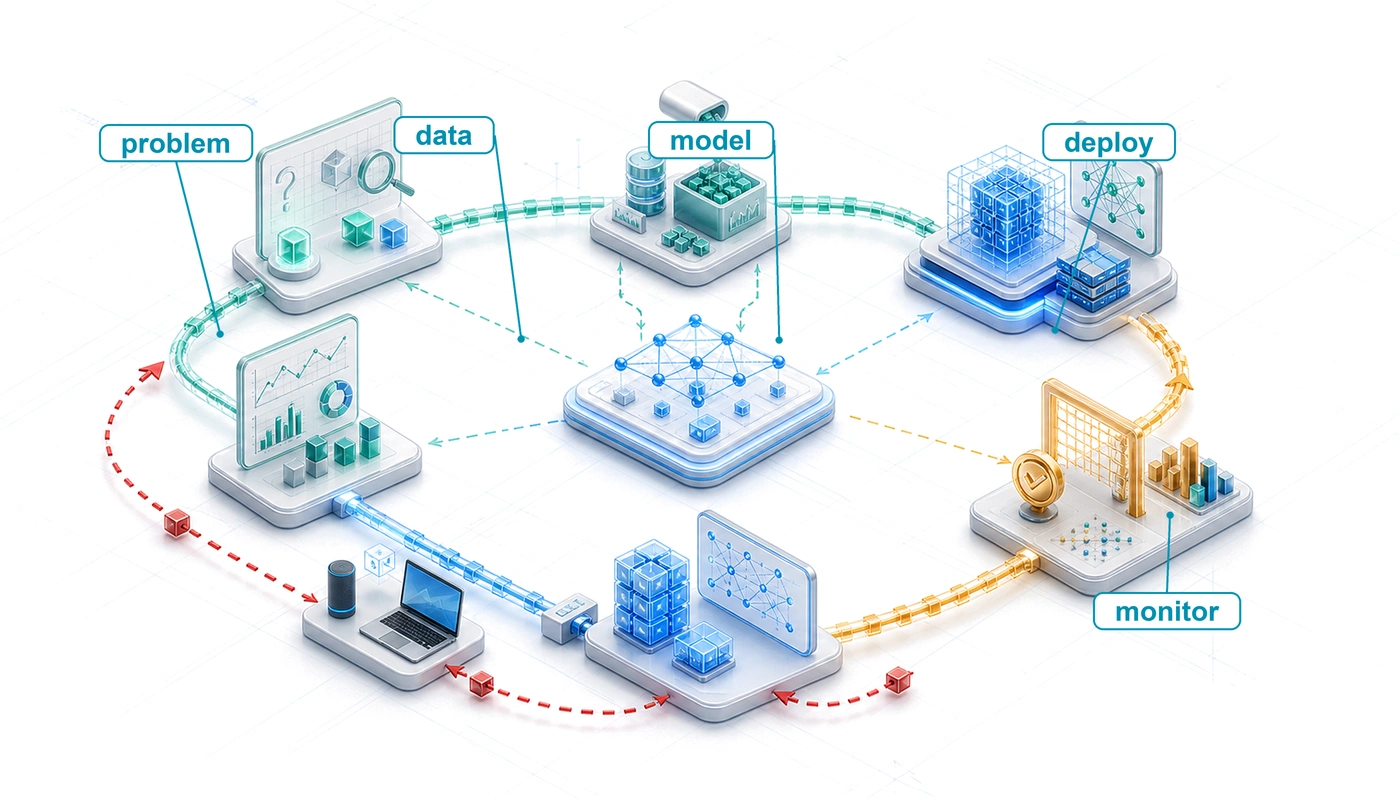
Understanding how these stages interconnect is essential before analyzing individual layers, as each technical domain—from storage pipelines (Data Engineering) to model training (Model Training), execution frameworks (ML Frameworks), and serving infrastructure (Model Serving)—operates as an interdependent system. In figure 1, the horizontal layout separates the top data pipeline from the bottom model development pipeline, with curved return vectors illustrating how operational insights and data defects cycle back into earlier stages.

The conceptual stages of the ML lifecycle establish the what and why of the development process. The operational layer constitutes the how: the implementation of this lifecycle through automation, tooling, and infrastructure. ML Operations names and develops those practices in detail. This distinction matters: the lifecycle is the conceptual framework; operational infrastructure is the machinery that implements it at scale.
Quantifying the ML lifecycle
Practitioner time allocation exposes where the lifecycle actually bottlenecks: engineering effort rarely concentrates where research literature spends its pages. Conceptual models of the ML lifecycle describe which stages exist, but systems decisions turn on quantitative reality—where engineering hours are spent, how much compute is consumed, and which pipeline stalls delay deployment.
Practitioner surveys reveal a stark asymmetry between where research attention centers and where engineering hours are spent, with data collection and preparation consuming 79 percent of practitioner time. In figure 2, a pie chart breaks down reported primary time sinks, contrasting the dominant data collection and preparation slices against the narrow share occupied by model architecture and algorithm tuning.

These survey proportions demonstrate why data engineering cannot be treated as mere preparatory plumbing. Data pipelines are the primary source of operational friction, iteration cycles, and system-level risk. Mastering data infrastructure (Data Engineering) provides maximum leverage before addressing the model architectures and training optimizations that ingest its output.
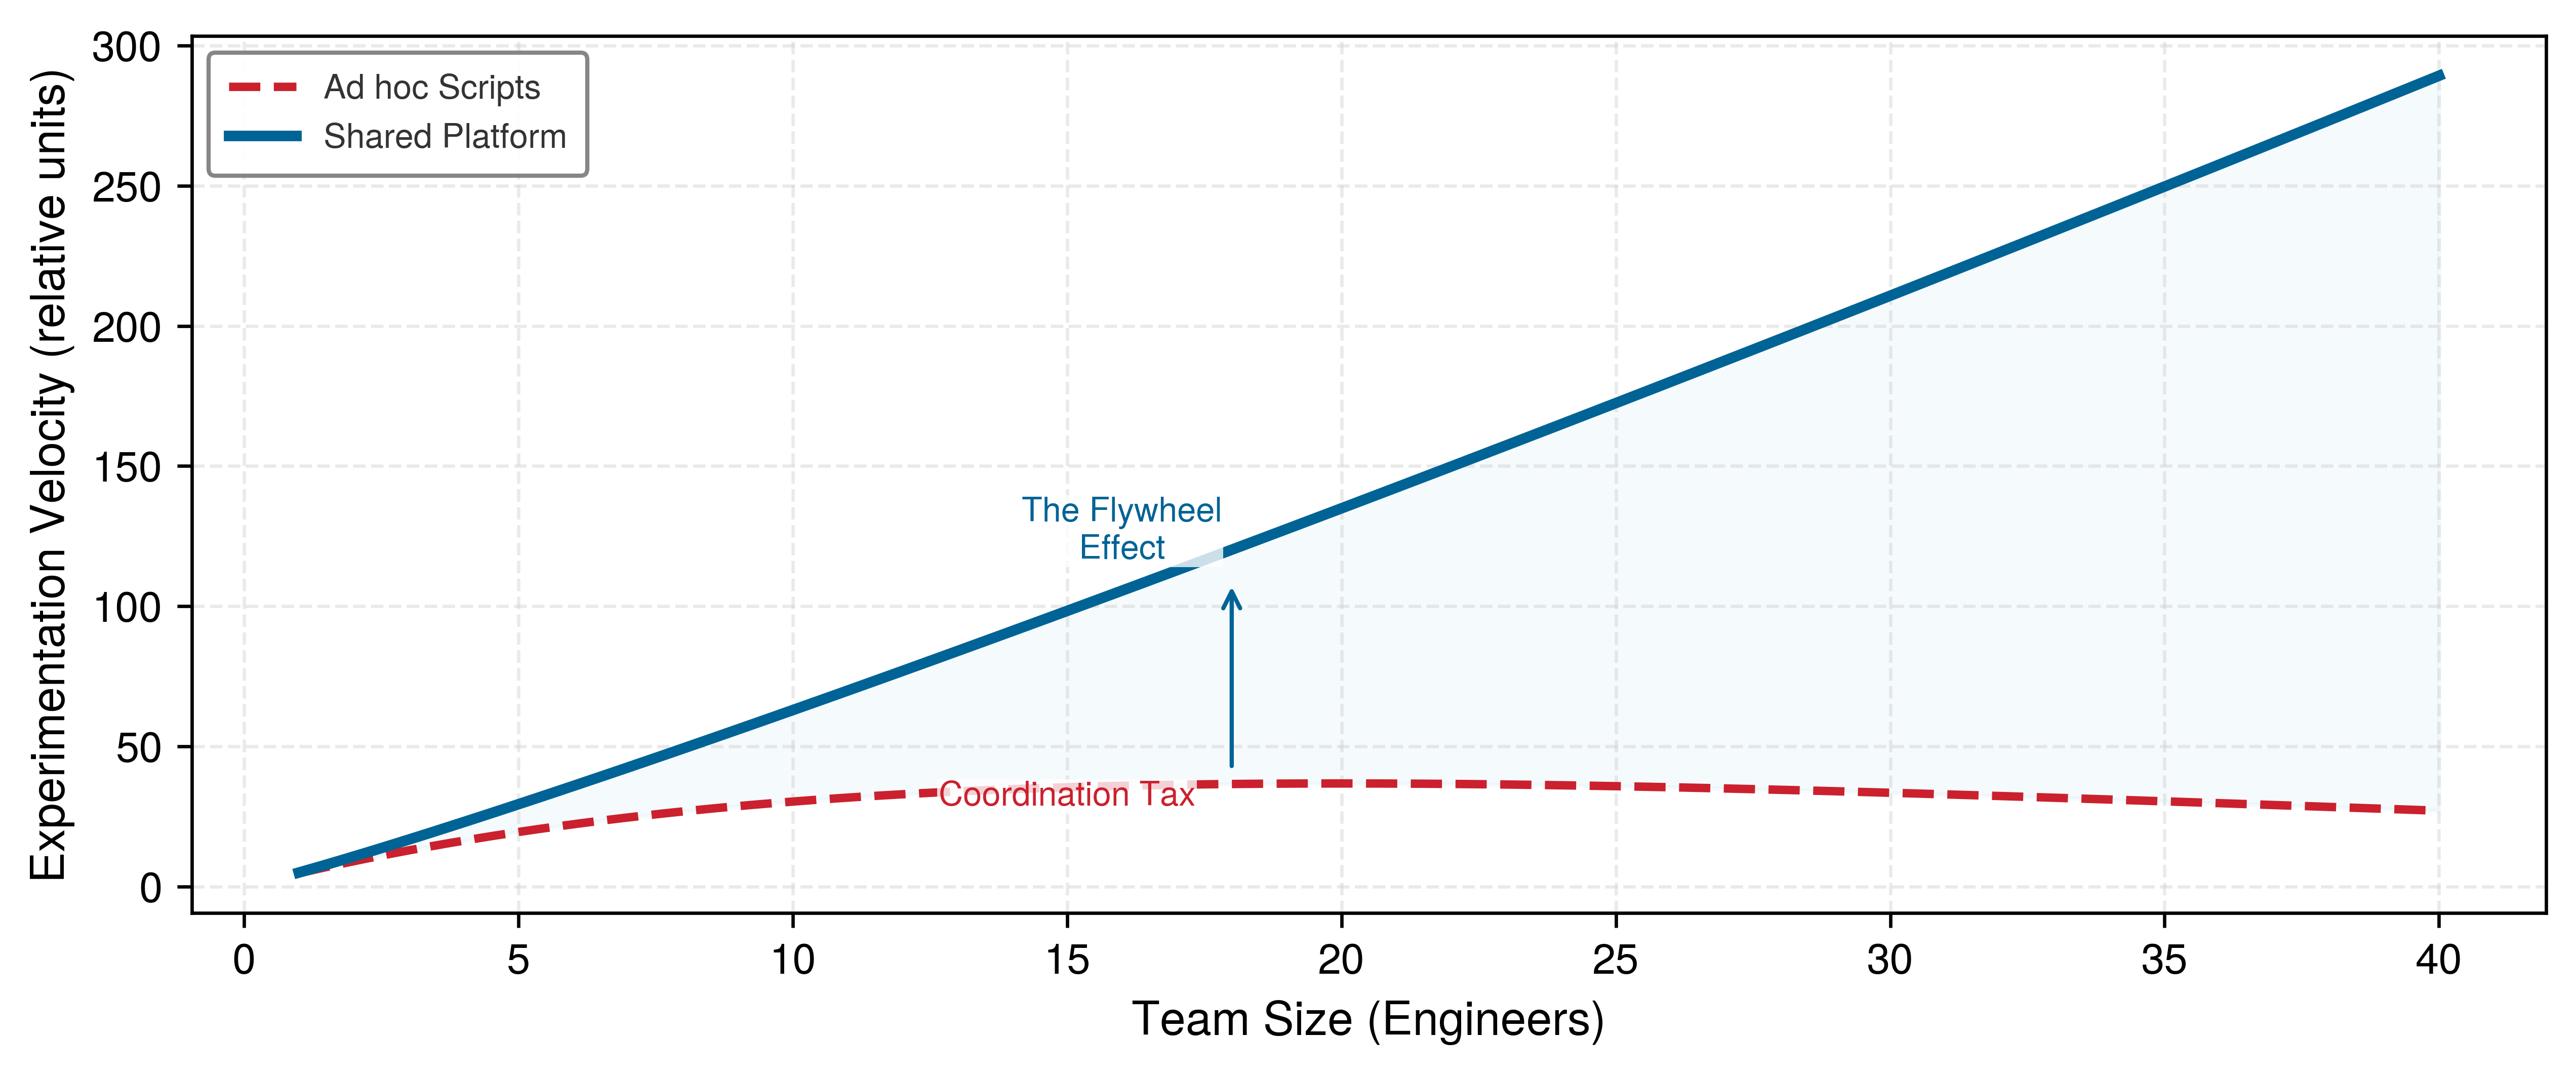
Beyond time allocation, iteration velocity governs project progress. The return vectors in figure 1 are not rare exceptions; they are paths teams traverse repeatedly. When data quality degrades through distribution shift or incorrect labels, rework sends teams back to collection. When an architecture exceeds accelerator memory or suffers numerical instability, engineers must revisit model design. When the serving layer exceeds latency budgets, the deployment pipeline stalls. Each loop consumes calendar time and compute budget, increasing development cost whenever downstream stages fail to catch violations early.
Under the stated assumptions, the faster-cycle model finishes slightly ahead after 26 weeks.
Napkin Math 1.1: The iteration tax
Problem: A DR screening system for rural clinics must choose between a large ensemble trained on high-resolution fundus images (training time: 1 week, accuracy: 95 percent) and a lightweight model suitable for edge deployment on clinic hardware (training time: 1 hour, accuracy: 90 percent). Which model has higher modeled accuracy after six months under these assumptions?
Math: In six months (~26 weeks), the possible experiment count is:
- Large model: 26 weeks of calendar time at 1 week per experiment. Each experiment improves accuracy by an assumed constant ~0.15 percentage points.
- Small model: 26 weeks of calendar time at 168 h/week gives 4,368 possible experiments at 1 hour each. Machine time is not the binding constraint at that cycle length, so this scenario counts only 100 of them as effective experiments, the number a team can realistically design, run, and learn from in six months. The remaining capacity sits idle for want of hypotheses. Even with a smaller assumed gain per iteration, more useful iterations can produce a larger cumulative gain.
Result: If each iteration improves accuracy by 0.1 percentage points on average, the small model starts at 90 percent and reaches 100 percent after 100 effective iterations, before applying the 99 percent ceiling. With the 99 percent ceiling applied, the small model achieves 99 percent. The large model starts at 95 percent and reaches 98.9 percent after 26 slower iterations. In practice, the small model’s rapid iteration enables discovering better architectures, label-preserving data augmentations, and tunable training settings.
Systems insight: Iteration velocity is a feature. When candidate systems have comparable attainable quality and useful experiments have similar expected value, shorter cycles expand how much of the design space a team can test. Speed alone cannot guarantee that a smaller model will outperform a larger one. In the DR screening scenario, the lightweight model’s rapid iteration cycle enables the team to experiment with label-preserving input transformations, preprocessing pipelines, and architecture variations far more quickly.
This cumulative delay defines the iteration tax: time spent waiting on slow training runs or cumbersome validation pipelines reduces how many candidate models a team can test. Late discoveries compound this penalty,3 as formalized by the constraint propagation principle (section 1.9.1). Violations discovered after deployment force expensive rollbacks across every preceding stage. This asymmetry demands explicit stage interface contracts: validating outputs at every stage boundary intercepts defects before they compound into systemic rework. Section 1.2.2 formalizes these contracts across the six stages.
3 Late correction costs: Boehm’s Software Engineering Economics (Boehm 1981) discussed how defects found late can cost more to fix than those caught during requirements. In ML systems, late-discovered constraints may require retraining, data-pipeline changes, and renewed validation. The doubling rule is an illustrative sensitivity scenario, not an empirical cost law.
Boehm, Barry W. 1981. Software Engineering Economics. Prentice-Hall.
The compounding cost of iteration delays and late discoveries reveals a broader structural reality: ML workflows are not slow versions of traditional software lifecycles. They differ fundamentally in where engineering effort concentrates, how feedback loops alter the system over time, and how late discoveries expand rework.
ML vs. traditional software
Traditional and ML systems can both use iterative lifecycles and exhibit nondeterministic behavior.4 The relevant distinction is how application behavior is specified. Rule-based software encodes explicit logic, while ML systems learn statistical mappings from data (ML vs. Traditional Software). This adds data, evaluation, and monitoring concerns to established software-engineering practices.
4 Waterfall model: A plan-driven lifecycle is often depicted as a sequence of requirements, implementation, and testing, but Royce (1970) warned that a purely sequential implementation was risky and described iteration between successive phases. ML systems add data and model feedback that must be managed explicitly. This chapter uses an illustrative sensitivity model for ML lifecycle stages.
Royce, Winston W. 1970. “Managing the Development of Large Software Systems.” Proceedings of IEEE WESCON 26: 328–88.
Machine learning systems therefore require additional workflow controls. Consider financial transaction processing: a deterministic authorization rule follows explicit logic and can execute quickly once its inputs are available. An ML-based fraud detector adds learned scoring, feature retrieval, and statistical decision logic. The model stage may take milliseconds, but end-to-end latency also depends on storage, networking, and surrounding services. This shift from explicit programming to learned behavior reshapes the development lifecycle, altering how teams establish reliability and robustness.
These differences alter how lifecycle stages interact. While conventional software engineering relies on production feedback to refine code and requirements, ML systems introduce feedback loops where operational data reshapes training distributions, detected drift prompts investigation, and runtime errors expose dataset blind spots. Table 1 contrasts traditional software and ML engineering across six core lifecycle dimensions, highlighting how data evolution redefines testing, deployment, and ongoing maintenance.5
5 Data versioning: Unlike code, which changes through discrete, auditable commits, data can drift gradually (distribution shift), suddenly (schema migration), or subtly (label quality degradation). Plain Git is impractical for many multi-terabyte datasets, so teams commonly version external-data manifests or pointers using tools such as DVC and Git LFS. Without data versioning, teams cannot reliably reproduce a prior training run or determine whether an accuracy regression stems from a code change or a data change.
| Aspect | Traditional Software Lifecycles | Machine Learning Lifecycles |
|---|---|---|
| Problem Definition | Precise functional specifications are defined upfront. | Performance-driven objectives evolve as the problem space is explored. |
| Development Process | Iterative code, configuration, and interface development. | Iterative experimentation with data, features, and models. |
| Testing and Validation | Many functional tests have exact expected results; performance and reliability remain quantitative. | Statistical validation and metrics that involve uncertainty. |
| Deployment | Behavior remains static until explicitly updated. | Performance may change over time due to shifts in data distributions. |
| Maintenance | Maintenance involves modifying code to address bugs or add features. | Continuous monitoring, updating data pipelines, retraining models, and adapting to new data distributions. |
| Feedback Loops | Production feedback commonly changes code, configuration, and requirements. | Insights from deployment and monitoring often refine earlier stages like data preparation and model design. |
Checkpoint 1.1: ML vs. traditional software
ML systems are not traditional software with a model attached. Check the differences that force a separate workflow:
Data locality at scale
Large ML data pipelines can stress the locality optimizations used by modern operating systems. Unlike traditional software pipelines that scan records sequentially, machine learning training deliberately shuffles examples across epochs to satisfy the independent and identically distributed (i.i.d.) sampling required by stochastic gradient descent. This algorithmic randomization directly conflicts with hardware and operating system assumptions: OS kernels rely on spatial and temporal locality,6 the tendency for a program that reads byte \(X\) to read nearby bytes soon and to reuse recently accessed memory.
6 Locality of reference: Denning (1968) formalized the working-set principle for virtual memory. Randomly ordered examples can reduce locality when the logical order maps to scattered physical reads, but the effect depends on storage layout, batching, caching, and prefetching.
Denning, Peter J. 1968. “The Working Set Model for Program Behavior.” Communications of the ACM 11 (5): 323–33. https://doi.org/10.1145/363095.363141.
When randomized sample order maps to scattered physical reads, shuffling can reduce the effectiveness of file-system buffers and virtual-memory prefetchers. The penalty depends on how logical examples map to physical storage. Contiguous reads from shuffled shards may retain useful locality, whereas small reads across many shards expose storage and network latency. Layout-aware batching, caching, and explicit prefetching can restore locality and reduce these stalls. The relevant systems variable is the physical access pattern presented to the memory hierarchy, not randomization alone.
That distinction determines where to optimize. If the loader already issues large sequential reads, more caching adds little benefit. If it fans out small reads across many shards, repacking records or increasing read granularity matters far more than adding compute. Profiling should trace the complete access path from storage to accelerator, measuring storage request size, queue depth, cache hit rate, and accelerator idle time together to prevent I/O bottlenecks from idling compute resources.
Self-Check: Question
Team A ships a diabetic retinopathy (DR) screening model and freezes all development once the model clears validation in the lab, treating subsequent tasks as standard server operations. Team B treats the launch as the beginning of an ongoing feedback loop, monitoring operational telemetry and data distributions to guide investigation and evidence-based model updates. Which team’s posture aligns with the ML lifecycle as defined in this chapter, and why?
- A. Team B, because the ML lifecycle is a closed loop where operational feedback, distribution drift, and real-world performance continuously reshape upstream data and model decisions.
- B. Team A, because once a model meets its offline validation thresholds, its statistical properties remain fixed and require only standard infrastructure maintenance.
- C. Team A, because changing a validated model in production introduces regulatory risk that outweighs the benefits of adapting to data drift.
- D. Team B, because the ML lifecycle mandates automatic daily retraining of production models regardless of whether input distributions have drifted.
In the chapter’s opening failure scenario, a team spends five months developing a diagnostic model that reaches 96 percent accuracy, only to have the entire project discarded on day 153. Explain the root cause of this failure from a workflow perspective and state the systems engineering rule that would have prevented it.
In the 2016 CrowdFlower data scientist survey cited in the text, respondents indicated that data-related tasks dominated their time, with 60 percent selecting ____ and organizing data as their largest time sink, compared to only 4 percent for refining algorithms.
True or False: Traditional software workflows and ML lifecycles differ fundamentally because ML system behavior can degrade through data distribution drift over time even when application source code, execution environment, and hardware configuration remain completely untouched.
A training pipeline randomly shuffles a multi-terabyte dataset across samples on every epoch, pulling records from storage backed by NVMe and spinning disks. Even though the hardware accelerator has ample peak compute capacity, training throughput stalls. Which explanation correctly identifies the systems-level bottleneck according to the chapter?
- A. Random shuffling makes the training workload strictly compute-bound, so the accelerator cores become overloaded by stochastic gradient calculations.
- B. Random sample access across multi-terabyte storage defeats operating system spatial and temporal locality, causing page cache misses and I/O latency stalls that additional compute cannot resolve.
- C. Shuffling multi-terabyte datasets bypasses the operating system page cache entirely, forcing floating-point arithmetic units to stall on instruction decoding.
- D. The memory hierarchy becomes saturated because the accelerator requires deterministic sample ordering to maintain kernel pipeline parallelism.
Lifecycle Stages
The rural-clinic failure shows why ML projects need an explicit six-stage framework: deployment constraints surfaced only after data, model, and evaluation decisions had hardened around the wrong target. Conventional and ML lifecycles both use iteration, while ML systems add feedback from deployment into data, training, and evaluation. The six-stage framework captures this loop.
The complete machine learning lifecycle distills into six core stages laid out across two functional rows. In figure 3, trace the top row from problem formulation through model evaluation, and follow the bottom row as deployment feeds monitoring signals back into upstream data collection.

MobileNetV2 grounds these stages in physical constraints, where a small footprint makes edge deployment limits visible from the outset. For MobileNetV2, problem definition establishes tight constraints: about 14 MB model size, about 600 MFLOP, and real-time inference on mobile-class hardware. Those constraints shape the rest of the workflow immediately. Data collection must account for on-device preprocessing limitations, and model development must choose an architecture whose operations fit the budget. MobileNetV2 achieves this through depthwise separable convolutions,7 factorizing spatial and channel operations rather than simply pruning parameters. Evaluation validates both accuracy and latency on target devices, deployment tests whether the model fits the device’s memory and power envelope, and monitoring tracks performance across diverse device populations. Each stage’s decisions propagate through subsequent stages, and the workflow framework makes these dependencies explicit. A DR screening model optimized for rural clinic deployment faces analogous pressures: limited device memory, strict power budgets, and the need for real-time inference without reliable connectivity. These shared constraints make DR an effective running case study.
7 Depthwise separable convolutions: Replacing a standard convolution with this cheaper factorization reduces computation by roughly 8–9\(\times\) for typical kernel sizes (Sandler et al. 2018), which is what makes the roughly 600 MFLOP inference budget plausible on mobile-class hardware. Network Architectures covers the architectural mechanism in depth.
Sandler, Mark, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, and Liang-Chieh Chen. 2018. “MobileNetV2: Inverted Residuals and Linear Bottlenecks.” 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition, 4510–20. https://doi.org/10.1109/cvpr.2018.00474.
Tracing MobileNetV2 through these transitions demonstrates that while a workflow diagram suggests sequential progression, production engineering is fundamentally cyclic, coupling downstream deployment constraints directly to upstream design.
Checkpoint 1.2: The workflow cycle
Verify that each stage enforces contracts that bind upstream choices to physical deployment constraints.
Beyond procedural orchestration, each lifecycle stage maps directly to specific terms in the performance equation. This mapping reveals a workflow-level manifestation of the iron law of ML systems (Iron Law of ML Systems): data preparation locks in byte volume, model development dictates operation count and hardware efficiency, and deployment infrastructure bounds fixed runtime overhead.
The binding constraint differs dramatically across workload archetypes, causing each lifecycle stage to optimize different iron law terms. ResNet-50, DLRM, and keyword spotting (KWS) are useful anchors because each stresses a different part of the system: dense vision training tries to keep accelerators busy, sparse recommendation spends much of its time moving embedding rows, and keyword spotting is constrained first by tiny memory and always-on energy budgets.
Production systems rarely fall neatly into a single archetype. A medical imaging classifier, for instance, requires sustained computation while training over large image datasets, yet faces strict energy and memory limits when deployed to portable clinic hardware. Understanding how the workflow framework adapts across these trade-offs is essential for sound engineering decisions. Table 2 shows how three selected workflow stages manifest for these recurring workload archetypes.
| Stage | ResNet-50 vision training | DLRM recommendation | KWS TinyML |
|---|---|---|---|
| Data Eng | Keep image batches available fast enough to sustain high GPU utilization. | Keep online feature-store lookups within the serving latency budget; embedding tables dominate storage and freshness. | Curate short audio clips for an SRAM-constrained device. |
| Training | Coordinate preprocessing, batching, mixed precision, and model execution to reduce accelerator idle time. | Optimize sparse embedding lookups because memory bandwidth limits throughput. | Search for the smallest model family that still recognizes the trigger phrase reliably. |
| Deploy | Use large batches when throughput and cost matter more than single-request latency. | Meet strict interactive p99 latency targets while keeping features fresh. | Stay within a strict always-on energy budget. |
Each stage of this workflow presents distinct systems challenges, from curating multi-terabyte datasets to sustaining tail latency in production. Grounding these challenges requires a quantitative lens on how stages govern execution.
Systems Perspective 1.1: The iron law of workflow
The six lifecycle stages alter distinct terms in the iron law of ML systems \((T = \frac{D_{\text{vol}}}{\text{BW}} + \frac{O}{R_{\text{peak}} \cdot \eta_{\text{hw}}} + L_{\text{lat}})\). Rather than rigid one-to-one assignments, the mappings serve as diagnostic starting points:
- Problem definition: Sets target constraints for accuracy, latency, cost, privacy, and deployment paradigm. These targets determine which terms of the equation are permitted to grow and which must be bounded from the outset.
- Data collection and preparation: Shapes dataset composition and the byte volume \((D_{\text{vol}})\) presented to downstream pipelines. Curation can also change the training work required to reach a quality target.
- Model development and training: Dictates the operation count \((O)\), data reuse patterns, parameter movement, and achievable hardware efficiency \((\eta_{\text{hw}})\).
- Evaluation and validation: Tests whether model quality and end-to-end execution meet deployment requirements on the target system.
- Deployment and integration: Determines the serving path, including runtime data movement, execution efficiency, and fixed overhead \((L_{\text{lat}})\).
- Monitoring and maintenance: Observes distribution drift, latency, throughput, and operational cost after launch, feeding violations back into earlier stages for re-optimization.
Viewing the lifecycle through the iron law grounds latency and cost in hardware physics. Production workflows must simultaneously satisfy accuracy, safety, privacy, and organizational constraints that sit outside the equation.
Case study: DR screening
Diabetic retinopathy (DR) screening serves as the running case study throughout this chapter because it passes three critical tests: it appears straightforward on the surface but reveals deep operational friction in practice, it exercises the full deployment spectrum from cloud training to edge inference, and its challenges are thoroughly documented across real-world deployments. The literature spans both sides of the lab-to-field divide: Gulshan et al. (2016) document the benchmark validation study for automated DR detection, while Beede et al. (2020) document the workflow and infrastructure failures that emerged when a deep-learning system was deployed in Thai clinics. Together, these sources provide an empirical baseline tracking data collection and validation through to physical deployment constraints.
8 Diabetic retinopathy (DR): DR is a common complication of diabetes; early detection can prevent vision loss, but specialist access varies substantially across countries. This gap motivates scalable screening programs. In clinics with limited hardware or unreliable connectivity, model size, offline capability, latency, and workflow integration can become binding deployment constraints.
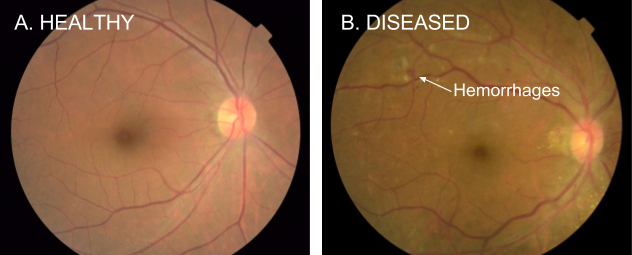
Diabetic retinopathy is a leading cause of preventable blindness.8 Limited specialist access in low-resource regions motivates automated screening programs, but detecting the disease requires identifying subtle pathological features. Figure 4 contrasts a healthy retina with one exhibiting diabetic retinopathy, where identifying localized microvascular hemorrhages demands fine spatial resolution and robust input validation.
Initial research achieved expert-level performance in controlled settings. However, translating laboratory models into clinical deployment exposed severe operational friction: sensor lighting variations, intermittent network connectivity in rural clinics, regulatory compliance, and clinic workflow integration.9 For the metrics that recur in this case, sensitivity is the true-positive rate, specificity is the true-negative rate, and AUC is the area under the receiver operating characteristic (ROC) curve. The same constraint propagation dynamics apply whether deploying medical diagnostics to rural health posts or computer vision to commodity smartphones: hardware limits, operator variance, and data quality govern real-world viability far more than benchmark AUC.
9 Healthcare AI deployment gap: In the Thai DR deployment studied by Beede et al. (2020), real clinics exposed workflow, image-quality, infrastructure, and human-factors constraints that were absent from controlled evaluation. The case shows why laboratory metrics alone do not establish deployment readiness.
Beede, Emma, Elizabeth Baylor, Fred Hersch, Anna Iurchenko, Lauren Wilcox, Paisan Ruamviboonsuk, and Laura M. Vardoulakis. 2020. “A Human-Centered Evaluation of a Deep Learning System Deployed in Clinics for the Detection of Diabetic Retinopathy.” Proceedings of the CHI Conference on Human Factors in Computing Systems (CHI), 1–12. https://doi.org/10.1145/3313831.3376718.
Stage interface specification
Each lifecycle stage operates as a distinct engineering phase with defined inputs, outputs, and quality invariants. In production workflow engines, these contracts are formalized across a workflow directed acyclic graph (DAG), where nodes represent discrete execution tasks and directed edges represent validated artifact dependencies. While the overarching ML lifecycle forms a cyclic feedback loop over weeks and months, each automated pipeline run executes as an acyclic graph of dependent steps, enabling orchestrators to parallelize independent branches, cache validated intermediate outputs, and halt execution before broken contracts propagate downstream. Just as microservices rely on interface specifications to establish integration boundaries, ML pipeline stages require schema and distribution contracts to detect incompatibilities before invalid data or degraded weights propagate downstream. Table 3 formalizes these contracts, defining the input requirements, deliverables, and quality invariants required across all six lifecycle stages.
| Stage | Input Contract | Output Contract | Quality Invariant |
|---|---|---|---|
| Problem Definition | Business requirements; operational context | Measurable objectives; deployment paradigm selection; resource constraints | All success criteria are quantifiable; target deployment paradigm is explicit |
| Data Collection & Preparation | Objectives; deployment target; quality requirements | Versioned dataset with schema; preprocessing pipeline; data validation rules | Distribution approximates anticipated production environment; labeling meets accuracy requirements |
| Model Development & Training | Dataset; accuracy targets; resource constraints | Trained model weights; training configuration; experiment logs | Meets accuracy thresholds within computational budget; architecture compatible with deployment target |
| Evaluation & Validation | Trained model; held-out test data; evaluation criteria | Performance metrics across subgroups; failure mode analysis; validation certificate | No critical subgroup falls below minimum thresholds; confidence calibration meets domain requirements |
| Deployment & Integration | Validated model; infrastructure requirements; service-level agreement (SLA) targets | Serving endpoint; monitoring instrumentation; rollback procedures | Latency and throughput meet paradigm requirements; integration tests pass |
| Monitoring & Maintenance | Live system; performance baselines; alert threshold | Drift detection alerts; update-review criteria; incident reports | Alert coverage and detection windows are defined; detected degradation triggers review |
This specification reveals why ML projects experience the iteration cycles diagrammed in figure 3. When a downstream stage discovers that an upstream contract was violated (for example, evaluation reveals the training data distribution does not match production), the project must iterate back to fix the root cause. Teams that validate contracts at each stage transition catch violations early, when correction costs are lowest. Validating stage contracts before advancing prevents defects from compounding into late-stage redesigns, as illustrated in the transition audit below.
Example 1.1: Auditing stage transitions
Scenario: An engineering team claims to have completed Problem Definition for a medical imaging classifier, attempting to transition to Data Collection without establishing deployment target constraints.
Diagnosis: The output contract lacks deployment paradigm selection and resource constraints (latency and memory targets). Attempting to deploy late in the lifecycle exposes violations (e.g., edge device memory limit < 200 MB), incurring 16× the cost compared to early correction.
Systems lesson: Stage transitions act as control-plane quality gates in the ML lifecycle. Enforcing strict output contract validation before proceeding downstream prevents expensive upstream rework and ensures data collection aligns with target deployment hardware.
Without explicit contract gates, unstated assumptions propagate downstream. The earliest opportunity to bound them is Problem Definition, which records the operational constraints that subsequent stages must satisfy.
Self-Check: Question
Order the following lifecycle phases in the canonical sequence established in the chapter for a new ML system project: (1) Deployment and Integration, (2) Problem Definition, (3) Monitoring and Maintenance, (4) Data Collection and Preparation, (5) Model Development and Training, (6) Evaluation and Validation.
An engineering team completes Problem Definition with clinical sensitivity targets but marks the target deployment paradigm as ‘TBD — to be determined after model training.’ According to the Stage Interface Specification, what should the transition audit verdict be, and why?
- A. Approved, because decoupling model development from hardware targets allows researchers to maximize accuracy before applying post-hoc pruning.
- B. Approved with warning, provided the team commits to using cloud inference if the model exceeds edge memory budgets.
- C. Blocked, because Problem Definition’s output contract explicitly requires deployment paradigm and resource constraints to be established before data collection and modeling begin.
- D. Blocked only if the model architecture requires distributed multi-GPU training, since single-device models can adapt to any deployment target.
The chapter discusses MobileNetV2 with its ~600 MFLOPs inference budget as a lighthouse case study for workflow thinking. Explain how establishing this mobile constraint at Problem Definition propagates across Data Collection, Model Development, and Evaluation.
Which mapping between lifecycle stages and the terms in the Iron Law of ML Systems ( = + + L_{}$) is conceptually correct according to the chapter?
- A. Problem Definition governs {}$; Evaluation governs $; Monitoring governs \(\text{BW}\).
- B. Data Collection sets {}$; Model Development sets \(\text{BW}\); Deployment sets {}$.
- C. Deployment governs \(; Model Development governs {\text{vol}}\); Data Collection governs {}$.
- D. Data Collection and Preparation shapes $ and {}$; Model Development and Training sets \(; Deployment and Integration minimizes {\text{lat}}\).
To prevent defect propagation across lifecycle boundaries, the chapter formalizes each stage boundary using a(n) ____ contract, which defines required inputs, output deliverables, and non-negotiable quality invariants.
Problem Definition
Problem definition in ML begins with sentences that look deceptively simple. A product manager writes: “Build a model that detects diabetic retinopathy.” That single sentence conceals a dozen engineering decisions: sensitivity thresholds for patient safety, hardware capabilities in rural clinics, latency budgets that keep clinicians engaged, and regulatory frameworks governing approval. In traditional software, requirements translate into deterministic control flow, explicit state machines, and relational schemas. In ML systems, defining what the system should do is inseparable from defining how it will learn from data and what physical constraints its execution must survive.
Balancing these demands requires reasoning across the full system stack. An engineering team cannot optimize accuracy in isolation: pursuing marginal sensitivity gains by scaling model depth or switching to vision transformers inflates parameter count and arithmetic intensity, directly challenging the memory capacity and thermal limits of low-cost clinic hardware. Conversely, pruning a model to fit an embedded accelerator’s DRAM budget risks dropping sensitivity below clinical safety thresholds. Every technical decision operates within a multi-constraint optimization problem where statistical goals, physical execution budgets, and operational mandates continually bound each other’s feasible design space.
Constraint layers
Every ML problem definition decomposes into three interacting constraint layers: statistical, physical, and operational. Rather than isolated requirements, these layers form a coupled stack where constraints in one tier immediately restrict the degrees of freedom in the others. The statistical layer specifies target behavior over data distributions—such as achieving \(>90\) percent sensitivity and \(>80\) percent specificity across diverse patient demographics and camera models, rather than an unweighted aggregate accuracy that conceals failure modes on minority subpopulations. The physical layer bounds execution within hardware limits: for rural clinics, inferencing on local edge accelerators under tight thermal budgets, bounded memory capacity (such as 4 to 8 GB of shared DRAM), and sub-second latency budgets to keep clinical workflows interactive without depending on intermittent network uplinks. The operational layer encompasses clinical auditability, regulatory clearance, and governance frameworks that dictate long-term system maintenance.
The operational layer carries physical consequences that traditional software engineering rarely encounters. In a traditional database, deleting a patient’s record is a DELETE statement. In an ML system, model weights may encode statistical patterns learned from that record: where law or a regulator requires removing that influence, compliance may require machine unlearning (an active research area with incomplete guarantees) or retraining on the remaining data. The obligation and remedy depend on the governing rule and system; at DR-system scale, either can make privacy compliance a recurring compute-budget item and training provenance an architectural constraint.
The constraint propagation principle (section 1.9.1) explains why all three layers must be bound before development begins: a constraint that exists in the physical or operational environment but remains unstated in the problem definition does not vanish—it re-emerges later as an architectural violation after dependent decisions have hardened. For example, if an engineering team defines the objective solely as aggregate classification accuracy on retinal images, standard optimization will minimize cross-entropy loss across the majority class. In an imbalanced screening population where 90 percent of patients are healthy, a model predicting “no disease” achieves 90 percent aggregate accuracy while failing every patient who needs urgent care. Preventing this requires translating domain invariants—the asymmetric cost of a missed diagnosis—into an explicit statistical contract that binds the loss formulation to the deployment hardware budget.
War Story 1.1: When the label was the bias (2018)
Context: In 2014, Amazon assembled an engineering team at its Edinburgh hub to build an internal machine-learning system for ranking technical job applicants, training it on ten years of resumes submitted to Amazon (Dastin 2018).
Mechanism: Because prior hiring was male-dominated, the model learned that male-coded language correlated with hiring success, systematically penalizing terms like “women’s” and downgrading graduates of all-women’s colleges.
Impact: The model reproduced historical hiring bias, rendering automated resume screening unsuitable for production recruitment.
Fix: Amazon abandoned the experimental tool after attempts to remove explicit gender signals could not guarantee that it would not learn other discriminatory proxies.
Systems lesson: Problem definition must specify fairness, auditability, and rejection criteria before data collection and training. A workflow trained on biased labels does not learn the operational goal; it learns to reproduce the labels.
Dastin, Jeffrey. 2018. “Amazon Scraps Secret AI Recruiting Tool That Showed Bias Against Women.” Reuters.
Problem definitions evolve
A problem definition is not a static specification frozen at project inception; it evolves as deployment expands. When a DR screening program scales from a pilot clinic with a calibrated fundus camera to regional health centers with heterogeneous imaging hardware and differing patient demographics,10 the initial assumptions break. Sensor noise profiles diverge, optical resolutions shift, and demographic variations alter subgroup error rates. Adapting to this operational reality forces the problem definition to incorporate stratified accuracy targets and broader hardware compatibility matrices.
10 Demographic drift: Population changes can expose performance gaps that aggregate evaluation obscures. Facial-analysis benchmarks found large demographic error-rate disparities (Buolamwini and Gebru 2018), while a healthcare risk-scoring study found racially biased allocation from a proxy label despite similar need (Obermeyer et al. 2019). These examples illustrate why a growing DR program should evaluate subgroup performance rather than claiming that such a rollout occurred.
Buolamwini, Joy, and Timnit Gebru. 2018. “Gender Shades: Intersectional Accuracy Disparities in Commercial Gender Classification.” Conference on Fairness, Accountability and Transparency, 77–91.
Obermeyer, Ziad, Brian Powers, Christine Vogeli, and Sendhil Mullainathan. 2019. “Dissecting Racial Bias in an Algorithm Used to Manage the Health of Populations.” Science 366 (6464): 447–53. https://doi.org/10.1126/science.aax2342.
This dynamic evolution stems directly from the statistical nature of ML. Scaling exposes long-tail inputs absent from pilot evaluations, while production environments introduce covariate shift that no static offline dataset fully captures. A robust problem definition anticipates this drift by establishing governance protocols upfront: defining which monitoring signals trigger formal re-evaluation and bounding how threshold updates propagate through subsequent pipeline stages. Once these operational constraints and performance boundaries are defined on paper, the workflow must ground them in physical artifacts—beginning with the data collection pipelines that gather the training distribution.
Self-Check: Question
Why does the statement ‘Build a computer vision model that detects diabetic retinopathy’ fail as a complete problem definition for an ML system?
- A. It specifies only a high-level task while omitting the statistical constraint layers (sensitivity/specificity floors across subgroups), physical constraints (edge device memory/latency budgets), and operational constraints (regulatory compliance, clinical workflow integration).
- B. It fails to specify which exact deep neural network backbone and learning rate schedule must be used during training.
- C. It defines an image classification problem when medical AI systems must always be framed as unsupervised anomaly detection tasks.
- D. It defines quantifiable objectives before data collection has occurred, which violates standard ML agile practices.
Explain why ophthalmologists and clinic administrators must participate directly in Problem Definition for a DR screening system, rather than being consulted only during clinical evaluation.
In the 2018 Amazon automated recruiting war story cited in the chapter, an ML model trained on ten years of resumes was abandoned because it systematically penalized female applicants. What fundamental systems lesson does this case illustrate regarding Problem Definition?
- A. Resume screening models require recurrent neural networks rather than transformer architectures to avoid learning gendered proxies.
- B. Offline evaluation metrics are inherently incapable of measuring demographic disparities in supervised learning models.
- C. A model trained on historical data learns to reproduce historical label biases rather than the intended operational goal; fairness criteria and auditability must be explicitly defined at Problem Definition.
- D. Multi-class classification algorithms should not be applied to human evaluation tasks where ground truth is subjective.
True or False: When a diabetic retinopathy screening deployment scales from a 3-clinic pilot to 200 clinics across diverse regions, the high-level clinical intent (detect referable retinopathy early) remains stable, but the specific engineering targets (subgroup sensitivity thresholds, device latency budgets, and camera-specific preprocessing rules) must evolve.
Data Collection
Constraints defined on paper only take effect when grounded in actual data. Moving from problem definition to data collection connects abstract accuracy targets with operational reality: sensor noise, missing records, and network limits. In iron law terms, this stage determines dataset size \((D)\) and the byte volume \((D_{\text{vol}})\) that storage systems, networks, and memory buses must move. The deployment constraints established during problem definition become technical data requirements: if the model must run on edge devices, the collection pipeline must produce inputs compatible with edge preprocessing; if it must achieve 90 percent sensitivity across diverse populations, the dataset must sample those subpopulations sufficiently to support model training.
Data collection and preparation is an ongoing engineering discipline rather than a one-time task (Data Engineering). For DR screening, the pipeline must ingest images statistically diverse enough to generalize across clinics, robust enough to handle varying capture conditions, and annotated with enough clinical rigor to withstand regulatory audits.
Problem definition decisions shape data requirements in the DR example. The multi-dimensional success criteria established (accuracy across diverse populations, hardware efficiency, and regulatory compliance) demand a data collection strategy that goes beyond typical computer vision datasets. Not all data contributes equally to learning, either—Data Selection shows how selection can retain comparable performance with less compute when a dataset contains redundancy, provided the selected subset preserves the evidence the task requires.
The DR system requires on the order of \(10^5\) retinal fundus photographs, each reviewed by multiple expert ophthalmologists. Expert consensus addresses the inherent subjectivity in medical diagnosis (two ophthalmologists may disagree on borderline cases) while establishing ground truth labels that can withstand regulatory scrutiny. The annotation process must capture clinically relevant features like microaneurysms, hemorrhages, and hard exudates across the full spectrum of disease severity.
Raw high-resolution retinal scans can reach tens of megabytes per image before compression, creating substantial infrastructure challenges. A clinic processing dozens of patients per day can produce gigabytes to tens of gigabytes of imaging data per week. This data volume can occupy much of a limited uplink during clinic hours, making local processing one option alongside compression, batching, scheduling, or increased link capacity.
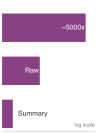
Edge summaries beat raw medical-image uploads when bandwidth dominates.
Napkin Math 1.2: Bandwidth vs. compute
Problem: A rural clinic captures retinal images for DR screening. How much of the assumed same-shift uplink window would raw uploads occupy, and what alternatives reduce that occupancy?
Math:
- Daily data: At 150 patients/day, 10 photos/patient, and 5 MB/photo, the clinic produces 7.5 GB/day.
- Upload time: The uplink is 2 Mb/s, or 0.25 MB/s. Dividing 7,500 MB by that rate gives 30,000 s, approximately 8.3 h.
- Constraint: If the clinic requires same-shift upload during its 8 h operating window, this transfer alone occupies the link for 104.2 percent of that window and may contend with other traffic.
Systems insight: Local inference with uploaded detection summaries (10 KB/patient) reduces bandwidth usage by 5,000×. Overnight batching, compression, scheduling, or a faster link are alternatives not compared by this calculation.
Lab-to-field data gap
Laboratory data and production data inhabit different worlds. This lab-to-field gap appears when DR screening deploys to rural clinics across Thailand and India: images arrive from diverse camera equipment operated by staff with varying expertise, often under suboptimal lighting with inconsistent patient positioning. A model trained on high-quality research images from standardized fundus cameras may fail on blurry, poorly-lit images from older equipment—not because the algorithm is wrong, but because the data distribution has shifted beyond the training envelope.
Because raw image uploads can exceed clinic uplink capacity, edge deployment offers an alternative. Deploying edge accelerators such as the NVIDIA Jetson family11 allows clinics to preprocess and run inference locally. This reduces network transmission by orders of magnitude, but introduces a hardware trade-off: use a smaller model that fits a low-power edge budget, or provision more capable on-premise devices at higher cost.
11 NVIDIA Jetson: NVIDIA’s Jetson family spans a wide SKU spectrum, from Jetson Orin Nano (7–15 W) through Jetson Orin NX (10–25 W) to Jetson AGX Orin (15–60 W). This scenario uses an Orin Nano-class device (4–8 GB shared LPDDR5, 7–15 W power envelope) as a concrete edge target. Its memory and power budgets constrain model complexity, while selecting a larger device changes both the feasible model and the per-clinic cost.
The bandwidth constraint makes infrastructure a data-collection decision rather than a late implementation detail. The scenario architecture combines edge devices for local inference and preprocessing, clinic aggregation servers for data management and buffering, and cloud training infrastructure for periodic model updates. It targets end-to-end latency under 100 milliseconds and operation without connectivity-induced delays.
Privacy constraints impose a similar architectural decision. Patient privacy regulations may motivate local retention or distributed training, but they generally specify protections and permitted uses rather than one required training topology. Workflows that keep raw clinic data local while sharing only approved updates or summaries add complexity to both data collection and model training infrastructure.
Distributed data infrastructure
If a deployment grows from a handful of clinics to hundreds, data infrastructure must scale accordingly. Each retinal image travels through multiple stages: clinic cameras capture the image, local systems provide initial storage and processing, quality validation checks ensure usability, secure transmission moves data to central systems, and finally, integration with training datasets completes the pipeline. The infrastructure decisions at each stage are shaped by the deployment constraints established during problem definition.
Storage tiers are another place where the data pipeline either preserves or erodes downstream iteration velocity. Different data access patterns demand different storage solutions, so teams typically implement tiered storage architectures,12 each calibrated to access frequency and performance requirements.
12 Tiered storage: Places data on different storage media based on access frequency and performance requirements. The storage price gap is roughly 4.3× in this example: Non-Volatile Memory Express (NVMe) SSDs deliver 500,000+ input/output operations per second (IOPS) at ~$0.10/GB/month, while object storage costs ~$0.023/GB/month but with 100–200 ms latency. For ML training loops requiring sustained sequential reads at 1–10 GB/s, choosing the wrong tier converts a compute-bound training pipeline into an I/O-bound one, directly inflating the iron law’s data term \((D_{\text{vol}}/\text{BW})\).
Hot storage uses high-throughput NVMe SSDs for data currently used in training loops. Warm storage uses S3-compatible object storage for recent datasets and active validation sets. Cold storage uses low-cost archival systems, such as AWS Glacier, for historical data required for regulatory audit trails but rarely accessed.
In practice, the boundary between tiers is dynamic: a dataset migrates from warm to hot when selected for the next training run, and from hot to cold when the model it trained is superseded. Automated lifecycle policies manage these transitions, promoting data based on training schedules and demoting it based on access recency—a pattern that Data Engineering explores in detail.
Rural clinic deployments face severe connectivity constraints that force a choice between transmission strategies. Clinics with reliable broadband can stream images in near-real-time for centralized processing, but clinics with intermittent satellite links, common in remote regions of India and sub-Saharan Africa, require store-and-forward architectures that batch images during connectivity windows and reconcile results asynchronously. The choice propagates through the entire stack: store-and-forward clinics need larger local storage buffers, more robust local inference capabilities, and conflict-resolution logic when locally generated predictions differ from later cloud-based analysis.
Infrastructure scalability poses a harder challenge than raw capacity. As the system grows from a handful of pilot clinics to hundreds of production sites, data heterogeneity grows alongside data volume: each clinic’s camera model, lighting environment, and operator habits can produce a different image distribution. The infrastructure must handle increasing throughput while also tracking which data came from where. This provenance metadata proves essential for debugging accuracy regressions at specific sites and for satisfying the audit trail requirements that regulatory validation demands. Scaling from initial clinics to a broader network therefore introduces emergent complexity: variability in equipment, workflows, operating conditions, and image sizes as newer clinics add higher-resolution devices. Each clinic becomes a distinct data source,13 yet the system must evaluate performance across the full network.
13 Distributed clinic data: Training across clinic sites without simply pooling all raw data addresses privacy and governance constraints, but it shifts cost into coordination. Each site may use different cameras, serve different patient populations, and follow different operating routines, so the system must track where data came from and how each site differs. The workflow cost is therefore not just storage capacity; it is the engineering work needed to compare, validate, and update models across sites whose data does not behave identically.
The workflow response is coordination infrastructure. Shared artifact repositories, versioned APIs, and automated testing pipelines make clinic-specific variation visible before it becomes a model failure. That same heterogeneity is what makes point-of-capture validation necessary: the larger and more varied the clinic network becomes, the less useful it is to discover quality failures weeks later in a centralized training run.
Quality assurance and validation
A blurry retinal image that slips past quality checks does not merely waste storage. If such images enter training with unreliable labels or appear frequently in production, they can distort the evidence available to the model and increase error risk. Quality assurance ensures that data meets the requirements downstream stages depend on. In our DR example, automated checks at the point of collection flag issues like poor focus or incorrect framing, allowing clinic staff to recapture images immediately rather than discovering the problem weeks later during model training.
Validation extends beyond image quality to verify proper labeling, patient association, and privacy compliance. Local validation catches problems at the point of capture; centralized validation detects distributional anomalies across the full clinic network—for instance, flagging when a particular site’s images skew toward a narrow demographic range that would bias the training set.
Data collection decisions directly constrain model development: bandwidth limits dictate what architectures are feasible, privacy requirements shape training pipelines, and quality variations across clinic environments determine robustness requirements. Figure 5 traces these feedback pathways concretely. Follow each labeled arrow: evaluation reveals the DR model underperforms on images from older fundus cameras, triggering targeted data collection from clinics using that equipment. Validation across diverse patient populations shows lower sensitivity for patients with cataracts, driving data augmentation strategies that simulate lens opacities. Monitoring detects accuracy drift in clinics that upgraded their imaging equipment, feeding back to update preprocessing steps.

These feedback pathways reinforce a central point: data collection does not end when training begins. The quality, volume, and diversity of the data flowing through these pipelines now become the raw material for the next stage—turning curated datasets into trained models.
Self-Check: Question
A rural clinic captures 150 patients per day for DR screening, with 10 retinal photos per patient at 5 MB per photo. The clinic operates on an 8-hour daily shift with a 2 Mbps uplink. According to the chapter’s Bandwidth vs. Compute analysis, what operational bottleneck arises, and how does edge inference resolve it?
- A. Daily raw image upload requires ~2.5 hours, which fits comfortably within the 8-hour window without needing edge processing.
- B. Daily raw image upload generates 7.5 GB of data requiring ~8.3 hours to transfer—saturating the entire 8-hour clinic shift—whereas edge inference uploading 10 KB detection summaries reduces network traffic by roughly 5,000\(\times\).
- C. Daily raw image upload generates 75 GB of data, which exceeds daily satellite uplink capacity by a factor of 100\(\times\) regardless of compression.
- D. Raw uploads complete in 45 minutes, but cloud GPU queuing delay adds 12 hours of fixed inference latency.
Explain why a DR screening model achieving an AUC of 0.99 on a curated laboratory research dataset can experience a severe drop in sensitivity (e.g., falling to 78 percent) when deployed to rural clinics across Thailand and India.
In tiered storage architectures for ML pipelines, placing active training data in cold or warm object storage (e.g., S3 Standard with 100–200 ms latency) instead of local high-throughput NVMe SSDs directly degrades training performance by affecting which term in the Iron Law of ML Systems?
- A. It increases the Operations ($) term by forcing the model to compute extra gradient updates.
- B. It decreases peak hardware performance ({}$) by downclocking GPU compute cores.
- C. It decreases hardware utilization efficiency (\(\eta_{\text{hw}}\)) solely through floating-point precision mismatches.
- D. It inflates the data movement time (\(\frac{D_{\text{vol}}}{\text{BW}}\)), converting a compute-bound training pipeline into an I/O-bound stall where accelerators sit idle waiting for data batches.
True or False: In large-scale medical data collection, if collected images pass basic file format and schema validation, image-quality defects (such as blur, low contrast, or partial occlusion) can be safely ignored because deep neural networks naturally learn to filter out bad samples when trained on sufficiently large datasets.
In rural clinics with intermittent connectivity, an architecture that buffers captured images locally and reconciles inference results asynchronously with the central cloud during available network windows is known as a(n) ____ architecture.
Model Development
The DR team has 128,000 labeled retinal images, a validated preprocessing pipeline, and a target: more than 90 percent sensitivity on edge hardware with less than 50 ms inference latency. The question is no longer what data to collect but what model to build—and that question has no answer independent of the deployment constraints already established. In iron law terms, this stage defines the Operations \((O)\) term: architectural choices set the computational floor that hardware must sustain. Training systems (Model Training) must coordinate data ingestion, distributed parameter synchronization, and hyperparameter exploration14 without stalling execution pipelines. In high-stakes domains like healthcare, every design decision affects clinical outcomes, so technical performance and operational constraints must be integrated from the start.
14 Hyperparameter: Architectural and optimizer choices (for example, learning rate and network depth) affect the computational work of training. A naive Cartesian grid that trains every combination independently incurs a multiplicative search cost: 5 hyperparameters with 4 values each produces 1,024 (\(4^{5}\)) configurations. Early stopping, multifidelity methods, and adaptive search can avoid completing every run, which is why the grid represents a baseline rather than an unavoidable cost.
15 Transfer learning: For the same architecture, transfer learning changes how parameters are initialized and optimized, not the operations required at inference.
Russakovsky, Olga, Jia Deng, Hao Su, Jonathan Krause, Sanjeev Satheesh, Sean Ma, Zhiheng Huang, et al. 2015. “ImageNet Large Scale Visual Recognition Challenge.” International Journal of Computer Vision 115 (3): 211–52. https://doi.org/10.1007/s11263-015-0816-y.
Yosinski, Jason, Jeff Clune, Yoshua Bengio, and Hod Lipson. 2014. “How Transferable Are Features in Deep Neural Networks?” Advances in Neural Information Processing Systems 27.
The DR system faces a sharp training challenge: achieve expert-level diagnostic accuracy with finite labeled-data and optimization budgets. Transfer learning15 addresses this constraint by adapting a model pretrained on a source task to a target task. The ImageNet Large Scale Visual Recognition Challenge (ILSVRC) 2012 training subset contains 1.3 million labeled images (Russakovsky et al. 2015). Reusing learned representations can improve target-task optimization and generalization relative to random initialization, with the benefit depending on source-target similarity, which layers are transferred, and transfer-related optimization effects (Yosinski et al. 2014).
In the controlled validation study reported by Gulshan et al. (2016), transfer learning and a labeled dataset of 128,000 images produced an AUC16 of 0.99, with sensitivity of 97.5 percent and specificity of 93.4 percent at one operating point. The result demonstrates the potential of large-scale pretraining with domain-specific fine-tuning under the study conditions; it does not by itself establish deployment performance. Backpropagation translates classification loss into weight adjustments across millions of parameters; the underlying neural primitives (Neural Computation) ultimately dictate whether training scales efficiently on specialized hardware (Model Training).
Gulshan, Varun, Lily Peng, Marc Coram, Martin C. Stumpe, Derek Wu, Arunachalam Narayanaswamy, Subhashini Venugopalan, et al. 2016. “Development and Validation of a Deep Learning Algorithm for Detection of Diabetic Retinopathy in Retinal Fundus Photographs.” JAMA 316 (22): 2402. https://doi.org/10.1001/jama.2016.17216.
16 AUC (area under the ROC curve): Measures the area under the receiver operating characteristic (ROC) curve plotting true positive rate vs. false positive rate across all classification thresholds, ranging from 0 to 1; 0.5 represents random discrimination, and values below 0.5 are possible. Unlike accuracy, AUC is threshold-independent and insensitive to class prevalence, making it a common metric for medical screening systems. The systems consequence: a model with 0.99 AUC can still produce unacceptable sensitivity at the specific operating threshold chosen for deployment, so AUC alone cannot validate deployment readiness.
Achieving high accuracy is only the first challenge. Edge deployment constraints impose strict efficiency requirements: models may need to fit within tens to hundreds of megabytes, complete inference in tens of milliseconds, and operate within tight memory budgets.
From a workflow perspective, accuracy gains must be weighed against deployment constraints. Ensemble learning17 illustrates this tension: combining predictions from multiple models often improves accuracy, but multiplies inference latency and memory requirements. Whether diversity comes from training on data subsets (bagging), sequentially correcting errors (boosting), or combining predictions with a meta-model (stacking), each additional model adds serving overhead that must fit the deployment target. The Netflix Prize showed how ensemble complexity can block deployment: the winning solution delivered high accuracy, but Netflix did not deploy it because the operational costs exceeded the business benefit (Johnston 2012).18
17 Ensemble learning: Combines predictions from multiple models (bagging, boosting, stacking). Inference compute and model storage generally sum across constituents. Serial execution can increase latency, while parallel execution trades latency for additional hardware and coordination; no fixed proportional latency multiplier follows from ensemble size.
18 Competition-production gap: The Netflix Prize winner used a complex ensemble, but Netflix did not deploy the winning approach because the additional accuracy did not justify the engineering effort (Johnston 2012).
Johnston, Casey. 2012. “Netflix Never Used Its $1 Million Algorithm Due to Engineering Costs.” Ars Technica, April.
Research models often span multiple gigabytes when using ensembles, exceeding the memory limits of edge devices. Rather than tuning accuracy in isolation, teams must apply systematic model compression. Techniques such as quantization and pruning (Model Compression) reduce model size and memory traffic, but each compression step must be validated to ensure it does not drop clinical sensitivity below required thresholds. Model development is an ongoing balance between statistical performance and physical execution cost.
Reproducible system artifacts
The accuracy-efficiency balancing act produces more than trained weights alone. A common failure mode is treating the trained model weights as the sole output of this stage. In a mature ML workflow, the deliverable is a reproducible system artifact with four components:
- Model Weights: The learned parameters.
- Inference Code: The exact code used to run the model, including preprocessing logic.
- Environment Specification: The complete dependency graph (for example, Docker container,
requirements.txt, CUDA drivers) required to execute the code. - Configuration: Hyperparameters and runtime settings.
Without bundling the environment with the model, dependency mismatches can create dangerous failures. Some incompatibilities, including unsupported CUDA combinations or missing libraries, fail loudly and immediately. Other differences in compatible kernels, linear algebra libraries, or image-resizing routines such as OpenCV and PIL may alter floating-point results or pixel interpolation without crashing the serving process. These changes can shift model outputs and affect accuracy. Environment reproducibility is therefore necessary not only for successful execution but also for validating equivalent inference behavior. A model that achieves 99 percent accuracy in development must be reevaluated if its production environment changes, even when inference completes without an exception.
Accuracy vs. efficiency
Medical applications demand specific performance metrics19 that differ from the standard classification outputs and losses Neural Computation introduces. A DR system requires high sensitivity (to limit missed referable disease) and high specificity (to avoid overwhelming referral systems). These metrics must be maintained across diverse patient populations and image quality conditions.
19 Medical AI performance metrics: Medical AI evaluation emphasizes sensitivity (true positive rate) and specificity (true negative rate) alongside aggregate accuracy. This DR scenario sets a >90 percent sensitivity target because missed referable disease can delay care and contribute to avoidable vision loss; actual acceptance criteria are product- and regulator-specific. The subtler systems trap is positive predictive value (PPV): even a high-accuracy model can have low PPV in a low-prevalence population. This prevalence dependence can require different operating thresholds across deployment sites, a constraint invisible in standard ML evaluation.
20 Model compression pipeline: Bridging the gap between research accuracy and edge deployment requires an iterative “compress-validate-adjust” loop. Each compression step can reduce model size or execution cost, but it can also silently degrade sensitivity below the clinical threshold. Finding a model that fits in device memory while preserving clinical sensitivity typically requires multiple iterations because only the full validation suite reveals whether the smaller model still satisfies the problem definition.
Optimizing for clinical performance alone is not enough. In this scenario, the model artifact must remain below 500 MB so that it fits comfortably within the edge target’s 4–8 GB of shared system memory, while the device operates inside a sub-20 watt power envelope and meets the clinical latency budget. Improvements in one dimension often come at the cost of others: the Operations \((O)\) term, the model byte footprint that contributes to \(D_{\text{vol}}\), and fixed serving overhead \((L_{\text{lat}})\) can pull in different directions. Network Architectures explores model capacity, while ML Systems discusses deployment feasibility, and the inherent tension between them drives architectural decisions. Systematic compression and revalidation20 can bridge the gap, meeting deployment requirements while aiming to preserve clinical utility.
The ensemble trade-off illustrates a broader pattern: choosing an ensemble of lightweight models over a single large model reduces per-model complexity (enabling edge deployment) but increases pipeline complexity (requiring orchestration logic and multi-model monitoring). Every architectural decision creates this kind of downstream ripple.
Constraint-driven development
Real-world constraints shape model development from initial exploration through final optimization, demanding systematic experimentation. Development begins when data scientists collaborate with domain experts (ophthalmologists in the DR case) to identify subtle lesions and image-quality requirements that matter clinically. Without that domain knowledge, a model architect might choose a resolution or receptive field, the input region each internal feature can see, that discards relevant detail before the network can use it. This interdisciplinary approach helps model architectures preserve clinically relevant evidence while respecting the computational constraints identified during data collection.
Computational constraints profoundly shape experimental approaches. Multiple model variants, hyperparameter sweeps, and preprocessing approaches can make exhaustive experimentation expensive. This economic reality drives investments in better job scheduling, caching of intermediate results, early stopping, and automated resource optimization. Systematic hyperparameter optimization and disciplined experiment design can reduce computation relative to exhaustive search.
The inherent uncertainty of ML outcomes demands scientific methodology: controlled variables through fixed random seeds and environment versions, systematic ablation studies21 to isolate component contributions, confounding factor analysis to separate architecture effects from optimization effects, and statistical significance testing across multiple training runs using paired offline tests rather than the A/B testing22 reserved for comparing models on live production traffic. Without this rigor, teams cannot distinguish genuine performance improvements from statistical noise—a distinction that becomes critical when a 0.5 percent accuracy difference determines whether a model meets the clinical sensitivity threshold.
21 Ablation studies: Named for surgical tissue removal, ablation studies systematically disable individual components to isolate their contribution to performance. The rigor matters because a 0.5 percent accuracy difference can determine whether the DR model meets its clinical sensitivity threshold. Without ablation, a team cannot distinguish a genuine architectural improvement from noise introduced by a different random seed, wasting iteration cycles on phantom gains.
22 A/B testing in ML: Compares a new model (B) against the production baseline (A) on randomly assigned live traffic to estimate the model’s causal effect. Required sample size depends on the baseline event rate, effect size, variance, allocation, significance level, and statistical power; no universal interaction count or duration follows from a 0.5 percentage-point change alone.
At every development milestone, teams validate models against the deployment constraints identified in earlier lifecycle stages. Each architectural innovation must be evaluated for accuracy improvements and compatibility with edge device limitations and clinical workflow requirements. This dual validation approach ensures that development efforts align with deployment goals rather than optimizing for laboratory conditions that do not translate to real-world performance.
Prototype to production
A team of three data scientists may manage experiments with spreadsheets and shared notebooks, while a team of 30 is more likely to need shared workflow infrastructure. As projects evolve from prototype to production, complexity grows across multiple dimensions simultaneously: larger datasets, more sophisticated models, concurrent experiments, and distributed training infrastructure. Informal coordination can become a bottleneck at production scale as teams share data splits, resolve experiment conflicts, and reconcile notebook versions. Figure 6 illustrates one assumed contrast between manual coordination and a shared workflow platform. The axes are relative units intended to show shape, not absolute throughput.
The curves in figure 6 encode assumed functions rather than measured team-scaling laws. The manual-workflow curve represents coordination costs from sharing data splits, resolving experiment conflicts, and reconciling notebook versions. The platform curve represents benefits from reusable preprocessing components, versioned experiment tracking, and automated scheduling. Actual throughput need not saturate or grow super-linearly; it depends on workload parallelism, platform overhead, team structure, and experiment quality. Figure 6 therefore illustrates why shared infrastructure can reduce duplicated work and manual handoffs without predicting a universal return for every team.
Reproducibility and technical debt
Shared infrastructure can accelerate experimentation—but rapid iteration creates a hidden liability. If experiments are not reproducible, the team cannot reliably distinguish genuine improvements from noise, and the codebase accumulates technical debt23 that compounds with every unreproducible result.
23 ML artifact interdependence: ML artifacts are deeply interdependent. A model’s measured accuracy is tied to the data version, preprocessing pipeline, and hyperparameter configuration used to produce it. Without lineage tracking, the team may not be able to determine whether a regression stems from code, data, or run-to-run variation, forcing expensive reruns of experiments whose provenance is lost.
Reproducing ML results requires tracking data versions, random seeds, hardware configurations, and library versions alongside program logic. Hardware and nondeterministic operations can alter training results, so teams need lineage to distinguish architectural changes from run-to-run variation. This run-to-run variation arises physically because parallel GPU threads execute with nondeterministic scheduling: operations like backward-pass gradient accumulations sum values in arbitrary arrival order, and floating-point addition is non-associative (\((a + b) + c \neq a + (b + c)\)). Furthermore, optimized vendor libraries (such as cuDNN) dynamically benchmark and select different execution kernels across hardware runs unless deterministic execution is explicitly locked down, causing identical code and random seeds to produce diverging weights. Systematic experiment tracking records unique run identifiers and artifact versions. Systems such as MLflow and Weights & Biases link data versions, code commits, hyperparameters, and resulting models so teams can reconstruct differences between runs.
The cost of neglecting reproducibility is economic, not just scientific. Teams that cannot reproduce a result waste cycles rerunning experiments that may not converge to the same outcome. Reproducibility infrastructure such as versioned environments, controlled pipelines, and automated checkpointing reduces redundant computation and supports more confident architectural decisions.
Reproducible, optimized models are necessary but not sufficient. A model that achieves expert-level accuracy on curated research data may still fail in production. The next stage subjects these trained artifacts to systematic testing against the conditions they will actually encounter.
Self-Check: Question
According to the chapter, which bundle of deliverables constitutes a complete, reproducible system artifact from the Model Development and Training stage, and why are model weights alone insufficient?
- A. Model weights, inference/preprocessing code, environment specification (e.g., container or locked dependency graph), and runtime configuration; weights alone fail because library version mismatches or preprocessing differences alter outputs without crashing.
- B. Model weights and a serialized training log; the execution environment can always be inferred from the framework version tag.
- C. Model weights, a test-set evaluation scorecard, and an architecture diagram; deployment engineers reconstruct dependencies during serving containerization.
- D. Source code repository commits and hyperparameters; weights can be deterministically reproduced from random seeds on any hardware.
Explain why a competition-winning 50-model ensemble that achieves state-of-the-art accuracy on a benchmark may be discarded for production edge deployment, citing the Netflix Prize as an empirical reference.
In the chapter’s Iteration Tax scenario, a team compares Model L (large ensemble, starts at 95% accuracy, 1-week training cycle, +0.15% gain/iter) with Model S (lightweight model, starts at 90% accuracy, 1-hour training cycle, +0.1% gain/iter, 100 effective iters) over a 26-week window with a 99% ceiling. What is the modeled outcome after 26 weeks, and what systems lesson does it demonstrate?
- A. Model L reaches 99.0% while Model S reaches 92.6%, proving that starting accuracy dominates iteration speed over six months.
- B. Model S reaches the 99.0% ceiling while Model L reaches 98.9%, demonstrating that shorter training cycles permit more iterative experiments that can overcome a lower starting accuracy.
- C. Both models reach exactly 95.0% accuracy because human hypothesis generation saturates at 26 experiments regardless of training speed.
- D. Model L fails to converge due to training instability, while Model S converges to 90.0% without improvement.
A team observes that model validation accuracy drops 2 percent between run 47 and run 48. Explain how an automated experiment tracking lineage record resolves this regression compared to an ad hoc notebook workflow.
Arrange the following model development milestones in the logical order prescribed for a constraint-driven ML workflow: (1) Baseline transfer-learning fine-tuning from pretrained weights, (2) Physical constraint profiling (target latency, memory ceiling, power envelope), (3) Systematic ablation studies to isolate component contributions, (4) Model compression (pruning/quantization) and hardware-in-the-loop latency validation, (5) Packaging weights, preprocessing code, dependencies, and configuration into a reproducible system artifact.
Evaluation and Validation
A diabetic retinopathy (DR) screening model achieves an area under the ROC curve (AUC) of 0.99 on a curated research dataset. When evaluated on field images from a clinic in Chiang Mai—where a technician with two weeks of training operates a five-year-old fundus camera—sensitivity drops to 78 percent. The software executes without throwing an exception or returning an error code; the convolutional filters simply encounter pixel distributions distorted by optical blur, low illumination, and variable pupil dilation that never appeared in the training distribution. High accuracy on curated test partitions does not guarantee operational reliability in production. Before deployment, trained models must pass through systematic evaluation and validation gates to verify that they satisfy accuracy, latency, and robustness requirements across realistic deployment conditions. This stage transforms raw checkpoint files into production-ready software systems by measuring behavior against predefined operational thresholds.
Production validation is a gate: field sensitivity below the required floor fails deployment.
Definition 1.2: Model validation
Model validation is an evidence gate for deciding whether a trained model is suitable to deploy for a specified use. It tests the model against deployment constraints such as latency targets, subgroup performance targets, cost budgets, and robustness under distribution shift, but cannot certify safety under every possible condition.
- Significance: Validation adds dimensions that test-set accuracy ignores. A model achieving 95 percent accuracy on a static test set may miss a 100 ms latency target on its slowest requests, underperform a required subgroup threshold such as a maximum five percentage-point performance gap across demographic groups, or lose more than ten percentage points of accuracy under common image-quality problems such as blur and glare. Each unchecked dimension is a deployment risk that compounds silently in production.
- Distinction: Evaluation measures model behavior using chosen datasets, metrics, and experiments, which may include out-of-distribution and subgroup tests. Validation assembles the broader evidence needed for a specified deployment decision, including system latency, throughput, robustness, operational readiness, and cost.
- Common pitfall: A frequent misconception is that validation is “one more test.” In reality, it is a multi-dimensional gate: a model can pass the accuracy test and still fail validation because it violates latency, subgroup reliability, or cost constraints that accuracy alone does not measure.
While evaluation quantifies isolated algorithmic properties on static test sets, validation assesses whether the integrated software and hardware pipeline satisfies operational invariants under live serving constraints. Because no finite test suite can certify correctness across all possible input variations, validation operates as a risk-management discipline structured across four stages: metric thresholding, staged production rollouts, environmental stress testing, and regulatory qualification.
Evaluation metrics and thresholds
Evaluation metrics must map directly to the asymmetric loss functions of the target application. In diabetic retinopathy screening, standard classification accuracy is misleading due to class imbalance: a trivial classifier predicting no disease for every sample would achieve high accuracy in a low-prevalence screening population while missing every treatable pathology. System requirements therefore mandate decoupled operating thresholds: sensitivity above 90 percent ensures the clinic captures actionable pathology, while specificity above 80 percent prevents false-positive referrals from saturating secondary ophthalmology clinics. Determining the classification threshold that satisfies both constraints simultaneously is an empirical optimization problem over the receiver operating characteristic (ROC) curve.
Aggregate metrics can conceal localized failure modes. Stratified evaluation partitions the test corpus across metadata dimensions—such as patient age brackets, chronic comorbidities, and clinic camera models—to measure performance parity across slices. A vision backbone achieving 94 percent overall accuracy across an entire benchmark may fall below 80 percent on images captured from patients with cataracts or under low ambient lighting. These localized performance drops remain invisible in aggregate evaluations but manifest as severe safety failures once deployed. Systematic benchmarking methodologies (Benchmarking) evaluate these sliced distributions automatically before promoting a candidate checkpoint.
In addition to label accuracy, evaluation must measure probability calibration:24 whether a model’s predicted confidence score aligns with its empirical error rate. Modern deep neural networks frequently produce uncalibrated posteriors, outputting overconfident predictions (\(>90\) percent confidence) even on samples near decision boundaries. When automated triage pipelines route borderline cases to human specialists based on confidence cutoffs, miscalibration misallocates clinical attention and undermines practitioner trust.
24 Calibration: A calibrated model’s predicted probabilities match observed frequencies: 80 percent confidence should correspond to 80 percent correctness. Calibration is distinct from accuracy, and the systems consequence for the DR system is severe: clinicians use confidence scores for triage decisions, so a miscalibrated model that assigns 90 percent confidence to uncertain cases can misdirect clinical workflows more dangerously than a less accurate but well-calibrated alternative. Platt scaling and temperature scaling can improve posttraining calibration, but their effectiveness must be evaluated on representative data.
Offline and online evaluation
The validation gate begins offline on static datasets and progresses incrementally toward live production traffic. Offline evaluation on held-out test partitions establishes baseline convergence, but it cannot expose physical systems bottlenecks such as memory fragmentation during dynamic batching, serialization delays over network interfaces, or pipeline stalls caused by real-world telemetry feeds. Online evaluation tests candidate models under real serving dynamics using staged rollout:25
25 Staged rollout: Shadow mode runs the new model in parallel, logging predictions without serving them. Canary deployment (named after coal-mine canaries) then exposes a limited, configurable share of traffic and increases it gradually if metrics hold. Coverage depends on traffic, observability, duration, and the failure modes exercised, so staged rollout reduces risk without guaranteeing that it catches a fixed share of production issues. ML Operations details implementation strategies.
- Shadow mode (dark traffic): The API gateway mirrors live production requests asynchronously to the candidate model running on dedicated accelerator resources. The candidate executes inference under true input dimensions and concurrent request arrival patterns, but its predictions are sinked to telemetry logs rather than returned to clients. This isolates tail-latency spikes, out-of-memory (OOM) faults, and numerical divergences without user-facing blast radius.
- Canary deployment: The ingress load balancer directs a small fraction of live traffic (such as 1 to 5 percent) to the new serving container, returning live predictions while monitoring systems telemetry for crash loops, latency regression, and downstream error spikes.
- A/B testing: Traffic splitters partition user requests across candidate and baseline models using deterministic hashing, providing statistical evidence to verify whether algorithmic improvements translate into measurable business or clinical gains.
This staged rollout workflow manages deployment validation risk; it is distinct from the cross-tier model compression pattern termed progressive deployment in ML Systems.
Each validation stage contributes distinct, complementary operational evidence, as table 4 summarizes.
| Validation stage | Typical evidence it adds |
|---|---|
| Offline evaluation | Algorithmic behavior |
| Shadow mode | Integration behavior |
| Canary deployment | Limited-traffic behavior |
| A/B testing | Comparative outcomes |
Serving infrastructure must support this staged validation pipeline by design. Retrofitting dynamic traffic splitting, asynchronous request mirroring, and differential output logging onto an existing deployment stack requires extensive modifications to API gateways and telemetry pipelines.
Production-condition validation
Production-condition validation evaluates whether an ML model withstands the physical and operational environments specified during problem definition. Standard evaluation implicitly assumes that test samples are identically distributed to training data; production validation deliberately stress-tests this assumption across three dimensions: site heterogeneity, input-level perturbations, and temporal drift.
External and multisite validation address site-level distribution shifts: determining whether the model has learned generalizable representations or overfit to the sensor hardware of the development environment. In retinal screening, camera sensor sensitivities, optical lens coatings, and illumination spectra differ across equipment vendors. A DR model trained exclusively on images from high-end fundus cameras in research hospitals can fail when deployed to community clinics utilizing older hardware. Multisite validation requires benchmarking candidate models on data collected across independent clinic sites with varying hardware configurations, ambient lighting environments, and operator skill tiers.
Robustness testing shifts focus to individual inference requests, evaluating resilience against realistic physical distortions and edge cases. For computer vision pipelines, these perturbations include sensor noise, optical blur, uneven contrast, and partial pupil occlusions. In the Thai DR clinical study (Beede et al. (2020)), field technicians with limited formal training frequently captured off-center or poorly focused fundus images. Evaluating models against synthetic and empirical perturbation suites exposes whether the serving pipeline requires an upstream image-quality filter to reject corrupt frames before allocating accelerator cycles for inference.
Temporal validation evaluates whether the model maintains predictive accuracy as the operating environment evolves over weeks and months. Cross-sectional test sets drawn from a fixed historical window fail to capture subsequent shifts in patient demographics, disease epidemiology, or clinical practice patterns. Input distribution changes without label changes produce covariate drift, whereas shifts in the relationship between input features and clinical diagnoses cause concept drift. Both phenomena cause silent model degradation and motivate the continuous telemetry and drift detection pipelines described in section 1.8.
Regulatory validation
Healthcare AI systems face device- and pathway-specific validation requirements. When FDA premarket review is required, the safety and performance evidence must be appropriate to the device and its regulatory pathway; clinical data are required for some submissions, not all.26
26 FDA AI/ML regulation: FDA marketing authorization requires evidence appropriate to the device, intended use, risk, and regulatory pathway. The FDA’s 2021 AI/ML SaMD Action Plan identified lifecycle management, real-world performance monitoring, and predetermined change control planning as central issues for adaptive medical-device software (U.S. Food and Drug Administration 2021). These concerns make model versions, training provenance, monitoring, and change documentation important workflow artifacts without imposing one identical audit artifact at every lifecycle stage.
U.S. Food and Drug Administration. 2021. Artificial Intelligence/Machine Learning (AI/ML)-Based Software as a Medical Device (SaMD) Action Plan. U.S. Department of Health; Human Services.
Domain-specific validation extends beyond statutory compliance to address clinical utility and safety protocols. In diabetic retinopathy screening, clinical validation studies deploy the automated system alongside licensed ophthalmologists, comparing model classifications against ground truth established by consensus adjudication panels. These studies must demonstrate not only non-inferior diagnostic accuracy but also safe failure modes: systems that fail safely—by routing ambiguous or low-confidence samples to clinical specialists—integrate successfully into care delivery, whereas systems that fail silently generate catastrophic diagnostic errors.
Human factors validation evaluates the model as an embedded component within the human decision-making loop. An accurate model that induces high operator cognitive load, exhibits excessive inference latency that stalls patient intake, or triggers frequent false alarms creates alert fatigue, prompting clinic staff to disable or bypass the system. Validation protocols must therefore quantify sociotechnical metrics—including clinician override frequency, examination turnaround time, and referral concordance—alongside raw statistical accuracy.
Deployment readiness
Passing the validation gate produces an immutable release manifest that certifies the model for production deployment. This manifest records the exact model checkpoint hash, preprocessing container configuration, calibration parameters, benchmark scores across designated demographic and equipment slices, and regulatory clearance certificates. If a model fails to clear an established threshold—such as p99 serving latency exceeding the service level agreement (SLA) budget or sensitivity on low-light fundus images falling below the safety floor—the release gate halts deployment. Diagnostics then route backward to the responsible lifecycle stage: data curation for targeted data collection, model training for loss function re-weighting, or compiler optimization for kernel fusion.
Clearing the algorithmic validation gate is a prerequisite for production, but deployment readiness requires verifying the entire execution substrate. A mathematically validated model cannot serve traffic without an operational serving path: deterministic input preprocessing routines, serialized inference graphs optimized for the target hardware runtime, telemetry collectors, and automated rollback triggers. Once the validation evidence package is complete, the operational challenge transitions from offline verification to online serving and systems integration.
Self-Check: Question
What is the primary conceptual distinction between Model Evaluation and Model Validation as defined in this chapter?
- A. Evaluation is conducted by internal software engineers, whereas validation is conducted exclusively by government regulatory agencies.
- B. Evaluation tests software execution speed on accelerators, whereas validation tests algorithm mathematical convergence on CPUs.
- C. Evaluation measures model behavior on chosen datasets and metrics; validation is a multi-dimensional evidence gate confirming the model satisfies all operational, latency, subgroup fairness, robustness, and cost constraints under production-representative conditions.
- D. Evaluation is performed on live production traffic, whereas validation is performed exclusively on synthetic offline data.
A diabetic retinopathy screening model achieves 94 percent aggregate accuracy on held-out validation data. However, stratified evaluation reveals that sensitivity drops to 76 percent for patients with cataracts and falls below the 90 percent sensitivity floor for one demographic subpopulation. How should the engineering team respond?
- A. Proceed to full deployment immediately, because aggregate accuracy above 90 percent statistically compensates for minor subpopulation variations.
- B. Apply post-hoc temperature scaling to increase overall prediction confidence, which automatically resolves subgroup sensitivity deficits.
- C. Deploy the model in shadow mode permanently, since shadow mode bypasses clinical subgroup safety requirements.
- D. Block deployment, because the model violates non-negotiable clinical sensitivity safety thresholds for vulnerable subgroups; stratified validation exists precisely to prevent aggregate metrics from masking localized clinical harm.
Explain why a medical diagnostic model with an outstanding Area Under the ROC Curve (AUC) of 0.99 on a research dataset may still fail deployment validation for clinical screening.
Order the stages of progressive online validation from lowest initial user risk to broadest comparative evaluation: (1) Canary deployment exposing 1–5% of live traffic, (2) Offline evaluation on held-out and stratified test sets, (3) A/B testing comparing outcomes against the production baseline, (4) Shadow mode running in parallel on live requests without serving predictions to users.
True or False: Model calibration—ensuring that a predicted confidence score of 0.80 corresponds to an empirical 80 percent probability of correctness—is critical for medical AI systems because clinical triage workflows rely directly on confidence scores to route ambiguous cases to human specialists.
Deployment and Integration
A model that passes validation in development faces different failure modes once deployed to production. In the DR scenario, the model must run on tablets in rural clinics with intermittent connectivity, integrate with hospital information systems with distinct schema requirements, and deliver predictions clinicians can interpret directly. The scenario’s latency and connectivity requirements rule out round-trip cloud inference. Deployment is where abstract operational constraints become physical systems requirements. In iron-law terms, the serving path couples data movement, execution efficiency, and fixed overhead together; which term binds varies by archetype. ResNet-50-class vision workloads may use batching to improve throughput, DLRM-class recommendation workloads emphasize interactive latency and embedding access, and TinyML-class audio workloads operate under severe energy budgets (table 2). Dedicated serving infrastructure (ML Operations) manages these trade-offs under live traffic.
Deployment requirements
Deployment translates an abstract computational graph into hard physical budgets: peak memory footprint, execution latency, thermal dissipation limits, and network bandwidth. In the clinical screening scenario, these constraints force an architectural choice between centralized cloud serving and localized edge execution. A cloud deployment consolidates compute onto centralized accelerators, but requires stable wide-area network uplinks and incurs recurrent API and bandwidth charges. Conversely, an edge deployment eliminates network transit latency and operates during wide-area connectivity outages, but demands upfront hardware capital expenditure and restricts model size to local device memory. Evaluating this trade-off requires quantifying the relationship between capital expense, operating expense, and inference volume.
Napkin Math 1.3: Cloud vs. edge deployment economics
Problem: A production model processes about 760,000 billable screening images per month across 500 clinics, assuming daily operation and one processed image per patient after local selection and quality checks. Should the deployment use a cloud inference endpoint or edge inference on an on-premises server?
Option A: Cloud inference.
- Model runs on centralized GPU servers
- Inference cost: ~$0.01/image (cloud GPU time + API overhead)
- Annual inference cost across 500 clinics, 50 patients/day, 1 billable image per patient, 365 days/year, and $0.01/image is $91,250/year
- Plus: An assumed connectivity and network-operations allocation for uploading 5 MB per billable image = ~$45,000/year
- Total: ~$136,250/year operational cost
- Risk: 200 ms+ exceeds the scenario latency target; connectivity outages halt screening
Option B: Edge deployment on a clinic device.
- One-time hardware: one $500/device per clinic across 500 clinics requires $250,000 capital expense
- Inference cost: ~$0.001/image (assumed all-in variable operating allocation)
- Annual cost: approximately $25,000/year maintenance plus approximately $9,125/year variable inference cost, for about $34,125/year
- Total: $250,000 upfront + ~$34,125/year
- Benefit: latency below 50 ms; works offline; much lower per-inference cost
Math:
- Annual savings: $136,250/year (cloud) − $34,125/year (edge) = $102,125/year
- Payback: $250,000 (hardware) ÷ $102,125/year = ~2.4 years
Systems insight: Under these scenario assumptions, edge deployment pays back in ~2.4 years and allows inference during connectivity outages, yet it requires tighter model optimization (must fit in edge memory) and more complex update pipelines. The deployment paradigm selected during Problem Definition determines whether the edge option is even viable.
Cloud cost outpaces edge cost as the deployment grows.
In this scenario, bandwidth limits, latency targets, and offline operational requirements favor edge deployment. That choice dictates strict memory, latency, and thermal envelopes that model compression (Model Compression) must satisfy and serving runtimes (Model Serving) must execute within production bounds.
Host integration extends these physical constraints to the software interfaces of existing clinical infrastructure. The inference runtime must exchange data with hospital information systems (HIS) to ingest patient records and record diagnostic output. Integrating a probabilistic model into an established clinical workflow differs fundamentally from connecting a deterministic sensor. Rather than emitting an invariant scalar measurement, the model produces a probability distribution coupled with an uncertainty estimate. The integration boundary therefore requires an explicit interface contract governing decision routing. This contract maps predictive uncertainty to clinical actions, specifying which classifications trigger automated referrals and which demand physician review. A confidence threshold cannot be evaluated in isolation; its operational safety depends entirely on the downstream workflow it triggers. Regulatory frameworks introduce structural constraints on this data lifecycle. Legal mandates such as HIPAA govern data transmission and restrict whether production inference payloads can be persisted, linked to patient identifiers, or ingested into retraining pipelines. When compliance prohibits retaining raw inputs, continuous improvement cannot rely on passive telemetry logging. Privacy rules thus constrain ongoing model maintenance strategies rather than serving merely as a transport-layer security checklist (ML Operations).
Pilot to full deployment
Production rollout proceeds in discrete stages to isolate failure modes across expanding execution environments. Offline replay and synthetic test harnesses verify schema contracts and concurrency limits without risking patient safety. Subsequent pilot deployments in a small number of clinics expose the serving stack to physical variations absent from laboratory benchmarks: optical distortion across camera models, sensor noise under uneven clinic lighting, and operator handling variations. Full-scale rollout broadens exposure to the long tail of anatomical variations and rare pathologies. Detecting these distribution shifts requires continuous runtime monitoring rather than assuming validation distributions persist indefinitely.
Scaling across hundreds of remote clinics introduces hardware heterogeneity and operational friction across distributed nodes. Variations in local sensor optics alter input pixel distributions before execution begins, necessitating robust input-validation kernels that reject out-of-spec captures locally. At the same time, severe wide-area bandwidth constraints rule out continuous weight synchronization or streaming high-resolution telemetry back to a centralized cluster. Edge nodes must instead operate autonomously, caching execution metrics locally and synchronizing state opportunistically during scheduled maintenance windows.
Sustaining clinical utility requires calibrated uncertainty estimation rather than raw aggregate accuracy. When the model encounters ambiguous pathology, emitting an uncalibrated prediction risks diagnostic failure. Instead, an operational serving path incorporates human-in-the-loop routing, using calibrated decision boundaries to direct borderline cases to expert clinicians. This routing mechanism serves a dual purpose: it acts as a real-time safety boundary for patient care, and it establishes a continuous data collection channel. Adjudicated edge cases yield verified, high-information annotations that are fed back into subsequent training iterations, directly counteracting the model’s known failure modes.
Maintaining consistency across distributed deployments demands immutable model artifact versioning and atomic update procedures. Client runtimes must verify cryptographic checksums of serialized graphs before loading new weights into memory, preventing partial updates from corrupting edge execution. Deployment marks the transition from static offline evaluation to continuous operations, where system telemetry continuously assesses whether real-world latency distributions and inference behaviors remain within specified operating bounds.
Self-Check: Question
A deployment model processes ~760,000 screening images per month across 500 rural clinics. Cloud inference costs zsh.01/image plus ,000/year for connectivity/network operations (,200/year total). Edge deployment requires a device per clinic (,000 CapEx), ,000/year maintenance, and zsh.001/image (,120/year total OpEx). According to the chapter’s economics calculation, what is the annual operating savings of edge deployment and its payback period?
- A. ~,080 annual savings with a payback period of approximately 2.4 to 2.5 years, while enabling offline operation during connectivity outages.
- B. ~,000 annual savings with a payback period of 10 years, making cloud deployment far more economical.
- C. ~,000 annual savings with an immediate 3-month payback period.
- D. Zero annual savings, because edge hardware maintenance costs exactly equal cloud inference fees at 500 clinics.
Explain why integrating a probabilistic ML model into a Hospital Information System (HIS) differs fundamentally from integrating a deterministic clinical sensor (such as a digital blood pressure monitor).
An edge-deployed DR screening tablet has a 100 ms total latency budget. Profiling reveals the following execution breakdown: on-device model inference = 15 ms, remote cloud lookup for patient metadata = 60 ms, and local serialization/HIS formatting = 40 ms (total = 115 ms). Which engineering modification directly reduces the Iron Law fixed overhead ({}$) term to meet the 100 ms budget?
- A. Prune the neural network weights to reduce on-device model inference time from 15 ms to 5 ms.
- B. Cache patient metadata locally on the tablet to eliminate the 60 ms remote network round-trip.
- C. Quantize the model from FP32 to INT8 to increase arithmetic operational intensity ($).
- D. Increase the GPU clock frequency on the edge tablet to accelerate tensor core processing.
True or False: Phased deployment progressing from simulation to pilot clinics to full production rollout is recommended because each phase is designed to expose a distinct, non-overlapping class of system failures: simulation catches software integration and schema bugs; pilots catch real-world camera and workflow heterogeneity; and full production catches distributed concurrency contention and rare clinical tail cases.
A deployment policy that automatically routes low-confidence or high-uncertainty model predictions to an expert specialist for manual review, while allowing high-confidence predictions to proceed automatically, is known as ____ routing.
Monitoring and Maintenance
Consider an illustrative case six months after a DR screening system launches. A clinic upgrades its fundus cameras, and the new equipment produces images with different color profiles. The model’s sensitivity then drops at that site because the pixel distributions it learned during training no longer match the images it receives. No code changed. The data drifted beyond the training envelope, and the model degraded silently. ML systems can degrade through data drift even when their artifacts remain untouched. This possibility means that deployment is not the end of the lifecycle but the beginning of an ongoing operational phase. Monitoring provides the statistical telemetry to detect degradation, while continuous maintenance pipelines (ML Operations) update models when evidence warrants it.
In this illustrative scenario, monitoring tracks performance across clinics to detect whether changing patient demographics, camera technology, or equipment degradation affects accuracy. Adding a new imaging modality such as optical coherence tomography would be a product change requiring new data, validation, workflow integration, and any applicable regulatory review rather than routine maintenance. Three feedback pathways guide update decisions: performance evidence can motivate targeted data collection, data-quality findings can prompt preparation changes, and confirmed model degradation can justify retraining or another intervention. Drift thresholds initiate review; they do not select the remedy automatically.
Production monitoring
Monitoring must serve two audiences simultaneously: technical teams tracking system health metrics and clinical staff needing actionable insights. Initial deployment may reveal blind spots invisible during laboratory validation.27 Clinics with older equipment may show accuracy decreases. Specific patient subgroups, such as those with proliferative retinopathy or cataracts complicating the fundus image, may trigger higher error rates. These discoveries drive targeted data collection and architectural improvements.
27 Lab-to-clinic performance gap: Medical AI systems can experience substantial performance changes when camera models, image quality, patient populations, or operator workflows differ from development data; the gap arises because training data cannot capture the full diversity of production conditions. FDA has emphasized total product lifecycle oversight and real-world performance monitoring for AI/ML-enabled medical devices, and device submissions may need evidence appropriate to the product’s intended use and risk. For ML systems engineers, this means monitoring infrastructure should be a deployment prerequisite, not a postlaunch addition.
28 Population stability index (PSI) and Kolmogorov-Smirnov (KS) test: Two lightweight statistical methods for detecting distribution drift; PSI bins features and computes divergence; thresholds such as 0.1 and 0.2 are operating conventions, not universal significance levels. The KS test measures maximum distance between empirical cumulative distributions. Both are cheap enough for frequent monitoring, but a detected input shift does not by itself prove an accuracy change; labels or other outcome evidence are needed. ML Operations covers drift detection pipelines in depth.
A DR screening system, where missed referable disease can delay care and contribute to avoidable vision loss, demands continuous operational monitoring plus periodic performance evaluation when labels arrive. Teams establish quantitative thresholds for latency, accuracy, and data distribution stability. Lightweight statistical tests such as the population stability index (PSI) and Kolmogorov-Smirnov (KS) test28 trigger responses ranging from automated alerts to retraining reviews (ML Operations).
A production DR system can track four metric categories at different timescales. The following thresholds illustrate one scenario policy; clinical and operational teams must validate them for the intended product, population, and deployment environment.
- Model performance metrics (requiring ground truth, available with delay): sensitivity (target above 90 percent, alert if seven-day rolling average drops below 88 percent), specificity (target above 80 percent, alert if it drops below 78 percent), and subgroup performance (alert if any demographic drops more than 5 percentage points below baseline).
- Proxy metrics (available immediately, without ground truth): prediction confidence distribution (alert if mean confidence drops more than 10 percent relative to baseline), referral rate (alert if rate changes more than 15 percent from baseline), and image quality rejection rate (alert if more than 20 percent of images fail quality checks).
- Operational metrics: Inference latency (p95 below 50 ms, alert if above 100 ms), throughput (alert if queue depth exceeds 50 images), and error rate (alert if more than 0.1 percent of requests fail).
- Data stability metrics: Feature and prediction distributions compared with a baseline, with alerts when recent traffic moves outside the expected range.
The hierarchy matters: operational metrics can surface immediate problems, proxy metrics can flag possible model issues without waiting for ground truth, and performance metrics often arrive later because they require labeled data.
Maintenance at scale
Model updates require careful validation and controlled rollouts. Teams employ A/B testing frameworks to evaluate updates and implement rollback mechanisms29 that address issues quickly. ML systems must account for data evolution that can affect behavior independently of code changes.
29 ML rollback complexity: An ML model’s validity is coupled to the data distribution on which it was trained, not just its code. “Data evolution” means a simple rollback restores a model artifact but cannot restore the past data environment, creating a temporal state mismatch. Even a rapid rollback is therefore a mitigation tactic rather than a true system restore, as the stale model’s performance on live data is not guaranteed.
30 Data lineage: The automated recording of metadata linking each clinic’s production logs to the exact data, code, and model version that generated them. Without this explicit trail, correlating a site-specific accuracy drop with a training experiment can require manual forensic analysis that delays root-cause identification.
In the illustrative scenario, scaling from pilot sites to hundreds of clinics increases monitoring complexity. The resulting log volume depends on request rates, sampling, payload sizes, and retention policies as well as the number of clinics. The monitoring infrastructure must track both global metrics and site-specific behaviors, maintain data lineage,30 the metadata trail linking production logs to data, code, and model versions, where required for regulatory compliance, and correlate production issues with training experiments for root cause analysis.
Proactive maintenance closes the lifecycle loop: operational signals identify potential problems, review determines whether newly validated data or another change is needed, and production evidence feeds back to refine problem definitions, data-quality standards, and architectural decisions. When retraining is selected, scheduled or evidence-triggered pipelines can incorporate approved data and return the candidate through validation. Underlying these operational dynamics are three fundamental systems principles: constraints propagate across stage boundaries, feedback operates across mismatched timescales, and system-level behavior diverges from component-level metrics (section 1.9).
Self-Check: Question
Why does production ML monitoring structure its telemetry into a four-tier hierarchy of operational, proxy, performance, and data stability metrics rather than relying on a single metric class?
- A. Because cloud monitoring vendors charge lower fees when metrics are divided into multiple dashboard tabs.
- B. Because operational metrics like latency and CPU load are sufficient to detect model accuracy degradation in real time.
- C. Because different failure modes emerge across different timescales: operational metrics catch service crashes in seconds, proxy metrics (confidence, referral rate) detect distribution shifts in hours without labels, and performance metrics (sensitivity, specificity) confirm diagnostic accuracy weeks later when ground truth arrives.
- D. Because ground-truth diagnostic labels are instantly available in real time for every inference request in production.
Explain why reverting an ML system to an older model checkpoint during a production degradation incident is only a mitigation tactic rather than a true system state restoration.
Six months after launch, a clinic network upgrades its fundus cameras to a newer model with a distinct color profile. System latency and server error rates remain perfectly stable at 0.0%, but clinical sensitivity drops from 92% to 77%. What systems phenomenon does this scenario illustrate?
- A. A deterministic crash in the GPU serving container caused by CUDA driver incompatibility.
- B. An adversarial perturbation attack executed against the clinic edge devices.
- C. Concept drift caused by a sudden biological mutation in the underlying disease pathology.
- D. Silent degradation caused by covariate/data drift; input pixel distributions shifted beyond the training envelope while traditional infrastructure monitoring showed healthy green dashboards.
True or False: In production ML monitoring, lightweight statistical tests such as the Population Stability Index (PSI) and Kolmogorov-Smirnov (KS) test can detect shifts in input feature distributions, but an alert from these tests does not by itself prove that model classification accuracy has degraded until ground-truth outcome evidence is evaluated.
Describe what metadata elements must be linked in an automated data lineage audit trail for medical ML systems, and explain how lineage reduces the engineering cost of investigating a site-specific accuracy regression.
Systems Thinking
The diabetic retinopathy scenario demonstrated how lifecycle stages interact as a coupled system: physical constraints at the point of care directly governed model capacity, training data curation, and preprocessing logic. Three structural mechanisms explain these coupled interactions: backward constraint propagation, multi-scale feedback loops, and emergent system trade-offs. Managing these mechanisms distinguishes proactive, constraint-driven system design from reactive post-deployment debugging.
Constraint propagation principle

An illustrative doubling scenario visualizes late-discovery sensitivity.
In the DR scenario, an intermittent 2 Mbps clinic uplink ruled out cloud inference, requiring edge deployment. The edge target’s memory and power budgets then constrained model architecture, favoring lightweight factorized convolutions over large ensembles and requiring automated image-quality checks at capture time. Each downstream constraint narrowed the design space for upstream stages, coupling hardware limits directly to data collection and model design.
Definition 1.3: The constraint propagation principle
The constraint propagation principle states that a constraint discovered late in the ML lifecycle can force rework in affected earlier stages. Actual correction cost depends on which artifacts and decisions must change. This chapter’s \(2^{N_{\text{stage}}-1}\) rule is an illustrative sensitivity scenario, not an empirical cost law.
- Significance: A 100 ms latency target discovered at deployment (stage 5) may propagate backward to constrain model size (stage 3: algorithm complexity \(O\)), dataset requirements (stage 2: dataset size \(D\)), and problem definition (stage 1: what accuracy is achievable). Rework depends on which earlier decisions relied on the missing constraint. Within the iron law, a deployment constraint on \(L_{\text{lat}}\) or \(R_{\text{peak}}\) can redefine the feasible region for \(O\), \(D_{\text{vol}}\), and \(\eta_{\text{hw}}\).
- Distinction: Unlike modular decomposition (which encourages independent optimization of each component), this principle mandates end-to-end reasoning: optimizing accuracy in isolation may produce a model that is infeasible to deploy, making the “local maximum” in accuracy a “global minimum” in system viability.
- Common pitfall: A frequent misconception is that deployment is “the last step.” The deployment environment is the day-one constraint: its latency budget, memory capacity, and power envelope define the boundaries of every upstream decision.
Propagation operates bidirectionally, creating dynamic constraint networks rather than linear dependencies. When rural clinic deployment reveals tight bandwidth limitations, teams may redesign the pipeline to transmit compact outputs after local inference. If the system instead compresses model inputs to traverse the uplink, the lossy compression artifacts degrade input quality; the training dataset must then incorporate matching distortion augmentations to prevent training-serving skew. Conversely, shifting inference entirely to the edge to transmit only diagnosis scalars relieves uplink bandwidth but tightens the edge device’s DRAM capacity and thermal envelope. Upstream data choices and downstream machine boundaries remain physically coupled.
Decisions made without accounting for downstream execution boundaries accumulate technical debt.31 The stage interface specification (table 3) operationalizes this principle by making constraints explicit at each stage boundary, aligning with the model, data, and infrastructure contract practices discussed in ML Operations. Those contracts enable earlier detection of constraints. When propagation occurs specifically through data quality failures, the resulting pattern is known as a data cascade: a chain of downstream failures triggered by bad data (Sambasivan et al. 2021). Data Engineering formalizes this failure mode and traces how it unfolds stage by stage.
31 ML technical debt: Sculley et al. (2015) identify ML-specific debt mechanisms such as entanglement (changing one feature affects all others because the model learned joint distributions), hidden feedback loops (predictions influence future training data), and undeclared consumers (downstream systems depending on outputs without contracts). Since ML code is often only a small part of a production system, the surrounding configuration, pipelines, and infrastructure can allow this debt to accumulate silently.
Sambasivan, Nithya, Shivani Kapania, Hannah Highfill, Diana Akrong, Praveen Paritosh, and Lora M Aroyo. 2021. “‘Everyone Wants to Do the Model Work, Not the Data Work’: Data Cascades in High-Stakes AI.” Proceedings of the 2021 CHI Conference on Human Factors in Computing Systems, 1–15. https://doi.org/10.1145/3411764.3445518.
Multi-scale feedback
ML systems succeed by orchestrating feedback loops across multiple timescales, each serving a different purpose. One illustrative operating plan for the DR scenario uses minute-level checks to catch a misconfigured camera before it produces a shift’s worth of unusable images; daily reviews for proxy shifts such as referral-rate, confidence, rejection-rate, or site-specific camera changes; weekly aggregation of labeled accuracy statistics and drift tests when ground truth is available; monthly analysis of population coverage; and quarterly review of whether the architecture still meets clinical needs. Actual cadences depend on label delay, product risk, traffic, and the cost of acting on each signal.
An illustrative monitoring plan spans minutes to quarters across five orders of magnitude.
The temporal structure of these feedback loops reflects the inherent dynamics of ML systems. Rapid loops enable quick correction of operational issues: a clinic’s misconfigured camera can be detected and corrected within minutes. Slower loops enable strategic adaptation; recognizing that population demographic shifts require expanded training data takes months of monitoring to detect reliably. This multi-scale approach balances responsiveness against statistical stability. Overreacting to short-term variance causes pipeline thrashing, such as triggering unnecessary retraining on transient shifts, while sluggish adaptation allows silent accuracy decay to persist unmitigated.
Emergent complexity and resource trade-offs
Complex systems produce emergent behaviors invisible when analyzing individual components. In a multisite DR deployment, individual clinics can exhibit stable aggregate performance while system-wide analysis detects degradation concentrated in specific demographic cohorts—a failure mode undetectable in isolated clinic logs. Furthermore, while conventional distributed systems fail primarily through deterministic faults such as network timeouts or out-of-memory crashes, ML systems also experience probabilistic degradation: data drift, concept drift, and bias amplification. Probabilistic degradation generates no stack traces or runtime exceptions; the model continues serving predictions within its latency SLA while its statistical validity decays silently.
Checkpoint 1.3: The cost of late discovery
Apply the constraint propagation principle to this scenario:
A team discovers during monitoring (Stage 6) that their DR model fails for patients over 70 years old. This demographic requirement should have been specified at Problem Definition (Stage 1).
Resource optimization introduces multi-dimensional trade-offs that also arise in conventional software, while ML adds learned statistical behavior to them. An accuracy improvement might require increasing model parameter count, forcing deployment onto more capable hardware; multiplied across hundreds of clinics, that marginal accuracy increment dictates cluster capital expenditure. These trade-offs manifest the power wall and memory wall from ML Systems: edge deployment eliminates WAN latency but constrains model complexity to local SRAM and DRAM limits; cloud deployment removes accelerator memory bounds but introduces network latency that can violate point-of-care clinical workflows. Every architectural choice reallocates pressure across the D·A·M triad.
These three structural patterns—constraint propagation across stage boundaries, multi-scale feedback timing, and emergent system trade-offs—demonstrate that ML systems cannot be engineered through modular decomposition alone. Optimizing data pipelines, model topologies, and execution targets in isolation guarantees runtime bottlenecks or silent failures. When engineering teams apply conventional software assumptions to these coupled dynamics, predictable antipatterns emerge. The fallacies and pitfalls in section 1.10 examine where these mental models break down across production lifecycles.
Self-Check: Question
What does the Constraint Propagation Principle assert regarding the engineering cost of discovering constraints late in the ML lifecycle?
- A. Correction costs scale exponentially as roughly ^{N_{}-1}$ times the base effort when discovery is delayed to stage {}$, because artifacts produced across all intervening stages inherit the violation and must be rebuilt.
- B. Correction costs grow strictly linearly with stage index, because each stage requires exactly one day of rework.
- C. Correction costs remain constant across all stages because modular software abstractions isolate upstream stages from downstream changes.
- D. Correction costs decrease over time as downstream profiling provides more performance telemetry to guide optimization.
A demographic fairness requirement (e.g., minimum sensitivity floor for patients over 70) should have been specified at Problem Definition (Stage 1) but is discovered only during Monitoring and Maintenance (Stage 6). Calculate the illustrative cost multiplier and enumerate the lifecycle stages that must be revisited to correct the system.
In a multi-site distributed ML deployment spanning hundreds of clinics, why can system-wide emergent behaviors produce failures that are completely invisible when examining individual clinics in isolation?
- A. Because distributed communication protocols inject pseudo-random noise into inference predictions.
- B. Because local monitoring averages away subpopulation variance; an underserved demographic group that represents only 1–2% of patients at each clinic appears as statistical noise locally, but forms a significant, systematically failing population in aggregate.
- C. Because modern ML models are strictly non-deterministic on edge devices and deterministic in the cloud.
- D. Because individual clinics never experience data drift, which occurs only across wide-area networks.
Arrange the following feedback loop cadences in order from shortest operating timescale (most rapid) to longest operating timescale (slowest): (1) Weekly aggregation of labeled accuracy metrics and statistical drift tests, (2) Minute-level operational health and image-capture focus checks, (3) Quarterly architectural review of model families and regulatory compliance, (4) Daily monitoring of proxy metrics such as referral rates and confidence distributions.
When an undetected data quality failure at data collection propagates downstream to cause compounding failures in model training, validation, and deployment, this systemic failure pattern is known as a(n) ____.
Fallacies and Pitfalls
Applying conventional software patterns to machine learning workflows overlooks the statistical and data-dependent nature of learned systems. The following fallacies and pitfalls capture recurring errors that stall development cycles, cause silent production outages, and compound technical debt across pipeline stages.
Fallacy: ML development can follow traditional software workflows without modification.
Traditional software processes rely on deterministic specifications verified by binary unit tests. Machine learning systems, by contrast, derive behavior inductively from data, replacing deterministic guarantees with statistical performance distributions (table 1). Linear phase gates and rigid sprint boundaries assume requirements remain fixed once specified. In an ML workflow, problem definitions evolve as exploratory training reveals distribution gaps, class imbalances, or infeasible accuracy-latency trade-offs. Furthermore, practitioner surveys demonstrate that data preparation and pipeline maintenance dominate engineering effort (section 1.1.1). Rigid linear gates treat data collection as a completed precursor rather than an active feedback loop, trapping teams in costly cycles when downstream evaluation forces fundamental revisions to early data assumptions.
Pitfall: Treating data preparation as a one-time preprocessing step.
Teams often treat data cleaning and feature engineering as a static milestone to clear before training begins. In production, incoming data distributions evolve continuously as user behavior shifts, sensors degrade, and upstream schemas change. The two-pipeline architecture (figure 1) reflects this operational reality: data pipelines and model pipelines must execute concurrently with continuous feedback. Early data preparation decisions cascade directly through training and deployment (section 1.4). When data preparation is static, silent distribution shifts and training-serving feature skew bypass code-level tests, degrading inference accuracy long before raising an operational alert. Continuous data validation pipelines with automated schema checking and distribution monitoring are necessary to catch data drift at ingestion rather than after silent model failure in production.
Fallacy: Passing model evaluation means the system is ready for deployment.
Offline evaluation measures statistical loss on static, curated validation sets, but it isolates the model from operational serving dynamics. Strong aggregate metrics provide no guarantee that the system will satisfy physical deployment constraints. In the two-pipeline architecture (figure 1), offline evaluation leaves serving integration, real-time input pipelines, and operational monitoring untested. The diabetic retinopathy case study (section 1.2.1) exemplifies this disconnect: a model that achieved specialist-level accuracy on curated benchmark images failed in clinic deployments due to variable camera lighting, technician workflow interruptions, and intermittent network connectivity. Production readiness demands system-level verification, including tail-latency budgets under concurrency, feature pipeline consistency, and graceful degradation under hardware faults. Under the constraint propagation principle (section 1.9.1), discovering operational failures only after deployment forces costly iterations across both model architecture and data collection.
Pitfall: Scaling data collection before checking marginal model value.
Expanding dataset size is often assumed to be a universally profitable investment for boosting accuracy. In practice, data collection follows power-law scaling with diminishing returns: once the underlying data distribution is adequately covered, additional raw examples yield negligible generalization gains while storage overhead, ingestion bandwidth, and labeling expenses escalate. The feedback loops in figure 1 show that model accuracy depends on the coupling between dataset quality, model capacity, and operational constraints. Ingesting high volumes of mislabeled or redundant samples introduces noise and inflates training compute without improving accuracy, whereas a compact, carefully curated dataset with verified labels and balanced representation often achieves superior performance. Because data quality decisions cascade through all downstream pipeline stages (section 1.4), teams must measure the marginal accuracy gain per additional sample before allocating engineering budget to larger data ingestion.
Fallacy: Skipping validation stages accelerates delivery.
Compressing or bypassing progressive validation stages appears to accelerate project delivery, but it transfers verification risk directly to production traffic. Multi-stage validation (section 1.6) isolates orthogonal failure modes across increasingly realistic execution environments. Skipping shadow mode prevents teams from observing live inference behavior—such as payload deserialization bottlenecks, concurrency contention, and tail-latency SLA violations—under real traffic distributions. Bypassing canary deployments removes the blast-radius barrier, exposing all users immediately to edge-case regressions or numerical instability. Resolving failures in production requires emergency rollbacks, distributed log triage, and corrupted state repair, incurring orders of magnitude more engineering downtime than the validation gates bypassed.
Pitfall: Deferring deployment paradigm selection until after model development.
Teams often assume deployment targets can be selected after optimizing model accuracy. In practice, the deployment paradigm (Cloud, Edge, Mobile, or TinyML) is a primary constraint that shapes every preceding lifecycle stage (table 3). Suppose a team develops a 2 GB ensemble model before learning that its TinyML target has 256 KB of memory. The resulting mismatch cascades backward, forcing teams to redesign data preprocessing, model architecture, and evaluation benchmarks. The chapter’s illustrative constraint-propagation model assigns a stage-5 discovery \(2^{4} = 16\times\) the stage-1 cost. Deferring platform selection guarantees expensive iteration cycles, because deployment hardware dictates which models are physically realizable, not merely where they execute.
Self-Check: Question
Why does the chapter characterize ‘scaling dataset size is always the best way to improve model accuracy’ as a major engineering pitfall?
- A. Because deep learning models degrade in accuracy when trained on more than ^5$ samples due to parameter saturation.
- B. Because collecting additional data increases the Operations ($) term during inference execution.
- C. Because once a target distribution is sufficiently covered, adding raw data yields sharply diminishing returns, whereas investing in label cleaning, balanced subgroup representation, and edge-case curation produces higher accuracy gains at lower compute and storage cost.
- D. Because data privacy regulations strictly limit training set sizes to under 100,000 images in healthcare applications.
True or False: Deferring deployment paradigm selection (Cloud, Edge, Mobile, or TinyML) until after model architecture design and training are complete is an effective engineering strategy because modern model compression techniques can universally fit any trained model onto any target hardware without compromising accuracy.
A software engineering team decides to skip shadow-mode validation and canary deployment to accelerate product delivery, relying entirely on strong test-set accuracy scores. According to the chapter’s analysis of workflow fallacies, why does this practice usually increase total time-to-production rather than shortening it?
- A. Because skipping canary deployment causes compilers to emit unoptimized serving binaries.
- B. Because offline test sets are mathematically incapable of computing classification accuracy.
- C. Because modern cloud orchestrators refuse to route traffic to containers that have not completed shadow mode.
- D. Because skipping progressive validation exports integration bugs, latency spikes, and distribution mismatches directly into production, where emergency triage, rollback, and data repair take far longer than staged validation.
Summary
The lifecycle is a feedback loop, not a checklist. The data pipeline transforms raw inputs through collection, ingestion, analysis, labeling, validation, and preparation into ML-ready datasets. The model development pipeline takes these datasets through training, evaluation, validation, and deployment to create production systems. With the full chapter as context, the feedback arrows in figure 1 carry the chapter’s central meaning: each one represents a lesson learned in production flowing back to strengthen earlier stages, making data and model feedback explicit in the development cycle.
Understanding this framework explains why machine learning systems require specialized additions to established software-engineering practices. ML workflows add probabilistic optimization, learned statistical behavior, and data-dependent feedback loops. The iron law supplies one quantitative lens: decisions across the lifecycle jointly change data movement, operation count, hardware efficiency, and fixed latency in \((T = \frac{D_{\text{vol}}}{\text{BW}} + \frac{O}{R_{\text{peak}} \cdot \eta_{\text{hw}}} + L_{\text{lat}})\), while production evidence feeds constraint violations back into review. This perspective recognizes that success emerges not from perfecting individual stages in isolation, but from understanding how data quality affects model performance, how deployment constraints shape training strategies, and how production insights inform each subsequent development iteration.
Three patterns define the engineering discipline of the ML lifecycle. Many practitioners report data collection, cleaning, labeling, validation, or preparation as major time sinks, while model development is only one part of the lifecycle. Production-ready systems also require repeated iteration cycles across data, model, and infrastructure stages, so investment in data engineering can have high leverage when data quality is a major source of rework. Finally, late constraints can increase rework: the chapter’s illustrative constraint-propagation model assigns a constraint discovered at stage \(N_{\text{stage}}\) roughly \(2^{N_{\text{stage}}-1}\) times the stage-1 correction cost, and it assigns a deployment paradigm mismatch discovered at stage 5 a 16× cost multiplier. Actual rework depends on which stages are affected. Early constraint discovery does not require freezing the workflow. It establishes an operating envelope through latency, memory, power, safety, and validation obligations while data and model choices continue to iterate within those bounds.
Key Takeaways: See the whole map first
- The lifecycle is a loop, not a checklist: Data and model pipelines advance in parallel, but production feedback is what makes them a system. Monitoring, validation, and retraining send lessons from deployment back into collection, labeling, architecture, and infrastructure decisions.
- Late constraints can increase rework: The illustrative model assigns a deployment limit found at stage \(N_{\text{stage}}\) roughly \(2^{N_{\text{stage}}-1}\) times the stage-1 correction cost. The stage-5 mismatch’s 16× multiplier shows why requirements should flow backward early.
- Iteration velocity expands search opportunity: Under the worked assumptions, a lightweight model starting 5 percentage points behind reaches the shared 99 percent ceiling because shorter cycles permit more assumed improvements. Workflow speed alone cannot guarantee model quality.
- Interfaces make feedback actionable: Stage contracts define inputs, outputs, and quality invariants so that data, model, and deployment teams can detect violations before integration. Without explicit contracts, each stage can optimize locally while the system fails globally.
- Production speaks on different clocks: Real-time inference monitoring, batch update reviews, and quarterly architectural reviews answer different failure modes. Treating all feedback as one loop either reacts too slowly to drift or churns expensive workflows without signal.
- Workflow carries constraints through time: Problem definition records targets, data collection shapes evidence and byte volume, model development changes operations and reuse, deployment realizes the complete serving path, and monitoring sends violations back into review. The lifecycle is data-algorithm-machine coupling unfolding over time.
This workflow framework turns ad hoc ML experimentation into a more disciplined engineering practice. By understanding how data pipelines and model development interact through feedback loops, teams can identify integration risks earlier and allocate resources more deliberately. The constraint propagation principle shows why systematic workflow management is risk mitigation rather than bureaucratic overhead.
Seen as a checklist, the lifecycle is a sequence of stages to clear in order. Seen correctly, it is a loop. A constraint discovered at deployment does not stay there; it may force rework in dependent model and data decisions. A workflow is therefore a coupled system rather than a pipeline, the same coupling the D·A·M taxonomy describes in space, now unfolding in time. Optimizing one stage in isolation moves the failure instead of removing it, which is why the discipline is to see the whole map before touching any single part of it.
What’s Next: From blueprint to fuel
The workflow framework established here provides the blueprint for every technical chapter that follows. An engine without fuel, however, is only a heavy block of metal; for an ML system, that fuel is data. Data Engineering therefore develops the first D·A·M axis, Data. Part II then builds the core system (neural network computation, model architectures, frameworks, training), Part III optimizes it for deployment (data selection, model compression, hardware acceleration, benchmarking), and Part IV deploys and operates it in production (model serving, operational practices, responsible engineering). Each chapter assumes familiarity with where its techniques fit within this complete workflow, building on the systematic perspective developed here.
Self-Check: Question
Which pair of parallel pipelines organizes the complete ML workflow in this chapter, and how do they interact through feedback loops?
- A. A research pipeline and a regulatory compliance pipeline that operate independently until final market authorization.
- B. A data pipeline (collection through preparation) and a model development pipeline (training through deployment), running in parallel and continuously coupled by forward artifact handoffs and backward operational feedback.
- C. A hardware provisioning pipeline and a software compiler pipeline that execute sequentially in a waterfall structure.
- D. An offline training pipeline and a real-time streaming pipeline that never share data artifacts.
Summarize how the chapter’s three primary quantitative takeaways—the CrowdFlower survey finding on data work, the Iteration Tax on development speed, and the exponential Constraint Propagation multiplier—jointly reshape how an engineering team should allocate resources on a new ML project.
True or False: An ML workflow is fundamentally a coupled, closed-loop system rather than a linear checklist, meaning that optimizing any individual stage in isolation merely shifts and compounds failures across data, algorithm, and machine dimensions rather than eliminating them.
Self-Check Answers
Self-Check: Answer
Team A ships a diabetic retinopathy (DR) screening model and freezes all development once the model clears validation in the lab, treating subsequent tasks as standard server operations. Team B treats the launch as the beginning of an ongoing feedback loop, monitoring operational telemetry and data distributions to guide investigation and evidence-based model updates. Which team’s posture aligns with the ML lifecycle as defined in this chapter, and why?
- A. Team B, because the ML lifecycle is a closed loop where operational feedback, distribution drift, and real-world performance continuously reshape upstream data and model decisions.
- B. Team A, because once a model meets its offline validation thresholds, its statistical properties remain fixed and require only standard infrastructure maintenance.
- C. Team A, because changing a validated model in production introduces regulatory risk that outweighs the benefits of adapting to data drift.
- D. Team B, because the ML lifecycle mandates automatic daily retraining of production models regardless of whether input distributions have drifted.
Answer: The correct answer is A. The chapter defines the ML lifecycle as an iterative, closed-loop engineering process where deployment is the start of the feedback loop rather than its conclusion. Production inputs, patient demographics, and equipment can shift even when code remains untouched, requiring continuous monitoring and evidence-based updates. The view that offline validation permanently freezes statistical behavior ignores real-world distribution drift. The claim that updates should be avoided due to regulatory risk misinterprets compliance frameworks, which mandate lifecycle management and change control. Furthermore, the lifecycle prescribes evidence-driven investigation and retraining when justified, not unconditional automatic daily retraining.
Learning Objective: Classify post-deployment engineering practices against the chapter’s closed-loop lifecycle definition.
In the chapter’s opening failure scenario, a team spends five months developing a diagnostic model that reaches 96 percent accuracy, only to have the entire project discarded on day 153. Explain the root cause of this failure from a workflow perspective and state the systems engineering rule that would have prevented it.
Answer: The failure was a workflow breakdown caused by optimizing model accuracy in isolation while ignoring downstream physical constraints. The team discovered only after development that the target clinic tablets had only 512 MB of memory available, whereas the model required 4 GB. The systems engineering rule that prevents this is backward constraint propagation: physical deployment limits (memory, latency, power budgets) must be established at Problem Definition on day one and propagate backward to constrain feasible model architectures before development begins.
Learning Objective: Explain how late discovery of deployment constraints invalidates isolated model development and forces backward propagation of physical limits.
In the 2016 CrowdFlower data scientist survey cited in the text, respondents indicated that data-related tasks dominated their time, with 60 percent selecting ____ and organizing data as their largest time sink, compared to only 4 percent for refining algorithms.
Answer: cleaning. The survey highlights that cleaning and organizing data accounted for 60 percent of responses, and collecting datasets accounted for 19 percent, demonstrating that data engineering and preparation consume the vast majority of engineering effort compared to model refinement.
Learning Objective: Analyze the primary empirical time sinks reported by ML practitioners in the chapter’s survey analysis.
True or False: Traditional software workflows and ML lifecycles differ fundamentally because ML system behavior can degrade through data distribution drift over time even when application source code, execution environment, and hardware configuration remain completely untouched.
Answer: True. Traditional software behavior changes only when code, configuration, dependencies, or environment change. In contrast, ML systems learn statistical mappings from data; as real-world input distributions shift (such as new clinic cameras or changing patient demographics), model accuracy can degrade silently without any code modification or infrastructure error.
Learning Objective: Compare the fundamental failure mechanisms of ML systems against traditional software systems under distribution drift.
A training pipeline randomly shuffles a multi-terabyte dataset across samples on every epoch, pulling records from storage backed by NVMe and spinning disks. Even though the hardware accelerator has ample peak compute capacity, training throughput stalls. Which explanation correctly identifies the systems-level bottleneck according to the chapter?
- A. Random shuffling makes the training workload strictly compute-bound, so the accelerator cores become overloaded by stochastic gradient calculations.
- B. Random sample access across multi-terabyte storage defeats operating system spatial and temporal locality, causing page cache misses and I/O latency stalls that additional compute cannot resolve.
- C. Shuffling multi-terabyte datasets bypasses the operating system page cache entirely, forcing floating-point arithmetic units to stall on instruction decoding.
- D. The memory hierarchy becomes saturated because the accelerator requires deterministic sample ordering to maintain kernel pipeline parallelism.
Answer: The correct answer is B. Randomly accessing multi-terabyte records across storage defeats the fundamental assumptions of OS memory management: spatial locality (reading sequential memory addresses) and temporal locality (reusing recently accessed pages). When sample fetches scatter across storage, file system buffers and prefetchers suffer cache misses, forcing expensive storage accesses. Because the stall occurs in the data delivery path ({}/\(), adding more peak compute ({\text{peak}}\)) cannot resolve the bottleneck. The claim that shuffling makes the workload compute-bound misidentifies a data-movement stall as a compute limitation. The assertion regarding instruction decoding confusion is technically incorrect, and accelerator parallelism does not depend on deterministic data ordering.
Learning Objective: Analyze how randomized data access patterns in ML training defeat OS locality mechanisms and cause data-delivery bottlenecks.
Self-Check: Answer
Order the following lifecycle phases in the canonical sequence established in the chapter for a new ML system project: (1) Deployment and Integration, (2) Problem Definition, (3) Monitoring and Maintenance, (4) Data Collection and Preparation, (5) Model Development and Training, (6) Evaluation and Validation.
Answer: The correct order is: (2) Problem Definition, (4) Data Collection and Preparation, (5) Model Development and Training, (6) Evaluation and Validation, (1) Deployment and Integration, (3) Monitoring and Maintenance. Each stage consumes artifacts and contracts produced by preceding stages: Problem Definition sets measurable objectives and physical constraints; Data Collection acquires and curates versioned datasets satisfying those constraints; Model Development trains candidate models within the computational budget; Evaluation and Validation gates models against stratified safety thresholds; Deployment and Integration delivers serving infrastructure meeting latency SLAs; and Monitoring and Maintenance tracks live operational telemetry and feeds drift evidence back into upstream stages.
Learning Objective: Classify and sequence the six core ML lifecycle stages and justify the prerequisite artifact dependencies across stage boundaries.
An engineering team completes Problem Definition with clinical sensitivity targets but marks the target deployment paradigm as ‘TBD — to be determined after model training.’ According to the Stage Interface Specification, what should the transition audit verdict be, and why?
- A. Approved, because decoupling model development from hardware targets allows researchers to maximize accuracy before applying post-hoc pruning.
- B. Approved with warning, provided the team commits to using cloud inference if the model exceeds edge memory budgets.
- C. Blocked, because Problem Definition’s output contract explicitly requires deployment paradigm and resource constraints to be established before data collection and modeling begin.
- D. Blocked only if the model architecture requires distributed multi-GPU training, since single-device models can adapt to any deployment target.
Answer: The correct answer is C. The Stage Interface Specification requires that Problem Definition’s Output Contract specify measurable objectives, deployment paradigm selection (Cloud, Edge, Mobile, or TinyML), and resource constraints. Deferring deployment paradigm selection violates the contract because target hardware constraints (such as memory limits and latency budgets) directly determine what data preprocessing is feasible and pre-eliminate unviable model architectures. Under the Constraint Propagation Principle, deferring this constraint to deployment causes exponential rework costs (^{N_{}-1}$). The argument for unconstrained accuracy optimization ignores physical deployment realities. Promising fallback to cloud inference ignores connectivity and latency requirements, and single-device models cannot universally run on resource-constrained edge hardware.
Learning Objective: Apply stage interface contracts to audit lifecycle transitions and enforce early constraint binding.
The chapter discusses MobileNetV2 with its ~600 MFLOPs inference budget as a lighthouse case study for workflow thinking. Explain how establishing this mobile constraint at Problem Definition propagates across Data Collection, Model Development, and Evaluation.
Answer: Establishing the ~600 MFLOPs mobile constraint at Problem Definition immediately reshapes all downstream stages: in Data Collection, input image resolution and preprocessing pipelines must be designed to execute within mobile memory and compute limits; in Model Development, it forces the selection of efficient operators (such as depthwise separable convolutions) rather than dense convolutions or large ensembles; in Evaluation, it requires validating on-device latency, power dissipation, and memory footprint on target mobile hardware alongside classification accuracy.
Learning Objective: Explain how mobile hardware constraints propagate backward through Problem Definition, Data Collection, Model Development, and Evaluation.
Which mapping between lifecycle stages and the terms in the Iron Law of ML Systems ( = + + L_{}$) is conceptually correct according to the chapter?
- A. Problem Definition governs {}$; Evaluation governs $; Monitoring governs \(\text{BW}\).
- B. Data Collection sets {}$; Model Development sets \(\text{BW}\); Deployment sets {}$.
- C. Deployment governs \(; Model Development governs {\text{vol}}\); Data Collection governs {}$.
- D. Data Collection and Preparation shapes $ and {}$; Model Development and Training sets \(; Deployment and Integration minimizes {\text{lat}}\).
Answer: The correct answer is D. In the chapter’s iron law perspective, Data Collection and Preparation directly determines dataset size (\() and the data movement byte volume ({\text{vol}}\)); Model Development and Training establishes model architecture and operations (\() along with achievable hardware efficiency (\)_{}\(); and Deployment and Integration engineers the serving pipeline to minimize fixed latency and network overhead ({\text{lat}}\)). The other mappings confuse stages that measure system performance with stages that physically set the underlying mathematical terms; for example, {}$ is a hardware specification rather than an output of Problem Definition, and {}$ is determined by deployment serving infrastructure rather than data collection.
Learning Objective: Apply the Iron Law of ML Systems to classify each core lifecycle stage by its governing parameter.
To prevent defect propagation across lifecycle boundaries, the chapter formalizes each stage boundary using a(n) ____ contract, which defines required inputs, output deliverables, and non-negotiable quality invariants.
Answer: stage interface. Stage interface contracts establish formal quality gates at each transition boundary in the ML lifecycle, ensuring that prerequisites (such as deployment paradigm selection or schema validation) are met before downstream engineering begins.
Learning Objective: Explain the role of stage interface contracts as control-plane quality gates in ML workflows.
Self-Check: Answer
Why does the statement ‘Build a computer vision model that detects diabetic retinopathy’ fail as a complete problem definition for an ML system?
- A. It specifies only a high-level task while omitting the statistical constraint layers (sensitivity/specificity floors across subgroups), physical constraints (edge device memory/latency budgets), and operational constraints (regulatory compliance, clinical workflow integration).
- B. It fails to specify which exact deep neural network backbone and learning rate schedule must be used during training.
- C. It defines an image classification problem when medical AI systems must always be framed as unsupervised anomaly detection tasks.
- D. It defines quantifiable objectives before data collection has occurred, which violates standard ML agile practices.
Answer: The correct answer is A. An ML problem definition is not a one-sentence task label; it is a multi-constraint optimization problem spanning statistical layers (>90% sensitivity and >80% specificity across diverse populations), physical layers (inference on edge hardware within 50 ms and under 500 MB memory), and operational layers (FDA regulatory compliance, HIS workflow integration, patient privacy). Omitting these layers leaves downstream teams without the constraints needed to bound the design space. Specifying model backbones upfront inverts the workflow order, unsupervised anomaly detection is not mandatory for medical classification, and establishing quantifiable targets upfront is an essential requirement of the Problem Definition output contract.
Learning Objective: Explain why complete ML problem definitions require layered statistical, physical, and operational constraints.
Explain why ophthalmologists and clinic administrators must participate directly in Problem Definition for a DR screening system, rather than being consulted only during clinical evaluation.
Answer: Engineers optimizing models in isolation tend to maximize aggregate accuracy, but clinical safety depends on domain-specific trade-offs that only medical experts understand. Ophthalmologists define the clinical penalty of false negatives (missed cases leading to blindness) versus false positives (overwhelming specialist clinics), translating medical needs into non-negotiable sensitivity (>90%) and specificity (>80%) floors. Clinic administrators identify physical and workflow constraints (such as 5-minute patient visit windows, older fundus cameras, and intermittent connectivity), ensuring engineering targets reflect real clinical operations from day one.
Learning Objective: Justify the necessity of cross-disciplinary domain collaboration during Problem Definition to establish valid engineering constraints.
In the 2018 Amazon automated recruiting war story cited in the chapter, an ML model trained on ten years of resumes was abandoned because it systematically penalized female applicants. What fundamental systems lesson does this case illustrate regarding Problem Definition?
- A. Resume screening models require recurrent neural networks rather than transformer architectures to avoid learning gendered proxies.
- B. Offline evaluation metrics are inherently incapable of measuring demographic disparities in supervised learning models.
- C. A model trained on historical data learns to reproduce historical label biases rather than the intended operational goal; fairness criteria and auditability must be explicitly defined at Problem Definition.
- D. Multi-class classification algorithms should not be applied to human evaluation tasks where ground truth is subjective.
Answer: The correct answer is C. The Amazon recruiting case demonstrated that when historical hiring was male-dominated, the model learned that male-coded terms correlated with past hiring decisions and penalized female-coded terms. Simply removing explicit gender words failed because the model identified correlated proxy features. The systems lesson is that Problem Definition must specify fairness, auditability, and validation criteria before data collection and training; an ML workflow trained on biased historical labels optimizes to reproduce the bias of those labels rather than the true organizational goal. The failure was not an architecture choice, offline metrics can measure disparities if stratified evaluation is performed, and binary/multi-class framing was not the root cause.
Learning Objective: Analyze how historical label bias corrupts ML workflows and justify why fairness criteria must be specified at Problem Definition.
True or False: When a diabetic retinopathy screening deployment scales from a 3-clinic pilot to 200 clinics across diverse regions, the high-level clinical intent (detect referable retinopathy early) remains stable, but the specific engineering targets (subgroup sensitivity thresholds, device latency budgets, and camera-specific preprocessing rules) must evolve.
Answer: True. Scaling exposes heterogeneity in patient demographics, camera manufacturers, lighting conditions, and operator training that was invisible at pilot scale. While the overarching clinical mission remains unchanged, the engineering problem definition is a living document that must be revised to include stratified subgroup thresholds, support for older hardware, and updated operational constraints.
Learning Objective: Compare stable clinical intent with evolving engineering targets during deployment scaling.
Self-Check: Answer
A rural clinic captures 150 patients per day for DR screening, with 10 retinal photos per patient at 5 MB per photo. The clinic operates on an 8-hour daily shift with a 2 Mbps uplink. According to the chapter’s Bandwidth vs. Compute analysis, what operational bottleneck arises, and how does edge inference resolve it?
- A. Daily raw image upload requires ~2.5 hours, which fits comfortably within the 8-hour window without needing edge processing.
- B. Daily raw image upload generates 7.5 GB of data requiring ~8.3 hours to transfer—saturating the entire 8-hour clinic shift—whereas edge inference uploading 10 KB detection summaries reduces network traffic by roughly 5,000\(\times\).
- C. Daily raw image upload generates 75 GB of data, which exceeds daily satellite uplink capacity by a factor of 100\(\times\) regardless of compression.
- D. Raw uploads complete in 45 minutes, but cloud GPU queuing delay adds 12 hours of fixed inference latency.
Answer: The correct answer is B. As calculated in the chapter: = 7,500 = 7.5 \(. Transmitting 7,500 MB over a 2 Mbps link (0.25 MB/s) requires ,500 / 0.25 = 30,000 \text{ seconds} \approx 8.33 \text{ hours}\). Because 8.33 hours exceeds the 8-hour operating window, raw upload continuously saturates the connection. Performing inference locally and transmitting compact 10 KB summaries per patient ( = 1.5 \() achieves a ,500 \text{ MB} / 1.5 \text{ MB} = 5,000\times\) bandwidth reduction, transferring in under 6 seconds. The 2.5-hour estimate reflects incorrect unit conversion, the 75 GB estimate miscalculates patient volume, and the 45-minute upload claim contradicts basic network physics.
Learning Objective: Calculate network transmission times for clinical data collection and evaluate edge preprocessing as a bandwidth mitigation strategy.
Explain why a DR screening model achieving an AUC of 0.99 on a curated laboratory research dataset can experience a severe drop in sensitivity (e.g., falling to 78 percent) when deployed to rural clinics across Thailand and India.
Answer: This drop illustrates the lab-to-field distribution gap. Curated research datasets are captured using standardized, high-end fundus cameras under controlled lighting with dilated pupils and experienced operators. In rural field clinics, images are captured on older, lower-resolution cameras by technicians with minimal training, leading to motion blur, poor illumination, glare, and improper framing. The model degrades not because the learning algorithm is broken, but because production inputs fall outside the training data distribution envelope.
Learning Objective: Analyze how distribution mismatches between curated research datasets and real-world field environments cause deployment performance gaps.
In tiered storage architectures for ML pipelines, placing active training data in cold or warm object storage (e.g., S3 Standard with 100–200 ms latency) instead of local high-throughput NVMe SSDs directly degrades training performance by affecting which term in the Iron Law of ML Systems?
- A. It increases the Operations ($) term by forcing the model to compute extra gradient updates.
- B. It decreases peak hardware performance ({}$) by downclocking GPU compute cores.
- C. It decreases hardware utilization efficiency (\(\eta_{\text{hw}}\)) solely through floating-point precision mismatches.
- D. It inflates the data movement time (\(\frac{D_{\text{vol}}}{\text{BW}}\)), converting a compute-bound training pipeline into an I/O-bound stall where accelerators sit idle waiting for data batches.
Answer: The correct answer is D. In the Iron Law ( = + + L_{}\(), storage throughput and access latency govern effective data bandwidth (\)\() and delivery time for training data volume ({\text{vol}}\)). High-throughput NVMe SSDs deliver 500,000+ IOPS and sequential reads at 1–10 GB/s, keeping accelerators saturated. Using high-latency object storage restricts effective \(\text{BW}\), causing data starvation where accelerators stall waiting for batches. It does not alter mathematical operations (\(), change hardware theoretical peak ({\text{peak}}\)), or alter floating-point formats.
Learning Objective: Analyze the impact of tiered storage choices on the Iron Law data movement term ({}/$) during model training.
True or False: In large-scale medical data collection, if collected images pass basic file format and schema validation, image-quality defects (such as blur, low contrast, or partial occlusion) can be safely ignored because deep neural networks naturally learn to filter out bad samples when trained on sufficiently large datasets.
Answer: False. Poor-quality images distort the training distribution and introduce label noise at the critical diagnostic boundary. A blurry fundus image where microaneurysms are obscured may be mislabeled as healthy or cause the network to learn spurious artifacts. Catching defects at the point of capture via real-time image-quality checks allows immediate recapture; allowing bad data into training triggers the Constraint Propagation Principle, where correcting the resulting model failures at stage 5 or 6 costs $ to $ more than catching them at stage 2.
Learning Objective: Evaluate why early point-of-capture data quality validation is essential despite large training set sizes.
In rural clinics with intermittent connectivity, an architecture that buffers captured images locally and reconciles inference results asynchronously with the central cloud during available network windows is known as a(n) ____ architecture.
Answer: store-and-forward. Store-and-forward architectures buffer data locally during network outages and transmit batched data when connectivity is restored, decoupling local clinical operations from central cloud availability.
Learning Objective: Classify store-and-forward architectures as the primary mechanism for managing intermittent network connectivity in distributed data pipelines.
Self-Check: Answer
According to the chapter, which bundle of deliverables constitutes a complete, reproducible system artifact from the Model Development and Training stage, and why are model weights alone insufficient?
- A. Model weights, inference/preprocessing code, environment specification (e.g., container or locked dependency graph), and runtime configuration; weights alone fail because library version mismatches or preprocessing differences alter outputs without crashing.
- B. Model weights and a serialized training log; the execution environment can always be inferred from the framework version tag.
- C. Model weights, a test-set evaluation scorecard, and an architecture diagram; deployment engineers reconstruct dependencies during serving containerization.
- D. Source code repository commits and hyperparameters; weights can be deterministically reproduced from random seeds on any hardware.
Answer: The correct answer is A. A mature ML workflow defines a reproducible system artifact as four co-dependent components: model weights, inference preprocessing code, environment specification (Docker image, CUDA driver, dependency graph), and runtime configuration. Packaging weights alone creates ‘works on my machine’ failures: subtle differences in linear algebra kernels, CUDA versions, or image-resizing libraries (e.g., OpenCV vs. PIL) alter floating-point outputs or pixel interpolation without throwing exceptions, silently degrading accuracy. Training logs or scorecards do not enable execution, and hardware differences make pure seed-based bitwise weight reconstruction unreliable across different accelerator architectures.
Learning Objective: Classify the four core components of a reproducible system artifact and explain why weights alone fail to guarantee consistent inference.
Explain why a competition-winning 50-model ensemble that achieves state-of-the-art accuracy on a benchmark may be discarded for production edge deployment, citing the Netflix Prize as an empirical reference.
Answer: Ensemble accuracy gains come with multiplicative operational costs: model size, memory footprint, and inference latency scale directly with the number of constituent models. In the Netflix Prize competition, the winning BellKor ensemble achieved a 10 percent RMSE improvement but was never deployed to production because the substantial engineering complexity and serving latency did not justify the incremental accuracy gain. On resource-constrained edge devices (such as clinic tablets with 512 MB memory), running a 50-model ensemble violates memory, latency, and power budgets, making lightweight single models or compressed architectures the only viable engineering choice.
Learning Objective: Analyze the competition-versus-production trade-off in ensemble methods and justify why benchmark-winning models may be unviable for edge serving.
In the chapter’s Iteration Tax scenario, a team compares Model L (large ensemble, starts at 95% accuracy, 1-week training cycle, +0.15% gain/iter) with Model S (lightweight model, starts at 90% accuracy, 1-hour training cycle, +0.1% gain/iter, 100 effective iters) over a 26-week window with a 99% ceiling. What is the modeled outcome after 26 weeks, and what systems lesson does it demonstrate?
- A. Model L reaches 99.0% while Model S reaches 92.6%, proving that starting accuracy dominates iteration speed over six months.
- B. Model S reaches the 99.0% ceiling while Model L reaches 98.9%, demonstrating that shorter training cycles permit more iterative experiments that can overcome a lower starting accuracy.
- C. Both models reach exactly 95.0% accuracy because human hypothesis generation saturates at 26 experiments regardless of training speed.
- D. Model L fails to converge due to training instability, while Model S converges to 90.0% without improvement.
Answer: The correct answer is B. As modeled in the Iteration Tax notebook: over 26 weeks, Model L runs 26 iterations at 1 week each, reaching .0% + (26 %) = 98.9%\(. Model S runs 100 effective iterations (capped by hypothesis generation), reaching an uncapped .0\% + (100 \times 0.1\%) = 100.0\%\), which hits the .0%$ ceiling. The systems lesson is that iteration velocity is a feature: shorter cycle times allow teams to test far more architectures, data augmentations, and hyperparameters, enabling an initially weaker but fast-iterating model to overtake a slow-training alternative across a fixed development timeline. The claim that Model L finishes higher contradicts the worked math, and the saturation/non-convergence claims contradict the chapter’s scenario parameters.
Learning Objective: Calculate the cumulative accuracy trajectory under the Iteration Tax model and explain how experimentation velocity acts as a systems optimization lever.
A team observes that model validation accuracy drops 2 percent between run 47 and run 48. Explain how an automated experiment tracking lineage record resolves this regression compared to an ad hoc notebook workflow.
Answer: In an ad hoc workflow without lineage, diagnosing the drop requires weeks of manual forensics and expensive trial-and-error experiment reruns because changes across code commits, dataset versions, hyperparameter values, random seeds, and library dependencies are unrecorded and entangled. With automated lineage tracking (e.g., MLflow, Weights & Biases), every run artifact is immutably indexed with its exact dataset snapshot, git commit hash, environment container, random seed, and hyperparameter dictionary. The team executes a single metadata diff between run 47 and run 48 to instantly isolate the causal variable.
Learning Objective: Explain how automated artifact lineage converts regression root-cause analysis from manual forensics into an immediate metadata query.
Arrange the following model development milestones in the logical order prescribed for a constraint-driven ML workflow: (1) Baseline transfer-learning fine-tuning from pretrained weights, (2) Physical constraint profiling (target latency, memory ceiling, power envelope), (3) Systematic ablation studies to isolate component contributions, (4) Model compression (pruning/quantization) and hardware-in-the-loop latency validation, (5) Packaging weights, preprocessing code, dependencies, and configuration into a reproducible system artifact.
Answer: The correct order is: (2) Physical constraint profiling (target latency, memory ceiling, power envelope), (1) Baseline transfer-learning fine-tuning from pretrained weights, (3) Systematic ablation studies to isolate component contributions, (4) Model compression (pruning/quantization) and hardware-in-the-loop latency validation, (5) Packaging weights, preprocessing code, dependencies, and configuration into a reproducible system artifact. Development must begin by establishing physical constraint boundaries; next, transfer learning establishes a functional baseline; ablation studies systematically isolate architectural improvements; model compression adapts the architecture to target device constraints; and finally, all code, weights, environment specs, and configs are packaged into a reproducible artifact.
Learning Objective: Design the sequence of stages in a constraint-driven model development and optimization pipeline.
Self-Check: Answer
What is the primary conceptual distinction between Model Evaluation and Model Validation as defined in this chapter?
- A. Evaluation is conducted by internal software engineers, whereas validation is conducted exclusively by government regulatory agencies.
- B. Evaluation tests software execution speed on accelerators, whereas validation tests algorithm mathematical convergence on CPUs.
- C. Evaluation measures model behavior on chosen datasets and metrics; validation is a multi-dimensional evidence gate confirming the model satisfies all operational, latency, subgroup fairness, robustness, and cost constraints under production-representative conditions.
- D. Evaluation is performed on live production traffic, whereas validation is performed exclusively on synthetic offline data.
Answer: The correct answer is C. The chapter defines Model Evaluation as characterizing algorithmic performance using selected datasets, loss metrics, and test benchmarks. Model Validation is an evidence-based decision gate for deployment readiness, verifying that the integrated model and system satisfy all physical constraints (latency, memory, power), subgroup safety floors (demographic fairness, comorbidity performance), robustness under distribution shift (blur, lighting, camera variation), and cost budgets. Confining validation to external regulators misses its internal engineering function, splitting evaluation/validation by hardware architecture is incorrect, and online vs. offline execution is handled within staged validation rather than defining the conceptual boundary.
Learning Objective: Compare Model Evaluation and Model Validation to classify their distinct roles in deployment readiness gating.
A diabetic retinopathy screening model achieves 94 percent aggregate accuracy on held-out validation data. However, stratified evaluation reveals that sensitivity drops to 76 percent for patients with cataracts and falls below the 90 percent sensitivity floor for one demographic subpopulation. How should the engineering team respond?
- A. Proceed to full deployment immediately, because aggregate accuracy above 90 percent statistically compensates for minor subpopulation variations.
- B. Apply post-hoc temperature scaling to increase overall prediction confidence, which automatically resolves subgroup sensitivity deficits.
- C. Deploy the model in shadow mode permanently, since shadow mode bypasses clinical subgroup safety requirements.
- D. Block deployment, because the model violates non-negotiable clinical sensitivity safety thresholds for vulnerable subgroups; stratified validation exists precisely to prevent aggregate metrics from masking localized clinical harm.
Answer: The correct answer is D. In medical AI systems, aggregate accuracy is deceptive: high overall accuracy can obscure catastrophic error rates in specific sub-populations. A sensitivity drop to 76 percent in cataract patients or below the 90 percent safety floor means referable eye disease will be missed, leading to preventable blindness. Problem Definition establishes that subgroup sensitivity floors are hard quality invariants; failing them must block deployment regardless of aggregate accuracy. Relying on aggregate metrics to override subgroup failure violates medical safety principles, temperature scaling modifies confidence scores without altering underlying class sensitivity, and shadow mode is an evaluation stage rather than a permanent production workaround.
Learning Objective: Evaluate stratified subgroup validation results and justify blocking deployment when subgroup safety thresholds are violated.
Explain why a medical diagnostic model with an outstanding Area Under the ROC Curve (AUC) of 0.99 on a research dataset may still fail deployment validation for clinical screening.
Answer: AUC is a threshold-independent metric that evaluates ranking quality across all possible classification cutoffs from 0 to 1. In production clinical screening, however, the model operates at a single, fixed decision threshold. At that specific operating point, the model must simultaneously satisfy strict clinical floors: sensitivity >90 percent (to prevent missed diagnoses) and specificity >80 percent (to prevent overwhelming referral clinics) on production-representative data with diverse camera models and lighting. A high AUC does not guarantee that any single operating threshold meets both clinical floors under real-world distribution shift.
Learning Objective: Explain why threshold-free AUC metrics do not establish clinical deployment readiness at fixed operating thresholds.
Order the stages of progressive online validation from lowest initial user risk to broadest comparative evaluation: (1) Canary deployment exposing 1–5% of live traffic, (2) Offline evaluation on held-out and stratified test sets, (3) A/B testing comparing outcomes against the production baseline, (4) Shadow mode running in parallel on live requests without serving predictions to users.
Answer: The correct order is: (2) Offline evaluation on held-out and stratified test sets, (4) Shadow mode running in parallel on live requests without serving predictions to users, (1) Canary deployment exposing 1–5% of live traffic, (3) A/B testing comparing outcomes against the production baseline. Progressive validation begins offline with static benchmark testing; next, shadow mode tests end-to-end serving integration and performance under live production load with zero user exposure; canary deployment routes a small, controlled fraction of traffic to verify stability under real user interactions; and finally, A/B testing establishes statistically significant comparative efficacy against the incumbent baseline.
Learning Objective: Design the sequence of progressive online validation stages from zero-exposure integration testing to live comparative evaluation.
True or False: Model calibration—ensuring that a predicted confidence score of 0.80 corresponds to an empirical 80 percent probability of correctness—is critical for medical AI systems because clinical triage workflows rely directly on confidence scores to route ambiguous cases to human specialists.
Answer: True. Calibration is distinct from classification accuracy. In clinical triage, physicians use model confidence scores to determine whether automated decisions can be trusted or require specialist review. An uncalibrated model that outputs 95% confidence on borderline, uncertain cases can dangerously mislead clinicians into skipping necessary specialist referrals, creating severe safety risks even if aggregate accuracy appears acceptable.
Learning Objective: Evaluate the role of model calibration in supporting safe clinical triage and human-in-the-loop routing.
Self-Check: Answer
A deployment model processes ~760,000 screening images per month across 500 rural clinics. Cloud inference costs zsh.01/image plus ,000/year for connectivity/network operations (,200/year total). Edge deployment requires a device per clinic (,000 CapEx), ,000/year maintenance, and zsh.001/image (,120/year total OpEx). According to the chapter’s economics calculation, what is the annual operating savings of edge deployment and its payback period?
- A. ~,080 annual savings with a payback period of approximately 2.4 to 2.5 years, while enabling offline operation during connectivity outages.
- B. ~,000 annual savings with a payback period of 10 years, making cloud deployment far more economical.
- C. ~,000 annual savings with an immediate 3-month payback period.
- D. Zero annual savings, because edge hardware maintenance costs exactly equal cloud inference fees at 500 clinics.
Answer: The correct answer is A. As calculated in the Deployment Economics notebook: Total Cloud Annual OpEx = ,200. Total Edge Annual OpEx = ,000 (maintenance) + ,120 (variable inference) = ,120. Annual Savings = ,200 - ,120 = ,080. Edge Hardware CapEx = 500 clinics \(\times\) /device = ,000. Payback Period = ,000 / ,080 \(\approx\) 2.45 years (~2.5 years). Beyond cost recovery, edge deployment provides the critical operational advantage of functioning without internet connectivity during network outages. The alternative figures miscalculate either CapEx, OpEx, or the payback quotient.
Learning Objective: Calculate total cost of ownership, annual operating savings, and payback period for cloud versus edge ML deployment.
Explain why integrating a probabilistic ML model into a Hospital Information System (HIS) differs fundamentally from integrating a deterministic clinical sensor (such as a digital blood pressure monitor).
Answer: A deterministic sensor outputs a discrete measurement with fixed units and deterministic error bounds that writes directly to database records. A probabilistic ML model outputs class probabilities and uncertainty estimates that reflect statistical distributions. HIS integration for ML must incorporate calibrated confidence thresholds, interpretable visual evidence (e.g., lesion localization), and validated human-in-the-loop clinical routing policies (e.g., automatically referring low-confidence cases to specialists). Furthermore, privacy regulations (e.g., HIPAA) constrain how inference outputs and patient images can be stored, audited, or fed back into retraining loops.
Learning Objective: Compare the architectural and operational integration requirements of probabilistic ML models against deterministic medical sensors.
An edge-deployed DR screening tablet has a 100 ms total latency budget. Profiling reveals the following execution breakdown: on-device model inference = 15 ms, remote cloud lookup for patient metadata = 60 ms, and local serialization/HIS formatting = 40 ms (total = 115 ms). Which engineering modification directly reduces the Iron Law fixed overhead ({}$) term to meet the 100 ms budget?
- A. Prune the neural network weights to reduce on-device model inference time from 15 ms to 5 ms.
- B. Cache patient metadata locally on the tablet to eliminate the 60 ms remote network round-trip.
- C. Quantize the model from FP32 to INT8 to increase arithmetic operational intensity ($).
- D. Increase the GPU clock frequency on the edge tablet to accelerate tensor core processing.
Answer: The correct answer is B. In the Iron Law ( = + + L_{}\(), the 60 ms network round-trip and 40 ms serialization overhead represent fixed serving overhead ({\text{lat}}\)), accounting for 100 ms of the 115 ms total. Pruning or quantizing the model can only save a fraction of the 15 ms inference time, leaving total latency above 100 ms. Caching patient metadata locally replaces the 60 ms network round-trip with a sub-millisecond local read, cutting {}$ from 100 ms to ~40 ms and reducing total latency to ~55 ms, well within the 100 ms budget.
Learning Objective: Apply the Iron Law fixed overhead term ({}$) to analyze latency bottlenecks and evaluate caching strategies.
True or False: Phased deployment progressing from simulation to pilot clinics to full production rollout is recommended because each phase is designed to expose a distinct, non-overlapping class of system failures: simulation catches software integration and schema bugs; pilots catch real-world camera and workflow heterogeneity; and full production catches distributed concurrency contention and rare clinical tail cases.
Answer: True. Staged rollout acts as structured risk segmentation. Testing in simulation isolates interface defects without risking patients; pilot deployment exposes environmental and human factors (such as clinic lighting, operator habits, and varying camera models) that simulations cannot replicate; and full-scale rollout surfaces system contention, network bottlenecks, and rare pathologies that appear only across large patient volumes. Skipping phases exports localized failure modes into expensive full-scale incidents.
Learning Objective: Analyze how phased deployment segments risk across distinct failure classes from simulation to full production.
A deployment policy that automatically routes low-confidence or high-uncertainty model predictions to an expert specialist for manual review, while allowing high-confidence predictions to proceed automatically, is known as ____ routing.
Answer: human-in-the-loop. Human-in-the-loop routing uses calibrated model uncertainty to triage decisions, ensuring that ambiguous or borderline cases receive expert human oversight while automating routine, high-confidence cases.
Learning Objective: Explain human-in-the-loop routing as an operational mechanism for managing model uncertainty in high-stakes deployments.
Self-Check: Answer
Why does production ML monitoring structure its telemetry into a four-tier hierarchy of operational, proxy, performance, and data stability metrics rather than relying on a single metric class?
- A. Because cloud monitoring vendors charge lower fees when metrics are divided into multiple dashboard tabs.
- B. Because operational metrics like latency and CPU load are sufficient to detect model accuracy degradation in real time.
- C. Because different failure modes emerge across different timescales: operational metrics catch service crashes in seconds, proxy metrics (confidence, referral rate) detect distribution shifts in hours without labels, and performance metrics (sensitivity, specificity) confirm diagnostic accuracy weeks later when ground truth arrives.
- D. Because ground-truth diagnostic labels are instantly available in real time for every inference request in production.
Answer: The correct answer is C. Different system failures surface on distinct timescales. Operational metrics (latency, error rate, queue depth) detect infrastructure crashes within seconds but reveal nothing about statistical prediction quality. Proxy metrics (confidence distributions, referral rates, image quality rejection rates) provide real-time indicators of data drift within hours without waiting for labels. Performance metrics (sensitivity, specificity) measure true accuracy but require adjudicated ground-truth labels that arrive with weeks of delay. Relying on any single tier creates blind spots: operational metrics miss silent drift, while performance metrics respond too slowly to active incidents.
Learning Objective: Analyze the multi-timescale hierarchy of operational, proxy, and performance metrics in production ML monitoring.
Explain why reverting an ML system to an older model checkpoint during a production degradation incident is only a mitigation tactic rather than a true system state restoration.
Answer: In traditional software, reverting to an older binary restores the exact prior system behavior because program logic is deterministic. In ML systems, however, model validity is coupled to the specific data distribution on which it was trained. When production data has drifted (e.g., clinics upgraded camera hardware or patient demographics shifted), rolling back to an older model restores stale weights against a permanently altered live data environment. The rolled-back model may perform even worse on current inputs than the newly deployed model, creating a temporal state mismatch.
Learning Objective: Explain why model rollback is a temporary mitigation rather than a true system restore due to temporal data mismatch.
Six months after launch, a clinic network upgrades its fundus cameras to a newer model with a distinct color profile. System latency and server error rates remain perfectly stable at 0.0%, but clinical sensitivity drops from 92% to 77%. What systems phenomenon does this scenario illustrate?
- A. A deterministic crash in the GPU serving container caused by CUDA driver incompatibility.
- B. An adversarial perturbation attack executed against the clinic edge devices.
- C. Concept drift caused by a sudden biological mutation in the underlying disease pathology.
- D. Silent degradation caused by covariate/data drift; input pixel distributions shifted beyond the training envelope while traditional infrastructure monitoring showed healthy green dashboards.
Answer: The correct answer is D. This scenario illustrates silent degradation through covariate/data drift. The upgraded cameras alter the input image distribution (color spectrum, contrast, sensor noise), moving incoming data outside the envelope learned during training. Because the model executes without code errors, traditional software monitoring (uptime, latency, error codes) reports healthy green dashboards while clinical diagnostic performance degrades severely. It is not an infrastructure crash, not an adversarial attack, and not concept drift (the biological relationship between retina lesions and diabetes did not change; the imaging sensor distribution shifted).
Learning Objective: Analyze silent model degradation caused by data drift and explain why traditional infrastructure monitoring fails to detect it.
True or False: In production ML monitoring, lightweight statistical tests such as the Population Stability Index (PSI) and Kolmogorov-Smirnov (KS) test can detect shifts in input feature distributions, but an alert from these tests does not by itself prove that model classification accuracy has degraded until ground-truth outcome evidence is evaluated.
Answer: True. PSI and KS tests detect distribution divergence \(\mathcal{D}(P_t \parallel P_0)\) between current inference traffic and baseline training data. An input shift indicates that incoming data has drifted, which raises the probability of accuracy loss and triggers investigation; however, it does not prove that accuracy has degraded (the model might be robust to the specific feature shift). Confirming accuracy degradation requires evaluating labeled outcomes or verified clinical feedback.
Learning Objective: Evaluate the diagnostic scope of statistical drift tests (PSI, KS) and distinguish input distribution shifts from confirmed accuracy loss.
Describe what metadata elements must be linked in an automated data lineage audit trail for medical ML systems, and explain how lineage reduces the engineering cost of investigating a site-specific accuracy regression.
Answer: An automated data lineage record must link every production inference request to its exact model version, training dataset snapshot, preprocessing pipeline commit, hyperparameter configuration, framework environment, and clinic hardware identifier. Without lineage, investigating a regression requires weeks of forensic guesswork across unindexed logs. With lineage, engineers execute a single query to trace the exact causal chain of artifacts, instantly isolating whether a sensitivity drop at Site X resulted from a recent camera change, a preprocessing version bump, or a specific training data split.
Learning Objective: Analyze the metadata links required in a data lineage audit trail and justify how lineage streamlines regression root-cause analysis.
Self-Check: Answer
What does the Constraint Propagation Principle assert regarding the engineering cost of discovering constraints late in the ML lifecycle?
- A. Correction costs scale exponentially as roughly ^{N_{}-1}$ times the base effort when discovery is delayed to stage {}$, because artifacts produced across all intervening stages inherit the violation and must be rebuilt.
- B. Correction costs grow strictly linearly with stage index, because each stage requires exactly one day of rework.
- C. Correction costs remain constant across all stages because modular software abstractions isolate upstream stages from downstream changes.
- D. Correction costs decrease over time as downstream profiling provides more performance telemetry to guide optimization.
Answer: The correct answer is A. The Constraint Propagation Principle models the compounding cost of late constraint discovery: discovering an unmet constraint at stage {}$ carries an illustrative cost multiplier of ^{N_{}-1}$ relative to specifying it at stage 1 (Problem Definition). This exponential growth occurs because each traversed stage produces dependent artifacts (curated datasets, trained weights, validation suites, serving infrastructure) that inherit the invalid assumption and must be invalidated, redesigned, and re-executed. Linear, constant, or decreasing cost models ignore the structural coupling across ML lifecycle stages.
Learning Objective: Analyze the core claim and exponential cost formulation (^{N_{}-1}$) of the Constraint Propagation Principle.
A demographic fairness requirement (e.g., minimum sensitivity floor for patients over 70) should have been specified at Problem Definition (Stage 1) but is discovered only during Monitoring and Maintenance (Stage 6). Calculate the illustrative cost multiplier and enumerate the lifecycle stages that must be revisited to correct the system.
Answer: Under the chapter’s illustrative doubling model, the cost multiplier is ^{6-1} = 2^5 = 32$ the base effort. The team must revisit: (1) Problem Definition to codify stratified demographic sensitivity thresholds; (2) Data Collection to gather representative retinal images from patients over 70; (3) Model Development to retrain and re-tune architectures on the balanced dataset; (4) Evaluation and Validation to re-audit stratified subgroup metrics against clinical safety floors; and (5) Deployment and Integration to redeploy updated models with calibrated monitoring alerts.
Learning Objective: Calculate late-discovery cost multipliers using the ^{N_{}-1}$ formula and enumerate all intermediate lifecycle stages requiring rework.
In a multi-site distributed ML deployment spanning hundreds of clinics, why can system-wide emergent behaviors produce failures that are completely invisible when examining individual clinics in isolation?
- A. Because distributed communication protocols inject pseudo-random noise into inference predictions.
- B. Because local monitoring averages away subpopulation variance; an underserved demographic group that represents only 1–2% of patients at each clinic appears as statistical noise locally, but forms a significant, systematically failing population in aggregate.
- C. Because modern ML models are strictly non-deterministic on edge devices and deterministic in the cloud.
- D. Because individual clinics never experience data drift, which occurs only across wide-area networks.
Answer: The correct answer is B. Emergent complexity means system-level behaviors cannot be understood by observing individual components in isolation. At any single clinic, an underrepresented patient subpopulation (e.g., elderly patients with rare comorbidities) may comprise only a handful of cases, making local accuracy metrics appear stable and healthy. When aggregated across hundreds of clinics, however, the model may systematically fail for thousands of patients in that demographic. Global cross-site telemetry is essential to surface systemic disparities that local averages conceal. Network noise, deterministic execution claims, and local drift immunity are technically incorrect.
Learning Objective: Analyze how emergent complexity creates systemic demographic disparities that local component monitoring obscures.
Arrange the following feedback loop cadences in order from shortest operating timescale (most rapid) to longest operating timescale (slowest): (1) Weekly aggregation of labeled accuracy metrics and statistical drift tests, (2) Minute-level operational health and image-capture focus checks, (3) Quarterly architectural review of model families and regulatory compliance, (4) Daily monitoring of proxy metrics such as referral rates and confidence distributions.
Answer: The correct order is: (2) Minute-level operational health and image-capture focus checks, (4) Daily monitoring of proxy metrics such as referral rates and confidence distributions, (1) Weekly aggregation of labeled accuracy metrics and statistical drift tests, (3) Quarterly architectural review of model families and regulatory compliance. Multi-scale feedback operates across five orders of magnitude: minute-level checks catch immediate operational and hardware misconfigurations; daily proxy tracking detects distribution shifts without waiting for labels; weekly performance reviews incorporate adjudicated ground-truth outcomes; and quarterly strategic reviews evaluate model architectures, lifecycle costs, and regulatory compliance.
Learning Objective: Compare multi-scale feedback loops across operational, proxy, performance, and strategic timescales.
When an undetected data quality failure at data collection propagates downstream to cause compounding failures in model training, validation, and deployment, this systemic failure pattern is known as a(n) ____.
Answer: data cascade. A data cascade is an compounding chain of downstream engineering and operational failures triggered by undetected data quality issues (such as poor labeling, sensor noise, or unrepresentative sampling) at upstream data collection.
Learning Objective: Explain data cascades as compounding downstream failure chains caused by upstream data quality defects.
Self-Check: Answer
Why does the chapter characterize ‘scaling dataset size is always the best way to improve model accuracy’ as a major engineering pitfall?
- A. Because deep learning models degrade in accuracy when trained on more than ^5$ samples due to parameter saturation.
- B. Because collecting additional data increases the Operations ($) term during inference execution.
- C. Because once a target distribution is sufficiently covered, adding raw data yields sharply diminishing returns, whereas investing in label cleaning, balanced subgroup representation, and edge-case curation produces higher accuracy gains at lower compute and storage cost.
- D. Because data privacy regulations strictly limit training set sizes to under 100,000 images in healthcare applications.
Answer: The correct answer is C. The pitfall of blind data scaling ignores the law of diminishing returns: once core data distributions are covered, collecting more uncurated examples adds storage, labeling, and compute costs while yielding negligible accuracy gains. In contrast, improving data quality—such as correcting noisy labels, balancing underrepresented subgroups (e.g., cataract patients), and filtering blurred images—directly addresses critical error modes at lower cost. Deep learning models do not degrade from parameter saturation on large datasets, training set size does not alter inference operation count ($), and privacy regulations do not impose arbitrary sample-count caps.
Learning Objective: Evaluate the diminishing marginal returns of raw data volume and justify prioritizing data quality, curation, and subgroup balance.
True or False: Deferring deployment paradigm selection (Cloud, Edge, Mobile, or TinyML) until after model architecture design and training are complete is an effective engineering strategy because modern model compression techniques can universally fit any trained model onto any target hardware without compromising accuracy.
Answer: False. Deployment paradigm is a primary day-one constraint, not an afterthought. A TinyML target with 256 KB of memory or an edge tablet with 512 MB cannot run a 2 GB ensemble model regardless of compression. Discovering hardware constraints after model development triggers the Constraint Propagation Principle (^{5-1} = 16$ rework cost), forcing teams to discard months of work and revisit Data Collection and Model Development from scratch.
Learning Objective: Evaluate why deferring deployment paradigm selection causes severe workflow failure and exponential rework.
A software engineering team decides to skip shadow-mode validation and canary deployment to accelerate product delivery, relying entirely on strong test-set accuracy scores. According to the chapter’s analysis of workflow fallacies, why does this practice usually increase total time-to-production rather than shortening it?
- A. Because skipping canary deployment causes compilers to emit unoptimized serving binaries.
- B. Because offline test sets are mathematically incapable of computing classification accuracy.
- C. Because modern cloud orchestrators refuse to route traffic to containers that have not completed shadow mode.
- D. Because skipping progressive validation exports integration bugs, latency spikes, and distribution mismatches directly into production, where emergency triage, rollback, and data repair take far longer than staged validation.
Answer: The correct answer is D. Skipping progressive validation stages (shadow mode, canary rollout) does not eliminate deployment risks; it merely exports unvetted integration bugs, serialization bottlenecks, and distribution mismatches into live production. Remediating failures in a live production environment requires emergency on-call response, live service rollbacks, forensic debugging under pressure, and emergency patch validation—consuming far more calendar time and engineering effort than planned staged validation. Canary deployment does not affect binary compilation, offline test sets can compute accuracy, and cloud orchestrators do not enforce shadow mode policies.
Learning Objective: Analyze why skipping progressive validation stages increases total time-to-production through emergency production remediation.
Self-Check: Answer
Which pair of parallel pipelines organizes the complete ML workflow in this chapter, and how do they interact through feedback loops?
- A. A research pipeline and a regulatory compliance pipeline that operate independently until final market authorization.
- B. A data pipeline (collection through preparation) and a model development pipeline (training through deployment), running in parallel and continuously coupled by forward artifact handoffs and backward operational feedback.
- C. A hardware provisioning pipeline and a software compiler pipeline that execute sequentially in a waterfall structure.
- D. An offline training pipeline and a real-time streaming pipeline that never share data artifacts.
Answer: The correct answer is B. The chapter’s structural blueprint organizes the ML workflow into two parallel, coupled pipelines: the top Data Pipeline (data collection, ingestion, curation, labeling, validation, preparation) and the bottom Model Development Pipeline (model training, evaluation, validation, deployment). Rather than executing as a one-way handoff, outer-loop feedback vectors from production monitoring and validation continuously cycle operational insights, data defects, and updated requirements back into upstream data and modeling stages. The other options propose disconnected, non-standard, or purely sequential pipeline architectures that contradict the chapter’s core closed-loop framework.
Learning Objective: Analyze the dual-pipeline architecture of the ML lifecycle and explain how feedback loops couple data and model development.
Summarize how the chapter’s three primary quantitative takeaways—the CrowdFlower survey finding on data work, the Iteration Tax on development speed, and the exponential Constraint Propagation multiplier—jointly reshape how an engineering team should allocate resources on a new ML project.
Answer: The three takeaways jointly mandate a data-first, iteration-focused, and constraint-driven strategy: (1) The survey finding (79% of responses citing cleaning or collection as primary time sinks) dictates reserving substantial engineering budget and infrastructure for data engineering rather than model tuning alone; (2) The Iteration Tax demonstrates that faster experiment cycle times allow teams to explore more hypotheses and achieve higher final quality, justifying early investment in automated platforms and experiment tracking; and (3) The Constraint Propagation Principle (^{N_{}-1}$) proves that early constraint discovery prevents exponentially compounding rework, requiring physical deployment and safety constraints to be bound at Problem Definition on day one.
Learning Objective: Evaluate the chapter’s three core quantitative takeaways to formulate an integrated resource allocation and workflow management strategy.
True or False: An ML workflow is fundamentally a coupled, closed-loop system rather than a linear checklist, meaning that optimizing any individual stage in isolation merely shifts and compounds failures across data, algorithm, and machine dimensions rather than eliminating them.
Answer: True. The central thesis of the chapter is that data, algorithms, and hardware form an interdependent system. Optimizing model accuracy without considering hardware memory budgets produces undeployable artifacts; optimizing data pipelines without understanding model needs produces irrelevant datasets; and launching without monitoring leaves systems vulnerable to silent degradation. Seeing the whole map first and managing continuous feedback across stages is what transforms ad hoc ML experimentation into disciplined systems engineering.
Learning Objective: Evaluate why the ML lifecycle functions as a coupled closed-loop system rather than an isolated linear checklist.